
async-batch-llm
Run thousands of LLM calls concurrently without babysitting them. When one call hits a rate limit, every worker sharing that quota holds off on new calls until the cooldown ends. Failures retry with the right strategy for their cause. After a crash, a rerun resumes from its checkpoint instead of starting over. Deadlines and spend caps stop a run cleanly, and token counts include the attempts that failed.
It works with any async client: wrap your own, or use the built-in OpenAI, Gemini, OpenRouter, DeepSeek, or PydanticAI support. Use it when you need results during the current workflow; for latency-tolerant jobs, a provider's native batch API may be cheaper.


Documentation · Getting started · Examples · Changelog
v0.27 is the last release before 1.0. Upgrading? Read the v0.27 migration guide and see Upgrading below.
Quick start
Install the OpenAI and terminal-progress extras, then set OPENAI_API_KEY:
pip install 'async-batch-llm[openai,progress]'
export OPENAI_API_KEY='...'
import asyncio
from async_batch_llm import llm, process_prompts

async def main():
    batch = await process_prompts(
        llm("openai:gpt-4o-mini"), ["Summarize A", "Summarize B"],
        concurrency=10, progress=True,
    )
    print(batch.summary())

asyncio.run(main())
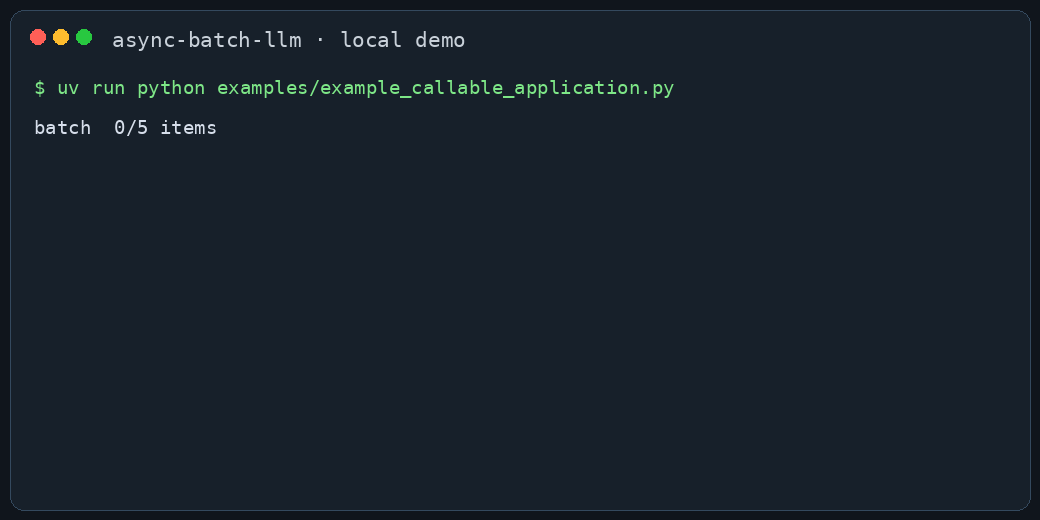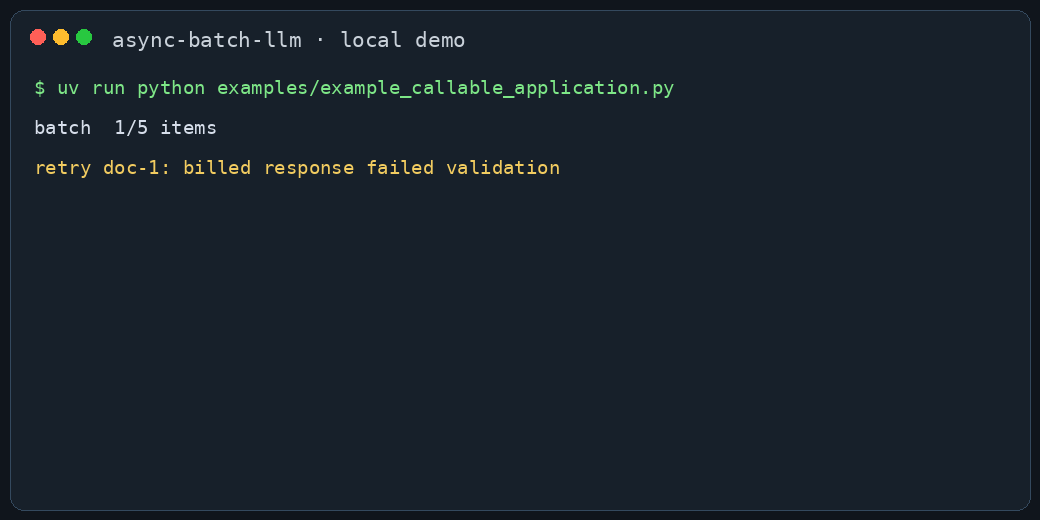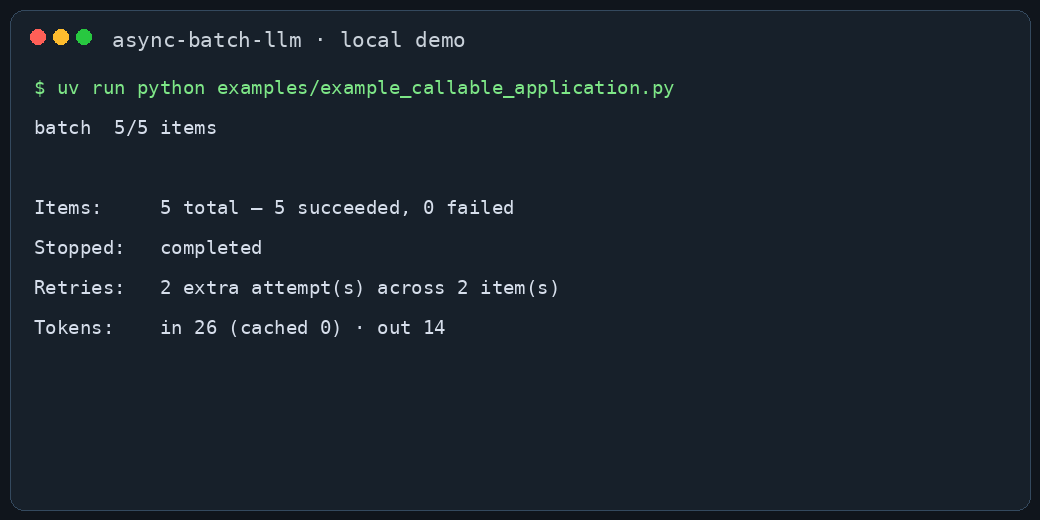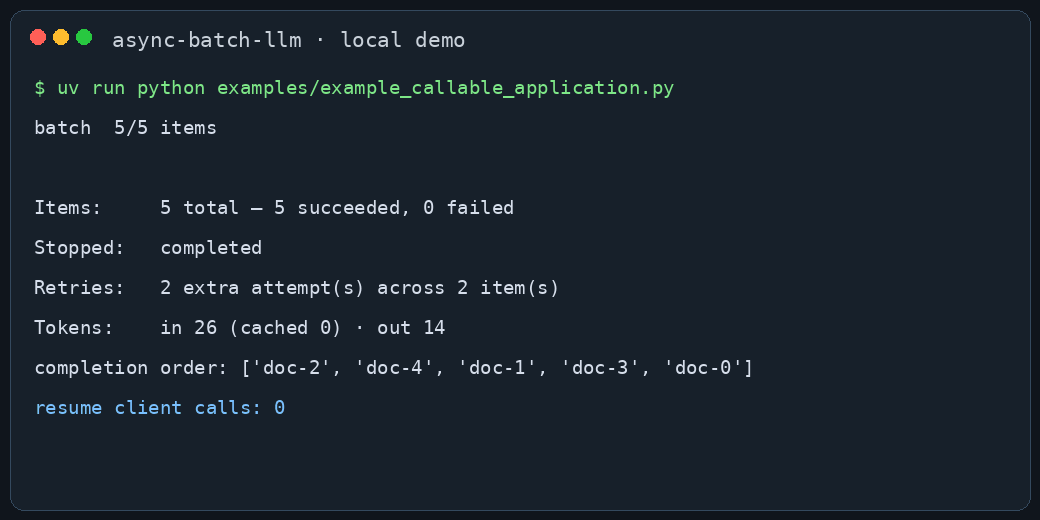
summary() reports what happened, including retries and tokens (timings vary):
Batch summary
=============
Items:     2 total — 2 succeeded, 0 failed
Stopped:   completed
Retries:   0 extra attempt(s) across 0 item(s)
Tokens:    in 240 (cached 0) · out 80
Wall time: 1.42s
  admission wait  p50 0.00s  p95 0.00s  p99 0.00s
  execution       p50 1.21s  p95 1.38s  p99 1.40s
No API key? Run the credential-free demo or open the no-key notebook in Colab.
Why not just asyncio.gather?
A semaphore plus asyncio.gather() caps concurrency, and for a small script
that is enough. Production batches need more:
| Problem | What async-batch-llm does |
|---|---|
| A 429 hits one call while 50 more are in flight | Coordinated cooldown: workers sharing the quota scope start no new calls or retries until it ends, then ramp back up; calls already in flight finish |
| Rate limits and bad outputs need different handling | Separate retry budgets for rate limits and for content/transport failures; on_error() lets a strategy escalate models |
| Request and token quotas (RPM + TPM) | Atomic per-scope admission with usage reconciliation and refunds |
| The input is a million rows, or the consumer is slow | Bounded input and result queues apply backpressure in both directions |
| The process dies at item 80,000 | JSONL or indexed SQLite checkpoints; resume replays only compatible results |
| A run must not exceed a time or money budget | Item deadlines, batch deadlines, token/cost caps, and category-based fail-fast |
| "How many tokens did that cost?" | Tokens and timing include retries and failed attempts |
| Exceptions mixed into a result list | Typed per-item results, lifecycle events, metrics, middleware, and progress callbacks |
For delayed, discounted processing, use a provider's native batch API. The scenario-based comparison covers Bespoke Curator, gateways, native batch APIs, and workflow engines.
Benchmarks
Dated measurements from the GSM8K math benchmark, not provider guarantees:
- Wall time (June 2026). 30 serial calls took 39–65 seconds; with a worker pool they took 2.1–4.2 seconds on the two unthrottled providers.
- Throughput (June 2026). At the same concurrency over 1,000 items, the worker pool processed 72–108 items/s, against 55–58 items/s for a hand-written semaphore pool.
- Model bake-off (all 1,319 items, August 2026): DeepSeek V4 Flash scored 96.9% for $0.11, Gemini 3.5 Flash-Lite 96.6% for $0.71, and GLM 5.3 Flash via OpenRouter 96.3% for $0.03.
The benchmarks page
has the methodology, model IDs, pricing snapshot, the throttled-provider case
where a bare gather was faster, and complete tables.
Install
The core package depends only on pydantic>=2.0 and typing-extensions. Add
extras for the providers you use:
| Extra | Enables | Installs |
|---|---|---|
openai |
OpenAIModel, OpenAICompatibleModel, llm("openai:…"), llm("openai-compatible:…") |
openai>=1.66.2 |
openrouter |
OpenRouterModel, llm("openrouter:…") |
openai>=1.66.2 |
deepseek |
DeepSeekModel, llm("deepseek:…") |
openai>=1.66.2 |
gemini |
GeminiModel, GeminiCachedModel, llm("gemini:…") |
google-genai>=1.49.0 |
pydantic-ai |
PydanticAIStrategy |
pydantic-ai>=1.32.0 |
progress |
tqdm bars for progress=True |
tqdm>=4.66 |
all |
All of the above | All of the above |
CallableStrategy, FakeStrategy, and custom LLMCallStrategy subclasses need
no extra. Supported on Python 3.10–3.14, tested on Linux and macOS.
Providers
llm("provider:model") covers openai:, gemini:, openrouter:, deepseek:,
and openai-compatible: (any other OpenAI-compatible server, with base_url=).
Keyword arguments forward to the model constructor, for example
llm("deepseek:deepseek-v4-flash", thinking=False, max_connections=150).
- OpenAI uses the Responses API by default (
api_surface="chat_completions"opts out). OpenRouter, DeepSeek, andOpenAICompatibleModelshare the same model layer; subclass it for Together, Fireworks, vLLM, and similar servers. - Gemini supports structured response parsing and shared context caching.
- PydanticAI agents run through
PydanticAIStrategywith typed output. - Anthropic and anything else work through PydanticAI,
CallableStrategy, or anLLMCallStrategysubclass.
For custom clients or cached models, use the explicit two-object form,
OpenAIStrategy(OpenAIModel.from_api_key("gpt-4o-mini")). See the
provider guides,
custom strategy guide,
and OpenAI-compatible high-throughput guide.
Model IDs and service limits change independently of this package, so check the
provider's documentation when choosing them.
Use your existing async client
If your application already has an async client or gateway, wrap one call:
from async_batch_llm import (
    ArtifactIdentity,
    CallOutcome,
    CallableStrategy,
    ProcessorConfig,
    process_stream,
)


async def invoke(prompt, *, attempt, timeout, state):
    response = await existing_client.generate(prompt, timeout=timeout)
    return CallOutcome(
        response.text,
        token_usage={
            "input_tokens": response.usage.prompt_tokens,
            "output_tokens": response.usage.completion_tokens,
            "total_tokens": response.usage.total_tokens,
        },
        metadata={"route": response.route},
    )


strategy = CallableStrategy(
    invoke,
    identity=ArtifactIdentity(provider="my-gateway", model="summary-route"),
)
config = ProcessorConfig(
    concurrency=32,
    max_queue_size=128,
    max_result_queue_size=64,
)

async for result in process_stream(strategy, database_prompt_source(), config=config):
    await save_result(result)
CallableStrategy runs on the same execution path as the built-in strategies,
so the call gets retries, cooldowns, deadlines, checkpoints, accounting, and
observers. max_queue_size bounds accepted input waiting for workers and
max_result_queue_size bounds finished results waiting for your loop; both
default to unbounded. See
Use Your Existing Async Client.
Choose an execution surface
| Need | API |
|---|---|
| Collect a finite run | process_prompts() |
| Handle results as they finish | process_stream() |
| Make one resilient request | call() / call_result() |
| Share limits across service requests | LLMCallPool |
| Customize queueing and lifecycle | ParallelBatchProcessor |
All five share the same retry, timing, admission, and token-accounting
pipeline. Pass (item_id, prompt) pairs to control IDs, or
(item_id, prompt, context) triples to carry application data into each result.
Results arrive in completion order; pass preserve_order=True to
process_prompts(), or call batch.in_input_order(), for submission order.
Exceptions the library defines subclass AsyncBatchLLMError and keep their
built-in bases (for example, ItemDeadlineExceeded is still a TimeoutError);
provider SDK errors are not wrapped. See the
single-call and shared-call guide
and core API.
Production runs: checkpoints, deadlines, and budgets
The complete
production resume example
is runnable. With your strategy and prompts defined, the core configuration
looks like this:
from pathlib import Path

from async_batch_llm import (
    AbortMode,
    ArtifactIdentity,
    ErrorCategory,
    GuardrailConfig,
    JsonlArtifactStore,
    ProcessorConfig,
    ResumePolicy,
    process_prompts,
)

identity = ArtifactIdentity(
    provider="openai",
    model="gpt-4o-mini",
    prompt_version="invoice-v4",
    parser_version="invoice-schema-v2",
    application_version="billing-pipeline-v7",
)
store = JsonlArtifactStore("runs/invoice-extraction.jsonl", identity=identity, fsync=True)
config = ProcessorConfig(
    concurrency=20,
    attempt_timeout=30,  # one provider attempt
    guardrails=GuardrailConfig(
        total_timeout_per_item=180,  # admission, waits, calls, and retries
        batch_timeout=3600,
        abort_on_error_categories=frozenset(
            {ErrorCategory.AUTHENTICATION, ErrorCategory.INSUFFICIENT_BALANCE}
        ),
        max_total_tokens=20_000_000,  # stop the run at a spend cap
        abort_mode=AbortMode.DRAIN_ACTIVE,
    ),
)

batch = await process_prompts(
    strategy,
    prompts,
    config=config,
    artifact_store=store,
    resume=ResumePolicy.REUSE_SUCCESSES,
    preserve_order=True,
)

if batch.termination.kind != "completed":
    print("controlled stop:", batch.termination)
Path("summary.json").write_text(batch.to_json(), encoding="utf-8")
What to know before relying on it:
-
Controlled stops return results. Batch deadlines, budget stops, and fail-fast stops end the run with a
BatchResultinstead of an exception; checkbatch.termination. A fail-fast category triggers only once an item fails for good, not on a retryable attempt. Checkpoint write failures and cancellation by your own code still raise. -
Budgets are soft caps. Calls already running when the cap is reached finish (or are cancelled with
AbortMode.CANCEL_ACTIVE), so usage can overshoot by at most one call per worker. -
Checkpoints come before publication. A result from a normal execution is appended and flushed before it is returned or streamed;
fsync=Trueadds durability. Audit records for batch deadline, abort, and budget stops are best-effort, and items rejected before execution may have no record; see the checkpoint failure rules.JsonlArtifactStoreis safe for concurrent writes within one process, not across processes. -
Replay is strict. A stored result is reused only when the item ID, prompt, participating context, and the whole artifact identity match.
REUSE_SUCCESSESreruns failures;REUSE_ALLalso replays terminal provider failures. Deadline, abort, and budget stops, and configuration failures, always re-execute. -
Privacy. Raw prompts and contexts are not stored by default. Outputs and metadata are, and may contain sensitive application data.
-
Large runs.
process_prompts()keeps every result in memory. For bounded memory, useprocess_stream()with a lazy source and bounded queues. For 100k+ items, also use the indexed SQLite backend: same records, same replay rules, no history decode on reopen. Pass the sameidentity:from async_batch_llm import SqliteArtifactStore store = SqliteArtifactStore("runs/invoice-extraction.sqlite", identity=identity)
attempt_timeout limits one provider attempt;
GuardrailConfig.total_timeout_per_item limits the whole item, including
cooldowns, admission, retries, and backoff. The
Choosing Your Limits guide
walks every limit in decision order with a worked 10k-item sizing example. See
also Results, Artifacts, and Resume,
Large Runs,
Deadlines, Budgets and Fail-Fast Guardrails,
and the production checklist.
Token-aware admission
For providers with both request and token quotas, enable token-aware admission explicitly:
from async_batch_llm import CharacterTokenEstimator, ProcessorConfig

config = ProcessorConfig(
    concurrency=32,
    max_requests_per_minute=500,
    max_tokens_per_minute=200_000,
    token_estimator=CharacterTokenEstimator(expected_output_tokens=400),
)
The Token-Aware Admission guide explains estimators, shared quota scopes, refunds, underestimation debt, retries, and known-zero versus unknown usage.
Tokens and cost
BatchResult totals input, cached, output, and total tokens across retries,
including usage recovered from failed attempts. Retries hidden inside an
upstream gateway are counted only if the gateway reports their usage. The
package has no built-in price table; you supply the rates:
cost = batch.estimated_cost(
    input_per_mtok=current_input_rate,
    output_per_mtok=current_output_rate,
    cached_token_rate=current_cache_rate,
)
To stop a run at a dollar amount, pass your pricing as
GuardrailConfig(max_total_cost=..., cost_function=...); see the
guardrails guide.
WorkItemResult and BatchResult serialize to strict, versioned JSON and JSONL;
unsupported values raise rather than fall back to repr(). See the
artifact and serialization API.
Testing without provider calls
Use FakeStrategy without provider extras or credentials:
from async_batch_llm import process_prompts
from async_batch_llm.testing import FakeStrategy

batch = await process_prompts(
    FakeStrategy(lambda prompt: prompt.upper(), token_usage={"input_tokens": 2, "output_tokens": 1}),
    ["hello", "world"],
)
assert list(batch.in_input_order().outputs()) == ["HELLO", "WORLD"]
FakeStrategy and MockAgent also simulate latency, rate limits, retryable
failures, and terminal failures without spending API quota. The project's own
test suite makes no live provider calls. See the
testing guide.
Examples
Start with these runnable examples:
- Existing async application client, bounded streaming, and replay
- Production checkpoints and guardrails
- OpenAI batch processing
- Single calls and a shared call pool
- Validation-aware model escalation
- Custom embedding strategies
The examples directory also covers Gemini, DeepSeek, OpenRouter, Anthropic, LangChain, caching, grounding, and the benchmark.
Documentation
- Getting Started
- Compare Alternatives
- Choosing Your Limits
- Production Checklist
- Troubleshooting and FAQ
- Results, Artifacts, and Resume
- Deadlines, Budgets and Fail-Fast Guardrails
- Bounded Work and Backpressure
- API Reference
- API Stability (draft for 1.0)
Upgrading
From v0.26, read the
v0.27 migration guide.
In short: OpenAIModel now uses the Responses API, built-in models no longer
send a default temperature, application errors are no longer mistaken for rate
limits, and several names are deprecated ahead of 1.0. Run your tests with
-W error::DeprecationWarning to find them (on Python 3.14 with google-genai
installed, also pass -W "ignore::DeprecationWarning:google.genai.types"). The
API stability page
lists what 1.0 keeps stable.
v0.27 is the last release that supports Python 3.10; 1.0 requires Python 3.11 or newer. Guides for earlier versions are in the migration section of the documentation.
Contributing
Clone the repository and use its pinned development environment:
git clone https://github.com/geoff-davis/async-batch-llm.git
cd async-batch-llm
uv sync --all-extras
make ci
See the contributing guide or open an issue. To report a security vulnerability, follow the security policy rather than opening a public issue.
License
MIT License. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for async-batch-llm 0.27.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| async_batch_llm-0.27.0.tar.gz | 1.2 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| async_batch_llm-0.27.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.5 MB
Release files / async_batch_llm-0.27.0.tar.gz
| Download URL | async_batch_llm-0.27.0.tar.gz |
|---|---|
| Size | 1.2 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4e44267ecdf44f651c806efac2bcefe84762461720a9f70f4983e48f7e6f7d8f
|
|
BLAKE2b-256 checksum How to use checksums |
af012805f769b18f270503c22dec4a8e702dff9fd8888f889b79921947941359
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 30, 2026.
Transparency logRelease files / async_batch_llm-0.27.0-py3-none-any.whl
| Download URL | async_batch_llm-0.27.0-py3-none-any.whl |
|---|---|
| Size | 255.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
44d854dae707bb3e0ee1ddcb94f6effde227b14d489cdf32a4e84c11fdb3022e
|
|
BLAKE2b-256 checksum How to use checksums |
b995f8c5acfcf280ff649146b38315f82c52d56f9dc355219783d0bae8ecd2cb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 30, 2026.
Transparency log













