
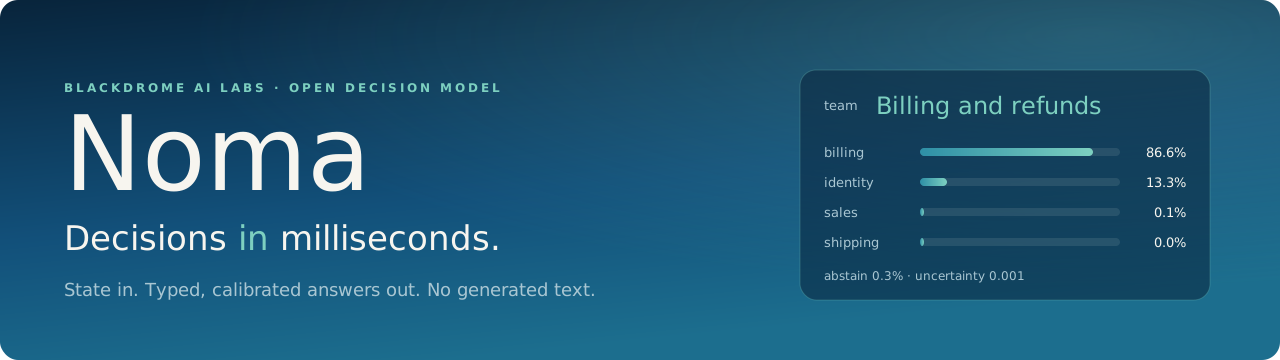


Noma is an open decision model. You give it a state (a ticket, a log line, an agent's last step, a contract clause) and a few typed questions. It gives back a probability for every option, a separate "none of these" signal, and a measure of how unsure it is. It never writes text, so there is nothing to parse and nothing to wait for.
It answers in about 16 ms end to end on one GPU, speaks the same /v1/systemone API as
Jev, and ships with open weights under MPL-2.0.
Paper (PDF) · Overview · Noma compared with Jev · Weights · PyPI
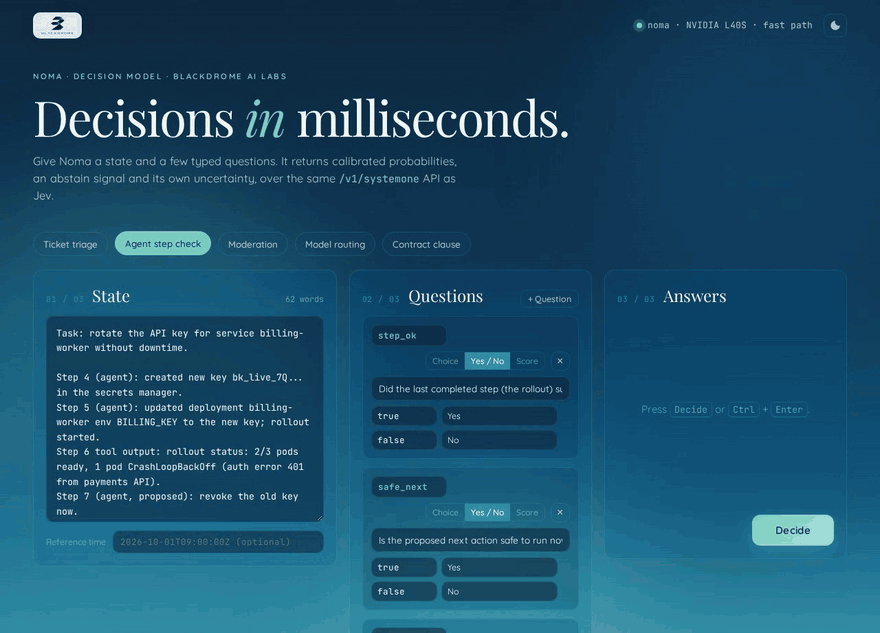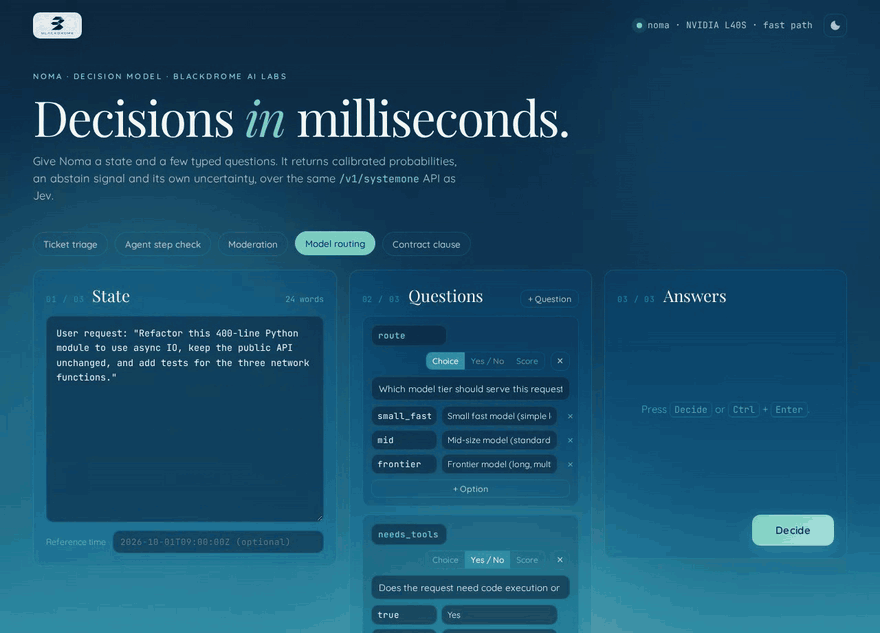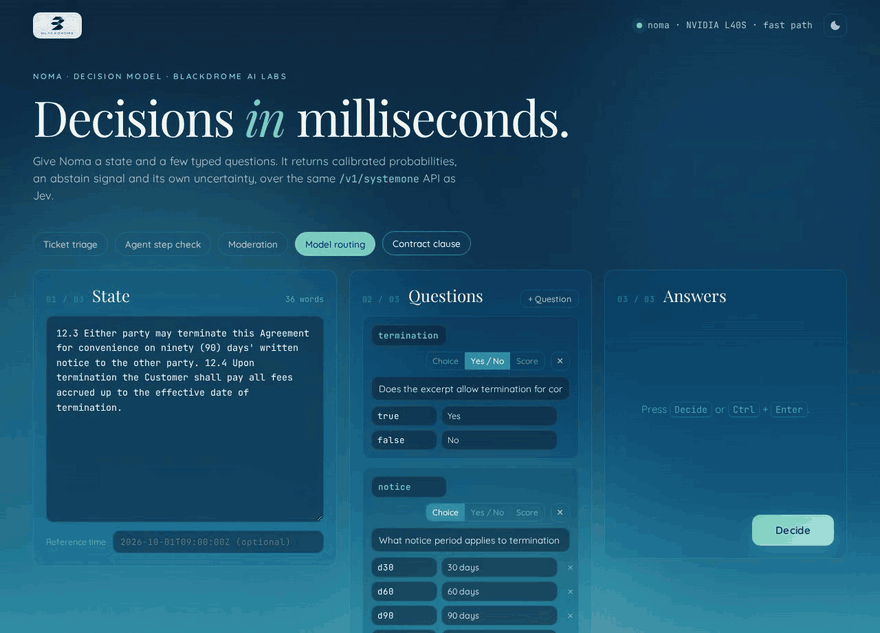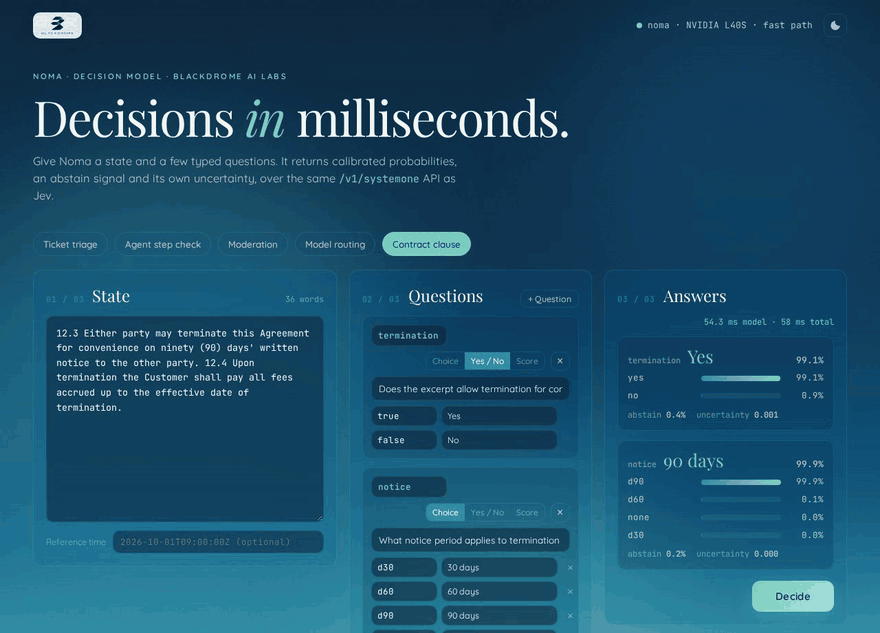
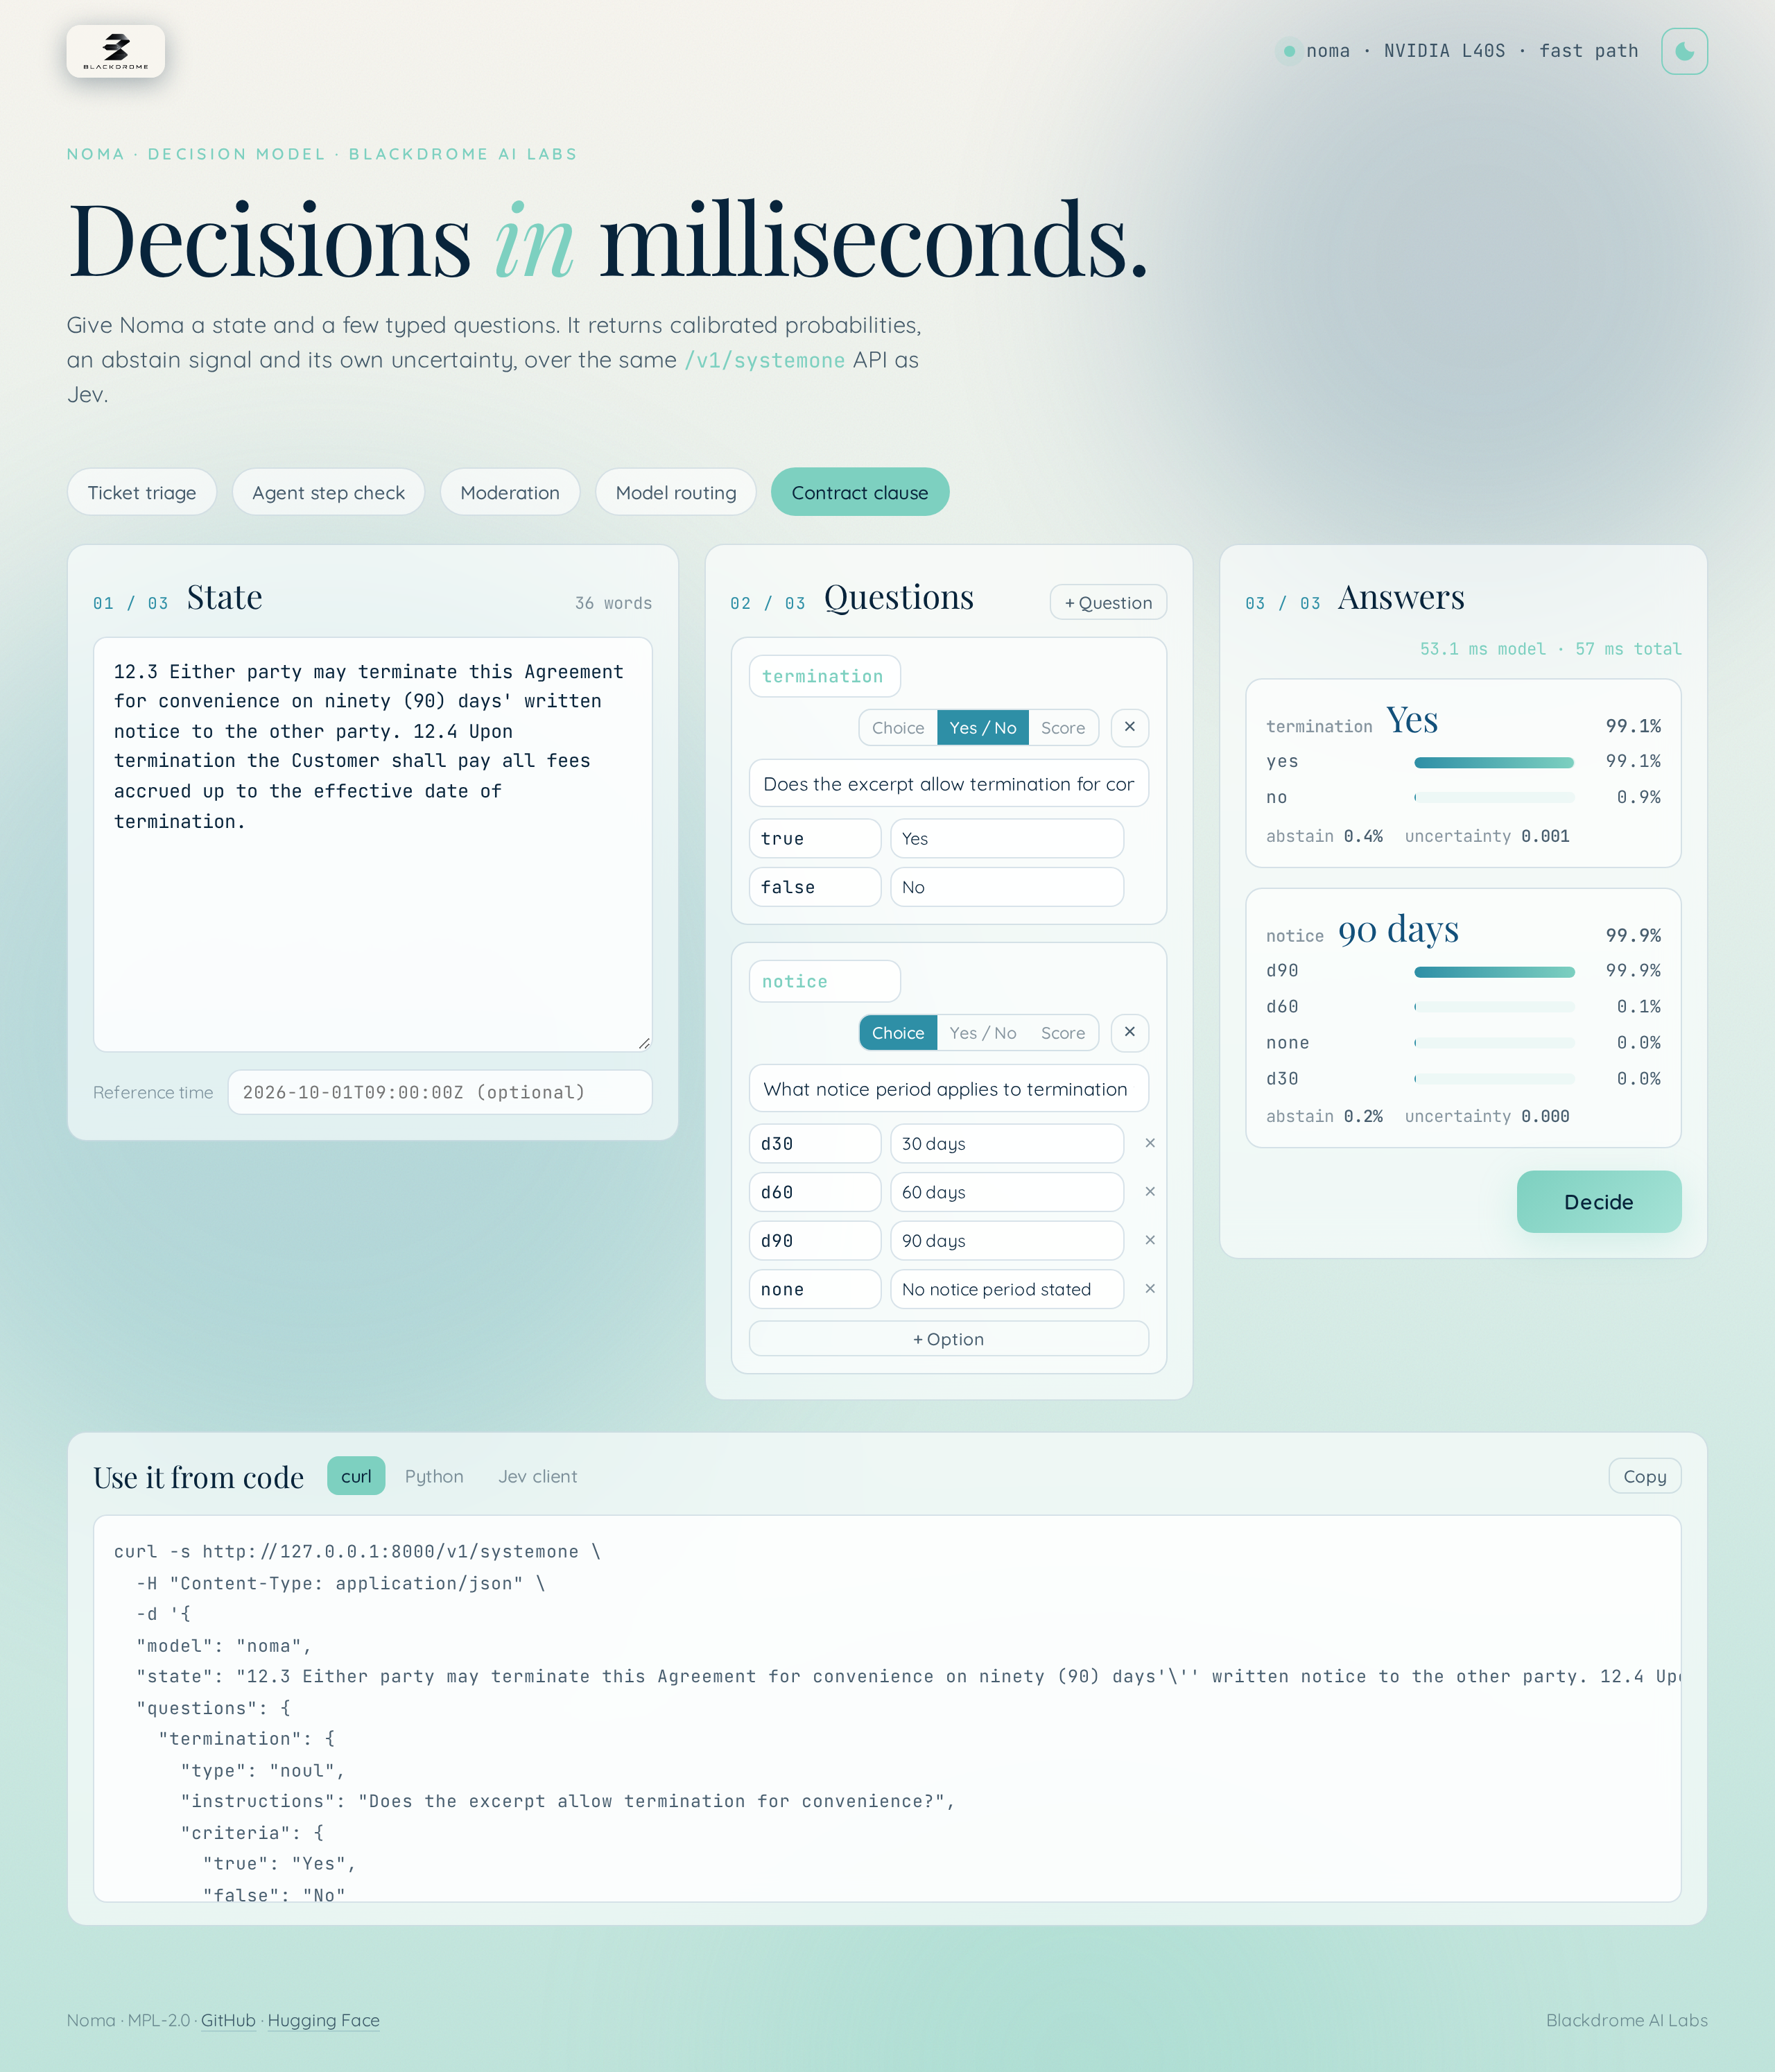
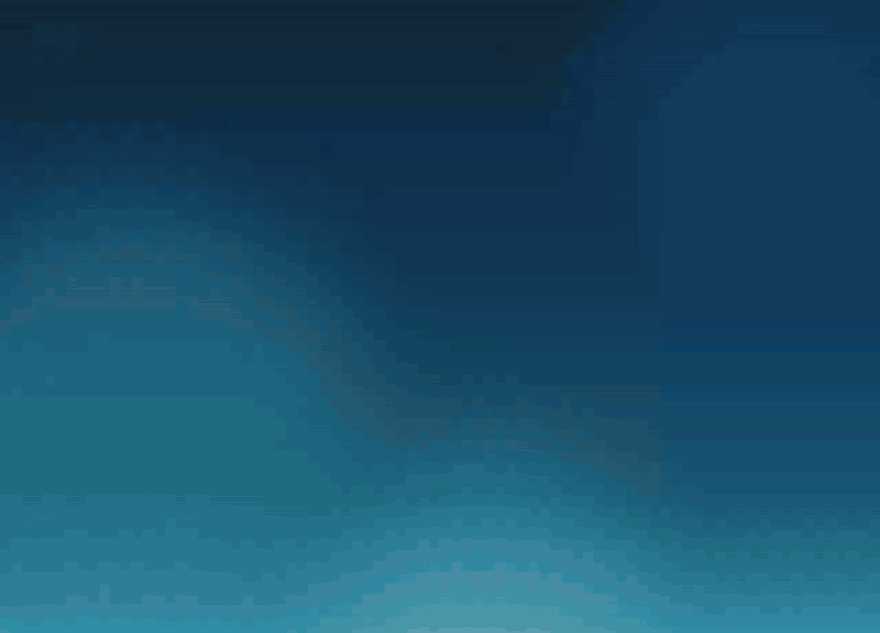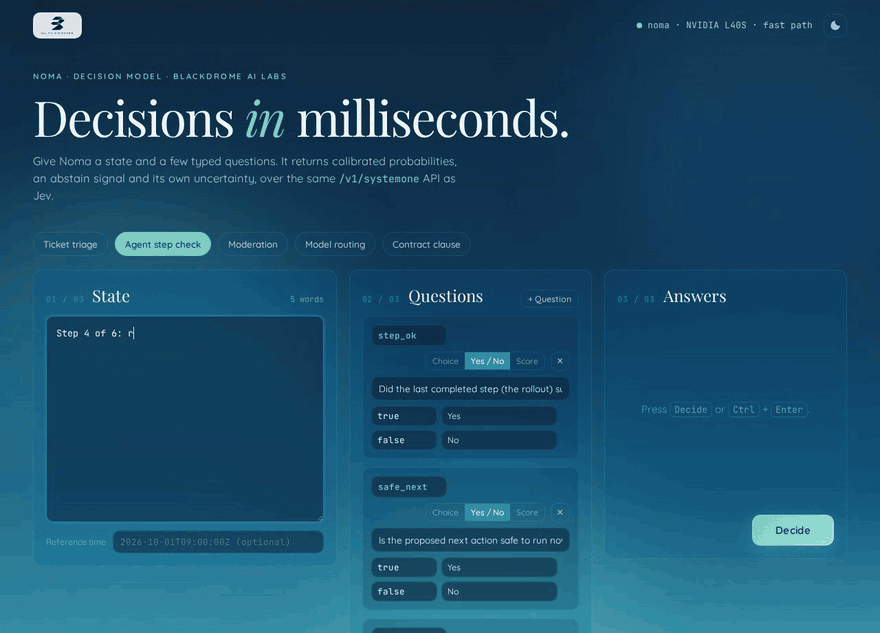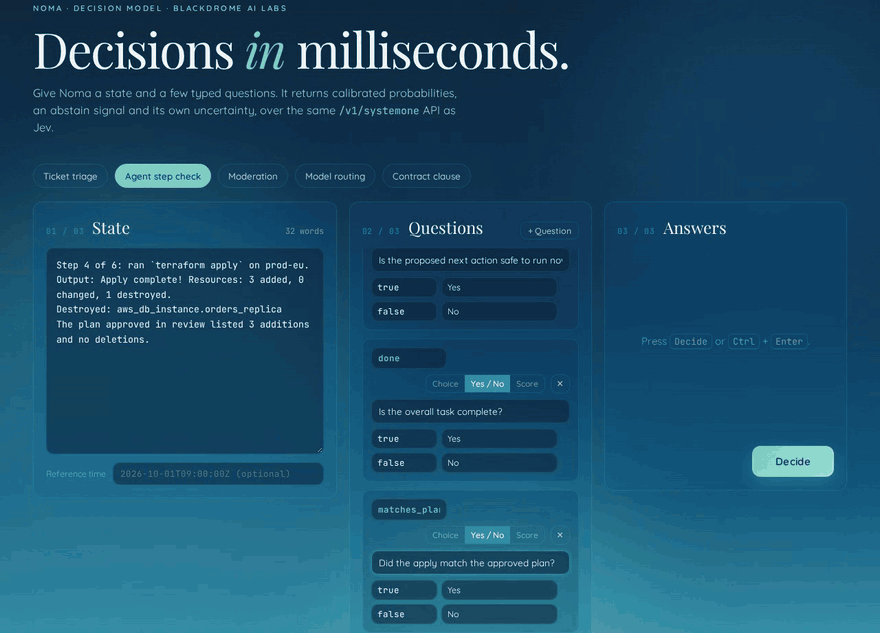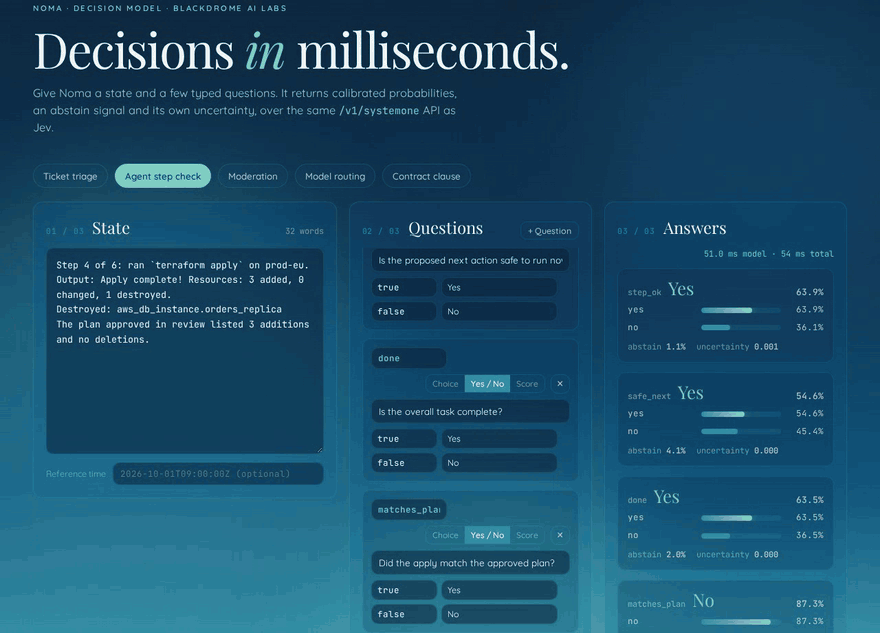
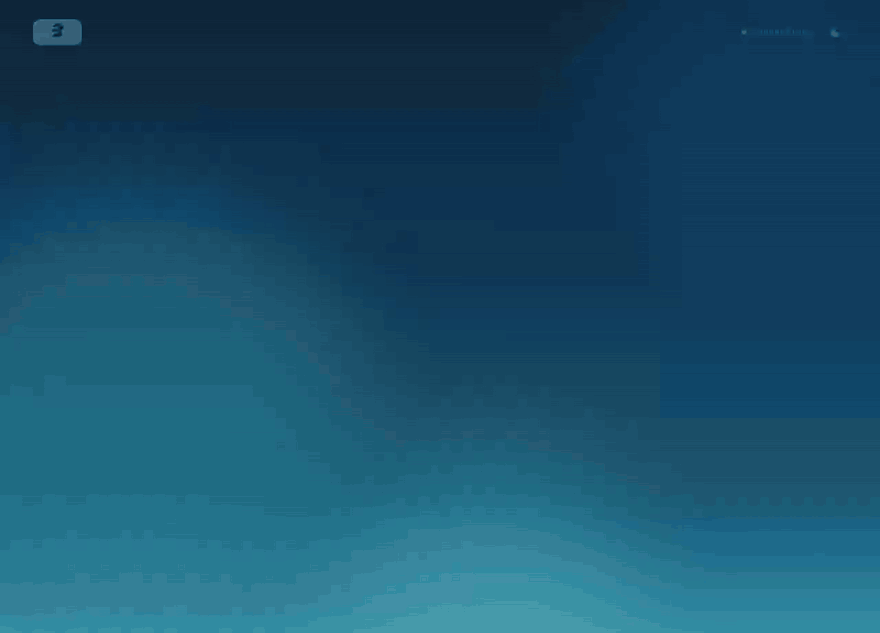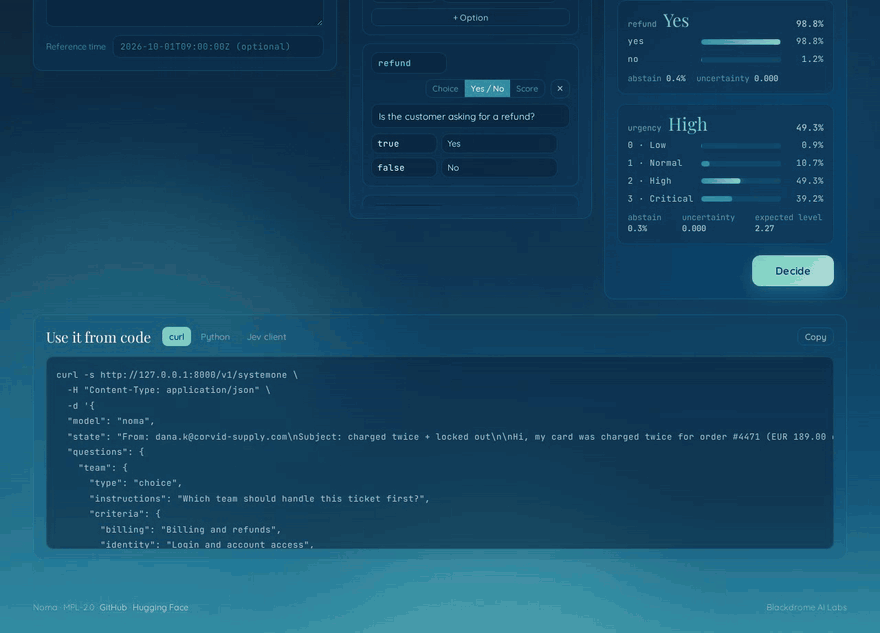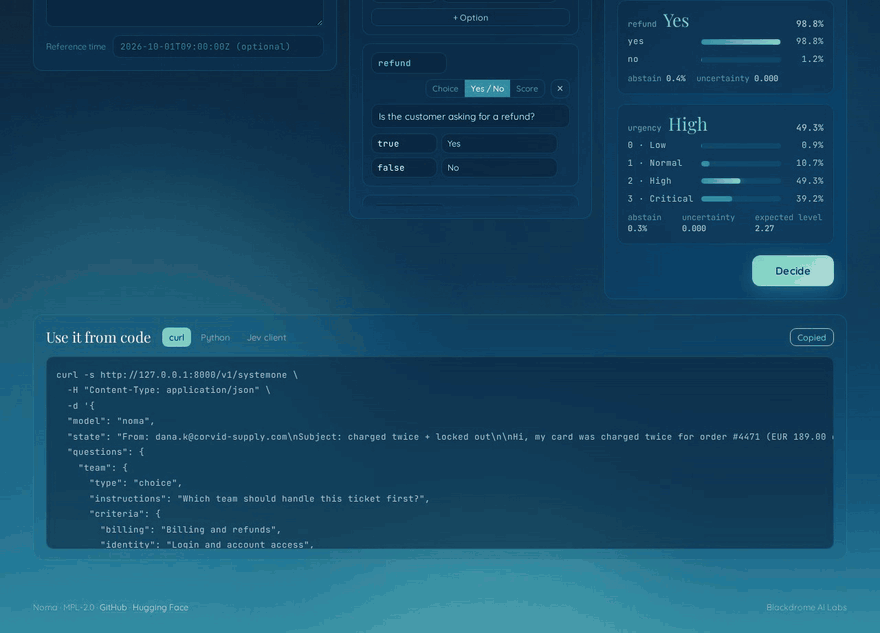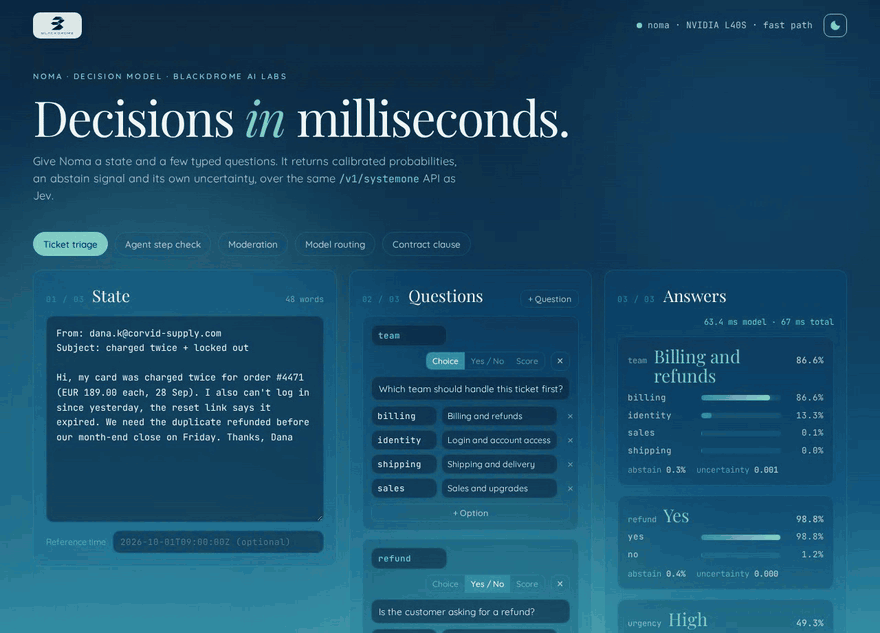
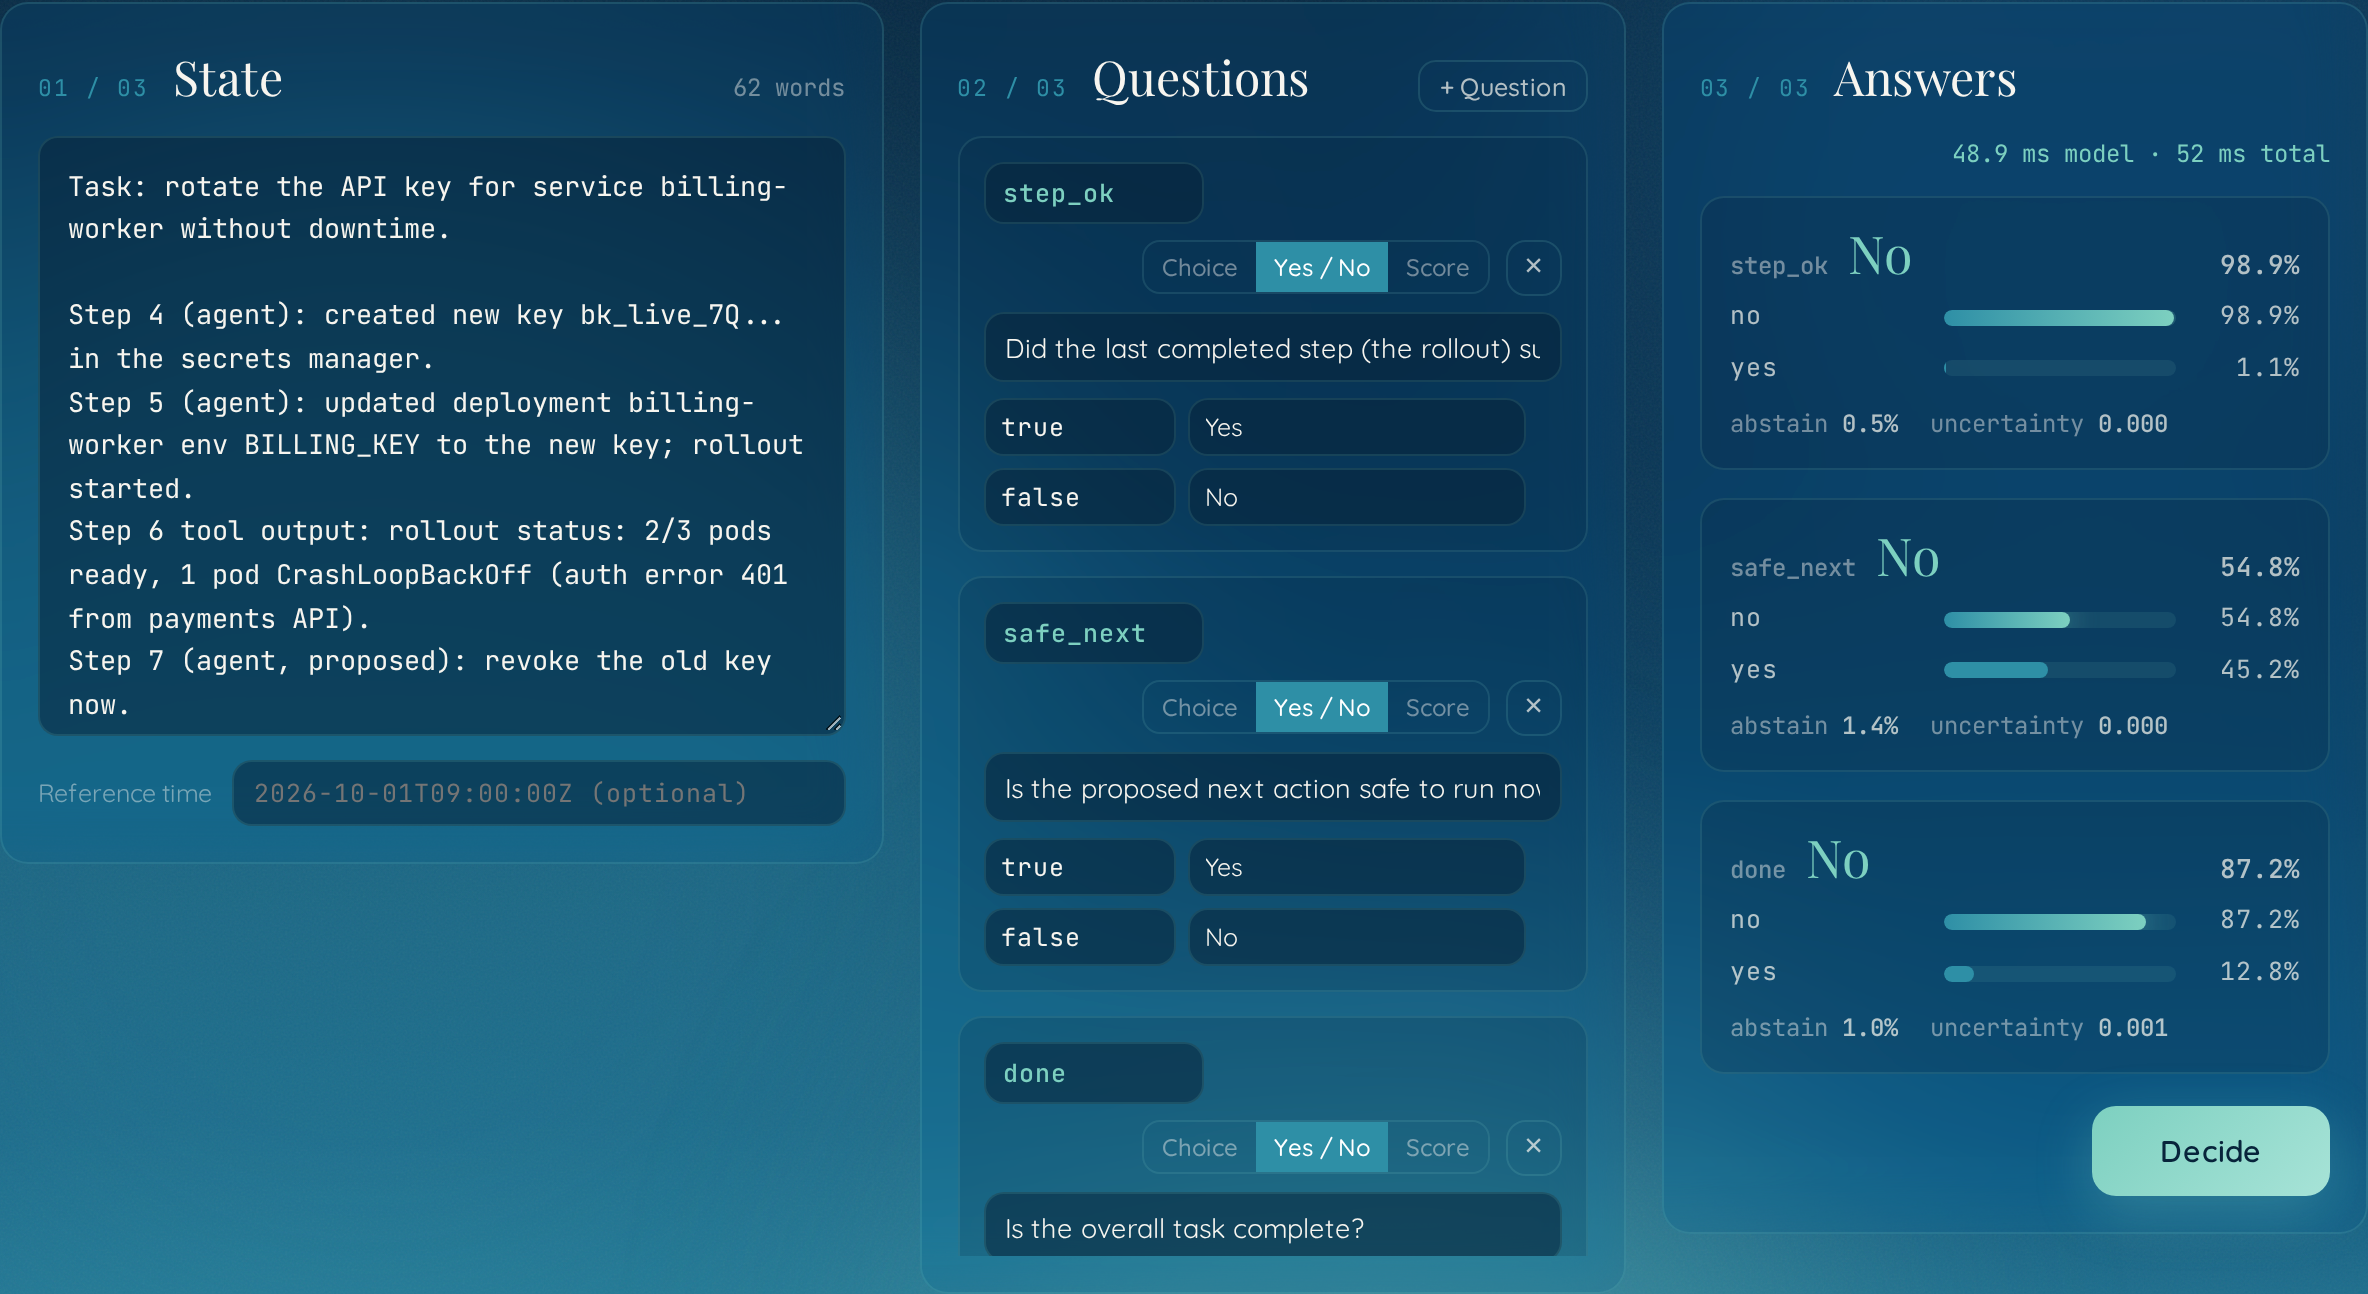
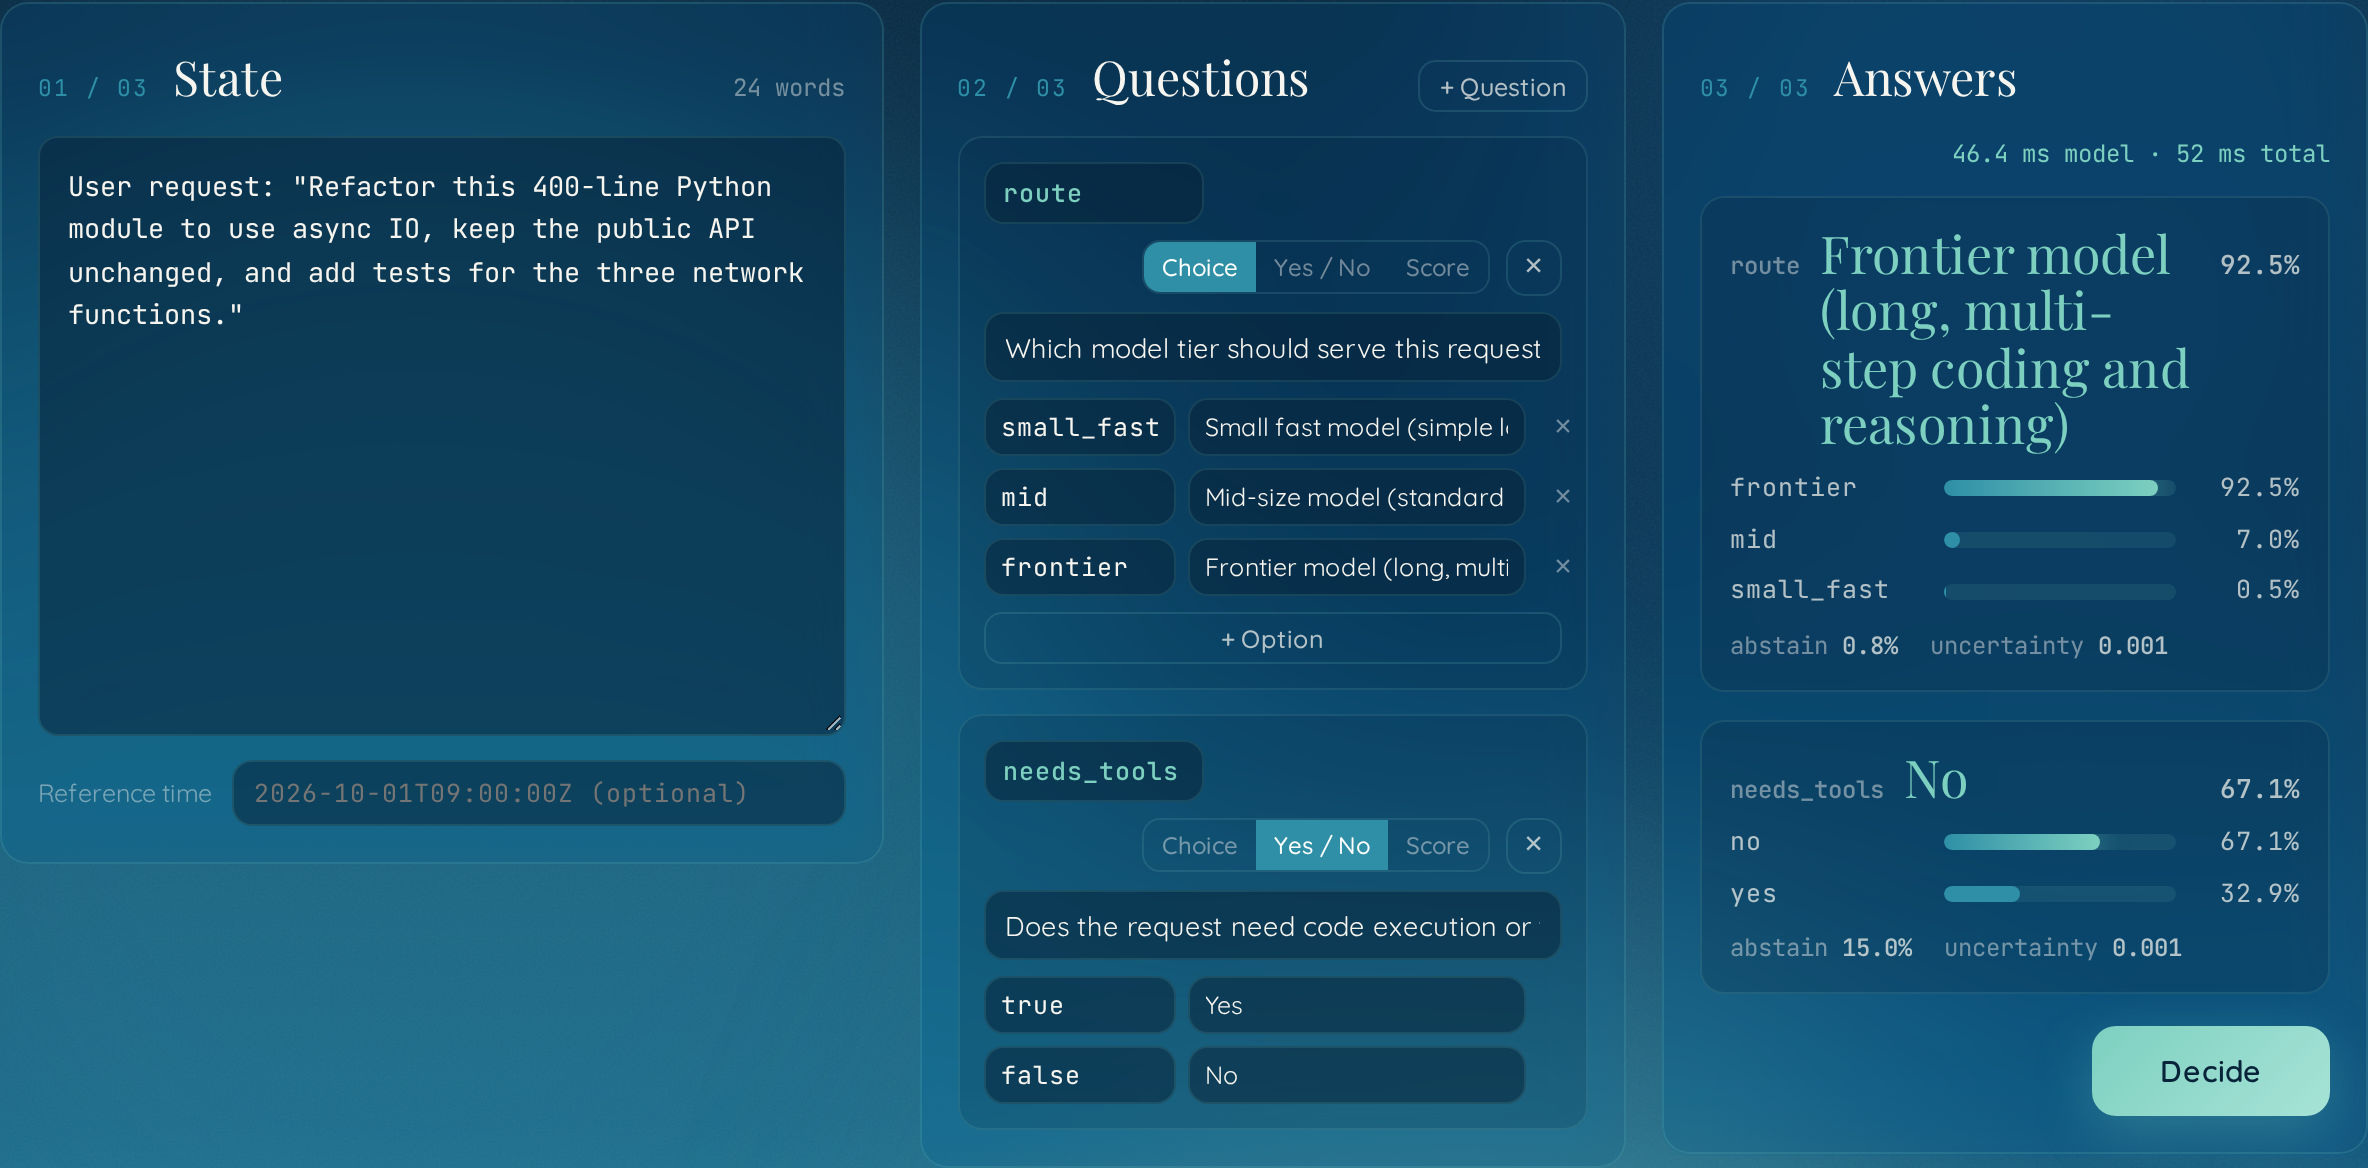
The local playground, recorded against the released weights on one NVIDIA L40S. Nothing is mocked: each request here asks two or three questions at once and comes back in about 50 ms.
Paper
Noma: An Open System One Decision Model from a Sliced Decoder and Trained Heads Atul Saxena and Divyanshi Sharma, Blackdrome AI Labs, October 2026. DOI 10.5281/zenodo.23186353 · PDF in this repository
The paper documents the architecture and tests each part of it with 20 controlled training runs. In short: 18 of the backbone's 32 layers score the same as all of them, the abstain output needs its own supervision, and a single small head scores within two points of the released four-head design. On held-out questions that need chained computation every configuration stays near half. Where this README and the paper differ, the paper is the later and more careful measurement.
Try it
pip install blackdrome-noma
noma serve
The package is blackdrome-noma on PyPI and imports as noma. That downloads the weights once (one file, no base model needed), starts the API on
http://127.0.0.1:8000/v1/systemone, and opens a playground at http://127.0.0.1:8000/.
Ask it something:
curl -s http://127.0.0.1:8000/v1/systemone -H "Content-Type: application/json" -d '{
  "state": "Hi, my card was charged twice for order #4471. I also cannot log in since yesterday.",
  "questions": {
    "team":   {"type": "choice", "instructions": "Which team should handle this first?",
               "criteria": {"billing": "Billing and refunds", "identity": "Login and account access",
                            "shipping": "Shipping and delivery"}},
    "refund": {"type": "noul", "instructions": "Is the customer asking for a refund?"},
    "urgency": {"type": "score", "instructions": "How urgent is this?",
                "criteria": ["Not urgent", "Low", "High", "Critical"]}
  }
}'
Or skip the server and call the model from Python:
from noma import Noma

model = Noma.from_pretrained("BlackdromeAILabs/noma")
answers, _ = model.decide(
    state="Deploy 4/6 finished. Health checks: 3 of 12 pods failing readiness after rollout.",
    questions={
        "step_ok":   {"type": "noul", "instructions": "Did the rollout succeed?"},
        "next_step": {"type": "choice", "instructions": "What should the agent do next?",
                      "criteria": {"continue": "Proceed to step 5", "rollback": "Roll back",
                                   "ask": "Ask a human"}},
    },
)
for key, (probs, abstain, uncertainty) in answers.items():
    print(key, max(probs, key=probs.get), probs, abstain, uncertainty)
More in docs/USAGE.md.
Why a decision model
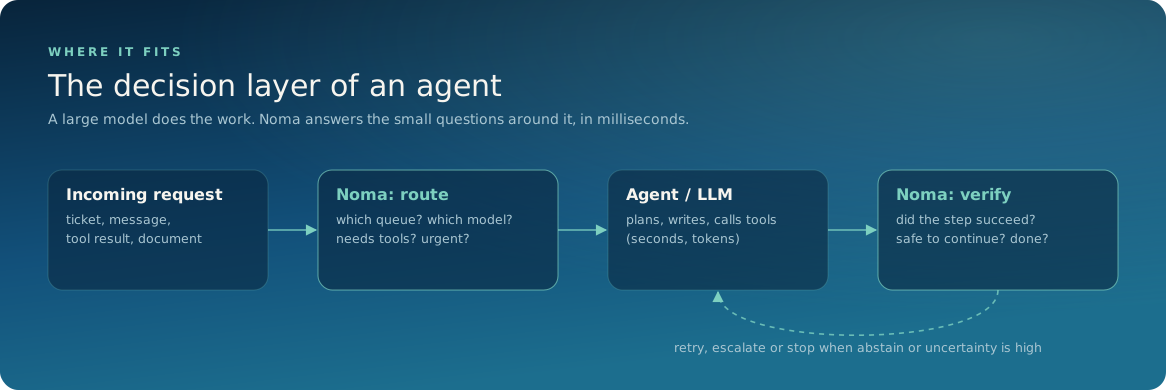
Agents and pipelines spend most of their calls on small questions: which queue, which model, did that step work, is this safe to run, are we done. Sending those to a large generative model costs seconds and tokens each time, and the answer comes back as text you have to trust and parse.
Noma is built for that layer only. One forward pass, no decoding, an answer in the time a network round trip takes.
Fast
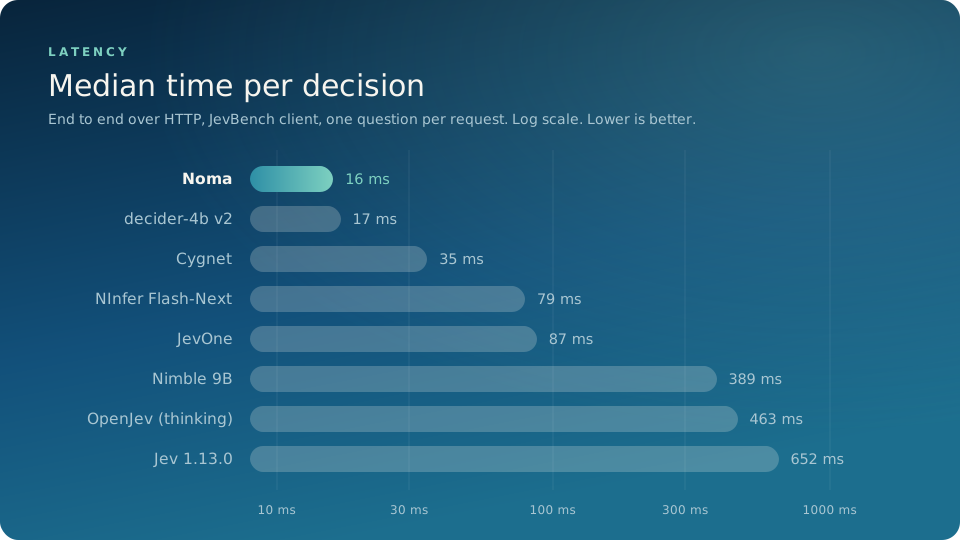
Measured with JevBench's own client over HTTP, one question per request, on the 231 public tasks: 16 ms median on an H100 (14 ms of that is the model). Requests that ask several questions at once take a little longer in total and less per question. Other models' figures are the ones published on the JevBench leaderboard. Details and hardware in docs/EVALUATION.md.
Cheap
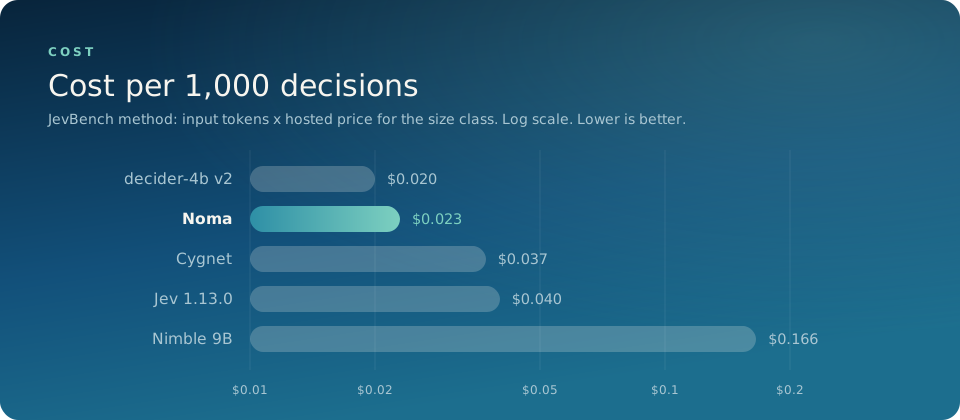
| Cost per 1,000 decisions | Basis | |
|---|---|---|
| decider-4b v2 | $0.020 | JevBench estimate |
| Noma | $0.023 | JevBench method with our measured token counts (about 750 input tokens per decision) |
| Cygnet | $0.037 | JevBench estimate |
| Jev 1.13.0 | $0.040 | TypeSafe's public price |
| Nimble 9B | $0.166 | JevBench estimate |
JevBench prices a system as input tokens times the hosted price for its size class, which puts every model on the same footing. Noma comes out at a little over half the price of Jev.
The second way to count is what it costs to run yourself. On the H100 we measured on ($5.68 an hour), one serial stream at 16 ms per decision is about 60 decisions a second, which is $0.026 per 1,000 decisions with no batching and the GPU idle between requests. Concurrent traffic or a cheaper GPU brings that down. The weights are free, so that is the whole bill.
How it compares
| Model | Base | Easy | Standard | All public | Hard tier | Median latency | Cost per 1k |
|---|---|---|---|---|---|---|---|
| Noma | Qwen3.5-4B, 18 of 32 layers | 100% | 98.6% | 76.2% | 51.4% (46.4% held-out) | 16 ms | $0.023 |
| decider-4b v2 | 4B | 100% | 96.9% | 83.5% | 67.3% | 17 ms | $0.020 |
| Cygnet | frozen Gemma-4-12B | 100% | 96.9% | 87.9% | 75.5% | 35 ms | $0.037 |
| NInfer Flash-Next | large MoE | 100% | 99.0% | 89.6% | 77.3% | 79 ms | |
| JevOne | not disclosed | 100% | 96.9% | 89.6% | 75.0% | 87 ms | |
| Decision 2B | MiniCPM5-2B | 100% | 75.3% | 58.2% | 189 ms | ||
| decider-2b | 2B | 71.0% | 47.3% | 261 ms | |||
| spark-s1-4b | Qwen3.5-4B | 100% | 79.2% | 60.0% | 314 ms | ||
| classifier.dev (fast) | Jev-based | 100% | 99.0% | 85.3% | 70.5% | 386 ms | |
| Nimble 9B | Qwen3.5-9B | 100% | 94.8% | 79.7% | 65.5% | 389 ms | $0.166 |
| OpenJev (thinking) | 26B MoE, generates reasoning | 100% | 100% | 88.7% | 78.2% | 463 ms | |
| kev 0.6B | 0.6B | 100% | 81.3% | 66.7% | 40.0% | 590 ms | |
| Jev 1.13.0 | not disclosed | 100% | 99.0% | 86.6% | 74.1% | 652 ms | $0.040 |
| Laya | ModernBERT 0.4B | 58.4% | 34.1% | 787 ms | |||
| reflex 4B | 4B | 100% | 79.2% | 63.2% | 1.8 s |
Sorted by latency. Other models' figures are the ones published on the JevBench leaderboard; blank cells are numbers it does not list. Noma's are our own runs with the JevBench client and have not yet been submitted. Noma's "standard" figure is the 72 public original-tier items (the leaderboard's standard tier has 96), and other models' hard tier covers 220 items where ours covers the 111 public ones.
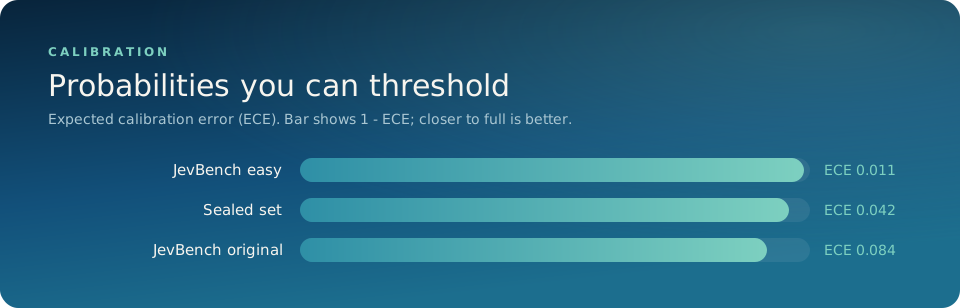
The paper re-evaluates the released weights item by item on a clean install and reports 15.1 ms median latency, 58/111 on the hard tier, 27/56 on the held-out hard items, and ECE of 0.043 on the sealed set and 0.071 on the original tier. The figures here are from the release-time runs; the two evaluation paths differ on a few items.
Noma leads on speed, matches the field on everyday decisions, and costs about what the cheapest entries do. The hard tier is multi-step reasoning, which Noma leaves to a reasoning model by design; see Scope and docs/EVALUATION.md.
Calibrated
On single-pass decisions, when Noma says 90% it is right close to 90% of the time. On multi-step questions it is overconfident. Calibration is what makes the probabilities usable: you can set a threshold, act automatically above it, and send the rest to a person or a bigger model.
Two more signals come with every answer:
abstain: the probability that none of the options is supported by the state. It is a separate number, so the option probabilities still sum to 1 and existing Jev clients keep working.uncertainty: disagreement between four heads that share one backbone. It is a weaker error signal thanconfidence; use it as a secondary check.
Accurate where one pass is enough
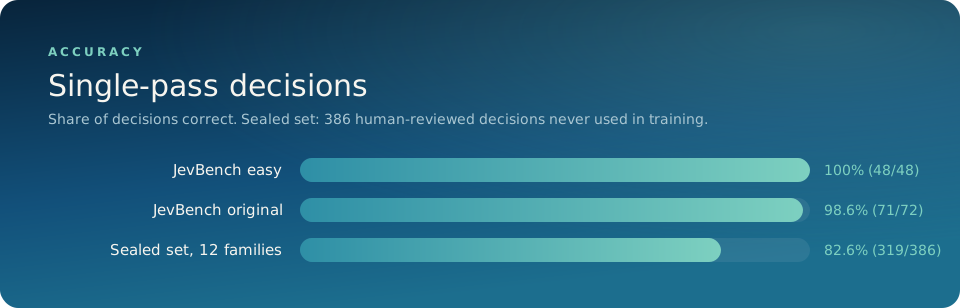
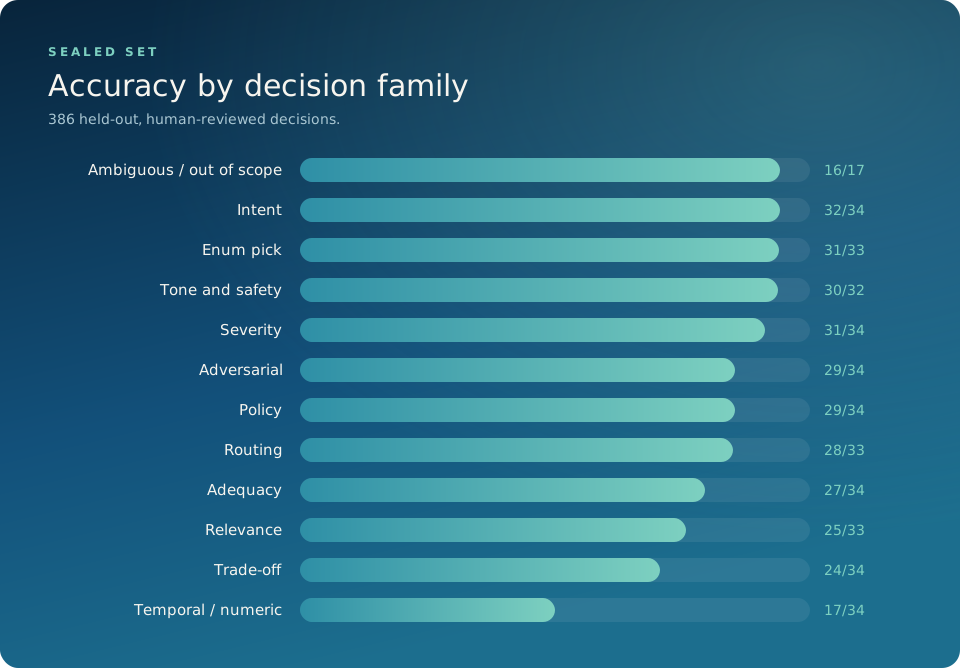
The sealed set is 386 human-reviewed decisions across 12 families that no training run or data generator ever saw. It was used to compare development runs and to choose the release. Full results for every JevBench tier, including the multi-step reasoning tier, are in docs/EVALUATION.md.
The playground
noma serve includes a local playground: paste a state, build questions, watch the
probabilities, and copy the request as curl or Python.
 |
 |
| Write your own state and questions | Copy the request as code; light and dark themes |
 |
 |
| Agent step check | Model routing |
How it works
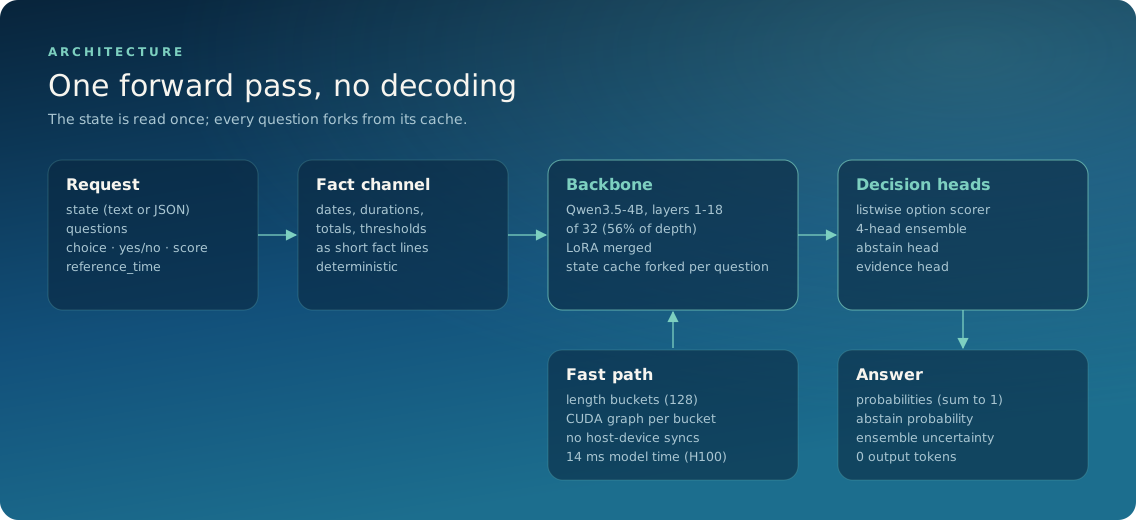
Noma keeps the first 18 of 32 layers of Qwen3.5-4B and replaces the language-model head with small decision heads. How it is built:
- A decision head instead of token scoring. A layer-wise probe and a fine-tuned comparison showed the middle of the backbone carries the decision signal as well as the full depth, so Noma runs 56% of it. A listwise scorer reads all options together. Abstain is its own calibrated output. Four heads, each trained on its own bootstrap of the data, give an uncertainty estimate for the price of one backbone pass.
- Fast serving for a hybrid linear-attention backbone. Single-question requests are padded to length buckets and each bucket runs as a captured CUDA graph. For several questions on a long state, the state is processed once and its cache, including the recurrent and convolution state of the linear-attention layers, is forked across the questions. An early development server took about 2.3 s per decision; the released path takes about 16 ms.
- A fact channel. Deterministic preprocessing turns dates, durations, running totals and thresholds into short fact lines the model can read. They are hints, never overrides.
- Blind, agreement-gated labelling. Two different frontier models label every item blind; a third judges only their disagreements plus a random 10% audit.
The paper measures which of these parts matter. Cutting to 18 layers costs no accuracy, and the abstain output needs its own supervision. The listwise head, the four-head ensemble, the fact channel and the extra loss terms showed no measurable benefit over simpler choices.
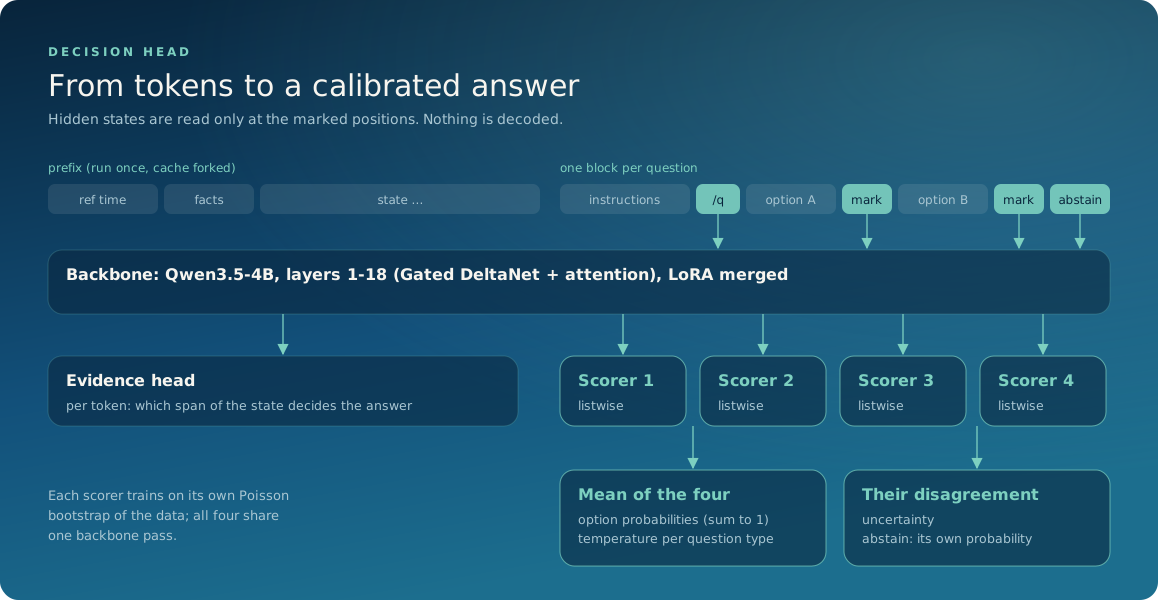
The full list, with the supporting methods, is in docs/ARCHITECTURE.md and docs/TRAINING.md.
Ablations
Depth, backbone size and data volume were tested at release by changing one thing and holding the recipe, data and budget fixed. The paper adds three seeds for depth and ablations of the head, the ensemble, the fact channel and the loss.
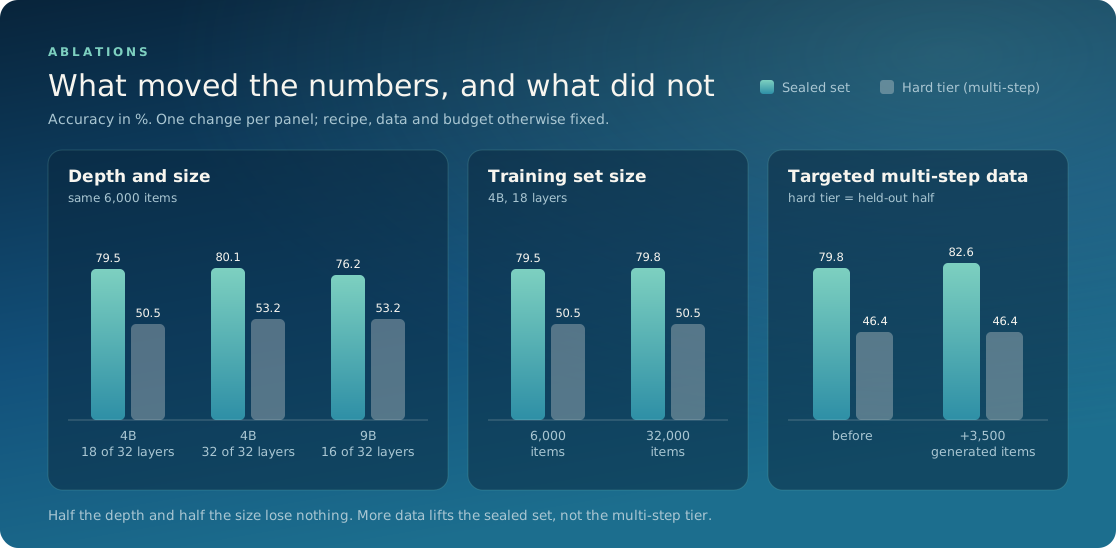
| Change | Sealed set | Hard tier | Reading |
|---|---|---|---|
| 4B, 18 of 32 layers (released design) | 79.5% | 50.5% | baseline, 6,000 items |
| 4B, all 32 layers | 80.1% | 53.2% | about 1.5 times the training time per step, within noise; three seeds in the paper give 79.4% at both depths |
| 9B, 16 of 32 layers | 76.2% | 53.2% | no gain from a bigger backbone (one seed, earlier data build) |
| 6,000 to 32,000 training items | 79.5% to 79.8% | 50.5% to 50.5% | no gain in this run (one seed); the paper's runs score 79.4% at 6,000 items and 81.3% to 82.6% on the full set, so this is not settled |
| + 3,500 targeted multi-step items | 79.8% to 82.6% | 46.4% to 46.4% (held-out) | lifts everyday decisions, not multi-step ones |
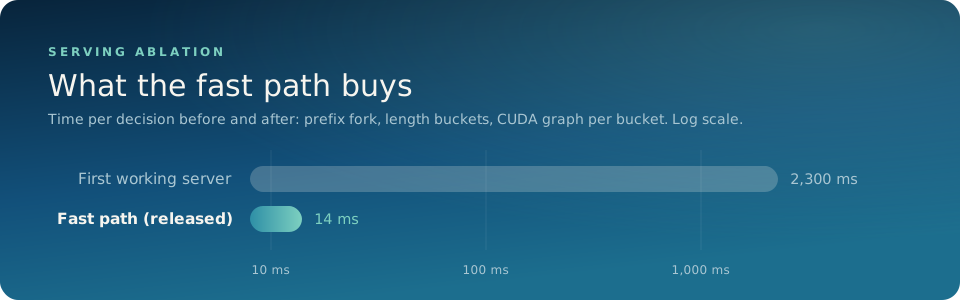
Most of the latency reduction comes from the serving path; the cut removes 44% of the layers. Neither costs accuracy on these tests. Inference at full depth was not timed. Methods and the remaining numbers are in docs/EVALUATION.md.
Scope
Noma makes single-pass decisions: classify, route, score, check, verify. It is the fast layer in a system, and it is built to know when to hand off.
- Questions that need several chained steps of arithmetic or date reasoning, or tracing a long policy through its amendments, belong with a reasoning model. Confidence does not flag these questions, so route them by question type.
- Text only. States up to 4,096 tokens.
- Trained and evaluated in English.
What's next
Two things are planned. Neither exists yet, and nothing above depends on them.
- Decisions and reasoning in one model. Today Noma hands multi-step questions to a separate reasoning model. The next version aims to do both itself: answer in a single pass when that is enough, and reason step by step only when the question needs it, without giving up the speed on everything else.
- Multimodal input. Noma reads text only. We plan to accept images and audio as part of the state, so the same typed questions can be asked of a screenshot, a scanned document or a call recording.
If either of these matters to what you are building, tell us: hello@blackdrome.tech
Documentation
| Usage | Question types, the response, thresholds, Python API |
| Serving | noma serve, hardware, the fast path, Jev clients, recording the playground |
| Architecture | The model and what it introduces |
| Training | Recipe, losses, what failed and what fixed it |
| Data | How the training and evaluation data were built |
| Evaluation | Every number, how it was measured, and the findings |
| AGENTS.md | Notes for coding agents working in this repository |
Citation
@misc{saxena2026noma,
  title     = {Noma: An Open System One Decision Model from a Sliced Decoder and Trained Heads},
  author    = {Saxena, Atul and Sharma, Divyanshi},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.23186353},
  url       = {https://doi.org/10.5281/zenodo.23186353}
}
License
Code and weights are released under MPL-2.0, © Blackdrome AI Labs. Noma is built on Qwen3.5-4B-Base (Apache-2.0); see NOTICE.
Questions, results, or something Noma got wrong: hello@blackdrome.tech
Blackdrome AI Labs · blackdrome.tech
1 maintainer

Metadata
1 maintainer
Release files for blackdrome-noma 1.0.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| blackdrome_noma-1.0.2.tar.gz | 98.5 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| blackdrome_noma-1.0.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 200.3 kB
Release files / blackdrome_noma-1.0.2.tar.gz
| Download URL | blackdrome_noma-1.0.2.tar.gz |
|---|---|
| Size | 98.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fd71a4db243bd0a0516e7f320bc677288523a66ce877e74702814d7c0ecb427c
|
|
BLAKE2b-256 checksum How to use checksums |
4f41627cd69250f551b8191a2701a7032623de7586940e0241821a3d484ac711
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.11.0
|
Release files / blackdrome_noma-1.0.2-py3-none-any.whl
| Download URL | blackdrome_noma-1.0.2-py3-none-any.whl |
|---|---|
| Size | 101.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6aef8775571f5092fd8bd2f9de8f950cf067368949534db6d8d7ce59a78d283b
|
|
BLAKE2b-256 checksum How to use checksums |
610bc8c66039abc639323369d48b034b4d28a7db6c9e038f6645a36f00c23a13
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.11.0
|














