
BlockStreamer
Licensed under the Apache License 2.0.
Execute ordered PyTorch blocks with pinned CPU master weights, asynchronous CUDA
prefetch, and at most prefetch_ahead + 1 resident blocks. Includes inference,
first-order training with backward re-fetch, correctness tests, and a measured
transfer/compute crossover benchmark.
Prior art and binding decision
Accelerate's cpu_offload_with_hook leaves a module on the execution device until
its offload hook runs; BlockStreamer instead schedules an explicit bounded window
of individual blocks and transfer-ready events.
Accelerate documentation
ZeRO-Infinity is a broader training system that spans GPU, CPU, and NVMe memory;
this project targets one GPU, CPU parameter storage, and an ordered block list.
ZeRO-Infinity paper
FSDP CPUOffload moves parameters and gradients to CPU within FSDP's sharding and
distributed training machinery; this library has no distributed collectives or
parameter sharding.
FSDP documentation
BlockStreamer's smaller scope makes the residency policy explicit, at the cost of
less general model execution and substantial Python/event overhead for tiny blocks.
Binding mechanism: torch.func.functional_call. Each block executes with a
dictionary of its staged GPU parameters and buffers, with strict key checking and
PyTorch's tied-weight handling. Registered parameters stay on pinned CPU storage.
Construction and .to() replace CPU storage to pin/convert it while preserving
Parameter identity; .data is never used to bind staged GPU weights for compute.
Functional-call documentation
The tradeoff is functional state discipline: blocks must not mutate registered parameters or buffers, retain staged tensors, or use custom kernels that cache parameter pointers outside module lookups. Detected registered-state mutation raises an error. Python attributes, global state, hooks, and opaque external caches cannot all be audited automatically; callers must keep those free of side effects. Training BatchNorm's running-state updates and mutable KV caches are unsupported. Ordinary dropout is supported through RNG replay during recomputation.
Install and run
Requires Python 3.11+, PyTorch 2.4+, and a CUDA GPU. Install a CUDA-enabled PyTorch wheel suitable for your GPU first. For the published package:
python -m pip install block-streamer
For development, clone the repository and install from its root:
python -m pip install -e ".[dev]"
python -m pytest -q
The development environment here uses .venv with the preinstalled CUDA PyTorch
available through system site packages. On this Windows workspace:
.venv/Scripts/python.exe -m pytest -q
.venv/Scripts/python.exe benchmark.py --widths 128 256 512 1024 --tokens 32 2048 8192 --runs 10 --warmup 4
import torch
from torch import nn
from block_streamer import StreamedModel

blocks = nn.Sequential(nn.Linear(256, 512), nn.GELU(), nn.Linear(512, 256))
x = torch.randn(16, 256, device="cuda:0", dtype=torch.bfloat16)

with StreamedModel(
    blocks, device="cuda:0", prefetch_ahead=1, dtype=torch.bfloat16
) as streamed:
    out = streamed(x)
    print(streamed.stats())
Construction takes ownership of the supplied Sequential, ModuleList, or list
of modules, pins their parameters and buffers on CPU, and defaults to .eval().
Make a deepcopy first if another model must retain independent state. Evaluation
forwards disable autograd, including when the caller did not use no_grad().
Call .train() to enable the training path. .eval() propagates to every block.
Inputs must already be on the execution device and have a suitable dtype. Additional positional and keyword arguments are passed unchanged to every block:
out = streamed(x, attention_mask=mask, position_ids=positions)
Every block must accept the supplied arguments. A block may return a tensor or a tuple whose first element is the next hidden state. Intermediate auxiliary tuple elements are discarded; the final block's entire result is returned. Tensor leaves in ordinary tuple/list/dict output trees are cloned so a returned parameter view cannot keep staged weights resident. There is no automatic per-layer KV-cache selection or collection; use adapter blocks to express that policy. Read-only attention masks, positions, rotary tensors, and cache values can pass through.
streamed.to(device="cuda:0", dtype=torch.float16) changes execution placement and
repins CPU state. Perform conversion before constructing an optimizer or a pending
training graph. CPU execution and inherited .cuda(), .cpu(), .half(), and
parent-module conversions are rejected; use this wrapper's .to() instead.
close() and context exit drain outstanding work; the wrapper remains reusable.
Streams, residency, and memory budget
The engine uses two streams: the compute stream active at construction and a
separate transfer stream. Borrowing the compute stream avoids creating persistent
cuBLAS workspaces for every new wrapper. A call made on another CUDA stream is
bridged to the compute stream, with input storage protected by record_stream().
The scheduler initially stages up to prefetch_ahead + 1 blocks. Compute waits on
each block's H2D-ready event. Every transfer-created tensor consumed by compute
calls record_stream(compute_stream) in BufferPool.acquire(), protecting it
from premature caching-allocator reuse.
PyTorch allocator documentation
A compute-completion event is host-synchronized before eviction and replacement
staging. This conservative retirement rule enforces the actual live-block limit,
including in-flight transfers, and introduces host scheduling overhead. The forward
returns after its work completes; H2D and compute can still overlap within it.
The GPU pool uses PyTorch's caching allocator with event-retired slots. Allocations
are sized per block, so heterogeneous shapes, integer buffers, and mixed state
dtypes require no homogeneous-buffer fallback. prefetch_ahead=0 is supported;
1 provides two slots. Parameter-free blocks still count as logical slots.
CUDA reserved cache memory may exceed live tensor payload and is not the
residency invariant. For heterogeneous models the byte bound is the largest live
window's summed state size, not a fixed number of bytes per block.
Set buffer_budget_bytes=... for a per-slot parameter-plus-buffer payload limit.
An oversized block raises a clear error before its copy. This is not a total-VRAM
budget: activations, CUDA library workspaces, gradients, and allocator rounding
are additional. Every H2D source is checked for pinned CPU storage immediately
before copying; an unpinned source fails loudly. Meta/sparse state and distinct
tensor objects sharing backing storage are rejected. Weight tying by sharing the
same Parameter object is supported within and across blocks.
stats() reports cumulative H2D bytes/time, D2H gradient bytes, GPU transfer-wait
time (stall_ms), host eviction wait time, current/peak resident blocks, and peak
parameter/state payload bytes. GPU stall time measures event waits on the compute
stream; it excludes host launch delays. Host eviction wait can include compute
and transfer waiting, so these two times must not be added as independent costs.
residency_history retains the last 4,096 transitions; an optional
residency_observer receives every transition. reset_stats() resets all counters.
Training design and usage
The inference suite passed on CUDA before the training implementation was added. The training design makes these choices:
- Re-fetch weights during backward. Keeping forward weights would require O(all blocks) parameter VRAM. Instead, save block inputs on GPU, discard staged weights, and re-fetch/recompute one block at a time during backward. A training step transfers each block's state twice and performs an extra forward compute. Saved activations remain O(depth); activation offloading is outside this project.
- Offload gradients after each block. Compute that block's gradients on GPU,
copy them into pinned CPU tensors on the compute stream, and make CPU reads wait
for the completion event. Return CPU parameter gradients through autograd so
normal
.gradaccumulation works. Peak GPU memory also includes one block's gradients and recomputation graph, plus saved activations and input gradients. Shared parameters' CPU gradient contributions are summed after copies finish. - CPU optimizer and state. Use an ordinary CPU optimizer on
model.parameters(). The optimizer step runs on CPU and does not stream to GPU. This incurs host RAM for all gradients/optimizer state. No automatic fp32 master-weight conversion, fused offloaded optimizer, or integrated loss scaling is provided. - Custom
torch.autograd.Function. It owns the forward/backward schedule, saves version-checked master state and block inputs, then visits blocks in reverse with the same bounded prefetch window. Block N-1 is fetched ahead of its recompute/backward while block N executes. This avoids relying on module hook order and explicitly returns gradients for tensor arguments and weights.
streamed = StreamedModel(blocks, dtype=torch.float32).train()
optimizer = torch.optim.Adam(streamed.parameters(), lr=1e-3)
x = torch.randn(16, 256, device="cuda")
target = torch.zeros_like(x)

for _ in range(10):
    optimizer.zero_grad(set_to_none=True)
    loss = (streamed(x) - target).float().square().mean()
    loss.backward()
    optimizer.step()  # CPU parameters, CPU gradients, CPU optimizer state
Recomputation restores PyTorch CPU/CUDA RNG states and CUDA autocast settings.
Backward does not advance the caller's RNG. First-order gradients, frozen/unused
parameters, tied weights, extra tensor arguments, and final tuple-output losses
are supported. Higher-order differentiation, torch.compile, CUDA graph capture,
distributed execution, and concurrent/reentrant calls are unsupported. Modules
must not modify block inputs in place, change execution behavior between forward
and backward, or retain GPU weights in external state. Normal in-place changes to
saved tensors are version-checked; edits through .data bypass PyTorch's protection.
Measured crossover and memory
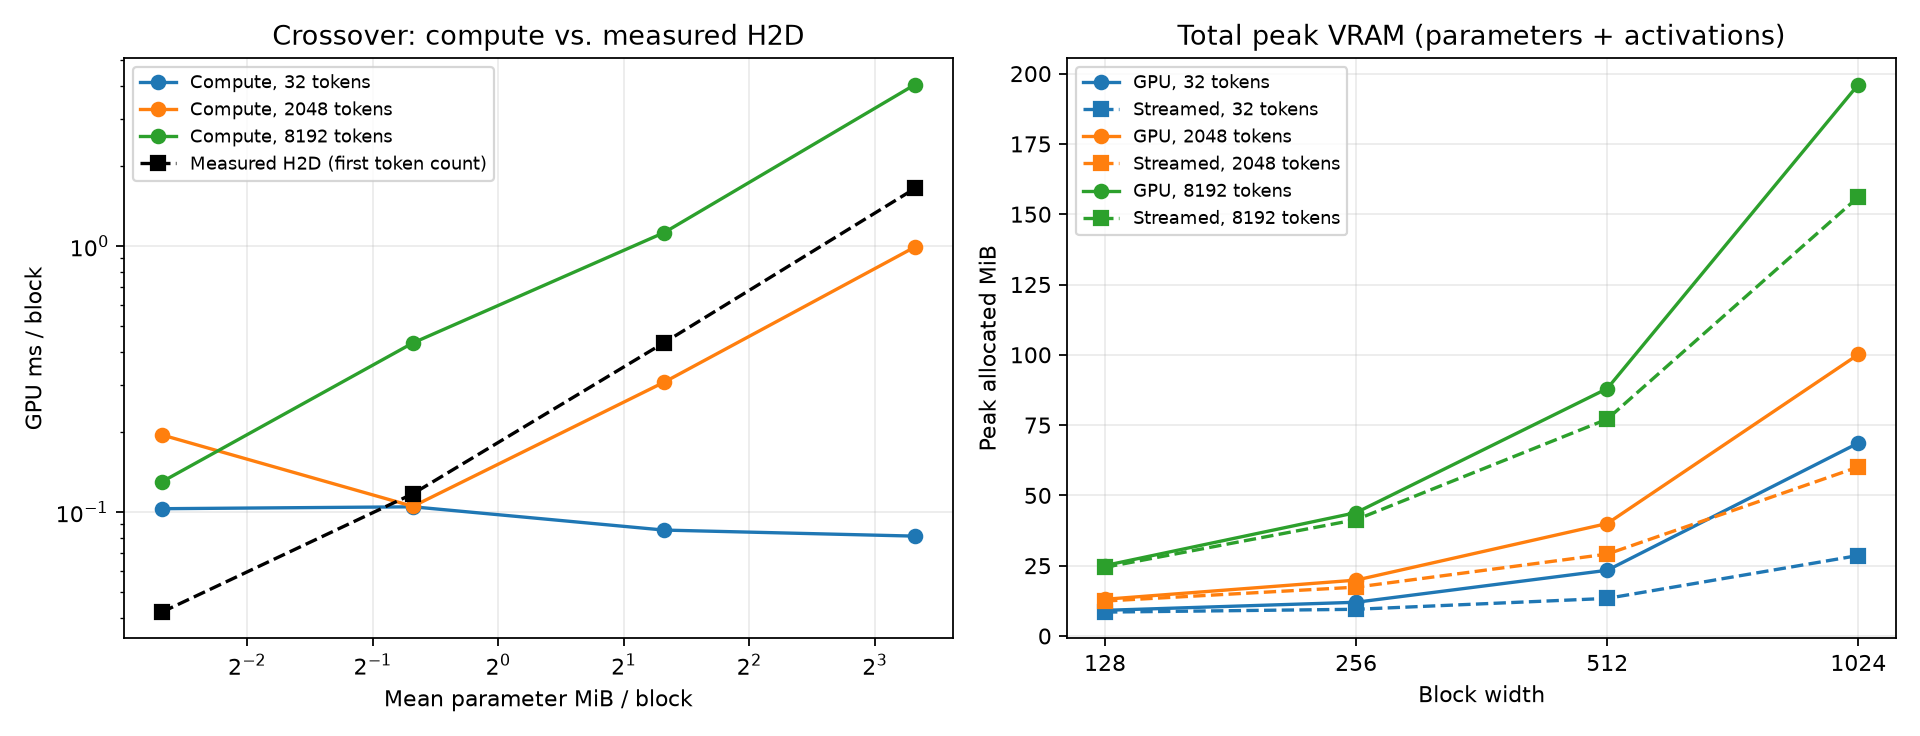
Local measurement: NVIDIA GeForce RTX 5050 Laptop GPU (8 GB), Windows WDDM,
PyTorch 2.11.0+cu128 / CUDA runtime 12.8, bf16, six heterogeneous MLP blocks,
prefetch_ahead=1, four warmups and ten timed runs. These are measurements on this
machine, not predictions for a desktop PCIe Gen4 x16 link. The benchmark records
31.5 GB/s as the nominal Gen4 x16 reference but uses measured pinned H2D time
for its conclusions. See the complete report.
Headline: at 32 and 2,048 tokens, the sampled compute/H2D crossover falls between widths 128 and 256. At 8,192 tokens, compute time exceeds H2D time at every sampled width; no width crossover was observed. At width 1,024, increasing tokens from 2,048 to 8,192 changes the measured regime from bandwidth-bound to compute-bound. Small-block CUDA event intervals include host launch gaps; the small-width "compute-bound" label means the measured compute path takes longer than H2D, not that GPU arithmetic units are saturated. This sweep is an empirical roofline diagnostic, not a hardware FLOP/s roofline or a universal crossover constant.
| Width / tokens | GPU median ms | Streamed median ms | GPU peak MiB | Streamed peak MiB | Activation/workspace increment MiB |
|---|---|---|---|---|---|
| 1,024 / 32 | 0.569 | 10.524 | 68.625 | 28.625 | 0.438 |
| 1,024 / 2,048 | 5.915 | 14.883 | 100.125 | 60.125 | 28.000 |
| 1,024 / 8,192 | 24.304 | 29.825 | 196.125 | 156.125 | 112.000 |
For these width-1,024 cases, baseline parameter payload is 60 MiB and streamed peak parameter payload is 20 MiB. The 8,192-token activation/workspace increment alone is 112 MiB: parameter streaming does not eliminate activation-dominated VRAM. This implementation saves memory but was slower in every sampled case.
The benchmark reports raw torch.cuda.max_memory_allocated() for total peak VRAM,
exact parameter/state tensor payload maxima, and an independently measured
activation/workspace increment: peak baseline allocation above the warmed baseline
with weights already resident. Existing input/library allocations are also recorded.
Separate maxima occur at different times; subtracting peak parameter payload from
total peak does not produce an exact activation peak. PyTorch's aggregate allocator
counter also cannot distinguish an activation from a temporary workspace.
Therefore an exact additive parameter-versus-activation split is not claimed.
Latency uses synchronized wall-clock intervals and reports medians, means, population variance, minima, and maxima. The requested overlap score is:
1 - (streamed_median_ms - all_on_GPU_median_ms) / isolated_H2D_ms
It is not clamped: Python, event, cloning, and scheduling overhead can make it negative; noise can put it above one. The score is 0.454 for width 1,024 / 8,192 tokens in this run. Kernel overlap cannot fully hide transfer when per-block H2D time exceeds compute time. Increasing token count changes arithmetic intensity; increasing width alone need not produce a crossover.
Profiler and validation status
benchmark.py exports results/trace.json, readable by Chrome tracing or Perfetto,
and checks whether GPU activities are present. On this machine CUPTI initialization
returned CUPTI_ERROR_INVALID_DEVICE, so the exported trace contains CPU events
only and trace_gpu_activity is false. GPU timeline overlap is therefore not
visually verified here. CUDA-event timing, real GPU parity tests, and memory
measurements did run. Re-run on a compatible CUPTI/driver setup to capture GPU
kernels and copies; --no-trace explicitly skips profiler collection.
The final local suite passed 32 tests on CUDA, with Ruff lint/format checks also passing. Tests cover inference in fp32/bf16/fp16 at prefetch depths 0–3, heterogeneous blocks and nonpersistent buffers, extra arguments and tuple results, every residency transition, a 100-iteration bandwidth-starved allocator stress, nondefault caller streams, inference mode, output aliases, tied weights, unpinned and over-budget errors, and exception cleanup. Training tests cover fp32/bf16/fp16 gradient parity at depths 1–3, CPU pinned gradients, extra-input gradients, dropout RNG replay, unused/shared parameters, accumulation, autocast with frozen weights, CPU Adam state placement, and a 12-step SGD toy loss curve.
Inference atol=rtol is 1e-5 for fp32, 8e-3 for bf16, and 1e-3 for fp16,
allowing roughly one low-precision rounding unit at unit scale. Backward
(atol, rtol) is (2e-5, 2e-4), (2e-3, 3e-2), and (5e-4, 5e-3) respectively;
backward includes reductions and multiple gradient contributions. The convergence
curves use fp32 with (2e-6, 2e-5) tolerances and must decrease by at least 10%.
These checks are evidence for the tested workloads, not proof for arbitrary custom
modules or hardware. The environment emitted a Triton CUDA-toolkit discovery
warning; the tests use PyTorch CUDA operations and do not require Triton compilation.
1 maintainer

Release files for block-streamer 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| block_streamer-0.1.0.tar.gz | 205.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| block_streamer-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 227.2 kB
Release files / block_streamer-0.1.0.tar.gz
| Download URL | block_streamer-0.1.0.tar.gz |
|---|---|
| Size | 205.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
27ff270f08d994bddf4e144e609cac1c6a420d1b6ae2b867c36a6abe13e5e4be
|
|
BLAKE2b-256 checksum How to use checksums |
65189cd210a1aa9c7e8431374ff11a9b92fd2c155c33e8981e695e0dd5d4a1ba
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.9 {"installer":{"name":"uv","version":"0.12.9","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / block_streamer-0.1.0-py3-none-any.whl
| Download URL | block_streamer-0.1.0-py3-none-any.whl |
|---|---|
| Size | 21.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1698236e4c545632df67485ed0952cb1fc3b49b2befa52c2fc17859cc6f7f482
|
|
BLAKE2b-256 checksum How to use checksums |
2879ec7cfe476659468135468dd5e9e947cf526d45d5408ef5895d5fb1c9afd1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.12.9 {"installer":{"name":"uv","version":"0.12.9","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|














