
c50py: C5.0 decision trees for Python, with native categorical splits




Decision trees were born able to split on categories. Quinlan's ID3, C4.5 and C5.0 ask questions like "is the sector in {mining, tourism, construction}?". scikit-learn's CART only splits on numbers, so categorical columns have to be one-hot encoded first, and one question becomes a staircase of dummy variables.
c50py brings the C5.0 way back to Python, as a scikit-learn estimator:
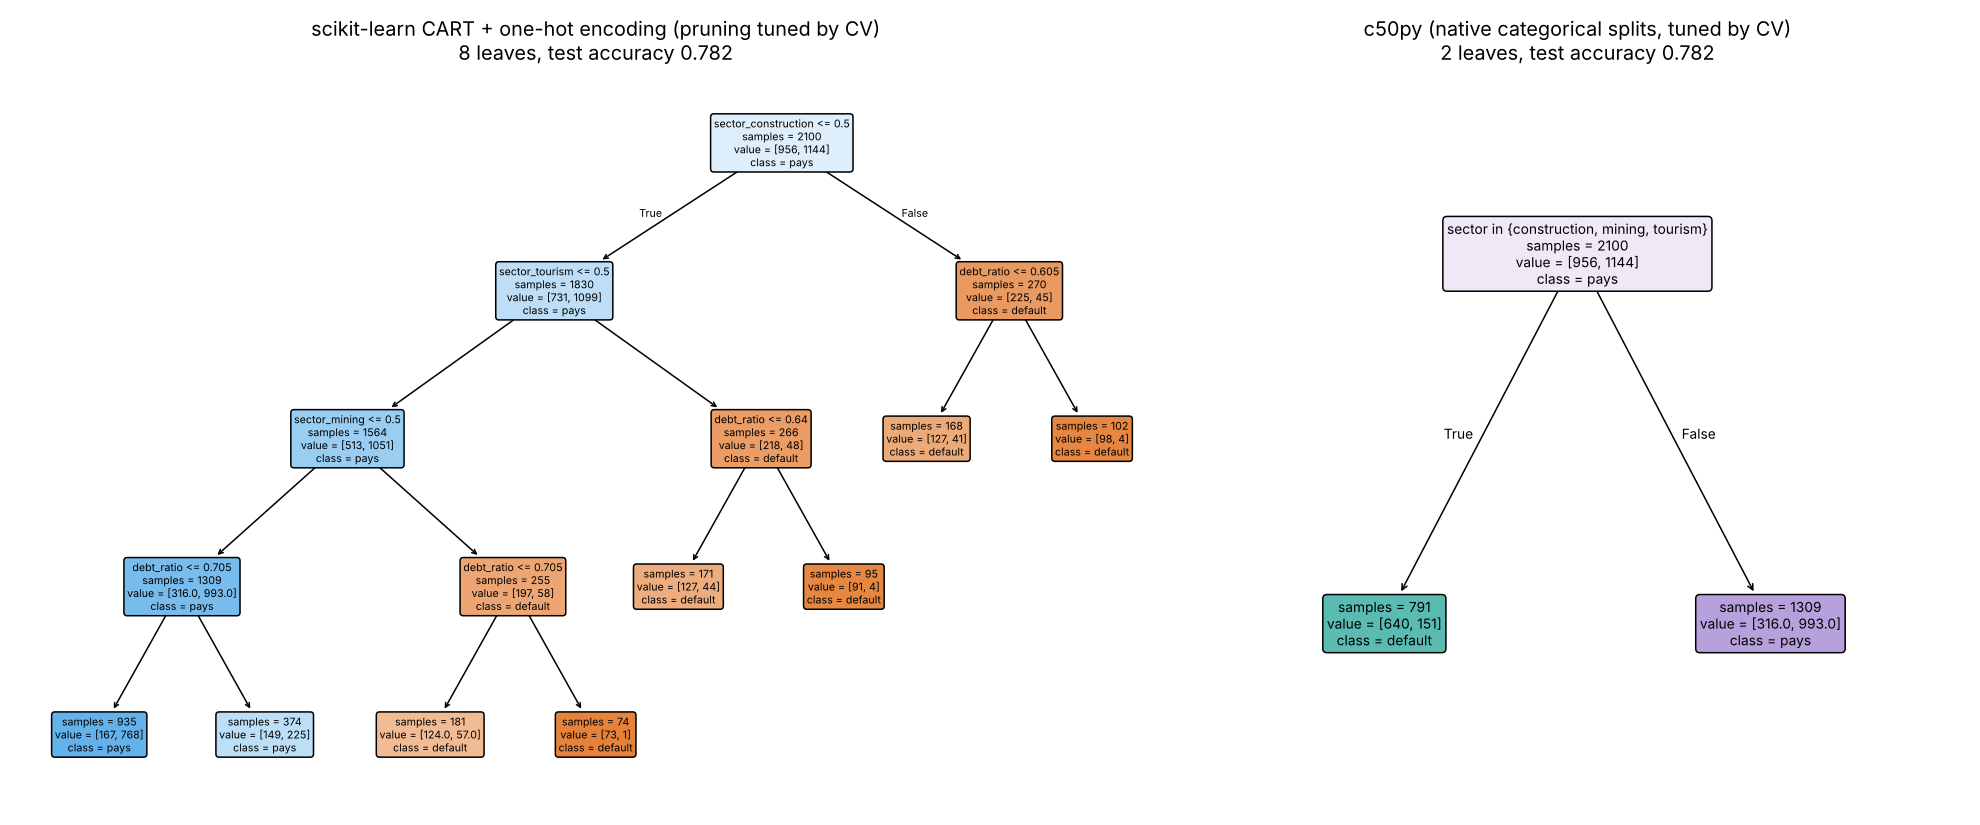
Same data, same test accuracy (0.782), both pruned by 5-fold cross-validation.
CART needs three dummy variables and 8 leaves; C5.0 asks one question.
Reproduce it with examples/make_readme_figure.py.
Every prediction of a C5.0 model comes from a rule a person can read. c50py gives both kinds of
rules C5.0 has: the rules of the tree (one per leaf; apply_rules(X) tells which one each row
follows) and C5.0's rulesets (C5RulesClassifier: fewer, shorter, overlapping rules with
confidence and lift), which turn a churn or credit model into segments a business can act on.
Notebooks
| Notebook | What it shows |
|---|---|
| 01 Getting started | A credit model on mixed data: fit, read, explain row by row, missing values, tuning, winnowing, boosting. |
| 02 c50py vs CART | One categorical question instead of a staircase of dummies; four real datasets, both trees tuned. |
| 03 c50py vs gradient boosting | How much accuracy a readable model gives up against HistGradientBoosting and random forests, and when it does not. |
| 04 Rules, rulesets and churn campaigns | Rules of the tree vs C5.0 rulesets, turned into retention campaigns by reason, down to each customer. |
| 05 Missing values and winnowing | How C5.0 handles gaps and irrelevant columns, what it buys and where it falls short. |
Each notebook opens in Colab from the badge at its top.
Install
pip install c50py
Python 3.9+, NumPy and scikit-learn. pandas is optional (DataFrames are used
directly) and matplotlib is needed for plot_tree.
Quickstart
import pandas as pd
from sklearn.model_selection import train_test_split
from c50py import C5Classifier

url = "https://raw.githubusercontent.com/daviddiazsolis/c50py/main/examples/titanic.csv"
df = pd.read_csv(url)
X = df[["pclass", "sex", "age", "fare", "embarked"]].astype({"pclass": "category"})
y = df["survived"].map({0: "died", 1: "survived"})
X_tr, X_te, y_tr, y_te = train_test_split(X, y, test_size=0.3, random_state=0)

# no one-hot encoding, no imputation: sex, embarked and pclass are used as
# categories, and the missing ages are handled by the tree
clf = C5Classifier(min_samples_leaf=10).fit(X_tr, y_tr)
print(f"test accuracy: {clf.score(X_te, y_te):.3f}")      # 0.794

for rule in clf.export_rules():
    print(rule)
# sex IN {male} => died
# sex NOT IN {male} AND pclass IN {3} AND fare <= 23.3500 => survived
# sex NOT IN {male} AND pclass IN {3} AND fare > 23.3500 => died
# sex NOT IN {male} AND pclass NOT IN {3} => survived

clf.plot_tree(filled=True, rounded=True)   # same look and options as sklearn.tree.plot_tree
A scikit-learn estimator
C5Classifier and C5Regressor pass scikit-learn's check_estimator, so they
work with clone, Pipeline, cross_val_score, GridSearchCV and the rest
of the ecosystem:
from sklearn.model_selection import GridSearchCV

grid = GridSearchCV(C5Classifier(), {"cf": [0.1, 0.25, 0.5], "min_samples_leaf": [1, 5, 20]}, cv=5)
grid.fit(X_tr, y_tr)
print(grid.best_params_, grid.score(X_te, y_te))
What C5.0 does differently from CART
| scikit-learn CART | c50py (C5.0) | |
|---|---|---|
| Categorical columns | must be encoded (one-hot, ordinal) | split natively: sector in {a, b, c} |
| Missing values | imputed, or one learned direction | cases go down both branches with fractional weights, as in C4.5/C5.0 |
| Split criterion | Gini or entropy | gain ratio, among splits with at least average gain, with MDL costs for thresholds and groupings |
| Pruning | cost-complexity (ccp_alpha) |
pessimistic error pruning with confidence factor cf, subtree raising and C5.0's global pruning |
| Rules | export_text |
rules of the tree (export_rules, apply_rules) and C5.0 rulesets (C5RulesClassifier) |
| Feature selection | separate step | built in: winnow=True |
| Boosting | separate AdaBoostClassifier |
built in: trials=10, C5.0's boosting |
Main features
- Classification and regression:
C5Classifier,C5Regressor. - Categorical columns detected automatically: pandas
category,object,stringandboolcolumns, or object columns holding strings. You can also list them withcategorical_features=["region", 3](names or indices). - Missing values (
None,np.nan,pd.NA) in training and prediction. - Case weights through
sample_weight. - Boosting with
trials > 1, following C5.0 (reweighting, voting by leaf confidence, early stop). - Winnowing (
winnow=True): C5.0's screen of irrelevant columns; the dropped ones are listed inwinnowed_features_. - Rules of the tree:
export_rules()(one rule per leaf),apply(X)(the leaf number, as in scikit-learn),apply_rules(X)andpredict_rule(X)(the rule each row follows). - Rulesets:
C5RulesClassifier(ortree.build_ruleset(X, y)) builds C5.0's rulesets;export_ruleset()lists them with confidence and lift,apply_ruleset(X)gives the rule behind each prediction. - Drawings identical to scikit-learn:
plot_tree,export_graphvizandexport_text, with the same parameters. Boxes use c50py's own palette so a C5.0 tree is easy to tell apart from a CART tree (palette="sklearn"gives scikit-learn's colours).
Regression
from sklearn.datasets import load_diabetes
from c50py import C5Regressor

X, y = load_diabetes(return_X_y=True, as_frame=True)
reg = C5Regressor(min_samples_leaf=20).fit(X, y)
print(reg.export_rules()[:3])
Key parameters
| Parameter | Default | Meaning |
|---|---|---|
cf |
0.25 |
Confidence factor for pruning; smaller values prune more. |
min_samples_leaf |
2 |
Minimum (weighted) cases in each child (C5.0's minCases). |
global_pruning |
True |
C5.0's global cost-complexity pruning (classifier). |
trials |
1 |
Number of boosted trees (classifier). |
winnow |
False |
C5.0's winnowing of irrelevant columns before the final tree. |
categorical_features |
None |
Extra columns to treat as categorical, by name or index. |
infer_categorical |
True |
Detect categorical columns from their dtype or content. |
max_categories_exhaustive |
12 |
Up to this many categories every binary subset is evaluated. |
max_depth |
None |
Optional depth limit. |
The Usage Guide covers every option.
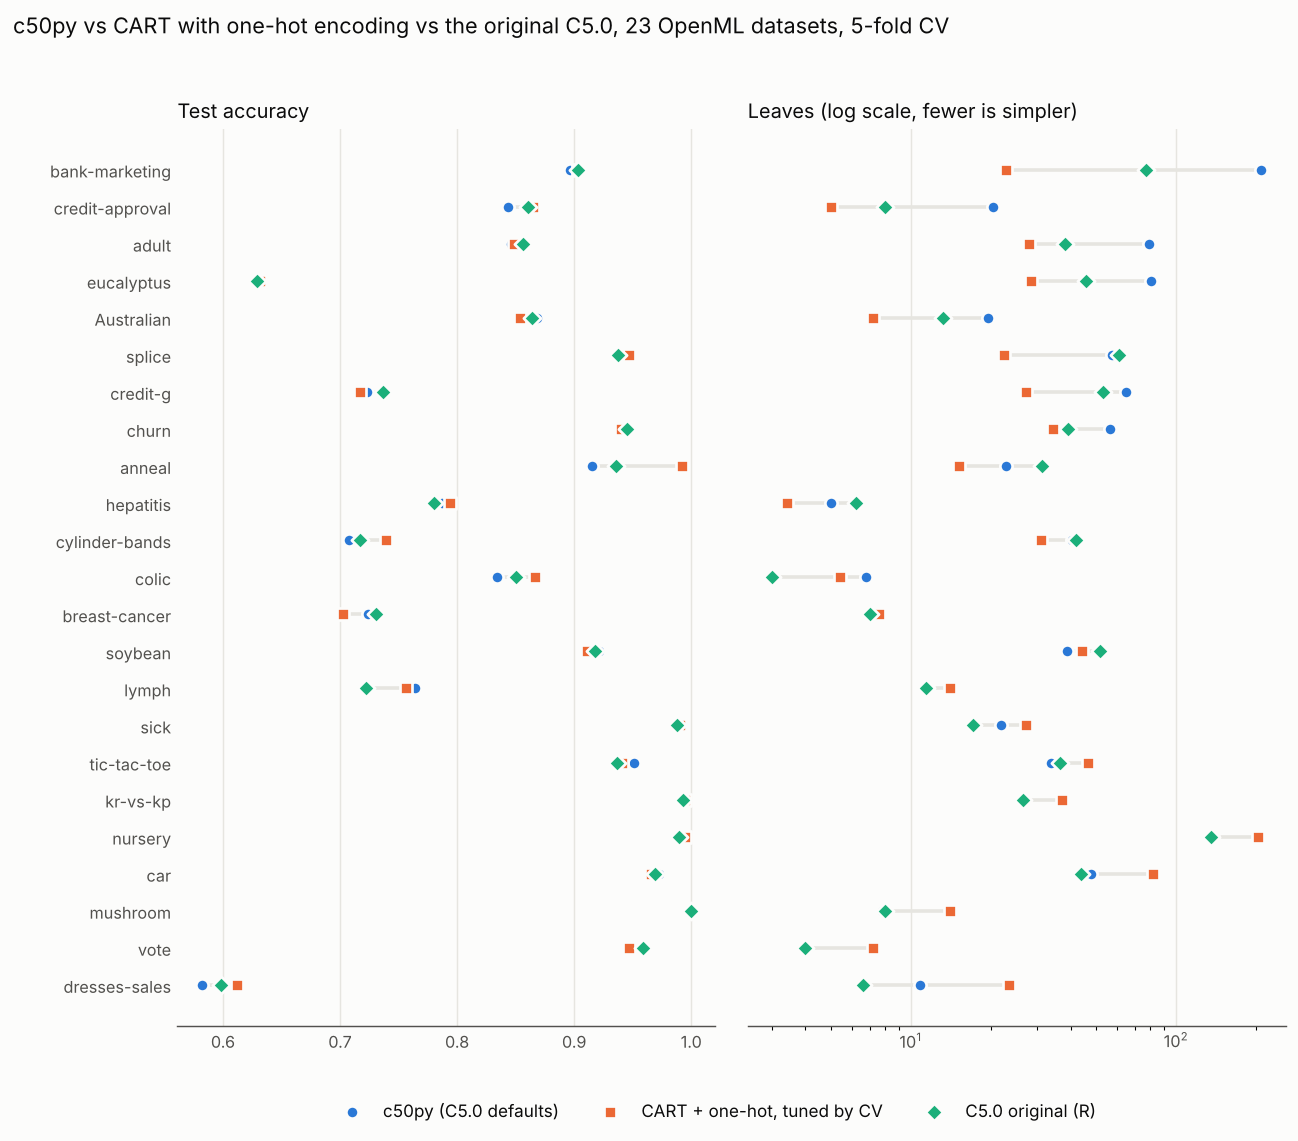
Benchmark: c50py vs CART, gradient boosting and the original C5.0
23 OpenML classification datasets with categorical columns (9 all categorical, 14 mixed), the same 5
stratified folds for every model (benchmarks/run_benchmark.py; full tables in
benchmarks/results/summary.md):
| accuracy | leaves or rules | tests per rule | all categorical | mixed | |
|---|---|---|---|---|---|
| c50py tree, defaults | 0.860 | 43.9 | 6.5 | 0.939 | 0.809 |
c50py tree, cf tuned by CV |
0.862 | 30.1 | 5.8 | 0.942 | 0.810 |
c50py ruleset (C5RulesClassifier) |
0.863 | 21.3 | 3.3 | 0.942 | 0.812 |
c50py boosting, trials=10 |
0.879 | 0.943 | 0.837 | ||
| CART + one-hot, scikit-learn defaults | 0.848 | 152.1 | 8.7 | 0.928 | 0.797 |
| CART + one-hot, pruning tuned by CV | 0.866 | 32.0 | 5.3 | 0.934 | 0.822 |
| HistGradientBoosting, native categories | 0.877 | 0.938 | 0.839 | ||
C5.0 original (R C50), tree |
0.862 | 33.2 | 0.937 | 0.813 | |
C5.0 original, rules = TRUE |
0.868 | 17.9 | 0.945 | 0.819 | |
C5.0 original, trials = 10 |
0.878 | 0.945 | 0.835 |
Paired Wilcoxon tests over the 23 datasets:
- Faithful to C5.0. Tree: -0.2 accuracy points against the original (p = 0.31). Ruleset: -0.5 points (p = 0.07). Boosting: +0.1 points (p = 0.72).
- Against CART as usually run (one-hot, default settings): +1.2 points (p = 0.02) and 64% fewer leaves.
- Against CART with tuned pruning: the same accuracy (tree -0.6 points, p = 0.55; ruleset -0.3 points, p = 0.78). The ruleset needs 28% fewer rules than the tuned tree has leaves (p = 0.03), and each rule has 3.3 tests against 5.3. On all-categorical data the C5.0 models are more accurate and smaller; on mixed data tuned CART is about one point more accurate than a C5.0 tree (the original C5.0 included) and smaller.
- Against gradient boosting: a single tree is 1.8 points less accurate (p = 0.007) and a ruleset 1.4 points (p = 0.02); C5.0's boosting is as accurate as HistGradientBoosting (+0.1 points, p = 0.43). On all-categorical data the single tree and the ruleset are as accurate as HistGradientBoosting.
How close is it to Quinlan's C5.0?
c50py is a from-scratch Python implementation that follows C4.5/C5.0 in the split criterion (gain
ratio among features with at least average gain, best split within a feature by gain, MDL costs), the
minimum split sizes, the handling of missing values, the pruning (pessimistic error with cf, subtree
raising and C5.0's global pruning), winnowing, rulesets and boosting, and has been checked against the
original C5.0 (above). Differences that remain:
- splits are binary: categorical splits group categories into two subsets, where C5.0 builds multiway splits (one branch per category or group). Binary trees are what scikit-learn's drawing tools expect, and they explain most of the remaining size difference (c50py trees have 1.24x C5.0's leaves);
- rulesets are built from that binary tree, so they differ in detail from C5.0's (1.15x as many rules);
- no misclassification costs and no sampling options.
Contributions are welcome.
Citation
If you use c50py in research, please cite it (a JOSS submission is in
preparation; meanwhile cite the repository):
@software{diaz_solis_c50py,
  author = {D{\'i}az Sol{\'i}s, David},
  title  = {c50py: C5.0 decision trees for Python},
  url    = {https://github.com/daviddiazsolis/c50py},
  year   = {2026}
}
Contributing and license
Bug reports and pull requests are welcome; see CONTRIBUTING.md
and the CHANGELOG. c50py is released under the MIT License.
The drawing code is adapted from scikit-learn (BSD-3-Clause).
1 maintainer

Metadata
1 maintainer
Release files for c50py 0.5.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| c50py-0.5.0.tar.gz | 67.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| c50py-0.5.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 125.2 kB
Release files / c50py-0.5.0.tar.gz
| Download URL | c50py-0.5.0.tar.gz |
|---|---|
| Size | 67.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
90cdb3e2250719d9e791448625765155561ca4d2fd5717db824487ae46b87c1c
|
|
BLAKE2b-256 checksum How to use checksums |
e6c60ade33af92597ebadca47216266a8c42b72bfc509d44aa37fa3e3f3989c6
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 2, 2026.
Transparency logRelease files / c50py-0.5.0-py3-none-any.whl
| Download URL | c50py-0.5.0-py3-none-any.whl |
|---|---|
| Size | 57.4 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
971cbe13131dc365126eca153bfa237b007e1c99297a08a219f8a3e7e0fda23c
|
|
BLAKE2b-256 checksum How to use checksums |
d06549e754de2d7d77b8d53d24392e87452f42f00b7dab0c6c043b835b2c6c74
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 2, 2026.
Transparency log













