
cachemaxxing




Stop paying full price for the same tokens.
Anthropic, OpenAI and Gemini bill a repeated prompt prefix at a fraction of the input price, but only when the bytes really repeat. cachemaxxing finds where they don't, tells you what it costs, and lays your prompts out so they do. It is a thin library, not a proxy: zero runtime dependencies, and you keep your own SDK client.
- Measure.
usage()turns any provider's response into the same numbers: input, cache read, cache write, output, estimated $ and hit rate.cachemaxxing reporttotals them per call site. - Diagnose.
cachemaxxing diffshows the first byte where two consecutive requests diverge, and why. - Fix.
Promptorders your prompt from most to least stable and places each provider's cache markers for you.
from cachemaxxing import Prompt, usage

p = Prompt(call_site="support.answer")
p.tools(TOOLS).system(SYSTEM).context(DOCS).history(messages).retrieved(chunks).user(question)

resp = client.messages.create(max_tokens=1024, **p.anthropic("claude-haiku-5-5"))

u = usage(resp)
print(f"{u.hit_rate:.0%} of input from cache, ~${u.est_cost or 0:.4f}")
Works with
| How | |
|---|---|
| Anthropic | client.messages.create(**p.anthropic(model)) |
| OpenAI | client.responses.create(**p.openai(model)) or client.chat.completions.create(**p.openai_chat(model)) |
| Gemini | client.models.generate_content(**p.gemini(model)), with an explicit cache via gemini_cache() when should_cache() says it pays |
| LiteLLM | litellm.completion(**p.litellm("anthropic/claude-haiku-5-5")) |
| LangChain agents | create_agent(..., middleware=[CacheMiddleware("support.agent")]) |
| LangGraph graphs, LCEL chains | llm = CachedModel(chat_model, system=SYSTEM), then llm.invoke(state["messages"]) |
On OpenAI GPT-5.6+ it places explicit cache breakpoints. On Anthropic it places cache_control markers, at most 4. Gemini stays on implicit caching unless an explicit cache pays.
Find the misses
$ cachemaxxing report calls.jsonl --min-hit-rate 0.6     # from record() logs; exits 1 below the threshold
call site   calls  hit rate  input   cache read  cache write  output  est $   top drift
rag.answer  4      88.8%     31,574  28,024      714          2,601   0.0020

$ cachemaxxing diff request_1.json request_2.json
diverges at system[0].text char 41 (timestamp), after ~14 matching tokens
  a: 'You are helpful. Today is 2026-10-30T10:00:00Z.'
  b: 'You are helpful. Today is 2026-10-30T10:05:00Z.'
Benchmark
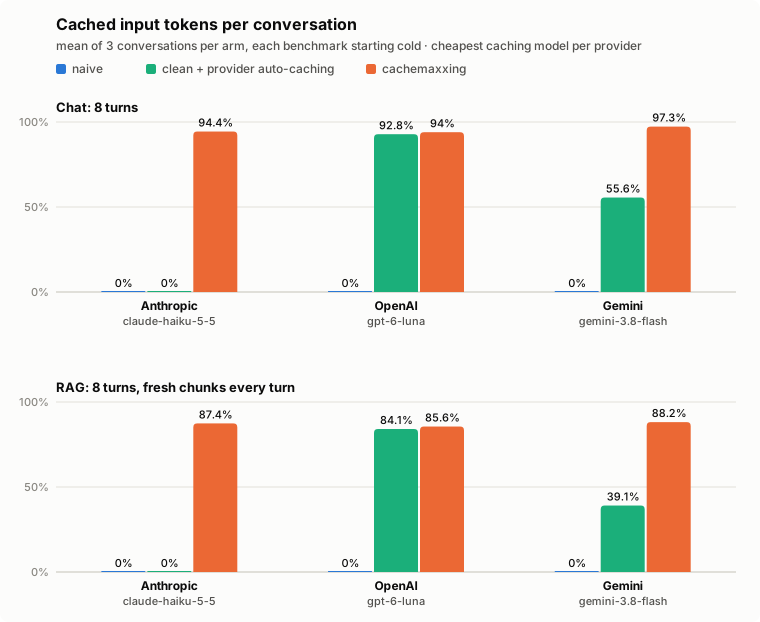
| Provider | Model | Cached input | $ per conversation | Saving |
|---|---|---|---|---|
| Anthropic | claude-haiku-5-5 |
0.0% → 94.8% | $0.0092 → $0.0017 | 82% |
| OpenAI | gpt-6-luna |
0.0% → 93.1% | $0.0070 → $0.0012 | 83% |
| Gemini | gemini-3.8-flash |
0.0% → 97.5% | $0.0484 → $0.0094 | 80% |
The same 8-turn conversation was run for 3 customers per arm, each starting from a cold cache. Costs are estimates at list price. The naive arm has four common habits: a timestamp at the top of the prompt, tool order that varies, JSON key order that varies, and history re-rendered every turn. The Gemini row uses an explicit cache, with its creation and storage cost included; with implicit caching alone it reached 40.0%. Data: benchmarks/results/, 2026-10-30.
Examples
examples/quickstart.py: one prompt, every provider and LiteLLMexamples/rag_chat.py: a multi-turn RAG chat with per-turn retrieval, logging and a reportexamples/langchain_agent.py: a LangChaincreate_agentagent withCacheMiddlewareexamples/langgraph_custom.py: a hand-built LangGraph graph withCachedModel
Install
pip install cachemaxxing                  # or: uv add cachemaxxing
pip install "cachemaxxing[anthropic]"     # extras: anthropic, openai, gemini, litellm, langchain
Docs: https://ashhadahsan.github.io/cachemaxxing/ covers the quickstart, how caching works per provider, diagnosing a low hit rate, LangChain and LangGraph, the API reference, and how it compares.
MIT licensed.
1 maintainer

Metadata
1 maintainer
Release files for cachemaxxing 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| cachemaxxing-0.2.0.tar.gz | 21.4 kB | With provenance | Details for cachemaxxing-0.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| cachemaxxing-0.2.0-py3-none-any.whl | Python 3 | none | any | Details for cachemaxxing-0.2.0-py3-none-any.whl |
Total release size: 46.6 kB
Release files / cachemaxxing-0.2.0.tar.gz
| Download URL | cachemaxxing-0.2.0.tar.gz |
|---|---|
| Size | 21.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a8c35b364632983d1917da027154c3d86ded1c4b3d037f565f4031e7a3dd67bc
|
|
BLAKE2b-256 checksum How to use checksums |
1f9c8cbda5cc586699d70e2dd4ba8164aff2505d18bcec719d2fbcce28228c8a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 30, 2026.
Transparency logRelease files / cachemaxxing-0.2.0-py3-none-any.whl
| Download URL | cachemaxxing-0.2.0-py3-none-any.whl |
|---|---|
| Size | 25.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
46e8936b234e2b4a1630e6df4eaa13d876720a1889051cc014fd8831ffef9a96
|
|
BLAKE2b-256 checksum How to use checksums |
551856f65375cbaefa657104389119ba39fb259df3c33d3758cb7844f7bde13e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 30, 2026.
Transparency logSecurity for cachemaxxing 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for cachemaxxing-0.2.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 30, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














