
CJE: Causal Judge Evaluation
Reuse an informative judge and available outcome labels to reduce the labeling needed for policy evaluation. CJE calibrates judge scores against ground-truth labels, estimates policy means and paired differences, and reports uncertainty under explicit sampling and transport assumptions. The savings come from applying that calibration to many responses and, where supported, across policies or evaluation cycles.


60 seconds
pip install cje-eval
Upgrading to 0.8.0: Refit saved two-stage calibrators to rebuild their empirical-rank boundaries with the corrected prediction arithmetic. Calibrated scores are now stable when prediction rows are split into batches or reordered; values at learned rank boundaries can differ from earlier versions. See the release notes.
Using a coding agent? The bundled skill covers data reshaping, calibration, comparisons, and diagnostics.
You need responses from each policy on a shared prompt set, a score for every response from one fixed LLM judge, and ground-truth labels (oracle_label) on a probability-sampled slice. Labels can be human ratings, expert reviews, or observed outcomes. Stratification can improve score-range coverage; record inclusion probabilities if sampling rates differ.
Each record is one judged response: {"prompt_id", "judge_score", "oracle_label" (optional)}. The API calls evaluation responses fresh draws. They can be newly generated or observed responses retained in logs, provided the sampling design supports the policies and population you are evaluating. Historical judge/outcome pairs can also supply separate calibration data. Neither use estimates an unseen policy's outputs from another policy's logs. Any bounded judge and oracle scales work (0–1, 0–100, Likert); they need not match.
from cje import analyze_dataset

# Two policies, gpt-5.6 vs fable-5, each answered the same 20 prompts.
# A separate fixed judge model scored all 40 responses; human raters
# labeled a random half of gpt-5.6's (None = not labeled).
judge_scores = {
    "gpt-5.6": [0.62, 0.68, 0.72, 0.76, 0.79, 0.83, 0.85, 0.88, 0.91, 0.95,
                0.64, 0.69, 0.73, 0.77, 0.80, 0.84, 0.87, 0.89, 0.92, 0.94],
    "fable-5": [0.70, 0.74, 0.75, 0.78, 0.81, 0.83, 0.86, 0.90, 0.93, 0.94,
                0.72, 0.76, 0.79, 0.80, 0.84, 0.85, 0.88, 0.89, 0.91, 0.95],
}
human_labels = [0.55, 0.60, 0.70, 0.74, 0.75, 0.80, 0.90, 0.92, 0.88, 0.97,
                None, None, None, None, None, None, None, None, None, None]

# gpt-5.6's labeled slice calibrates the judge for BOTH policies. Reusing
# that map for fable-5 is an assumption; the output flags it as
# "residual transport NOT_CHECKED" until a held-out probe audit grades it.
draws = {
    "gpt-5.6": [
        {"prompt_id": f"q{i:02d}", "judge_score": s, "oracle_label": y}
        for i, (s, y) in enumerate(zip(judge_scores["gpt-5.6"], human_labels))
    ],
    "fable-5": [
        {"prompt_id": f"q{i:02d}", "judge_score": s}
        for i, s in enumerate(judge_scores["fable-5"])
    ],
}
results = analyze_dataset(fresh_draws_data=draws)
print(results.summary())
CJE Estimation Results (method: calibrated_direct)
  fable-5  0.824  95% CI [0.766, 0.882]
  gpt-5.6  0.786  95% CI [0.706, 0.866]
Best by point estimate: fable-5
Limitations: residual transport NOT_CHECKED
Status: warning
Both policies get a calibrated estimate and a confidence interval, including fable-5, which has no labels of its own. Its calibration reuse remains NOT_CHECKED until supported by a held-out audit. This small synthetic example demonstrates the API, not adequate power for a real evaluation. The intervals account for evaluation sampling and the finite label budget; interpreting them still depends on the sampling design and shared-calibration assumptions.
→ Runnable Colab with real data · Full docs
Use CJE from your AI agent
You don't have to learn the API yourself. skills/cje/ teaches a coding agent to reshape eval data, plan labels, calibrate, compare, and report diagnostics. It's plain Markdown: any agent can use it, and agents with skill support load it natively. Or just paste:
Read https://raw.githubusercontent.com/cimo-labs/cje/main/skills/cje/SKILL.md,
then use CJE to compare the policies in my eval data.
Is CJE the right tool?
| Your situation | Use |
|---|---|
| Rank/compare policies using an LLM judge, with some ground-truth labels | CJE |
| One dataset, labels sampled from it, want a CI on its mean | CJE's calibrated_mean_ci provides a prediction-powered mean estimate with diagnostics |
| Evaluate many policies without labeling under each | CJE. Labels pool across policies; audit that reuse with held-out probes before relying on it |
| Predict how a specific response will score | Per-item prediction (e.g. conformal methods) |
| Counterfactual estimates for unobserved policy outputs using importance weighting / doubly robust OPE | The frozen cje-eval==0.3.* OPE line. Current CJE is Direct-mode only (see Why Direct mode only?) |
How it works
- Calibrate: learn the judge → oracle mapping on the labeled slice (isotonic, two-stage when needed; mean-preserving by construction; cross-fitted).
- Evaluate: score every policy's fresh responses through the calibrated judge and compare policies on the same prompts.
- Diagnose: automatically report scalar score-range support, and optionally run a held-out residual equivalence audit with a predeclared practical margin. These answer different questions and are reported separately.
Confidence intervals include finite-label calibration uncertainty on supported inference paths. Their interpretation still depends on the oracle sampling design, shared-calibration assumptions, and any transport claims being made.
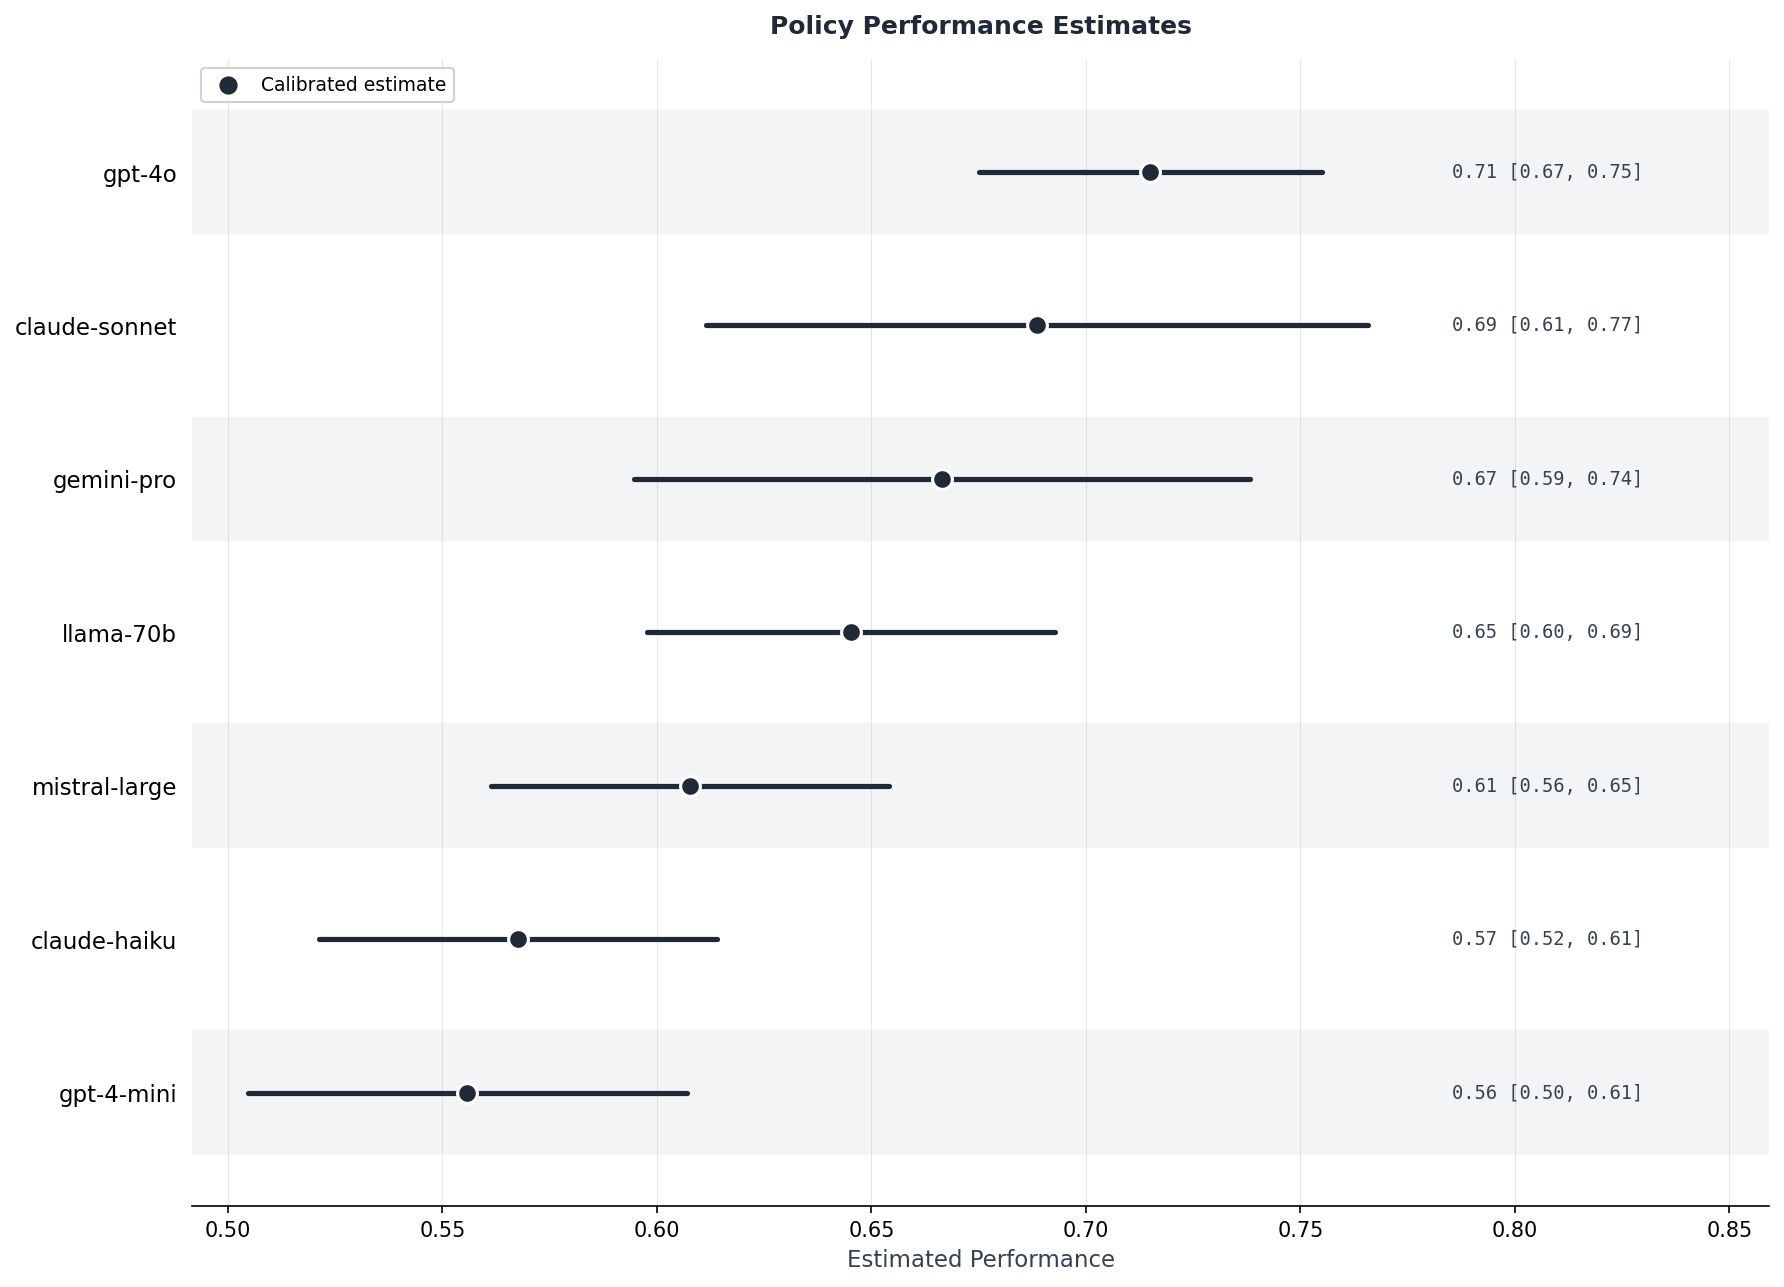
Calibrated estimates with 95% CIs under the experiment's stated sampling and calibration assumptions
Validation on real ground truth
- HealthBench Consensus (29,511 response–criterion records): a custom confidence-augmented regrade found judge overconfidence of 24.5 and 13.0 percentage points against strict positive physician majority, with ties coded not met (14.4 and 3.0 points against mean physician agreement). One seeded retrospective replay exposed 5% of aggregate labels (1,454 endpoints, each based on 2–5 physician grades); calibrated estimates were within 1.4–2.1 points of the full aggregate endpoint. This was not prospective annotation or repeated-split validation. Read the full audit →
- Chatbot Arena (4,961 prompts, 5 policies): 99% pairwise ranking accuracy in the headline 5%-oracle configuration, with 94% average accuracy across configurations, against a stronger model's ratings standing in for human labels (a model-reference study, not human validation). The arXiv v3 cost model gives a 14× reduction against full labeling under that reference. In this benchmark, calibration-aware intervals achieved ~95% coverage versus 0% for naive judge-score intervals. An adversarial policy that fools the judge is correctly flagged by the transport audit. Paper →
How many labels will a judge save you? When representative labels correct a policy's estimate, the judge acts as a control variate: at equal precision it saves about the share of the outcome's variance it explains within a policy (its squared within-policy correlation with the label), not its overall agreement rate. Agreement on easy, lopsided comparisons does not reduce audit labels. Before planning around savings, label a pilot slice of a few hundred responses with the outcome you will actually report and measure that share; when it is below about 0.10, budget labels as if there were no judge and use the judge for triage and for ordering clear differences.
Guardrails: claims CJE refuses to make
Diagnostics never act silently; every estimate ships with its limitations attached.
Score-support badge (automatic). Each policy gets a scalar badge checking whether its judge scores extrapolate beyond the labeled score range. When at least 5% of scores land outside it, the estimate carries REFUSE-LEVEL:
REFUSE-LEVEL for policy 'candidate': 88.3% of fresh-draw judge scores fall
outside the oracle calibration range [0.161, 0.595]. Do not report level
(absolute) claims for this policy from this fit. Collect oracle labels covering
the missing score range.
The badge checks scalar support only; it does not test mean residual bias, covariate shift, or ranking validity.
Residual transport audit (opt-in). Reusing a calibration map on another policy, time period, or domain is an assumption. Grade it with held-out oracle probes that were not used to fit the calibrator, plus a predeclared practical margin:
from cje import TransportAuditConfig

transport = TransportAuditConfig(
    probes_by_policy={"fable-5": held_out_probe_rows},  # same record shape as draws, oracle_label filled
    delta_max_by_policy={"fable-5": 0.03},  # OUTPUT units (units of results.estimates)
)
results = analyze_dataset(fresh_draws_data=draws, transport=transport)
print(results.metadata["transport_audits"]["fable-5"]["status"])
PASS requires the simultaneous residual CI to lie wholly inside [-delta_max, +delta_max]; wholly outside is FAIL; overlap is INCONCLUSIVE; omitting the margin is NOT_GRADED. Fewer than 20 effective clusters withholds PASS but can still grade FAIL; a policy cannot escape a FAIL by supplying too small a probe. Policies without probes stay NOT_CHECKED. Among these audit states, only an observed FAIL hard-flags a policy whose estimate depends on that map; every other unresolved state remains visible as a limitation without suppressing the estimate. For an already fitted calibrator, the array primitive transport_audit(probe_scores, probe_labels, results.calibrator, delta_max=...) runs the same audit directly.
Use audit labels for correction. Audit-only probes do not alter the point estimate. Attach probability-sampled labels to their matching evaluation responses to use the existing augmented estimator, then inspect metadata["point_estimator"]["routes"] and the recomputed intervals. The audit-to-correction guide includes a runnable example that keeps calibration fixed and distinguishes correction from independent validation.
Plan audit labels before collecting them. plan_transport_audits estimates independent audit units under declared residual assumptions, checks availability, and counts calibration plus audit ratings in the human-label budget. It is a Gaussian planning model, not an observed audit. See the audit budget guide.
Reliability-aware winner. results.best_policy() demotes a gate-flagged argmax to the best gate-passing policy (the default, reliable_only=True), and the demotion is loud; the flagged raw winner stays visible with its limitations (reliable_only=False returns the raw argmax, marked flagged):
Best by point estimate: candidate
Limitations: flagged by the reliability gates; residual transport NOT_CHECKED
Best reliable policy: baseline — raw argmax candidate was flagged (boundary:
88.3% of judge scores outside the oracle calibration range); pass
reliable_only=False for the raw argmax
Levels, rankings, and production outcomes
A level claim concerns the mean oracle outcome. A ranking concerns a difference between policies. For a pair, the oracle difference equals the calibrated-prediction difference plus the difference in policy mean residuals. A common residual offset cancels, so a failed level audit does not by itself prove the ordering wrong. Conversely, individual-score monotonicity or a scalar support badge does not certify policy ordering under a shift. Use compare_policies and evidence about the residual difference; CJE has no validated automatic label-free reuse gate.
Production outcomes can reduce new annotation cost when their meaning and response identity match the evaluation. Document how feedback was selected, the target population, dependence clusters, and any change in the judge or outcome process. Organic feedback is not automatically representative. Report incremental annotation cost separately from total label acquisition cost, and audit transport before relying on reuse across populations or time.
The array API
calibrated_mean_ci is the library's bottom layer: a ppi_py-style primitive accepting NumPy arrays and returning a calibrated mean and confidence interval. Reach for it when you have one sample of judge scores with ground-truth labels on a random slice; use analyze_dataset for multi-policy comparisons. The interval accounts for both sampling noise and the finite label budget (prompt-cluster-robust variance plus a delete-one-oracle-fold jackknife; t interval with Welch–Satterthwaite effective df); inference="bootstrap" switches to refit-bootstrap percentile intervals.
import numpy as np
from cje import calibrated_mean_ci

rng = np.random.default_rng(0)
scores = rng.uniform(size=400)                      # judge scores for every sample
labels = np.full(400, np.nan)                       # NaN = unlabeled
labeled = rng.choice(400, size=100, replace=False)  # oracle slice (25%)
labels[labeled] = np.clip(scores[labeled] + rng.normal(0, 0.1, size=100), 0, 1)

result = calibrated_mean_ci(scores, labels)
print(result.summary())
Calibrated mean: 0.5316 (SE 0.0174, CI [0.4974, 0.5659], n=400, n_oracle=100, cluster_robust)
When partial oracle coverage requires calibration, result.calibrator predicts in the same public judge and oracle units supplied by the caller; complete oracle coverage returns the direct oracle mean with result.calibrator is None. Grade any fitted calibrator's reuse on an independent probe with transport_audit(..., delta_max=<practical margin>); result.diagnostics["boundary_card"] carries the separate scalar score-support badge when calibration is fitted.
Documentation
| Resource | Description |
|---|---|
| Interactive Tutorial | Walk through a complete example in Colab; no setup required |
| Agent Skill | Teach any coding agent to run CJE correctly |
| CJE in 3 Minutes | Video: why raw judge scores mislead and how CJE fixes it |
| Technical Walkthrough | Video: calibration, evaluation, and transport auditing pipeline |
| Operational Playbook | End-to-end runbook: audits, drift correction, label budgeting |
| Migration Guide | Upgrading from 0.5.x or earlier: what changed and how to adapt |
| Planning Notebook | Optimize your evaluation budget with pilot data |
| Full Docs | Installation, assumptions, API reference, research notes |
Bridges: Use the Langfuse experiment bridge to preserve response identity and label provenance before analysis. Already running evals in Promptfoo, TruLens, LangSmith, or OpenCompass? Convert those outputs into CJE format with one command.
Module deep dives: Calibration · Diagnostics · Estimators · Interface/API · Data formats
Why Direct mode only (no IPS/DR)?
CJE is Direct-mode only: fresh draws, calibrated judge, audits. There is no off-policy machinery: no importance-sampling or doubly-robust estimators (calibrated-ips, dr-cpo, mrdr, tmle, stacked-dr), teacher forcing, SIMCal weight stabilization, or overlap diagnostics. Our own paper's results drove that design: for realistic LLM policy pairs, importance weighting failed even when ESS looked healthy (target-typicality coverage 0.19–0.49, far below the 0.70 gate), and the best DR stack merely matched Direct mode's accuracy at ~12× the compute. Direct mode is what the evidence supports, so it is the whole product.
- Need IPS/DR from logged propensities? Pin the frozen OPE line:
pip install "cje-eval==0.3.*"(maintained on the0.3.xbranch; docs at thev0.3.0tag; requires Python <=3.12; on 3.13 use a 3.12 env for OPE). - Have old logged data with
judge_score+oracle_label? It works as the calibration source:analyze_dataset(fresh_draws_dir=..., calibration_data_path="logged.jsonl"). - OPE entry points raise migration errors that say exactly this.
Full version history in the CHANGELOG.
Development
git clone https://github.com/cimo-labs/cje.git
cd cje && poetry install && make test
Citation
If you use CJE in your research, please cite:
@misc{landesberg2025causaljudgeevaluationcalibrated,
  title={Causal Judge Evaluation: Calibrated Surrogate Metrics for LLM Systems},
  author={Eddie Landesberg and Manjari Narayan},
  year={2025},
  eprint={2512.11150},
  archivePrefix={arXiv},
  primaryClass={stat.ME},
  url={https://arxiv.org/abs/2512.11150},
}
License
MIT. See LICENSE for details.
1 maintainer

Metadata
1 maintainer
Release files for cje-eval 0.9.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| cje_eval-0.9.0.tar.gz | 223.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cje_eval-0.9.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 463.9 kB
Release files / cje_eval-0.9.0.tar.gz
| Download URL | cje_eval-0.9.0.tar.gz |
|---|---|
| Size | 223.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5fa7682355f49a1e6effbf0f585063a0ec3ae3d913163f7e495442213c002fb2
|
|
BLAKE2b-256 checksum How to use checksums |
c2d0e6a9d4048b72cc59008827145e4e41865dbbd04e090285968d6616e72340
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency logRelease files / cje_eval-0.9.0-py3-none-any.whl
| Download URL | cje_eval-0.9.0-py3-none-any.whl |
|---|---|
| Size | 240.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
345f4c29fedf2f8acbcec9ab59edba8eecd166ca7b77b0003a80d48327e999eb
|
|
BLAKE2b-256 checksum How to use checksums |
1287d26fa62a90c658d2d770a5ef2392835f71ce87f0297d267f5ba3d49d4450
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 4, 2026.
Transparency log













