
clocwork
Run clocwork inside any git repository and get a dashboard of its whole
history: lines per language and type (code, comment, blank) at every commit,
which commits an AI agent co-authored and when each model first appeared, and,
when the repository was worked on with Claude Code, Codex CLI, Copilot CLI,
Gemini CLI, Kilo Code, OpenCode, Qwen Code or Antigravity, what that work cost in tokens,
dollars and electricity. Every commit is measured with cloc --git --diff, cached per
file, and reconciled against a cloc snapshot of HEAD so drift is visible
rather than silent.
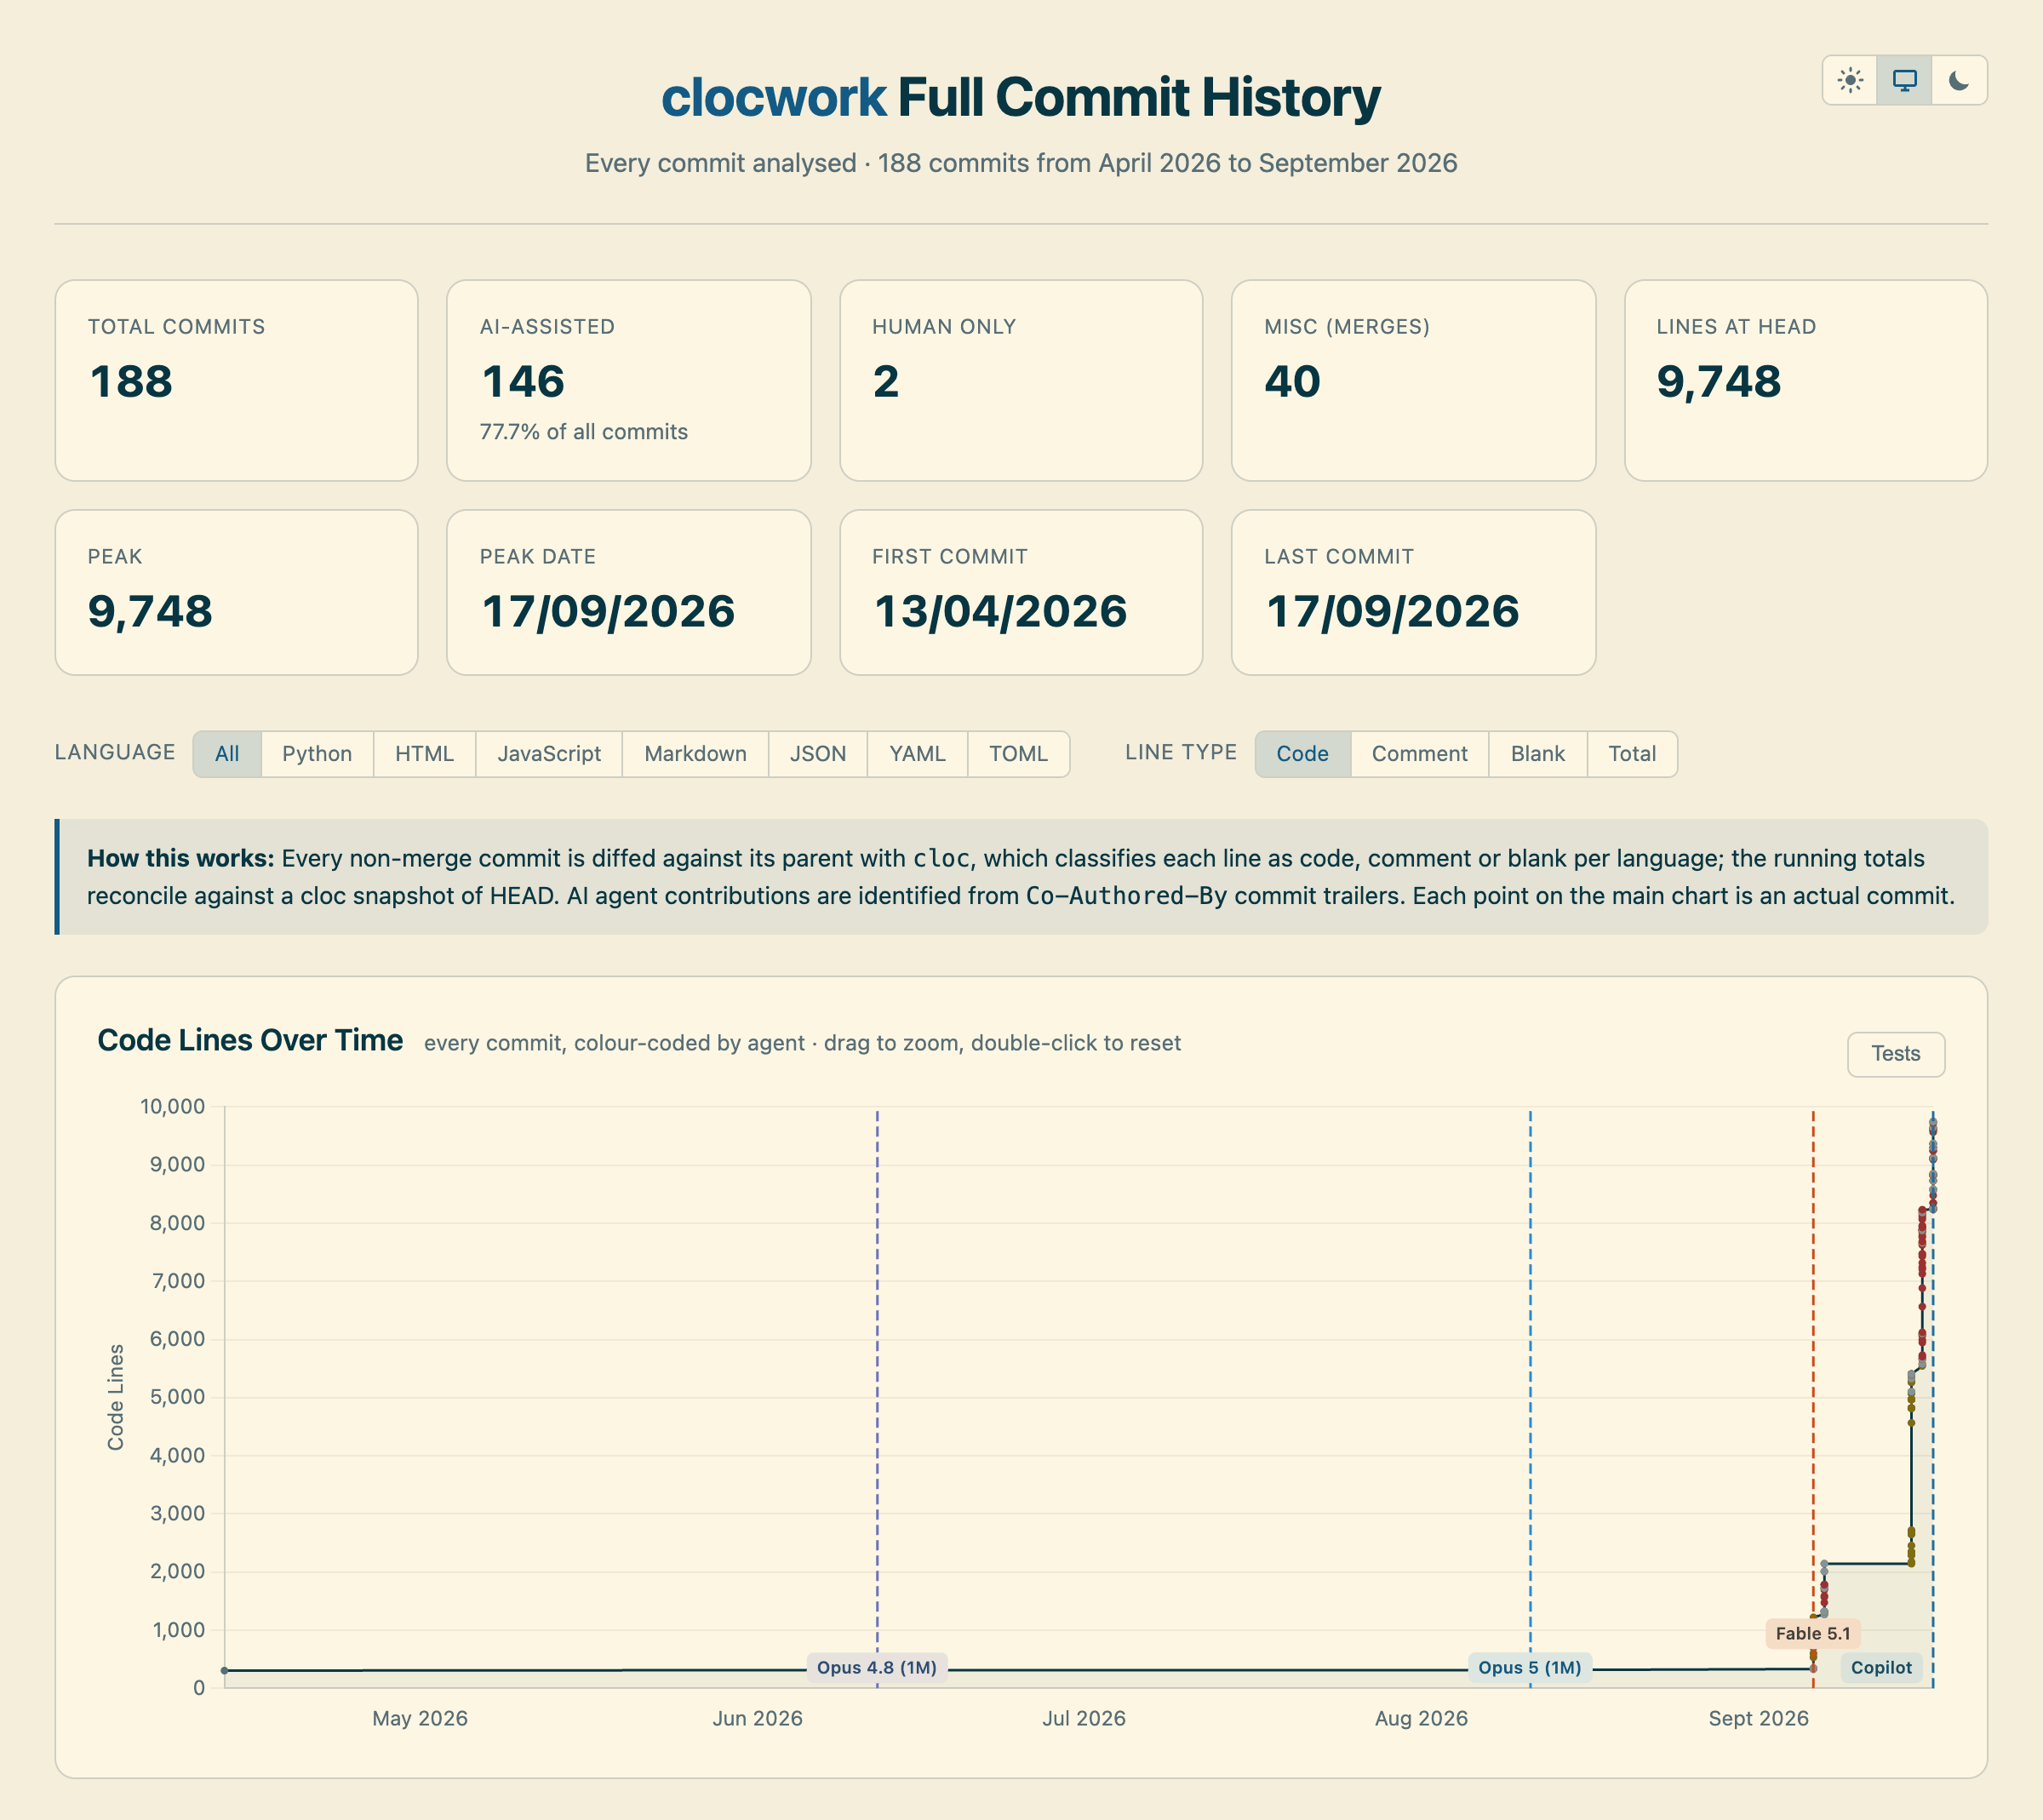
The top of the page clocwork writes for its own history. Each point on the chart is a commit, coloured by the agent that co-authored it (grey when none did), and each dashed line marks the first commit of a new model. The page comes in Solarized Light and Solarized Dark: the switch at its top right picks one, or follows the system, and the browser remembers the choice.
The output is one index.html (its charts load Chart.js and its plugins from
a CDN) plus a commit_bodies.js sidecar for the full commit messages, written
to a workspace next to the repository, never inside it.
Requirements
The Homebrew formula below brings its own Python and cloc, so with Homebrew
only git is needed.
- Python 3.11 or later (standard library only)
cloc2.06 or later onPATH. On macOS,brew install clocgives a current release. Linux distributions often package an older one (Ubuntu 24.04 has 1.98). clocwork refuses an older cloc, because earlier releases list file extensions in a form it misreads. If yours is older, savecloc-<version>.plfrom the cloc releases as an executable namedcloconPATH.git
Installing
With Homebrew, which also installs cloc and the manual page:
brew install nicktoumpelis/tap/clocwork
Installing by the full name, as above, trusts the formula. The
tap's README
covers a bare brew install clocwork, which needs brew trust first, and a
Brewfile entry, which trusts it with trusted: true.
From PyPI:
pipx install clocwork # or: pip install clocwork
pip does not install the manual page; man/clocwork.1 is in the repository
and in the source distribution.
Each release also carries clocwork.pyz, the whole command in one file, which
runs with no install step:
curl -LO https://github.com/nicktoumpelis/clocwork/releases/latest/download/clocwork.pyz
chmod +x clocwork.pyz
./clocwork.pyz ~/code/foo
Or run it from a clone:
git clone https://github.com/nicktoumpelis/clocwork.git ~/code/clocwork
cd ~/code/foo && ~/code/clocwork/clocwork
Both run under the first python3 on PATH, which must be 3.11 or later;
an older one is refused with a message naming it. On macOS,
/usr/bin/python3 comes from Apple's developer tools and can be older
(Xcode's is 3.9); name a newer interpreter instead, as in
python3.13 clocwork.pyz.
For development, pip install -e ~/code/clocwork installs the clocwork
command from the clone.
Running
Run clocwork inside the repository to analyse, or pass its path. The first
run over a long history measures every commit with cloc, running one
cloc process per CPU core (--jobs N chooses the number). On a 10-core
machine the 289 commits of spf13/cast take
14 seconds (113 seconds with --jobs 1), and a repository of 3,800 commits,
2,700 of them non-merge, takes about four minutes. Results are cached, so
later runs take seconds. --max-commits N caps one run and a later run
continues from where it stopped.
Commands
clocwork [REPO]          analyse, archive tokens, render, open the dashboard
clocwork tokens [REPO]   archive agent token logs only
clocwork render -o DIR   re-render the dashboard from existing workspace data
REPO is the repository or any directory inside it; the default is the
current directory. A first argument that is not a subcommand is taken as
REPO, so clocwork ~/code/foo works.
tokens is a separate command because the two halves of the pipeline have
opposite economics. The cloc pass is slow and fully regenerable. The token
archive is cheap and irreplaceable: coding agents delete their logs (Claude
Code after roughly 30 days), and a day that is not archived while its logs
exist is gone for good. clocwork tokens is what to run from cron.
render needs no repository, only a workspace; it exists so the page can be
iterated on without re-analysing.
Options (clocwork run --help):
  -q, --quiet       print nothing but errors
  -v, --verbose     also print each phase's details and the per-language table
  --config PATH     explicit clocwork.toml
  --locale TAG      region locale for the page (default: $CLOCWORK_LOCALE,
                    else the machine's region)
  --no-open         do not open the dashboard in a browser
  -o, --output DIR  workspace directory (default: <repo-parent>/<repo-
                    name>-stats)
  --branch REF      ref to analyse (default: the checked-out branch)
  --max-commits N   measure at most N uncached commits this run
  -j, --jobs N      cloc processes to run at once (default: one per CPU core)
  --no-tokens       skip the agent log scan
  --cache-dir DIR   cache location (default: $XDG_CACHE_HOME/clocwork, else
                    ~/.cache/clocwork; wins over both)
tokens takes only -o, -q and -v: it writes no page. render takes
the page options, -q and -v, and its -o is required. --version
prints the version.
The same reference is a manual page: man clocwork after a Homebrew install,
man ./man/clocwork.1 from a clone.
On a terminal, a run prints one line per phase (tokens, history,
dashboard), with a live progress bar while cloc measures (only the counts
on a terminal narrower than 60 columns), then a short summary and the page's
path. -v adds each phase's details and the per-language table; -q prints
only errors. Anything else (a pipe, a log file, cron) gets plain lines
without colour or redraws, one fact per line and a progress line every 50
commits, and so does a terminal when NO_COLOR is set to anything but the
empty string, or TERM is dumb.
The page formats every number, date and unit for a region locale. The
generator records it, because browsers expose only the language list: the
CLOCWORK_LOCALE environment variable wins (a BCP 47 tag such as en-SE),
then the macOS Language & Region setting, then LC_ALL, LC_NUMERIC and
LANG; --locale overrides all of them for one run.
The workspace
Output goes to a sibling of the repository: ~/code/foo produces
~/code/foo-stats. It is deliberately not inside the repository, because the
tool would then be measuring its own output and dirtying the working tree of
the repository it reports on. Pass -o DIR to put it elsewhere.
foo-stats/
  clocwork.json           which repository this workspace belongs to
  clocwork.toml           optional configuration (see below)
  token_usage.json        the per-day, per-agent token archive; cannot be regenerated
  full_commit_data.json   the analysis, with the clocwork build that made it
  index.html              the dashboard
  commit_bodies.js        full commit messages, loaded when a row is expanded
The workspace is meant to be committed to its own repository: that is the
backup for token_usage.json. clocwork.json is an identity guard. On every
run the target repository is compared against it, by remote URL first and
absolute path second, and a mismatch is refused with an error naming both
repositories, so no ordinary mistake can overwrite one repository's token
archive with another's.
The cloc cache lives outside the workspace, in
$XDG_CACHE_HOME/clocwork/<name>-<hash>/ or ~/.cache/clocwork/, keyed by
the repository's absolute path. It holds per-file rows rather than
per-language totals, so changing the language table or the test-path rules
below re-reads the cache instead of re-running cloc.
Configuration
Optional. Searched in this order, first hit wins: --config PATH, then
<workspace>/clocwork.toml, then <repo>/.clocwork.toml. The last is read and
never written, so a repository can commit its own settings while someone
analysing it can still override them from their workspace.
title = "MyApp"                         # page heading; default is the repository's directory name

[tests]
include = ["integration/**", "e2e/**"]  # added to the built-in test-path rules
exclude = ["tests/fixtures/**"]         # applied last, wins over everything
replace = false                         # true drops the built-ins entirely

[agents]
extra = [{ match = "Jules", name = "Jules" }]   # a name in a Co-Authored-By trailer, and what to report it as
Globs match the whole path from the repository root: ** matches across
directories, * within one, ? one character. *.py therefore matches only
top-level files; **/*.py matches at any depth.
What counts as test code
Built in, by directory: test, tests, __tests__, testdata (any
case); spec and specs for Ruby, JavaScript, TypeScript and CoffeeScript
files only, so a specs/ directory of design documents is not counted; a directory named *Test or
*Tests (Xcode, JVM); the src/test/, src/androidTest/ and
src/integrationTest/ layouts. By filename: *_test.go; test_*.py, *_test.py, conftest.py; *.test.*
and *.spec.* for JavaScript and TypeScript; *Test.* and *Tests.* for
Java, Kotlin, C# and Swift; *_spec.rb, *_test.rb, *_test.dart,
*_test.exs. Inline test code (Rust's #[cfg(test)], Go examples in a
non-test file) is not detectable from paths.
The run summary prints the test share of HEAD. A share that is obviously wrong is the signal to add a rule; the fix costs a config line and a re-read, not a re-measure.
Which commits are AI-assisted
Attribution comes from Co-Authored-By: trailers only, so a commit that
merely mentions an agent is not counted. Any Claude model is recognised and
normalised (Claude Opus 4.6, Claude Opus 5 (1M)), and Copilot, Cursor,
Codex, Devin, aider, Antigravity, OpenCode, Qwen Code, Gemini and Gemini
Code Assist are recognised by name. Anything else stays unmatched rather than guessed
at; [agents].extra names the rest.
An agent's name has to be a whole word in the trailer's display name or
in the address's local part, or a whole label of its domain. So
Antigravity AI, AGY <noreply@antigravity.dev> and opencode-go/mimo-v2.5
are all recognised, while Jane Doe <jane@antigravity-drones.example> is a
person at a company whose name happens to start the same way, and stays
unattributed — the domain is the strict one because that is where the name of
whoever owns the address sits, and a domain written in a note beside the
address is judged the same way. Only the trailer's own address counts: in
Jane <jane@example.com> (was jane@opencode.ai) the second address is
someone else's, and says nothing about who wrote the commit. A note naming
an agent in words still counts, as in Someone <s@example.com> (via Codex).
A dotted version such as gemini-2.5-pro is a word, not a domain, because a
domain ends in a label of letters. An extra is matched by the same whole-word
rule, which is also what bounds a short match: code reaches no OpenCode
trailer, because it is no whole word of opencode. The built-in names are
tried before a workspace's own, so [agents].extra names agents the table
does not know rather than renaming the ones it does. Neither match nor
name may be blank, and whitespace around a match is ignored; a match
with a dot in it (jules.google) matches a domain only as whole labels, so
x@jules.google-mirror.example is not it.
Antigravity writes no trailer of its own (agy 1.2.8 commits with the message
it was asked for and nothing after it), and the ones people add agree on
nothing but the word itself, so a trailer naming "Antigravity" — in its
display name or its address, by the rules above — counts as Antigravity. It
is matched before Gemini,
because such a trailer often names the Gemini model that ran
(Antigravity CLI (Gemini 3.8 Flash)) or uses a gemini@google.com
address.
A Claude model named anywhere in a trailer wins over every vendor, so
Antigravity (Claude Sonnet 4.5) and Cursor (Claude Sonnet 4.5) are both
read as Claude Sonnet 4.5: the page charts the model rather than the tool
that ran it, and such a commit can carry Claude Code's tokens for the day.
A commit crediting several agents in separate trailers goes to the first one
recognised, whichever agents those are.
Token usage
The token section appears when the workspace's token archive holds at least
one day. Each run reads the logs coding agents keep on the machine and
archives per-day totals, per agent and model, into token_usage.json.
| Agent | Logs read | Override |
|---|---|---|
| Claude Code | ~/.claude/projects/, the directory named after the repository's path |
none |
| Codex CLI | ~/.codex/sessions/ and ~/.codex/archived_sessions/ |
CODEX_HOME replaces ~/.codex |
| Copilot CLI | ~/.copilot/session-state/, one events.jsonl per session, and ~/.copilot/session-store.db beside it |
COPILOT_HOME replaces ~/.copilot |
| Gemini CLI | ~/.gemini/tmp/ and ~/.cache/.gemini/tmp/, sessions started in the repository or a directory it tracks |
GEMINI_CLI_HOME replaces ~ |
| Qwen Code | ~/.qwen/projects/*/chats/, one JSONL file per session from 0.4.0 (an archived one moves to chats/archive/), and the Gemini-format sessions under ~/.qwen/tmp/ that earlier releases wrote |
QWEN_HOME replaces ~/.qwen; QWEN_RUNTIME_DIR, and the advanced.runtimeOutputDir setting in any of Qwen Code's settings files, add the directory they name |
| OpenCode | ~/.local/share/opencode, on macOS and Windows as well: its opencode*.db databases and the file stores older releases wrote |
XDG_DATA_HOME replaces ~/.local/share; OPENCODE_DB adds the database it names |
| Kilo Code | ~/.local/share/kilo, on macOS and Windows as well: its kilo*.db databases, an opencode-*.db left there by the fork's rename, and the file stores its 1.0.x releases wrote |
XDG_DATA_HOME replaces ~/.local/share; KILO_DB adds the database it names |
| Antigravity | ~/.gemini/antigravity-cli/conversations/, one SQLite database per conversation, placed by the CLI logs beside it, then history.jsonl, then conversation_summaries.db, then the conversation's own record of its workspace; the IDE's ~/.gemini/antigravity-ide, and ~/.gemini/antigravity and ~/.gemini/antigravity-backup, are read the same way |
none |
For any repository not worked on with these agents on this machine, the section and the commit table's Tokens column are simply absent. That is the normal case, not an error.
What is kept, and how it reaches commits
Only dates, model names, and token and turn counts reach the archive; prompts and replies are never kept. The archive keeps the larger record for each day and agent, because agents delete their logs and a day not archived in time is gone.
Tokens land only on the commits of the agent whose logs measured them, split across that agent's commits of the day by lines changed. A commit carries no token figure when:
- its agent's logs are not read (Cursor, Devin, aider, Gemini Code Assist or any other), or
- they cover no day on which that agent's commits changed lines.
Such a commit is never priced at another agent's rate. When the repository
has token data, the run summary counts the AI-credited commits that carry no
figure and names their agents. Gemini Code Assist is the name for gemini-code-assist[bot],
which GitHub credits when one of its review suggestions is accepted.
A day the archive does not cover for an agent, but on which that agent's commits changed lines, is estimated from the agent's own tokens-per-line ratio; a record that holds no tokens covers nothing. The result is priced at API list prices: each measured day at the prices in force on it, and the estimated days at the measured mix. Its electricity is estimated too.
An archive written by an earlier version is read as Claude Code's and rewritten in the per-agent shape the next time a scan finds logs. An archive of a version this clocwork does not know is refused with an error rather than read or overwritten.
The sections below say, for each agent, which sessions count, how their tokens are read, and which commits they land on.
Claude Code
Sessions. Claude Code keeps a directory of transcripts per working directory, named after its absolute path with every character other than an ASCII letter or digit replaced by a hyphen. clocwork reads the one named after the repository, so a session started in a subdirectory, which Claude Code files under that subdirectory's name, is not read.
Tokens. A resumed or forked session replays its earlier turns into the new transcript, so each assistant turn is counted once, by its message id, or its request id or record id where it has none.
Commits. Claude Code's tokens land on the commits whose trailers credit
Claude. Any Claude model is recognised, and a trailer naming none reads as
Claude (unknown version) (see
Which commits are AI-assisted).
Codex CLI
Sessions. A Codex session belongs to the repository when it records the
same remote as the repository's origin, so sessions from any clone or
worktree count.
A session that recorded another remote still belongs when it ran in the repository, or a directory inside it, from one of the repository's commits. A renamed or transferred repository keeps its sessions that way, and a different repository later cloned to the same path gets them only if it holds the commit they started from.
When the session records no remote, or origin is missing or not a URL
clocwork recognises, the session belongs when it ran in the repository or a
directory inside it.
Tokens. Codex rollouts that Codex has compressed are read on Python 3.14 and later; earlier versions count them as unreadable and say so in the log.
Commits. Codex asks its model to end commit messages with
Co-authored-by: Codex <noreply@openai.com> unless attribution is turned
off.
Copilot CLI
Sessions. A Copilot CLI session records its repository as owner/name
beside its host, which is the identity clocwork builds from origin. So it
belongs by the same rule as a Codex session: the same remote from any clone,
otherwise the repository's directory plus one of its commits, otherwise the
directory alone.
Tokens. Copilot keeps usage in two places:
- The session's log records tokens only at shutdown, as a running total per model rather than per response. A session resumed and shut down again writes a further total, and clocwork archives the increase, so a session recorded twice is counted once.
session-store.db, from release 1.0.69 on, keeps a row per model call, each with its own time.
A session whose log names 1.0.69 or later at its start is read from its rows alone, so each call lands on its own day rather than on the day of the shutdown that reported it.
Where the store is there but such a session's rows are not — pruned, or the store unreadable for that run — the session is held back and the run says so, rather than read from its snapshots. The archive keeps the larger record for each day, so a session that moved to its shutdown days would be counted on both. What earlier runs archived for a held session stays unless that day's record from a later run outgrows it, and a session whose rows were gone before any run saw it is not counted at all. With no store at all, the snapshots are read.
A session from an earlier release, or whose log names none at its start, is read from whichever of the two holds more tokens: the snapshots for one begun before the table existed, the rows for one that never shut down. A session whose log is gone is placed by the working directory the store records for it.
Both report their uncached input directly, and clocwork checks every row and snapshot that reports it against the figure it derives. One that disagrees is counted in the log as unparseable rather than archived, because a format that has changed should be visible instead of quietly halving a total.
Commits. Copilot CLI asks its model to end commit messages with
Co-authored-by: Copilot <223556219+Copilot@users.noreply.github.com> unless
includeCoAuthoredBy is turned off. Its tokens land on the commits whose
trailers credit Copilot, whether the agent wrote the trailer or its author
added it.
A trailer naming GitHub's cloud Copilot agent (copilot-swe-agent[bot])
resolves to the same name, so a commit carrying one is counted as Copilot's:
it takes a share of the CLI's measured tokens on the days they cover, and an
estimate at the CLI's rate on the days they do not.
Gemini CLI
Sessions. Gemini CLI identifies a session's project only by a hash of the
directory it started in, so its sessions count when that is the repository's
current path or a directory tracked at HEAD below it.
Commits. Gemini CLI adds no trailer, so its tokens reach a commit only
when the commit credits Gemini by hand, in a trailer such as
Co-Authored-By: Gemini CLI <address>. Otherwise the page says its tokens
land on no commit.
Qwen Code
Sessions. From 0.4.0 a Qwen Code session belongs to the repository when the working directory each of its records carries is the repository or a directory in it. The earlier releases' sessions belong as Gemini CLI's do, by the hash of the root or of a tracked directory.
Beside ~/.qwen, the sessions are looked for wherever QWEN_RUNTIME_DIR or
the advanced.runtimeOutputDir setting moved them. That setting is read from
each file Qwen Code merges:
- the system defaults and system settings:
/Library/Application Support/QwenCode/on macOS,/etc/qwen-code/on Linux,C:\ProgramData\qwen-code\on Windows, orQWEN_CODE_SYSTEM_DEFAULTS_PATHandQWEN_CODE_SYSTEM_SETTINGS_PATH; - the user's
settings.jsonin~/.qwen(orQWEN_HOME); - the repository's own
.qwen/settings.json.
Every file's directory is read, not only the one that wins, because sessions
stay where they were written when the setting changes. A relative directory
is taken from the repository's root, so a session started in a subdirectory
with a relative setting is not found, and neither is a variable that only
Qwen Code's .env files define.
Tokens. Usage is read from the telemetry record every API call writes, so the side calls Qwen Code makes — the memory extractor's, say — are counted beside the main one, each on its own day.
Qwen Code normalises every provider's counts before it logs them: the input includes the cache read, and for Anthropic the cache write as well. It reports that write nowhere apart from the input, so it is counted, and priced, as input.
The record's own total says whether its reasoning is already inside its output, and where it has none the provider does. The OpenAI and Anthropic readings were checked against a mock of each API; Gemini's is Gemini CLI's convention, not yet checked for Qwen Code.
Commits. Qwen Code appends
Co-authored-by: Qwen-Coder <qwen-coder@alibabacloud.com> to the commits it
makes itself, unless general.gitCoAuthor.commit is turned off, so its
tokens land on those commits.
It does so by rewriting the quoted message of a git commit -m (or -am,
--message) it runs through bash, which is every shell it uses on macOS and
Linux and only Git Bash on Windows. A commit made in an editor, from a
message built with $(…), after a cd or with a git -C that may leave the
repository, or through another shell carries no trailer, and is not
credited.
Qwen alone is not enough, since it names the model too, and Qwen-Coder
has to stand whole, with no hyphen joining it to another word:
Cline (qwen-coder-plus) names a model Alibaba serves, not Qwen Code.
OpenCode
Sessions. An OpenCode session names its project by the SHA-1 of
origin's host and path, so every clone and worktree counts, as do the
sub-agent sessions that share the project. Releases before v1.15.11 named it
by the repository's first commit instead; such a session counts when it also
ran in the repository, which is what keeps another history cloned to the
same path out.
Tokens. Each model call writes a step-finish part carrying its own tokens, and those parts are what is counted. A message's own tokens are overwritten by each step, so they count only where a message has no step-finish part.
OpenCode has moved its storage four times, and each move copied rather than replaced, so a store can hold the same session two or three times over. Records are counted once, by the ids the moves preserved. A forked session copies its messages under new ids, and those copies are not counted again.
OpenCode has not always stored its counts the same way, so each record is read by the rules of the release its session names. clocwork names five counter eras:
| Era | Releases | What the prompt count holds | How clocwork reads reasoning, when total cannot say |
|---|---|---|---|
| A | before v1.0.62 | the cache reads too, for every provider but Anthropic's | inside the output, or beside it for Google's |
| B | v1.0.62 to v1.3.3 | uncached input only | inside the output, or beside it for Google's |
| C | v1.3.4 and v1.3.5 | the cache reads and writes too, for Anthropic's only | inside the output, or beside it for Google's |
| D | v1.3.6 to v1.3.15 | uncached input only | inside the output, or beside it for Google's |
| E | v1.3.16 on | uncached input only | beside the output |
Where the prompt count holds the cache, clocwork takes it back out, except
from an input smaller than the cache, which cannot have held it. Anthropic's
means the anthropic, amazon-bedrock and google-vertex-anthropic
providers or any claude- model; Google's means the google and
google-vertex providers or any gemini model. Eras A and C appear in no
public recording, so their test fixtures are hand-written.
The reasoning column is a default, not a rule every release kept. Where
reasoning sat was the provider's choice rather than the release's, and a
v1.3.13 recording, in era D, has a Google model's reasoning inside the
output; that record carries a total, which settles it.
A record's own total is the first evidence of where reasoning sits,
because it does not depend on knowing the release. When total equals
input, output and cache together, the reasoning is already inside the
output; when it equals that plus the reasoning, the reasoning is beside it,
and clocwork adds it to the output. Records carry total from v1.1.57, though
not every later one does. A record without it, or one whose input still
holds the cache so that neither sum matches, falls back to the table.
A record whose session names no version is read as era A only when it also
has no total, since only such a record can predate v1.1.57; one with a
total is read as era B. A record from the
session_message table is read as v1.14.34 at the earliest, the release that
added the table.
OpenCode calls are priced at the model vendor's list price, like every other source. That is an estimate when the call was billed by a reseller, a subscription or a regional endpoint — through OpenCode's own Zen, GitHub Copilot or Bedrock, say — and models the price table does not know are reported as unpriced.
Commits. OpenCode adds no trailer (it did until v0.4.19), so its
measured tokens land on no commit unless the author credits it, in a trailer
such as Co-Authored-By: opencode <noreply@opencode.ai>. A trailer naming a
model and OpenCode both (GLM-5.3 via OpenCode) is OpenCode's.
One from opencode-agent[bot] is the GitHub Actions agent, whose logs stay
on the runner, so it is named separately and carries no tokens.
Kilo Code
Sessions. Kilo Code is a fork of OpenCode and keeps the same store, so it
belongs by the same rule and is read by the same code: the SHA-1 of
origin's host and path, the id cached in the repository's git directory —
under kilo, where OpenCode writes opencode, so the two never claim each
other's projects — or the repository's first commit.
Tokens. Kilo's releases are numbered 1.0.x and then 7.x, which OpenCode's
counter eras cannot read as they stand. So each Kilo release is mapped to the
OpenCode release it carried — from v1.1.36 at Kilo 1.0.0 onwards, found by
which OpenCode tags each Kilo tag descends from — and read at that release's
era. A record's own total still decides where reasoning sits first, as it
does for OpenCode.
A version the mapping cannot place, such as the local a build from source
records, is read as era B rather than era A. Era A is the only rule a record
naming no version could reach that takes a cache read back out of the
prompt, and no Kilo release carried it.
That choice has a cost if such a record was in fact written under era A, for every provider but Anthropic's: it keeps its cache read in the input count while the cache-read count reports it too, so the two together count it twice. Erring that way keeps the tokens visible in a labelled count rather than dropping prompt tokens silently.
Kilo also stores a per-session roll-up of its own messages' tokens, which clocwork does not count: the per-message rows are the ones that carry a day and a model.
Commits. Kilo Code adds no trailer of its own. The one its GitHub agent
writes credits the person who dispatched the workflow, and the agent itself
commits as an author rather than a co-author. So its tokens reach a commit
only through a trailer someone wrote by hand, naming it as Kilo Code,
Kilo or kilocode.
Antigravity
Sessions. Antigravity's CLI, agy, keeps each conversation in a SQLite
database of protobuf records, and the Antigravity IDE keeps its own the
same way under ~/.gemini/antigravity-ide. A print-mode conversation's
database (agy -p) names no directory at all, so a conversation is placed
by the first of these that names one (except that one a CLI log records goes
no further than history.jsonl, as below):
- The CLI log of the run that created it, under
log/, names the working directory first and any--add-dirdirectories after it. agy kept every log in the runs checked, a year-old one included. history.jsonlnames an interactive conversation's working directory when it is ended with/exit.conversation_summaries.dblists the--add-dirdirectories given as absolute paths and then, for an interactive conversation only, the working directory, so its last entry is taken. A print-mode run with--add-dirwhose log is gone is therefore read as its added directory's, which is why this file comes after the other two.- The conversation itself. The IDE writes none of the three files, but each of its conversations records the folders of the IDE's workspace. The first is taken: the folder that was opened, or the first folder listed in a workspace of several. Checked with Antigravity IDE 2.5.5; an agy conversation that none of the three files places is read the same way, although whether agy records its folders there was not checked.
A conversation belongs when its working directory is the repository or a directory in it.
A log lists a run's directories separated by spaces, so where one of them has
a space in its name, the longest part of the text that is a directory on disk
is taken. The text is split only before a path (/…, ./…, ../… or
~/…, with the system's own separator; a Windows drive-letter path, C:\…,
never starts one). Text that no split makes a directory of, as a bare
relative --add-dir docs leaves it, falls through to history.jsonl alone,
since that run's summary names only its added directories; without an
/exit record it is held back.
A conversation that none of these places is not guessed at. When the repository has Antigravity usage, the run's summary says how many such conversations the machine holds, since none of them can be tied to any one repository.
Tokens. Each database holds one row per model call in two tables, which are read once per call by its response id.
The input, the output (with the thinking already in it), the cache read and
the model are as agy stores them, and they match what agy reports itself
(--output-format json). The cache read sits beside the input, not inside
it. A Claude model's calls through agy show it, and so do a Gemini model's
through the IDE, whose prompt (input plus cache read) grows from one call to
the next rather than falling to the uncached part.
Each IDE conversation also makes one small call, of 100 or so input tokens, on a
model it does not name, and that call is counted under unknown.
No recorded call reports a cache write, not even the first Claude call, whose cache the next one read, so a write is presumably inside the input, where nothing separates it. The IDE's older conversations are encrypted, and are not read.
Commits. agy writes no trailer, so its tokens land only on commits a person credits to Antigravity.
Development
python3 -m unittest discover -s tests -t . -q     # the Python suite
node tests/dashboard/run_all.js                   # the page, in a fake DOM under node
The dashboard suite renders a synthetic workspace (tests/dashboard/fixture.py)
through ./clocwork render. Set CLOCWORK_DASH_WORKSPACE=<dir> to run the
checks over any rendered workspace, a real one included; the files that
exercise the token-less page and the page with several agents render their
own synthetic variants regardless. Checks that assume the fixture's size,
such as the 500-row cap, fail over a short history.
tests/fixtures/ holds real Codex CLI, Copilot CLI, Gemini CLI, Kilo Code
and OpenCode sessions from eight public repositories, five MIT-licensed and
three Apache-2.0, reduced to identity, model, usage and timestamps,
Qwen Code sessions recorded against a local mock of the OpenAI and Anthropic APIs,
and Antigravity conversations recorded with agy for this repository; its README
names each source with the commit it was taken at, carries their licence
notices, and says which rows are as recorded and which are hand-written.
man/clocwork.1 is generated from the argparse parsers, and a test checks the
committed page is current. After changing any help text or the version,
regenerate it:
PYTHONPATH=src python3 -m clocwork.manpage > man/clocwork.1
To exercise the command end to end against a throwaway repository with Go, Python, JavaScript and Java test conventions:
R=$(python3 -c 'import sys, tempfile, os; sys.path[:0] = ["src", "."]
from tests import repo_fixture as fx
d = tempfile.mkdtemp(); r = os.path.join(d, "poly"); os.makedirs(r); fx.make_polyglot_repo(r); print(r)')
./clocwork "$R" --no-open --cache-dir /tmp/clocwork-cache
Licence
MIT.
1 maintainer

Metadata
1 maintainer
Release files for clocwork 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| clocwork-0.2.0.tar.gz | 365.7 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| clocwork-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 511.7 kB
Release files / clocwork-0.2.0.tar.gz
| Download URL | clocwork-0.2.0.tar.gz |
|---|---|
| Size | 365.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
76fa8dfaab1d910ddde3dda188b44070e5511197128953370596d3f99e6c08c2
|
|
BLAKE2b-256 checksum How to use checksums |
6201c9eaab6ac3fb6c4986c2f5844054d07dcec7bebeb8df1ab49d1d91a57787
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 22, 2026.
Transparency logRelease files / clocwork-0.2.0-py3-none-any.whl
| Download URL | clocwork-0.2.0-py3-none-any.whl |
|---|---|
| Size | 146.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a6f1067f889b4182c315bbf04c86e6913ccd29e7a064b2e2e0d4f933253d1863
|
|
BLAKE2b-256 checksum How to use checksums |
ec9c0cb7ed8245170bcf86525d7b15efeac9d9a8053f881ff5223e0012530b72
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 22, 2026.
Transparency log













