
CoAna — which oligomers mattered, and why
Find the oligomers that build the aggregate, not just count them.



An MD aggregation run produces thousands of transient clusters. Most of them dissolve. CoAna follows every assembly through each split and merge, then tells you which lineages went on to build the final aggregate, which were dead ends, and what a second species (a guest peptide, a crowder partner) actually did while it was inside: incorporated, catalytic, passenger, promoting, or bystander.
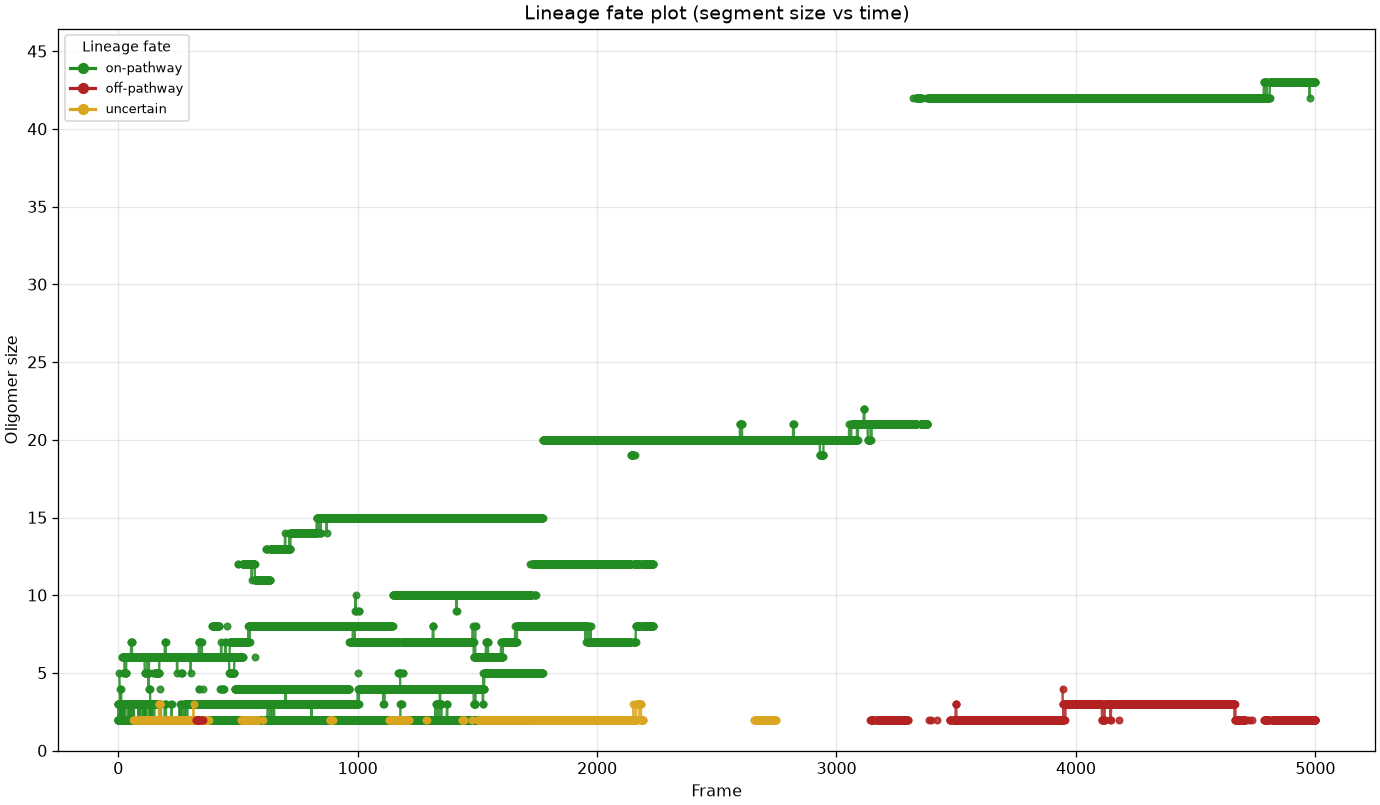
Every lineage in one run, coloured by fate: green lineages build the final 43-chain assembly, red ones are dead ends. 50 α-synuclein chains, Martini 3 with protein–water scaling λPW = 1.001, no crowder, ≈519 µM, 5 µs (5001 frames).
Cluster-counting tools tell you which clusters exist. CoAna tells you which ones mattered and what a guest did.
- Reads trajectories directly: XTC, TRR, GRO and PDB, with NumPy/SciPy only. MDAnalysis is optional.
- Exact periodic contacts: minimum-image contacts across every box face.
- Bit-for-bit reproducible: re-running Stage A reproduces a production contact cache exactly; 255 tests run on Linux and Windows.
pip install coana
coana precompute --traj prod.xtc --topology prod.gro --species aSyn:295x50 -o run.npz
coana lineage run.npz        # on-/off-pathway lineages and their fates
coana report  run.npz -o report.html
More of what CoAna shows
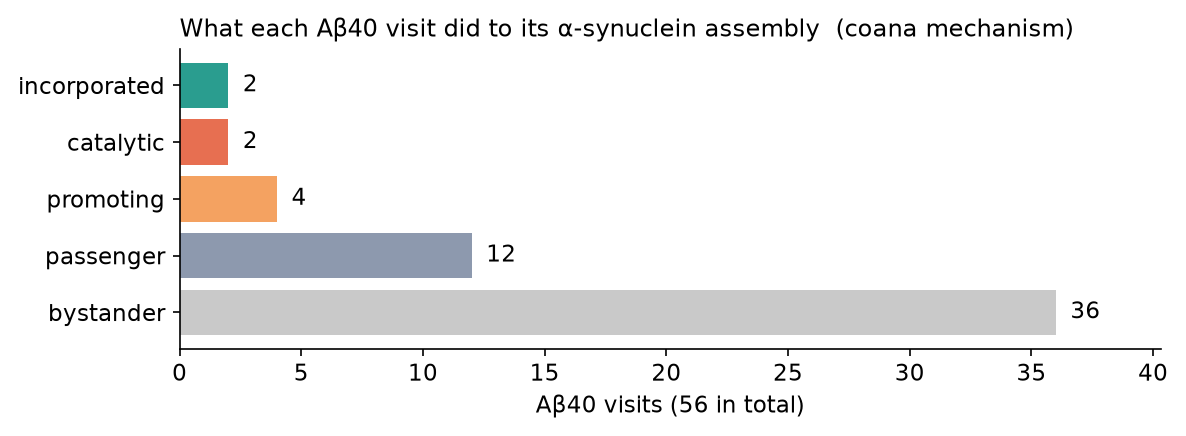
What did the guest do? In a run with 10 Aβ40 chains among the 50
α-synuclein chains, coana mechanism labels each of the 56 Aβ40 visits by what
happened to the assembly it visited. Most are brief encounters (bystander).
Some join an assembly that has already committed (passenger), are there while
it grows (promoting), are present when it commits and then leave (catalytic),
or stay in the product (incorporated).
How many clusters of each size, at every moment (same run):
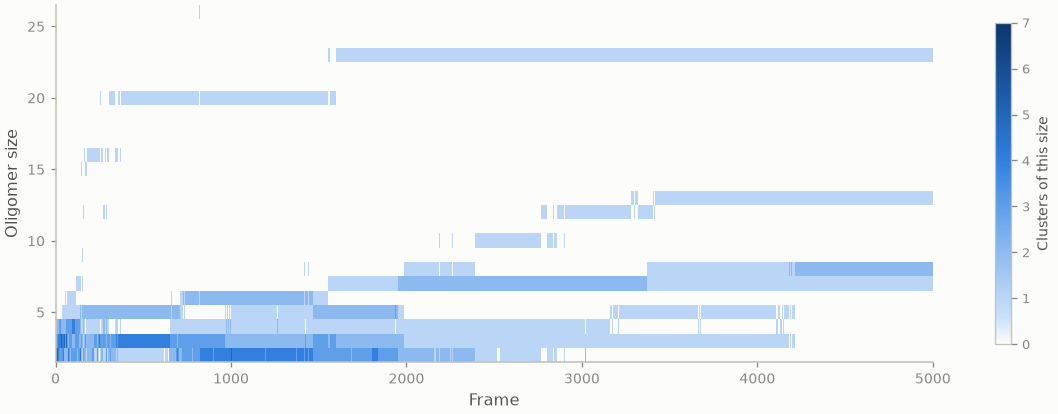
The Aβ40 run: λPW = 1.010 for α-synuclein–water, PEG-10000 crowder with PEG–PEG scaling λCC = 0.50, 5 µs. Its parameters differ from the run above, so the two runs are examples of CoAna's output, not a comparison between conditions.
Quick start (coana CLI + HTML report)
pip install coana                  # or, from a checkout: pip install .

# Stage A on all CPU cores, crash-safe for batch/walltime limits
coana precompute --traj md1.pdb --topology initial1.pdb --frames all \
    --cutoff 6.5 --intra-exclude 2 \
    --segment-mode atom_blocks --atoms-per-monomer 83 --n-monomers 128 \
    --n-jobs -1 --parallel process --checkpoint-every 200 --resume \
    -o cache_cut6.5.npz

coana info cache_cut6.5.npz        # inspect the cache

# one self-contained HTML report: figures embedded, prints to PDF
coana report cache_cut6.5.npz -o report.html --title "128-mer aggregation"

# the interactive split/merge timeline, laid out on a real frame axis
coana timeline cache_cut6.5.npz -o TIMELINE.html --frame-lo 640 --frame-hi 820
Running on a SLURM cluster? Section 14 of GUIDE.md has a batch
script; --checkpoint-every and --resume make Stage A safe under walltime
limits.
v3.4: mixed systems, chemistry, convergence, comparison, mechanism
Version 3.4 adds what a two-component (co-aggregation) study needs on top of the lineage tracker. Declare the composition once at Stage A and every later step knows which chain is which:
# Stage A for a 50 aSyn + 10 Ab40 Martini box (species in topology order)
coana precompute --traj prod.xtc --topology start.gro --frames all --cutoff 6.5 \
    --species "aSyn:295x50,Ab40:92x10" --contact-classes --hotspot-blocks 5 \
    --n-jobs -1 --parallel process --checkpoint-every 200 --resume -o cache.npz

coana partition cache.npz                 # partition coefficient K per species, c_free
coana chemistry cache.npz                 # salt bridge / hydrophobic / cation-pi budget
coana hotspots  cache.npz --species-a aSyn --species-b Ab40 \
                --regions "N-term:1-60,NAC:61-95,C-term:96-140"
coana converged cache.npz --all           # Geweke + drift; exit 1 if not converged
coana lineage   cache.npz --min-size 10 --lineage-min-duration 50 --sweep 6,8,10,12
coana mechanism cache.npz --guest Ab40    # incorporated / catalytic / passenger / ...
coana compare   runs/*/cache.npz --descriptor-regex "(?P<cond>[0-9.]+[a-z]+)_(?P<ff>[a-z]+)/" \
                --group-by cond            # warns when a group mixes force fields
coana export    cache.npz --what both --composition-states --out-dir gexf/
| Command | Question it answers |
|---|---|
partition |
Is the minority species enriched inside the assembly (K > 1)? Is c_sat even measurable in this box? |
chemistry |
Which interaction channel holds the assembly together — and which one salt removes? |
hotspots |
Which residues of A bind which residues of B, and is a region enriched beyond its length? |
converged |
Has this observable reached a steady state, with an error bar that respects autocorrelation? |
lineage |
Are the on-pathway lineages the mixed ones? (+ warnings, persistence floor, target-size sweep) |
mechanism |
Is the guest incorporated into the product, catalytic, a passenger, or a bystander? |
compare |
One row per run, grouped safely — flags descriptors that vary inside a group |
export |
Lineage graph and state-transition network as GEXF for Gephi |
--contact-classes and --hotspot-blocks must be requested at Stage A (residue
identity is gone once contacts are binned to chains); everything else works on
any existing cache. Section 17 of GUIDE.md walks through each command
with a worked synthetic example; tests/test_v34_features.py holds the
hand-derived expectations they are verified against.
Scientific principle
The central biological question is not only "which connected component exists at this frame?" but:
Which oligomeric lineages progress toward productive aggregation, and which are off-pathway traps, dead ends, or transient nonproductive species?
Therefore, on/off-pathway classification is fate-based, not size-based. A small oligomer can be on-pathway if it contributes to a later productive aggregate. A large oligomer can be off-pathway if it is a non-growing trap.
Preserved old workflow
Stage A: expensive preprocessing
Stage A computes PBC-safe residue/segment contact maps and saves a cache:
framescmapsnintra,ninter,ntotaln_free,n_boundseg_centersboxesmeta_json
Stage B: old linear pathway tracker
The original linear tracker is still available:
from oligomer_analysis import load_cache, analyze_from_cache

cache = load_cache("cache_cut6.5_compactness.npz")
res = analyze_from_cache(
    cache,
    inter_thresh=1,
    size_thresh=3,
    continue_min_size=1,
    overlap_min=1,
    shrink_tolerance=3,
    dur_store_min=5,
)
finished = res["finished"]
This is useful for backward compatibility and the mature 9-panel dashboard.
New lineage-aware workflow
The new layer tracks:
OligomerSegment: one continuous connected oligomer episodeLineageEvent: split, merge, birth, death, rearrangementLineage: the graph component connecting related segments
A temporary split such as:
10-mer -> 6-mer + 4-mer -> 10-mer
is represented as one lineage with explicit split and merge events. It is not automatically off-pathway.
from oligomer_analysis import (
    load_cache,
    TargetStateConfig,
    build_lineages_from_cache,
    lineage_summary_dataframe,
    plot_whole_system_background,
    plot_lineage_graph,
    plot_lineage_fate,
    plot_on_off_pathway_dashboards,
)

cache = load_cache("cache_cut6.5_compactness.npz")

lineage_result = build_lineages_from_cache(
    cache,
    inter_thresh=1,
    cluster_min_size=2,       # size 1 = monomer; size >= 2 = oligomer
    overlap_min=1,
    parent_frac_min=0.30,
    child_frac_min=0.30,
    union_cover_min=0.70,
    target_config=TargetStateConfig(
        min_size=10,
        min_duration=5,
        min_contribution=0.70,
    ),
)

summary = lineage_summary_dataframe(lineage_result)
print(summary.head())

plot_whole_system_background(cache, lineage_result)
plot_lineage_graph(lineage_result)
plot_lineage_fate(lineage_result)
plot_on_off_pathway_dashboards(cache, lineage_result, inter_thresh=1)
Figure strategy
The package supports the recommended aggregation figure hierarchy:
-
Whole-system background plots
- number of oligomers
- largest size
- mean size
- contacts
- free vs bound monomers
- bound fraction
-
Lineage graph
- nodes = continuous oligomer segments
- edges = split/merge/rearrangement events
- node color = on-pathway / off-pathway / uncertain
-
Fate plot
- x-axis = frame
- y-axis = oligomer size
- trace color = fate class
-
Deep-dive dashboards
- one strong on-pathway lineage
- one strong off-pathway lineage
- reuses the original 9-panel monitor
Validation
Synthetic tests are included under tests/. The canonical validation case is:
frame 0: {0,1,2,3,4,5,6,7,8,9}
frame 1: {0,1,2,3,4,5} and {6,7,8,9}
frame 2: {0,1,2,3,4,5} and {6,7,8,9}
frame 3: {0,1,2,3,4,5,6,7,8,9}
Expected behavior:
- one lineage
- split event
- merge event
- four continuous segments
- on-pathway when the target is size >= 10 and duration >= 1
Dependency policy
- Nothing in the package requires MDAnalysis. Stage A precomputation is done
by the built-in CoAnaPure engine (
precompute_cache_pure) using NumPy/SciPy only; it streams.pdb,.gro,.trr, and.xtctrajectories at constant memory and writes the identical.npzcache. It supports atom selections (selection="not resname W ION"), unequal monomer sizes (segment_mode="atom_counts"), process-parallel parsing (parallel="process"), progress/ETA reporting, and checkpoint/resume for batch jobs. - Cache loading, Stage B, lineage tracking, and plotting are cache-only as before.
- MDAnalysis is an optional extra (
pip install coana[mdanalysis]) used for: the originalprecompute_cacheengine, exotic trajectory formats, and the engine cross-validation benchmark (coana benchmark). - scipy is a required dependency: it powers the CoAnaPure neighbour search. The pure-NumPy cell-list fallbacks give identical results without it, but are several times slower.
from oligomer_analysis import PrecomputeConfig, precompute_cache_pure

precompute_cache_pure(cfg, out_npz="cache.npz")                      # default engine
precompute_cache_pure(cfg, out_npz="cache_pbc.npz", broadcast_box=True)  # correct PBC
Plot calibration for large oligomers
If oligomer sizes can reach 50--100 monomers, use a shared PlotCalibration
object to keep axes, matrix ticks, and network node sizes readable.
from oligomer_analysis import PlotCalibration

cal = PlotCalibration(
    max_oligomer_size=100,
    size_tick_step=10,
    matrix_max_size=100,
    node_size_min=250,
    node_size_max=1800,
    node_size_transform="sqrt",
    marker_size=3.5,
    line_width=1.4,
)

plot_whole_system_background(cache, lineage_result, calibration=cal)
plot_lineage_fate(lineage_result, calibration=cal)
plot_lineage_graph(lineage_result, calibration=cal, node_size_by="max_size")
plot_on_off_pathway_dashboards(cache, lineage_result, inter_thresh=1, calibration=cal)
Recommended settings for large aggregation simulations:
max_oligomer_size=100size_tick_step=10matrix_max_size=100node_size_transform="sqrt"node_size_maxbetween1200and2200
This avoids unreadable plots where 100-mer nodes or transition matrices dominate the figure.
V2 publication-discovery layer
Version 2 adds a set of modules designed to turn monitoring output into a hypothesis-testing framework for protein aggregation and LLPS.
New modules:
commitment.py— target aggregate discovery and future commitment scores.predictors.py— segment/lineage structural predictors such as compactness, weighted contacts, contact persistence, exchange fraction, and small-worldness.llps.py— coarse dense/dilute phase observables from cached segment centers.hotspots.py— on-pathway vs off-pathway segment-contact enrichment.publication_figures.py— manuscript-oriented figures for commitment predictors, LLPS coupling, and hotspot enrichment.
The central scientific idea is:
On/off-pathway should be assigned from future productive fate within a lineage, while structural descriptors should be tested as early predictors of that fate.
Example:
from oligomer_analysis import (
    load_cache, TargetStateConfig, build_lineages_from_cache,
    build_feature_table, figure_commitment_predictors,
    figure_llps_coupling, figure_contact_hotspots,
)

cache = load_cache("cache_cut6.5_compactness.npz")
lineage_result = build_lineages_from_cache(
    cache,
    inter_thresh=1,
    target_config=TargetStateConfig(min_size=10, min_duration=5, min_contribution=0.70),
)

features = build_feature_table(cache, lineage_result, inter_thresh=1)
figure_commitment_predictors(cache, lineage_result, inter_thresh=1)
figure_llps_coupling(cache, lineage_result)
figure_contact_hotspots(cache, lineage_result, inter_thresh=1)
Interpretation caution:
llps.pyuses cached protein/segment centers and gives operational dense-phase labels. Validate these against visualization and replicate simulations.hotspots.pyis segment-pair based because the default Stage A cache does not store residue-pair contact identities. Extend Stage A if residue-level hotspot maps are required.
Fix for large PDB systems with reused chain IDs
Standard PDB chain IDs are only one character, so large Martini systems can reuse chain IDs. If your physical system has 128 monomers but Stage A reports about 63 segments, define monomers by atom blocks:
cfg = PrecomputeConfig(
    topology_file="initial1.pdb",
    traj_file="md1_centered_filtered_1956frames.pdb",
    frames=list(range(1956)),
    cutoff_contact=6.5,
    intra_exclude=2,
    n_jobs=-1,
    chunk_size=50,
    segment_mode="atom_blocks",
    atoms_per_monomer=83,
    n_monomers=128,
)
precompute_cache(cfg, out_npz="cache_atomblocks.npz")
Use pdb_chain_id_summary("initial1.pdb", atoms_per_monomer=83) to diagnose chain-ID reuse.
V3.1 combined utilities
Version 3.1 adds convenient helpers for large analyses:
from oligomer_analysis import *

cache_250 = subset_cache_by_frames(cache, range(1, 251))

df_oligomers = oligomer_sizes_by_frame_dataframe(cache, frames_clusters, min_size=2)
df_summary = oligomer_summary_by_frame_dataframe(df_oligomers)
save_oligomer_frame_excel(df_oligomers, df_summary, "oligomer_frame_analysis.xlsx")

plot_pathway_presence_heatmap_safe(df_pathways, finished=finished, max_pathways=50)
Panel 6 / Panel 9 node-size controls
The old 9-panel dashboard and single-panel viewer now allow direct control of node sizes in the network panels:
monitor_oligomer_label(
    cache=cache,
    finished=finished,
    label=finished[0].label,
    inter_thresh=1,
    panel6_node_size=120,   # Panel 6: start/peak/last connection graphs
    panel9_node_size=180,   # Panel 9: small-world snapshot networks
)
For single-panel views:
plot_oligomer_panel(cache, finished, label, panel=6, inter_thresh=1, panel6_node_size=120)
plot_oligomer_panel(cache, finished, label, panel=9, inter_thresh=1, panel9_node_size=180)
For standalone small-world snapshots and series:
plot_panel9_style_snapshot(cache, members, frame, inter_thresh=1, node_size=180)
plot_small_world_range(cache, finished, label, 0, 23, inter_thresh=1, panel9_node_size=180)
Author
CoAna is developed by Dr. Nguyen Truong Co (Truong Co Group) since January 2024; see HISTORY.md for how it grew. ORCID 0000-0001-5642-3641 · Google Scholar
If CoAna helps your work, please cite the software (see CITATION.cff, or the
"Cite this repository" button on GitHub).
License
MIT. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for coana 3.6.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| coana-3.6.1.tar.gz | 280.1 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| coana-3.6.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 528.3 kB
Release files / coana-3.6.1.tar.gz
| Download URL | coana-3.6.1.tar.gz |
|---|---|
| Size | 280.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
27aeb94c900c1008fb08e4a11f816928b82a3c5b5e6107ba81c4d77bac9b7af4
|
|
BLAKE2b-256 checksum How to use checksums |
36d6025fbea110dab3af6ccc5d59a1ad8a8f230c17b6fed7846cc547c0162840
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 24, 2026.
Transparency logRelease files / coana-3.6.1-py3-none-any.whl
| Download URL | coana-3.6.1-py3-none-any.whl |
|---|---|
| Size | 248.3 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d933fddd0f771e0541b39807e6abeab8a79548412ca608f201f640852736ee98
|
|
BLAKE2b-256 checksum How to use checksums |
94766c8772b2bbc4a8f1ce2f25b573b1789d3acdf46c5e942d560241e5d4ae32
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 24, 2026.
Transparency logSecurity for coana 3.6.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for coana-3.6.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 24, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














