
Cocoa: a configurable collator

☕️ Chicago's second favorite bean
About
This repo provides a configurable way to collate data from multiple sources into a single denormalized dataframe and create tokenized timelines from the results. It benefits from previous experience collating data to train foundation models on tokenized electronic health records. 1 2 3 4 5
Installation
Install the latest release from PyPI:
pip install cocoa-tokenizer
This installs the cocoa command. To see it run end to end on public data,
follow the
MIMIC-IV demo,
which installs cocoa with its demo extra (on Python 3.11 to 3.14):
pip install 'cocoa-tokenizer[demo]'
The extra brings clifpy, the CLIF
consortium's Python package, which ships the demo as CLIF tables, and
cocoa get-demo writes them out. The examples below come from that demo and use
its paths: it reads CLIF tables from data-raw/demo and writes processed data to
processed/demo.
(1) Collation
The collator pulls from raw data tables (parquet or csv) and combines them into a
single denormalized dataframe in a
MEDS-like format. Each row
in the output represents an event with a subject_id, time, code (all
mandatory), and optional numeric_value / text_value columns.
Collation is driven by a YAML config (the package ships a default; see
./src/cocoa/config/collation.yaml)
that specifies:
- A reference table with a primary key (
subject_id), start/end times, and optional augmentation joins (e.g. joining a patient demographics table). - A list of entries, each mapping a source table (or the reference frame
itself via
table: REFERENCE) to the output schema. Each entry declares which column provides thecode,time, and optionallynumeric_value, andtext_value. Codes can be given a prefixprefix. Some preprocessing can be done with optional entries forfilter_expr,with_col_expr,agg_expr, andkey. These take the form of polars expressions that are evaluated and applied to the dataframe during loading. Mild checks are performed when evaluating these expressions, but in general, the yaml config is just as powerful as the python. Check all yaml files prior to use. - Subject splits (
train_frac/tuning_frac) that partition subjects chronologically into train, tuning, and held-out sets.
A collation config has three top-level sections: identifiers, subject splits, and the reference + entries that define which events to extract.
Identifiers and splits
subject_id: hospitalization_id # the atomic unit of interest
group_id: patient_id # multiple subjects can belong to a group
default_timezone: UTC # or, e.g. America/Chicago; times are stored in this zone
default_time_unit: us # precision of stored times: 'ms', 'us', or 'ns'
drop_duplicate_events: false # collapse rows an entry repeats verbatim
max_lookback_days: null # drop events more than this many days before start_time
max_lookahead_days: null # drop events more than this many days after end_time

subject_splits:
    train_frac: 0.7
    tuning_frac: 0.1
    # the remainder is held out
subject_id is the column that uniquely identifies each subject (e.g. a
hospitalization). group_id is an optional higher-level grouping column.
Subjects are sorted chronologically and split into train / tuning / held-out sets
according to the specified fractions; with group_id, groups are sorted instead,
each by its earliest start time, keeping every group in one split. Ties are
broken by id, so the split is the same every run.
All timestamps are stored as timezone-aware datetimes in default_timezone (an
IANA name like America/Chicago, defaulting to UTC if unset). Columns that
already carry a timezone are converted instant-preserving; columns without one
are assumed to be local times in default_timezone and labeled as such. Where a
daylight-saving shift makes such a local time ambiguous, the later instant is
used; a local time that a shift skips over is an error. A csv carries no schema,
so its datetimes arrive as strings and are parsed under the same two rules: one
written with a UTC offset is converted, one without is localized.
The timezone is part of the stored dtype, so it travels with the data through the
rest of the pipeline. Durations are computed from instants and are therefore
unaffected by the choice: time spacing tokens, and the winnowing thresholds and
horizons, measure elapsed physical time across a daylight-saving shift. Clock
tokens are different — CLCK//HH marks an hour of the local day in
default_timezone (see Tokenization). And because processed
timestamps keep their timezone, cocoa combine-datasets cannot merge processed
directories that were collated with different default_timezone values.
Timestamps are stored at default_time_unit precision, one of the three polars
datetime units — ms, us (the default), or ns. Raw columns are repinned to
it on load whatever precision they arrive at, so a single unit holds across
tables; set it to match an upstream table or a downstream consumer. As with the
timezone, the unit is part of the stored dtype and travels with the data, so
combine-datasets likewise cannot merge directories collated at different units.
Durations are derived from the stored instants, so the choice changes no token or
label — but note that ns cannot represent times outside 1677–2262.
drop_duplicate_events collapses duplicate events as each entry is collated. Raw
tables can carry the same event more than once — a result posted by two systems,
a vital charted twice, a row multiplied by a join — and each copy would otherwise
become another token at the same timestamp. Rows are compared on the whole
collated event, so two copies are dropped to one only when their subject_id,
time, code, numeric_value, and text_value all agree.
max_lookback_days and max_lookahead_days bound how far a subject's events may
reach outside its reference window, from start_time to end_time (see
Reference table). An event more than max_lookback_days
before its subject's start time, or more than max_lookahead_days after its end
time, is dropped; one exactly at the limit is kept. The limits apply to every
entry, unlike reference_key, which holds a single entry to the window itself. A
day is 24 hours of elapsed time, so like the other durations the limits are
unaffected by daylight-saving shifts, and fractional days are allowed. Either
limit can be set alone, and 0 drops everything outside the window on that side.
Unset or null (the default), a limit drops nothing; so does a null bound, or a
subject missing from the reference table, since there is no time to measure from.
Reference table
The reference table is the primary static table to which other static information can be joined:
reference:
    table: clif_hospitalization
    start_time: admission_dttm
    end_time: discharge_dttm

    augmentation_tables:
        - table: clif_patient
          key: patient_id
          validation: "m:1"
          with_col_expr: pl.lit("age").alias("AGE")
table— the name of the parquet (or csv) file in--raw-data-home(without the extension).start_time/end_time— columns that define the subject's time window; used to filter events from other tables whenreference_keyis set (see below).augmentation_tables— optional list of tables to join onto the reference frame. Each needs akeyto join on and avalidationmode (e.g."m:1"). You can also add computed columns viawith_col_expr.
Pass-through columns
The pass_through_columns option allows you to preserve static columns from the
reference table and include them in the output files. This is useful for
demographic and contextual data that should accompany the collated events:
pass_through_columns:
  - age_at_admission
  - admission_type_category
  ...
Columns specified in this list will be copied from the reference table to:
subject_splits.parquet*_for_inference.parquetfiles (e.g.,train_for_inference.parquet,tuning_for_inference.parquet,held_out_for_inference.parquet) — for use in downstream tasks where you may need subject metadata alongside predictions
Entries
The entries list defines the events to extract. Every entry produces rows with
the columns subject_id, time, code, numeric_value, and text_value. The
entry's fields tell the collator which source columns map to these outputs.
Required fields:
| Field | Description |
|---|---|
table |
Source table name, or REFERENCE to pull from the reference frame. |
code |
Column whose values become the event code. |
time |
Column whose values become the event timestamp. |
Optional fields:
| Field | Description |
|---|---|
prefix |
String prepended to the code (separated by //), e.g. LAB-RES. |
numeric_value |
Column to use as the numeric value for the event. |
text_value |
Column to use as the text value for the event. |
filter_expr |
A Polars expression (or list of expressions) to filter rows before extraction. |
with_col_expr |
A Polars expression (or list) to add computed columns before extraction. |
agg_expr |
A Polars aggregation expression (or list) applied via group_by(...).agg(...) before extraction. |
key |
Grouping key used with agg_expr. Defaults to subject_id when not provided. |
reference_key |
Join the source table to the reference frame on this key and keep only rows within the subject's start_time–end_time window. |
An entry with table: REFERENCE takes these options too. They apply to the
reference frame as the reference block builds it, so they can
use the columns its augmentation tables join on, and they find its start_time
and end_time already converted to default_timezone, where the options of an
entry over any other table see that table's raw columns. They shape that entry's
events alone: the other entries, the subject splits, and the lookback and
lookahead windows still see every row of the reference frame.
Examples:
-
A simple categorical event from the reference frame:
- table: REFERENCE
  prefix: DSCG
  code: discharge_category
  time: discharge_dttm
creates codes such as
DSCG//expired,DSCG//home,DSCG//hospicewith timedischarge_dttm. -
A numeric event from an external table:
- table: clif_labs
  prefix: LAB-RES
  code: lab_category
  numeric_value: lab_value_numeric
  time: lab_result_dttm
creates codes such as
LAB-RES//altandLAB-RES//astwith numeric_valuelab_value_numericat timelab_result_dttm. -
Tables can be filtered prior to extraction with
filter_expr:- table: clif_position prefix: POSN filter_expr: pl.col("position_category") == "prone" code: position_category time: recorded_dttm
selects only rows where
pl.col("position_category") == "prone" -
Multiple filters can be applied as a list:
- table: clif_medication_admin_intermittent_converted
  prefix: MED-INT
  filter_expr:
      - pl.col("mar_action_category") == "given"
      - pl.col("_convert_status") == "success"
  code: med_category
  numeric_value: med_dose_converted
  time: admin_dttm
-
Pre-aggregating events before token extraction with
agg_expr:- table: clif_crrt_therapy prefix: LABEL filter_expr: pl.col("crrt_mode_category").is_not_null() with_col_expr: pl.lit("crrt_init").alias("code") agg_expr: - pl.col("code").sort_by("recorded_dttm").first() - pl.col("recorded_dttm").min() code: code time: recorded_dttm
-
Creating a computed column with
with_col_exprto use as the code:- table: clif_respiratory_support_processed prefix: RESP with_col_expr: pl.lit("fio2_set").alias("code") filter_expr: pl.col("fio2_set").is_finite() code: code numeric_value: fio2_set time: recorded_dttm
-
The
reference_keycan be used to restrict events to a subject's time window:- table: clif_code_status prefix: CODE code: code_status_category time: admission_dttm reference_key: patient_id
Outputs
-
meds.parquetgives a table of the collated events. Here are some of the demo's, from the minutes around hospitalization 27708593's transfer to the ICU, sorted by time:┌────────────┬─────────────────────────┬───────────────────────┬───────────────┬────────────┐ │ subject_id ┆ time ┆ code ┆ numeric_value ┆ text_value │ │ --- ┆ --- ┆ --- ┆ --- ┆ --- │ │ str ┆ datetime[μs, UTC] ┆ str ┆ f32 ┆ str │ ╞════════════╪═════════════════════════╪═══════════════════════╪═══════════════╪════════════╡ │ 27708593 ┆ 2177-03-15 10:49:00 UTC ┆ VTL//heart_rate ┆ 143.0 ┆ null │ │ 27708593 ┆ 2177-03-15 10:49:00 UTC ┆ VTL//respiratory_rate ┆ 13.0 ┆ null │ │ 27708593 ┆ 2177-03-15 10:49:00 UTC ┆ VTL//spo2 ┆ 98.0 ┆ null │ │ 27708593 ┆ 2177-03-15 10:49:00 UTC ┆ VTL//weight_kg ┆ 95.099998 ┆ null │ │ 27708593 ┆ 2177-03-15 10:49:26 UTC ┆ XFR-IN//icu ┆ null ┆ null │ │ … ┆ … ┆ … ┆ … ┆ … │ │ 27708593 ┆ 2177-03-15 11:00:00 UTC ┆ ASMT//cam_mental ┆ null ┆ no │ │ 27708593 ┆ 2177-03-15 11:00:00 UTC ┆ ASMT//cam_total ┆ null ┆ no │ │ 27708593 ┆ 2177-03-15 11:00:00 UTC ┆ ASMT//gcs_eye ┆ 4.0 ┆ null │ │ 27708593 ┆ 2177-03-15 11:00:00 UTC ┆ ASMT//gcs_motor ┆ 6.0 ┆ null │ │ 27708593 ┆ 2177-03-15 11:00:00 UTC ┆ ASMT//gcs_total ┆ 15.0 ┆ null │ └────────────┴─────────────────────────┴───────────────────────┴───────────────┴────────────┘ -
subject_splits.parquetgives a table of every subject_id with its split assignment, its start and end times, and its pass-through columns (left out here):┌────────────┬──────────┬─────────────────────────┬─────────────────────────┐ │ subject_id ┆ split ┆ start_time ┆ end_time │ │ --- ┆ --- ┆ --- ┆ --- │ │ str ┆ str ┆ datetime[μs, UTC] ┆ datetime[μs, UTC] │ ╞════════════╪══════════╪═════════════════════════╪═════════════════════════╡ │ 25563031 ┆ train ┆ 2110-04-11 20:08:00 UTC ┆ 2110-04-14 20:00:00 UTC │ │ 20291550 ┆ train ┆ 2110-11-30 11:31:00 UTC ┆ 2110-12-10 20:53:00 UTC │ │ … ┆ … ┆ … ┆ … │ │ 29366372 ┆ tuning ┆ 2167-05-04 02:24:00 UTC ┆ 2167-05-11 17:57:00 UTC │ │ 22954658 ┆ tuning ┆ 2167-11-08 00:05:00 UTC ┆ 2167-11-11 19:23:00 UTC │ │ … ┆ … ┆ … ┆ … │ │ 27708593 ┆ held_out ┆ 2177-03-12 12:15:00 UTC ┆ 2177-03-19 19:25:00 UTC │ │ 29281842 ┆ held_out ┆ 2178-07-04 02:13:00 UTC ┆ 2178-07-09 01:20:00 UTC │ └────────────┴──────────┴─────────────────────────┴─────────────────────────┘
(2) Tokenization
The tokenizer consumes the collated parquet output and converts events into integer token sequences suitable for sequence models. It:
- Adds
BOS/EOS(beginning/end-of-sequence) tokens to each subject's timeline. - Optionally inserts configurable clock tokens to mark the passage of time.
- Computes quantile-based bins for numeric values (from training data only).
- Optionally inserts configurable time spacing tokens between events.
- Maps codes (and optionally their binned values) to integer tokens via a vocabulary that is formed during training and is frozen for tuning/held-out data.
- Aggregates per-subject token sequences according to time, and then configurable sort order.
Tokenization is driven by its own YAML config (the package ships a default; see
./src/cocoa/config/tokenization.yaml)
that specifies:
n_bins— number of quantile bins for numeric values.fused— whether to fuse the code, binned value, and text value into a single token (true, the default) or keep them as separate tokens (false).include_numeric_values— whether to include raw numeric values alongside tokens in the output (falseby default).include_hours_to_end_time— whether to include, alongside tokens, the fractional hours from each token to its subject'send_timeas recorded insubject_splits.parquet(falseby default). Values count down toward the end time and go negative for tokens beyond it, which theEOSand time spacing tokens of a timeline running pastend_timecan be.min_training_ct— minimum number of times a word must occur in the training split to earn a place in the vocabulary.0(the default) disables the threshold and keeps every word seen while training. Raise it to prune the long tail of one-off codes. Structural tokens (BOS,EOS, and anyCLCK//orTIME//tokens) are exempt and always learned.shuffle_rows— whether to shuffle the order of subjects' rows intokens_times.parquet(falseby default). Each subject's row is unchanged; only the order of rows changes, the same way on every run.insert_spacers— whether to insert time spacing tokens between events. Each marks the gap between two consecutive instants and opens the later one, ahead of the events there.insert_clocks— whether to insert clock tokens at specified times.ordering— the priority order of code prefixes when sorting events within the same timestamp. A prefix missing from it sorts after the listed ones, though still beforeEOS, which always ends the timeline. IfTIMEis missing, time spacing tokens instead sort first, so they still open their instant.spacers— mapping of time intervals (e.g.,5m-15m,1h-2h) to their lower bounds in minutes, used for time spacing tokens.clocks— list of hour strings (e.g.,00,04, ...) at which to insert clock tokens. Hours are read in the collation config'sdefault_timezone, so across a daylight-saving shift a repeated hour yields two tokens and a skipped hour yields none.
Outputs
-
tokens_times.parquetgives one row per subject, ordered by when each timeline opens and then bysubject_id(or shuffled, undershuffle_rows). By default it has three columns:subject_idtokens— the integer token sequence for the subject's timeline.times— a parallel list of timestamps, one per token, indicating when each event occurred.
A
numeric_valuescolumn, holding the corresponding values for numeric value tokens, is added only wheninclude_numeric_valuesis set, and anhours_to_end_timecolumn only wheninclude_hours_to_end_timeis.For the demo, the table looks like this:
┌────────────┬───────────────────┬─────────────────────────────────┐
│ subject_id ┆ tokens            ┆ times                           │
│ ---        ┆ ---               ┆ ---                             │
│ str        ┆ list[u32]         ┆ list[datetime[μs, UTC]]         │
╞════════════╪═══════════════════╪═════════════════════════════════╡
│ 25563031   ┆ [88, 5, … 105]    ┆ [2110-04-11 20:08:00 UTC, 2110… │
│ 20291550   ┆ [88, 1103, … 105] ┆ [2110-11-30 09:45:00 UTC, 2110… │
│ …          ┆ …                 ┆ …                               │
│ 21477991   ┆ [88, 1105, … 105] ┆ [2201-12-11 08:04:13 UTC, 2201… │
└────────────┴───────────────────┴─────────────────────────────────┘
In this example, token 88 corresponds to the beginning-of-sequence token (
BOS), token 105 to the end-of-sequence token (EOS), and the tokens in between correspond to the subject's clinical events in chronological order (with ties broken by the configuredordering). In fused mode each event is a single token; in unfused mode an event with a numeric value becomes two tokens (code + quantile bin). -
tokenizer.yamlis a plain yaml file that contains information about the configuration, learned vocabulary, and bins. This file is sufficient to reconstitute the tokenizer object. Currently, there's an entry for the lookup that maps strings to tokens:lookup: UNK: 0 ADMN//direct: 1 ADMN//ed: 2 ADMN//elective: 3 AGE//age_Q0: 4 …
and an entry for bin cutpoints, listed by code:
bins:
  LAB-RES//platelet_count:
    - 40.0
    - 76.0
    - 108.0
    - 135.0
    - 158.0
    - 189.0
    - 229.0
    - 282.0
    - 348.0
  VTL//heart_rate:
    - 67.0
    - 75.0
    - 80.0
    - 84.0
    - 89.0
    - 94.0
    - 100.0
    - 105.0
    - 113.0
  …
The lists following each key correspond to the cutpoints for the associated category.
(3) Winnowing
The winnower prepares timelines for evaluation by splitting each at a threshold and flagging the outcome tokens on either side. It:
- Loads the tokenized timelines of each split it is configured to prepare.
- Splits each subject's timeline at a configurable threshold, either a duration after the timeline's first event, a duration after the subject's start time, or the first occurrence of a specified token, separating events into "past" (before the threshold) and "future" (after it).
- Checks for the presence of outcome tokens in both the past and future periods.
- Filters out subjects whose timelines never reach the threshold, ensuring subjects have sufficient observation time.
- Outputs a winnowed dataset suitable for inference and evaluation tasks.
Winnowing is driven by a YAML config (the package ships a default; see
./src/cocoa/config/winnowing.yaml)
that specifies:
-
outcome_tokens— list of event codes to track as outcomes (e.g.,XFR-IN//icu,DSCG//expired). The winnower creates binary flags for each outcome indicating whether that token appears in the past or future period. -
threshold— defines how the threshold is set. Currently supported options are as follows:duration_s(integer) thresholds a given duration (in seconds) after the timeline's first eventafter_start_time_s(integer) thresholds a given duration (in seconds) after the subject's start time, thestart_timeof the reference table; see below for how it differs fromduration_sfirst_occurrence(token string) thresholds after the first occurrence of the provided token
Set only one of them: given several, the winnower uses the first in this list.
-
horizon_after_threshold_sis an optional parameter that allows you to set a prediction window (in seconds) after the threshold is triggered -
splits— an optional list selecting which splits to prepare (defaults toheld_out). Rep-based inference also requires thetrainandtuningsplits.
Example configuration:
outcome_tokens: # supports patterns with fnmatch
    - XFR-IN//icu # ICU transfer
    - RESP//imv # invasive mechanical ventilation event
    - DSCG//expired # discharge due to death
    - LABEL//* # any kind of label token
threshold:
    # choose one and only one of the following (given several, the first wins)
    duration_s: !!int 86400 # 24h after the timeline's first event
    # after_start_time_s: !!int 86400 # 24h after the subject's start_time
    # first_occurrence: XFR-IN//icu

horizon_after_threshold_s: !!int 2592000 # 30d outcome window after prediction threshold

splits: # select which splits to prepare
    - train
    - tuning
    - held_out
duration_s vs. after_start_time_s
Both thresholds cut a timeline a set number of seconds after some time, but not after the same time:
duration_scounts from the timeline's first event, the time of itsBOStoken, so every past spans the same stretch of record. Where the cut falls in a stay depends on what was recorded first: a timeline that opens before its admission is cut that much earlier in the stay, and one that opens after it, that much later.after_start_time_scounts from the subject's start time: the reference table'sstart_timecolumn (admission_dttmin the shipped collation config), assubject_splits.parquetrecords it. Every stay is cut at the same point, such as 24 hours after admission, whatever the timeline holds, and events recorded before the start time land in the past.
The two cut a timeline at the same point only if it opens at its start time. With
the shipped collation config, which times its REFERENCE entries at
admission_dttm, no timeline opens after its admission, but many open before it:
on the demo, 236 of the 310 timelines do, by as much as a day, 213 of them with
an arrival in the emergency department (XFR-IN//ed). Held-out hospitalization
29079034 arrives there 20 hours before its admission, so duration_s: 86400 cuts
it less than 4 hours into its stay, with 57 tokens in its past, where
after_start_time_s: 86400 cuts it a day in, with 197.
Under either, an event at exactly the cut falls in the future, and a timeline is
kept only if it runs past the cut. Under after_start_time_s, it must also begin
before the cut, since its past would otherwise be empty; under duration_s, the
past always holds BOS.
Outputs
held_out_for_inference.parquethas columns for each outcome token (e.g.,XFR-IN//icu_past,XFR-IN//icu_future) indicating whether that outcome occurred in the respective time period.train_for_inference.parquetandtuning_for_inference.parquetare also provided; these are required to make rep-based predictions
These files are written to the processed data directory unless cocoa winnow is
given --output-home / -o, which sends them to another directory (created if
need be) and leaves the processed data directory untouched. The files of the
processed data directory are copied there too, so that it is a complete processed
dataset of its own (one cocoa visualize -p can read, say); its subdirectories
are not, nor are any *_for_inference.parquet files already there, which may
come from another configuration. That way one tokenized dataset can be winnowed
under several configurations, each into its own directory:
cocoa winnow -p processed/demo -o processed/demo/winnowed-24h
cocoa winnow -p processed/demo -o processed/demo/winnowed-admit-24h \
    '~threshold.duration_s' threshold.after_start_time_s=86400
cocoa winnow -p processed/demo -o processed/demo/winnowed-icu \
    '~threshold.duration_s' threshold.first_occurrence=XFR-IN//icu
On the demo, the first keeps 57 of the 63 held-out hospitalizations, those whose timelines run past 24 hours; the second 55 of those, the ones that also run past 24 hours after admission, cutting 25 of them later than the first; and the third 26, those with a transfer to the ICU.
(4) Visualization
The visualizer draws one subject's tokenized timeline as an interactive html page, so you can see what collation and tokenization made of it. Unlike the three stages, it writes nothing to the processed data directory: it only reads what they wrote there. It:
- Loads the subject's tokens and times from
tokens_times.parquet, and decodes each token withtokenizer.yamlinto its code, quantile bin, and text value. - Looks up the subject's split, start and end times, and pass-through columns in
subject_splits.parquet. - Finds the numeric value behind each binned token: in the
numeric_valuescolumn if the tokenizer wrote one, or else inmeds.parquet, binned again with the tokenizer's cutpoints to match each value to its token. - Groups codes into lanes by their prefix, one row of the timeline per lane.
- Optionally marks where the winnower split the timeline into past and future,
and which outcome tokens it flagged, from
{split}_for_inference.parquet. - Serves the page on localhost, or saves it as a self-contained html file, a static pdf, or both.
Visualization is driven by a YAML config (the package ships a default; see
./src/cocoa/config/visualization.yaml)
that decides how the page looks, not what data it shows. Every section is
optional, and an empty one means none. It specifies:
show_winnowing— whether to show the winnower's split (falseby default;cocoa visualize --show-winnowingturns it on without a config of your own). The page then marks the threshold, shades the future, and summarizes which outcomes were flagged on each side.lanes— the rows of the timeline, top to bottom, each grouping one or more code prefixes under anameand acolor. A lane is drawn only for a subject with codes of one of its prefixes.palette— colors for prefixes that no lane claims. Each such prefix gets a lane of its own, below the configured ones, and the most frequent in training take the first colors not already worn by a lane, so a prefix keeps its color across a dataset's subjects.other_color— the color of prefixes past the end of the palette, and ofUNK.prefixes— what each prefix denotes, shown on hover alongside the code; it also names the lane of a prefix that no lane claims.descriptions— fuller descriptions of codes, shown on hover, keyed by the code without its bin or text value. Keys may befnmatchpatterns; an exact key wins over a pattern. The shipped config has none.
Example configuration:
show_winnowing: !!bool false

lanes: # top to bottom
    - name: Labs
      prefixes: [LAB-ORD, LAB-RES]
      color: "#007396" # lake
    - name: Vitals
      prefixes: [VTL]
      color: "#A4343A" # brick
    …

palette: # for prefixes no lane claims, most frequent first
    - "#59315F" # violet
    - "#007396" # lake
    …
other_color: "#737373" # dark greystone

prefixes: # shown on hover
    LAB-RES: Lab result
    VTL: Vital sign
    …

descriptions: # none ship; keys may be fnmatch patterns
    VTL//spo2: Oxygen saturation, by pulse oximetry
    ASMT//gcs_*: Glasgow Coma Scale
The shipped lanes cover the prefixes of the shipped collation config. When a
vocabulary has prefixes that no lane claims, cocoa visualize lists them; to
name and color their lanes, list them under lanes in a config passed with -c.
A -c config replaces the shipped default rather than merging into it, so start
from a copy of the default.
The page
The page opens with the subject: its id and split, its start time, end time, and
span, how many tokens, events, and distinct codes its timeline holds, and its
pass-through columns. Below, the timeline draws each event as a mark in its lane,
against an axis in the data's time zone (the collation config's
default_timezone), whatever the viewer's zone:
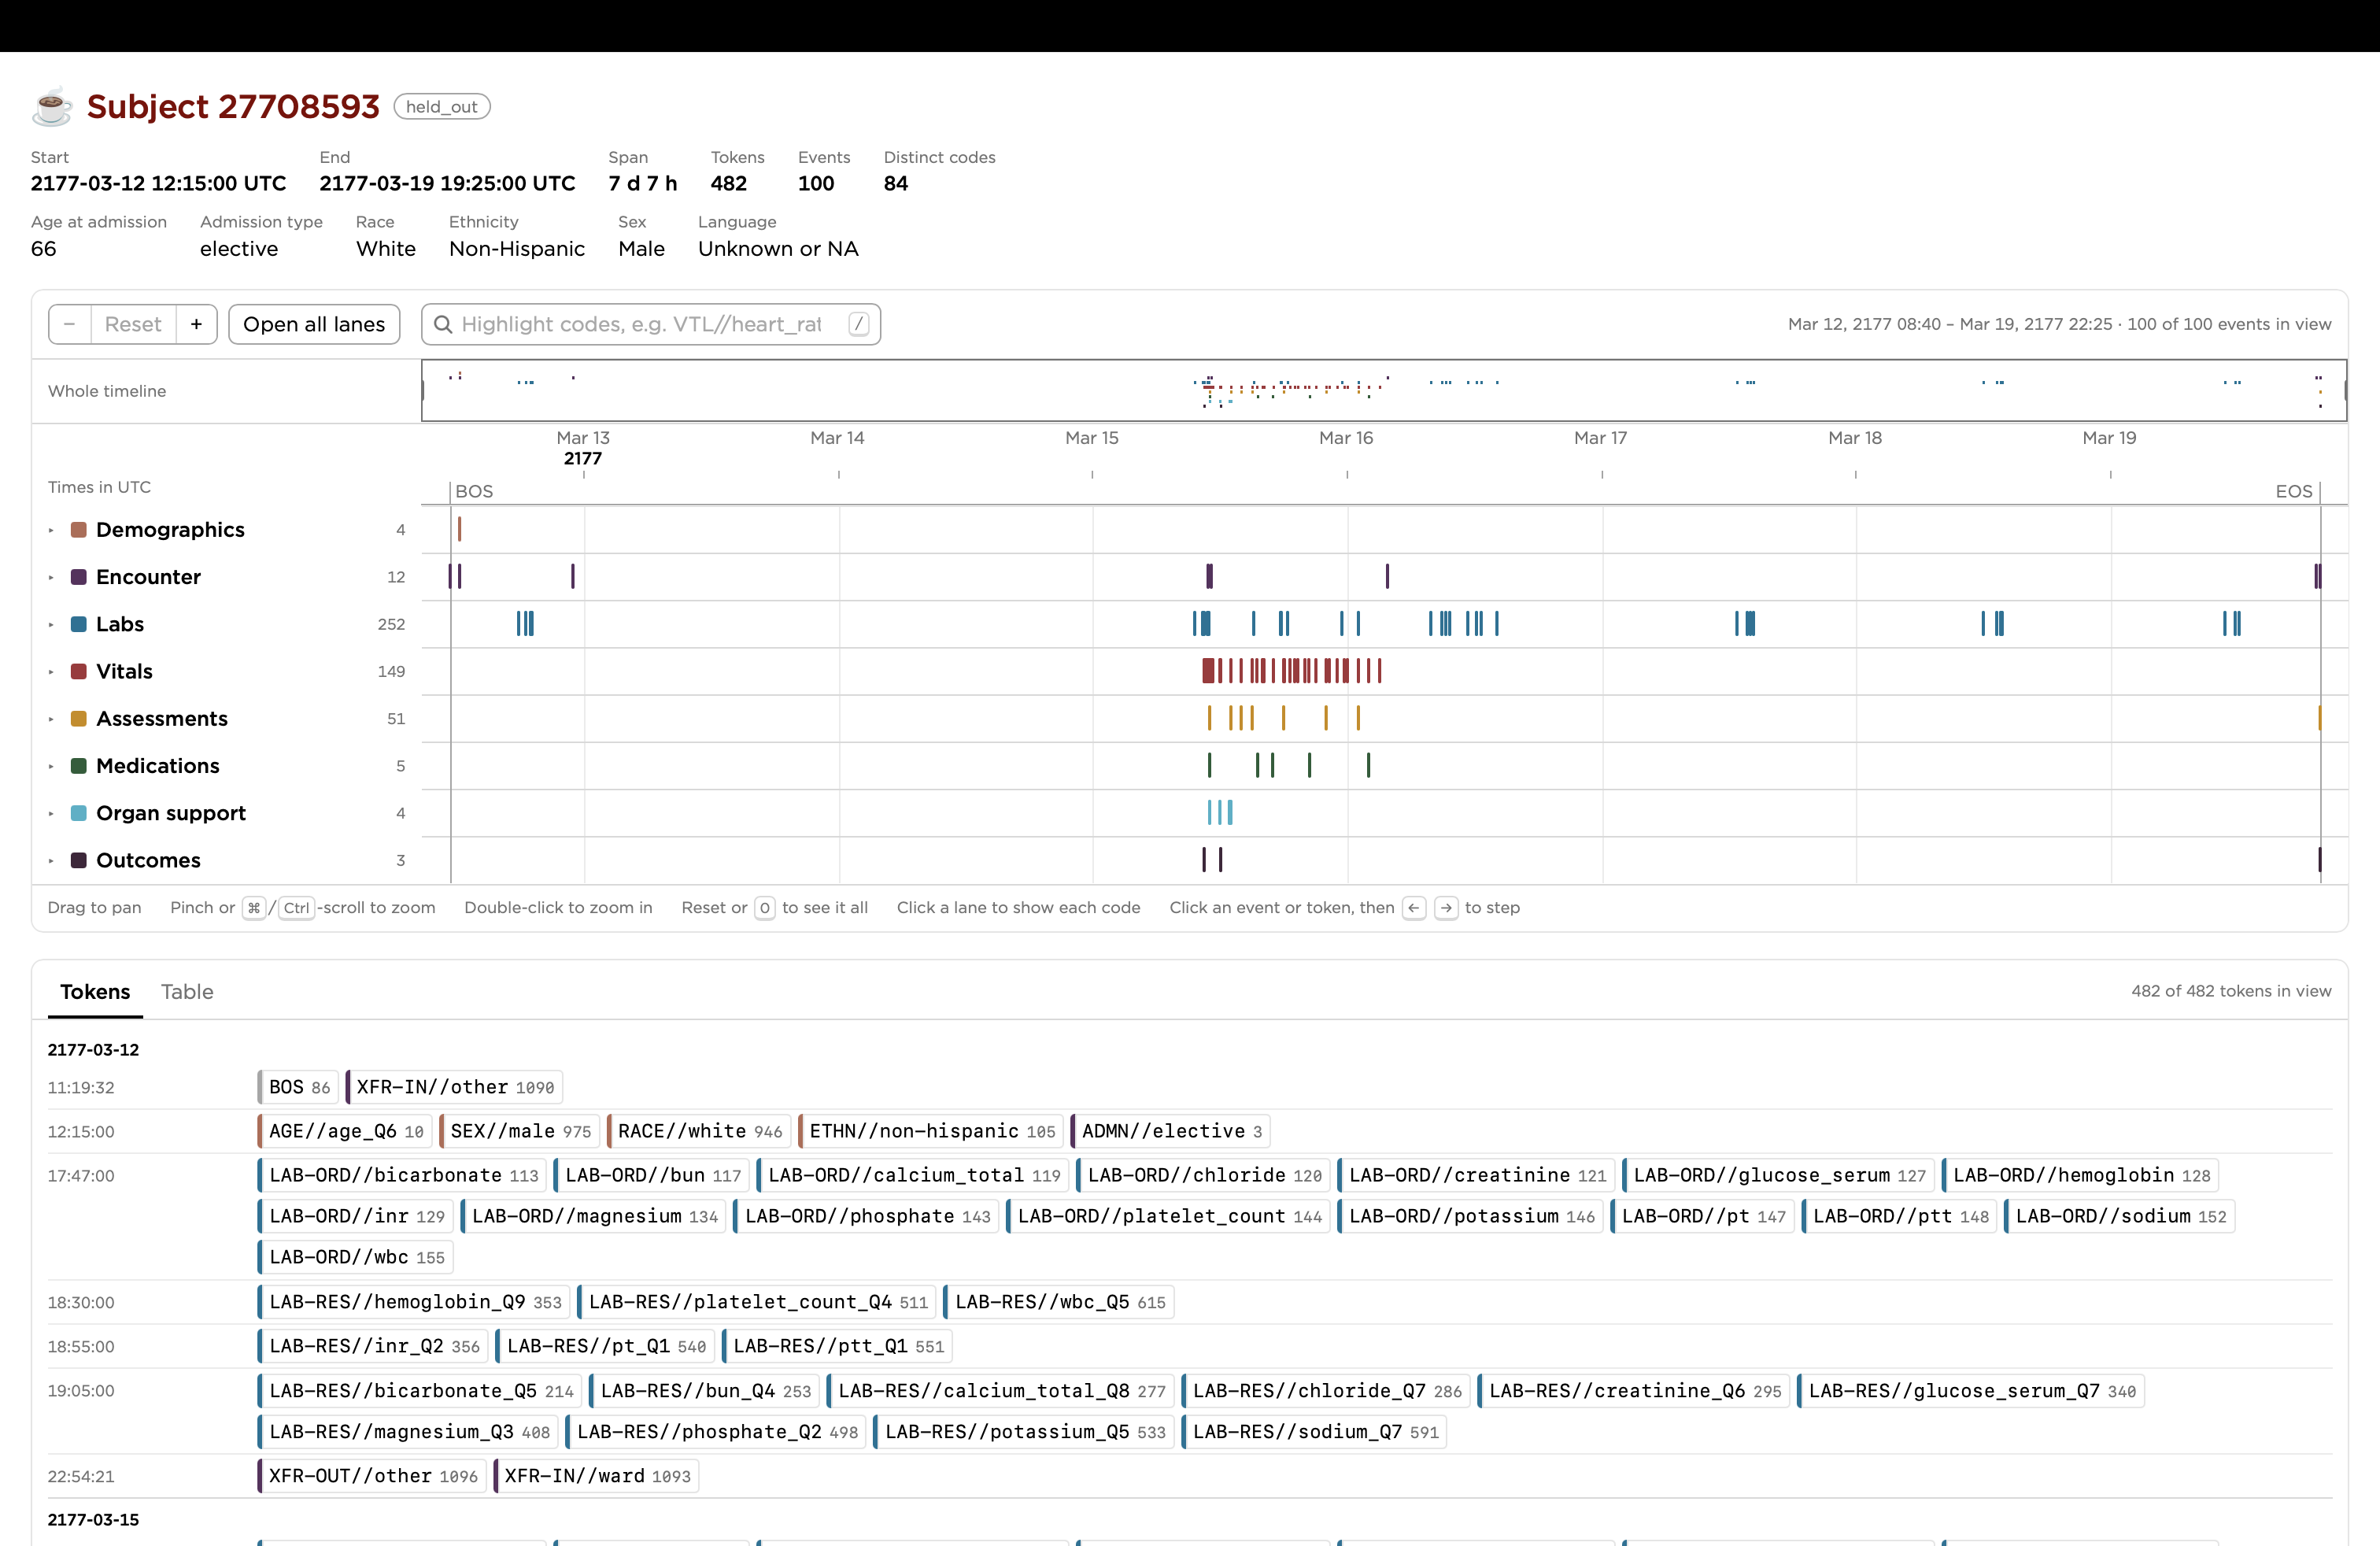
To explore it:
- Drag to pan; pinch, ⌘/Ctrl-scroll, or double-click to zoom; and press
0(or Reset) to see the whole timeline again. The strip above the axis shows the whole timeline, and dragging across it picks the window in view. - Click a lane's name to open it, giving each of its codes a row of its own. A
binned code's marks sit at the height of their quantile, from
Q0at the bottom to the top bin at the top. "Open all lanes" opens every lane at once. - Hover over a mark to see its time, how long after the start time it came, and, for each event in that row at that instant, its code, its value or bin (with the bin's range in training), its description, and its tokens.
- Type in the search box (or press
/) to highlight the codes whose code, prefix name, lane, or description contains the text, and dim the rest. - Click a mark, token, or table row, then step through the events with the arrow keys; while searching, only through the highlighted ones.
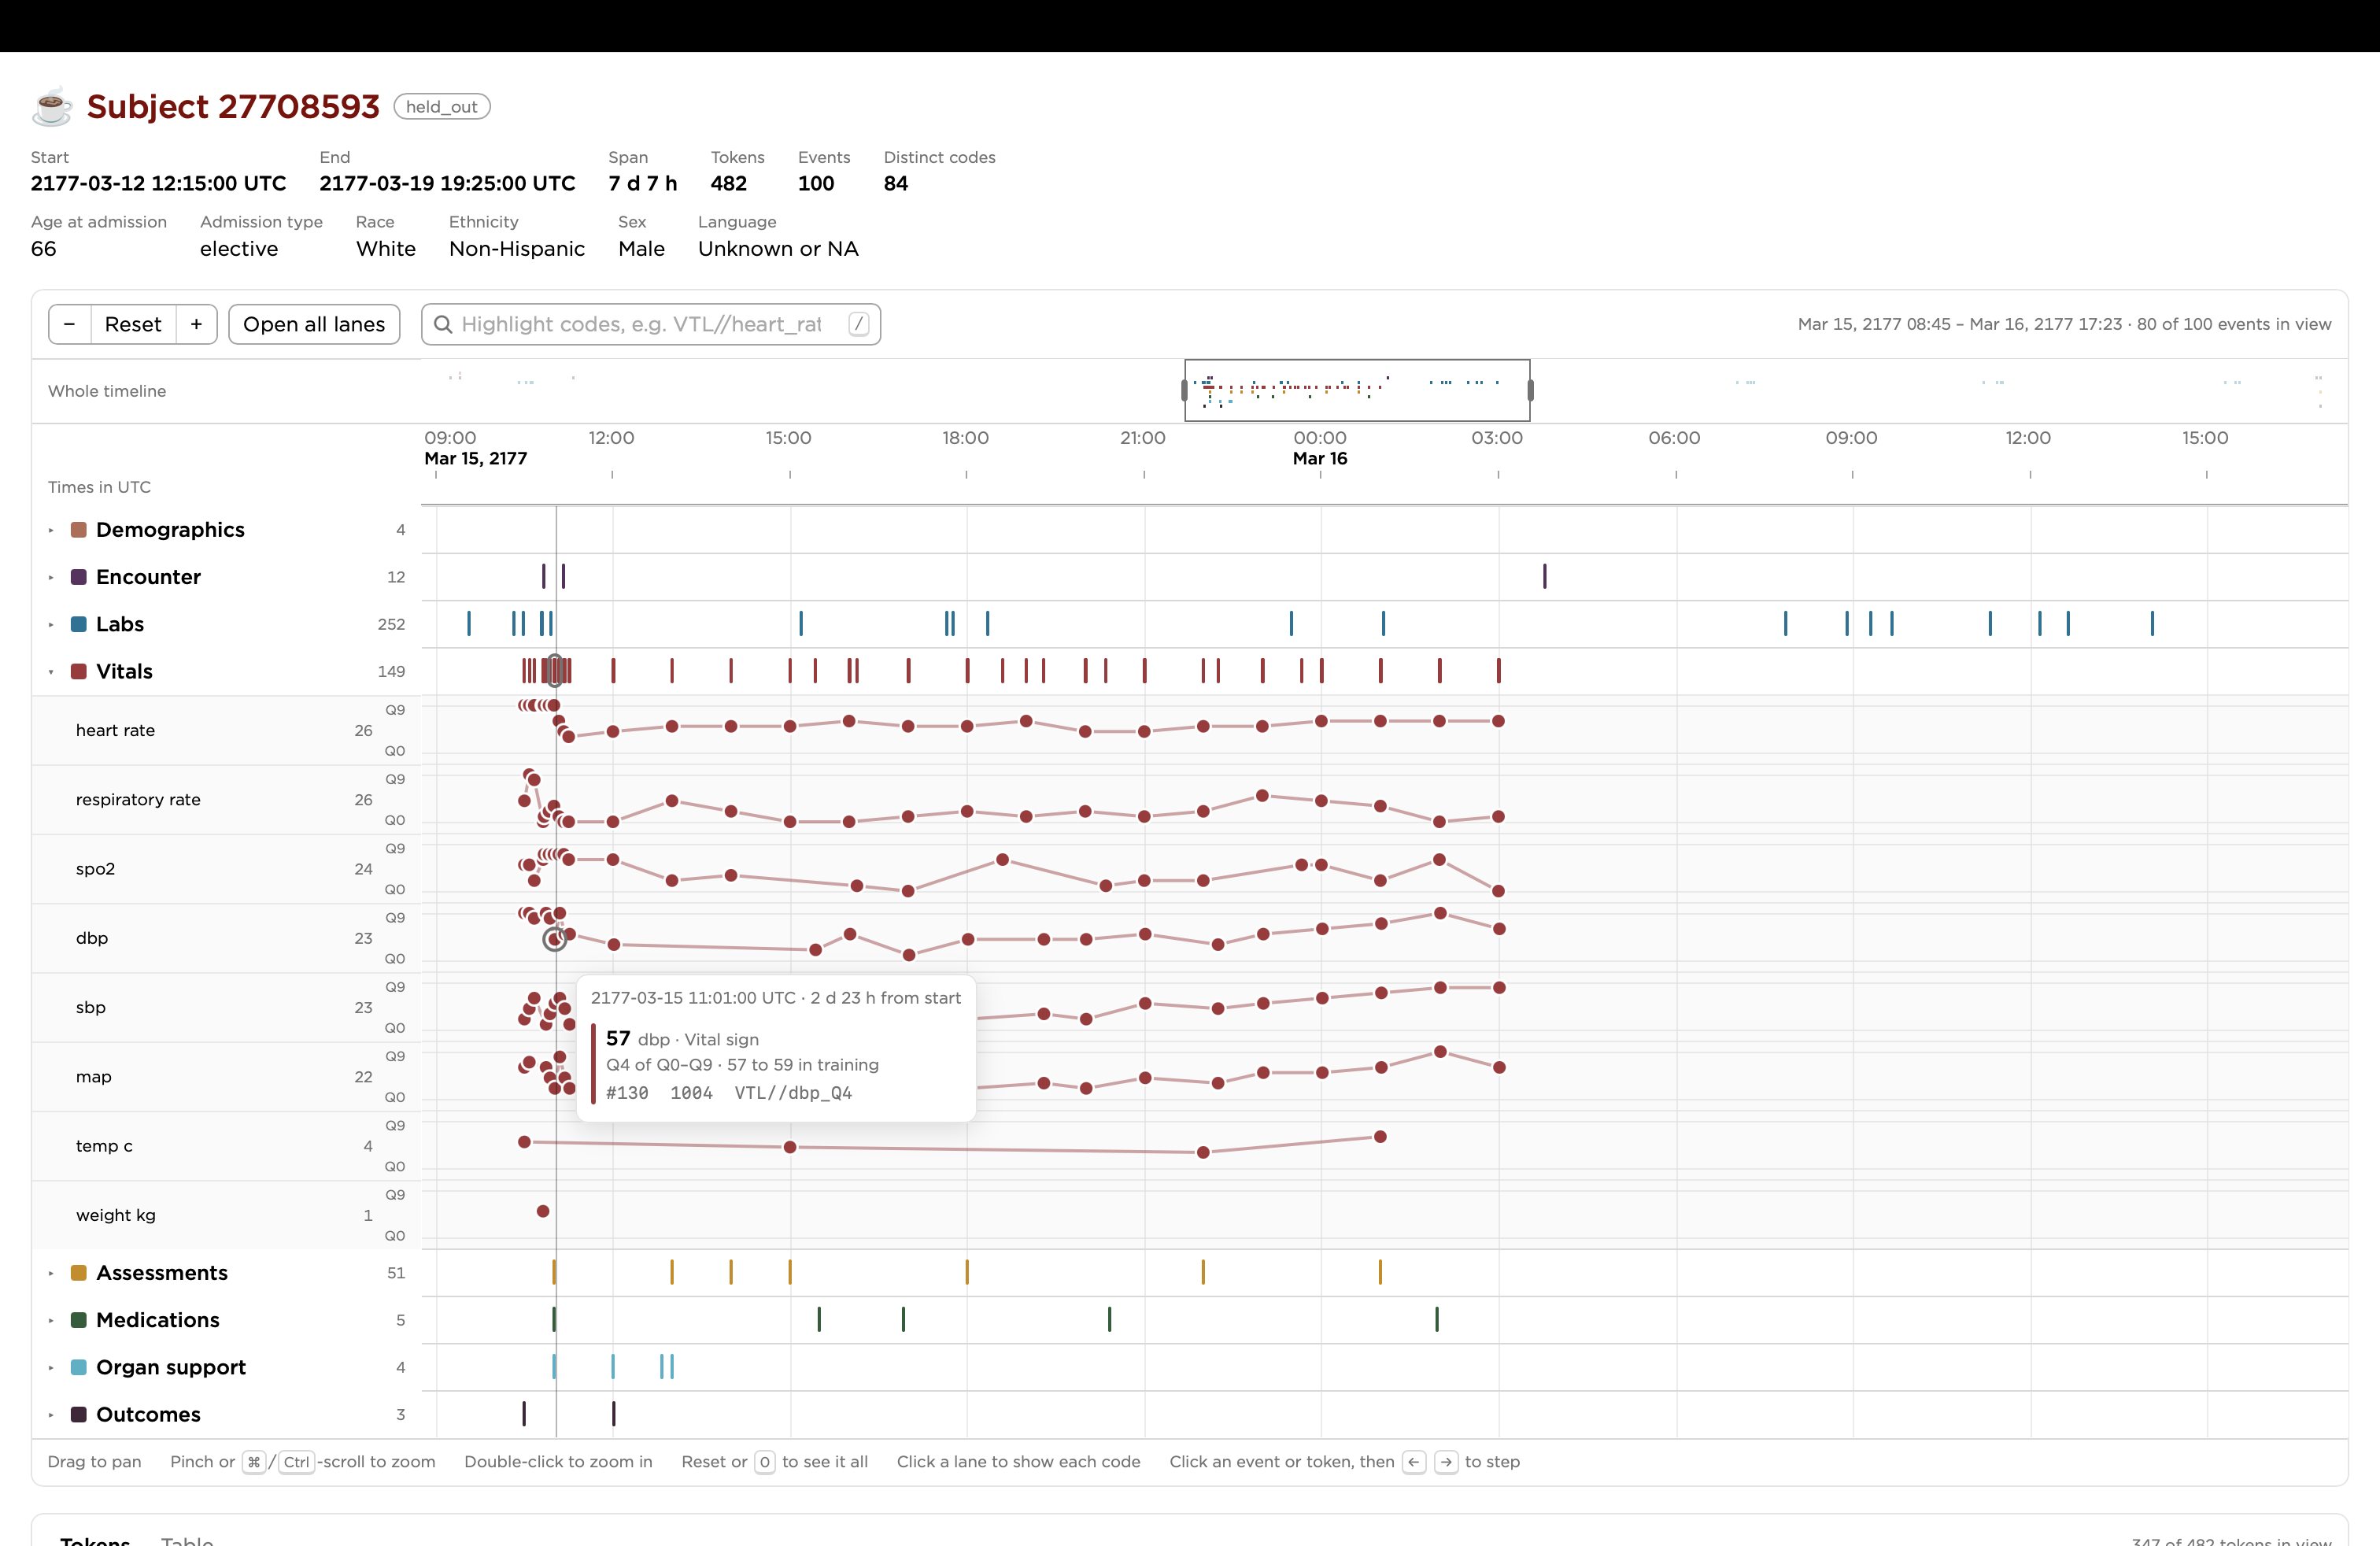
Below the timeline, two tabs list what's in view: Tokens, the tokens grouped by
time, and Table, one row per event with its lane, code, bin, value, text value,
and tokens. With show_winnowing, a summary of the winnower's split follows, and
a footer records the cocoa version, the tokenizer's settings, and the processed
data directory the page was drawn from.
Outputs
cocoa visualize takes a subject id and a processed data directory. By default,
it serves the page at http://127.0.0.1:8765/ (or on a free port, if that one is
taken) until you press Ctrl-C, and --open opens it in a web browser:
cocoa visualize 27708593 -p processed/demo --open
To keep the page rather than serve it, save it to a file, or to two:
cocoa visualize 27708593 -p processed/demo \
    -e timeline.html --export-pdf timeline.pdf
--export-html(-e) writes the page as one self-contained html file. Its styles, script, fonts, and data are inlined, so it loads nothing from the network: anyone can open it in a current web browser, offline, without cocoa or the processed data. Email and file previews often show html without running its script, so until the timeline is drawn, the page asks to be opened in a browser instead.--export-pdfwrites a static pdf of the same timeline, which opens anywhere, even in a phone's message preview. Its first page shows the subject and every lane of the whole timeline; the pages after give every code a row of its own, with binned values at the height of their quantile, and then list the events.
Either file holds the subject's timeline, so share one made from real patient data only as you would the data itself. The visualizer reads a processed data directory written by any release since 26.6.2; the page leaves out whatever an older release didn't write.
Usage
We provide a CLI that should be sufficient for most use cases (to change a few config keys from the command line, see Overriding config keys):
 Usage: cocoa [OPTIONS] COMMAND [ARGS]...

 Configurable collation and tokenization (v26.10.1)

╭─ Options ───────────────────────────────────────────────────────────────╮
│ --install-completion            Install completion for the current      │
│                                 shell.                                  │
│ --show-completion               Show completion for the current shell,  │
│                                 to copy it or customize the             │
│                                 installation.                           │
│ --help                -h        Show this message and exit.             │
╰─────────────────────────────────────────────────────────────────────────╯
╭─ Commands ──────────────────────────────────────────────────────────────╮
│ collate           Collate raw data into a denormalized format.          │
│ tokenize          Tokenize collated data into integer sequences.        │
│ winnow            Winnow timelines for evaluation.                      │
│ pipeline          Run the full pipeline: collate, tokenize, & winnow.   │
│ combine-datasets  Combine multiple processed datasets into one.         │
│ visualize         Visualize a subject's timeline as an interactive html │
│                   page.                                                 │
│ get-demo          Write the MIMIC-IV demo's CLIF tables, from clifpy.   │
╰─────────────────────────────────────────────────────────────────────────╯
with commands:
-
cocoa collateUsage: cocoa collate [OPTIONS] [overrides]... Collate raw data into a denormalized format. Reads collation configuration and produces a MEDS-like parquet file with collated events. ╭─ Arguments ─────────────────────────────────────────────────────────────╮ │ overrides <str> Config overrides: key=value sets a key, adding │ │ it if need be, and ~key deletes one │ ╰─────────────────────────────────────────────────────────────────────────╯ ╭─ Options ───────────────────────────────────────────────────────────────╮ │ --collation-config -c <path> Collation configuration file │ │ (overrides default) │ │ * --raw-data-home -r <str> Raw data directory [required] │ │ * --processed-data-home -p <str> Processed data directory │ │ [required] │ │ --verbose -v Verbose logging for collate; │ │ this may cause memory issues │ │ with large datasets │ │ --help -h Show this message and exit. │ ╰─────────────────────────────────────────────────────────────────────────╯ -
cocoa tokenizeUsage: cocoa tokenize [OPTIONS] [overrides]... Tokenize collated data into integer sequences. Reads collated parquet files and produces tokenized timelines with vocabulary and bin information. ╭─ Arguments ─────────────────────────────────────────────────────────────╮ │ overrides <str> Config overrides: key=value sets a key, adding │ │ it if need be, and ~key deletes one │ ╰─────────────────────────────────────────────────────────────────────────╯ ╭─ Options ───────────────────────────────────────────────────────────────╮ │ --tokenization-config -c <path> Tokenization configuration │ │ file (overrides default) │ │ * --processed-data-home -p <str> Processed data directory │ │ [required] │ │ --tokenizer-home -t <str> Load a previously learned │ │ tokenizer from this │ │ tokenizer.yaml file (reuses │ │ its frozen config, │ │ vocabulary, and bins) │ │ --verbose -v Verbose logging for tokenize; │ │ this may cause memory issues │ │ with large datasets │ │ --help -h Show this message and exit. │ ╰─────────────────────────────────────────────────────────────────────────╯ -
cocoa winnowUsage: cocoa winnow [OPTIONS] [overrides]... Winnow timelines for evaluation. Splits each timeline of the configured splits into a past and a future at a threshold, drops those that never reach it, and flags which outcome tokens fall on each side. ╭─ Arguments ─────────────────────────────────────────────────────────────╮ │ overrides <str> Config overrides: key=value sets a key, adding │ │ it if need be, and ~key deletes one │ ╰─────────────────────────────────────────────────────────────────────────╯ ╭─ Options ───────────────────────────────────────────────────────────────╮ │ --winnowing-config -c <path> Winnowing configuration file │ │ (overrides default) │ │ * --processed-data-home -p <str> Processed data directory │ │ [required] │ │ --output-home -o <str> Directory to write the │ │ winnowed files to, along with │ │ copies of the processed data │ │ directory's files (defaults │ │ to the processed data │ │ directory) │ │ --verbose -v Verbose logging for winnow; │ │ prints summary statistics │ │ --help -h Show this message and exit. │ ╰─────────────────────────────────────────────────────────────────────────╯ -
cocoa pipelineUsage: cocoa pipeline [OPTIONS] [overrides]... Run the full pipeline: collate, tokenize, & winnow. ╭─ Arguments ─────────────────────────────────────────────────────────────╮ │ overrides <str> Config overrides, each key starting with the │ │ stage it's for: e.g. tokenization.n_bins=5 or │ │ ~winnowing.threshold.duration_s │ ╰─────────────────────────────────────────────────────────────────────────╯ ╭─ Options ───────────────────────────────────────────────────────────────╮ │ --collation-config <path> Collation configuration file │ │ (overrides default) │ │ --tokenization-config <path> Tokenization configuration │ │ file (overrides default) │ │ --winnowing-config <path> Winnowing configuration file │ │ (overrides default) │ │ * --raw-data-home -r <str> Raw data directory [required] │ │ * --processed-data-home -p <str> Processed data directory │ │ [required] │ │ --verbose -v Verbose logging for pipeline │ │ steps │ │ --help -h Show this message and exit. │ ╰─────────────────────────────────────────────────────────────────────────╯ -
cocoa visualizeUsage: cocoa visualize [OPTIONS] {subject_id} [overrides]... Visualize a subject's timeline as an interactive html page. Serves the page on localhost until interrupted, or saves it as a self-contained html file with --export-html, a static pdf with --export-pdf, or both. ╭─ Arguments ─────────────────────────────────────────────────────────────╮ │ * subject_id <str> Subject whose timeline to show [required] │ │ overrides <str> Config overrides: key=value sets a key, │ │ adding it if need be, and ~key deletes one │ ╰─────────────────────────────────────────────────────────────────────────╯ ╭─ Options ───────────────────────────────────────────────────────────────╮ │ * --processed-data-home -p <str> Processed data directory │ │ [required] │ │ --visualization-config -c <path> Visualization configuration │ │ file (overrides default) │ │ --export-html -e <path> Save the timeline to this │ │ self-contained html file │ │ instead of serving it │ │ --export-pdf <path> Save a static pdf of the │ │ timeline to this file │ │ instead of serving it; with │ │ --export-html, save both │ │ --host <str> Address to serve the page on │ │ [default: 127.0.0.1] │ │ --port <int> Port to serve the page on; 0 │ │ picks any │ │ [default: 8765] │ │ --open Open the page in a web │ │ browser │ │ --show-winnowing Show the winnowing split │ │ into past and future, and │ │ its outcome flags │ │ --help -h Show this message and exit. │ ╰─────────────────────────────────────────────────────────────────────────╯ -
cocoa combine-datasetsUsage: cocoa combine-datasets [OPTIONS] {input_data_dirs}... Combine multiple processed datasets into one. Merges the parquet files of the input directories and keeps the first directory's tokenizer.yaml, warning if another's differs. ╭─ Arguments ─────────────────────────────────────────────────────────────╮ │ * input_data_dirs <str> Processed data directories to combine │ │ [required] │ ╰─────────────────────────────────────────────────────────────────────────╯ ╭─ Options ───────────────────────────────────────────────────────────────╮ │ * --output-data-dir -o <str> Output directory for combined data │ │ [required] │ │ --help -h Show this message and exit. │ ╰─────────────────────────────────────────────────────────────────────────╯ -
cocoa get-demoUsage: cocoa get-demo [OPTIONS] Write the MIMIC-IV demo's CLIF tables, from clifpy. Copies the tables of the demo that clifpy ships to a raw data directory, and derives from them, with clifpy, the four more that the shipped collation config reads. Needs clifpy, which cocoa's demo extra installs. ╭─ Options ───────────────────────────────────────────────────────────────╮ │ * --raw-data-home -r <str> Raw data directory to write to │ │ [required] │ │ --verbose -v Show what clifpy prints as it │ │ derives tables │ │ --help -h Show this message and exit. │ ╰─────────────────────────────────────────────────────────────────────────╯
Overriding config keys
To change a few keys without writing a new config file, list them after a command's options, as dotted paths into its config:
cocoa tokenize -p processed/demo n_bins=5 insert_spacers=true
cocoa pipeline takes them too, each key starting with the stage it's for:
cocoa pipeline -r data-raw/demo -p processed/demo \
    collation.default_timezone=America/New_York tokenization.n_bins=5 \
    '~winnowing.threshold.duration_s' winnowing.threshold.first_occurrence=XFR-IN//icu
It checks every stage's overrides before collating, so an unreadable winnowing override fails at once rather than after the first two stages have run.
The syntax borrows from Hydra's:
key=valuesets a key, adding it if it isn't there, e.g. ahorizon_after_threshold_sfor winnowing. Keys aren't checked against the config, so a misspelled one is added quietly and does nothing. A leading+or++, as Hydra marks an addition, is accepted and ignored.~keydeletes a key.
Overrides apply in order to the config file passed with -c (or to the shipped
default when none is). Values are read as YAML: 0.5 is a float, [a, b] a
list, and {train_frac: 0.5} a block, merged into any block already there.
A few things to know:
- Setting a key to
nulldoesn't switch it off where its presence is what counts. The winnower uses whichever ofthreshold.duration_s,threshold.after_start_time_s, andthreshold.first_occurrenceis there (the first in that order, if several are), so switching between them takes~on one and setting the other, as above. Settingthreshold.after_start_time_salone changes nothing, since the shippedthreshold.duration_soutranks it. - Lists are replaced whole:
entriescan't be edited one item at a time, so a change to an entry calls for a config file. - YAML decides each value's type, so quote what has to stay a string:
'clocks=["00", "12"]', since an unquoted00is the number 0, and'other_color="#737373"', since an unquoted#starts a comment. - With
--tokenizer-home, the loaded tokenizer's saved config is used as written: it is frozen, so neither overrides nor-capply, and nothing from the shipped default is merged in (cocoa tokenizesays so when given either). - Quote anything starting with
~in zsh, which otherwise reads it as a directory name and fails.
Combining datasets
cocoa combine-datasets merges processed directories into one, such as the
timelines of two hospitals, or of the two periods that the
tokenizer transfer recipe
splits the demo into:
cocoa combine-datasets processed/demo-2011-2013 processed/demo-2014-2016 \
    -o processed/demo-combined
Each parquet file of the first directory (meds.parquet,
subject_splits.parquet, tokens_times.parquet, and any
{split}_for_inference.parquet) is concatenated with the file of the same name
in each of the others, and its rows are shuffled, the same way on every run. Each
subject keeps the split it had, so the combined splits are the inputs' splits put
together, not a fresh split of the combined subjects.
The output gets the first directory's tokenizer.yaml, so every input's tokens
have to come from that one tokenizer: tokenize each of the others with
--tokenizer-home pointing at the first's tokenizer.yaml. The inputs'
tokenizer.yaml files are compared, but a difference isn't refused:
combine-datasets warns of a Configuration mismatch, logs the keys that
differ, and combines the inputs anyway. A tokenizer loaded with
--tokenizer-home records is_training: false where the one it came from
records true, so expect that key in the warning; any other key means the inputs
were tokenized differently, and their tokens don't mean the same thing.
A few more things to know:
- Subject ids must not repeat across the inputs.
combine-datasetsdoesn't check, butcocoa winnowthen fails on the combined directory, since it pairs each timeline with a single row ofsubject_splits.parquet. - The first directory decides which files are combined: a parquet file only a later directory has is left out, and one that a later directory lacks is an error. Likewise, a column only the first input has is filled with nulls for the others, but a column only a later input has is an error, so list the input with the most columns first.
- Inputs collated with different
default_timezoneordefault_time_unitvalues can't be combined; polars fails with aSchemaError.
Contributing
Contributions are welcome, from bug reports and typo fixes to new features. To get started, see the contributing guide.
-
M. Burkhart, B. Ramadan, Z. Liao, K. Chhikara, J. Rojas, W. Parker, & B. Beaulieu-Jones, Foundation models for electronic health records: representation dynamics and transferability, arXiv:2504.10422 ↩
-
M. Burkhart, B. Ramadan, L. Solo, W. Parker, & B. Beaulieu-Jones, Quantifying surprise in clinical care: Detecting highly informative events in electronic health records with foundation models, Pacific Symposium on Biocomputing 31 (2026), 173–188 ↩
-
L. Solo, M. McDermott, W. Parker, B. Ramadan, M. Burkhart, & B. Beaulieu-Jones, Efficient generative prediction for EHR foundation models: the SCOPE and REACH estimators, arXiv:2602.03730 ↩
-
I. Lee, L. Solo, M. Burkhart, B. Ramadan, W. Parker, & B. Beaulieu-Jones, Representation before training: a fixed-budget benchmark for generative medical event models, arXiv:2604.16775 ↩
-
M. Burkhart, L. Solo, I. Lee, S. Charles, Z. Liao, K. Chhikara, D. Therese, W.-T. Liao, C. Gao, W. Parker, & B. Beaulieu-Jones, Federated generative event models for tokenized electronic health records, arXiv:2608.02939 ↩
2 maintainers


Metadata
2 maintainers
Release files for cocoa-tokenizer 26.10.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| cocoa_tokenizer-26.10.3.tar.gz | 340.9 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cocoa_tokenizer-26.10.3-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 525.9 kB
Release files / cocoa_tokenizer-26.10.3.tar.gz
| Download URL | cocoa_tokenizer-26.10.3.tar.gz |
|---|---|
| Size | 340.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ed55f5665fce5ec1f0f283de6f9600316fdc0d4f2860efa0e392ea7f39dab14e
|
|
BLAKE2b-256 checksum How to use checksums |
a5a2cf1565c279e031f9c6f8f5705a76cb099579551ea9dd268fc937a023c0bb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.15
|
Release files / cocoa_tokenizer-26.10.3-py3-none-any.whl
| Download URL | cocoa_tokenizer-26.10.3-py3-none-any.whl |
|---|---|
| Size | 185.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
582b4cf6372a7352ffe06b875fe7df617b36726e45d36b3a8310e9dca482473a
|
|
BLAKE2b-256 checksum How to use checksums |
1cbbb9d776ca32270002f893738979ded07ad3668fe75db5f74f7804a4cd4c91
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.15
|
Security for cocoa-tokenizer 26.10.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














