
cost-risk-toolkit


Cost estimating, earned value and schedule analysis for defense programs, as
one Python package and one command, ce-core. It forecasts a program's cost
and finish from its EVM data or an IPMDAR delivery, checks a Microsoft Project
schedule against the DCMA 14 points, runs joint cost and schedule confidence
(JCL), compares alternatives on life-cycle cost, chooses a portfolio within a
budget, fits learning curves and CERs, and reads real programs' unit costs out
of public SARs. Every result says what it means in plain words, and writes
down every assumption it made.
Start here
pip install "cost-core[plots]"   # the charts need the [plots] part
ce-core                          # what it can do, in plain English
ce-core demo evm                 # see it work on example data: no files needed
ce-core template evm             # a spreadsheet to fill in with your own numbers
If ce-core isn't found after installing (common on managed Windows PCs),
python -m cost_core does exactly the same. docs/getting-started.md
walks through each task from "what do I need" to "what does this tell me".
| I want to... | Try it | Then with my data |
|---|---|---|
| Forecast a program's final cost and finish from EVM | ce-core demo evm |
ce-core evm --data my_evm.xlsx or --ipmdar delivery.zip |
| Check a schedule's logic (DCMA 14-point) | ce-core demo schedule |
ce-core schedule-check --mspdi my_schedule.xml |
| Know the chance of meeting a budget and a date (JCL) | ce-core demo jcl |
ce-core jcl --spec my_jcl.json |
| Compare alternatives on life-cycle cost (AoA) | ce-core demo aoa |
ce-core aoa --spec my_aoa.json |
| Choose which programs to fund within a budget | ce-core demo portfolio |
ce-core portfolio --spec my_portfolio.json |
| Fit a learning curve to production lots | ce-core template lots |
ce-core fit-lots --csv my_lots.csv --dollar-year 2026 |
| See how real programs' unit costs grew | ce-core sar-panel --programs F-35 |
ce-core template <topic> writes the file to fill in for each one, and every
command answers --help. Every result also comes as one Excel workbook,
report.xlsx, with a plain-English summary, the tables, live charts and the
assumptions; in the EVM workbook the metrics are Excel formulas, so a
reviewer can click any CPI and see how it was made. And as a short
PowerPoint briefing, brief.pptx, that opens with the bottom line, then the
chart, the numbers behind it and the assumptions. The rest of this page is the reference: what each
part does, how, and why.
Want a window instead of a terminal? The desktop lot cost model lives in
its own repository, lot-cost-model.
It is a tkinter tool over the same three models: paste analogy lots and
estimate lots from Excel, fit LC, Rate and LC+Rate, roll several WBS elements
into one programme, and write the Excel workbook. Since its 3.0.0 it is a front
end onto this library rather than a second copy of it: the fit, the roll-up, the
risk and the workbooks all come from cost_core, and the window refuses to
start without it.
Learning curves from your own lot data
Fit a curve to your own lot data in one command:
ce-core fit-lots --csv my_lots.csv --dollar-year 2026 --out results/
lot,units,cost
LRIP 1,22,96800000
LRIP 2,18,70200000
FRP 1,25,90000000
Two columns is the whole input. Jump to the details, including the four things that quietly ruin a lot fit and how the tool checks for each one.
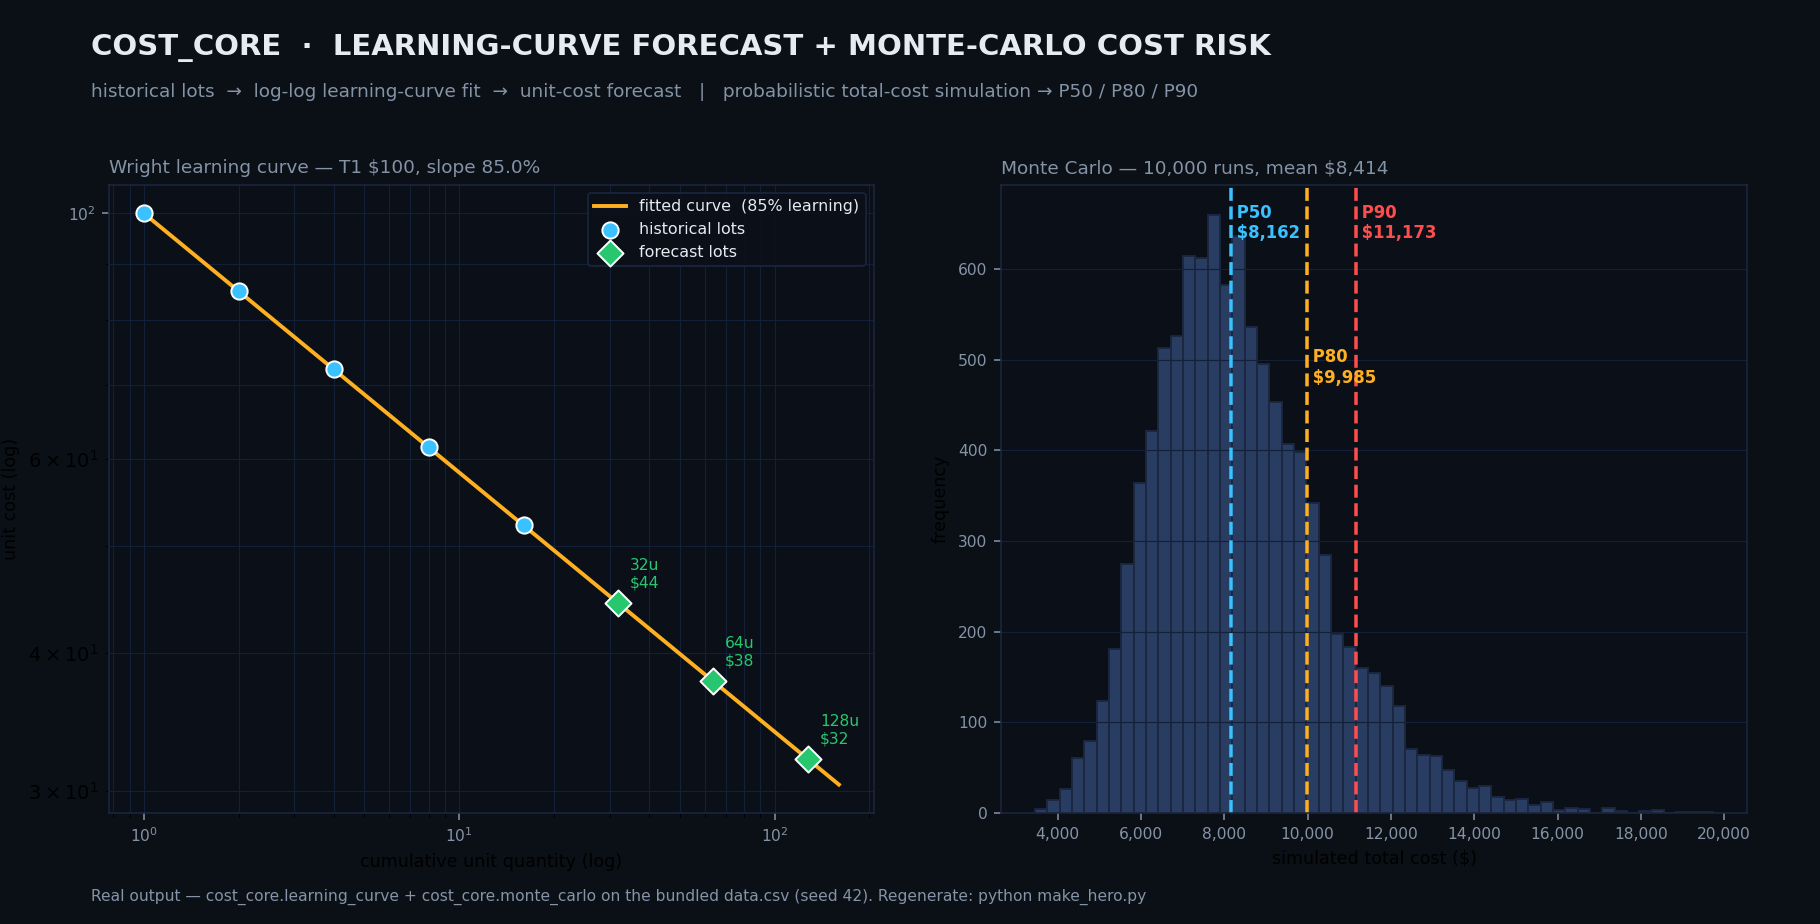
Real output. cost_core fits an 85% Wright learning curve and forecasts future
lots (left), then runs a 10,000 iteration Monte Carlo total cost simulation with
P50/P80/P90 thresholds (right). Regenerate with python make_hero.py, which
reads a local data.csv that isn't committed, since .gitignore excludes
*.csv.
No proprietary data is committed to this repository. You supply your own for
fit-lots, and nothing you pass in gets stored here. The synthetic pipeline and most of the test suite run on a seeded generator producing invented programs in the shape of CADE submissions. The one exception is public:cost_core.publicreads DoD's released Selected Acquisition Reports, and its tests carry the text of a few pages from five of them, which are U.S. government works in the public domain.
What it does
| Module | Purpose |
|---|---|
cost_core.lotmodel |
The lot cost engine. Analogy lots in, estimate lots out. Fits LC / Rate / LC+Rate, selects on significance with an AICc tiebreak, and layers refits, influence, prediction intervals and buy risk on top. Carried over from the desktop tool in lot-cost-model, which runs on this code from its 3.0.0 rather than a copy of it |
cost_core.program |
WBS roll-up. Several elements, fitted, factor or amount, priced against one lot schedule and correlated into a programme estimate |
cost_core.lots |
Your own data. Units and cost per lot, in CSV or Excel. Runs the same three model engine, then layers the statistics on top |
cost_core.synth |
Seeded synthetic CSDR/SRDR generator: DD 1921, DD 1921-1, DD 1921-2, Cost and Hour Report (FlexFile), Quantity Data Report, SRDR (DD 2630), with realistic pathologies to clean |
cost_core.ingest |
ETL to one normalized long table: WBS crosswalk, base year normalization, resubmission dedup, loud validation gates, row level provenance |
cost_core.fitting |
Shared estimator: OLS, MUPE and ZMPE, with delta method prediction and confidence intervals |
cost_core.learning_curve |
Wright (cumulative average) and Crawford (unit) theories, rate breaks, prediction intervals |
cost_core.cer |
Parametric CERs, log log and linear, with leverage and influence diagnostics, extrapolation warnings, small sample guardrails |
cost_core.monte_carlo |
Correlated WBS level risk: Gaussian copula or Iman Conover, PSD repair, discrete risks, tornado, convergence |
cost_core.reporting |
S curve, tornado, cost improvement curve, CER diagnostics, and the assumptions log |
cost_core.evm |
Earned value. CPI, SPI, TCPI, the independent EACs and earned schedule from a spreadsheet or an IPMDAR delivery, the warning signs named, and the EAC and finish forecast as a calibrated range |
cost_core.aoa |
Analysis of alternatives. Life-cycle cost of each alternative in base-year, then-year and present-value dollars, compared under correlated uncertainty: P50, P80, the chance each is cheapest, cost-effectiveness and which are dominated |
cost_core.schedule |
Schedules, DCMA and JCL. Microsoft Project XML read in and checked against the DCMA 14 points; an activity network with uncertain durations, time-independent and time-dependent costs, a standing army and discrete risks, simulated jointly: the probability of meeting a budget and a date together, the 70% line, and how often each activity is critical |
cost_core.portfolio |
Which programs to fund. An integer program over candidates, funding options and yearly budgets, with mandatory programs, dependencies and exclusive alternatives; the marginal value of money by year, a value against budget frontier, and the chance the chosen portfolio breaks each year's budget |
cost_core.public |
Real programs. DoD's public Selected Acquisition Reports, 2010 to today, read into a program by year table of unit cost against the current and original baselines, with the source file and an arithmetic check behind every number |
Real programs from public SARs
Every major defense program reports to Congress each year in a Selected Acquisition Report, and DoD releases them. Their unit cost pages are the longest public record of cost growth there is: what each program expected a unit to cost when it started, and what it expects now, in constant dollars.
pip install "cost-core[public]"
ce-core sar-panel --list-cycles
ce-core sar-panel --programs F-35 --out f35/
The second command reads the F-35's SARs from December 2010 to the FY 2027
budget and writes three files: unit_cost.csv (PAUC and APUC, baseline beside
current estimate, per subprogram and report), reports.csv (what was read and
what wasn't, and why) and checks.csv. Leave off --programs for all of them,
about a thousand reports, which takes an hour or two the first time and
seconds after, since every download is cached.
On a machine with no internet. Point it at a folder of SAR PDFs you already have, from DAMIR, the reading room, or a drive someone handed you, and nothing touches the network:
ce-core sar-panel --dir path/to/sars --out panel/
Each file's reporting cycle comes from the reading room's folder name if you
kept it (FY_2014_SARS, June_2025_MSARs), otherwise from the file name
("F-35_SAR_Dec_2017.pdf", "AAG_MSAR_FY2027_PB.pdf"). A file whose name gives no
cycle is still read, and its own date line lands in report_label. The file's
path and SHA-256 go beside every row, the same as for a download.
A few things worth knowing before you use the numbers:
- The files come from the Internet Archive. The reading room that publishes them (esd.whs.mil) refuses scripted downloads, so the library asks the Wayback Machine for its copy of each official URL instead, and records the capture it used and the file's SHA-256 beside every row.
- Three templates are read. The SAR layout changed in 2021 and again for the modernised MSAR in December 2023; all three parse, including scans whose OCR text layer garbles the headers.
- Every row is checked against its own arithmetic. Unit cost times quantity has to come back to cost, and the printed percentage change has to match the unit costs. Across every cycle, 979 of 1,006 reports read and 11,856 of 11,919 checks held (99.5%). The failures looked at were errors in the SARs themselves (an OCR layer that dropped a decimal point, a printed percentage that contradicts its own unit costs), and they stay in the table, marked, rather than being quietly fixed. The 27 reports that didn't read are archive copies that are truncated in every capture, and reports with no unit cost table.
- Then-year tables are marked. A report on a program in breach repeats
its unit cost tables in then-year dollars; those rows have
dollars == "TY"and no base year, and growth analysis skips them. - "Original" can be reset. After a critical Nunn-McCurdy breach the original baseline can be revised, which takes the breach out of the growth figure. Seventeen programs show it moving between reports, so growth against the SAR's original baseline is a floor for the programs that grew most.
- Base years differ between blocks. A SAR can state its current baseline in one base year and its original baseline in another (SDB II, December 2022: BY2015 and BY2010), so compare growth percentages across programs, not dollars, unless you convert them.
In Python:
from cost_core.public import build_sar_panel
panel = build_sar_panel(programs=["DDG 51"], progress=print)
panel.unit_cost[["cycle", "measure", "comparison", "unit_cost_growth_pct"]]

# or, offline, from PDFs already on disk
from cost_core.public import local_catalog
panel = build_sar_panel(catalog=local_catalog("path/to/sars"))
Comparing alternatives: life-cycle cost for an AoA
An analysis of alternatives asks which way of meeting a need is worth its cost
over the whole life of the thing. Write the alternatives down as a JSON file
(ce-core template aoa writes a complete one, with invented numbers) and run:
ce-core aoa --spec my_aoa.json --out aoa/
     alternative        by        ty       pv      p50       p80  p_cheapest  effectiveness  cost_per_effectiveness     dominated_by
Upgrade in place  6,260.00  7,597.89 5,262.48 5,737.37  6,181.63        0.95           0.62                9,335.40
 New development 10,770.00 14,304.08 8,486.81 9,470.01 10,268.04        0.00           0.90               10,611.67
  Buy commercial  7,730.00  9,648.51 6,381.08 6,680.31  7,041.37        0.05           0.55               12,224.04 Upgrade in place
Each alternative is a set of cost lines (development, procurement, operating and support, disposal), each phased by fiscal year in base-year dollars and carrying an uncertainty factor. Three things the module is careful about:
- Three kinds of money. Base-year dollars for building the estimate,
then-year dollars for the budget, and present value for the comparison.
Alternatives that spend at different times are compared on present value,
as OMB Circular A-94 requires, discounting constant dollars at a real
rate. There's no default rate: pass the current one from A-94 Appendix C
and it's recorded in
assumptions.json. Discounting then-year dollars at a real rate would count inflation twice, so the module never does. - Uncertainty decides rankings. Each alternative's lines are correlated
and simulated, so the answer is a distribution.
p_cheapestis the share of draws in which that alternative costs least, which says how firm a ranking is; two alternatives a few percent apart on point estimates are often a coin toss. - Cost is half the question. With effectiveness scores, the table gives cost per unit of effectiveness and names any alternative that another beats on both counts. In the example, buying commercial costs more than upgrading in place and does less, so it's off the frontier.
The spread on a line can come from history instead of judgement:
historical_growth takes the SAR panel above and returns each program's
latest unit cost growth against its original baseline, one observation per
program, and growth_factor turns it into a distribution a cost line can
carry.
from cost_core.aoa import CostLine, growth_factor, historical_growth, spread
history = historical_growth(panel.unit_cost, measure="APUC", max_quantity_change_pct=10)
line = CostLine("Production", "Procurement", spread(4200, 2032, 8), growth_factor(history))
Cost and schedule together: JCL
A cost S-curve says what money buys 70% confidence and nothing about when. For a project that carries a team for its whole life the two are one question, since every month of slip is a month of salaries. NASA budgets its major projects at the 70% joint cost and schedule confidence level (JCL): the probability of finishing at or under the cost and by the date.
ce-core demo jcl                          # the example below
ce-core jcl --spec my_jcl.json --out jcl/   # yours, from: ce-core template jcl
The spec is an activity network in months: each activity has a most-likely duration with an uncertainty factor, its predecessors (finish-to-start, start-to-start, finish-to-finish or start-to-finish, with lags or leads), a time-independent cost (materials, a fixed-price contract) and a burn rate that costs more the longer it runs. The project carries a standing army, paid every month until it's done, and discrete risks that delay activities and add cost when they happen. The example, a small spacecraft with invented numbers, shows the three things a JCL analysis is for:
- The point estimate is almost never met. The plan of 43 months and $229M has under 1% joint confidence.
- Separate P70s aren't a 70% plan. Budgeting at the cost P70 and
scheduling at the schedule P70 reaches only 66% jointly, because the two
have to hold at once. The frontier gives the budget and date pairs that
really do reach 70%, and
jcl.pngdraws them over the cloud of simulated outcomes. - The long pole isn't always the critical path. The instrument is on the deterministic critical path and critical in 95% of runs; the criticality table is where management attention should go.
Schedule uncertainty in merging paths is what a deterministic plan misses most: two uncertain paths into one milestone finish later on average than either does alone (merge bias), so the critical path method is optimistic by construction. The simulation carries it; the test suite checks it.
From a Microsoft Project schedule
The network doesn't have to be retyped. Save the integrated master schedule from Microsoft Project as XML (MSPDI, which Primavera P6 and most other tools also export), check it's fit to simulate, then point a spec at it:
ce-core schedule-check --mspdi ims.xml --out check/
ce-core jcl --spec ims_jcl.json --out jcl/
schedule-check runs the DCMA 14-point assessment on the incomplete detail
tasks: missing logic, leads, lags, relationship types, hard constraints,
high and negative float, high duration, invalid dates, resources, missed
tasks, the critical path test, CPLI and BEI. It writes each check with its
threshold and every task that failed it, since a JCL run on dangling logic
and hard constraints is confident about nothing.
The spec names the file, with an uncertainty for every task and overrides for the ones you know more about; tasks are named by their name or UID:
{"mspdi": "ims.xml", "standing_army": 1.2,
 "duration_uncertainty": {"type": "triangular", "left": 0.9, "mode": 1.0, "right": 1.3},
 "per_task": {"Thermal vacuum test": {"type": "triangular", "left": 0.9, "mode": 1.0, "right": 2.0}},
 "risks": [{"name": "Late GFE", "probability": 0.3, "activities": ["Integrate payload"], "delay": 2}]}
Links keep their type and lag. Summary-task links move onto the tasks under
them. A task in progress keeps only its remaining work, so the simulation
runs from the status date. Each task's fixed cost stays fixed, and its
resource cost becomes a burn rate. Calendars and date constraints are not
modelled, and the run's assumptions.json says so, along with everything
else simplified on the way in.
Earned value: where the program is heading
ce-core demo evm                                # the example below
ce-core evm --data my_evm.xlsx --units thousands --out evm/   # yours: ce-core template evm
ce-core template evm writes a spreadsheet laid out for it, holding the
example. Column names such as PV, EV, AC, "Planned Value" or "Month" are
recognised as well, so an export from another tool often reads as it is.
The data is the three numbers every EVM report carries, by period: BCWS, BCWP and ACWP, with the baseline running on past the status period and, optionally, the contractor's EAC and a control account column. From them come CV, SV, CPI, SPI, TCPI, the standard independent EACs, and earned schedule. SPI(t) and the IEAC(t) completion date are what to watch late in a program, since SPI drifts back to 1.0 as the last work is earned, however late.
Two things go further than the formulas:
- The EAC and the finish as a range. Every independent EAC formula
assumes some future efficiency, and they disagree by as much as the
program's performance has varied.
forecastruns the rest of the program many times on its own record: each simulated period earns schedule and spends at a pace and efficiency drawn, as a pair, from the periods so far, with runs of good and bad periods lasting as long as they did. The result is an EAC and a completion date with a P50 and a P80, their joint confidence, and where the contractor's EAC and each formula fall on it. On synthetic programs whose outcome is known, the P80 holds the true cost and finish 79 to 82% of the time (72 to 77% when performance is strongly persistent), and the test suite holds it to that. - The warning signs, stated. A contractor EAC whose TCPI is more than 0.10 above the CPI, one below every independent EAC, one that needs the CPI to recover more than 0.10 after 20% complete (Christensen's finding on DoD contracts), and an SPI that has recovered while SPI(t) has not.
In the example, three invented control accounts at 32% complete, the contractor's EAC of $16.3M sits below the P1 of the forecast, whose P50 is $17.0M.
from cost_core.evm import EvmData, forecast
data = EvmData.read("cpr.csv")            # period, bcws, bcwp, acwp[, eac][, wbs]
data.flags()
forecast(data, seed=1).summary()
Straight from the IPMDAR (preview). The Contract Performance Dataset, the JSON tables contractors deliver under DI-MGMT-81861, reads directly:
ce-core evm --ipmdar cpd_2026_11.zip --out evm/
ce-core evm --ipmdar cpd_2026_*.zip --out evm/     # cumulative-only deliveries
Table and field names follow the CPD Data Exchange Instructions (March 2020). Work packages roll up into their control accounts, the baseline to complete and the contractor's estimate to complete come from their own tables, and the control accounts are reconciled against the PMB summary, with any gap stated. A dataset whose to-date values are time-phased holds the whole history. One that reports them only cumulative to date gives a single point, so pass the monthly deliveries together and the history is rebuilt from them, with any missing month named. A folder or ZIP of one JSON file per table and a single JSON file keyed by table name both read.
This reader is a preview. It follows the published Data Exchange Instructions and is tested on datasets written to them, but not yet on a real contractor delivery, and how the tables are packaged is still to be checked against the File Format Specification. Check the reconciliation note it prints against the delivery's own totals, and if a file does not read, please say so on the issue tracker (describe the file's layout; never attach the data). Until it is confirmed, a CSV export of BCWS, BCWP and ACWP by period is the dependable route.
Choosing a portfolio: which programs get funded
Moving money between programs is a capital budgeting problem, and the spreadsheet version of it is Excel Solver with a binary cell per program. Here it's a mixed-integer program solved with HiGHS through PuLP:
pip install "cost-core[optimize]"
ce-core portfolio --spec my_portfolio.json --out portfolio/   # ce-core template portfolio
Each candidate has one or more funding options (full rate, minimum sustaining
rate, defer two years), each with a cost in every budget year and a value
score. The solver maximises value within every year's budget, funds the
mandatory programs, keeps dependencies ("integration needs the missile") and
picks at most one of each set of exclusive alternatives, which is what an AoA's
alternatives are: candidates_from_aoa turns an AoA result straight into them.
The optimum is where the analysis starts, and three more tables come with it:
- What an extra dollar is worth, by year.
marginal_valuere-solves with a little more money in one year at a time and says what it would buy. A year whose extra money buys nothing is where money can move from. - Value against budget.
frontiersolves at a range of budget levels, so the discussion can be about where value per dollar flattens. - Budget risk. An optimum on point estimates fills the budget almost
exactly, so cost growth breaks it.
budget_riskdraws correlated growth for each funded program (from SAR history viacost_core.aoa.growth_factor, or any distribution) and gives each year's chance of going over. In the example, the plan that fits on paper breaks its 2028 budget 94% of the time once costs grow the way the example's growth distribution says; planning to a growth factor (solve(..., cost_factor=1.15)) is the usual answer.
The solver is checked against brute force: on 40 random portfolios, every combination of options is enumerated and the integer program has to find the same best value.
Installation
Bringing it into a lab or a government office, behind a proxy, offline, or through a software approval review? docs/using-at-a-lab.md covers the licence question, the SBOM attached to every release, installing on a managed or air-gapped machine, and what touches the network.
Python 3.9 or higher. The distribution name is cost-core and the import name
is cost_core. It's on PyPI:
pip install "cost-core[plots]"
Leave off [plots] if you don't need the charts. To work on the code itself,
install from a clone instead:
python -m venv .venv && .venv/Scripts/activate && pip install -e ".[plots]"
That pulls in pandas, numpy, scipy and openpyxl, plus matplotlib for the
[plots] extra. Excel input and the workbooks the lot engine writes both need
openpyxl, so it's installed by default rather than as an extra. matplotlib is
the other way round: it draws the charts and nothing else, so installing without
the extra gives you the whole engine, the CERs, the risk simulation and the Excel
workbooks, and anything that draws a PNG tells you to add [plots] when you
reach it.
numpy and scipy also carry an upper bound, numpy<2.5 and scipy<1.18. That is
about reproducing numbers, not about running: above those versions the library
imports and works, but it stops reproducing the figures this release pins. Both
land the unbiased MUPE and ZMPE refits in a slightly different place, which moves
golden leaves by up to 8e-9 and 4.5e-8 relative against a 1e-9 tolerance, and
scipy 1.18 also changes the simulated draws, which the frozen-draw tests hash.
Both are seen on Windows, where the goldens were captured. Elsewhere those refit
leaves carry a measured allowance for the machine's own last bits and the hashes
are not checked, so a bound has to be measured on Windows. Raising a bound means
rebaselining the goldens and the frozen draws against the new stack and writing
down what moved, the same process every other rebaseline here went through.
CHANGELOG.md carries the measurements.
Quick start
With your own data
ce-core fit-lots --csv my_lots.csv --dollar-year 2026 --forecast "30,40" --out results/
Costs come back in the units they went in, because the fit is scale free and
this command converts nothing. Headings that read ($K) are the engine's own
column names, carried over from the desktop tool whose input column is
AUC ($K), and the S-curve formats the same numbers as dollars, so read both
as "cost" in your file's units unless that file really is in thousands.
Prints the fitted slope and first unit cost, the standard error and CV, an
interval on the slope, and a per lot percentage error showing which lots the
curve misses. With --out it also writes those tables as CSV and an
ASSUMPTIONS.md; the one chart this command draws is the buy S-curve, and that
needs --simulate. See
Fitting a curve to your own lot data.
With generated data, to see the whole pipeline
Generate synthetic submissions, ingest and normalize them, fit a learning curve and a CER, simulate with correlation, then write charts, tables and an assumptions log:
ce-core full-run --out artifacts/ --seed 7
That writes:
artifacts/
  ASSUMPTIONS.md              the written assumptions and provenance log
  charts/                     s_curve, tornado, learning_curve,
                              cer_diagnostics, summary_table  (PNG, 200 dpi)
  tables/                     every table behind those charts, as CSV
  artifacts/source_reports/   the six synthetic submissions
  artifacts/wbs_crosswalk.csv the persisted name crosswalk
  artifacts/inflation_index.csv
The same seed reproduces the run exactly.
The lot cost engine
The lot cost engine is cost_core.lotmodel, the code the desktop tool runs
on. Historical analogy
lots (fiscal year, quantity, unit cost) are the history; estimate lots
(fiscal year, quantity, complexity factor) are the buy being priced.
from cost_core.lotmodel import run_lot_cost_model, generate_analyst_summary, enrich_run

projections, ctx = run_lot_cost_model(analogy_df, estimate_df)
summary = generate_analyst_summary(ctx, {"Program": "TEST"})
extras = enrich_run(ctx, projections, summary)
Three models get fitted to the analogy lots, and every estimate lot is priced under all three, so the projections carry the models the tool didn't pick right alongside the one it did:
LC        ln(cost) = ln(T1) + b*ln(lot midpoint)
Rate      ln(cost) = ln(T1) + c*ln(lot quantity)
LC+Rate   both terms together
Selection goes to LC+Rate when its rate coefficient is significant, to Rate when the rate slope is significant and beats LC by more than the AICc tie threshold, and to LC otherwise. Where AICc disagrees with the significance gate, the summary says so instead of hiding it. Because the lot midpoint depends on the slope you're fitting, the fit iterates to a fixed point. That's the Goal Seek the original workbook did by hand.
What the statistics layer adds
The estimate itself is untouched by any of this. A golden master test fails if a
single coefficient moves. What enrich_run reports is how much confidence
those numbers can carry.
Retransformation bias. The fit is OLS on ln(cost), then exponentiated back.
That estimates the median and understates the mean by exp(s²/2). MUPE and
ZMPE refit the same regressors under a proportional error loss and drive the
mean percentage error to zero, so the bias gets measured on your data instead of
argued about.
Influence. Six analogy lots is a normal sample here, and at that size one lot can set the slope while every summary statistic still looks healthy. Leverage and Cook's distance name it. On the reference programme in the tests, analogy lot 1 carries leverage 0.77 and Cook's D 4.00.
Prediction intervals on every projected lot. For a new lot, carrying the residual scatter, with a t multiplier because sigma is estimated rather than known.
Buy risk. A distribution over the total of the estimate lots with P50/P80/P90 and where the point estimate falls on it. Residuals across lots are correlated at 0.30 by default, for the same reason WBS elements are.
enrich_run returns the four tables (Fit_Methods, Influence,
Prediction_Intervals, Buy_Risk) as frames. The desktop tool writes the risk
ones into its workbook after the original three sheets, so an analyst who wants
only the original three still gets exactly those.
Fitting a curve to your own lot data
The simplest way in. Two columns, one row per lot:
lot,units,cost
LRIP 1,22,96800000
LRIP 2,18,70200000
FRP 1,25,90000000
FRP 2,30,100500000
ce-core fit-lots --csv my_lots.csv --dollar-year 2026 --forecast "30,40" --out results/
The lot column is optional. Common header spellings (Qty, Quantity,
Total Cost, Amount, and so on) are recognized automatically, and anything
unusual you name with --units-col / --cost-col. Currency formatting like
$1,200,000 parses fine. .xlsx works out of the box.
Everything else is derived. Lot 1 is units 1 to 22, lot 2 is units 23 to 40, and
so on by running total. That's what turns a flat list of lots into positions on a
curve. You get the fitted slope and first unit cost, standard error and CV, an
interval on the slope, a per lot percentage error showing which lots the curve
misses, prediction intervals on forecast lots, and an ASSUMPTIONS.md.
Re-using the curve on another program
The fit is also an estimating relationship you can lift and apply somewhere else.
The equation gets printed and written to equation.csv. The four lots above
select LC+Rate, so theirs carries both terms:
Unit Cost = 7,424,501.70 * midpoint^(-0.108355) * qty^(-0.093348)
Where only the learning term survives the significance gate the qty factor is
absent. Drop FRP 2 from that sample and the remaining three lots select LC,
printing Unit Cost = 5,586,219.86 * midpoint^(-0.108548). The priced lots carry
whichever terms the equation does. There's a test for exactly that, because for a
while they didn't.
--price-lots applies the selected model to any buy profile from unit 1,
producing the learning curve table an analyst would build by hand:
ce-core fit-lots --csv my_lots.csv --dollar-year 2026 --price-lots "10,15,20,25,30" --out results/
The lot_midpoint column is the algebraic midpoint, meaning the unit whose
cost equals the lot average. Most tools approximate it, because they only have an
approximate lot average to work from. Here the lot average is exact, so the
midpoint gets solved for directly. There's a test asserting the cost at the
midpoint equals the lot average, which is its definition.
This is the analogy use case: price a program with no cost history of its own using the slope from one that does. Whether that's valid is a judgement, not a result. The slope carries across only if the two programs are comparable in product, process, rate and contractor. Nothing in the data can confirm that, so the assumptions log records it as an untested assumption and notes that the extra error it introduces isn't in any interval reported.
Forecasting the next buy, with risk
--forecast prices future lots continuing from the last unit built, with
prediction intervals. --simulate then Monte Carlos them:
ce-core fit-lots --csv my_lots.csv --dollar-year 2026 --forecast "30,40" --simulate 50000 --out results/
Unlike the WBS level simulator, this needs no elicited distributions. The uncertainty is measured from the program's own history. Two sources get propagated: parameter uncertainty in the fitted slope and T1, which dominates on a short series, and lot to lot scatter, which is what makes the answer a prediction about a real lot. Residuals across future lots are correlated at 0.30 by default for the same reason WBS elements are. Consecutive lots share a workforce and a schedule, and treating them as independent understates the spread of the whole buy.
It does not include schedule risk, requirement changes, or rate changes the history never saw. That's a narrower claim than a full risk model, and the log says so.
How it fits
Three candidate models against the lot midpoint, one selected:
LC        ln(unit cost) = ln(T1) + b*ln(lot midpoint)
Rate      ln(unit cost) = ln(T1) + c*ln(lot quantity)
LC+Rate   both terms together
This engine came across from the desktop tool in lot-cost-model, which since its 3.0.0 imports it rather than keeping a copy, so the two are the same code by import rather than by descent. All three models get fitted and all three price every lot, so the alternatives stay on the record. Because the midpoint depends on the slope you're fitting, the fit iterates to a fixed point.
Four things that quietly ruin a lot fit
The tool checks all four, because each one leaves a fit that looks perfectly healthy while the slope is several points wrong.
Nonrecurring cost in the totals. Nonrecurring is front loaded, so including it
makes early lots look expensive and the curve reads steeper than the production
process really is. That overstates future savings. --cost-basis has to be
declared, and total warns.
Escalation left in "constant" dollars. --dollar-year is required. No
index gets applied, but constant dollars are constant relative to a year, and an
output nobody can place in a year can't be escalated or compared. The tool checks
whether cumulative average cost ever rises, which can't happen on a learning
curve, and it also tests the log log residuals for a bend.
Be careful about what that second check can actually do. Fitted against the lot midpoint it's a poor escalation detector: the fitted slope moves with the escalation, the midpoint moves with the slope, and the trend gets absorbed instead of being left in the residuals. It catches a rate break, a design change or a production gap, not moderate escalation. The level check needs roughly 10% a year before it bites. Below that, moderate escalation and genuinely slower learning can't be told apart without a fiscal year attached to each lot, and the log says exactly that. There's a parametrized test at 2%, 4% and 6% asserting the miss, so the limit is documented rather than discovered later.
Lots that don't start at unit 1. If the program has a prior buy the curve has
already learned through, --first-unit shifts the series. Otherwise the fitted
first unit cost describes a unit nobody built.
Too few lots. Degrees of freedom are lots minus 2. Two lots interpolate exactly and are refused. Three gives one degree of freedom and an interval too wide to support a decision. Five is the practical floor. The tool fits below that but says so loudly.
Usage guide
Full run
ce-core full-run --out artifacts/ --seed 7 --iters 50000 --theory crawford --method mupe --correlation 0.30
--clean generates data with no reporting pathologies, which is how the tests
show that the pipeline recovers the generating truth exactly.
Fit a learning curve
Takes a CSV with program, lot, unit_quantity and unit_cost columns.
ce-core fit-curve --csv your_history.csv --out model_params.json
Forecast future lots
ce-core forecast --model model_params.json --quantities "32,64,128" --out forecast.csv
Run a Monte Carlo simulation
In PowerShell, wrap the JSON arguments in single quotes.
ce-core simulate --n-iter 10000 --unit-cost-dist '{"type": "lognormal", "mean": 5.0, "sigma": 0.2}' --quantity-dist '{"type": "triangular", "left": 40, "mode": 50, "right": 75}' --out sim_results.csv
As a library
from cost_core.synth import generate_program
from cost_core.ingest import normalize_program
from cost_core.learning_curve import Theory, fit_from_progress_report

program = generate_program(seed=7)
data = normalize_program(program)                    # raises if a gate fails
curve = fit_from_progress_report(
    data.learning_curve_input(), theory=Theory.CRAWFORD, method="mupe"
)
curve.forecast_lots([[109, 132]], level=0.80, kind="prediction")
Methodological choices
Why MUPE and ZMPE, not just OLS
The standard cost fit is ordinary least squares in log space, followed by
exponentiating back to dollars. That retransformation is biased. If the log space
errors are normal with variance s², then
E[y | x] = f(x) · exp(s² / 2)
so the retransformed value estimates the median and understates the mean
by a factor of exp(s²/2). On a 30% CV relationship that's roughly a 4 to 5%
understatement baked into the estimate before any risk analysis even starts, and
it runs in the direction that makes a program look cheaper.
Two unbiased alternatives are provided, and both drive the mean percentage error to exactly zero:
MUPE (minimum unbiased percentage error) minimizes Σ (y - f)² / f_prev² by
iteratively reweighted least squares. At its fixed point, the normal equation for
a multiplicative scale parameter collapses to Σ (y - f)/f = 0.
ZMPE (zero percentage bias minimum percentage error) minimizes
Σ ((y - f)/f)² subject to Σ (y - f)/f = 0. Same zero bias property, but
imposed as a constraint rather than emerging from the algebra, and it gives a
different slope.
retransformation_bias() measures the bias three ways: the theoretical
exp(s²/2), Duan's nonparametric smearing estimate, and the observed shift
against MUPE and ZMPE. So the correction gets quantified instead of asserted.
Prediction intervals, not confidence intervals
These aren't interchangeable, and the confusion always runs the same direction.
A confidence interval covers the mean response at a point, meaning where the fitted line is. It shrinks toward zero as the sample grows.
A prediction interval covers a single new observation, meaning where the next actual program will land. It carries the residual scatter as well as the parameter uncertainty.
The variance relationship is exact:
Var_prediction = Var_confidence + σ²
That extra σ² is the spread of programs about the line, and no amount of
additional data removes it. A cost estimate forecasts one new program, so the
prediction interval is the correct one. CER.predict() takes kind explicitly
and defaults to "prediction".
Why correlation matters
Sampling WBS elements independently is the spreadsheet default and close to the worst assumption available. Elements on one program share a workforce, a management chain, a supply base and a schedule. When one runs late they mostly all run late. The variance of a sum is
Var(Σ Xᵢ) = Σ Var(Xᵢ) + 2 · Σ_{i<j} ρᵢⱼ · sdᵢ · sdⱼ
so for k equally variable elements at a common ρ, ignoring correlation
understates the variance of the total by exactly 1 + ρ(k-1). Ten elements at
ρ = 0.3 is a factor of 3.7 in variance, close to a doubling of the standard
deviation, and it lands on the upper tail, which is where the P80 lives.
Because independence is so rarely right, RiskModel applies a non zero default
correlation when none is supplied, and warns that it did so. A default is an
assumption, and an unstated assumption is the failure this documentation exists
to prevent. correlation_impact() reports the measured and the closed form
inflation side by side, so the claim doesn't rest on the simulation alone.
Standard error and CV, not R²
R² measures how tightly points hug the fitted line, which a wrong model can do
perfectly well. In tests/test_learning_curve.py, data generated under Crawford
unit theory and fitted as a Wright curve returns R² of about 0.996 with a
demonstrably wrong forecast. Standard error is in dollars and CV is a proportion.
Both are arguable. R² is reported, but last.
Projections have to satisfy the equation
The original desktop tool priced its Rate lots on the lot midpoint, which isn't
the variable that model regresses on, and priced LC+Rate without the rate factor
at all. So it printed an equation and then printed lot costs that didn't satisfy
it. On example_lots.csv that overstates a back cast of the fitted lots by 36%
against a known total, while the residual columns from the same run showed the
model tracking those lots to about 1%. One run, two formulas.
Dropping the term isn't a modeling choice you could defend. It evaluates the fit at a lot quantity of one unit while keeping the learning position of the real lot, and because the rate exponent is negative it only ever biases upward.
The corrected behavior is the default. LegacyRateOmission reproduces the old
numbers for anyone who has to match a legacy workbook, and the command line has
--legacy-rate-omission for it, which prints a warning when you use it. Passing
the old setting name raises instead of being ignored, because a caller who asked
for legacy behavior and quietly got something else is worse off than one who
gets an error.
The guard is a test that retypes the printed equation and evaluates it against the printed projections, for all three models. That test is why this is a paragraph about a fix rather than a known issue.
Wright and Crawford are different theories
Wright's cumulative average form says the average cost of the first x units
follows T1·x^b. Crawford's unit form says the cost of unit x does. Which one
applies is a property of the production process, not a modeling preference.
fit_curve() makes the caller choose and compare_theories() reports both,
because the same data under the two gives materially different forecasts.
Mapping to the GAO Cost Estimating and Assessment Guide
Every run emits an ASSUMPTIONS.md organized around the four characteristics of
a reliable estimate.
| Characteristic | How this library addresses it |
|---|---|
| Comprehensive | All six report shapes ingested. Recurring and nonrecurring cost, five functional categories and discrete risks all modeled. The WBS crosswalk surfaces unmatched elements rather than dropping them |
| Well-documented | Row level provenance from every output number back to its source submission. The crosswalk and inflation index are persisted artifacts, not inline logic. The assumptions log separates what was measured from what was assumed, and counts the assumptions |
| Accurate | Validation gates reconcile row counts and dollar totals within and across reports, and fail the run when they disagree. Retransformation bias is measured and corrected. Estimating methods are compared rather than assumed |
| Credible | Prediction intervals on every forecast. Leverage and influence diagnostics on the CER. Extrapolation flagged, including hidden extrapolation. The correlation assumption's effect quantified against independence. P80 convergence checked |
Project structure
cost_core/
  fitting.py          shared OLS / MUPE / ZMPE estimator and intervals
  lots.py             your own lot data: units and cost per lot
  cli.py              the ce-core command line interface
  lotmodel/           the lot cost engine: LC / Rate / LC+Rate on lot midpoints, summary, enrichment
  program/            WBS roll-up of several elements into one programme
  learning_curve.py   Wright and Crawford theories, rate breaks
  monte_carlo.py      correlated risk simulation
  data_io.py          CSV and SQLite loading
  synth/              synthetic CSDR/SRDR generator
  ingest/             crosswalk, inflation, normalization pipeline
  cer/                parametric CERs and diagnostics
  reporting/          charts, assumptions log, the Excel workbooks, end to end run
  public/             public SARs: fetch with provenance, catalogue, unit cost parser, panel
  aoa/                life-cycle cost of alternatives, spec files, growth from SAR history
  portfolio/          which programs to fund: integer program, marginal value, budget risk
  schedule/           activity networks, schedule risk and joint cost and schedule confidence
tests/                property tests, see below
Tests
pip install -e ".[plots]" pytest
pytest tests/ -q
requirements.txt also exists, but it holds the exact versions this repo
develops against, and four of the five will not install on 3.9, three of them
not on 3.10. It is the pinned development set, not the way to set up a checkout
on an older interpreter. Install the package and let the version range in
pyproject.toml resolve.
759 tests, run on Python 3.9, 3.10, 3.11, 3.12, 3.13 and 3.14 on every push, which is the whole supported range; four of them, the frozen-draw hashes, run on Windows only. They assert mathematics against closed form answers rather than against recorded output, with one deliberate exception: tests/goldens pins what the lot engine produced on 6 September 2026, so a refactor that moves a number has to say so. The strongest ones:
Our OLS is the textbook OLS. The generic estimator reproduces
scipy.stats.linregress and the normal equations to machine precision, and the
delta method prediction interval reduces algebraically to
s·√(1 + 1/n + (x₀-x̄)²/Sxx).
MUPE and ZMPE drive the mean percentage error to exactly zero. That's what their names mean, and it's asserted to 1e-9. ZMPE's sum of squared percentage errors is also proven to be no larger than MUPE's, which is a theorem, not a tuning outcome.
Cook's distance is checked against an actual leave one out refit. The closed form is exact, so the test drops each program, refits, and confirms the formula reproduces the movement in the fitted surface.
Variance inflation is exactly 1 + ρ(k-1). Asserted across element counts
and correlations, and confirmed against simulation.
Tornado variance shares sum to exactly one, because the covariance
decomposition Var(T) = Σ Cov(Xᵢ, T) is an identity when T is the sum.
A messy program normalizes back to the generating truth to the cent. Name drift, mixed then year and base year dollars, resubmitted periods and a mid program quantity change are all reversible by construction, so the pipeline that reverses them has no excuse for landing anywhere else.
Learning curve identities are definitional. Doubling quantity multiplies the right quantity by the slope under each theory. Wright's unit costs telescope back to its cumulative total. Crawford's lot cost is the exact sum of its units.
Simulations are seed deterministic. A P80 that moves between runs isn't a number you can put in front of anyone.
Limits get tested, not just capabilities. There's a parametrized test asserting that both escalation checks stay silent at 2%, 4% and 6% a year under a midpoint fit, while the fitted slope drifts several points off the truth. A second test confirms the level check does catch 15%. Documenting where a diagnostic stops working matters more than showing where it works.
The projections satisfy the equation the tool prints. Retyped by hand for all three models and evaluated against the projected costs, to the cent the column is rounded to. Flipping the legacy switch back on fails five of these, which is how I know they'd have caught the original defect.
Bad input is refused, not absorbed. Zero degrees of freedom, a missing base year, two lots, fractional units, unmatched WBS names, non positive costs in a log fit, a correlation matrix that isn't symmetric, a rate break beyond the data, an unknown interval kind, an index asked for a year it doesn't cover. Each one raises instead of producing a plausible looking number.
License
Versions 1.0.0 and 1.0.1 were released under the Apache License 2.0 and stay that way. Everything after them is under the PolyForm Noncommercial License 1.0.0. In plain terms:
- Free for any noncommercial purpose: personal study, research, teaching, hobby projects.
- Free for schools and universities, public research organizations, government institutions, charities, and public safety, health and environmental organizations, whatever their funding. A government cost office or a university research lab can use it as it stands.
- Commercial use needs a license from the author. That includes using it in paid work for clients or building it into a product. Ask through the issue tracker.
Anyone who passes on a copy of any part of it has to pass on the license terms
and the Required Notice: line in NOTICE with it. This is a plain
summary; the LICENSE file is what governs.
1 maintainer

Release files for cost-core 2.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| cost_core-2.3.0.tar.gz | 1.7 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cost_core-2.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 2.1 MB
Release files / cost_core-2.3.0.tar.gz
| Download URL | cost_core-2.3.0.tar.gz |
|---|---|
| Size | 1.7 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
358e8adf1e3b5f5ff4bfee3a10061fa4b75ca96e64404482e67aa55ee9274cc4
|
|
BLAKE2b-256 checksum How to use checksums |
cdc5f6520fed8a99a55e343493662bfe85cdbb5e5d8bebff1e22037dd410c1e4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency logRelease files / cost_core-2.3.0-py3-none-any.whl
| Download URL | cost_core-2.3.0-py3-none-any.whl |
|---|---|
| Size | 337.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
80c7efe856f08dd3186357f3824da174f23768592bb4622d7db86813071fd654
|
|
BLAKE2b-256 checksum How to use checksums |
1806960227db3551d2439353ddc055e48f5fdab34759262d05c4ef3bcc1f2d88
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 25, 2026.
Transparency log













