



/ kraahn-stuh-bl /
A cron replacement with retries, alerts, saved run history, workflows, and web and terminal dashboards. Run it on one machine or across a cluster.
Why cronstable?
cronstable runs your commands from a schedule file, following cron's model. It adds retries, alerting, durable state, orchestration, clustering, and a live dashboard.
It's built for machines of all sizes, with efficiency in mind. The benchmarks compare speed and memory use against the latest release on every commit and catch regressions before release.
Scheduling
- YAML and classic crontab files: define jobs in YAML or load an existing crontab (see classic crontab files)
- Business-day schedules: run on the last weekday of the month, the weekday nearest a date, or the nth occurrence of a weekday (see business-day schedules)
- Schedule linting: flag impossible schedules, uneven intervals, and daylight-saving surprises (see schedule introspection)
- Arbitrary time zone support
- iCal calendar export: subscribe to upcoming runs in your calendar app or view them in the dashboard's week calendar (see calendar export)
Failure handling
- Result verification: check a job's output before recording success or starting downstream tasks (see result verification)
- Configurable failure conditions
- Automatic retries with exponential backoff
- Failure notifications through Sentry, email, and Slack-compatible webhooks
- End-to-end encrypted push notifications: send alerts that only paired devices can decrypt (see push notifications)
- Per-job SLA monitoring: detect missing or late runs and excessive runtimes, with alerts and dashboard status (see late-run detection)
Durability and orchestration
- Shared resource pools: limit capacity across jobs and DAG tasks, with priority queues and deadlines (see resource pools)
- Selective workflow recovery: retry failed tasks or replay failed dates while reusing successful results (see workflow recovery)
- Opt-in durable state: preserve history and retries across restarts, catch up missed runs, and share state between jobs (see durable state)
- Orchestration DAGs: build durable workflows with task dependencies, data sharing, dynamic fan-out, sensors, and approval gates (see orchestration and DAGs)
Observability and control
- Web and terminal dashboards: follow live logs, review history, control jobs and workflows, and monitor the cluster
- Optional HTTP REST API for job status, history, and control
- Runtime pause/resume: pause scheduled runs for maintenance without editing configuration (see pausing jobs)
- Built-in TLS: serve the API over HTTPS, optionally require client certificates, and reload web certificates without restarting (see serving the API over TLS)
- MCP server: let AI agents inspect jobs and debug schedules. Read-only by default, with optional control
- Prometheus and statsd metrics: track outcomes, durations, retries, and cluster health (see metrics)
- Per-job resource monitoring: track CPU time and peak memory across each job's process tree (see resource monitoring)
Fleets
- Job-set ID: compare configuration fingerprints to detect drift between replicas (see job-set ID)
- Opt-in clustering and leader election: coordinate job execution across replicas (see clustering and leader election for backend options and guarantees)
Deployment
- Built for restricted containers: run as a non-root user with a read-only root filesystem and restricted Kubernetes security settings (see production container deployment)
- Prebuilt releases: multi-architecture container images and self-contained binaries for Linux, macOS, BSD, illumos, and Windows (see installation)
Web UI tour.
Quick start
To run your first scheduled job with a live dashboard, install cronstable. For Docker, Homebrew, and standalone binaries, see installation.
pip install cronstable
Create a cronstable.yaml file with your first job:
jobs:
  - name: hello
    command: echo "hello from cronstable on $(hostname)"
    schedule: "* * * * *"        # every minute
    captureStdout: true

web:
  listen:
    - http://127.0.0.1:8080      # optional: the REST API + dashboard
Start the scheduler. It runs in the foreground:
cronstable -c cronstable.yaml
Open http://127.0.0.1:8080/ to view the job's live output in the
dashboard. The hello job runs once a minute.
You can extend this configuration to:
- Get failure alerts: retries with backoff and a Slack/mail/Sentry report when a job ultimately fails (tutorial).
- Survive restarts: a
state:block preserves history and retries and enables missed-run catch-up (tutorial). - Chain jobs into a pipeline: a durable DAG with data sharing and an approval gate (tutorial).
- Coordinate replicas: use leader election to coordinate job execution (tutorial).
- See it all at once:
docker compose -f example/grand-tour/docker-compose.yml up --buildboots a nine-node cluster running every feature together (example gallery).
To use an existing crontab exported with crontab -l, run
cronstable -c my.crontab. For a system crontab such as /etc/crontab,
remove the extra user column first. See
classic crontab files for format differences.
Installation
Run with Docker
Prebuilt multi-architecture images (seven Linux platforms) are published on
every release to two registries, the GitHub Container Registry
(ghcr.io/ptweezy/cronstable) and Docker Hub (ptweezy/cronstable). Mount
your configuration file and start the container:
docker run --rm \
  -v "$PWD/cronstable.yaml:/etc/cronstable.d/cronstable.yaml:ro" \
  ghcr.io/ptweezy/cronstable:latest
The image runs as a non-root user and reads its configuration from
/etc/cronstable.d by default. The default image is built on Debian (slim).
Alpine, Ubuntu, RHEL/UBI, Fedora, openSUSE, Amazon Linux, and distroless
variants are published from the same release under a -<distro> tag suffix.
The platform list, the variant table, and each variant's architecture coverage
are in
installation in the
wiki. For production, pin a specific version instead of latest, and see
production container deployment for the
hardened Kubernetes/Docker setup.
Install using pip
cronstable requires Python >= 3.10 (for systems with an older Python, use the binary instead). Install it in a virtual environment:
pip install cronstable
or let pipx create an isolated one for you:
pipx install cronstable
Install using Homebrew or winget
Both package managers install the self-contained release binary for your platform, so no Python is required.
macOS or Linux:
brew install ptweezy/tap/cronstable
Windows:
winget install ptweezy.cronstable
Upgrade later with brew upgrade cronstable or
winget upgrade ptweezy.cronstable.
The WinGet release workflow submits signed, per-machine MSIs. When you install
an MSI, approve the administrator prompt and open a new shell to use cronstable
from PATH. The installer registers the Windows service, which stays stopped
until you configure and start it. See the
WinGet installation guide
for package availability and instructions to switch from a portable install.
Install using binary
Alternatively, download a self-contained binary from GitHub:
https://github.com/ptweezy/cronstable/releases. Every release attaches
binaries for Linux (glibc and musl builds for amd64, amd64v3, arm64, i686,
armv7, armv6, ppc64le, s390x, riscv64 and loong64, plus a glibc-only
mips64le and armel), macOS (amd64, amd64v3 and arm64, signed and notarized by
Apple), FreeBSD (amd64, amd64v3 and arm64), OpenBSD, NetBSD, illumos
(amd64 and amd64v3) and
Windows (amd64, amd64v3, arm64 and i686), plus .deb, .rpm, Alpine .apk and
FreeBSD .pkg packages. The amd64, amd64v3, arm64, and s390x glibc builds need
only glibc 2.17, so they run on everything from RHEL 7 onward; ppc64le
needs 2.28 (RHEL 8 onward). Python is not required on the target
system; it is embedded in the executable.
For x64 downloads, choose:
amd64v3— Recommended for compatible CPUs. Uses an optimized embedded Python runtime and requires the full x86-64-v3 feature set.amd64— Compatibility build. Choose this when the CPU or VM does not support v3, or when you are unsure.
Every amd64 binary and package format has a v3 counterpart. All eight Docker
distros offer explicit -amd64v3 tags, recommended for compatible hosts
(for example, latest-amd64v3 and latest-alpine-amd64v3). Existing amd64
asset URLs and Docker tags retain their current requirements; Homebrew, Scoop
and winget keep their baseline downloads. See CPU requirements and variant selection.
# Recommended for an x86-64-v3-capable Linux CPU (glibc).
# Use amd64 instead of amd64v3 for compatibility; append -musl on Alpine.
curl -fsSL -o cronstable \
  https://github.com/ptweezy/cronstable/releases/latest/download/cronstable-linux-amd64v3
chmod +x cronstable
./cronstable --version
The binary unpacks an embedded Python runtime at startup, so under a
read-only root filesystem it needs a small writable and executable temp mount.
The container image and pip/pipx installs never self-extract. The full
asset table, the glibc/musl compatibility notes, and the tmpfs/emptyDir
recipe are in
installation in the
wiki.
Windows releases additionally attach cronstable-windows-<arch>.zip, a
one-directory build that extracts to a single cronstable folder and can
host the Windows
service, and
cronstable-windows-<arch>.msi, a machine-wide installer that registers
the service for GPO/Intune/SCCM deployment (see the Windows
MSI wiki page).
Running on Windows
cronstable runs natively on Windows (x64, ARM64 and 32-bit x86). Install it
with pip install cronstable, or take one of the builds on the
releases page, none of which
need Python: the self-contained cronstable-windows-amd64v3.exe
(recommended for compatible x64 CPUs), cronstable-windows-amd64.exe
(compatibility build), or
cronstable-windows-arm64.exe / cronstable-windows-i686.exe, the
one-directory
cronstable-windows-<arch>.zip (the shape that can host the Windows service),
or the machine-wide cronstable-windows-<arch>.msi. Everything else, like the
YAML crontab, scheduling, reporting, retries, the HTTP API and the
web dashboard, works the same as on POSIX. A few platform
details differ:
-
Default config location. Without
-c, cronstable looks in the machine-wide%ProgramData%\cronstable(the Windows analog of/etc/cronstable.d) whenever that directory holds configuration, and in the per-user%APPDATA%\cronstableotherwise (for example,C:\Users\you\AppData\Roaming\cronstable).cronstable initwrites a commented starter configuration into whichever one applies, and-coverrides the choice with any path:cronstable -c C:\path\to\cronstable.yaml
-
Default shell. A string
commandwith no explicitshellruns through the native command processor (%ComSpec%, that is,cmd.exe), which fills the same role/bin/shfills on POSIX.shell: cmdandshell: powershellboth work as written: cronstable gives cmd.exe the/cinvocation and quoting it expects, and every other shell-c. For PowerShell, or any other interpreter, setshell:or passcommandas a list, which bypasses the shell entirely:jobs: - name: powershell-job command: - powershell - -Command - Get-Date schedule: "*/5 * * * *" captureStdout: true
-
Graceful shutdown. Press
Ctrl-Cto stop cronstable. It shuts down once the running jobs finish, the same asSIGTERMon POSIX. Each job runs in its own console process group, so the keystroke never reaches the jobs themselves. Closing the console window and shutting the machine down drain the same way, within the few seconds of grace the OS allows.The authenticated
POST /shutdownroute stops a console-less daemon, and stops the Windows service cleanly, without tripping its recovery actions. Logging off does not stop it: an unattended daemon sees that event for every user on the machine. -
Running unattended, as a real Windows service.
cronstable service install -c C:\ProgramData\cronstableregisters the scheduler with the Service Control Manager, so it starts at boot, runs whether or not anyone is logged on, appears inservices.msc, and gets Windows' own recovery actions. Stopping it drains the running jobs first, and it keeps telling the SCM the stop is still in progress for as long as that takes.cronstable service reloadmakes it reparse the configuration immediately, the forced reload thatSIGHUPtriggers on POSIX. The whole thing is a ctypes shim over advapi32, so it adds no dependency.The published one-file
.execannot host a service, because its bootloader runs the program in a child process the SCM never sees. Theinstallcommand says so. Install with pip or pipx for that, or use theschtasksrecipe. See Windows Service and Running on Windows. -
Migrating from Task Scheduler.
cronstable import-taskscheduler tasks.xml -o jobs.yamlconverts an estate's exports into cronstable jobs. It maps time, calendar and boot triggers,Execactions, working directories, execution time limits, instance policy and priority. It is a one-shot converter rather than a loader, because exporting a task does not unregister it. It lists everything it cannot carry across, with the reason, instead of dropping it, and on a whole-machine export that list is long: most registered tasks on a stock Windows install are COM-handler or event-driven internals rather than schedules. See Importing from Task Scheduler. -
Not supported on Windows. Per-job
user/groupswitching has nosetuid/setgidequivalent, so cronstable rejects it with a configuration error, and it skipsunix://web listeners with a warning. Use anhttp://listener instead.
Production container deployment
cronstable is built to run unmodified under the hardened security contexts that
corporate and enterprise Kubernetes / container platforms enforce. At runtime
the daemon only reads its configuration and secrets and writes its output to
stdout/stderr. It never needs a writable working directory, temp files, or log
files, so it can run as an unprivileged non-root user with the RuntimeDefault
seccomp profile, a read-only root filesystem, all Linux capabilities dropped,
and config/secret volumes mounted with an fsGroup.
Only the optional per-job user/group switching
requires root. Two exceptions need a small writable mount: a unix:// web
listener's socket, and the standalone binary's temp directory (see
install using binary).
The published image (ghcr.io/ptweezy/cronstable and docker.io/ptweezy/cronstable)
is already built this way (non-root, with cronstable -c /etc/cronstable.d as its
entrypoint and no writable paths required), so for most deployments you can use
it directly and mount your crontab read-only.
Production deployment
in the wiki has the full setup: a Kubernetes Deployment with a fully
restricted security context, baking configuration into your own image, the
writable-path exceptions in detail, and health checks.
Web dashboard
The built-in web dashboard is a self-contained page served by the daemon, with no build step or external assets. Enable the HTTP interface, then open its address in a browser.
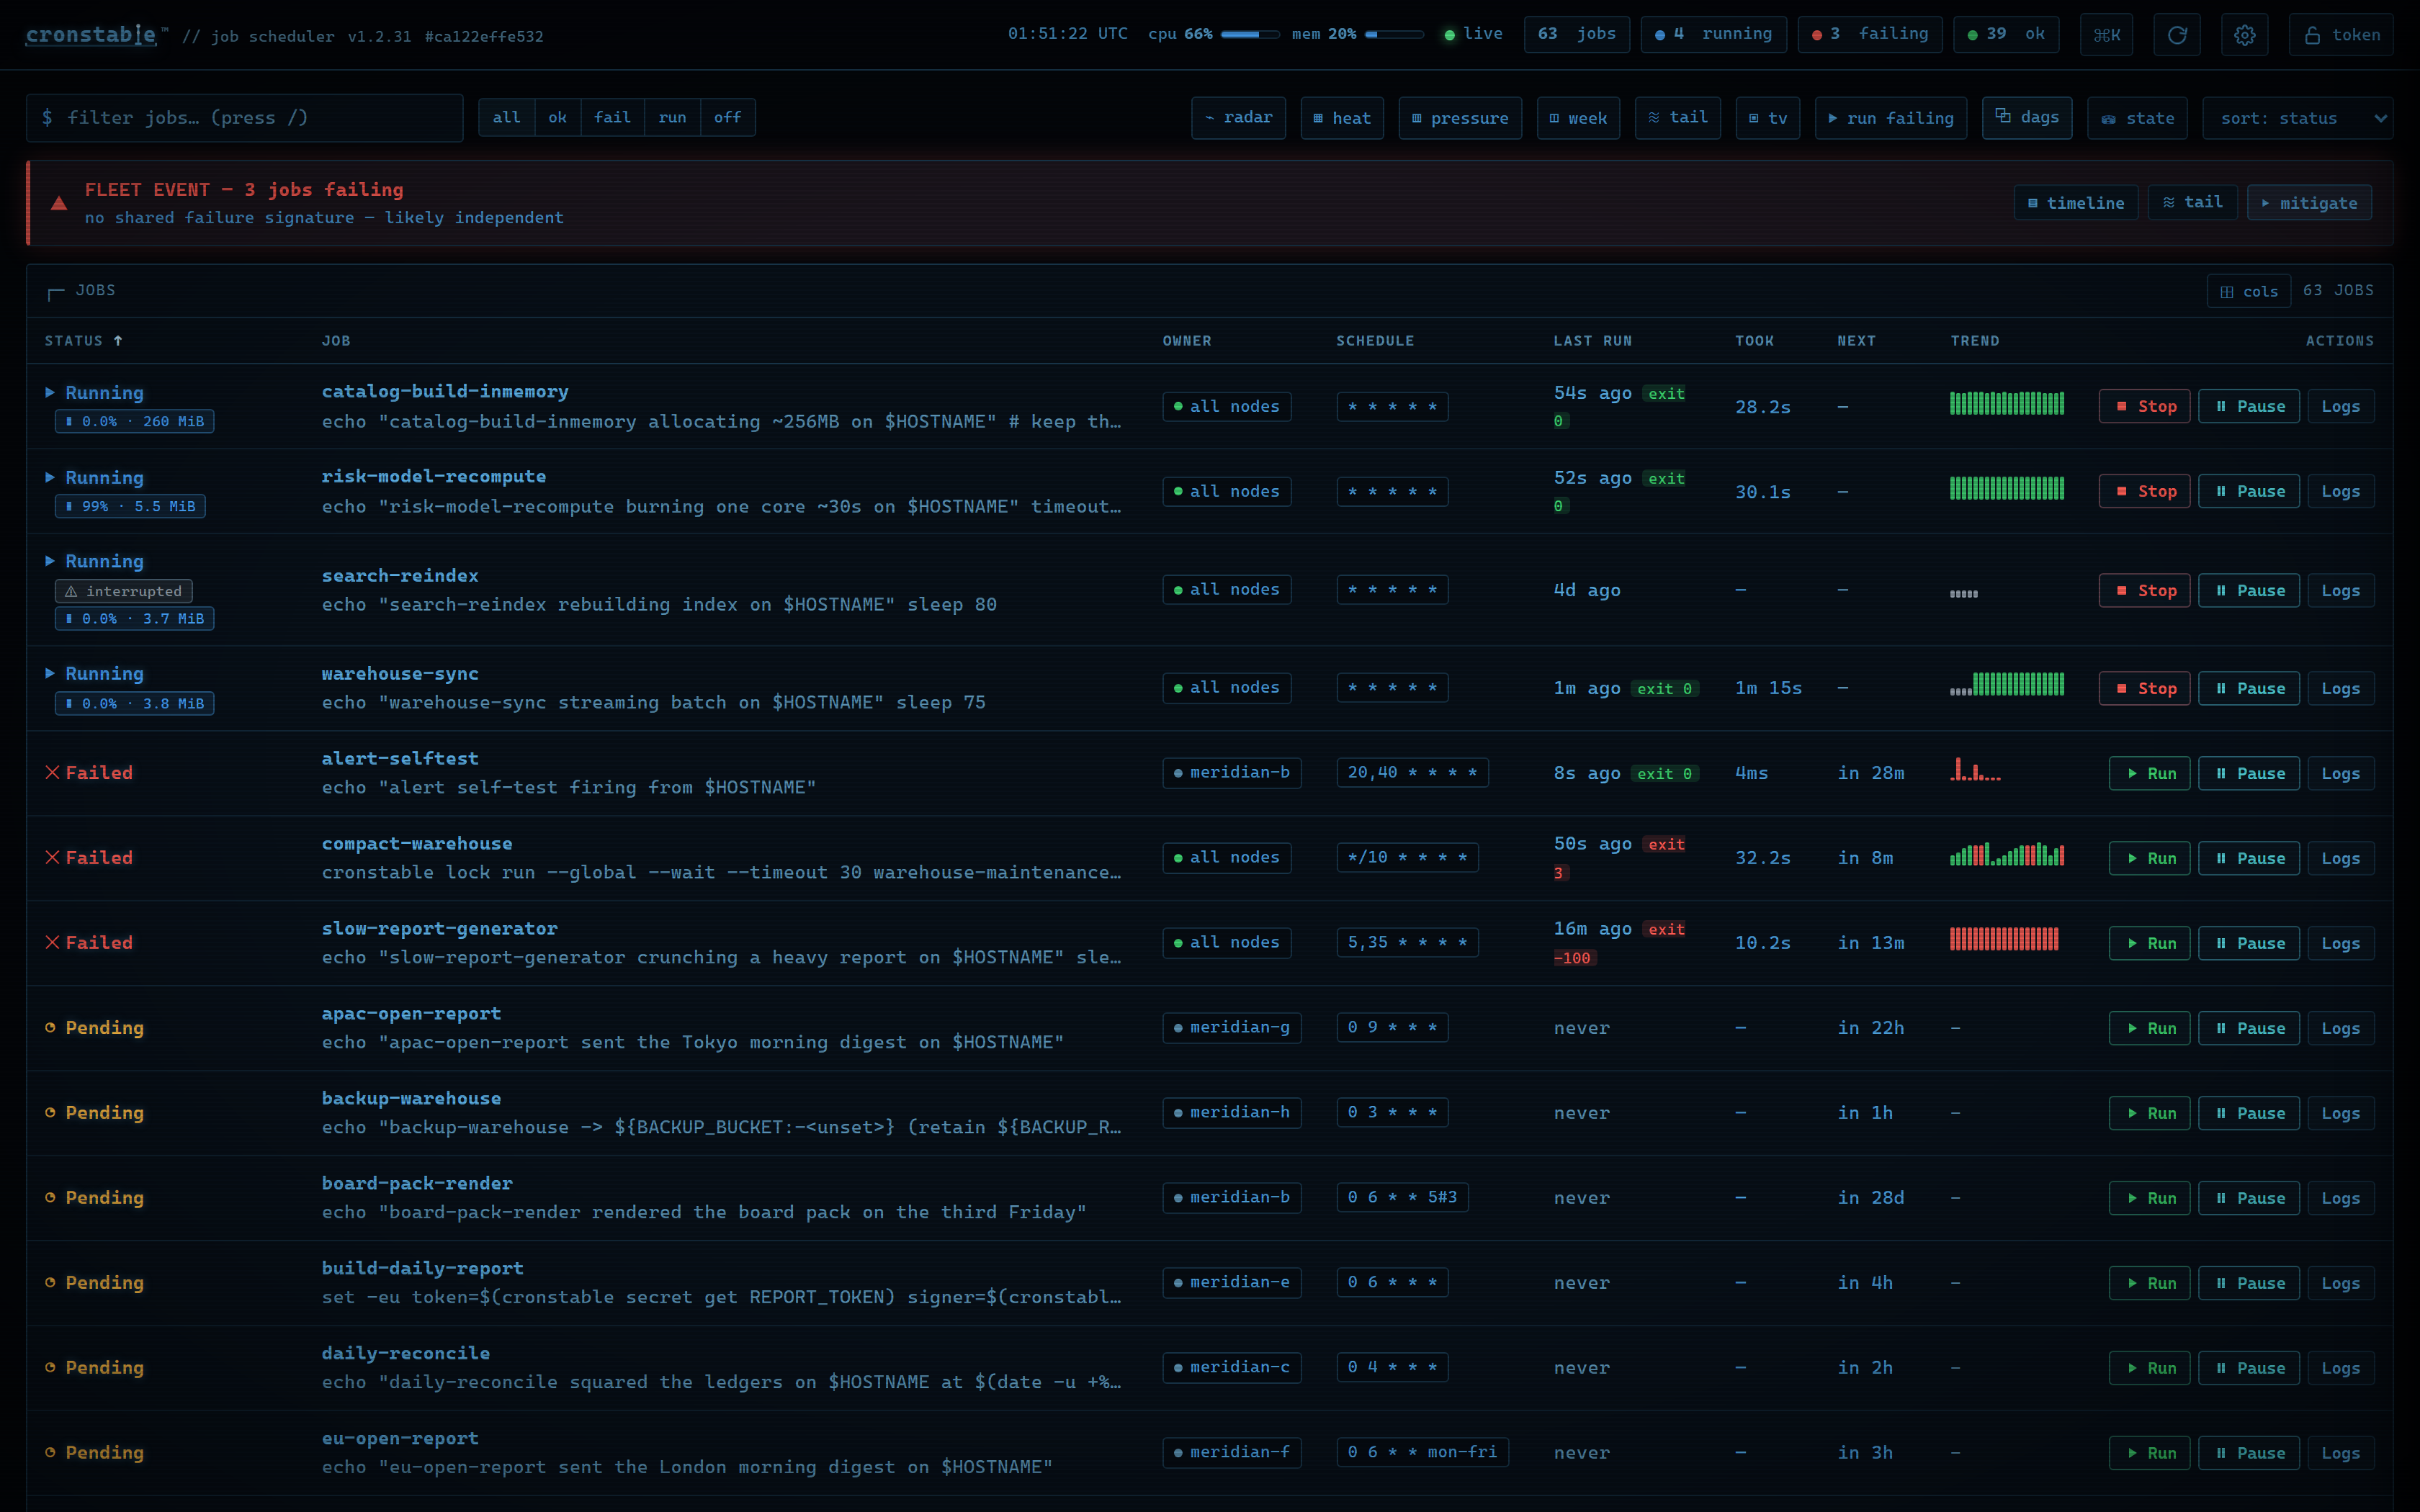
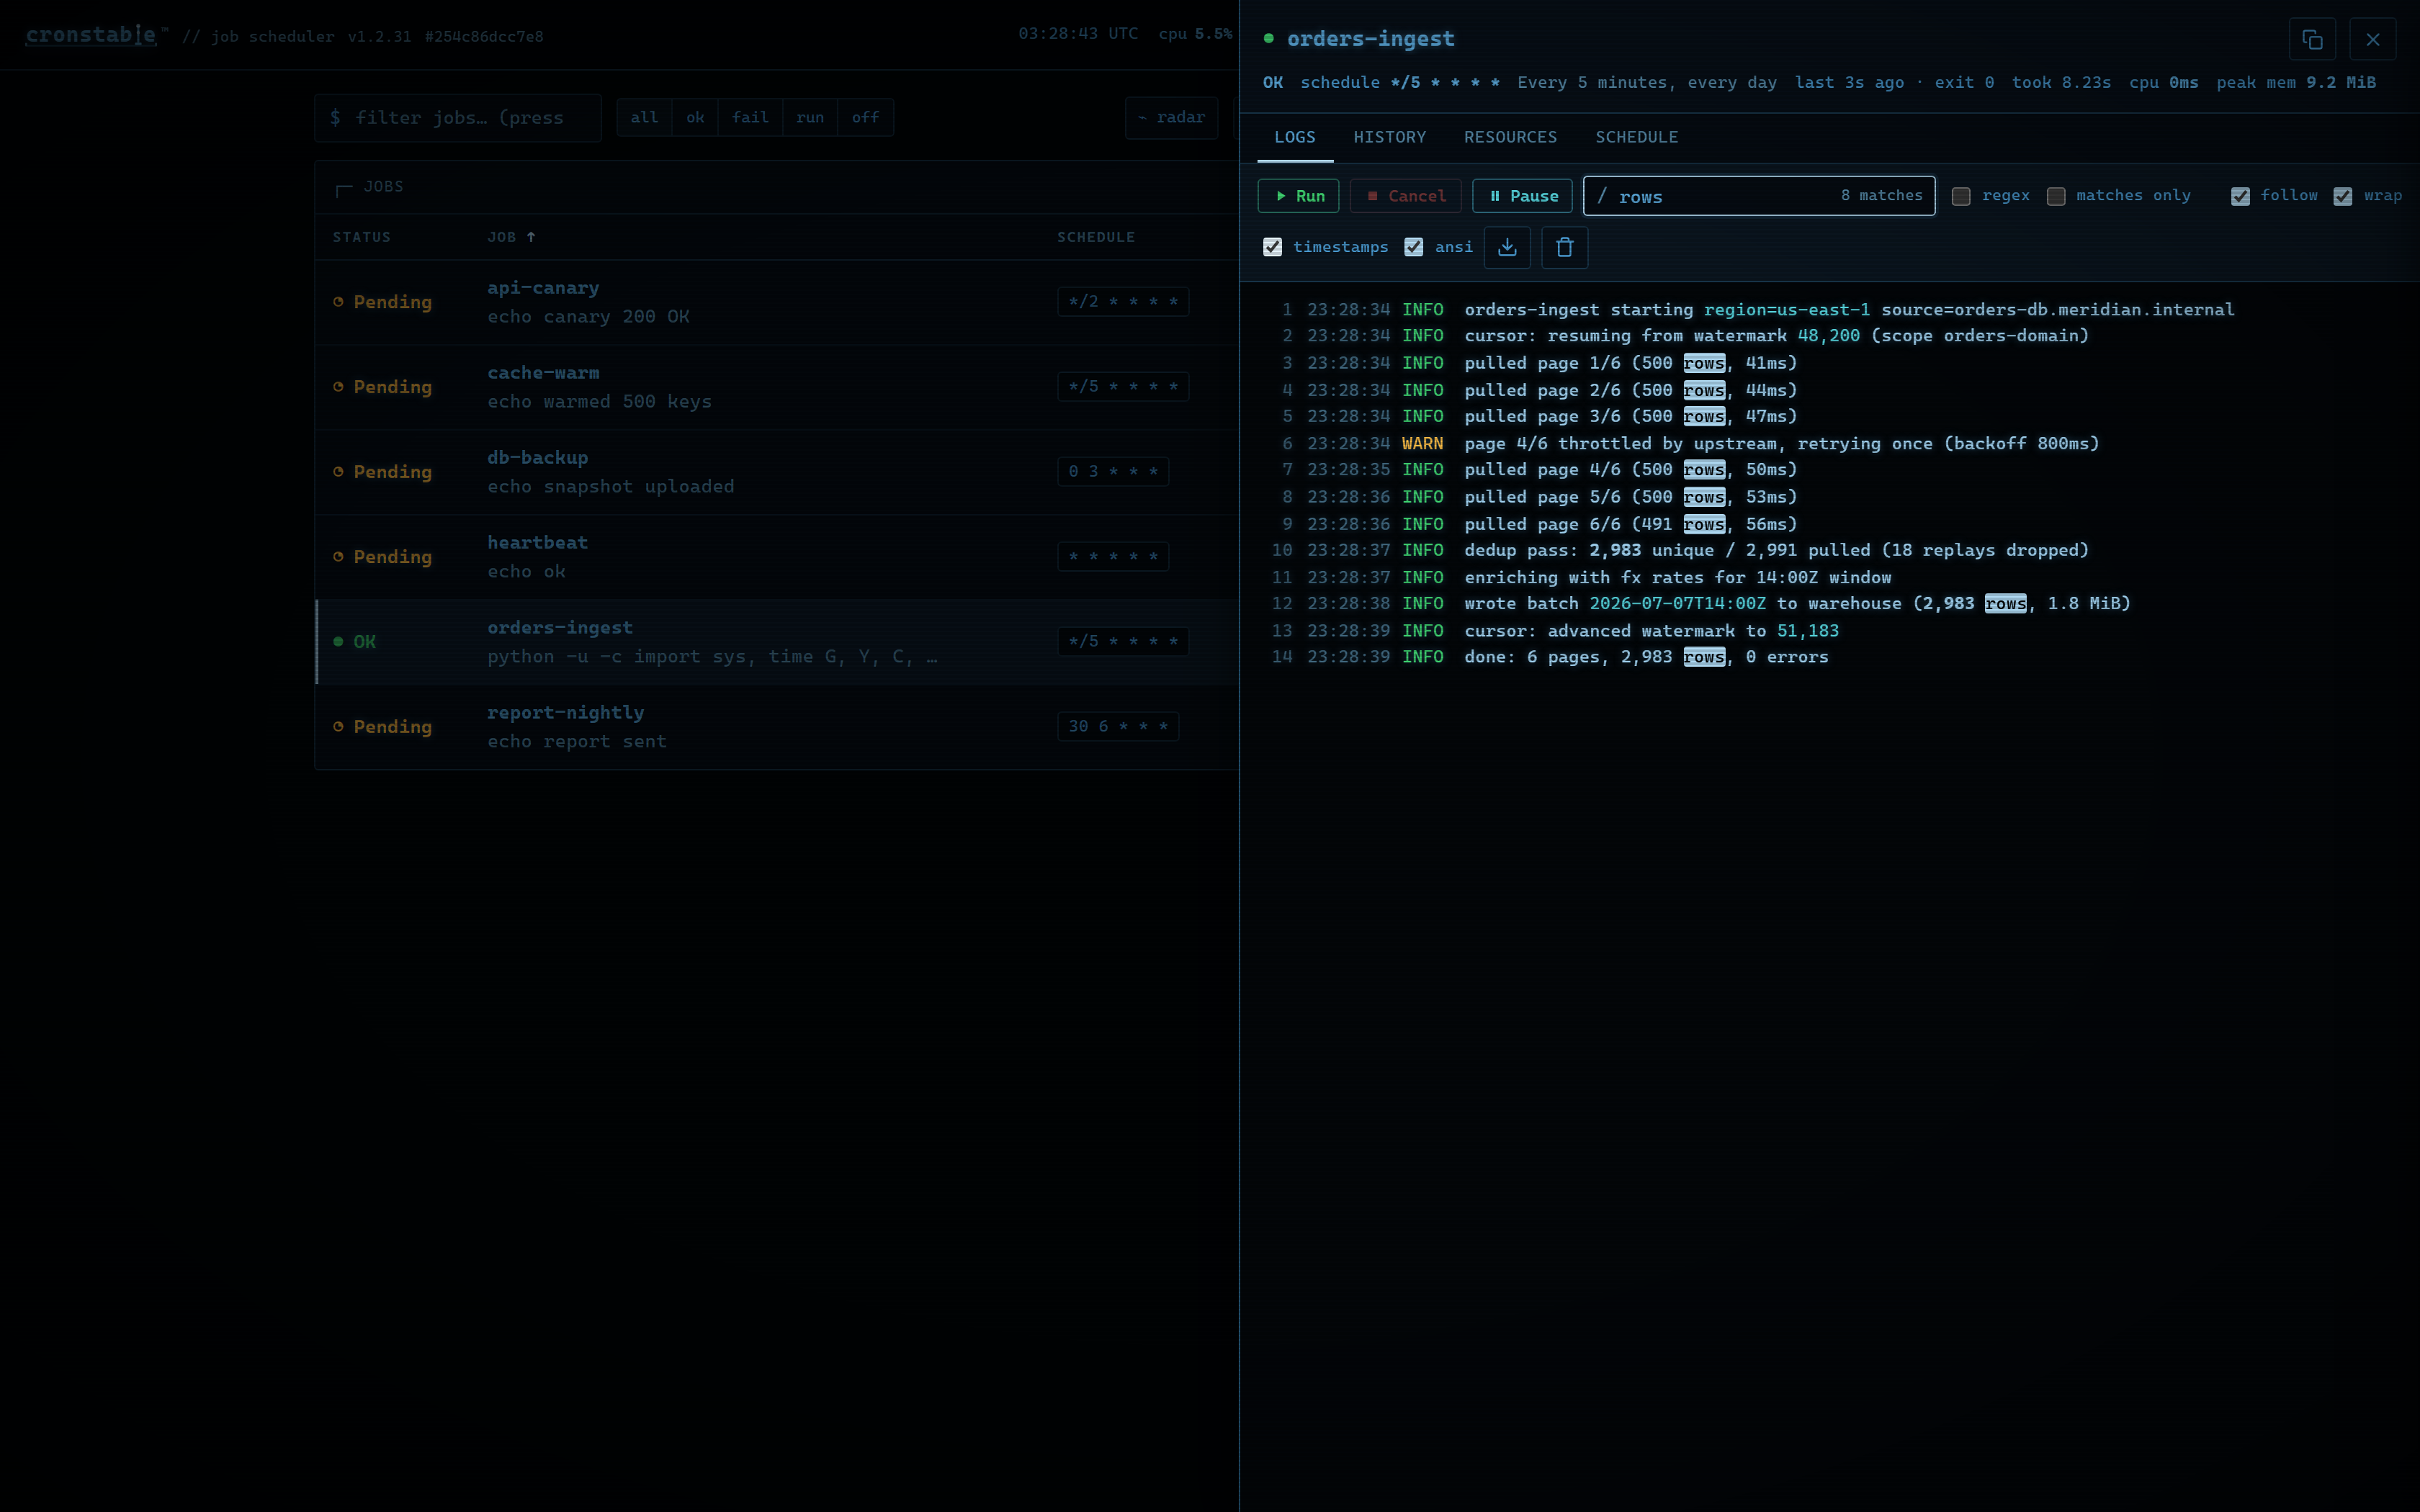
The overview shows job status, upcoming runs, recent outcomes, and resource usage when monitoring is enabled. Open a job to follow its logs, review run history, or inspect its schedule. You can also:
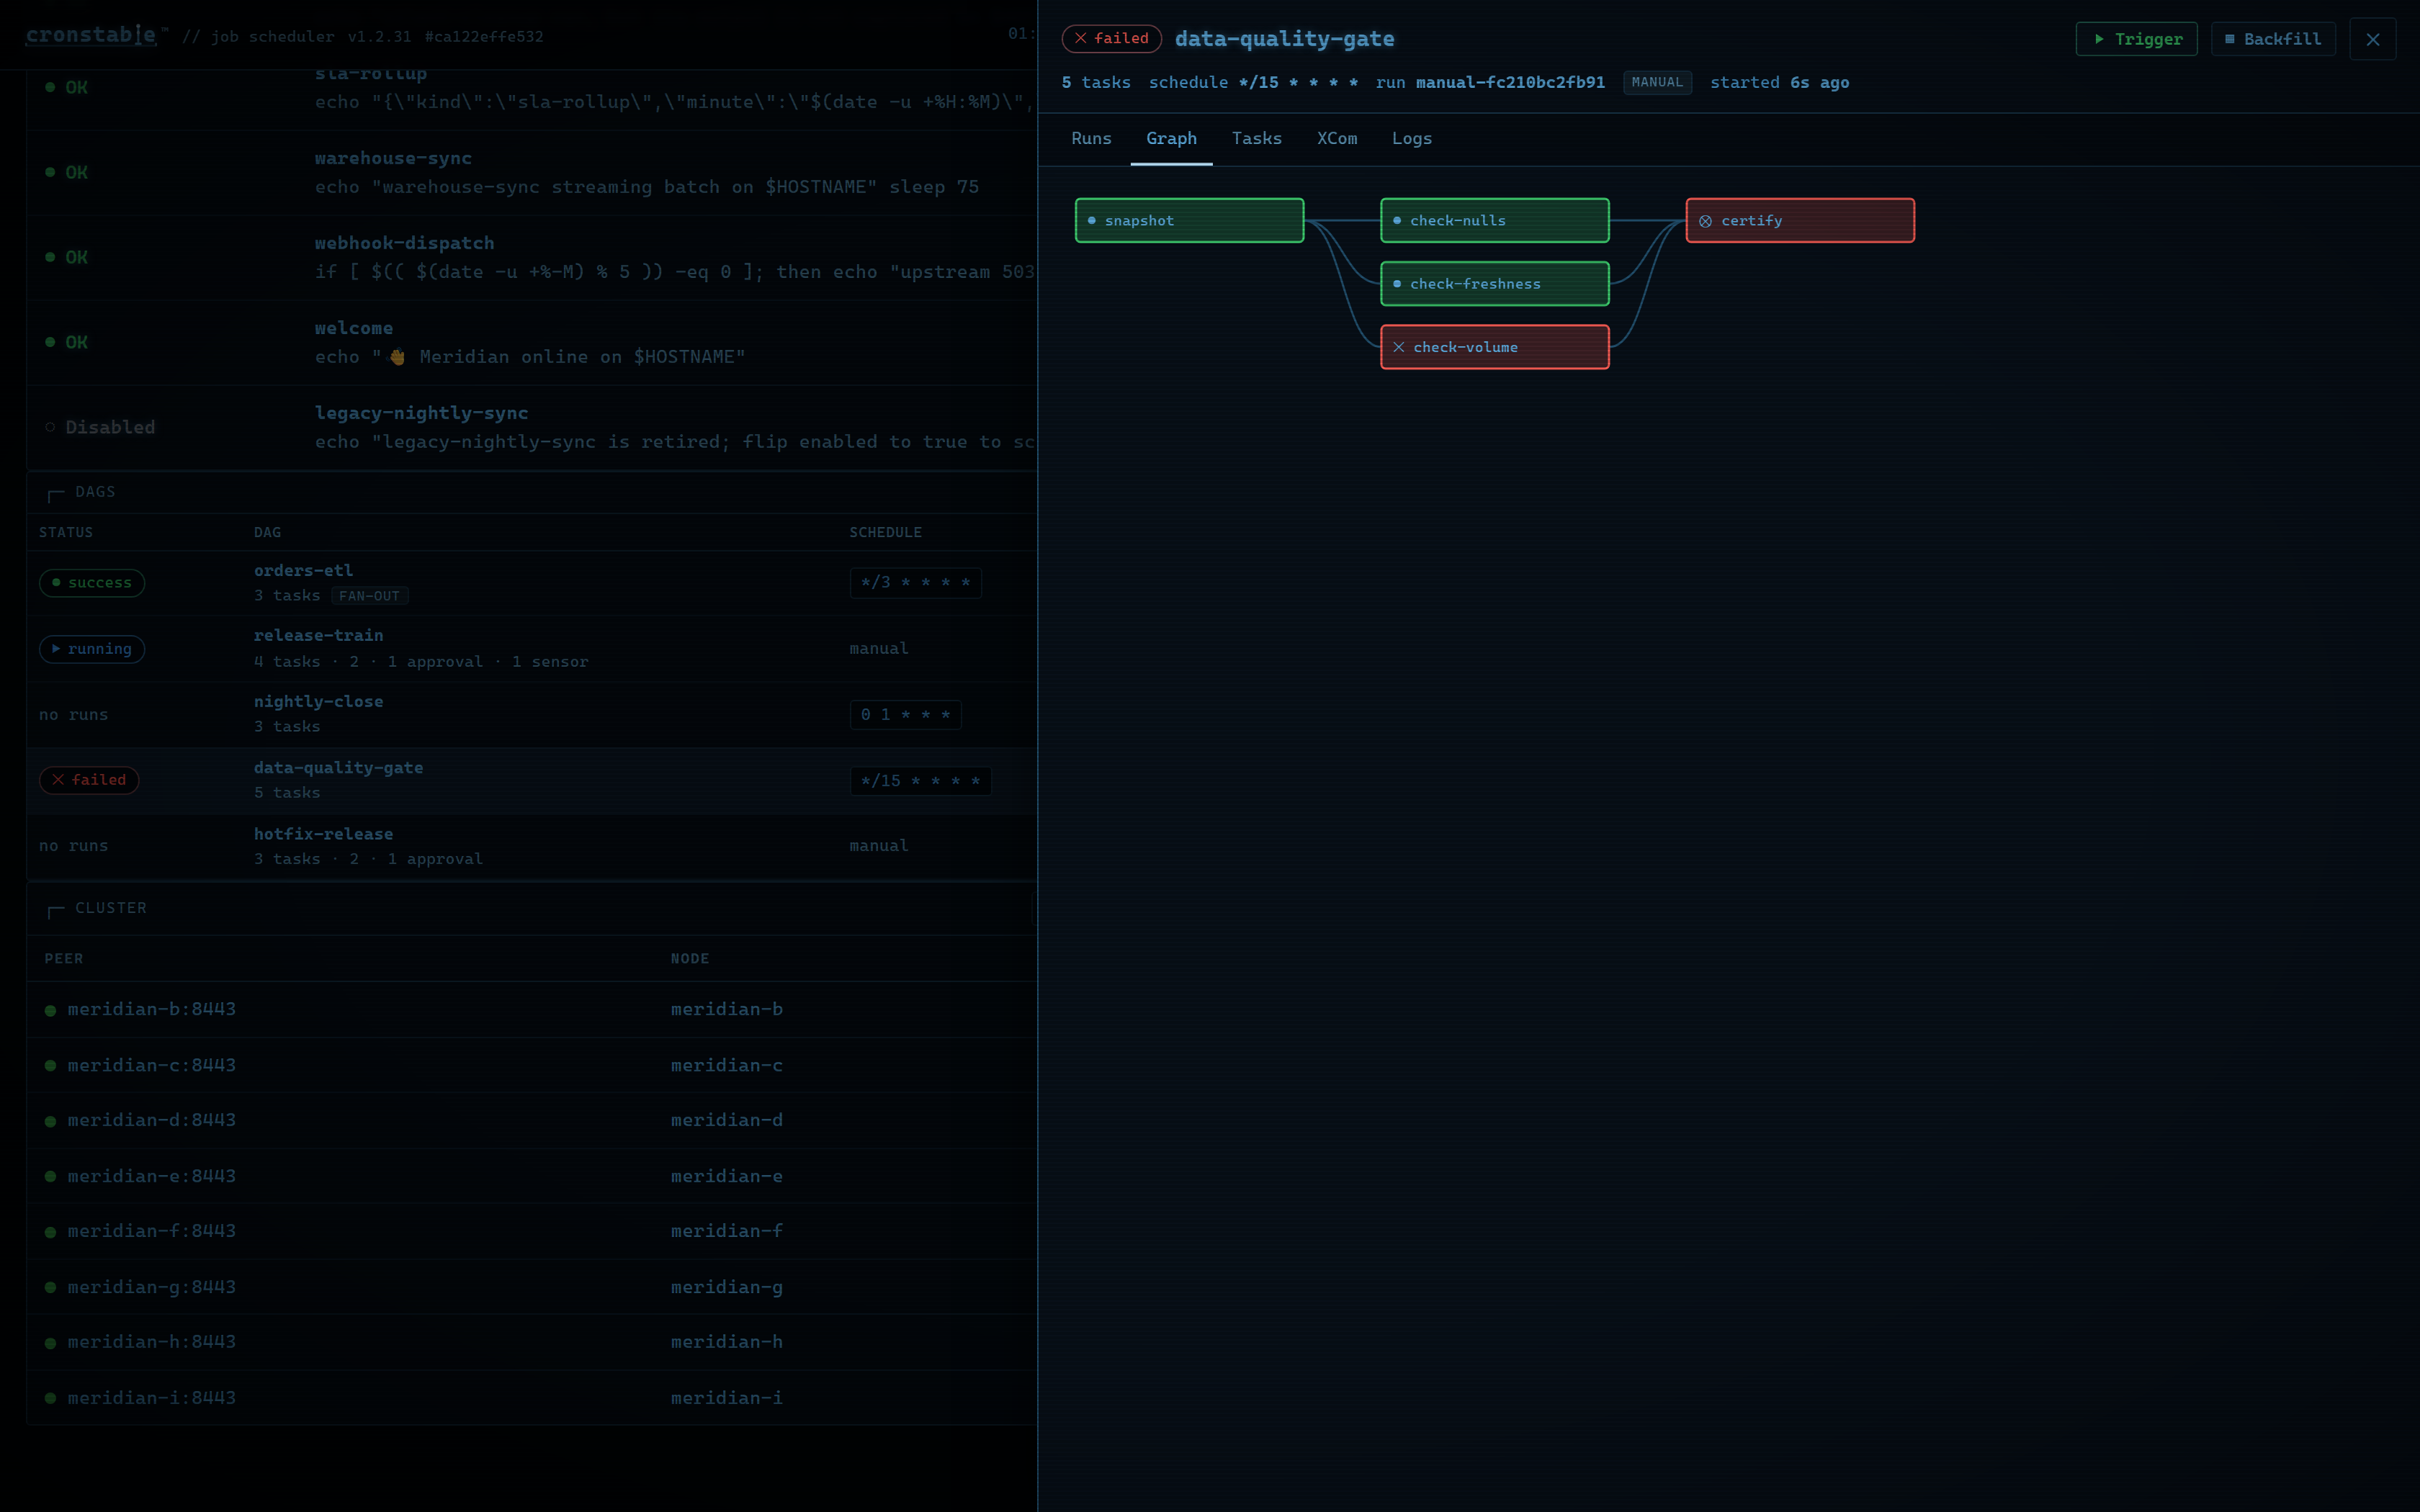
- Trigger workflows, follow task graphs, and approve or reject approval gates.
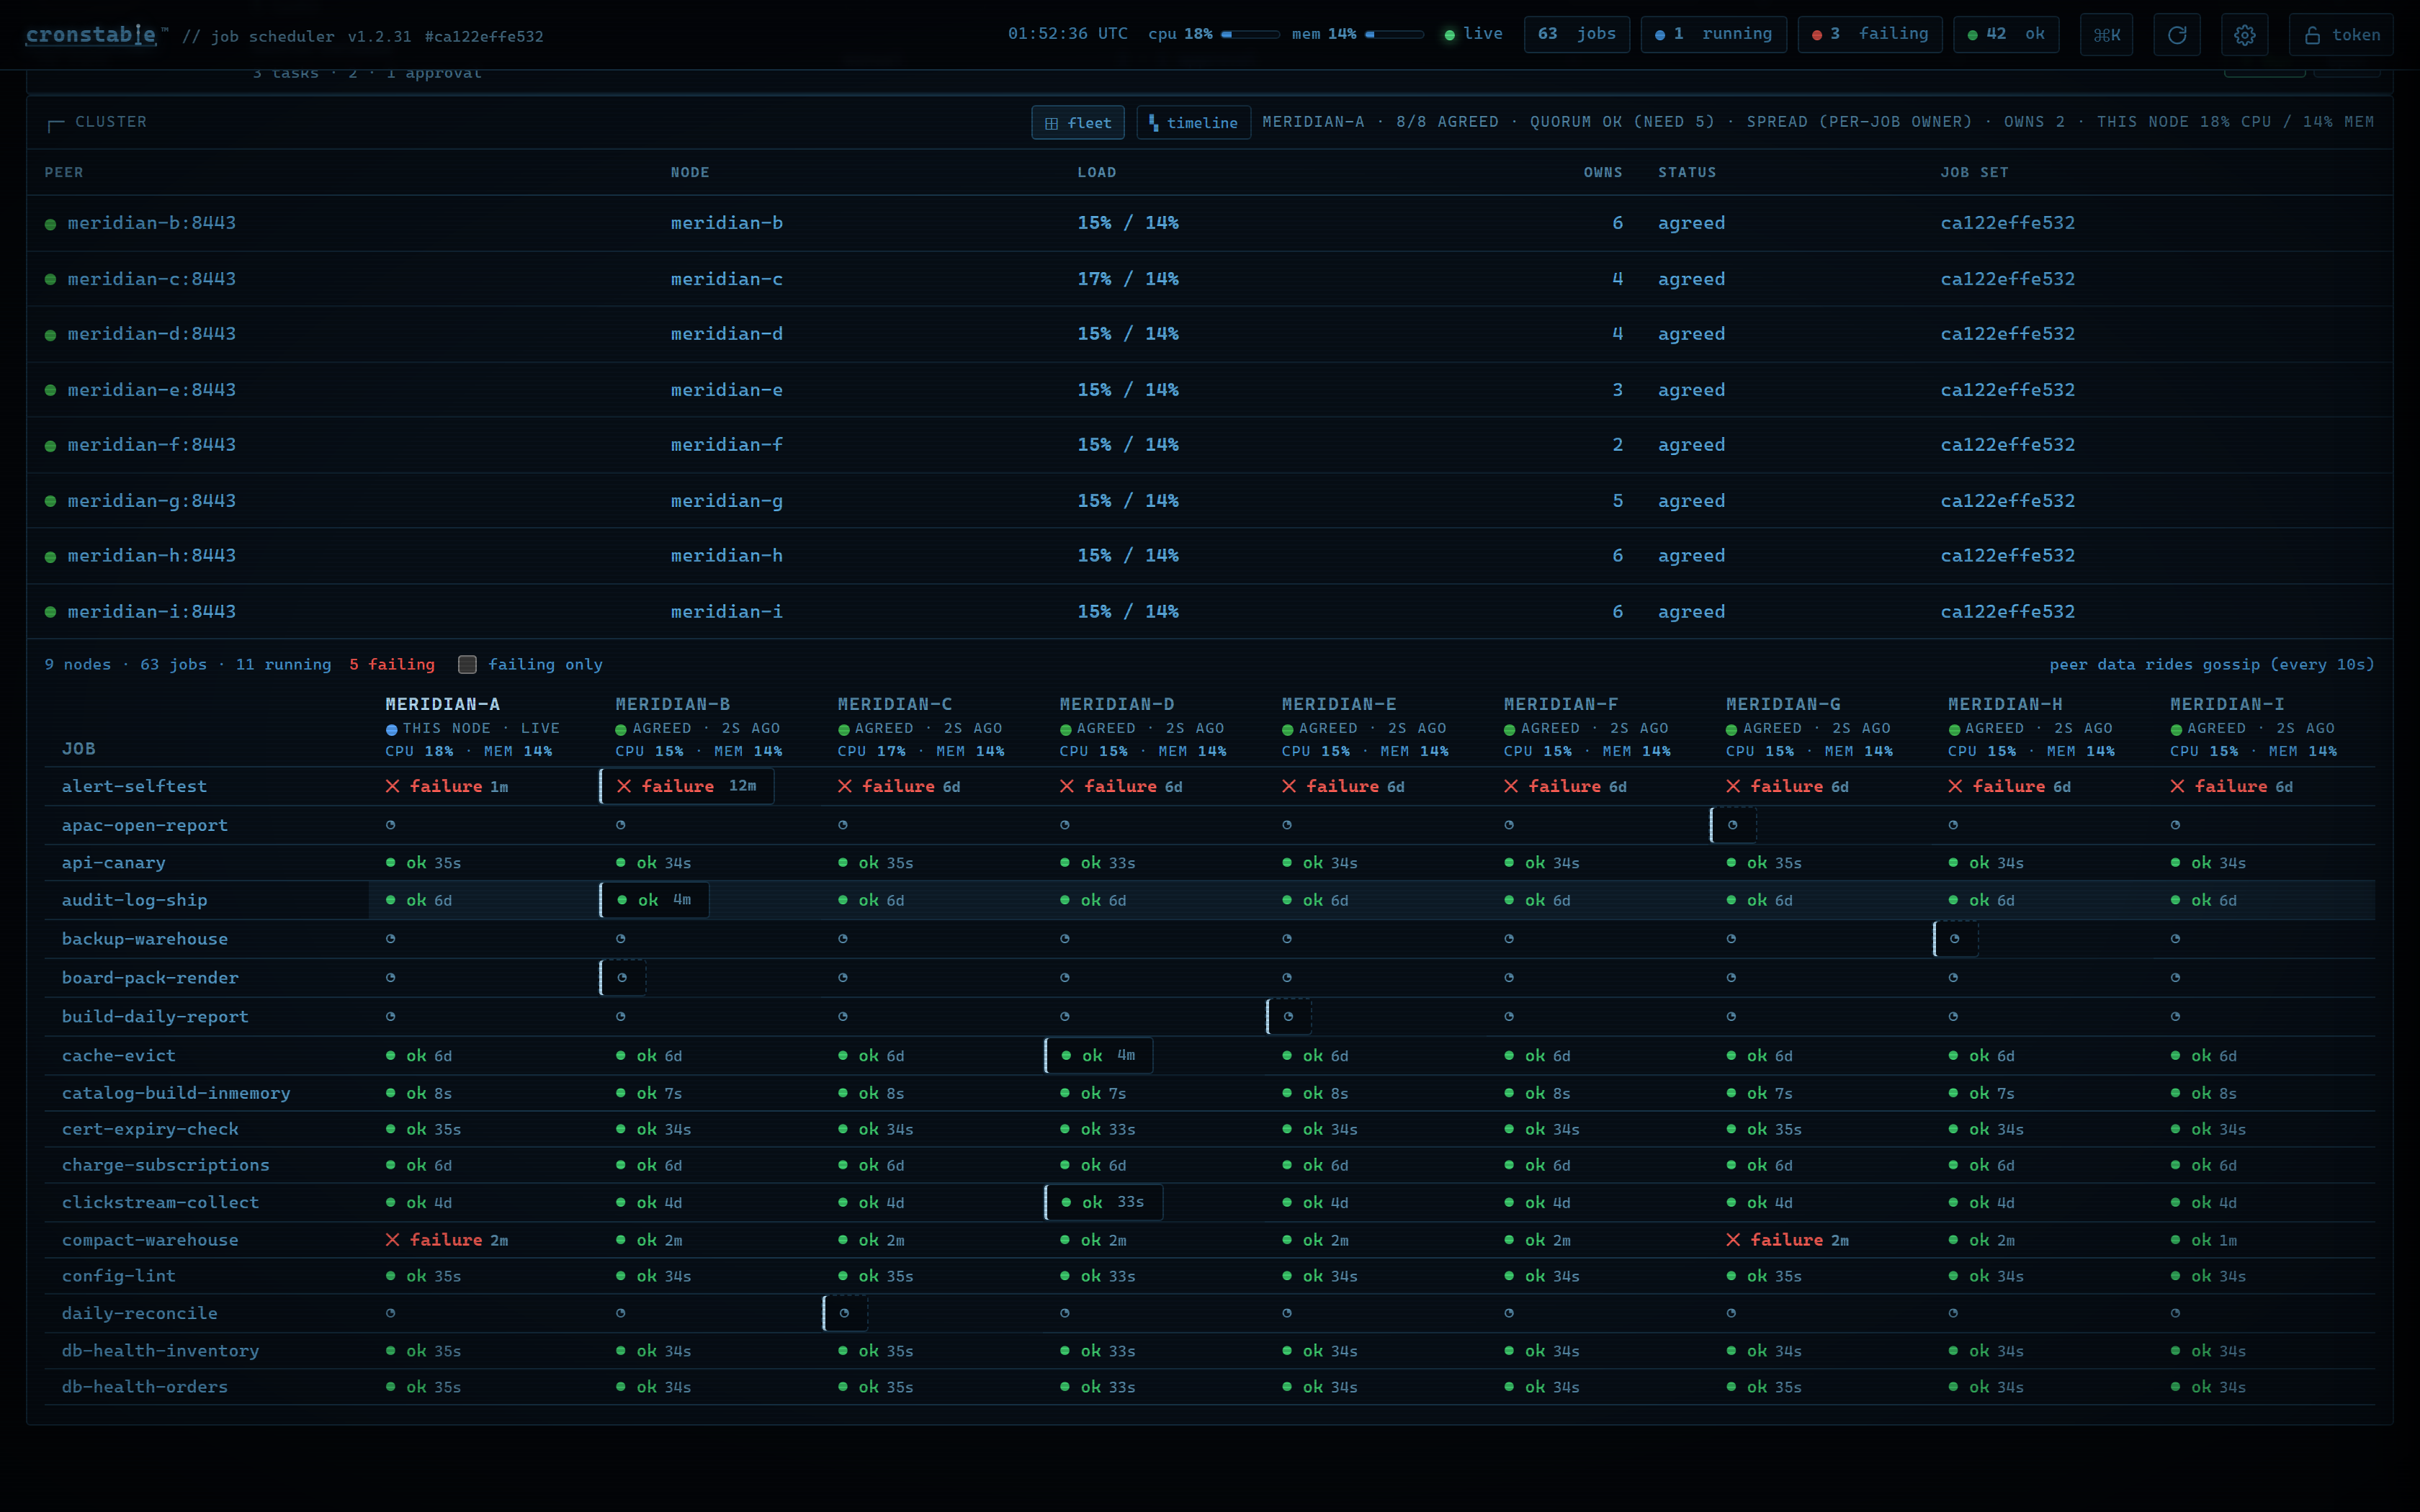
- Inspect cluster health and compare each job's runs across nodes.
- Investigate failures with an incident timeline and merged live logs.
- Use the wallboard, activity heatmap, and durable state inspector.
| Live logs | Workflow task graph | Fleet view |
|---|---|---|
 |
 |
 |
Press Ctrl-K / ⌘K for the command palette, ? for shortcuts, or Enter
to open the selected job. Ten themes, adjustable fonts and UI scale,
color-vision-safe palettes, and reduced-motion support help with readability.
Status is shown through text and symbols as well as color.
Run history and live logs stay in memory unless you enable the durable state store. The page is served with a strict Content-Security-Policy. See the web dashboard guide for the full panel tour, screenshots, shortcuts, and settings.
Try it: start a demo node with:
docker compose -f example/zen-demo/docker-compose.yml up
The example gallery includes a three-node cluster and the nine-node grand tour, with workflows, shared state, and failure reporters.
Terminal dashboard
cronstable tui brings the dashboard to your terminal, including SSH and tmux
sessions. It uses the same HTTP API and keyboard shortcuts as the web dashboard,
with job logs, history, workflows, cluster views, and incident tools.
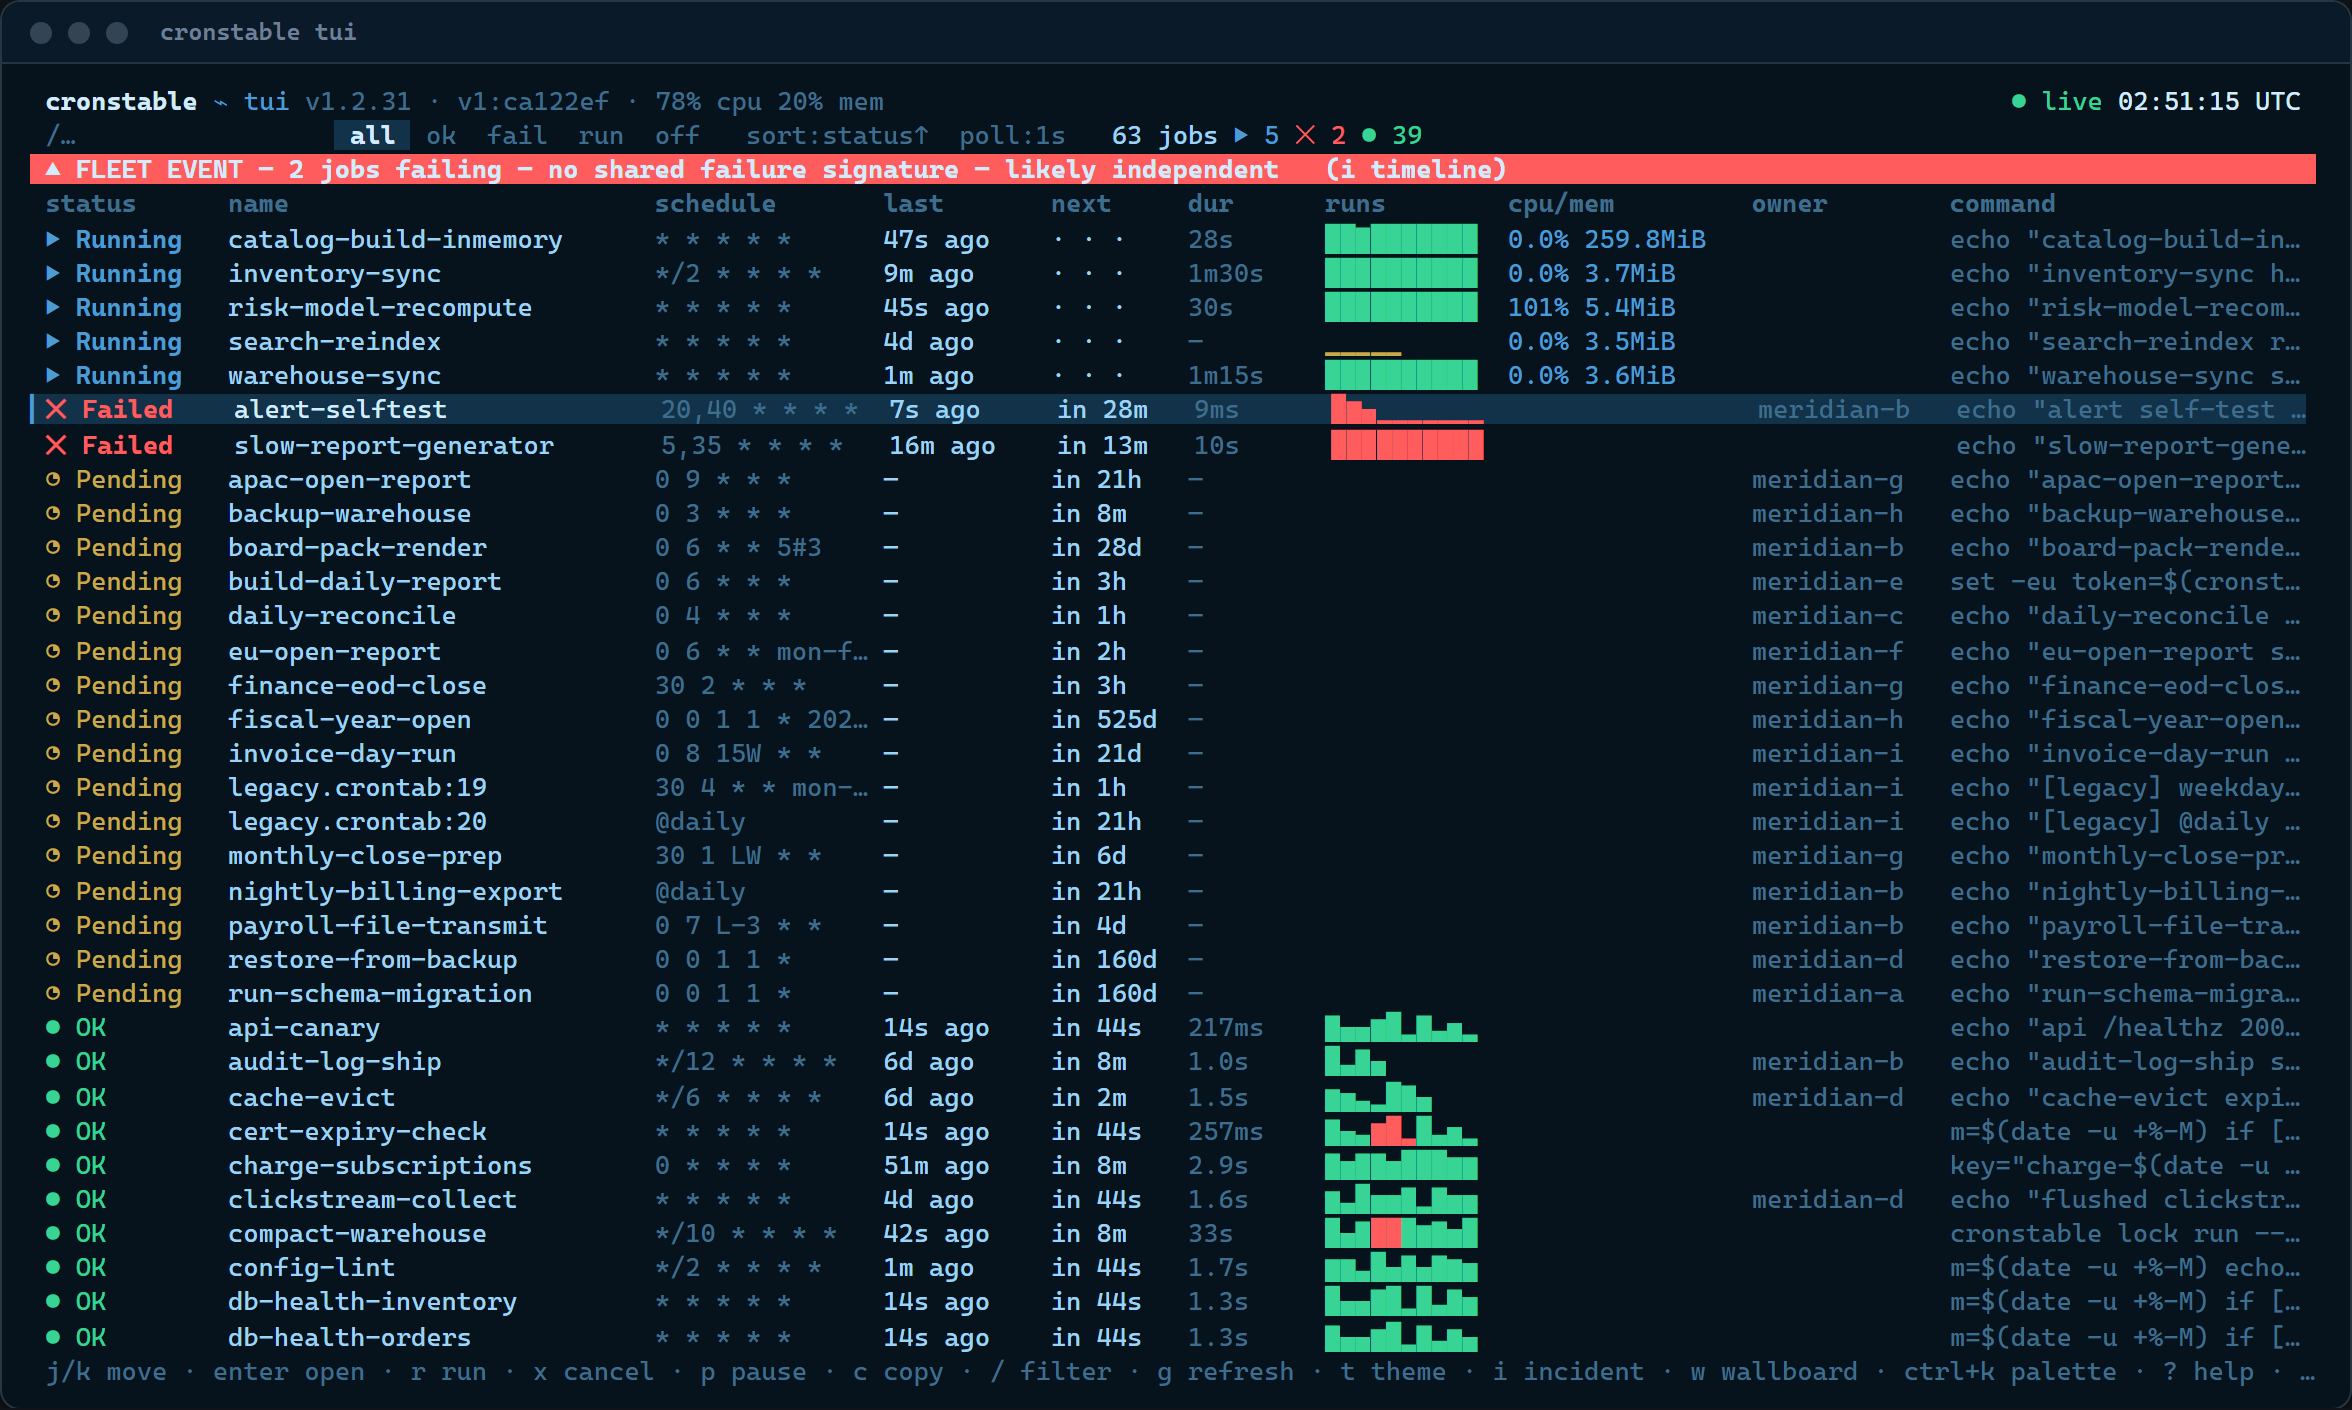
cronstable tui                            # local daemon on port 8080
cronstable tui --url http://prod-node:8080  # remote daemon
cronstable tui --tv                       # open the wallboard
Use --token-env for authentication, --job to open a specific job, or
--ascii when your terminal lacks the status glyphs. The
terminal dashboard guide
covers all options, shortcuts, panels, themes, and screenshots.
Tutorials
Four short walkthroughs you can copy and run, each built on the quick start config and each pointing at the wiki page that covers it in full.
Tutorial 1: Alert when a job fails, then retry it
Classic cron mails root. Instead: retry with exponential backoff, and page a Slack channel only if the job ultimately fails.
jobs:
  - name: nightly-backup
    command: /usr/local/bin/backup --incremental
    schedule: "0 3 * * *"
    captureStderr: true            # include stderr in the report
    onFailure:
      retry:
        maximumRetries: 5
        initialDelay: 5            # 5s, 10s, 20s, 40s, ... capped at 300s
        maximumDelay: 300
        backoffMultiplier: 2
    onPermanentFailure:            # fires once, after the last retry is spent
      report:
        webhook:
          url:
            fromEnvVar: SLACK_WEBHOOK_URL
By default a job fails when it exits nonzero or writes to a captured
stderr. Tune that per job with failsWhen. The webhook's
default body is Slack-compatible (Mattermost and Teams work as-is), and mail,
Sentry, and a shell command are equally one block away, with jinja2 templating
over the run's name, output, and exit code. Deeper:
failure detection and retries
and reporting in the wiki.
Tutorial 2: Survive restarts, catch up what was missed
Stateless is the default. When a deploy or a reboot lands mid-schedule, one
state: block gives jobs a memory:
state:
  path: /var/lib/cronstable           # a local dir, or a shared mount for a fleet

jobs:
  - name: hourly-invoice-emit
    command: python -m billing.emit_hourly
    schedule: "0 * * * *"
    onMissed: run-all              # replay each hour missed while we were down
    startingDeadlineSeconds: 21600 # ...unless the slot is older than 6h
    onFailure:
      retry:
        maximumRetries: 10
        initialDelay: 30
        maximumDelay: 600
        backoffMultiplier: 2
With the state.path line alone, run history survives restarts (the
dashboard rehydrates it), armed retries re-arm at their absolute deadlines,
@reboot means once per boot rather than once per daemon start, and
Prometheus counters stop resetting to zero.
onMissed adds catch-up on top: run-once coalesces any number of missed
slots into one launch, run-all replays each one, bounded by
startingDeadlineSeconds. Jobs recover after a restart and when the same
daemon resumes after system sleep or a long stall. A normal start after
resume satisfies run-once; failed catch-up attempts count as attempted
and do not arm retries. The same store also hands your job commands
durable primitives (key/value, cursors, fleet-wide locks, idempotency keys,
artifacts, run-scoped secrets) over a loopback endpoint:
cronstable state|cursor|lock|idempotent|artifact|secret. Deeper:
durable state.
Tutorial 3: Your first DAG, a durable pipeline
A dags: block turns the scheduler into a small, durable workflow engine.
This one builds, waits for a human, then publishes:
state:
  path: /var/lib/cronstable           # DAGs live on the state store

dags:
  - name: release-train            # no schedule: manual-only
    tasks:
      - id: build
        command: make dist
      - id: approve
        type: approval             # parks the graph on a human decision
        dependsOn: [build]
      - id: publish
        dependsOn: [approve]
        command: make publish
        retries: 2                 # task-level retries, DAG-owned
        retryDelaySeconds: 60
Trigger it and approve the gate (or click Approve in the dashboard's DAG drawer):
curl -X POST http://127.0.0.1:8080/dags/release-train/trigger
# -> {"dag": "release-train", "runKey": "manual-..."}
curl -X POST http://127.0.0.1:8080/dags/release-train/runs/<runKey>/tasks/approve/decision \
     -H 'Content-Type: application/json' -d '{"decision": "approve", "by": "alice"}'
Every transition is durable: restart the daemon mid-run and the run resumes
exactly where it was, and across a fleet the run advances under a lease so a
task never launches twice. Scheduled DAGs add catch-up and backfill over a
date range. Tasks can pass data with cronstable xcom push/pull, fan out
dynamically over a list an upstream task produced, and poll for conditions
with type: sensor. Deeper:
orchestration and DAGs.
Tutorial 4: Two replicas, zero double-runs
Run the same config on two (or nine) hosts that share a POSIX mount, and let them elect a leader through a fenced lease file, with no certificates and no coordination service:
state:
  path: /mnt/shared/cronstable/state  # shared durable state (optional but natural here)

cluster:
  backend: filesystem
  filesystem:
    path: /mnt/shared/cronstable      # the mount is the election store
  nodeName: node-a                 # unique and stable per replica!
  electLeader: true

jobs:
  - name: charge-subscriptions
    command: python -m billing.charge
    schedule: "0 6 * * *"
    clusterPolicy: Leader          # the default: exactly the leader runs it
Only the elected leader fires Leader jobs. Stop it, and a follower adopts
the lease within its TTL. Per job, clusterPolicy picks the trade-off:
Leader (never double-runs, may skip when quorum is lost), PreferLeader
(never skips, may double-run under a partition), or EveryNode (genuinely
per-node work).
Without a shared mount, the gossip backend elects over mutual TLS with no
shared store at all, kubernetes uses a coordination.k8s.io Lease, and
etcd a lease-bound key. distribution: spread load-balances job ownership
across the fleet instead of concentrating it on one leader. Deeper:
clustering and leader election.
Example gallery
Every example in example/ is a self-contained, annotated,
runnable project. Each compose file lives in its example's folder (the demo
quickstart uses the root docker-compose.yml). Highlights:
| Example | One command | Shows off |
|---|---|---|
demo |
docker compose up |
The dashboard playground: varied jobs, live logs, retries, a long-runner, an on-demand job. |
grand-tour |
docker compose -f example/grand-tour/docker-compose.yml up --build |
Everything at once: a 9-node mTLS cluster, shared durable state, five DAG patterns, second-level probes, all five cross-platform reporters wired to live sinks. |
cluster |
docker compose -f example/cluster/docker-compose.yml up |
A 3-node gossip cluster: peer attestation, quorum, leader election, live failover. |
cluster-large |
docker compose -f example/cluster-large/docker-compose.yml up |
A 10-node, CPU-heavy fleet for watching distribution: spread and the load meters. |
dag |
cronstable -c example/dag |
Orchestration alone, single node: dependencies, XCom, fan-out, a sensor, an approval gate. |
dag-cluster |
docker compose -f example/dag-cluster/docker-compose.yml up |
DAGs coordinating across three nodes on one shared store: crash-resume, exactly-once tasks. |
job-state |
cronstable -c example/job-state |
The job-facing state primitives: KV, cursors, locks, idempotency keys, artifacts, secrets. |
mcp |
docker compose -f example/mcp/docker-compose.yml up --build |
The MCP server: an AI agent (Claude, Cursor, Copilot) observing and driving the scheduler over POST /mcp, or the cronstable mcp stdio bridge. |
pulse-monitor |
docker compose -f example/pulse-monitor/docker-compose.yml up |
Second-level scheduling as a real-time uptime / SLA monitor. |
pulse-cluster |
docker compose -f example/pulse-cluster/docker-compose.yml up |
The same probes fanned across a 3-node leader-electing cluster. |
zen-demo |
docker compose -f example/zen-demo/docker-compose.yml up |
A deliberately calm board, for the wallboard's zen screensaver. |
crontab |
cronstable -c example/crontab |
Classic Vixie crontabs running as-is next to YAML jobs. |
kubernetes |
kubectl apply -f example/kubernetes/deployment.yaml |
Leader election through a coordination.k8s.io/v1 Lease. |
etcd |
docker compose -f example/etcd/docker-compose.yml up |
Leader election through an etcd lease, over plain HTTP. |
docker |
docker build |
The minimal "add cronstable to your own image" recipe. |
Usage
Configuration is in YAML format. To start cronstable, give it a configuration
file or directory path as the -c argument. For example:
cronstable -c /tmp/my-crontab.yaml
This starts cronstable (always in the foreground!), reading
/tmp/my-crontab.yaml as configuration file. If the path is a directory, any
*.yaml or *.yml files inside that directory are taken as
configuration files, along with any classic crontabs (*.crontab, *.cron,
or a file named crontab; see
classic crontab files).
Configuration basics
This configuration runs a command every 5 minutes:
jobs:
  - name: test-01
    command: echo "foobar"
    shell: /bin/bash
    schedule: "*/5 * * * *"
The command can be a string or a list of strings. If command is a string,
cronstable runs it through a shell, which is /bin/bash in the preceding
example, but is /bin/sh by default.
If the command is a list of strings, cronstable runs it directly, without a shell. The command's ARGV comes straight from the configuration:
jobs:
  - name: test-01
    command:
      - echo
      - foobar
    schedule: "*/5 * * * *"
The schedule option can be a string in the classic crontab format (5, 6 or 7
fields; ranges, steps, lists, jan/mon names, and Quartz's ? standing
alone in a day field), parsed by cronstable's built-in cron engine. For the
full dialect, see
schedules and time zones.
Expressions in other dialects (Quartz #/W, the seconds-first 6-field
layout) fail with an error naming the dialect and how to convert.
You can also include @reboot, which runs the job only when cronstable first
starts up. The schedule option can also be an object with properties. The
following configuration runs a command every 5 minutes, but only on the
specific date 2017-07-19, and does not run it on any other date:
jobs:
  - name: test-01
    command: echo "foobar"
    schedule:
      minute: "*/5"
      dayOfMonth: 19
      month: 7
      year: 2017
      dayOfWeek: "*"
Schedule introspection
Six features answer questions about schedules, each with its own wiki page:
- Schedule linting: cronstable lints every schedule at config load for legal
expressions that probably do not mean what they say (no future occurrence,
the day-of-month AND day-of-week rule, non-dividing
*/nsteps, wall times DST skips or repeats). Findings surface on/jobsand/status, andGET /schedule/previewchecks any expression before it becomes a job (Schedule Linting). - Hashed schedules: an
Hfield hashes a stable slot from the job's name, so a fleet of hourly jobs spreads across the hour instead of stampeding at:00(Hashed Schedules). - Schedule load:
GET /schedule/pressurebuckets the next 24 hours of fires into a collision heatmap, drawn in both dashboards (Schedule Pressure). - Duplicate detection:
GET /schedule/duplicatesgroups jobs whose schedules fire on identical instants, by semantic equality (Duplicate Schedule Detection). - Suggest a slot:
GET /schedule/suggestrecommends the least-loaded slot for a new job from the fleet's real fires (Suggest a Slot). - Why didn't it run:
GET /schedule/why?job=<name>&at=<timestamp>decomposes the scheduler's own match test field by field for one job and one instant (Why Didn't It Run?).
Second-level schedules
Schedules are minute-granular by default, but cronstable can also run jobs at second granularity. There are two equivalent spellings:
- a full seven-field crontab string, where the first field is the second
(
second minute hour dayOfMonth month dayOfWeek year); or - the object form with a
second:property.
Both of the following jobs run every 15 seconds (at seconds 0, 15, 30 and 45 of every minute):
jobs:
  - name: every-15s-string
    command: echo "tick"
    schedule: "*/15 * * * * * *"   # 7 fields: the leading field is seconds
  - name: every-15s-object
    command: echo "tick"
    schedule:
      second: "*/15"
The second field accepts the same syntax as the others (*, */5, 0,30,
10-20, ...). second: "*" (or * * * * * * *) fires every second.
While any enabled job specifies seconds, the scheduler wakes once per second instead of once per minute. Minute-granular jobs are unaffected and still fire exactly once in their scheduled minute. If no job uses seconds, cronstable keeps its original once-a-minute cadence, so there is no overhead for the common case.
Second-level scheduling is a YAML feature: classic crontab files
keep their standard five-field, minute-granular format. (A six-field string
is read as the classic five fields plus a trailing year column, not as
seconds; seconds require the full seven fields.)
For a runnable end-to-end example, see
example/pulse-monitor, a small real-time uptime / SLA
monitor that probes a service every few seconds
(docker compose -f example/pulse-monitor/docker-compose.yml up), and its clustered sibling
example/pulse-cluster, which fans the probes across a
three-node leader-electing cluster
(docker compose -f example/pulse-cluster/docker-compose.yml up).
Important: by default cronstable interprets all time as UTC, but you can
request local time instead. For instance, the following cron job runs
every day at 19h27 local time because of the utc: false option:
jobs:
  - name: test-01
    command: echo "hello"
    schedule: "27 19 * * *"
    utc: false
    captureStdout: true
You can also request that the schedule be interpreted in an arbitrary time
zone, using the timezone attribute:
jobs:
  - name: test-01
    command: echo "hello"
    schedule: "27 19 * * *"
    timezone: America/Los_Angeles
    captureStdout: true
You can ask for environment variables to be defined for the command:
jobs:
  - name: test-01
    command: echo "foobar"
    shell: /bin/bash
    schedule: "*/5 * * * *"
    environment:
      - key: PATH
        value: /bin:/usr/bin
Load environment variables for the command from a file:
jobs:
  - name: test-01
    command: echo "foobar"
    shell: /bin/bash
    schedule: "*/5 * * * *"
    env_file: .env
The env file must be a list of KEY=VALUE pairs. Empty lines and lines
starting with # are ignored.
Variables declared in the environment option override those found in the
env_file.
Classic crontab files
Already have a crontab? The daemon runs it as-is. A file named *.crontab,
*.cron, or plain crontab (so -c /etc/crontab works) is read in the
classic Vixie format, whether passed directly to -c, dropped into a config
directory next to YAML files, or pulled in with include::
SHELL=/bin/bash
PATH=/usr/local/bin:/usr/bin:/bin

# m h dom mon dow command
*/15 * * * *  /usr/local/bin/backup --incremental
30 4 * * mon-fri  /usr/local/bin/report --daily
@daily  /usr/local/bin/rotate-logs
0 0 * * *  pg_dump mydb > /backup/mydb-$(date +\%F).sql
Comments, NAME=value environment lines (position-sensitive, SHELL and
CRON_TZ honored), the @reboot/@daily/... nicknames, and \% escapes
all work as in man 5 crontab. Each entry becomes an ordinary cronstable job
named <file>:<line>, configured to cronstable's standard defaults rather
than an emulation of cron's environment:
- Schedules run in UTC unless the crontab sets
CRON_TZ. - Failure means a nonzero exit or stderr output (no
MAILTOmail). - The
%-as-stdin feature is a load-time error instead of a silent surprise (\%still gives a literal%).
When an entry needs retries, reporting, timeouts, or any other per-job option, move it to YAML. The full mapping and every deviation are documented in classic crontabs, and a runnable example (a config directory mixing a crontab with YAML and the dashboard) lives in example/crontab.
Specifying defaults
The config can have a special defaults section. Any attributes defined in
this section provide default values for cron jobs to inherit, although cron
jobs can still override the defaults as needed:
defaults:
    environment:
      - key: PATH
        value: /bin:/usr/bin
    shell: /bin/bash
    utc: false
jobs:
  - name: test-01
    command: echo "foobar"  # runs with /bin/bash as shell
    schedule: "*/5 * * * *"
  - name: test-02  # runs with /bin/sh as shell
    command: echo "zbr"
    shell: /bin/sh
    schedule: "*/5 * * * *"
Note: if the configuration option is a directory holding several
configuration files, each file's defaults section provides default options
only for cron jobs inside that same file. The defaults have no effect beyond
any individual YAML file.
Reporting
cronstable has six built-in reporters: sentry, mail, shell, webhook
(Slack-compatible with no extra configuration), and push
(end-to-end encrypted push notifications, later on this
page). Each can fire on the onFailure, onPermanentFailure, onSuccess,
and onLate hooks. The mail subject/body and sentry body are jinja2
templates over the run's outcome and captured output, and secrets (DSNs,
passwords, webhook URLs) can come from value, fromFile, or fromEnvVar:
- name: test-01
  command: |
    echo "hello" 1>&2
    exit 10
  schedule:
    minute: "*/2"
  captureStderr: true
  onFailure:
    report:
      sentry:
        dsn:
          fromEnvVar: SENTRY_DSN
      mail:
        from: example@foo.com
        to: example@bar.com
        smtpHost: 127.0.0.1
        subject: Cron job '{{name}}' failed
        body: |
          {{stderr}}
          (exit code: {{exit_code}})
      shell:
        shell: /bin/bash
        command: echo "Error code $CRONSTABLE_RETCODE"
      webhook:
        url:
          fromEnvVar: SLACK_WEBHOOK_URL
A report includes the output streams the job captures (captureStderr is on
by default, captureStdout off; see
output capturing
for the capture options, including the streamPrefix line prefix).
Reporting in the wiki
documents every reporter's options (HTML mail, sentry fingerprints, webhook
method/headers/body and per-service examples), the template variables, and
the shell reporter's CRONSTABLE_* environment.
Push notifications
The push reporter delivers end-to-end encrypted alerts to paired devices.
Each alert is sealed to the device's public key before it leaves the daemon:
an X25519 device gets a libsodium sealed box, and an X-Wing device (the
post-quantum ML-KEM-768 + X25519 hybrid) gets single-shot HPKE. The hosted
relay that forwards it to the platform push service (APNs) sees only
ciphertext and routing metadata, never job names, hostnames, or log lines.
The reporter needs the push extra (pip install "cronstable[push]"), a
daemon-global push: section, and an opt-in on the reporting hooks. The
extra carries both sealing libraries: PyNaCl for X25519 on every platform,
and cryptography for X-Wing on every platform it publishes a wheel for
(see
Push Notifications
for the list). The daemon lists what it can seal in sealableSuites on
GET /whoami, and the app pairs under xwing on its own whenever that
list carries it. If a config enables push without the extra or the
section, cronstable refuses to start rather than silently dropping alerts:
push:
  relay:
    url: https://relay.example.net/v1/notify
  devicesFile: /var/lib/cronstable/devices.json

defaults:
  onFailure:
    report:
      push:
        enabled: true
(With a state: section configured, devicesFile can be dropped: pairings
live in the durable store and are visible to every node sharing it.)
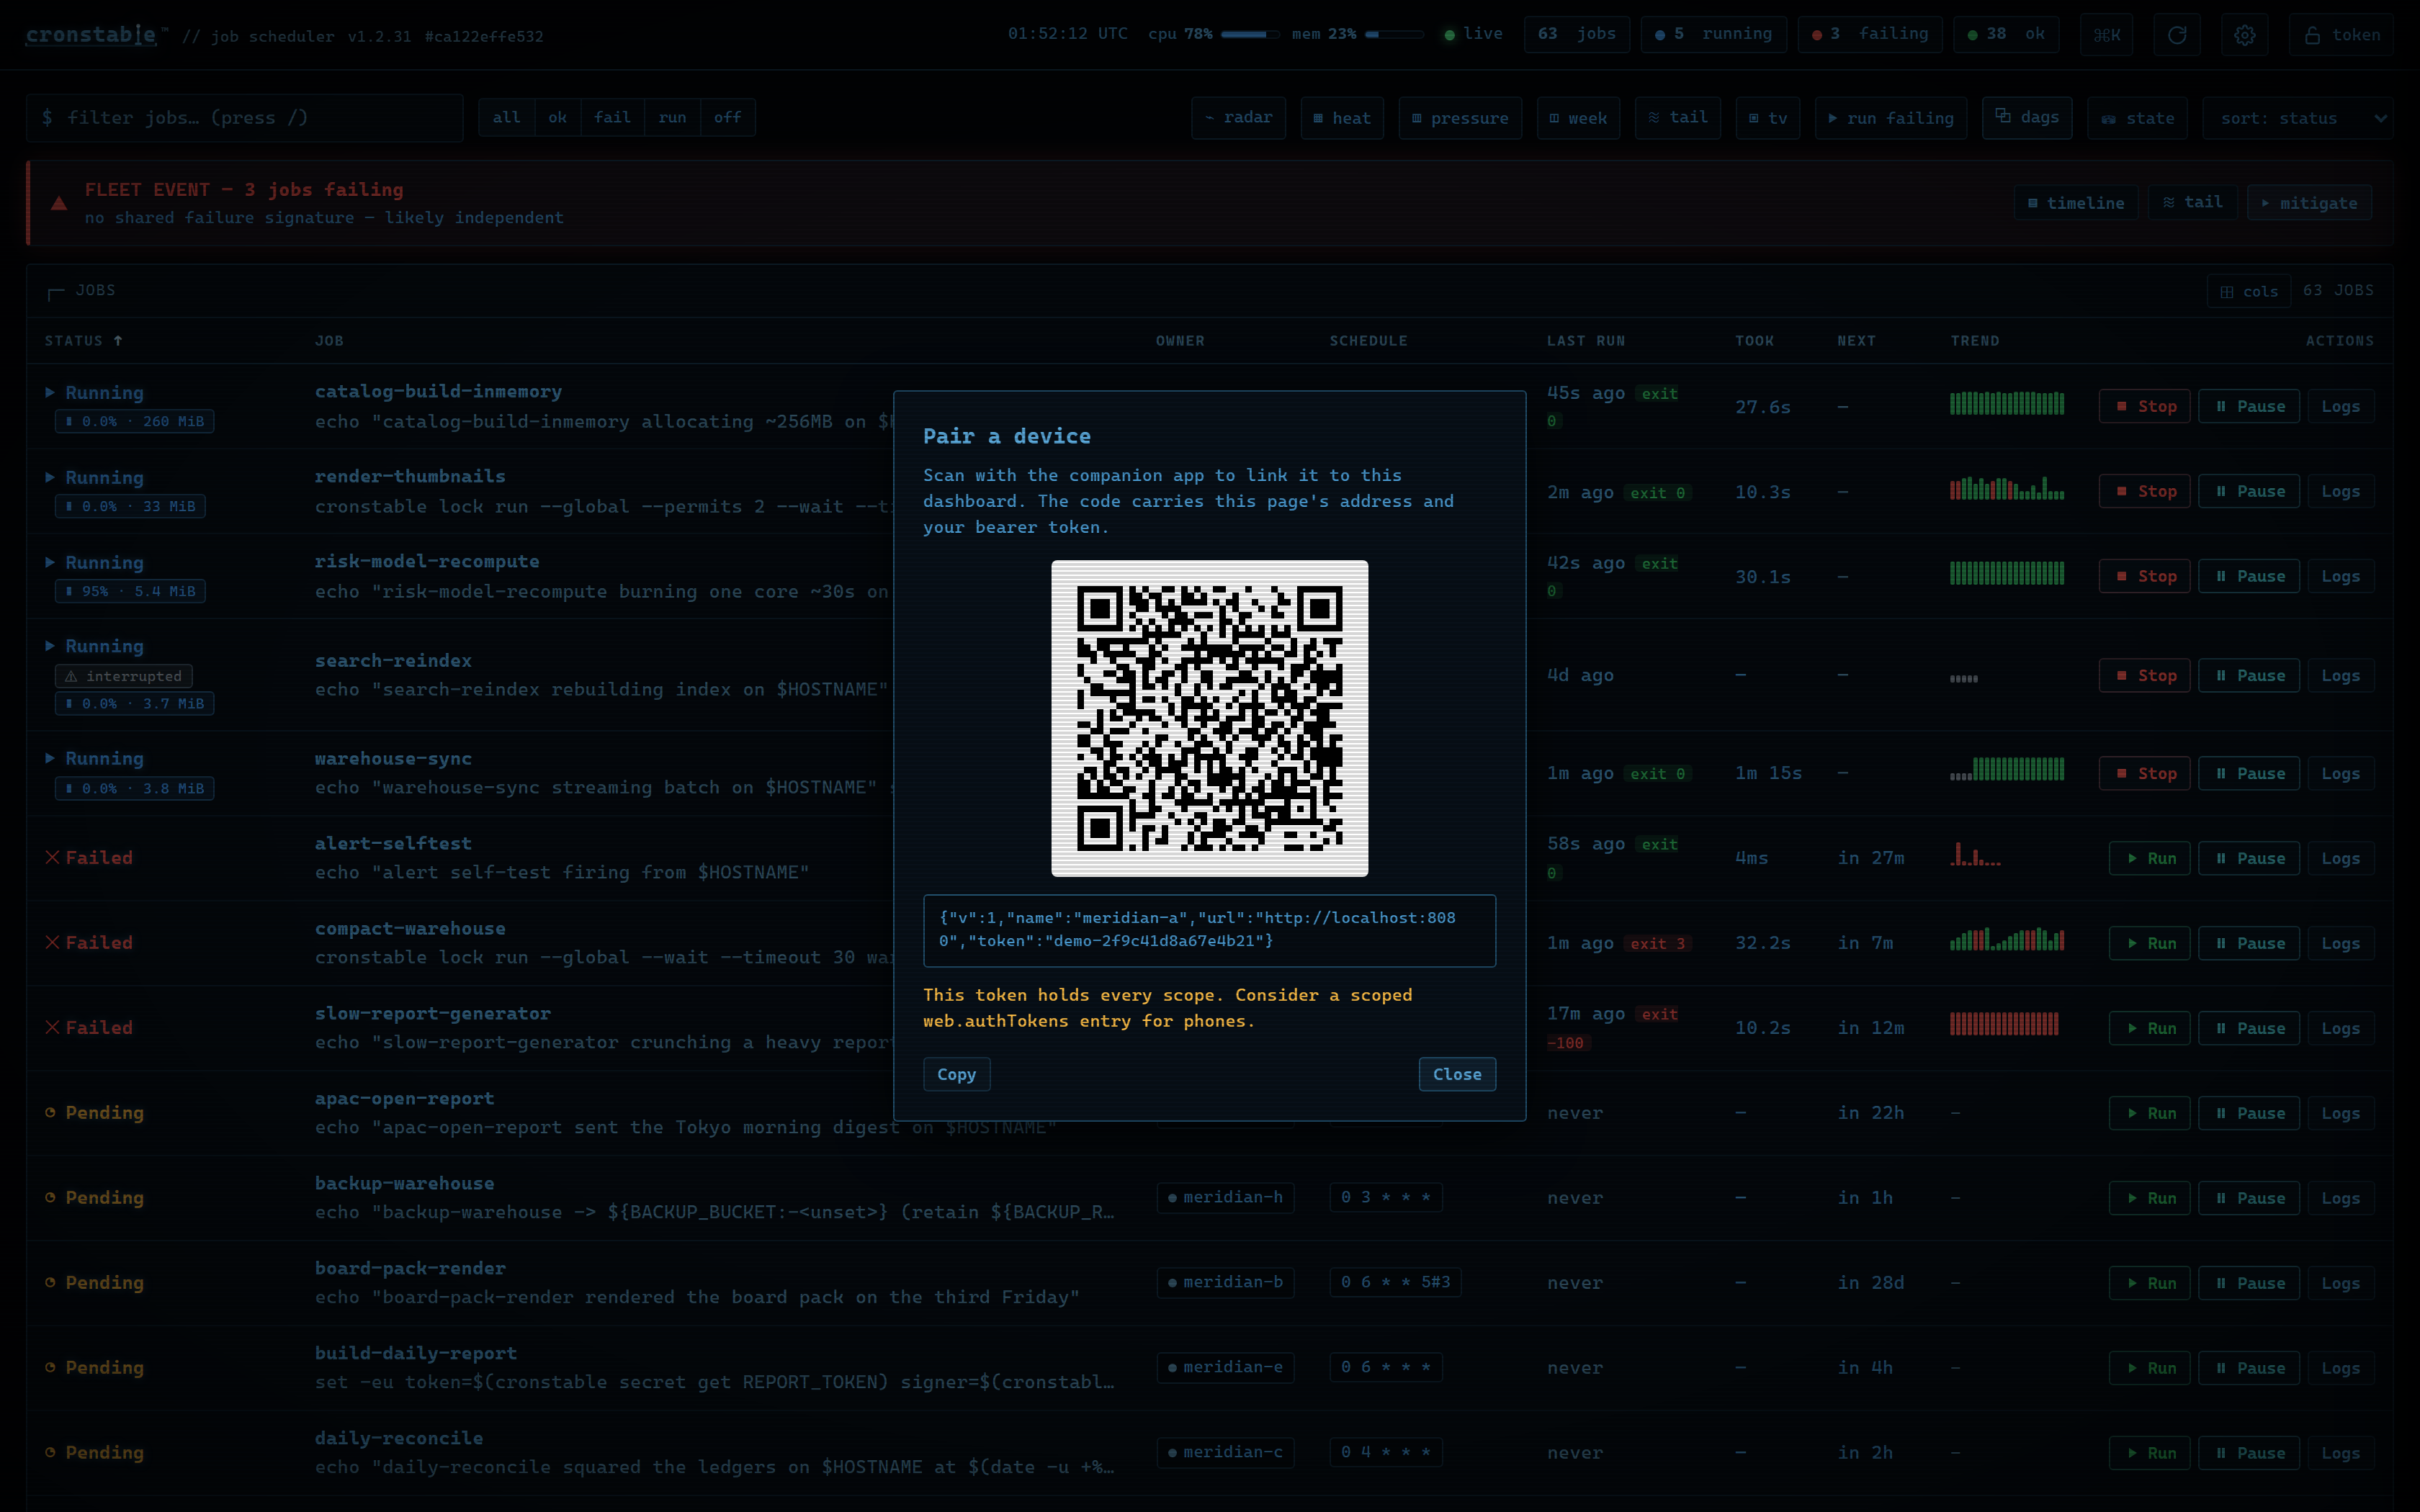
Pair a device from the dashboard, with Pair a device in the command palette or settings. The QR is a deep link, so a phone-camera scan opens the companion app, or a landing page with install pointers when the app is missing. Or pair with one call:
curl -X POST -H "Authorization: Bearer $TOKEN" -H "Content-Type: application/json" \
    -d '{"name": "my-iphone", "platform": "ios", "publicKey": "<base64 X25519 key>", "pushToken": "<device push token>"}' \
    http://127.0.0.1:8080/push/devices
Setting web.bonjour: true (with the discovery extra installed)
additionally advertises the web API as a _cronstable._tcp mDNS service on
the local network, so a companion app finds the daemon without a typed URL.
See LAN discovery
in the wiki.
See push notifications in the wiki for the report options, pairing and revocation, storage, size limits, and the relay trust model.
Windows Event Log
On Windows, the eventlog reporter writes each outcome to the Event Log,
where a Windows shop's monitoring already looks: Event Viewer, a Windows
Event Forwarding subscription, SCOM, and every SIEM connector. It needs no
extra and no dependency, and each record carries a stable event ID plus a
fixed set of insertion strings, so a rule written against it keeps working:
defaults:
  onFailure:
    report:
      eventlog:
        enabled: true
Get-WinEvent -FilterHashtable @{ LogName = 'Application'; ProviderName = 'cronstable'; ID = 1001, 1002 }
Jobs use event IDs 1000 (succeeded), 1001 (failed), 1002 (failed
permanently) and 1003 (overdue). Daemon and orchestration events use 1010
and 1011. cronstable does not register its event source, so Event Viewer
prefixes the rendered text with its generic "description cannot be found"
note. The provider, ID, level and every insertion string are unaffected, so
the XML view, wevtutil, forwarding and SIEM connectors read the record
normally. On any other platform the reporter does nothing, and the config
load says so once.
See Windows Event Log in the wiki for the full ID and field tables, the optional source registration, and the reasons behind both defaults.
Metrics
The daemon exposes built-in Prometheus metrics whenever the HTTP REST API is enabled, with no exporter sidecar needed:
web:
  listen:
    - http://127.0.0.1:8080
GET /metrics then serves job run outcomes, duration histograms, retries,
next-run times, config-reload health, and cluster/leader-election state, in
both the Prometheus text format and OpenMetrics. See
metrics with Prometheus
for the full metric reference, scrape configuration, and example alert rules.
The daemon also has built-in support for pushing per-job metrics to statsd:
jobs:
  - name: test01
    command: echo "hello"
    schedule: "* * * * *"
    statsd:
      host: my-statsd.example.com
      port: 8125
      prefix: my.cron.jobs.prefix.test01
With this config, cronstable writes the following metrics over UDP
to the statsd listening on my-statsd.example.com:8125:
my.cron.jobs.prefix.test01.start:1|g  # this one is sent when the job starts
my.cron.jobs.prefix.test01.stop:1|g   # the rest are sent when the job stops
my.cron.jobs.prefix.test01.success:1|g
my.cron.jobs.prefix.test01.duration:3|ms
Resource monitoring
To find out which cron job is consuming the machine, turn on per-job resource
accounting with a single flag (or once under defaults: for every job):
jobs:
  - name: nightly-model-refresh
    command: python -m models.refresh
    schedule: "0 4 * * *"
    monitorResources: true
While the job runs, cronstable samples its whole process tree (children and shell-outs included) with psutil, and the run ends with its total CPU time (user + system) and peak resident memory. The numbers surface everywhere the run does:
- live on the dashboard job row and drawer while it runs (
cpu 61% · 288 MiB); - per run and aggregated (avg/max CPU, peak memory) in the dashboard
History tab and
GET /jobs/{name}/runs; - as CPU/memory charts in the dashboard's Resources tab (a live
view of the running instance, the recorded profile of any recent run, and
per-run trend strips), plus a node-wide history chart behind the header
meter (
GET /jobs/{name}/resources,GET /node/history); - as Prometheus families on
GET /metrics(cronstable_job_cpu_seconds_total,cronstable_job_last_run_max_rss_bytes, ...) and over statsd when the job has a sink; - in the durable run record's
resourcesobject when a state store is configured, so it survives restarts; - in report templates (
cpu_seconds/max_rss_bytes) and the shell reporter's environment (CRONSTABLE_CPU_SECONDS/CRONSTABLE_MAX_RSS_BYTES), so a failure page can say how big the run was when it died.
Resource monitoring is observability only: it never changes a run's verdict. It is off by default, with zero overhead when off. The numbers are sampled, so short-lived runs are approximate, although the long, heavy runs that matter are sampled many times.
The map form tunes the sampling cadence and how many chart points each run
keeps (monitorResources: { interval: 0.5, history: 240 }). Series are
downsampled in place, so even a days-long run stays a few KB. DAG tasks accept
the same flag, and their usage lands in the task record of the dag_run
document. On a cluster, cluster.observability additionally shares each
node's whole-host CPU/memory, so the dashboard's cluster panel and fleet
view show where the load actually is. The full semantics live in the
configuration reference.
Handling failure
By default, cronstable considers a job failed if the process exits nonzero
or writes to standard error (with stderr capturing enabled). The failsWhen
option tunes this per job with four booleans: producesStdout (default
false), producesStderr (default true), nonzeroReturn (default true), and
always (default false).
A retry option inside onFailure retries failing jobs with exponential
backoff, and onPermanentFailure reports only after all retries are
exhausted and cronstable gives up:
- name: test-01
  command: |
    echo "hello" 1>&2
    exit 10
  schedule:
    minute: "*/10"
  captureStderr: true
  onFailure:
    retry:
      maximumRetries: 10
      initialDelay: 1
      maximumDelay: 30
      backoffMultiplier: 2
  onPermanentFailure:
    report:
      mail:
        from: example@foo.com
        to: example@bar.com
        smtpHost: 127.0.0.1
maximumRetries: -1 retries forever, mostly useful with an @reboot
schedule to restart a long-running process when it fails. Retries are
in-memory by default, so a daemon restart forgets an armed retry. With a
state: section configured they survive restarts and resume where they left
off. See
failure detection and retries
and durable state
in the wiki.
Late-run detection (SLA monitoring)
Failure hooks only see runs that happened. An sla: block watches for the
runs that did not: each job can declare up to three independent thresholds,
evaluated once per minute by an in-process monitor. A dedicated onLate
reporting hook fires once when a threshold is breached, and takes the same
report block (mail, Sentry, shell, webhook) as onFailure:
- name: nightly-etl
  command: python -m etl.run
  schedule: "0 4 * * *"
  sla:
    maxTimeSinceSuccessSeconds: 129600   # no success for 36h
    lateAfterSeconds: 900                # a due slot not started within 15min
    maxRuntimeSeconds: 7200              # a run still going after 2h
  onLate:
    report:
      webhook:
        url:
          fromEnvVar: SLACK_WEBHOOK_URL
Breaches latch: one report per breach, not one per minute, with a recovery
log line and no report when the check clears. maxRuntimeSeconds observes and
never stops a run (use executionTimeout to enforce a limit). The monitor
skips paused and disabled jobs, and under leader election only the job's
owning node evaluates, so one breach pages once.
Breaches surface as an OVERDUE badge in both dashboards, an sla object
on GET /jobs, and cronstable_job_late{job_name, check} /
cronstable_job_sla_breaches_total{job_name, check} in the metrics. The
monitor runs inside the daemon and cannot report its own death, so pair it
with an external Prometheus staleness alert. See
late-run detection
in the wiki.
Concurrency
If a job is still running when its next scheduled run is due,
concurrencyPolicy determines what happens:
Allow : allows concurrently running jobs (default)
Forbid : forbids concurrent runs, skipping next run if previous hasn't finished yet
Replace : cancels currently running job and replaces it with a new one
Execution timeout
Set executionTimeout to terminate a job after a specified number of seconds.
This job would take two seconds to complete, but cronstable terminates it
after one:
- name: test-03
  command: |
    echo "starting..."
    sleep 2
    echo "all done."
  schedule:
    minute: "*"
  captureStderr: true
  executionTimeout: 1  # in seconds
killTimeout sets how long cronstable waits for a job to exit gracefully
before forcing termination. On Unix, it sends SIGTERM, waits up to
killTimeout seconds (30 by default), then sends SIGKILL if the process
is still running.
This job ignores SIGTERM, so cronstable sends SIGKILL half a second later:
- name: test-03
  command: |
    trap "echo '(ignoring SIGTERM)'" TERM
    echo "starting..."
    sleep 10
    echo "all done."
  schedule:
    minute: "*"
  captureStderr: true
  executionTimeout: 1
  killTimeout: 0.5
Change to another user/group
You can request that cronstable change to another user, group, or both for a
specific cron job. The field user indicates the user (uid or user name) that
the subprocess must run as. The field group (gid or group name) indicates
the group id. If only user is given, the group defaults to the main group of
that user. Example:
- name: test-03
  command: id
  schedule:
    minute: "*"
  captureStderr: true
  user: www-data
To have permissions to change to another user, cronstable must be running as root.
This feature is POSIX-only (it relies on setuid/setgid). On Windows, a job
with user or group set is rejected with a configuration error; see
Running on Windows.
Working directory
By default a job starts in whatever directory cronstable itself is running in.
workingDirectory names the directory instead. It matters most on Windows,
where an elevated console starts the daemon in the system directory, so every
relative path in a script resolves somewhere unintended. It is the equivalent
of the "Start in" box on a Task Scheduler action.
- name: nightly-import
  command: import.bat
  schedule:
    minute: "0"
    hour: "2"
  workingDirectory: C:\jobs\importer
cronstable expands ~ and ${VAR} and makes the result absolute at config
load. The OS checks that the directory exists at spawn, not at load, so a
missing one fails that one run at launch instead of rejecting the whole
config. You can also set the key in a defaults: block and on a DAG task. See
commands and environment.
Process priority
priority says how a job should be scheduled against everything else on the
machine, in five levels: idle, below-normal, normal, above-normal,
high.
- name: nightly-reindex
  command: reindex.sh
  schedule:
    minute: "0"
    hour: "3"
  priority: idle
On Windows the level becomes the process's priority class at creation. On
POSIX cronstable renices the job's process group right after the spawn
(idle is nice 19, high is nice -10). Descendants inherit a lowered level
on both platforms.
On Windows, child processes do not automatically inherit above-normal or
high priority; they start at NORMAL unless explicitly configured. On POSIX,
cronstable adjusts the whole process group. The default, normal, leaves
the inherited priority unchanged. Raising priority requires privilege on POSIX;
if denied, the job continues at its inherited priority. See
commands and environment.
Remote web/HTTP interface
Enable the HTTP API to control cronstable remotely:
web:
  listen:
     - http://127.0.0.1:8080
     - unix:///tmp/cronstable.sock
With the web interface enabled, cronstable also serves the
web dashboard at the root path (/) of any http://
listener. To expose only the REST API, set ui: false. With web.authToken
set, the dashboard page loads without a token, then prompts for one and
stores it only in that browser tab.
Adding web.anonymousScopes: [view] alongside the tokens turns the same page
into a public read-only board: credential-less requests hold the view scope,
the dashboard skips the prompt and draws view-only chrome, and every mutating
route still requires a token. See
public read-only access
and the
full dashboard tour
in the wiki.
The API covers the daemon (version, status, summary, metrics, job-set ID), jobs (start, cancel, pause and resume, run history, live SSE log tails, resources), schedules (preview, pressure, duplicates, suggest, why), DAGs, the durable state store, push-device pairing, the cluster and fleet views, and an iCal feed of upcoming fires. For example, pausing a job for a two-hour maintenance window (HTTPie shown):
$ http post http://127.0.0.1:8080/jobs/test-02/pause durationSeconds:=7200 note="db migration"
HTTP/1.1 200 OK

{"paused": {"since": "2026-07-19T14:00:00+00:00", "until": "2026-07-19T16:00:00+00:00", "note": "db migration", "by": "api", "channel": "api"}}
Every endpoint, with request and response shapes, is documented in the HTTP API reference in the wiki. The repo also ships a machine-readable OpenAPI specification.
Serving the API over TLS
web.listen also accepts https:// addresses, served from a web.tls block.
Each entry keeps its own transport, so one runner can serve the same API and
dashboard in plaintext on loopback and over TLS on a routable interface.
unix:// listeners are always plaintext, where the socket's own permissions
(socketMode) are the access control.
web:
  listen:
     - http://127.0.0.1:8080                      # loopback, plaintext
     - https://0.0.0.0:8443                       # served with the material below
  tls:
    cert: /etc/cronstable/web.pem
    key:  /etc/cronstable/web.key
    clientCa: /etc/cronstable/callers-ca.pem      # optional: require client certs
Set clientCa to require mutual TLS, which authenticates clients as well as
encrypting connections. Web certificates rotate in place without a daemon
restart. The clients (cronstable tui, cronstable mcp) take matching
--cacert / --client-cert / --client-key / --insecure flags.
The rest is covered in depth in the
listener TLS
guide in the wiki: issuing the certificates, the mTLS trust model and how it
interacts with web.authToken, the rotation mechanics and what they do not
cover, the job state API's trust anchor, and the full client flag surface.
Job-set ID
The job-set ID is an order-independent fingerprint of the set of jobs a cronstable instance is running. Two instances produce the same id if and only if they hold the same set of jobs, which lets several replicas deployed from the same configuration confirm they are running the same jobs, or detect that one has drifted from the others.
The id is taken over the effective (post-merge) configuration of every job, which gives it some useful properties:
- it is independent of job order, and of whether a setting was written
inline on each job or hoisted into a
defaultsblock; - equivalent schedule spellings match: the
minute:/hour:object form fingerprints the same as the equivalent five-field crontab string; - it covers every behavior-affecting field (
command,schedule,shell, the names ofenvironmentvariables, capture flags,failsWhen, retry/reporting policy,timezone,enabled, and other behavior-affecting fields), so any meaningful change to a job changes the id. It deliberately leaves out per-host values,workingDirectoryamong them, so a Windows replica and a Linux one running the same jobs from paths they spell differently still agree; user/groupare fingerprinted as configured (www-data, for example), not as the resolved numeric uid/gid, which can differ host to host;- secret/value material is never embedded: inline reporting secrets
(Sentry DSN, mail password, webhook URL and header values) are redacted,
and only the names of
environmentvariables are hashed, not their values (env commonly holds secrets, and a per-host value, such as one fromenv_file, would otherwise make identical configs differ across hosts). The id is safe to log and serve, and rotating a secret or changing an env value does not change it.
Because it reflects effective config, it also reflects platform-dependent
defaults (the default shell is /bin/sh on POSIX, cmd.exe on Windows), so
compare instances running on the same platform, which replicas are. The scheme
is versioned with a v1: prefix, and ids are only comparable within a scheme
version.
It is available three ways:
-
CLI: print it and exit (useful in scripts and health checks):
$ cronstable -c /etc/cronstable.d --job-set-id
v1:b834d7565aee0da50cd017f666651a5ba3b2e6b161daf0cb6e430f23f51ce90b
-
HTTP:
GET /job-set-idon the web interface (alsoapplication/json), and shown in the dashboard header:$ http get http://127.0.0.1:8080/job-set-id v1:b834d7565aee0da50cd017f666651a5ba3b2e6b161daf0cb6e430f23f51ce90b $ http get http://127.0.0.1:8080/job-set-id Accept:application/json {"job_set_id": "v1:b834d7…51ce90b", "jobs": 3}
-
Logs: it is logged once at startup, and again whenever a config reload changes it.
Clustering and leader election
By default cronstable runs as a single instance and every replica runs every job.
An optional cluster section lets several replicas coordinate: each node serves
a small GET /peer endpoint over mutual TLS and periodically polls its
configured peers, comparing job-set IDs so they can confirm they
are running the same set of jobs (cluster peer attestation). Turning on
electLeader promotes that same attestation into a quorum-gated leader
election, so you can run more than one replica from one config without
double-running scheduled jobs:
cluster:
  listen: "0.0.0.0:8443"          # the mTLS listener for this node
  tls:
    ca:   /etc/cronstable/cluster-ca.pem   # trust anchor for peer certificates
    cert: /etc/cronstable/this-node.pem    # this node's certificate
    key:  /etc/cronstable/this-node.key
  peers:
    - host: cronstable-b.internal:8443
    - host: cronstable-c.internal:8443
  nodeName: cronstable-a              # optional; defaults to the system hostname
  interval: 30                    # optional; seconds per round (default 30)
  connectTimeout: 10              # optional; per-peer connect timeout (default 10)
  driftAfter: 3                   # optional; rounds before "drifted" (default 3)
  electLeader: true               # observe-only if false (the default)
Each node independently elects, as leader, the lowest nodeName among the
members it currently sees agreeing on the job-set ID, but only if that set is a
quorum (a strict majority) of the cluster, so under a clean partition at
most one side leads. This is best-effort, because the default gossip backend
keeps no shared state. For a fenced, exactly-once guarantee, set
cluster.backend: kubernetes or cluster.backend: etcd to elect through a
coordination.k8s.io/v1 Lease or a lease-bound etcd key instead.
Each job can override the cluster-wide default with a per-job clusterPolicy
(Leader, the default, may skip under a partition; PreferLeader never
skips but may double-run; EveryNode runs everywhere), picking its own
point on the liveness-vs-duplication trade-off.
The current view (members, elected leader, quorum, and any conflicts) is
available at GET /cluster and shown as a panel in the dashboard. The full
trust model, per-peer status table, quorum math, sizing guidance,
distribution: spread load-balancing, and the fenced lease backends are all
covered in depth in the
clustering and leader election
guide in the wiki. Try a cluster from the example gallery
to watch leader election in the dashboard.
Includes
Use include to share defaults and other configuration across files. It
accepts a list of filenames, which cronstable parses and merges into the
current configuration.
For example, the main configuration:
include:
  - _inc.yaml

jobs:

  - name: my job
    ...
And the shared defaults in _inc.yaml:
defaults:
  shell: /bin/bash
  onPermanentFailure:
    report:
      sentry:
        ...
Environment variable interpolation
Any string value in the config can pull from cronstable's environment with
${VAR}, or ${VAR:-default} for a fallback, so one config file serves many
environments without a wrapper script templating it. Write $$ for a literal
$.
Interpolation runs after the file is validated, so it reaches any string-typed
field (a listen address, a state path, a time zone, a webhook URL). A ${VAR}
that is unset and has no default is a hard configuration error that names the
variable, caught by cronstable --validate-config.
web:
  listen:
    - "0.0.0.0:${WEB_PORT:-8080}"   # port from the environment, default 8080
state:
  path: ${STATE_DIR}               # required: unset fails --validate-config
jobs:
  - name: rollup-${REGION}
    command: run-rollup             # ${VAR} in a command is left for the shell
    schedule:
      minute: "0"
    timezone: ${TZ:-UTC}
The daemon deliberately leaves a job's (and reporter's) command and shell
untouched, so the runtime shell expands their ${VAR} against the job's own
environment, not the daemon's. The logging section is likewise left for
Python's logging.config. See
environment-variable interpolation
for the full rules, including how it affects the job-set ID.
Custom logging
You can provide a custom logging configuration with the logging
configuration section. For example, the following configuration displays log
lines with an embedded timestamp for each message.
logging:
  # In the format of:
  # https://docs.python.org/3/library/logging.config.html#dictionary-schema-details
  version: 1
  disable_existing_loggers: false
  formatters:
    simple:
      format: '%(asctime)s [%(processName)s/%(threadName)s] %(levelname)s (%(name)s): %(message)s'
      datefmt: '%Y-%m-%d %H:%M:%S'
  handlers:
    console:
      class: logging.StreamHandler
      level: DEBUG
      formatter: simple
      stream: ext://sys.stdout
  root:
    level: INFO
    handlers:
      - console
Obscure configuration options
enabled: true|false (default true)
You can disable a specific cron job by adding an enabled: false
option. Jobs with enabled: false are skipped, as if they aren't there, apart
from validating the configuration.
jobs:
  - name: test-01
    enabled: false  # this cron job will not run until you change this to `true`
    command: echo "foobar"
    shell: /bin/bash
    schedule: "* * * * *"
Documentation map
Every feature has its own page in the wiki. The sidebar there is the full index. Good starting points: Installation, the Configuration Reference, the Web Dashboard tour, and Troubleshooting.
Contributing and license
Bug reports, feature ideas, and pull requests are welcome; see CONTRIBUTING.md for the development setup, how to sign off your commits (DCO), and Contributing and Releasing for how releases work. cronstable is MIT-licensed; see LICENSING.md for how the repository's licensing is organized.
Security. Report vulnerabilities privately rather than in a public issue; SECURITY.md has the disclosure process, what is in scope (including the hosted relay and the public demo), and what to expect.
Trademarks. The MIT License covers the code, not the brand. cronstable™ and the cronstable logo are trademarks of Parker Loflin; see TRADEMARKS.md. The rendered logo artwork is also reserved rather than MIT-granted, while the code that draws it stays MIT; see Brand assets.
cronstable is a fork of yacron (by Gustavo Carneiro), continuing development from version 0.19.
1 maintainer

Release files for cronstable 1.2.54
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| cronstable-1.2.54.tar.gz | 3.5 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cronstable-1.2.54-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 4.7 MB
Release files / cronstable-1.2.54.tar.gz
| Download URL | cronstable-1.2.54.tar.gz |
|---|---|
| Size | 3.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
639c3f423e88bf5251c1f40576e369fc634f4e9ba350716c982a00864a2aa561
|
|
BLAKE2b-256 checksum How to use checksums |
db65dfef5b0b17acdc9afea90da4a2824014fdf8f1b89cebd1b4cf67b578177e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 21, 2026.
Transparency logRelease files / cronstable-1.2.54-py3-none-any.whl
| Download URL | cronstable-1.2.54-py3-none-any.whl |
|---|---|
| Size | 1.1 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
87e48fd35f45397ae1049f7ecb9bc527a4e60fb6f65e15d2318e90f5355c1e8f
|
|
BLAKE2b-256 checksum How to use checksums |
25ffd6e193ee45b18cc4be3f09d6c775700ace231d85501b39862b7fc8139e8b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 21, 2026.
Transparency log













