
✂️ CutSeq


CutSeq is a library-aware wrapper for cutadapt. Real NGS libraries need several trimming steps performed in the correct order — encoding them all in one cutadapt command is error-prone, and chaining separate commands wastes I/O. CutSeq fixes this with a single input: what the library looks like. It compiles your library scheme into one native cutadapt pass and runs it automatically.
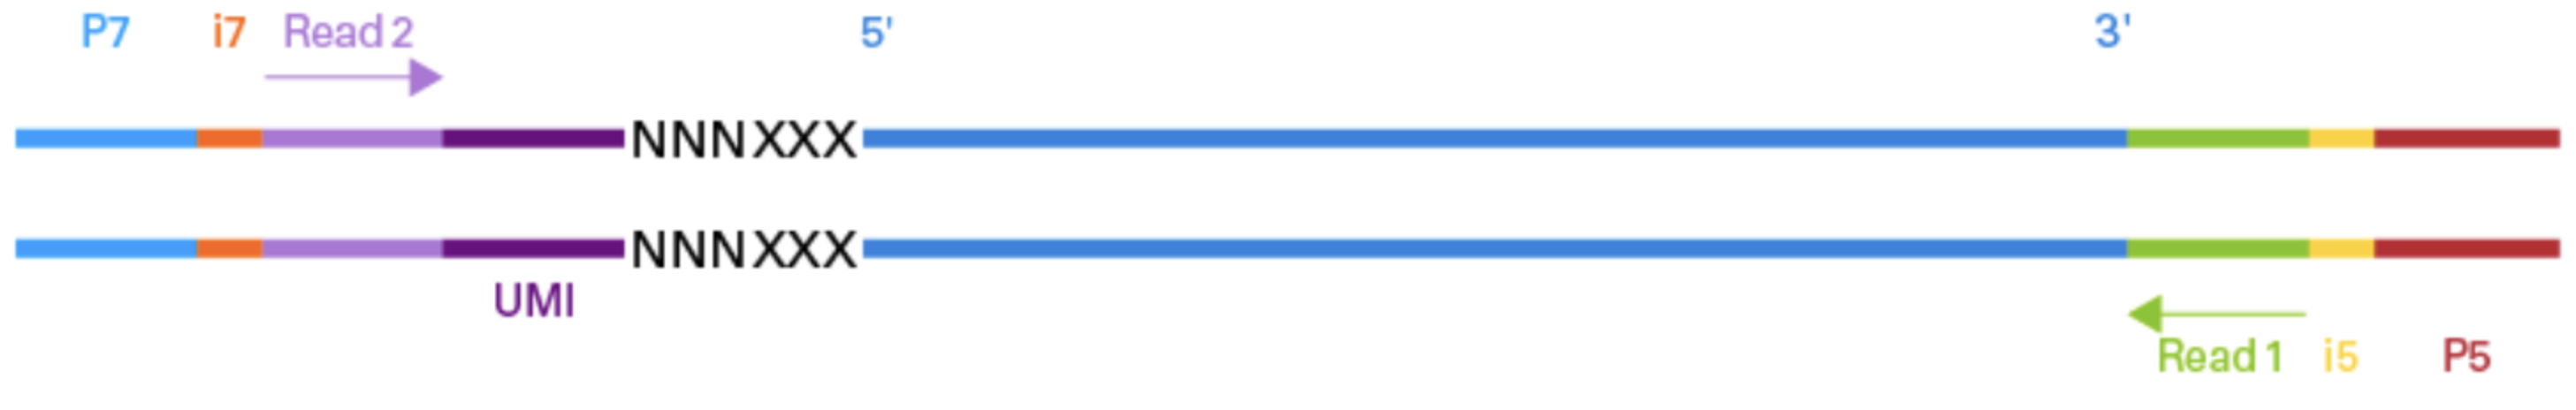
Take SMARTer® Stranded Total RNA-Seq Kit v3 (built-in TAKARAV3) — many
operations in one pass:
| Read | Steps |
|---|---|
| R1 | remove the 5′ p5 adapter + 3-nt linker mask · capture the 8-nt UMI & mask the 6-nt linker at the 3′ end (the 14-nt run-over when insert < read) · remove the 3′ read-through adapter · quality trim |
| R2 | remove the 5′ read-through adapter · extract the 8-nt UMI into the read name · mask the 6-nt linker right after it · remove the 3′ read-through adapter · quality trim |
Installation
pip install cutseq
Basic usage
Express the whole library as one scheme and let CutSeq do the rest:
# built-in scheme
cutseq -A TAKARAV3 test_R1.fq.gz test_R2.fq.gz

# or a custom grammar scheme
cutseq -A "ACACGACGCTCTTCCGATCTXXX-XXXXXXNNNNNNNNAGATCGGAAGAGCACACGTC"
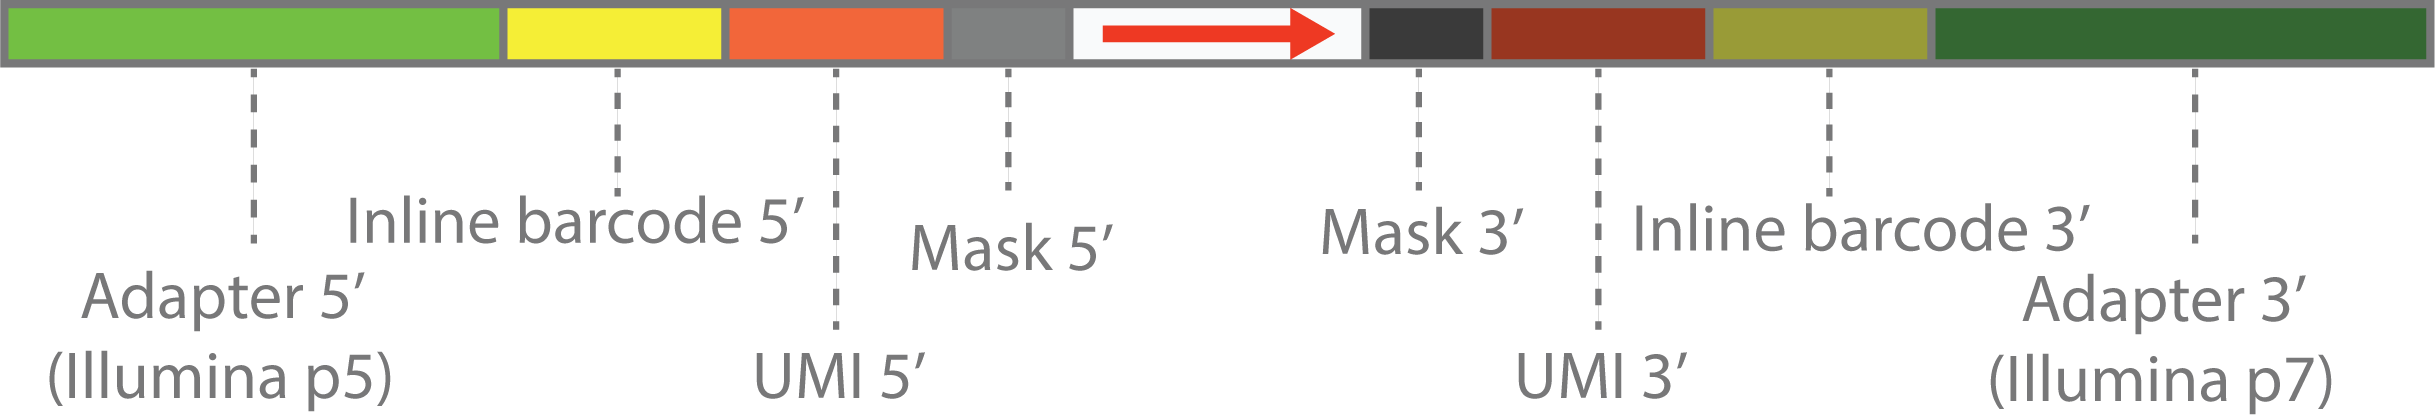
The scheme is a top-strand molecular map: one DNA strand, 5′ → 3′, no spaces:
- The part left of the insert marker (
+-:) is read by R1 as-is; the part right of it is the molecule's 3′ continuation and is matched on R2 as its reverse complement automatically (e.g. a right-handAGATCGGAAGAGCACACGTCis matched on R2 asGACGTGTGCTCTTCCGATCT). += sense,-= antisense,:= unstranded.- Uppercase
ACGT…= adapters/primers, trimmed. N= random UMI, captured into the read name (NNNNNNNN/N8).X= masked sequence, trimmed but not captured (XXXXXX/X6).- Lowercase
acgt…= inline barcode, matched and captured. - Homopolymer tails use the dot form
AAA...AAA/TTT...TTT/GGG...GGG; the 5′/3′ direction is auto-detected from the scheme layout (a run at the read start trims the 5′, elsewhere the 3′), andG<k>sets the minimum run length (e.g.G10). - A 3′ read-through adapter (from the other read's 5′ arm) is trimmed automatically from the opposite end of each read.
- Numeric shorthand (
N8,X6) equals the expanded run form.
Customizing read names
Captured UMIs/barcodes are appended to the read name with _ by default
(@READID_CTATTAAAAA, exactly like legacy output). By default every
captured segment — each N UMI plus each inline (lowercase) barcode, across
both arms — is concatenated in scheme written order (left / R1-arm parts
first, then right / R2-arm parts). If any required capture is missing or
incomplete the whole appended suffix is dropped (@READID_, the legacy
single-capture contract); a partial barcode is never silently padded. Use
--rename for full control — cutadapt's brace variables ({id}, {header},
{cut_prefix}, {match_sequence}, {rc}, …) plus positional captures
{1}, {2}, … in scheme order:
cutseq -A INLINE --rename '{id}_BC1:{1}_BC2:{2}_umi:rc({3})' in_R1.fq.gz in_R2.fq.gz
Transform functions wrap any capture and nest (case-insensitive):
rc(x)/rev(x)/comp(x)— reverse complement / reverse / complementupper(x),lower(x),len(x)canon(x)— canonical UMI,min(x, rc(x)), for UMI collapsingleft(x,k),right(x,k),slice(x,a,b)— substring helpers
In paired mode {r1.1} / {r2.1} force a specific read; an unprefixed capture
resolves to its anchor read (left-side captures → R1, right-side → R2), so
both mates carry the same value. Unlike an explicit --rename template (whose
missing references are just empty for that slot), the default is all-or-nothing:
it only emits the combined capture suffix when every required capture is
complete on its anchor read, otherwise it emits just the read id. Explicit
label: names must be unique across the whole scheme — a duplicate (or an
auto barcode{n} that collides with an explicit label) is rejected with an
actionable error rather than silently overwritten.
Complex example: spatial barcode arm (DBiT-seq)
Spatial libraries stack several fixed-length barcodes on one arm. In
DBiT-seq (deterministic barcoding in tissue, 50×50 grid) R2 walks
handle(22) | BarcodeB(8) | linker(30) | BarcodeA(8) | linker(30) | UMI(12) | polyT | cDNA, while R1 carries the insert with a template-switch oligo (TSO).
Everything fits in one command:
cutseq -A DBITSEQ \
  -R '{id}_BCB:{3}_BCA:{2}_UMI:{1}' \
  -O mysample R1.fq.gz R2.fq.gz
Built-in DBITSEQ scheme:
AAGCAGTGGTATCAACGCAGAGTGAATGGG...GGG : N12 AGTCGTACGCCGATGCGAAACATCGGCCAC
                                           N8  CGAATGCTCTGGCCTCTCAAGCACGTGGAT
                                           N8  AGATGCGAGAAGCCAACGCTTG
- Left of
:= R1's real read-5′ scaffold: the TSO (23 nt) then an auto-detected 5′ G-stretch (GAATGGG...GGG), both trimmed. - Right of
:= the barcode arm, walked on R2: UMIN12→ capture{1}, linker trimmed, BarcodeAN8→ capture{2}, linker trimmed, BarcodeBN8→ capture{3}, handle trimmed. The-Rtemplate writes@READID_BCB:…_BCA:…_UMI:…. M6AARTRis kept as a deprecated alias.--r1-primer/--r2-primerare informational only — reads start downstream of the priming site, so the sequencing primers are never trimmed.
The same library as a fully inline scheme:
cutseq -A "AAGCAGTGGTATCAACGCAGAGTGAATGGG...GGG:N12AGTCGTACGCCGATGCGAAACATCGGCCACN8CGAATGCTCTGGCCTCTCAAGCACGTGGATN8AGATGCGAGAAGCCAACGCTTG" \
  -R '{id}_BCB:{3}_BCA:{2}_UMI:{1}' -O mysample R1.fq.gz R2.fq.gz
Full construct, top strand 5′ → 3′:
P5(29) | i5(8) | R1-primer(34) | TSO(23) | insert | polyA/T | UMI(12)
| rc(L1)(30) | BarcodeA(8) | rc(L2)(30) | BarcodeB(8) | rc(handle)(22)
| rc(R2-primer)(34) | i7(8) | rc(P7)(24)
Inline-barcode auto-detection
If an uppercase barcode is written next to a sequencing primer, the engine
checks the scheme's two outermost adapters against a curated database of
Illumina / BGI primers (cutseq --list-primers); a fixed uppercase run
adjacent to a recognized primer is reclassified as an inline barcode (with a
warning). Custom schemes without known primers are never altered. Disable with
--no-auto-inline.
Discarding reads with a reason
A single -d output collects every rejected read, with the reason encoded in
the name:
cutseq -A SMALLRNA -d discarded_R1.fq.gz discarded_R2.fq.gz in_R1.fq.gz in_R2.fq.gz
| Tag | Why |
|---|---|
reason=too_short |
shorter than --min-length after trimming |
reason=too_many_n |
exceeds --max-n |
reason=low_quality |
mean Phred below --min-avg-quality |
reason=no_barcode |
missing an inline barcode (with --ensure-inline-barcode) |
Without -d/-O, discard files are auto-named from the input files.
How it works
CutSeq compiles a scheme once into a lazy graph of native cutadapt modifiers (adapter cutters, renamers, quality trimmers) and runs them in a single cutadapt pass — no intermediate I/O. Each grammar token maps to a 5′/3′/ single-end emitter, and output is verified to match the legacy engine exactly across all built-in schemes, paired- and single-end.
More details: https://cutseq.yech.science
Primer-boundary read plans (recognised sequencing sites)
When a library's outer adapters are genuine sequencing-primer binding sites
(e.g. the Illumina read-1 / read-2 primers), CutSeq recognises them as upstream
and ABSENT from the read, so the read starts INSIDE the scheme rather than
containing the primer. Such a scheme is routed through a read plan: R1 begins
downstream of the read-1 site (the first N/X/poly run after it is cut
unconditionally), R2 begins at its read-2 site, and the mirrored read-through
cuts (adapter gate → preceding UMI/masks, poly-T mirrored as an A-run) fire only
when that arm really was sequenced — never because a read happens to be long.
# read-1 site ACACGACGCTCTTCCGATCT is upstream of R1; the read starts at XX2.
# read-2 site AGATCGGAAGAGCACACGTC is upstream of R2; the read starts at the UMI.
cutseq -A 'ACACGACGCTCTTCCGATCTXXT...T-XXXXXXXXNNNNNNNNAGATCGGAAGAGCACACGTC' \
  -R '{id}_umi:{r2.1}' R1.fq.gz R2.fq.gz
A library whose outer adapters are ordinary read-visible scaffolds (e.g. the
legacy DBiT / INLINE schemes) is unchanged: those adapters stay in the read and
are trimmed as normal. The recognised R1/R2 sites are curated (cutseq --list-primers); genuine upstream sites are matched end-directed (R1 by the
primer's 3′ extension end, R2 by the top-strand site's prefix), so a primer that
is ambiguous or missing from the scheme fails actionably. Explicit
--r1-primer / --r2-primer (the actual sequencing oligo 5′→3′, R2 = rc of the
top-strand site) overrides the curated table and lets custom primers be
recognised.
TODO
- support more library schemes
1 maintainer

Metadata
1 maintainer
Release files for cutseq 0.0.73
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| cutseq-0.0.73.tar.gz | 1.8 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| cutseq-0.0.73-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.8 MB
Release files / cutseq-0.0.73.tar.gz
| Download URL | cutseq-0.0.73.tar.gz |
|---|---|
| Size | 1.8 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5ce766340c04bf972321f4d5182099132877c6a0eab9b2f27a46f2ebb99c81a0
|
|
BLAKE2b-256 checksum How to use checksums |
555d6a15f0ba99ecfa765d624b99fbed1be389074374c0fa76362142629e12a4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Release files / cutseq-0.0.73-py3-none-any.whl
| Download URL | cutseq-0.0.73-py3-none-any.whl |
|---|---|
| Size | 66.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0f4155672f3065ce9b37648adefa3c320ea1124ce7b700724782f4d029ed2140
|
|
BLAKE2b-256 checksum How to use checksums |
ac068ae3592aafe2a0bd66ebb63ca6eaf3060656436e969dd0f77ab8645515ec
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|














