
dagster-dataframely
Dataframely validates Polars frames against a schema.
Dagster has two built-in places to show a schema: the Columns tab and asset checks.
dagster-dataframely attaches a Dataframely schema to a Dagster asset, so you declare a table once and Dagster shows it in both places.
import dataframely as dy
import polars as pl

import dagster_dataframely as dd


class Customers(dy.Schema):
    """A storefront customer account."""

    customer_id = dy.String(primary_key=True, description="Account identifier.")
    email = dy.String(nullable=False, description="Where receipts are sent.")
    lifetime_value = dy.Float64(nullable=False, min=0.0, description="Spend to date.")


@dd.asset(Customers)
def customers(raw_customers: pl.DataFrame) -> pl.DataFrame:
    """Validate the storefront's customer accounts."""
    return raw_customers
That is the whole integration.
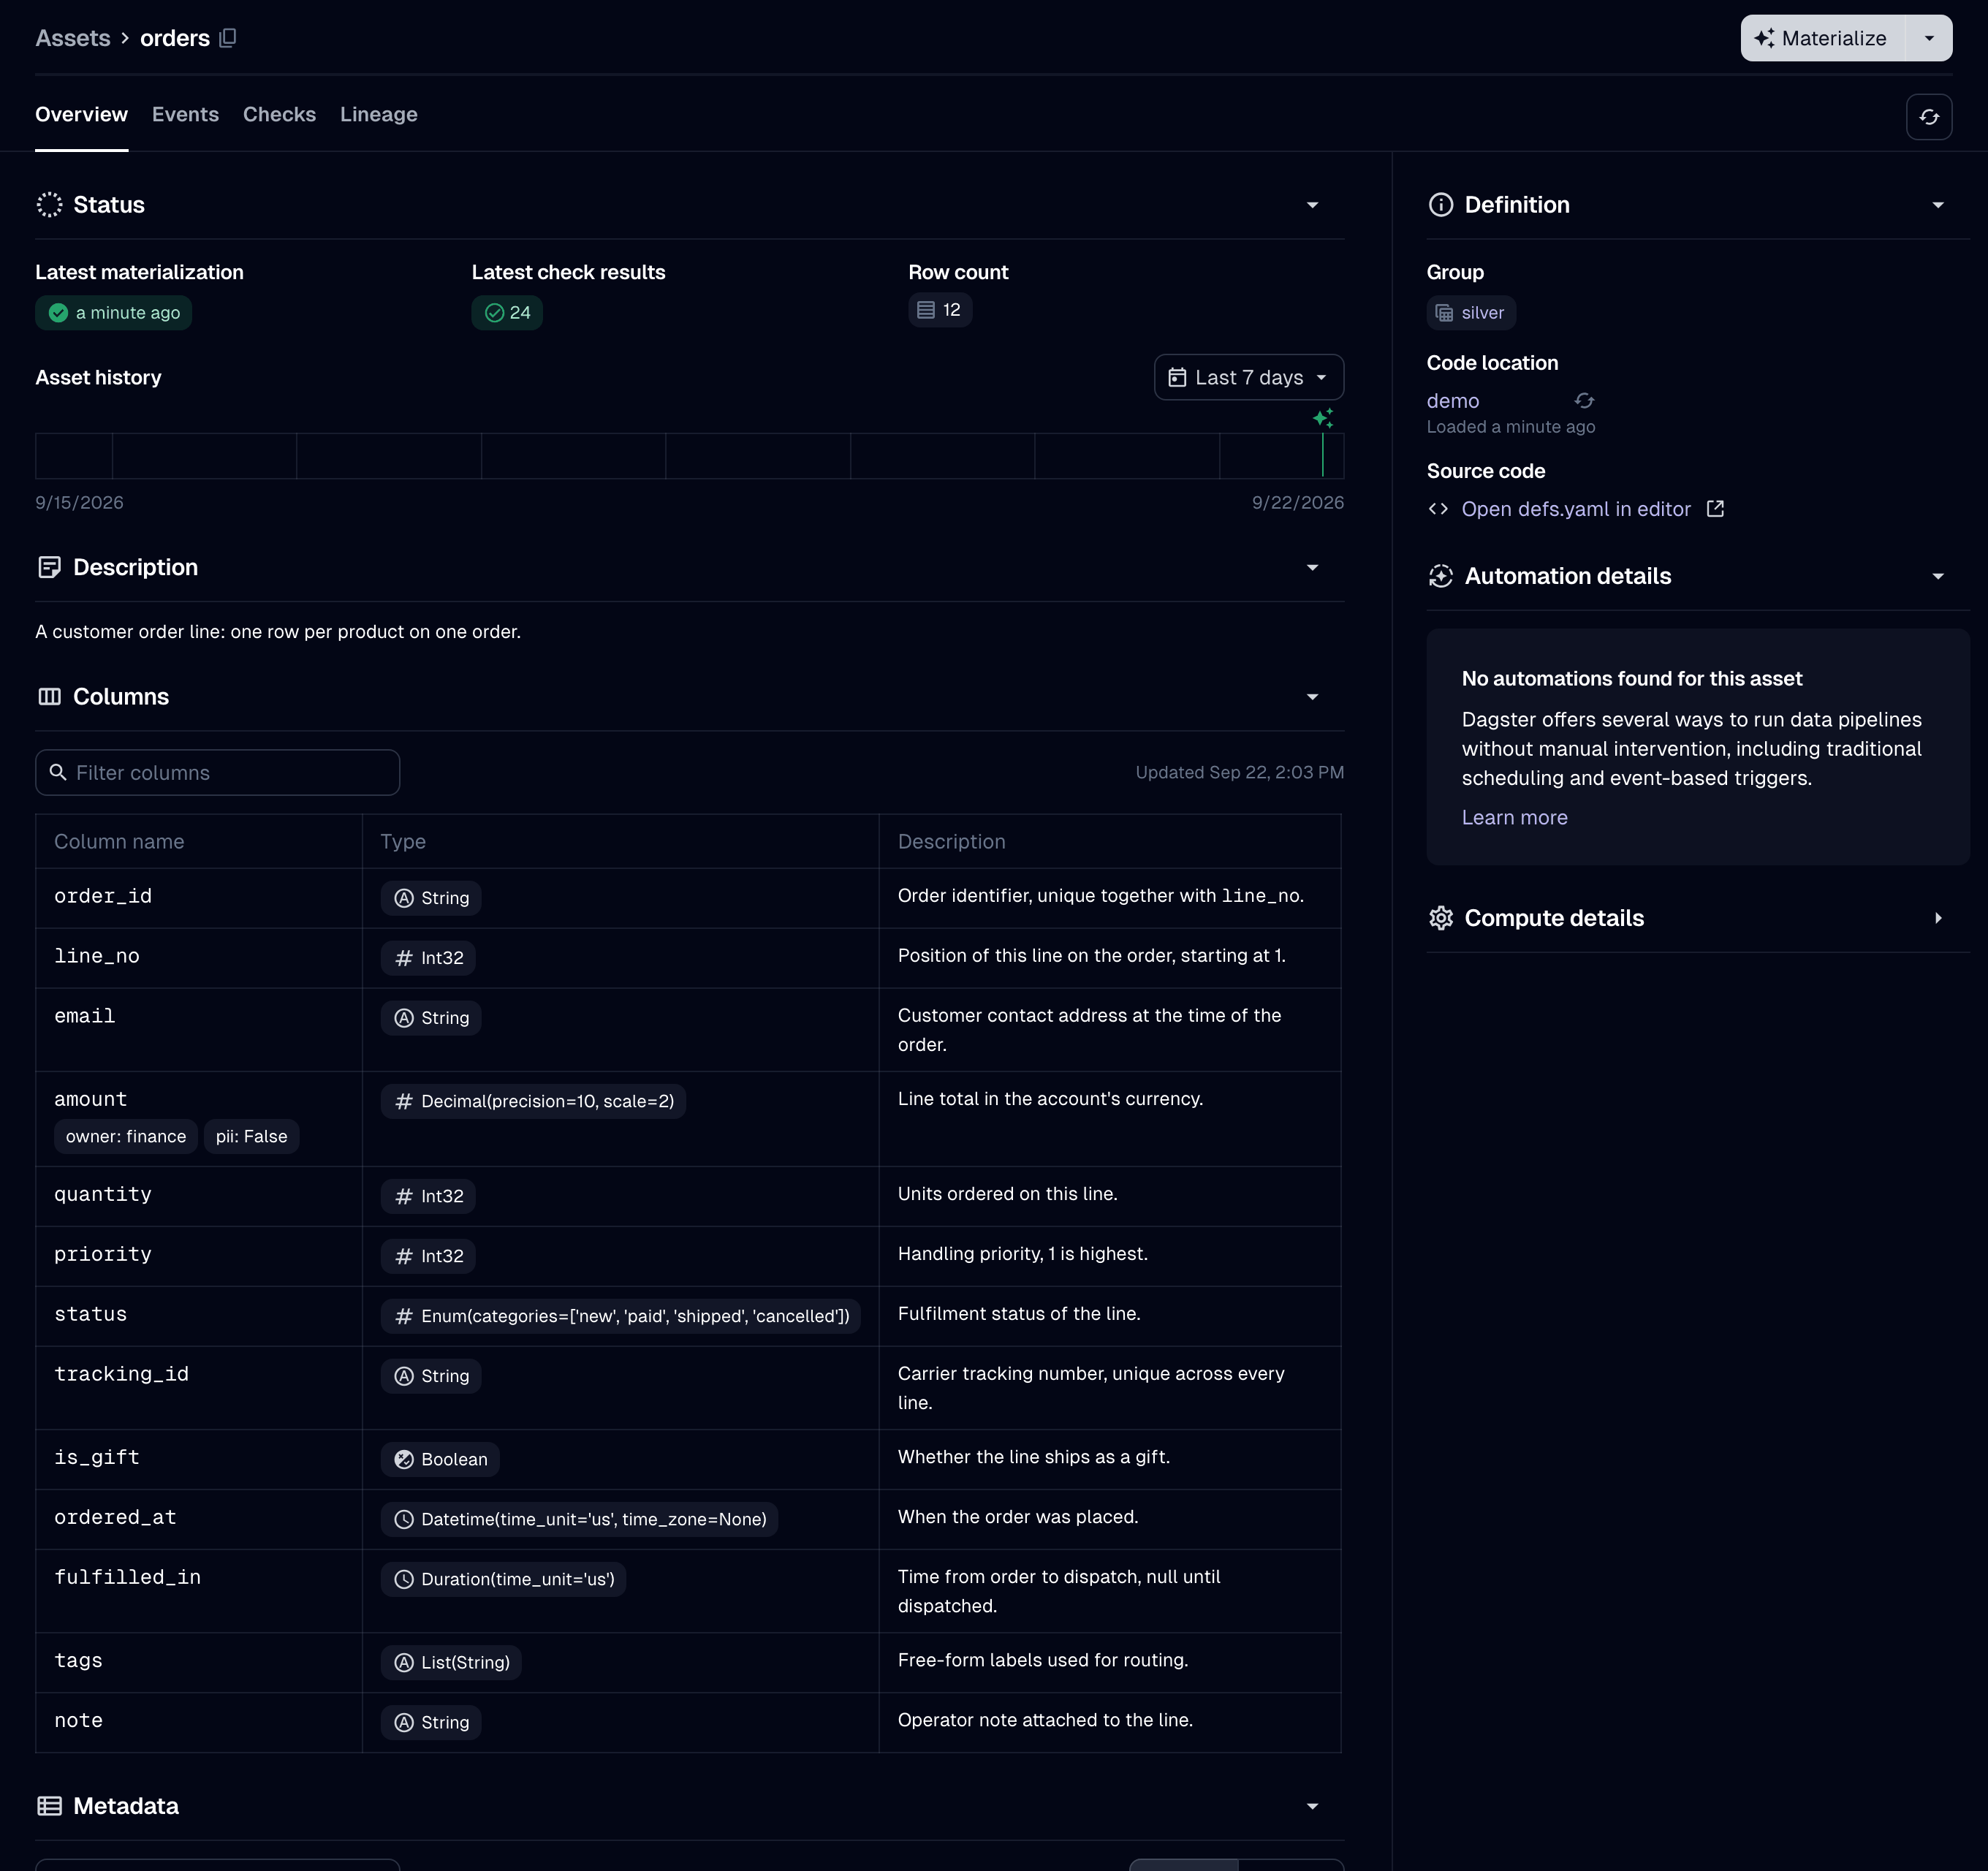
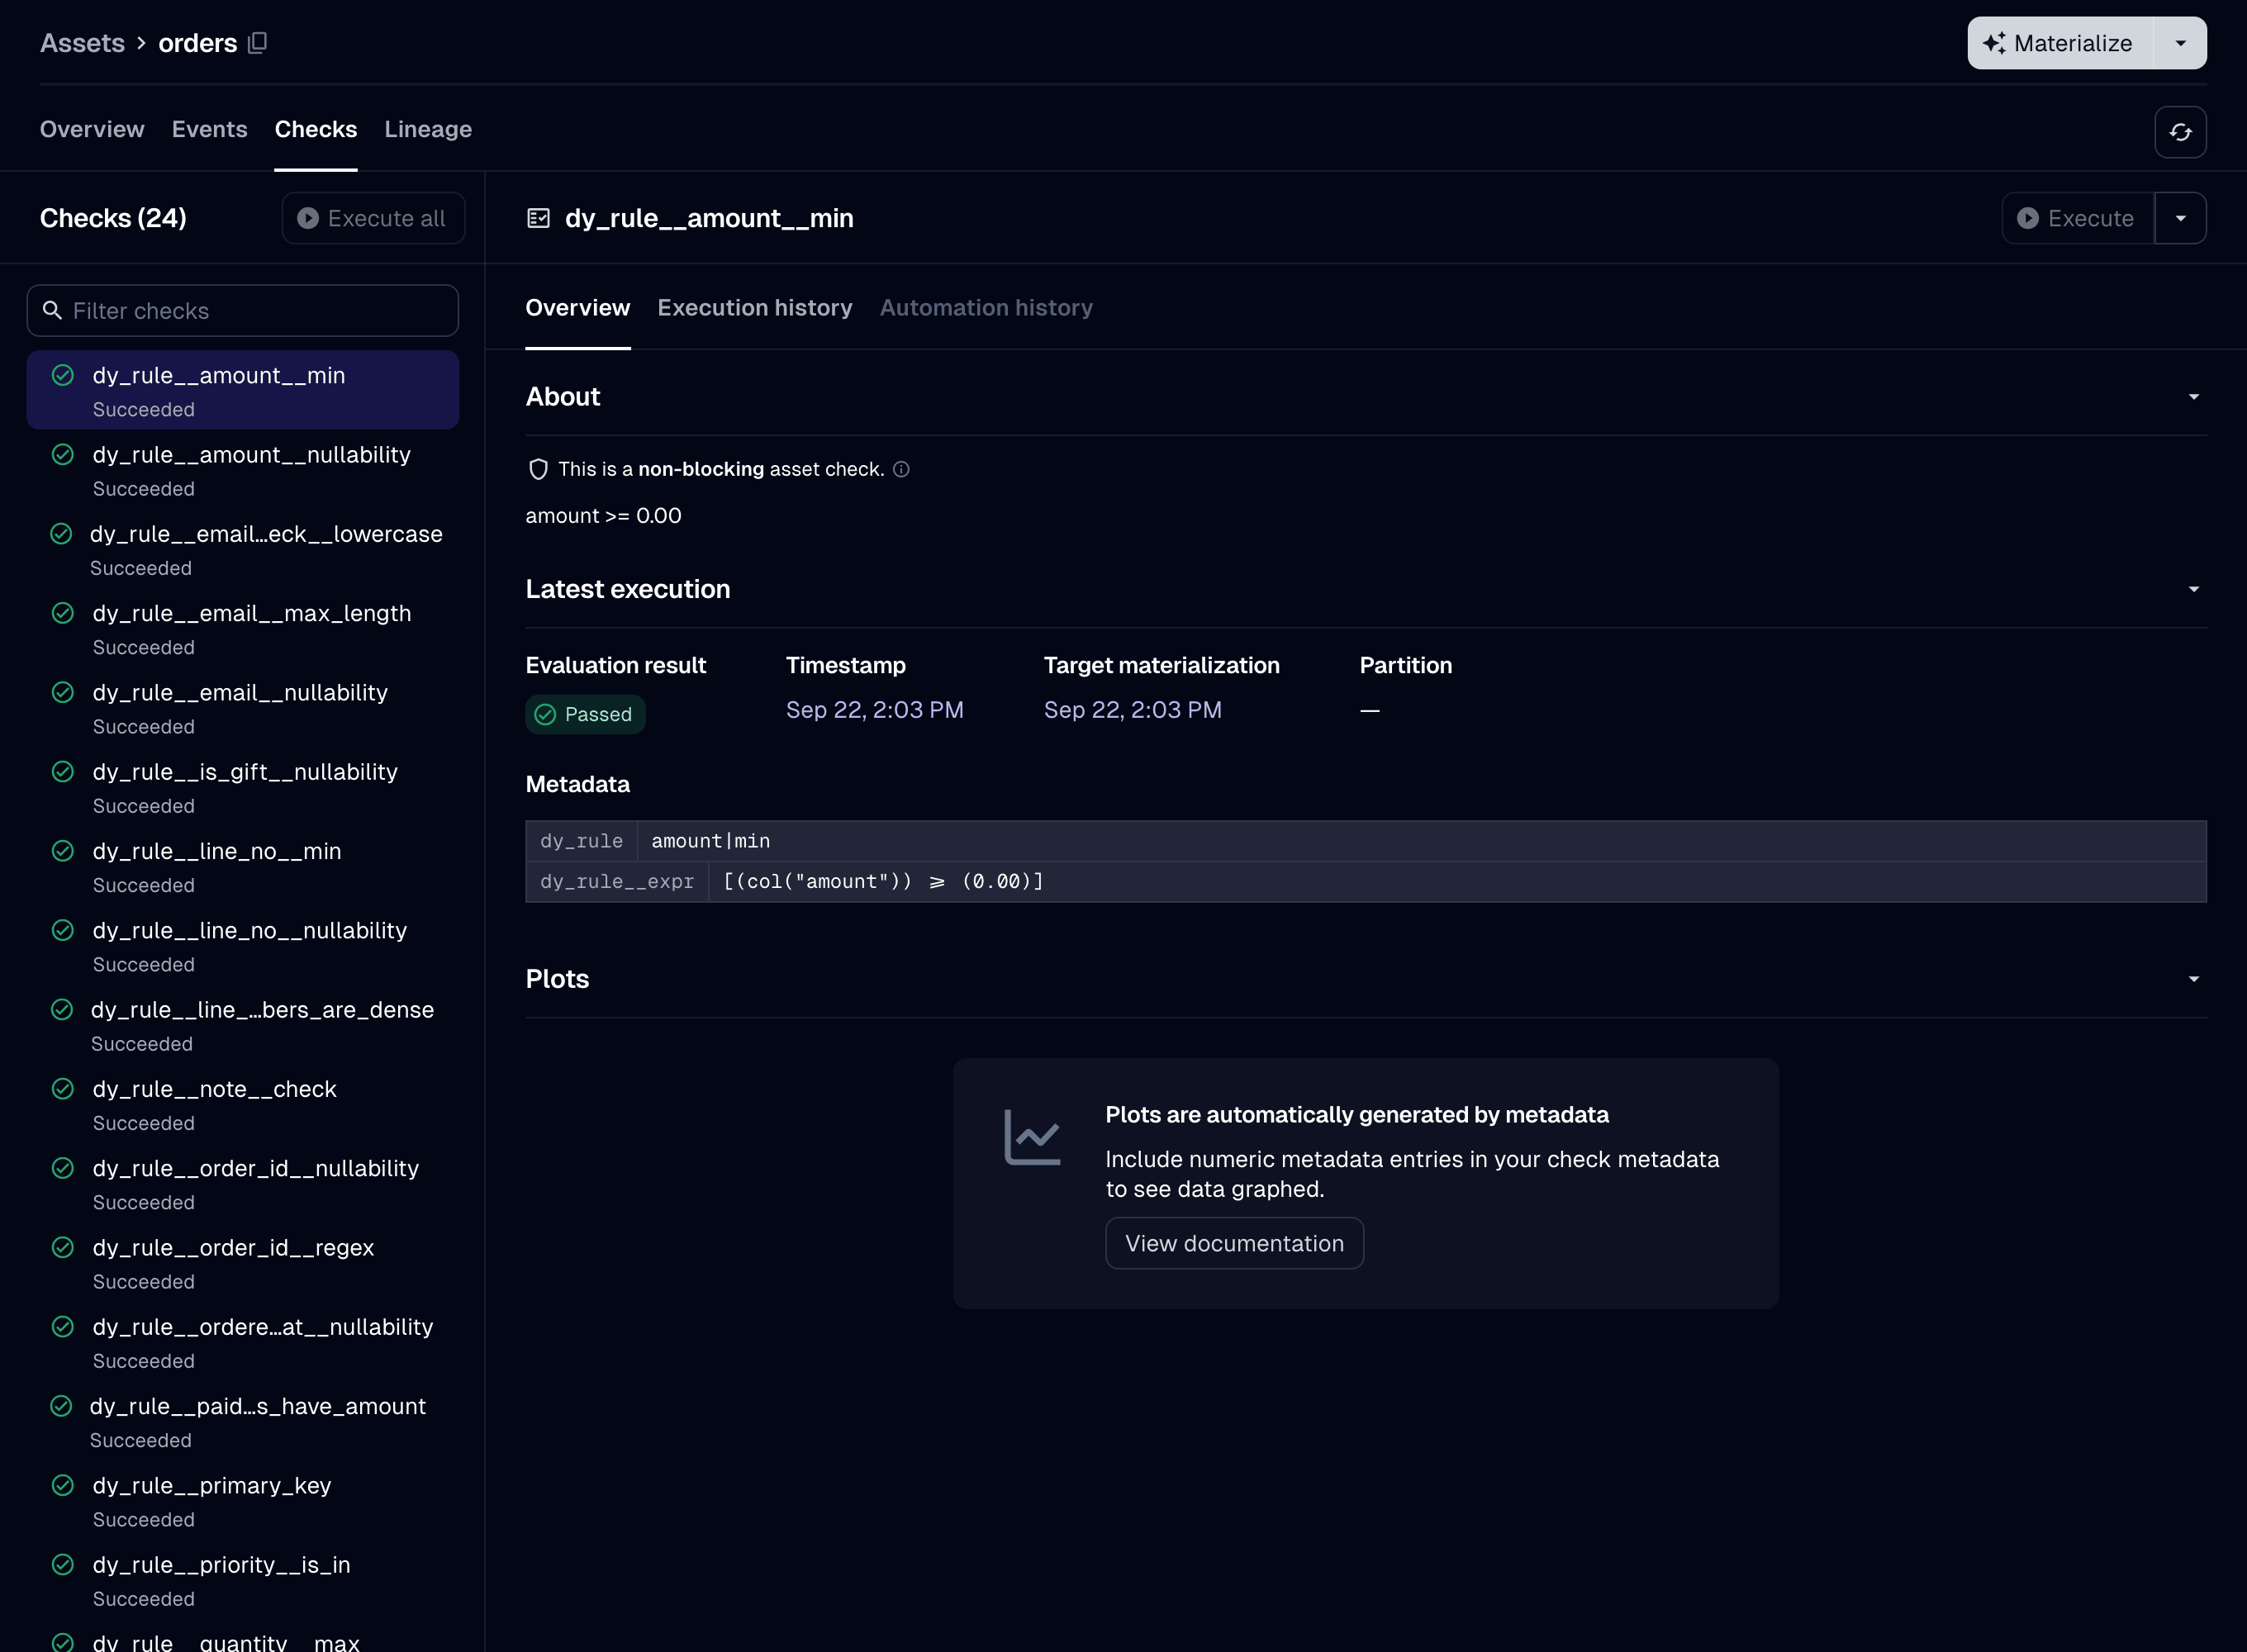
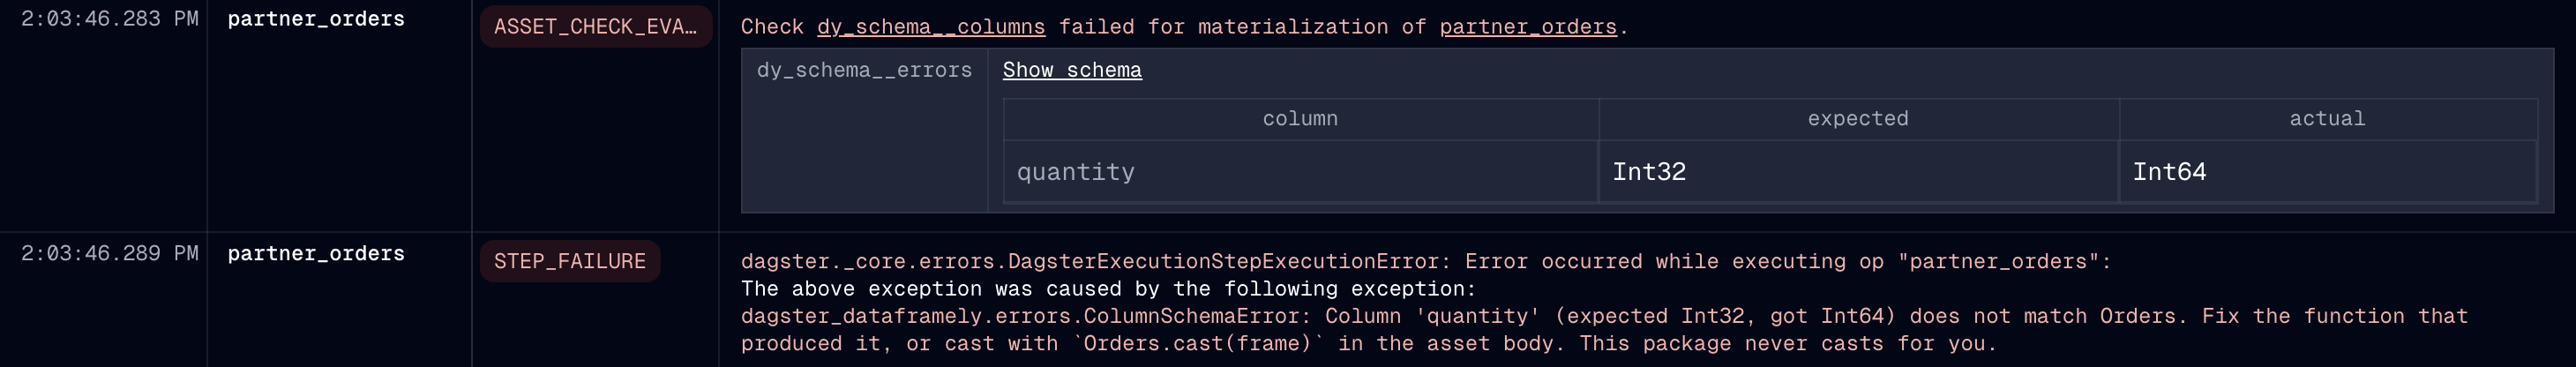
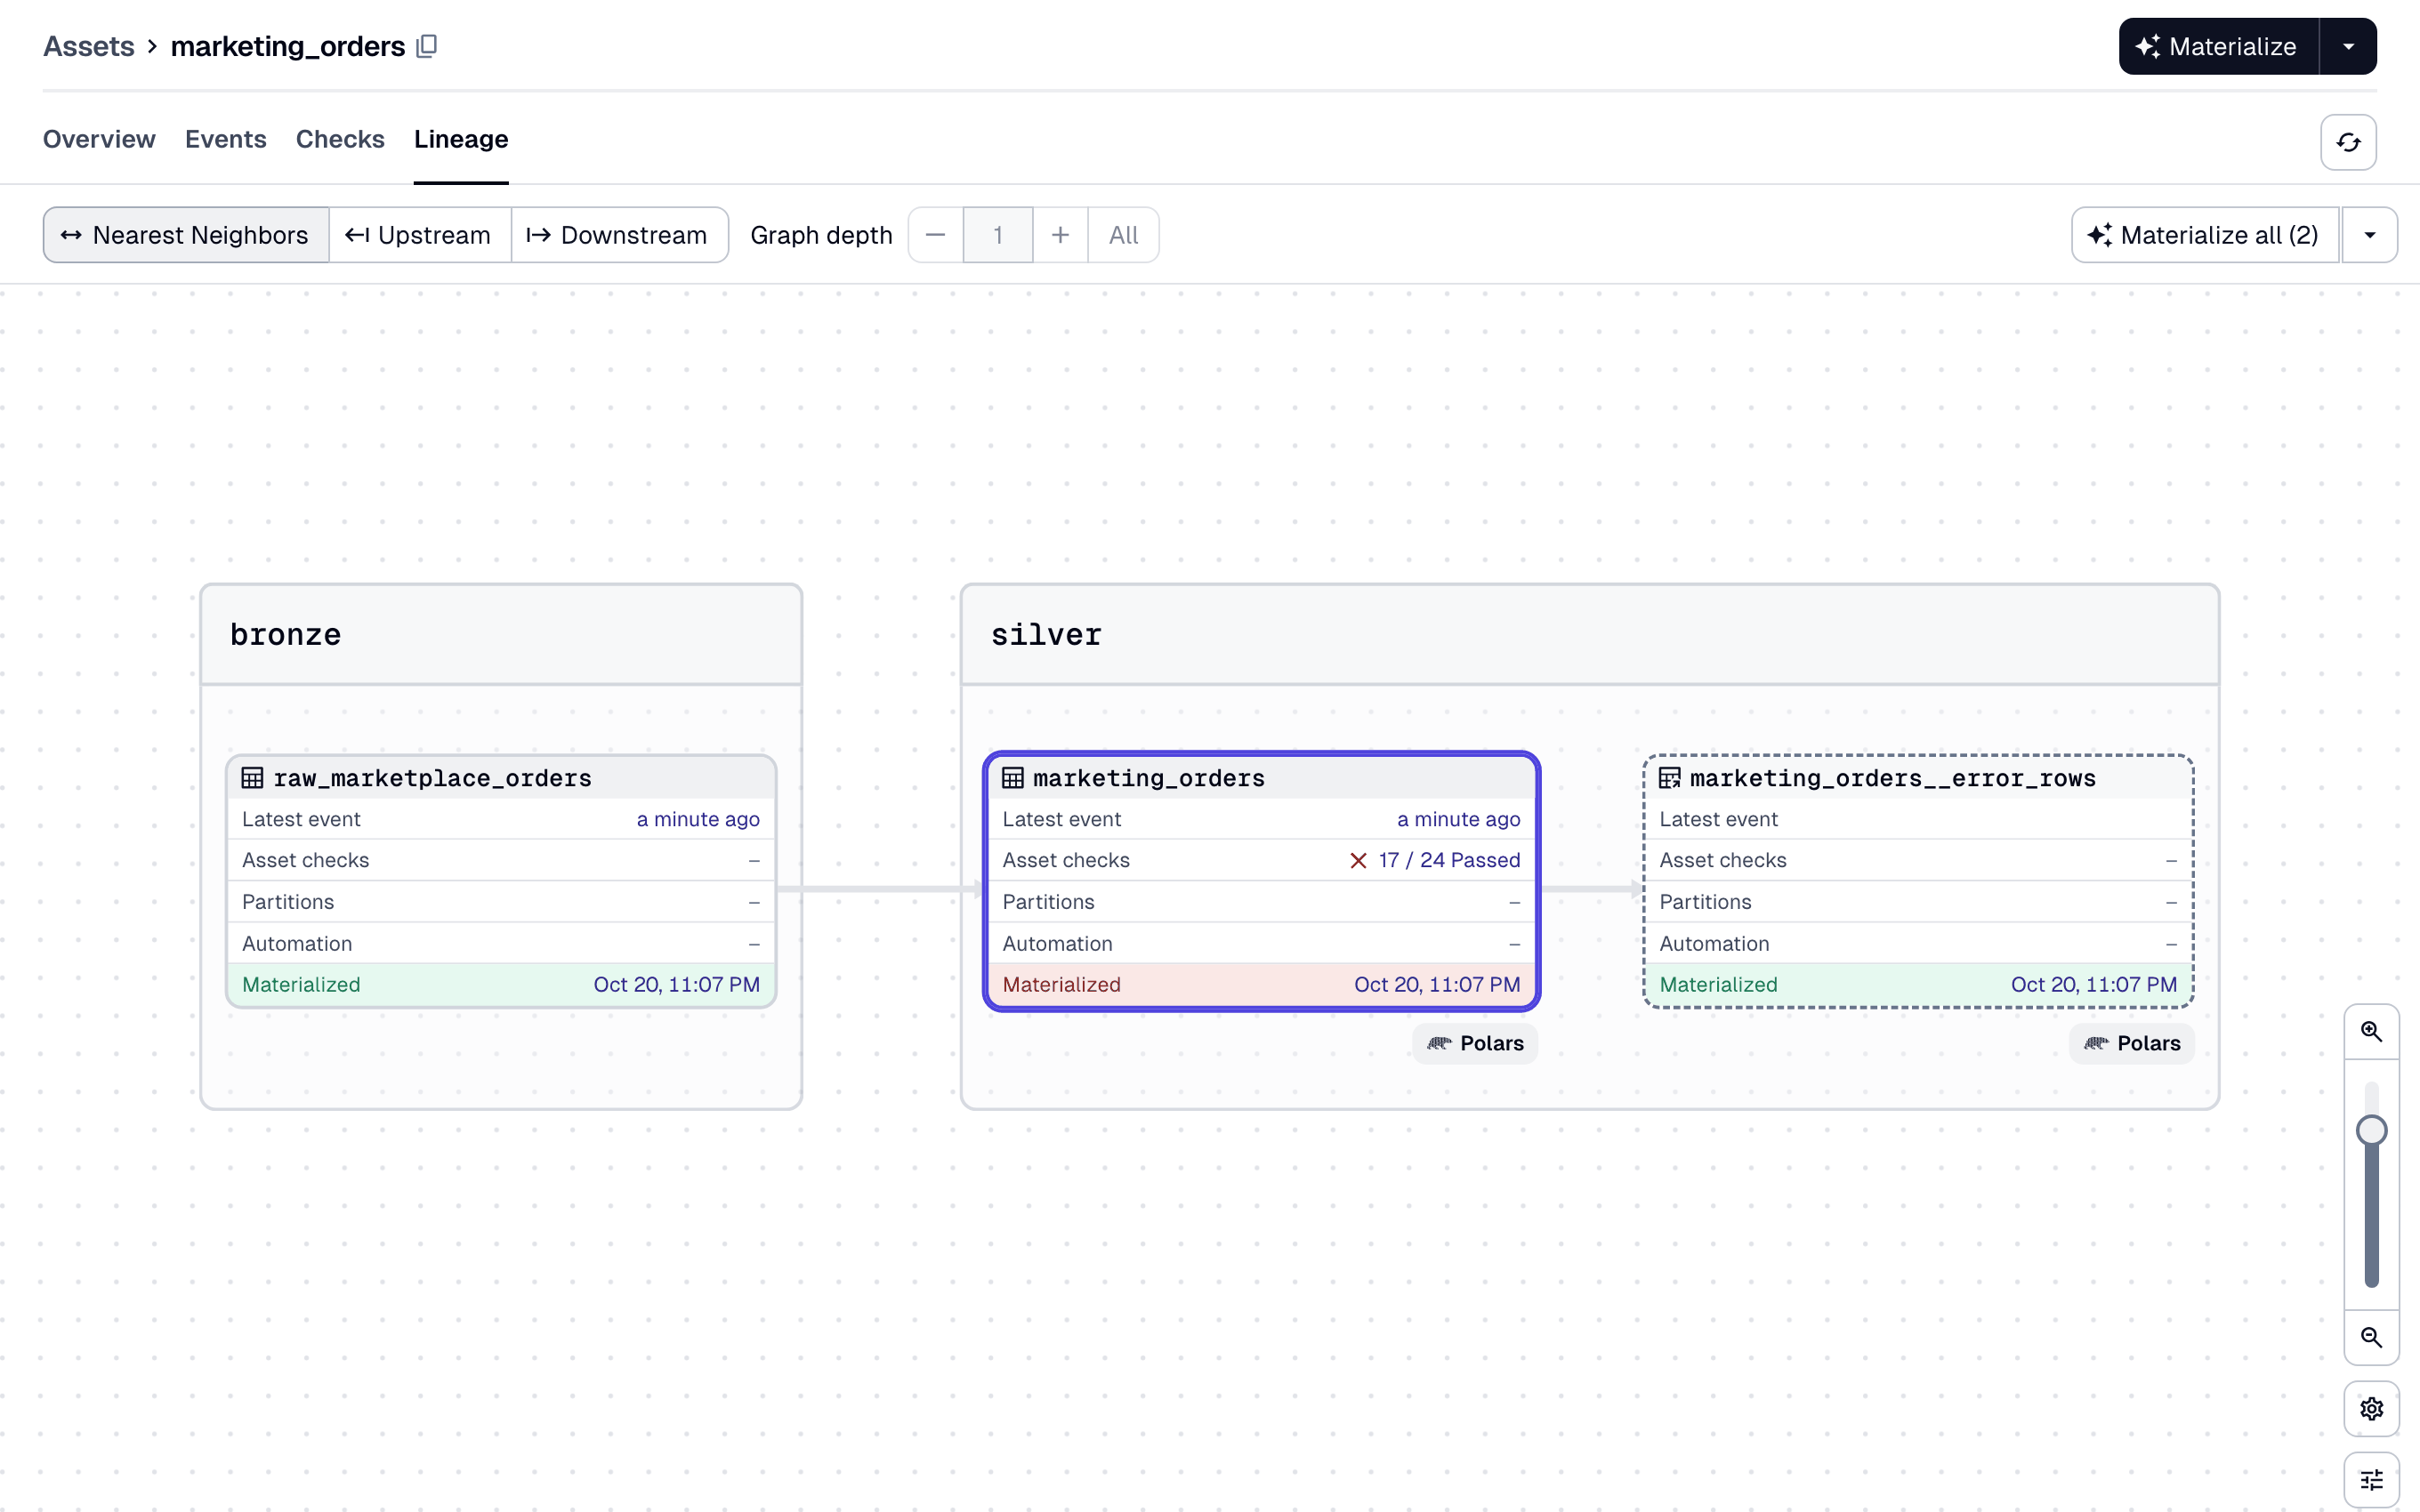
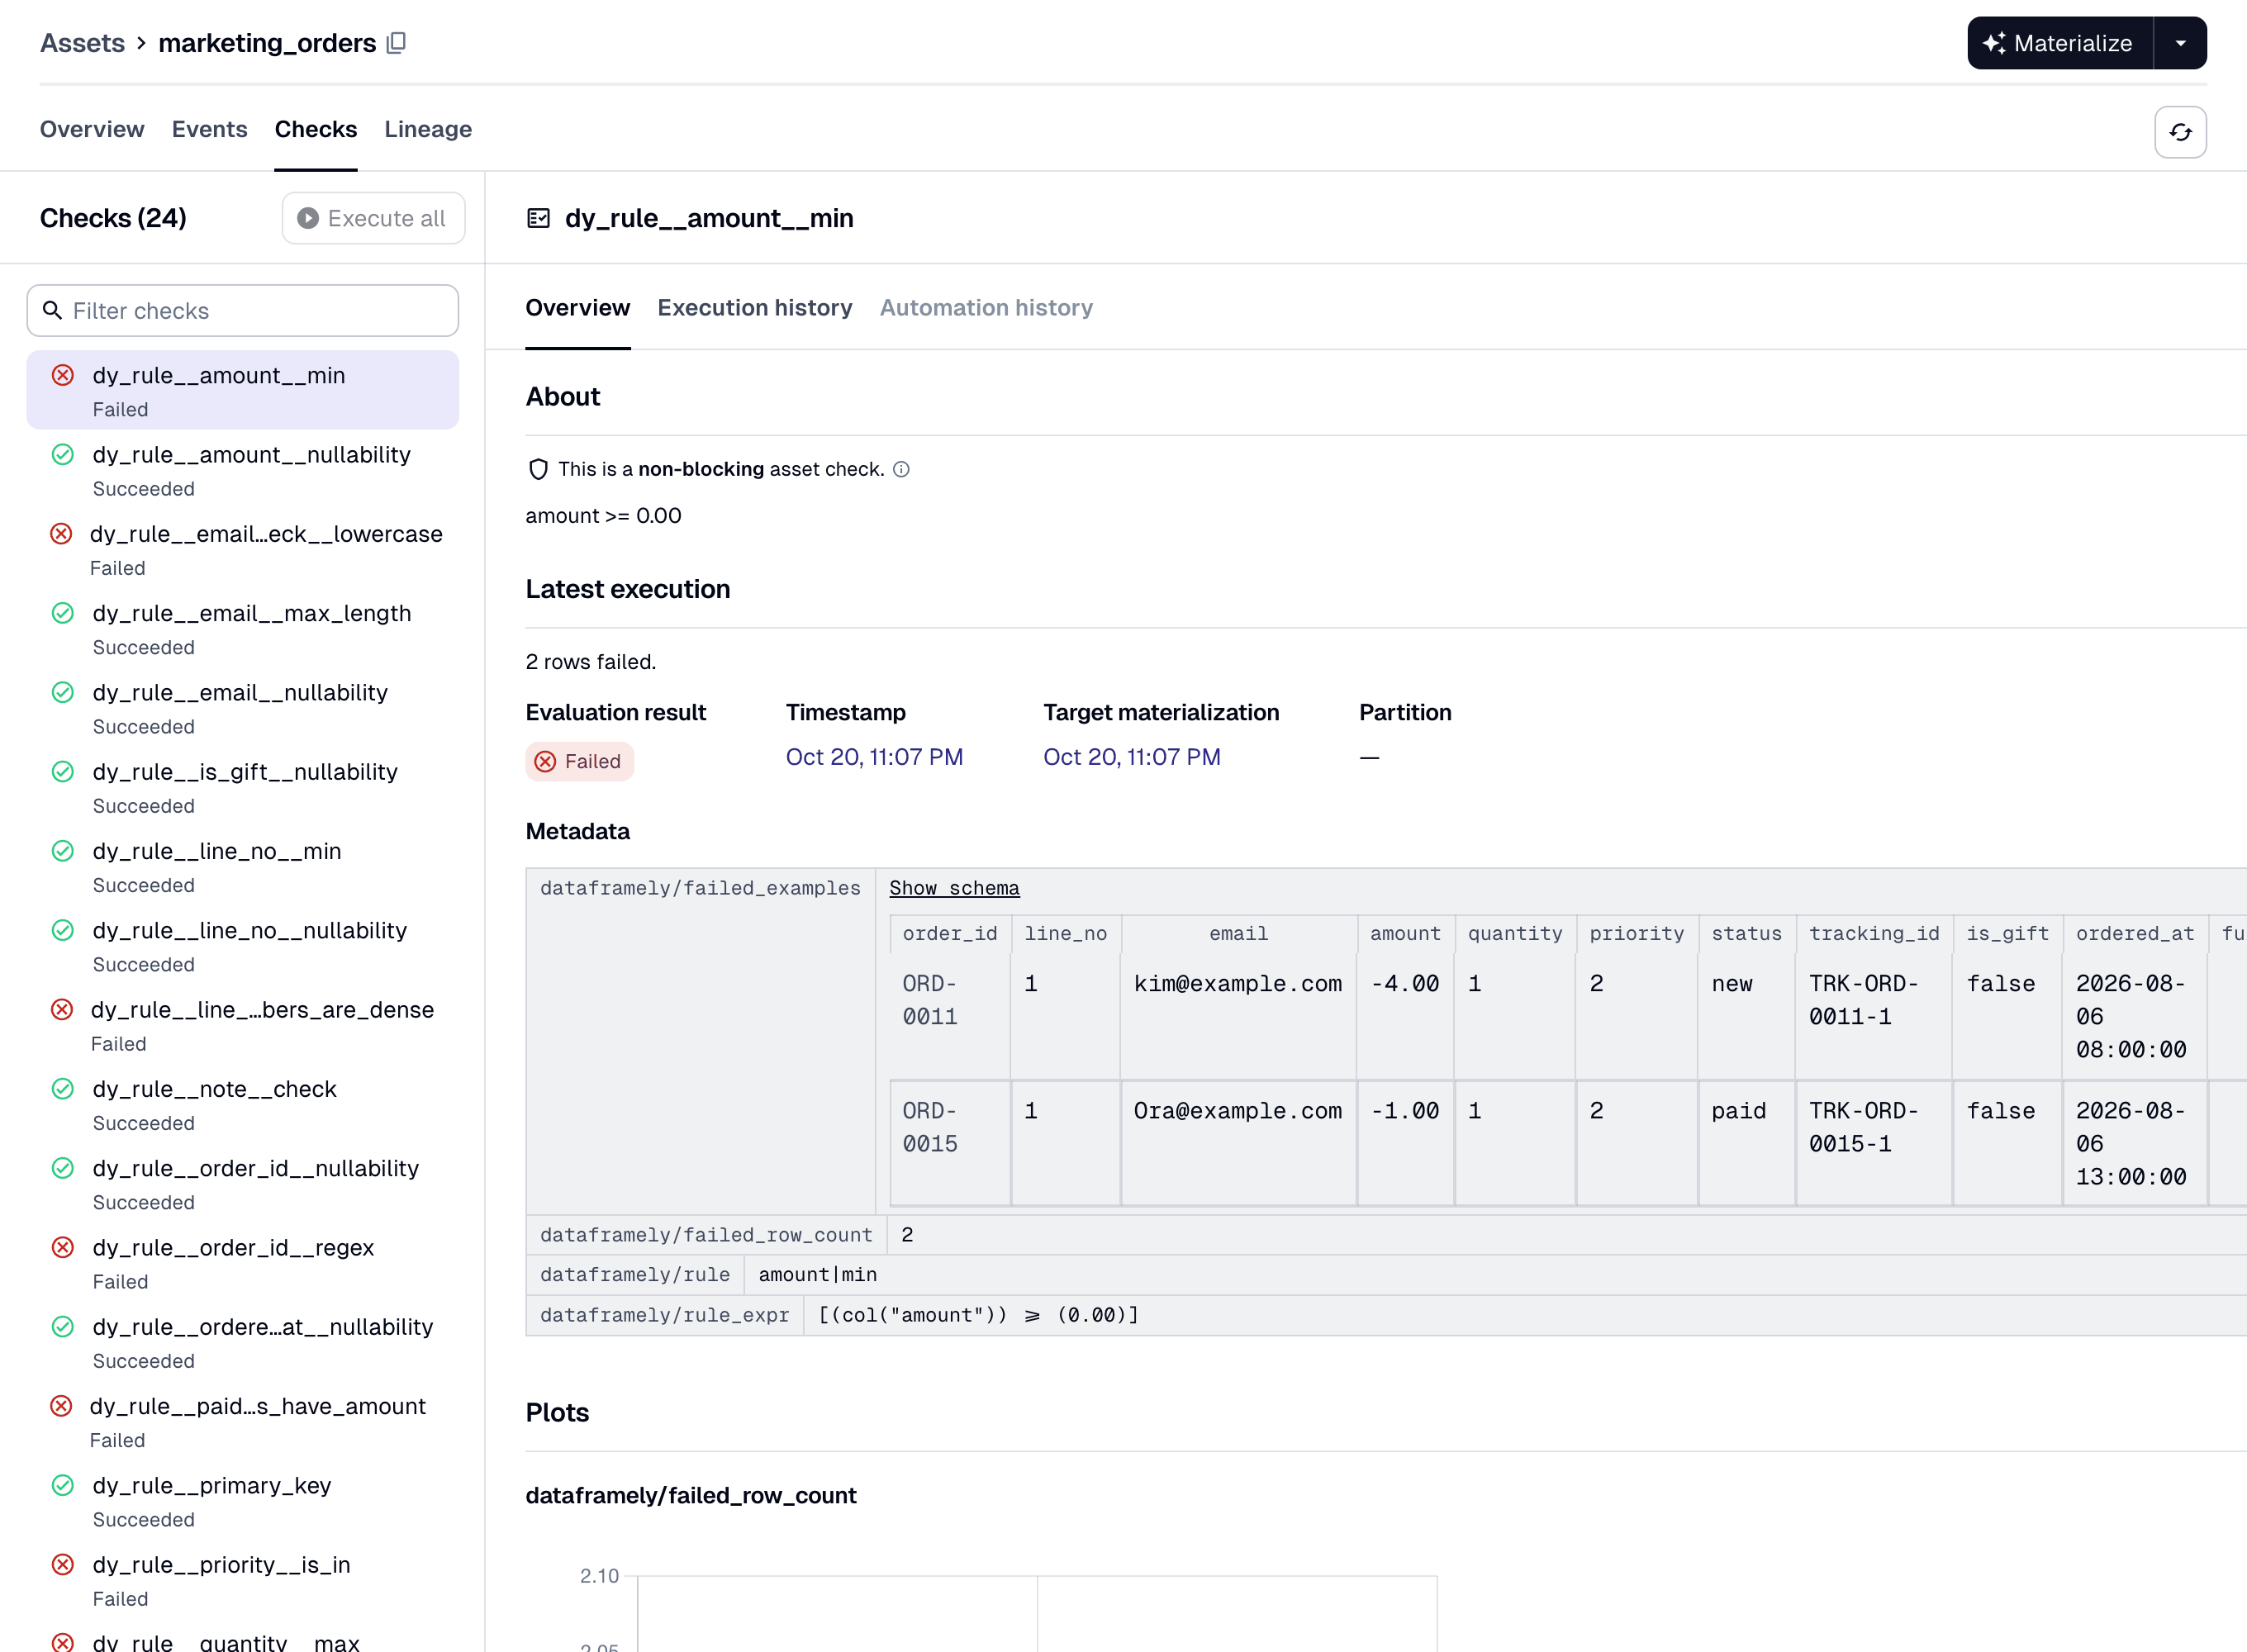
Every Python block on this page comes from the demo pipeline, and every image is a screenshot of it.
The images show assets that use its thirteen-column Orders schema.
From that one declaration you get:
-
The catalog's Columns tab, filled in before the asset first runs: dtypes, descriptions, nullability, uniqueness, the primary key at table level, and every other column constraint beside its column.
-
One asset check per Dataframely rule, and each check has its own pass/fail history.
-
A blocking column-schema check that compares the frame's columns and dtypes with the schema's, before
Schema.filterruns. -
A severity for each rule,
"error"by default or"warn", declared in the schema. A row that fails an"error"rule fails the run, and a row that fails only"warn"rules is written with a warning. -
Error rows, if you set
filter=True. A run writes the rows that failed an"error"rule to a table next to the asset's, writes the other rows to the asset's table, and succeeds. The run still fails when every row fails an"error"rule.
The decorated function is a normal Dagster asset function.
Dagster passes upstream assets to it as parameters.
It can also declare a context parameter.
It returns a pl.DataFrame or a pl.LazyFrame, a dg.MaterializeResult whose value is one of those, or None.
dd.asset builds a @dg.asset and accepts its parameters under the same names.
It leaves out six, which it sets itself or does not support.
The user guide lists them.
A test fails if @dg.asset adds a parameter that dd.asset lacks, or removes one that dd.asset passes on.
Package philosophy
Schema on write. Validation happens when an asset writes a table, never when it reads one. The checks run before the IO manager receives the frame, so it never writes a failing row to the table.
Use this package after ingestion, from bronze to silver to gold, to check that data is fit to publish.
Load raw records with a permissive loader such as dlt, and declare a schema on the first table that other people query.
Use another tool for ingestion-scale or larger-than-memory data.
The decorated function must return the schema's dtypes.
A dtype that differs from the schema's fails the run, and the package never casts it.
There is no lenient mode.
Extra columns and column order need no extra work: Schema.filter drops the columns the schema does not declare and returns the rest in the schema's order.
So dtypes are the only thing you have to fix.
Partial data needs a declaration, not a setting.
The only parameter for it is filter=True.
No environment variable sets it.
Without it, one failing row fails the run and the package writes nothing, so your last-known-good table is unchanged.
The decorator is strict, but you can use its parts without it.
The package builds dd.asset from parts that it also exports under dd.wiring.
Each part adds one feature to an asset that dd.asset cannot build: the Columns tab for an asset that writes its own storage, or the checks for a table that something else already wrote.
Quick start
uv add dagster-dataframely
You need Python 3.12 or newer.
The dependencies are dagster, dataframely and polars, plus universal-pathlib, which dagster already installs.
This package does not include an IO manager.
dagster-polars writes Polars frames to a filesystem or object store, and dagster-duckdb-polars writes them to a warehouse.
Any IO manager that stores by asset key works.
Pre-1.0. A characterization test covers the public surface, so it never changes by accident. It can still change: a
0.xminor release can include breaking changes. If that matters to you, pin to one minor version:>=the version you installed,<the next minor. If you are upgrading from 0.8 or earlier, read the changelog first.
Declare the schema and the asset as above, then bind an IO manager.
In a dg project, Dagster loads every module under defs/ automatically, so the IO manager needs one more file:
import dagster as dg
from dagster_polars import PolarsParquetIOManager


@dg.definitions
def resources() -> dg.Definitions:
    """Bind the Parquet IO manager the pipeline writes through."""
    return dg.Definitions(
        resources={"io_manager": PolarsParquetIOManager(base_dir="storage")}
    )
customers reads raw_customers, so the asset that produces raw_customers goes under defs/ too.
Run dg dev and materialize both from the UI.
Four things now exist that did not before:
- The catalog's Columns tab, filled from
Customers, before the first run. - One asset check per rule, each with its own history, evaluated on every run.
- A materialization that has the row count, a row sample and statistics for each dtype group.
- A table, written by your IO manager.
To write the rows that fail an "error" rule to a separate table instead of failing the run, declare @dd.asset(Customers, filter=True).
The same IO manager writes them, under the asset's key with __error_rows appended.
Each of those rows has one added column per rule, which shows whether the row failed that rule.
The run succeeds, so downstream assets read the other rows, and each failing "error" rule's check still fails at ERROR.
Documentation
https://ozanozbeker.com/dagster-dataframely has the guide, the API reference and the changelog.
The site is for users.
Contributor documentation stays in the repository: CONTEXT.md is the glossary, and docs/pre-1.0.md records the decisions and the measurements the package was built on.
License
Apache 2.0.
See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for dagster-dataframely 0.10.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| dagster_dataframely-0.10.0.tar.gz | 43.7 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| dagster_dataframely-0.10.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 93.8 kB
Release files / dagster_dataframely-0.10.0.tar.gz
| Download URL | dagster_dataframely-0.10.0.tar.gz |
|---|---|
| Size | 43.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4e0447b120b17e765c14dfa3f709b71b62f7c3ad141fa6900a58c19576632974
|
|
BLAKE2b-256 checksum How to use checksums |
d4a4ad9146416213416ba873bd9cee98ecdffba4308251831da0e068131db7f4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logRelease files / dagster_dataframely-0.10.0-py3-none-any.whl
| Download URL | dagster_dataframely-0.10.0-py3-none-any.whl |
|---|---|
| Size | 50.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1bf5dbe6daf5a332273fd5f50354281a2a229ceb6ace090d0952f0dc2f353e74
|
|
BLAKE2b-256 checksum How to use checksums |
ee58d136453d22f5829ab8ee8ca81b7882b7ea7a629f2362fcc81ca5644dd09b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logSecurity for dagster-dataframely 0.10.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for dagster_dataframely-0.10.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 18, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














