






Decision-Jef-0.1
Answer several runtime-defined questions about one state, in a single forward pass, with a probability over exactly the options you supply.
307M parameters. 12.0 ms for three decisions in one forward pass.
The answer space is built from the request, so a value you did not offer is not representable — not merely unlikely. There is no classification head over a fixed label set.
Results
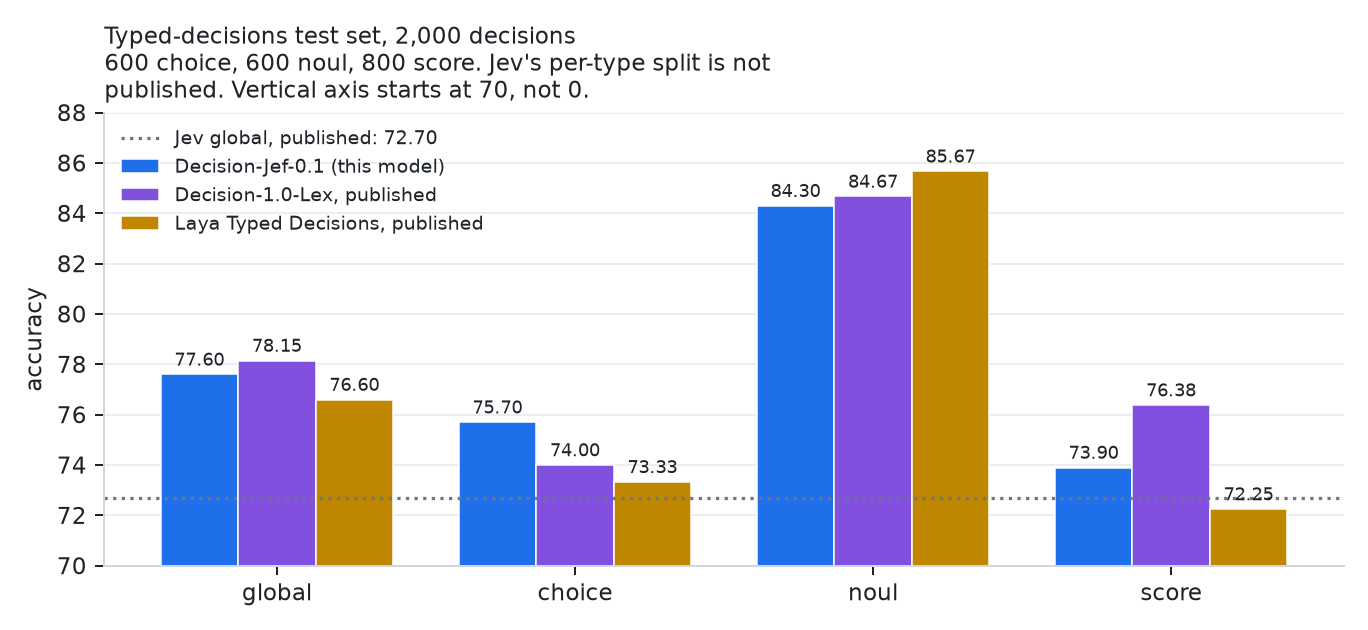
Typed-decisions test set, 2,000 decisions: 600 choice, 600 noul, 800
score. Same set and same split as the published models below. Figures are as
shipped, with no temperature applied.
| model | global | choice | noul | score |
|---|---|---|---|---|
| Decision-1.0-Lex | 78.15 | 74.00 | 84.67 | 76.38 |
| Decision-Jef-0.1 | 77.30 | 73.70 | 83.70 | 75.40 |
| Laya Typed Decisions | 76.60 | 73.33 | 85.67 | 72.25 |
| Jev | 72.70 | not published | not published | not published |
Behind Lex by 0.85 and ahead of Laya by 0.70. score at 75.40 is this
model's best figure relative to the field and its own best to date; choice
and noul are behind both published models.
This release trades 0.60 of benchmark accuracy for something the benchmark does not cover at all, and the section on ViZDoom below is that trade measured. Read it before comparing this row against the previous release.
The figures each model publishes do not line up. Lex publishes a per-type breakdown and no aggregate metrics; Jev publishes aggregates and no breakdown. The tables here say which is which rather than filling the gaps.
| this model | Laya | Jev | |
|---|---|---|---|
| soft accuracy | 0.605 | 0.471 | 0.580 |
| Brier, summed over classes | 0.102 | 0.061 † | 0.148 |
| ECE, 10 bins | 0.010 | 0.213 | 0.144 |
| score MAE | 0.267 | 0.242 | 0.391 |
| majority class on this set | 0.457 | ||
| random guess on this set | 0.318 |
Soft accuracy is the label mass on the answer we pick, which matters on a benchmark whose labels are annotator averages rather than single verdicts.
† Published Brier figures use two conventions. Laya reports 0.061 averaged per class and attributes 0.148 to Jev summed over classes, which reads as a 2.4x gap and is a unit mismatch. The 0.102 above is summed, the same convention as the 0.148, so it is comparable to Jev's figure and not to Laya's.
Option order
Every choice question in this benchmark presents its options in one fixed
order, and that order is not uniform. The questions carry four or five options,
so a uniform draw would put the gold answer in any one slot 23.3% of the time.
Measured over the 600 choice questions:
| slot | share of gold answers | against uniform |
|---|---|---|
| 1st | 20.7% | 0.89x |
| 2nd | 20.2% | 0.86x |
| 3rd | 39.7% | 1.70x |
| 4th | 12.2% | 0.52x |
| 5th | 7.3% | 0.31x |
A model can therefore score on this benchmark by learning to answer third. This one does not:
| native order | options permuted | change | |
|---|---|---|---|
| global | 77.35 | 77.45 | -0.10 |
| choice | 73.67 | 74.00 | -0.33 |
| noul | 83.67 | 83.67 | +0.00 |
| score | 75.38 | 75.38 | +0.00 |
Over 1,800 permutations of the benchmark's choice questions, the answer
changes on 5.5% of them. Jev is measured at 0.13 and Laya at 0.15 on the
same kind of check.
This table comes from the permutation harness and the one above from the like-for-like harness, which is why the global figures read 77.35 and 77.30. The two differ by less than the +/-0.15 of bf16 arithmetic noise reported under Limitations; neither is rounded to flatter the other. Permuting the options raises the score by 0.10, which is what a model with no positional prior does on a benchmark that places the gold answer third 39.7% of the time.
Calibration
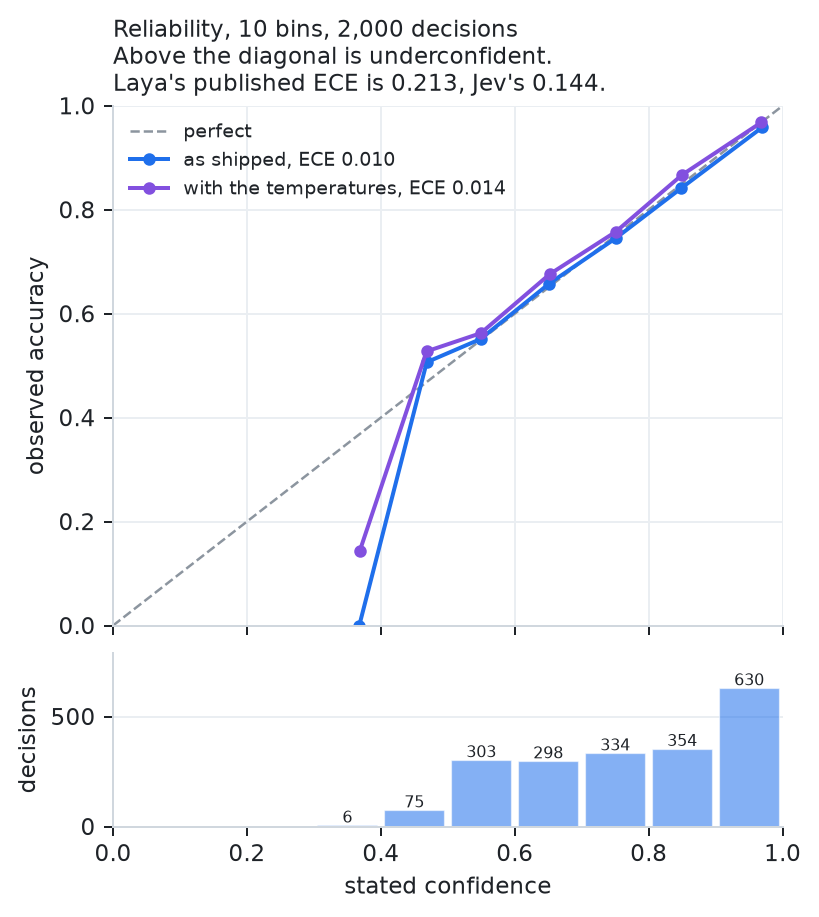
ECE is 0.010 as shipped, which is already inside a 0.10 criterion without any post-hoc correction. Temperature scaling per (type, cardinality) bucket ships with the model and is off by default. Applying it trades one metric for the other:
| as shipped | with the temperatures | |
|---|---|---|
| ECE, 10 bins | 0.010 | 0.008 |
| Brier, summed | 0.102 | 0.107 |
| score MAE | 0.267 | 0.271 |
| global accuracy | 77.30 | 77.30 |
The two disagree because they ask different questions. ECE asks whether stated confidence matches hit rate; Brier asks whether the reported distribution matches the annotator average. The temperatures barely move anything this time -- ECE 0.010 to 0.008 -- because the model already ships close to calibrated, and several buckets fit at 1.000. Accuracy does not move either way, because a per-bucket temperature never changes an argmax.
The reliability curve sits slightly above the diagonal, which is underconfidence: this model's stated confidence runs a little below its hit rate. The bin counts are plotted underneath because the two leftmost points carry 10 and 124 decisions out of 2,000 and should not be read as a trend.
Leave them off unless you specifically need the confidence figure to track the hit rate, and fit your own on your own data if you do. Laya's published pair — Brier 0.061 with ECE 0.213 — sits at the opposite end of the same trade-off rather than at a better point on it.
Where the probabilities are honest
Measured against a generator whose true posterior is known by construction: a ticket that cues one department has a true answer, one that cues two is a genuine coin flip between them.
| case | true answer | this model |
|---|---|---|
| one department cued | 1.00 | 1.000 |
| two departments cued | 0.50 | 0.554 |
| escalation implied by priority | 0.90 | 0.965 |
| mass on the two cued departments | 1.00 | 1.000 |
The model recovers the true posterior when the state settles the question, puts all of its mass on the departments the state allows, and reports close to an even split where the answer is genuinely undetermined. For scale on the third row, a 0.90 truth is the case where a stated rate rather than a verdict is the right answer.
Question isolation
Adding a question does not change another question's answer. This holds exactly, not approximately, and it holds against the length of the other questions as well as their content — each question's block is packed with the geometry it would have if it were alone in the request.
Checked across all 2,000 benchmark decisions with one, two, three and four questions sharing each sequence: in fp32 the four runs agree to every digit reported, globally and per type. In bf16 they spread by about 0.15, which is padded-shape arithmetic rather than information crossing between questions.
Files
| file | what |
|---|---|
model.safetensors |
the weights, 143 tensors. No pickle is published, so a load executes nothing. |
config.json |
the encoder's own config, verbatim from jhu-clsp/mmBERT-base, plus one decision_jef key for this model's geometry. |
temperatures.json |
the fitted per-bucket temperatures. Off by default; see above. |
metrics.json |
this checkpoint's benchmark figures, raw and calibrated. |
tokenizer.json, tokenizer_config.json, special_tokens_map.json |
vendored, so a load needs one repository and no second download. |
The encoder tensors carry their canonical ModernBERT names, so the fine-tuned encoder can be loaded on its own:
from transformers import AutoModel
encoder = AutoModel.from_pretrained("BarraHome/Decision-Jef-0.1")
That returns a ModernBertModel with every one of its 134 weights loaded and
the nine decision-head tensors skipped. Verified tensor by tensor: both paths
give bit-identical encoder weights.
Latency
NVIDIA H100 NVL, fp32, median of 30 calls after warm-up, measured end to end
through this package: packing, encoder and readout. fp32 is what
from_pretrained gives you; bf16 roughly halves these numbers.
| questions in one call | median | p95 |
|---|---|---|
| 1 | 11.69 ms | 12.33 ms |
| 2 | 11.88 ms | 12.17 ms |
| 3 | 11.96 ms | 12.26 ms |
| 4 | 12.13 ms | 12.82 ms |
Three extra questions cost 0.44 ms in total, under 4% over a single question. The state is encoded once and the question branches are masked apart, so a request carrying four questions is not four requests — but it is not free either, and the trend across these four rows is monotonic rather than noise.
Throughput at batch 64 and 1,024 tokens is 5.36 ms per decision in fp32.
Usage
pip install decision-jef
The weights are published separately from the package.
from decision_jef import Decider, Question, email

d = Decider.from_pretrained("BarraHome/Decision-Jef-0.1")

state = email.as_state(
    "user@acme.com", "Duplicate charge on invoice #4411",
    "We were billed twice for March. Please refund the duplicate today "
    "or we will cancel our plan.")

answers = d.decide(state, {
    "department": Question("choice", "Which department should handle this?", {
        "billing": "invoices, payments, refunds",
        "technical": "bugs, outages, system errors",
        "sales": "pricing, new contracts",
        "other": "everything else",
    }),
    "urgency": Question("score", "How urgent is this request?",
                        ["not urgent", "soon", "critical or blocking"]),
    "churn_risk": Question("noul", "Does the user threaten to leave?", {
        "false": "The user makes no threat to stop using the service.",
        "true": "The user threatens to cancel, churn or leave.",
    }),
})

for qid, a in answers.items():
    print(qid, a.choice or a.p("true"), a.confidence, a.probabilities)
department  billing  1.00  {'billing': 0.9997, 'technical': 0.0001, 'sales': 0.0001, 'other': 0.0001}
urgency     1        0.96  {'0': 0.0175, '1': 0.96, '2': 0.0225}      score=1.00
churn_risk  0.988    0.99  {'false': 0.012, 'true': 0.988}
decide returns raw probabilities. Pass calibrated=True to apply the shipped
temperatures, and read the calibration section first.
d.to_wire(answers) returns the same content as a JSON-ready response body.
A question must be a Question, not a plain dict. Passing a dict raises a
TypeError that says so.
Give every yes/no outcome a description that carries meaning
This is a requirement, not a style note, and a template does not satisfy it.
The model scores the option text, so what that text says is what it has to
work with. Measured over all 600 noul questions in the benchmark, replacing
their own descriptions:
false / true text |
accuracy |
|---|---|
| the question's own descriptions | 83.83 |
| nothing at all | 66.17 |
"No. <question>." / "Yes. <question>." |
65.33 |
A templated prefix is worse than supplying nothing, by 0.84 points, and on an individual question it can be much worse. On the refund e-mail above, asking whether the user threatens to leave gives p(true) 0.617 with no descriptions, 0.007 with the template -- confidently the wrong side -- and 0.988 with
{"false": "The user makes no threat to stop using the service.",
 "true":  "The user threatens to cancel, churn or leave."}
Write what each outcome means. Do not generate the two strings from the question.
Large option sets
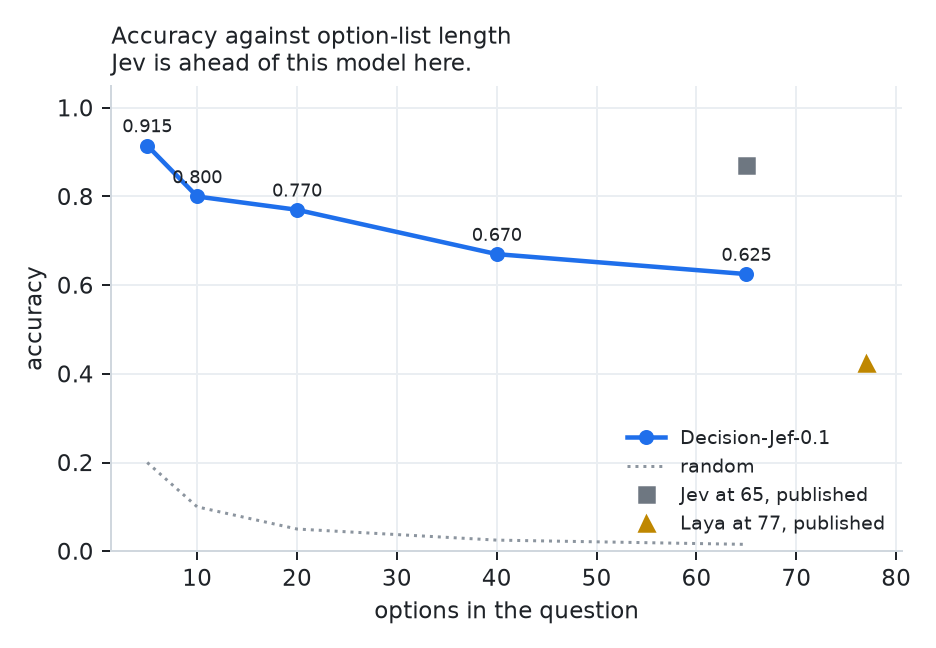
Accuracy falls as the option list grows, and the window is not the reason: eighty options with one-line descriptions pack into 772 tokens of the 1,024 with none truncated, so the list fits and the readout is what degrades. The token figure scales with how long your descriptions are.
| options | accuracy | random |
|---|---|---|
| 5 | 0.915 | 0.200 |
| 10 | 0.825 | 0.100 |
| 20 | 0.785 | 0.050 |
| 40 | 0.695 | 0.025 |
| 65 | 0.625 | 0.015 |
Laya reports 0.425 on a 77-label set and attributes it to an option-text budget; Jev is reported at 0.870 and is ahead of this model here. Narrow the set first if you are above about twenty options:
from decision_jef import shortlist_decide

answers, meta = shortlist_decide(decider, state, questions, k=16)
meta["intent"]["kept"]     # the options that survived, best first
Ranking is lexical overlap between the state and each option's text, weighted
so a term every option shares counts for little. It needs no second model.
Pass embed_fn to rank with your own embeddings instead. A question at or
below k options passes through and costs nothing.
This model's own logits are also a usable ranker, and a better one than the lexical default. On 200 banking-intent cases cut to fifty options, recall of the gold answer in the top sixteen:
| ranker | recall@16 |
|---|---|
| this model's logits | 0.960 |
| lexical overlap | 0.865 |
| random | 0.320 |
Ranking is an easier task than answering, so the logits stay informative at a list length where the argmax is already unreliable. Two passes of this model cost about 24 ms and need no second model or embedding service.
A reply carries the thread below it, a signature, and often a legal disclaimer. None of that is the message, and it is often the longest part.
from decision_jef import email

state = email.as_state(sender, subject, body)
email.clean(body) cuts the quoted thread, the signature block and the
disclaimer, and as_state formats the fields the way the rest of this package
feeds the model.
Serving an existing Jev client
Clients written against Jev post to /v1/systemone and read back
{"answers": {...}}. This package serves that route from these weights, so
such a client changes one URL and nothing else.
pip install decision-jef
decision-jef-serve                       # 127.0.0.1:8088, weights from the Hub
decision-jef serving BarraHome/Decision-Jef-0.1 on http://127.0.0.1:8088/v1/systemone
| flag | default | what |
|---|---|---|
--weights |
BarraHome/Decision-Jef-0.1 |
repository id or a local directory |
--host --port |
127.0.0.1 8088 |
where to listen |
--token TOKEN |
none | require Authorization: Bearer TOKEN; omitted, any value is accepted |
--calibrated |
off | apply the shipped temperatures; read the calibration section first |
--device |
auto |
passed to the loader |
--quiet |
off | stop logging one line per request |
GET /health returns {"status": "ok"}. Every answer body carries
latency_ms for the forward pass. Requests are serialised behind a lock: the
model is not re-entrant, so two overlapping ticks would otherwise interleave
their batches. It is the standard library and one forward pass, not a
framework.
Then point the client at it. Both published Doom agents hardcode the upstream URL, so this is a one-line edit:
# AmoghCreator/doom-jev, agent/jev_client.py
self.url = "http://127.0.0.1:8088/v1/systemone"
// lukaske/jev-doom-agent, server/typesafe.ts
await fetch('http://127.0.0.1:8088/v1/systemone', { ... })
Measured against the first of those, sending its own six-question tick -- four
choice and two noul over a YAML situation report -- the round trip is 33 ms
end to end, 31 ms of it the forward pass. Their client allows 1.5 s and queries
at 10 Hz.
What the server accepts that the format does not
A live client builds its option list from the world. A game agent asking which
visible enemy to aim at usually has one or none, and {"none": "No valid targets"} is a single-option choice. The wire format requires two, and
should: a choice among one alternative is not a choice. But the answer is
forced and correct, so the server answers those itself, with probability 1 and
"forced": true in the body, and never asks the model. Without this, one of
those agents gets HTTP 422 for most of a game.
Instructions and state also arrive structured rather than as strings from some
clients -- {"task": "Choose navigation for this tick.", "policy": ...} -- and
are flattened to text rather than rejected, because the model reads them as
text.
Pointing a game at it
The previous release could not read a game state at all. Given
AmoghCreator/doom-jev's own situation reports, every question came back a
constant: macro_goal answered engage on an empty room at 0.81 confidence,
movement answered the same direction whatever the walls said. Rewriting the
criteria to name the state's own fields did not help; it only changed which
constant. On 3,210 held-out decisions from that agent's state format, the
0.4.0 weights scored 37.4%.
That was not a prompting problem and it did not need a bigger model. It needed
20,000 situation reports in that exact format -- the same distance and bearing
bands, the same wall_directly_ahead booleans -- with every answer computed
from the state by a rule the state makes visible. These weights score 99.4%
on the same held-out set, and the answers are no longer constant:
| question | 0.4.0 | this release |
|---|---|---|
movement |
42.3% | 100.0% |
firing |
55.0% | 100.0% |
jump |
16.2% | 100.0% |
rotation |
29.8% | 99.7% |
macro_goal |
41.3% | 97.5% |
target |
44.3% | 98.6% |
| all 3,210 decisions | 37.4% | 99.4% |
The cost is 0.60 points of typed-decisions accuracy, 77.90 to 77.30. Whether that is worth it depends on whether your states look like the benchmark's support tickets or like something else.
The lesson generalises past Doom. A constant answer with high confidence is
what this model does on a state format it has not seen, and the calibration
that gives it ECE 0.010 on the benchmark does not warn you: that engage at
0.81 was confidently wrong. If you are putting it on a new state format,
measure it against a few dozen cases where you know the answer before trusting
any of its confidences.
The three question types
| type | criteria |
answer |
|---|---|---|
choice |
ordered map of key to description, up to 255 | choice, probabilities |
noul |
optional map of false and true to a description — supply it |
noul probability |
score |
ordered array of 2 to 10 level descriptions | probability-weighted score, legend |
Option order is part of the request: the same options in a different order are
a different request. The answer changes on 5.7% of choice questions under
permutation, so average over permutations if you need a stable answer.
How it works
<bos> state ... <eos>                                    shared, encoded once
[Q] instructions ... [OPT] opt0 [OPT] opt1 ... [DEC]     question 1
[Q] instructions ... [OPT] opt0 [OPT] opt1 ... [DEC]     question 2
The query is read at [DEC], after the whole option list, so the decision sees
every option. Keys come from each [OPT] in the same pass, so the options are
read together rather than scored in isolation. Each question attends to the
state and to itself only; the state attends to neither. Position ids restart at
the end of the state for every question, and the local-attention band is
measured in those restarted positions, which is what makes isolation hold
against the other questions' length and not only their content.
No escalation head in this release
Earlier releases shipped a head that predicted whether the model's own answer was wrong, so a caller could hand the flagged cases to a person. It does not work in these weights and has been removed rather than shipped with a caveat.
Measured on the benchmark's 2,000 decisions before removal: mean predicted P(wrong) was 0.045 where the answer was right and 0.083 where it was wrong. Escalating the worst half by predicted P(wrong) raised accuracy on the rest from 0.777 to 0.795 — not enough separation to set a threshold on, and not something a different threshold recovers.
decide(..., with_escalation=True) therefore returns escalation=None. The
field is documented and will carry a value again when a head earns it.
Limitations
choiceandnoulare behind both published models, 73.70 against 74.00 and 73.33, and 83.70 against 84.67 and 85.67.scoreat 75.40 is the one type where this model leads the field's second place.- A state format this model has not seen produces a constant answer with high confidence, and the ECE of 0.010 does not warn you, because it is an in-distribution figure. See the ViZDoom section. Measure before you trust a confidence on new inputs.
- Large option sets degrade steadily, against a random baseline of 0.050 and 0.015 respectively. Jev is reported at 0.870 at sixty-five and is ahead here. 0.785 at twenty and 0.625 at sixty-five here. Narrow the list above twenty; the model's own logits rank well enough to do it, at 0.960 recall@16 out of fifty options, even where its argmax is already unreliable.
- A yes/no without meaningful outcome descriptions loses 17.7 points, 83.83 against 66.17, and a description templated from the question is worse than none at all, 65.33. Write what each outcome means.
- The shipped temperatures barely change anything and are off by default. ECE 0.010 to 0.008, Brier 0.102 to 0.107.
- No escalation head, see above.
- Option order still changes the answer on 5.7% of
choicequestions. That is ahead of both published figures but it is not zero. - Trained and measured on English typed decisions. The backbone is multilingual and the tokenizer covers 256k tokens, but no non-English benchmark has been run — treat multilingual use as untested.
- The
guardrailsandmoderationtags reflect coverage of toxicity and hate-speech decisions. Neither capability has been benchmarked. - Reported global figures carry about ±0.15 of bf16 arithmetic noise. The 77.30 above is a single measurement, not a mean over seeds.
- Long states are truncated to the window with the questions reserved first.
License and provenance
The code and these weights are MIT, following the jhu-clsp/mmBERT-base
backbone. No weights, gradients or private data from any third-party decision
service are used or claimed; the design follows publicly documented API
behaviour and public benchmark splits.
Training data, stated plainly. Part of this checkpoint's training corpus
comes from tasksource/tasksource-jev-typed-decisions,
which carries license: other. Its own card says no single upstream licence
covers every row and that each source's licence should be checked before
reuse; it draws on 571 of them. That review has not been done for this
release. If your use is one where upstream data licensing matters, treat this
checkpoint as unreviewed on that point and say so downstream. The rest of the
corpus is either generated for this project or comes from
tasksource/procedural-jev,
which is Apache-2.0 and procedurally generated with no upstream data.
Neither dataset is affiliated with TypeSafe or OpenJev, and neither is this model.
1 maintainer

Release files for decision-jef 0.6.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| decision_jef-0.6.0.tar.gz | 40.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| decision_jef-0.6.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 74.8 kB
Release files / decision_jef-0.6.0.tar.gz
| Download URL | decision_jef-0.6.0.tar.gz |
|---|---|
| Size | 40.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
f50d7f13c0a71ab42fce54bcd09c62bb79bad64033fe0d7e9e7aee20bc0a9bda
|
|
BLAKE2b-256 checksum How to use checksums |
8d7e6500e58e380d81c599875caf987f1c901818e338e3189442a251a6dccd8b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.9
|
Release files / decision_jef-0.6.0-py3-none-any.whl
| Download URL | decision_jef-0.6.0-py3-none-any.whl |
|---|---|
| Size | 34.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d09ab97ef3a91bb7348388e19f34070bf6d848cb0d41e460ffac2713b462eb1e
|
|
BLAKE2b-256 checksum How to use checksums |
006888eb8838bdcc9e4545d5bf3284037f4bec3a29c51a86079744be7ff7e823
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.9
|














