
DocVortex
A fast, multi-format document parsing and conversion engine.
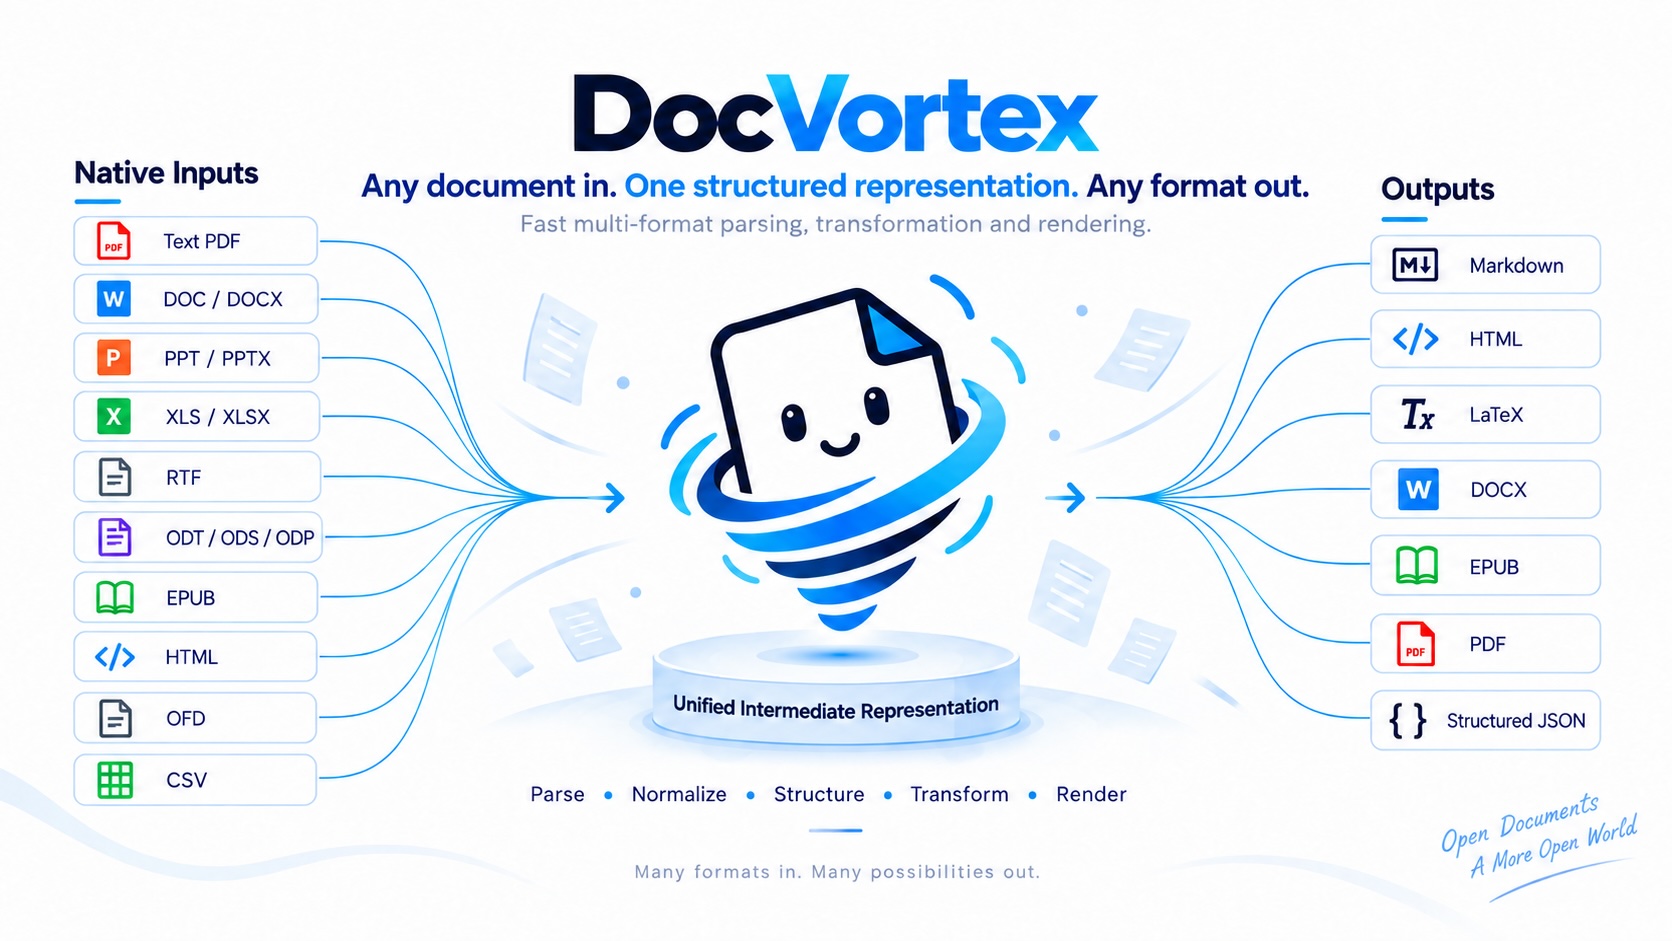
DocVortex provides a complete, standalone document pipeline:
Document -> Unified Intermediate Representation -> Render / Export
Native inputs include text PDFs, DOC/DOCX, PPT/PPTX, XLS/XLSX, RTF, ODT/ODS/ODP, EPUB, HTML, OFD and CSV. Output formats include Markdown, HTML, LaTeX, DOCX, EPUB, PDF and structured content.
Native parsing runs without OCR or VLM inference services. PDF classification is an explicit document operation; native analysis does not silently classify the document or select another inference backend.
Install
pip install docvortex
docvortex convert report.pdf --format markdown --output output/report.md
docvortex classify report.pdf
Python 3.10–3.14 is supported. Native parsing does not require OCR/VLM inference services.
Parse once, export many times
import docvortex

result = docvortex.parse("report.pdf", keep_model_json=True)
result.export("output/report.md", output_format="markdown")
result.export("output/report.docx", output_format="docx")
result.export("output/report.epub", output_format="epub")
result.save_bundle("output/report.bundle")

# This works after the source document and its parsing process are gone.
restored = docvortex.load_bundle("output/report.bundle")
restored.export("output/report.pdf", output_format="pdf")
Bundles contain manifest.json, middle.json, optional model.json, and image
assets. The loader verifies asset hashes. Missing external assets must be supplied
before saving a portable bundle. Existing files are protected unless the caller
explicitly sets overwrite=True.
Stage APIs
from docvortex.api import analyze, postprocess, render

analysis = analyze("report.pdf", page_range="1-5")
result = postprocess(analysis)
artifact = render(result.middle_json, "docx", assets=result.assets)
artifact.write("output/report.docx")
The stage API lives in docvortex.api. Root-level conveniences include parse,
analyze, convert, postprocess_document, and render_artifact. The
docvortex.render package also exposes the low-level renderers and their original
string, bytes, dictionary, or list return values.
PDF page selections use 1-5, r1 and all; other native formats are parsed as
whole documents. A caller-owned PDFDocument can be passed to analyze or parse
and remains open afterward.
Page images and embedded assets
from docvortex.assets import parse_image_data_uri_strict, transcode_image
from docvortex.content.tree import iter_image_payloads
from docvortex.document.pdf import PDFDocument

with PDFDocument("report.pdf") as document:
    image = document.render_image(0, bbox=(0.1, 0.2, 0.8, 0.7), image_format="png")
# image.data, image.width, image.height, image.mime_type and image.extension
# remain available after the document closes.
render_image accepts zero-based page indices, optional normalized bounding boxes
and jpeg (default), png or webp output. Omitting bbox renders the whole page.
Crops are encoded directly to the requested format. crop_image continues to
return JPEG bytes. Image sources opened with PDFDocument.from_image retain the
existing image-to-PDF conversion behavior.
docvortex.assets exposes immutable ImageArtifact and ImageFormat contracts.
parse_image_data_uri_strict(uri) validates embedded image bytes and returns
(data, extension); transcode_image(data, image_format="png") returns an
ImageArtifact. These operations do not fetch URLs or resolve filesystem paths,
and transcoding does not add SVG rasterization support.
iter_image_payloads(block) yields the current node, if it carries an image,
then traverses its children depth first without modifying the document tree.
Explicit PDF classification
from docvortex.document.pdf import PDFDocument

with PDFDocument("report.pdf") as document:
    mode = document.classify()  # "txt" or "ocr"; no inference is started
    if mode == "txt":
        result = docvortex.parse(document)
Native analysis trusts the caller's choice and does not classify automatically. Applications can use the classification result to select their own OCR or inference service when a document requires it.
DocVortex JSON uses schema identity docvortex.model or docvortex.middle, schema
version 2.0, and required metadata.file_suffix / metadata.producer. Definitions are in schemas/.
Application-specific metadata belongs in extensions. See the
shared JSON protocol and migration guide and the
compatibility guide for existing application integrations
and historical data formats. The HTML protocol describes
DocVortex markers and semantic round trips.
Scope and development
PDF output is a semantic reflow of the document, not a lossless reproduction of the original page drawing instructions. Input support for PPTX/XLSX does not imply PPTX/XLSX output support. Rust implementation work is a future stage behind these public data and processing boundaries.
uv venv
uv pip install -e ".[test,dev]"
uv run --no-project python -m pytest -q
uv run --no-project ruff check src
uv run --no-project ruff format --check src
uv build
DocVortex project code is licensed under the MIT License.
See rendering ownership for the seven engine targets, MinerU Content List integration and public fragment helpers.
Read source metadata without parsing the body
from docvortex import extract_metadata

inspection = extract_metadata("report.pdf")
print(inspection.metadata.document.title)
print(inspection.metadata.document.authors)
All 15 native document formats support this API. Normal parsing also carries these properties in
metadata.document, preserving the original PDF properties across page selections. See the
field definitions, format matrix, and compatibility notes.
Python 3.14 and text joining (0.3.0)
DocVortex supports ordinary CPython 3.10–3.14. Physical text lines are joined by deterministic Unicode boundary rules, with URL and dehyphenation safeguards. Language detection models and the fast-langdetect / fasttext-predict dependencies are no longer required.
The shared resolve_text_line_boundary and merge_text_line_contents helpers no longer accept block_language; detect_lang has been removed. Hosts should call the shared boundary helpers directly. OCR language selection and Magika code-language recognition are unchanged.
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file docvortex-0.3.0.tar.gz.
File metadata
- Download URL: docvortex-0.3.0.tar.gz
- Upload date:
- Size: 27.8 MB
- Tags: Source
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
c44f7d182eaa7bb77f21194afd613ed135e6f8debb9c40d29c846af2fde22222
|
|
| MD5 |
48d07a5d52950f8c35ebf2dbf57da616
|
|
| BLAKE2b-256 |
48ad1010a014af9f0bf39c18f6f36d642d4c0cb19e7e439fea7feaa82943f0bb
|
Provenance
The following attestation bundles were made for docvortex-0.3.0.tar.gz:
Publisher:
publish.yml on myhloli/DocVortex
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
docvortex-0.3.0.tar.gz -
Subject digest:
c44f7d182eaa7bb77f21194afd613ed135e6f8debb9c40d29c846af2fde22222 - Sigstore transparency entry: 2761009571
- Sigstore integration time:
-
Permalink:
myhloli/DocVortex@6a6be656882d58c468a6a0d821ee491dafea18f4 -
Branch / Tag:
refs/tags/v0.3.0 - Owner: https://github.com/myhloli
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
publish.yml@6a6be656882d58c468a6a0d821ee491dafea18f4 -
Trigger Event:
release
-
Statement type:
File details
Details for the file docvortex-0.3.0-py3-none-any.whl.
File metadata
- Download URL: docvortex-0.3.0-py3-none-any.whl
- Upload date:
- Size: 4.3 MB
- Tags: Python 3
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
2f32c9a3ea4b5cf5004d79f2a603d3d1b652779e0f1d708637ec302e90541259
|
|
| MD5 |
3c3cb427a53d5914926ac0fe5dbf120d
|
|
| BLAKE2b-256 |
df5a77fbbfdeeaa2d75180c996bcf6dc25d4f04fc57d4acf2429884e4db49e2c
|
Provenance
The following attestation bundles were made for docvortex-0.3.0-py3-none-any.whl:
Publisher:
publish.yml on myhloli/DocVortex
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
docvortex-0.3.0-py3-none-any.whl -
Subject digest:
2f32c9a3ea4b5cf5004d79f2a603d3d1b652779e0f1d708637ec302e90541259 - Sigstore transparency entry: 2761009640
- Sigstore integration time:
-
Permalink:
myhloli/DocVortex@6a6be656882d58c468a6a0d821ee491dafea18f4 -
Branch / Tag:
refs/tags/v0.3.0 - Owner: https://github.com/myhloli
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
publish.yml@6a6be656882d58c468a6a0d821ee491dafea18f4 -
Trigger Event:
release
-
Statement type:














