




Documents in. Possibilities out.
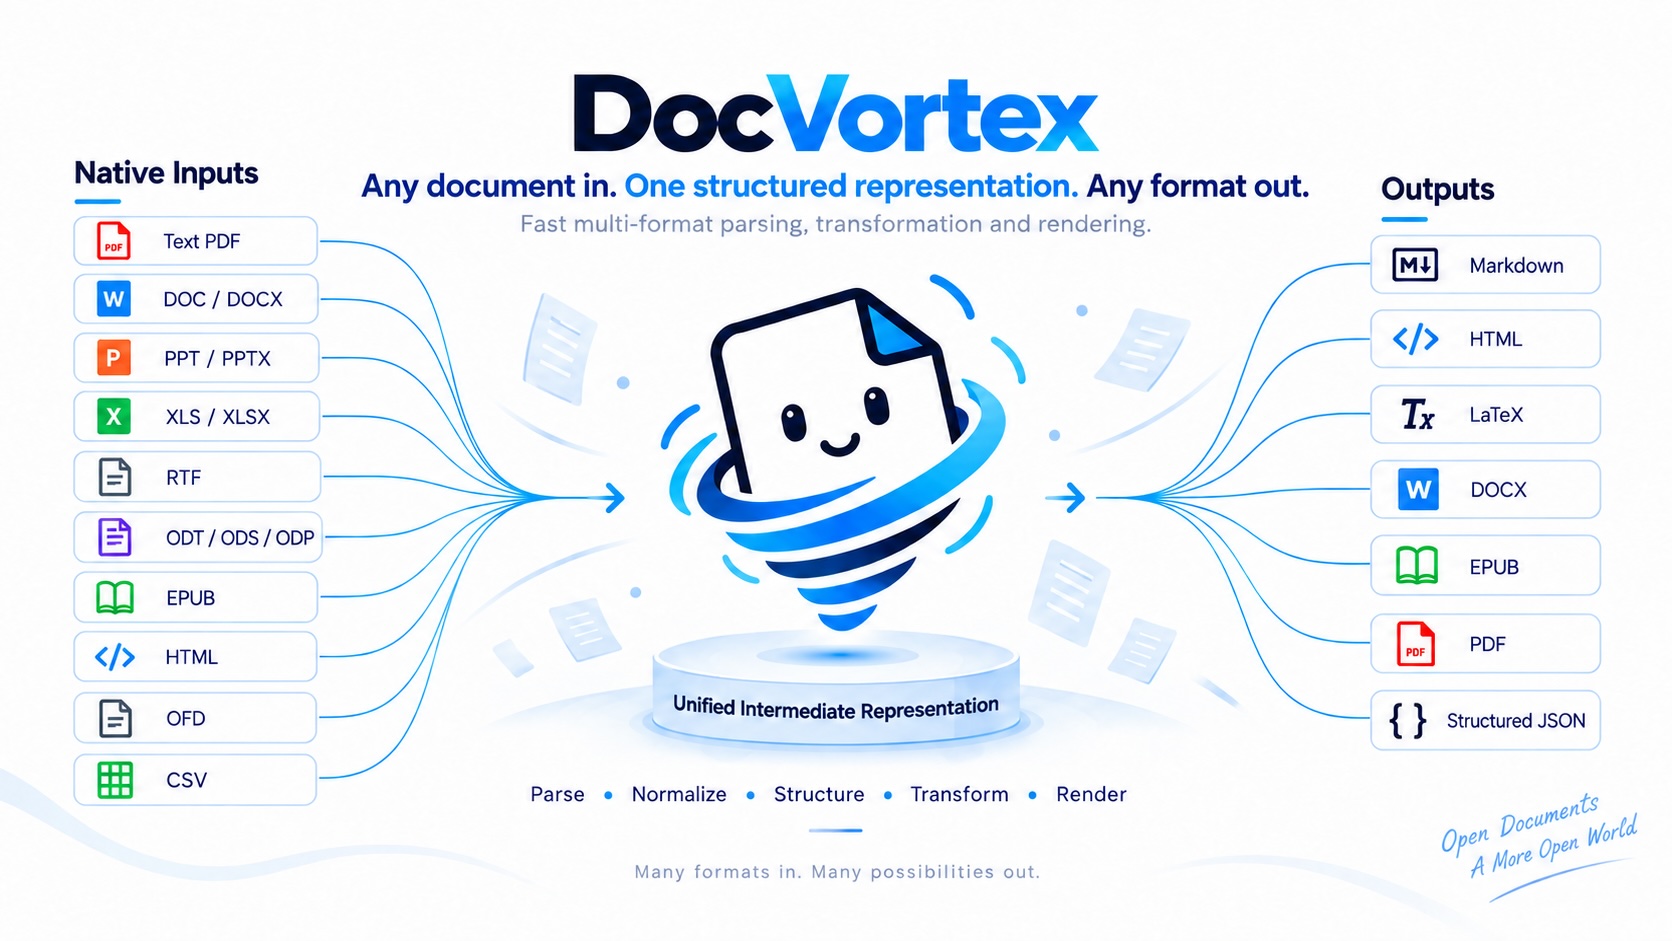
DocVortex is a standalone Python engine for parsing and converting documents. It reads native text and document structure into a unified representation, then exports the result in the formats your workflow needs.
- Multi-format input — read text PDFs, Office files, OpenDocument files, EPUB, HTML, OFD and CSV.
- Parse once, export many times — reuse the same result for Markdown, HTML, LaTeX, DOCX, EPUB, PDF and structured JSON.
- Portable results — save document structure and image assets in a Bundle, then export again without the source file.
- Composable APIs — use the complete pipeline or integrate analysis, postprocessing and rendering separately.
Native parsing works without an OCR or VLM inference service. Use DocVortex directly through its CLI or Python SDK, independently of MinerU.
Quick start
Requires Python 3.10–3.14.
Install
pip install docvortex
Command line
Convert a text PDF to Markdown:
docvortex convert report.pdf --format markdown --output output/report.md
Replace report.pdf with a local file in any supported input format.
Use --format to choose the output; run docvortex convert --help for options.
The root-level --log-level option controls loguru output and defaults to info.
It must precede the command; DOCVORTEX_LOG_LEVEL=warning can also configure it.
Python
Parse a document once and export it twice:
import docvortex

result = docvortex.parse("report.pdf")
result.export("output/report.md", output_format="markdown")
result.export("output/report.docx", output_format="docx")
The result owns its document structure and assets, so further exports do not
reopen or reparse the source. Existing output files are protected by default;
use overwrite=True in Python or --overwrite in the CLI to replace them.
Supported formats
Native inputs · 15 formats
| Document family | Formats |
|---|---|
| PDF with native text | |
| Word & rich text | DOC, DOCX, RTF |
| Presentations | PPT, PPTX |
| Spreadsheets | XLS, XLSX, CSV |
| OpenDocument | ODT, ODS, ODP |
| E-books & web documents | EPUB, HTML |
| Open Fixed-layout Document | OFD |
Outputs · 7 formats
| Output | --format / output_format |
|---|---|
| Markdown | markdown |
| HTML | html |
| LaTeX | latex |
| Word document | docx |
| EPUB e-book | epub |
pdf |
|
| Structured JSON | structured_content |
PPT/PPTX and XLS/XLSX are input formats only. Structured JSON is an export format; the document JSON protocol separately defines the analysis and intermediate representations.
Save now, export later
A Bundle packages the parsed document and its image assets for reuse across processes or machines. Load it whenever you need another output format:
import docvortex

result = docvortex.parse("report.pdf")
result.save_bundle("output/report.bundle")

restored = docvortex.load_bundle("output/report.bundle")
restored.export("output/report.epub", output_format="epub")
The restored result works without the original file. See the usage guide for Bundle contents, asset handling and overwrite rules.
Need only the title, authors or other source properties?
docvortex.extract_metadata()
reads metadata without parsing the document body.
Choose the right workflow
- Text PDFs: native parsing uses the document's existing text and structure. Scanned pages requiring OCR need an external OCR or inference service.
- PDF classification:
docvortex classify report.pdfreturnstxtorocr. Classification is explicit and does not start inference; parsing does not automatically switch backends. - PDF export: PDF sources with page geometry default to block layout restoration, with selectable text and HTML-based tables; charts retain region images. Other sources and older results use semantic reflow. Use
--pdf-layout original|reflowto select explicitly; fonts, line breaks and drawing instructions are not reproduced losslessly. See PDF output layout.
Documentation
| Guide | What you will find |
|---|---|
| Usage | Stage APIs, PDF pages, classification, images and Bundles |
| Agent skill | CLI and Python SDK workflows for agents; copy the entire skills/docvortex folder to reuse |
| Examples | Local PDF and Office samples with a runnable demo |
| Metadata | Source properties and per-format coverage |
| JSON protocol | Document schemas, extensions and protocol migration |
| HTML protocol | Semantic markers and round trips |
| Public SDK & migration | Supported integration boundaries and the 0.4 upgrade |
| Rendering ownership | DocVortex exports and MinerU-specific renderers |
Development
From a local checkout:
uv venv
uv pip install -e ".[test,dev]"
uv run --no-project python -m pytest -q
uv run --no-project ruff check src
uv run --no-project ruff format --check src
uv build
Bug reports and contributions are welcome. When reporting a parsing issue, include a reproducible command and a sample document you can share in GitHub Issues.
License
DocVortex project code is released under the MIT License.
1 maintainer

Download files
Download the file for your platform. If you're not sure which to choose, learn more about installing packages.
Source Distribution
Built Distribution
Filter files by name, interpreter, ABI, and platform.
If you're not sure about the file name format, learn more about wheel file names.
Copy a direct link to the current filters
File details
Details for the file docvortex-0.4.7.tar.gz.
File metadata
- Download URL: docvortex-0.4.7.tar.gz
- Upload date:
- Size: 40.0 MB
- Tags: Source
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
263bb5a5b2a8161d8ad1c51a5c13dbbcebc6fcd1400ae5ca2294c70853f5b50e
|
|
| MD5 |
9266e3d2869be155c1713e19f44b7e08
|
|
| BLAKE2b-256 |
cd3ef42954a1c6069081ec261f2fd486e7368f88a48ec0118e70540dc362e85b
|
Provenance
The following attestation bundles were made for docvortex-0.4.7.tar.gz:
Publisher:
publish.yml on myhloli/DocVortex
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
docvortex-0.4.7.tar.gz -
Subject digest:
263bb5a5b2a8161d8ad1c51a5c13dbbcebc6fcd1400ae5ca2294c70853f5b50e - Sigstore transparency entry: 2850460249
- Sigstore integration time:
-
Permalink:
myhloli/DocVortex@a6b462c101d58551d4a12425af9a32f5f44201d1 -
Branch / Tag:
refs/tags/v0.4.7 - Owner: https://github.com/myhloli
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
publish.yml@a6b462c101d58551d4a12425af9a32f5f44201d1 -
Trigger Event:
release
-
Statement type:
File details
Details for the file docvortex-0.4.7-py3-none-any.whl.
File metadata
- Download URL: docvortex-0.4.7-py3-none-any.whl
- Upload date:
- Size: 4.4 MB
- Tags: Python 3
- Uploaded using Trusted Publishing? Yes
- Uploaded via:
twine/7.0.0 CPython/3.13.14
File hashes
| Algorithm | Hash digest | |
|---|---|---|
| SHA256 |
f1340835bb3700a3983c0766ed2b82e11782e9a798da3921cafc1e2cd145d727
|
|
| MD5 |
8fb31e2477ab84b1f790bce4ad327a39
|
|
| BLAKE2b-256 |
99b47fe4853879ec739cd480ab0d39663560f6416efa28f34349bf9298967954
|
Provenance
The following attestation bundles were made for docvortex-0.4.7-py3-none-any.whl:
Publisher:
publish.yml on myhloli/DocVortex
-
Statement:
-
Statement type:
https://in-toto.io/Statement/v1 -
Predicate type:
https://docs.pypi.org/attestations/publish/v1 -
Subject name:
docvortex-0.4.7-py3-none-any.whl -
Subject digest:
f1340835bb3700a3983c0766ed2b82e11782e9a798da3921cafc1e2cd145d727 - Sigstore transparency entry: 2850460328
- Sigstore integration time:
-
Permalink:
myhloli/DocVortex@a6b462c101d58551d4a12425af9a32f5f44201d1 -
Branch / Tag:
refs/tags/v0.4.7 - Owner: https://github.com/myhloli
-
Access:
public
-
Token Issuer:
https://token.actions.githubusercontent.com -
Runner Environment:
github-hosted -
Publication workflow:
publish.yml@a6b462c101d58551d4a12425af9a32f5f44201d1 -
Trigger Event:
release
-
Statement type:














