
donelogger


Time long-running steps with two ordinary log lines.
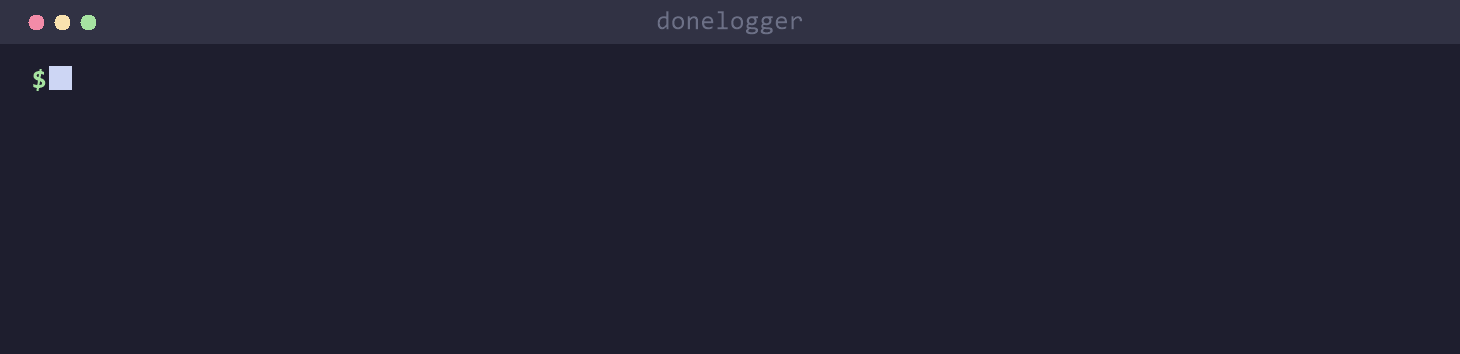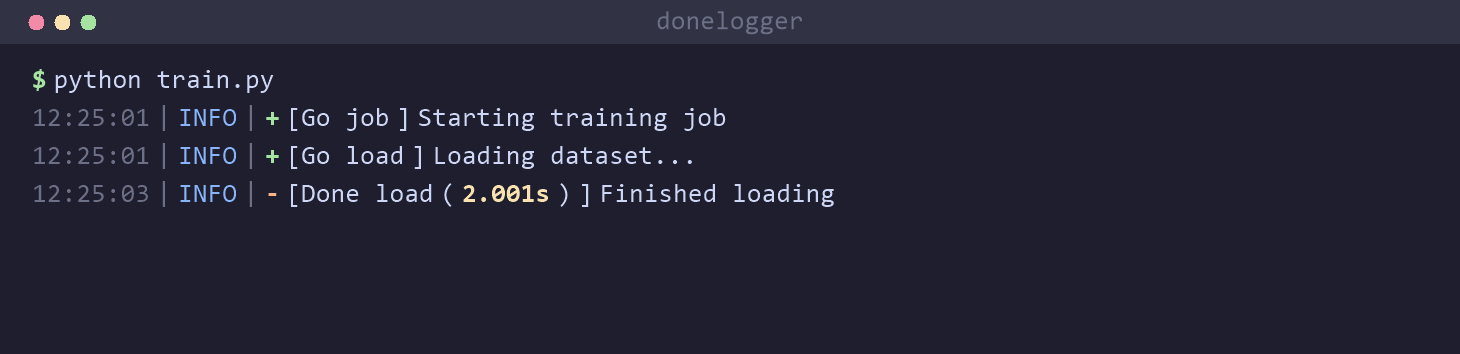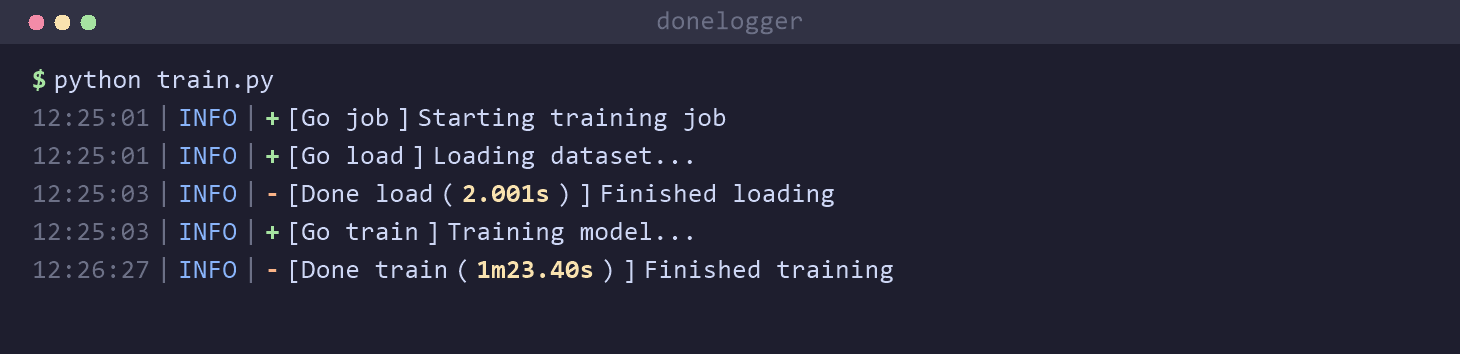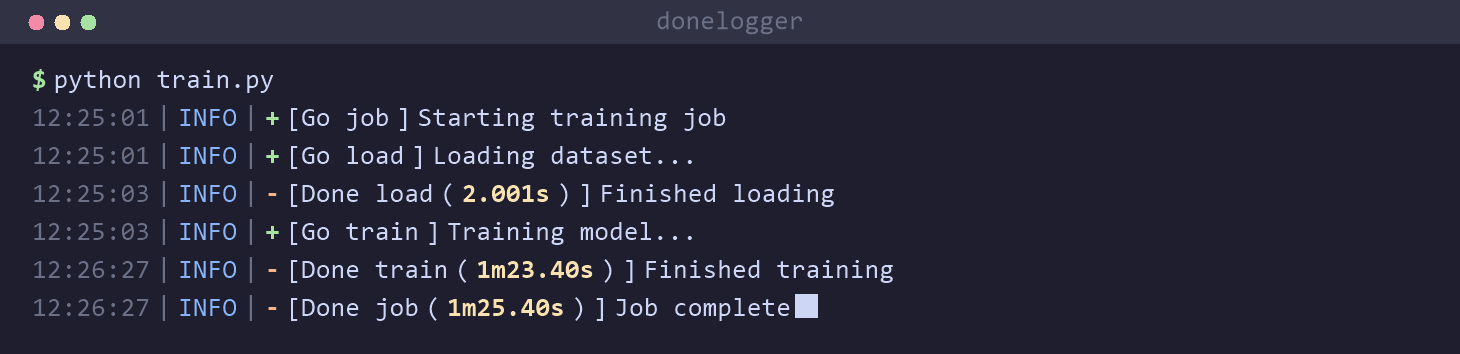
Write [Start] when work begins and [Done] when it ends. donelogger fills
the elapsed time into the log line for you.
from donelogger import getLogger

logger = getLogger()

logger.info("[Start] Training model...")
train()
logger.info("[Done] Finished")
# -> +[Go Job] Training model...
# -> -[Done Job(1m23.40s)] Finished     ← elapsed time, measured for you
That's the whole idea: no time.perf_counter() variables, no manual
subtraction, no f"{...:.3f}s" formatting scattered through your code.
If you've ever written this:
t0 = time.perf_counter()
logger.info("Loading dataset...")
load_dataset()
logger.info(f"Finished loading in {time.perf_counter() - t0:.3f}s")
you can write this instead:
logger.info("[Start] Loading dataset...")
load_dataset()
logger.info("[Done] Finished loading")
# -> -[Done Job(2.413s)] Finished loading
The timing is just part of the log. Your call sites stay plain
logger.info(...), and everything that is not a marker remains a normal log
message.
No tag needed for the basic case. When you want to time nested or overlapping
steps, add an optional :tag ([Start:train] ... [Done:train]).
Battle-tested: donelogger runs in production internal tooling, where knowing "how long did each stage take?" across a long pipeline matters every day.
Installation
pip install donelogger
Why donelogger?
1. Make timing cheap enough to use everywhere
When timing is annoying, you only add it after something gets slow. donelogger makes it cheap enough to leave timing breadcrumbs throughout a script, CLI, batch job, ML run, or data pipeline:
logger.info("[Start] Download files")
download_files()
logger.info("[Done] Downloaded")

logger.info("[Start] Parse records")
parse_records()
logger.info("[Done] Parsed")

logger.info("[Start] Write output")
write_output()
logger.info("[Done] Wrote output")
You get readable progress logs while the job runs, and elapsed times once each step finishes. This pays off most once timings are nested — when you want an inner step's time and the whole job's time without scrolling back up the log to subtract two timestamps by hand. (See nested timing.)
2. Skip the logging setup boilerplate
Getting plain logging to print the way you want takes a handler, a formatter,
a level, and a few lines of wiring before a single line shows up:
# Before — standard logging needs setup before it's usable
import logging, sys
logger = logging.getLogger("myapp")
logger.setLevel(logging.INFO)
handler = logging.StreamHandler(sys.stdout)
handler.setFormatter(logging.Formatter("%(asctime)s|%(levelname)s|%(message)s",
                                        "%d/%m/%Y %H:%M:%S"))
logger.addHandler(handler)
getLogger() does all of that for you — and hands back a real
logging.Logger, so levels, file output, and custom formats keep working
exactly as you'd expect:
# After — configured and ready in one line
from donelogger import getLogger
logger = getLogger()                      # console-ready, sensible defaults
logger = getLogger(logfile="app.log")     # ...also writes to a rotating file
Nothing proprietary to learn: it's logging underneath, just without the setup.
Features
- Zero-boilerplate timing — wrap work in
[Start]/[Done]; the elapsed time is filled in for you, no tag required. - One-line setup —
getLogger()returns a ready-to-use, reallogging.Logger;.info()/.warning()/.error()and named tags all work unchanged. - Named & cross-module tags — time nested or overlapping stages independently, even starting in one file and finishing in another.
- Human-friendly durations — adaptive units from microseconds to hours (
300us,512.0ms,1m15.40s), or force fixed seconds. - Zero dependencies — pure standard library, with an optional one-argument rotating file log.
Usage
Default timer (no tag required)
Tags are optional. Bare [Start] / [Done] use a default timer named Job:
logger.info("[Start] Processing")
# ... work ...
logger.info("[Done] Complete")
# -> -[Done Job(512.0ms)] Complete
Named tags: time nested or overlapping work
Bare [Start] / [Done] track one thing at a time. Add a :tag to run several
timers at once — ideal when you want an inner step's time and the overall
time, without scrolling back up the log to subtract timestamps by hand:
logger.info("[Start:total] Pipeline starting")
logger.info("[Start:load]  Loading dataset...")
load_dataset()
logger.info("[Done:load]   Data ready")          # inner step time
train()
logger.info("[Done:total]  Pipeline finished")   # whole-pipeline time
# -> -[Done load(2.001s)] Data ready
# -> -[Done total(1m25.40s)] Pipeline finished
Timers are independent, so tags can nest (as above) or overlap freely without clobbering each other:
logger.info("[Start:download] Downloading files")
logger.info("[Start:parse]    Parsing config")
logger.info("[Done:parse]     Config ready")     # parse stops first
logger.info("[Done:download]  Files saved")      # download stops later
Cross-module timing
getLogger(name=...) returns the same logger instance for a given name
(process-wide singleton), and the timer state lives on that logger. So any
module that calls getLogger() with the same name shares the same timers —
start in one file, finish in another:
# === data_loader.py ===
from donelogger import getLogger
getLogger().info("[Start:pipeline] Begin data pipeline")

# === trainer.py ===
from donelogger import getLogger
# ... after all stages finish ...
getLogger().info("[Done:pipeline] Pipeline complete")
# -> -[Done pipeline(42.300s)] Pipeline complete
Loggers created with different names keep independent timers, so unrelated components never clobber each other's tags.
Because the logger is shared, the first getLogger() call is usually made by an
imported module with the defaults, not by your entry point. Explicit settings
are therefore applied on every call, not only the creating one: a later
getLogger(logfile=...) adds the file handler (once per path), and a later
logLevel / fmt / datefmt / elapsed_style replaces the current value.
Omitted arguments leave the existing configuration untouched, so plain
getLogger() calls in other modules never reset what the entry point set.
Regular logging
Everything that isn't a marker passes straight through — donelogger is a normal logger:
logger.info("Just a normal message")
logger.warning("This is a warning")
logger.error("Something went wrong")
(Only INFO-level messages are scanned for markers; other levels are never
touched.)
Choosing the elapsed-time format
elapsed_style controls how durations are rendered (default "adaptive"):
logger = getLogger(elapsed_style="adaptive")  # 300us, 512.0ms, 1.003s, 1m15.40s, 1h15m00s
logger = getLogger(elapsed_style="seconds")   # fixed 3 decimals: 0.300s, 1.003s, 1m15.400s
File logging
Pass logfile= to also write to a rotating file (1 MB × 2 backups) with a
detailed, machine-friendly format:
logger = getLogger(name="myapp", logfile="app.log")
This can come from the entry point after other modules already created the logger; the file is attached to the shared logger, so their output lands in it too. Asking twice for the same path attaches it once.
Full configuration
import logging
from donelogger import getLogger

logger = getLogger(
    name="myapp",
    logLevel=logging.DEBUG,
    logfile="app.log",
    fmt="%(asctime)s|%(levelname)s|%(message)s",
    datefmt="%d/%m/%Y %H:%M:%S",
    elapsed_style="adaptive",
)
Marker syntax
| Marker | Meaning |
|---|---|
[Start] / [Go] |
Start the default (Job) timer |
[Start:tag] / [Go:tag] |
Start a named timer |
[Done] |
Stop the default timer and print elapsed time |
[Done:tag] |
Stop a named timer and print elapsed time |
- The keyword is case-insensitive (
start,Start,go,Go,done,Done). - A marker is only recognized at the very beginning of the message.
[Done:tag]without a prior[Start:tag]emits*LOG ERROR* (tag is not started) {...}so mistakes are obvious.- A tag is not consumed on
[Done], so you can stop the same tag more than once (each reports elapsed since its[Start]).
Output format
+[Go data_load] Loading dataset...      ← '+' = timer started
-[Done data_load(2.001s)] Finished      ← '-' = timer stopped, elapsed shown
adaptive (default) picks a unit by magnitude:
| Duration | Rendered |
|---|---|
| 300 µs | 300us |
| 5 ms | 5.0ms |
| 0.512 s | 512.0ms |
| 1.003 s | 1.003s |
| 75.4 s | 1m15.40s |
| 4500 s | 1h15m00s |
seconds uses fixed three-decimal second precision (handy when you
post-process logs), while still grouping durations of a minute or more:
| Duration | Rendered |
|---|---|
| 0.005 s | 0.005s |
| 75.4 s | 1m15.400s |
| 4500 s | 75m00.000s |
API
getLogger(name="doneLogger", logLevel=logging.INFO, logfile=None, fmt=..., datefmt=..., elapsed_style="adaptive")
Returns a configured logging.Logger. Calling it again with the same name
returns the cached instance (so configuration only happens once). Configure a
named logger at your entry point before retrieving it from other modules; later
calls intentionally preserve the first call's configuration.
| Parameter | Default | Description |
|---|---|---|
name |
"doneLogger" |
Logger name. Same name → same instance (and shared timers). "root" configures the root logger. |
logLevel |
logging.INFO |
Level for the console handler / logger. |
logfile |
None |
If set, also log to this file via a rotating handler (1 MB × 2 backups). |
fmt |
%(asctime)s|%(levelname)s|%(message)s |
Console log format (standard logging format string). |
datefmt |
%d/%m/%Y %H:%M:%S |
Timestamp format. |
elapsed_style |
"adaptive" |
"adaptive" (µs→h) or "seconds" (fixed three-decimal second precision). |
The package also exposes DoneloggerFormatter, DoneloggerStreamHandler, and
LoggerManager for advanced/custom wiring. DoneloggerFormatter is a drop-in
logging.Formatter (the standard fmt / datefmt / style arguments still
work), with one extra keyword-only argument, elapsed_style.
How it works
donelogger installs a custom logging.Formatter that inspects each INFO
message. A [Start]/[Go] marker records time.perf_counter() in the
formatter attached to that logger; the matching [Done] looks it up, computes
the delta, and renders the line with the elapsed time. The original log record
is left untouched, so other handlers can format it independently. Because the
timing behavior is in the formatter, your call sites stay plain
logger.info(...) calls and non-marker logging is unaffected.
Testing
python -m unittest discover
The suite is dependency-free and mocks time.perf_counter, so the timing
assertions are deterministic (no sleep, no flakiness).
Releasing
Maintainers: see RELEASING.md. Releases publish to PyPI automatically via GitHub Actions when a GitHub Release is published.
License
1 maintainer

Release files for donelogger 0.1.11
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| donelogger-0.1.11.tar.gz | 13.3 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| donelogger-0.1.11-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 24.1 kB
Release files / donelogger-0.1.11.tar.gz
| Download URL | donelogger-0.1.11.tar.gz |
|---|---|
| Size | 13.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
33d2f0acb4a1c7d8a214541e47084eb4508623c881408e65f70a9ab5d29a4625
|
|
BLAKE2b-256 checksum How to use checksums |
4da43a737834284eed47c846a4b6ff318e7e1b1378c5452d9f3a6c24ab481ed4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 25, 2026.
Transparency logRelease files / donelogger-0.1.11-py3-none-any.whl
| Download URL | donelogger-0.1.11-py3-none-any.whl |
|---|---|
| Size | 10.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
064597309627337a1516e88a4876ee71be164a15f66f1d02da652382a6f4d557
|
|
BLAKE2b-256 checksum How to use checksums |
3af56795a8a84bc06bd636d5836a29639379ec4eb69144b166f8d61278ae50a2
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 25, 2026.
Transparency log













