
Dory
Persistent memory for AI agents. Graph-based retrieval, principled forgetting, and a local SQLite-backed memory graph. No server required.
pip install dory-memory
from dory import DoryMemory

mem = DoryMemory()
mem.observe("User prefers local-first AI")
mem.observe("User switched from llama.cpp to MLX — 25% faster")

print(mem.query("what does the user prefer for inference?"))
# → MLX (updated preference, supersedes llama.cpp)
Current benchmark result: 84.8% on LongMemEval (500-question oracle split, Haiku judge) — all-time best. Temporal-reasoning 90.2%, single-session-assistant 89.3%. See Benchmark results and Reproducing the benchmark.
v1.0.0 — verbatim extraction from assistant turns, supplementary FTS sweep for multi-session retrieval, all-time best benchmark score.
The problem
Every session, your agent starts from zero. Many systems that claim to "remember" still reduce memory to retrieval over a flat list of notes.
The deeper problem: naive context injection makes things worse. Research (Chroma, 2025) shows all major frontier models degrade starting at 500–750 tokens of context. Dumping everything into a prompt creates noise that degrades performance on the things that actually matter.
What Dory does
Four memory types
| Type | What it stores | Status |
|---|---|---|
| Episodic | Past events, sessions, experiences | ✓ |
| Semantic | Facts, preferences, entities, relationships | ✓ |
| Procedural | Skills, workflows, repeatable processes | ✓ |
| Working | Ephemeral session-scoped facts; auto-archived after consolidation | ✓ |
Spreading activation retrieval — relevant memories can pull in connected memories through the graph. "payments API" activates "Stripe" activates "webhook handler" activates "retry logic" because those things co-occurred.
Cacheable prefix output — Dory splits output into a stable prefix (unchanged until memory changes, enabling prompt cache hits) and a dynamic suffix (query-specific). This is designed to reduce prompt churn and make repeated agent calls cheaper.
Principled forgetting — three decay zones: active, archived, expired. Scores based on recency + frequency + relevance. Archived memories are queryable for historical context ("what was true in January?"). Decay never deletes; it only changes visibility.
Provable erasure — dory forget physically removes content from nodes, edges, the search index, and the raw conversation turns it was derived from, then writes a hash-chained receipt so the deletion can be verified later without retaining what was deleted.
Bi-temporal conflict resolution — when a fact changes, the old version is archived with a SUPERSEDES edge and a timestamp. Full provenance for every update.
Zero-server stack — single SQLite file. FTS5 for keyword search, adjacency tables for the graph. Works offline and stays easy to inspect locally.
Quick start
from dory import DoryMemory

mem = DoryMemory()

# Add memories manually
mem.observe("User is migrating the auth system from JWT to OAuth2", node_type="EVENT")
mem.observe("User prefers async Python over synchronous frameworks", node_type="PREFERENCE")
mem.observe("The migration deadline is end of Q2", node_type="EVENT")

# Query — returns context to inject into your LLM prompt
context = mem.query("auth migration deadline")
print(context)

# End of session: consolidate, decay, promote core memories
mem.consolidate()  # flush() is a kept alias

# See your graph in the browser
mem.visualize()
# Or explicitly opt into the remote D3 interactive view
mem.visualize(allow_remote_js=True)
Or from the command line:
dory visualize                    # local-only fallback view, no remote JS
dory visualize --remote-assets    # full interactive D3 view
dory show               # print stats + core memories
dory query "topic"      # spreading activation from the terminal
dory explain <node_id>  # provenance chain: what superseded it, what it supersedes
With auto-extraction (Dory extracts memories from conversation turns automatically):
mem = DoryMemory(extract_model="qwen3:8b")                  # local via Ollama (5 GB)
mem = DoryMemory(extract_model="qwen3:14b")                 # local via Ollama (9 GB, better quality)
mem = DoryMemory(                                           # Claude
    extract_model="claude-haiku-4-5-20251001",
    extract_backend="anthropic",
    extract_api_key="sk-ant-...",
)
mem = DoryMemory(                                           # GPT / Grok / any compat
    extract_model="gpt-4o-mini",
    extract_backend="openai",
    extract_api_key="sk-...",
)

# Log turns — extraction happens automatically every N turns
mem.add_turn("user", "I need to add rate limiting to the API today")
mem.add_turn("assistant", "What backend are you using?")

# Build API-ready messages with prompt caching
result = mem.build_context("rate limiting API")
messages = result.as_anthropic_messages(user_query)   # Anthropic SDK w/ cache_control
messages = result.as_openai_messages(user_query)      # OpenAI / compat
MCP server
dory-mcp is a standard MCP stdio server. It works with any MCP-compatible agent tool.
pip install 'dory-memory[mcp]'
which dory-mcp   # note this path — you'll need it below
The --db path defaults to ~/.dory/engram.db if omitted. You can also set DORY_DB_PATH as an environment variable. Use the same path across all tools so they share one memory graph.
Five tools are exposed: dory_query, dory_observe, dory_consolidate, dory_visualize, dory_stats.
Claude Code — registers globally across all projects:
claude mcp add --scope user dory -- /full/path/to/dory-mcp --db ~/.dory/engram.db
claude mcp list   # should show dory ✓ Connected
Claude Desktop — add to claude_desktop_config.json:
{
  "mcpServers": {
    "dory": {
      "command": "/full/path/to/dory-mcp",
      "args": ["--db", "/Users/you/.dory/engram.db"]
    }
  }
}
Codex — add to ~/.codex/config.yaml:
mcpServers:
  dory:
    command: /full/path/to/dory-mcp
    args:
      - --db
      - ~/.dory/engram.db
Cursor / Windsurf / Continue / any MCP client — add to the tool's MCP server config (usually a JSON file):
{
  "mcpServers": {
    "dory": {
      "command": "/full/path/to/dory-mcp",
      "args": ["--db", "/Users/you/.dory/engram.db"]
    }
  }
}
For a practical repo-local workflow, see docs/AGENT_MEMORY_WORKFLOW.md.
For shared memory across multiple tools in the same project, see docs/CODEX_INTEGRATION.md.
REST API + browser extension
Run Dory as a local HTTP server and use it from any browser-based AI chat:
pip install 'dory-memory[serve]'
dory serve                  # starts on http://127.0.0.1:7341
dory serve --port 8080      # custom port
dory serve --db ~/my.db     # custom database
Endpoints: GET /health · GET /query?topic=... · POST /observe · POST /ingest · GET /stats · GET /nodes
Browser extension — persistent memory sidebar for claude.ai, chatgpt.com, gemini.google.com, and perplexity.ai:
- Start
dory serve - In Chrome:
chrome://extensions→ "Load unpacked" → selectDory/browser-extension/ - Open any supported chat site — the Dory panel slides in from the right
The panel queries your memory graph on page load, re-queries after each AI response, and auto-extracts memories from every conversation turn in the background. Cmd+Shift+M toggles the panel.
Visualization
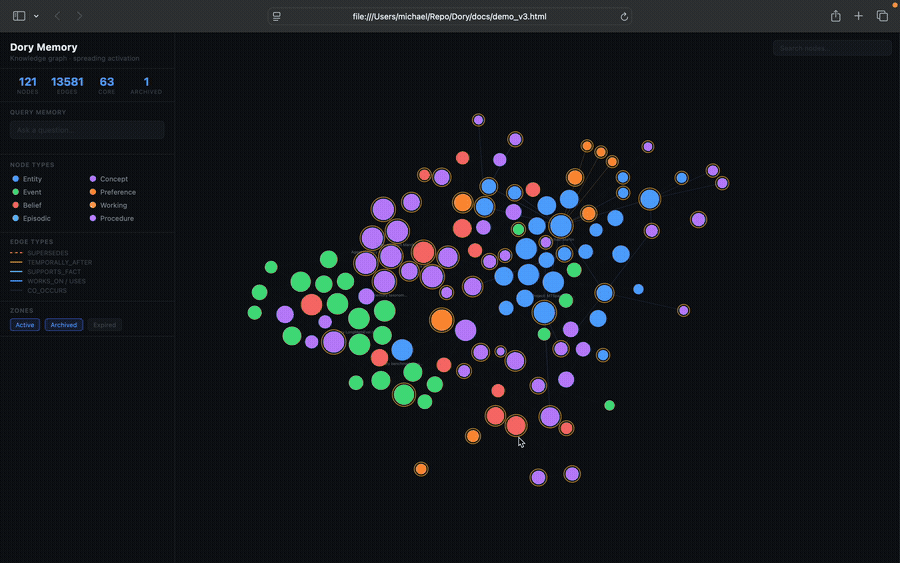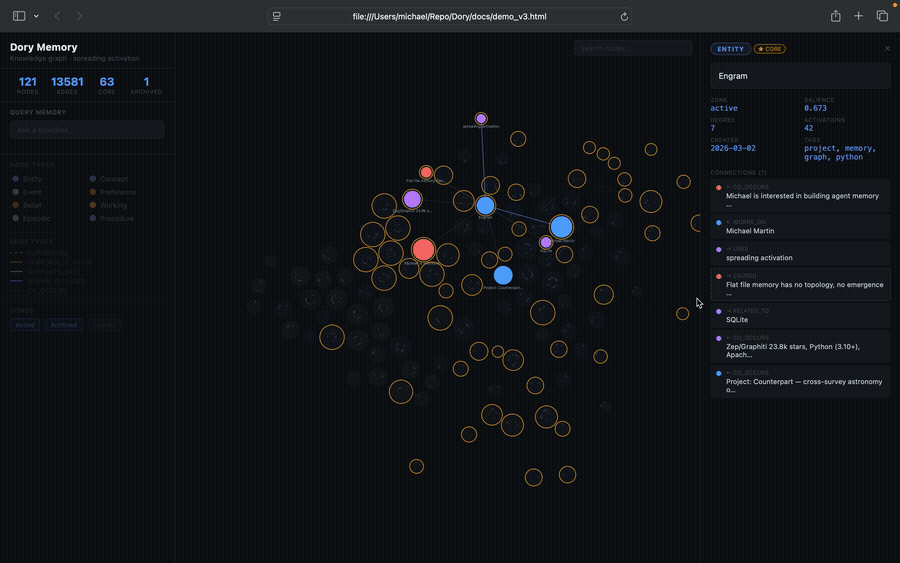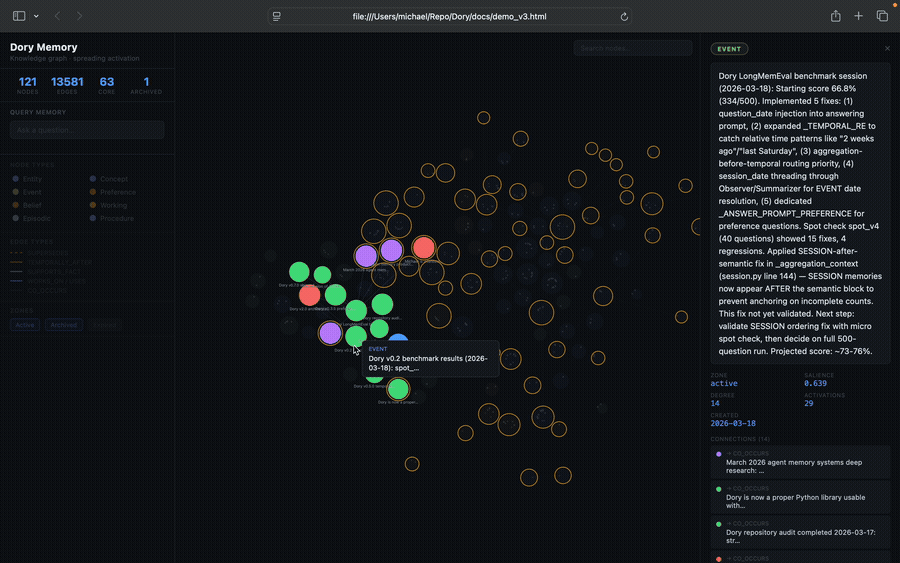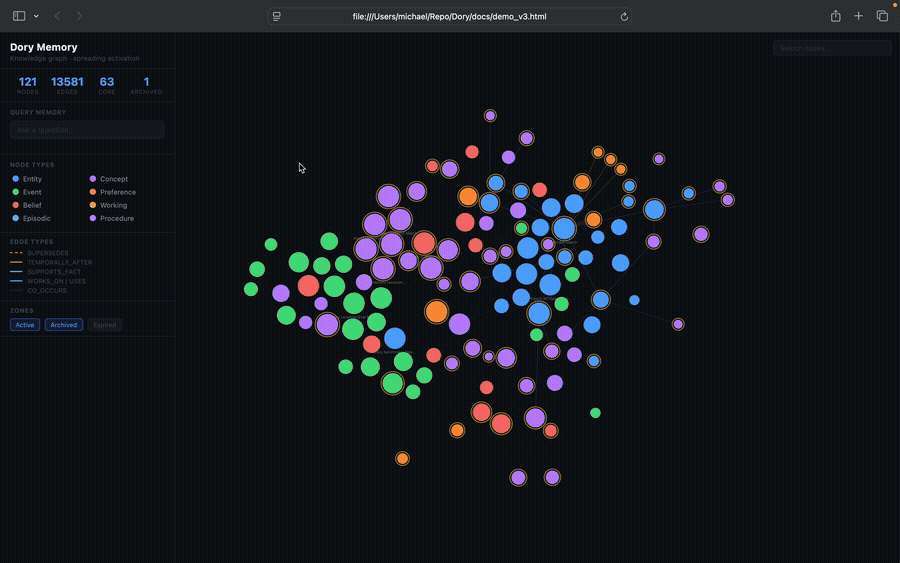
The hosted demo uses the fully interactive D3 view.
Locally, generated visualizations now default to a local-only fallback page that
shows the full node and edge data without loading remote JavaScript. If you want
the old interactive graph locally, opt in with allow_remote_js=True or
dory visualize --remote-assets.
Framework adapters
LangChain — drop-in BaseMemory replacement:
from dory.adapters.langchain import DoryMemoryAdapter
from langchain.chains import ConversationChain
from langchain_anthropic import ChatAnthropic

memory = DoryMemoryAdapter(
    extract_model="claude-haiku-4-5-20251001",
    extract_backend="anthropic",
    extract_api_key="sk-ant-...",
)
chain = ConversationChain(llm=ChatAnthropic(model="claude-sonnet-4-6"), memory=memory)
LangGraph — graph nodes with the (state) -> state signature:
from dory.adapters.langgraph import DoryMemoryNode, MemoryState
from langgraph.graph import StateGraph, START, END

mem = DoryMemoryNode(extract_model="claude-haiku-4-5-20251001", extract_backend="anthropic")

builder = StateGraph(MemoryState)
builder.add_node("load_memory", mem.load_context)
builder.add_node("record_turn", mem.record_turn)
builder.add_edge(START, "load_memory")
builder.add_edge("load_memory", "record_turn")
builder.add_edge("record_turn", END)
graph = builder.compile()
Multi-agent — shared memory pool with thread-safe writes and agent attribution:
from dory.adapters.multi_agent import SharedMemoryPool

pool = SharedMemoryPool(db_path="shared.db")
pool.observe("User prefers dark mode", agent_id="agent-1")
pool.add_turn("user", "Let's ship it", agent_id="agent-2", session_id="s1")
results = pool.query("UI preferences")
Async API
All DoryMemory methods have async counterparts — safe to await from FastAPI, LangGraph, and any async framework:
context = await mem.aquery("current topic")
result  = await mem.abuild_context("current topic")
await mem.aadd_turn("user", "message")
node_id = await mem.aobserve("User prefers JWT", node_type="PREFERENCE")
stats   = await mem.aconsolidate()  # aflush() is a kept alias
Export / import
from dory.export.jsonld import JSONLDExporter

exporter = JSONLDExporter(graph)
exporter.export("memory.jsonld.json")
JSONLDExporter.import_into(graph, "memory.jsonld.json")
Security notes
Security and hardening guidance lives in:
SECURITY.mddocs/HARDENING_2026-03-29.mddocs/REPO_CLEANUP_2026-03-29.md
What Dory is, and is not
Dory is currently best suited for:
- local-first agent workflows
- single-user or small-team memory graphs
- tool integrations such as Claude Code, MCP clients, and Python agent stacks
Dory is not yet a hosted, managed memory platform. The current tradeoff is deliberate: favor a transparent local library over a multi-tenant service.
How it works
Knowledge graph
Every piece of information is a typed node: ENTITY, CONCEPT, EVENT, PREFERENCE, BELIEF, PROCEDURE, SESSION (episodic narrative), SESSION_SUMMARY (structured episodic). Edges between them are typed and weighted: USES, WORKS_ON, PREFERS, SUPERSEDES, CO_OCCURS, SUPPORTS_FACT, TEMPORALLY_AFTER, etc.
Salience is computed from connectivity, activation frequency, and recency. High-salience nodes become core memories — they anchor the stable context prefix.
Observer
Every N conversation turns, the Observer calls an LLM to extract structured memories. Extractions carry confidence scores — anything below threshold is logged but not written to the graph.
Backends: Ollama (default), Anthropic (Claude), or any OpenAI-compatible endpoint.
Prefixer
Builds context in two parts:
[stable prefix]         ← core memories + key relationships
                          same bytes across turns → prompt cache hits

[dynamic suffix]        ← spreading activation for this specific query
                          + recent episodic observations
Decayer
score = recency_weight  × exp(-λ × days_since_activation)
      + frequency_weight × log(1 + activation_count)
      + relevance_weight × salience
Nodes below the active floor → archived. Below the archive floor → expired. Core memories are shielded with a configurable multiplier.
Reflector
Near-duplicate detection (Jaccard ≥ 0.82): merges duplicates, keeping the higher-salience node and rewiring edges. Supersession detection (Jaccard in [0.45, 0.82), shared subject): archives the older node, adds SUPERSEDES provenance edge. Old observations compressed into summaries.
Architecture
dory/
├── graph.py          ← nodes, edges, salience computation
├── schema.py         ← NodeType, EdgeType, zone constants
├── activation.py     ← spreading activation engine
├── consolidation.py  ← edge decay, strengthen, prune, promote/demote core
├── session.py        ← session-level helpers: query, observe, write_turn, end_session
├── memory.py         ← DoryMemory — high-level API (sync + async)
├── visualize.py      ← D3.js interactive graph visualization
├── mcp_server.py     ← MCP tools (dory_query, dory_observe, dory_consolidate, …)
├── rest_server.py    ← FastAPI REST server (dory serve, localhost:7341)
├── store.py          ← SQLite backend (nodes, edges, FTS5, observations)
│
├── pipeline/
│   ├── observer.py   ← LLM extraction of memories from conversation turns
│   ├── summarizer.py ← episodic layer: SESSION nodes from conversation turns
│   ├── prefixer.py   ← stable prefix + dynamic suffix builder
│   ├── decayer.py    ← node decay scoring + zone management
│   └── reflector.py  ← dedup, supersession, observation compression
│
├── adapters/
│   ├── langchain.py   ← DoryMemoryAdapter (BaseMemory drop-in)
│   ├── langgraph.py   ← DoryMemoryNode (StateGraph integration)
│   └── multi_agent.py ← SharedMemoryPool (thread-safe multi-agent)
│
└── export/
    └── jsonld.py      ← JSON-LD round-trip export/import

browser-extension/         ← Manifest V3 Chrome extension (memory sidebar)
├── manifest.json
├── background.js          ← service worker, all API calls to localhost
├── content/               ← site-specific content scripts
│   ├── base.js            ← sidebar DOM + shared logic
│   ├── claude.js          ← claude.ai
│   ├── chatgpt.js         ← chatgpt.com
│   ├── gemini.js          ← gemini.google.com
│   └── perplexity.js      ← perplexity.ai
└── sidebar/sidebar.css    ← panel styles
Local LLM setup
ollama pull qwen3:14b          # extraction
ollama pull nomic-embed-text   # embeddings (768-dim, offline after pull)
OpenAI-compatible endpoint (llama.cpp server, vLLM, etc.):
obs = Observer(graph, backend="openai", base_url="http://localhost:8000", model="qwen3")
Vector search activates automatically once nomic-embed-text is available. Falls back to FTS5 BM25 if no embedding model is running.
Decay zones
| Zone | Behavior | How to query |
|---|---|---|
active |
Retrieved in all normal queries | graph.all_nodes() (default) |
archived |
Invisible to normal queries | graph.all_nodes(zone="archived") |
expired |
Completely invisible | graph.all_nodes(zone=None) |
Decay never deletes — it only moves nodes between zones. Archived and expired nodes retain full provenance and can be restored if reactivated. Exact structural duplicates detected by the Reflector are hard-merged (lower-salience copy removed, edges rewired to the winner).
Deletion is a separate, explicit operation: see Erasure below. Decay makes memory invisible; erasure makes it gone. Do not confuse the two — an expired node is still fully present on disk.
Erasure
Decay hides memory. Erasure removes it.
dory forget is the only operation in Dory that physically destroys data, and
it covers every surface that holds it — not just the graph:
| Surface | What lives there |
|---|---|
nodes |
the semantic memory itself, in every zone including archived and expired |
edges |
every edge incident to an erased node |
nodes_fts |
the search index, including FTS5's shadow segments |
observations |
the raw conversation turns the nodes were extracted from |
compressed_obs |
summaries derived from those turns |
The raw-turn surface is the one that is easy to miss and the one that matters most. Deleting a node while leaving the turn that produced it means the text is still on disk in plaintext.
dory forget "chicago"          # preview — shows what would go, changes nothing
dory forget "chicago" --yes    # erase permanently
dory receipts                  # the erasure log
dory verify-erasure            # prove it held
Why it's provable
Every erasure writes a receipt recording SHA-256 hashes of the destroyed content — never the content itself. Receipts are chained: each one carries the hash of its predecessor, so editing or removing a past receipt breaks every receipt after it.
That gives two independently checkable properties:
verify_chain()— no receipt was altered, removed, or reordered.verify_erasure()— re-hashes everything currently stored and confirms nothing matches a hash in any receipt. This proves the content is still absent, not merely that a delete once ran.
from dory import erasure

print(erasure.verify(graph.path))
# {'chain_valid': True, 'erasure_holds': True, 'receipts': 3, ...}
Details that matter
- The bytes really go.
PRAGMA secure_delete=ONzeroes freed pages, the WAL is checkpointed, and the file isVACUUMed. Without all three, "deleted" content stays recoverable with a hex editor. - The query is not retained. The search term is often the exact thing being
erased, so receipts store only a hash of it. Pass
--retain-querywhen the term is not itself sensitive. - Provenance is forward-looking. Nodes record
source_obs_idsat extraction time. Nodes written before this existed have no provenance link, so erasing them will not find their originating turns by that route — the direct content search still catches turns that mention the query. --cascadeis opt-in. It also erases nodes derived from an erased turn even when their own text doesn't match. Off by default, because those nodes are abstractions that may no longer contain the erased content, and removing them deletes more than was asked for.- Hashes are unsalted so third parties can verify them. That makes short or guessable content brute-forceable from a receipt; the receipt log is not a safe place for low-entropy secrets.
Feature snapshot
| Feature | Dory |
|---|---|
| Principled forgetting (decay zones) | ✓ |
| Provable erasure (hard delete + hash-chained receipts) | ✓ |
| Spreading activation retrieval | ✓ |
| Cacheable prefix output | ✓ |
| Bi-temporal conflict resolution | ✓ |
| Zero-server local stack (SQLite) | ✓ |
| Drop-in Python library | ✓ |
| REST API + browser extension | ✓ |
| Apache 2.0 | ✓ |
Graph topology — what flat search can't do
Run examples/demo_topology.py to see six live graph traversals:
Q1 · Supersession — "What was the inference backend before MLX replaced it?"

  ┌ BEFORE  [PREFERENCE]  Prefers llama.cpp — cross-platform, well-supported
  │         zone=archived  archived=2026-03-01
  ├─SUPERSEDES──▶
  └ AFTER   [PREFERENCE]  Prefers MLX over llama.cpp on Apple Silicon (20-30% faster)

  ✗ Flat search: returns both nodes with equal score. No directionality. No timestamp.

──────────────────────────────────────────────────────────────────────
Q4 · Semantic Path — "How does the local-first preference connect to the model choice?"

  ● [CONCEPT]    Local-first AI — data stays on device, no cloud
    └─[CO_OCCURS]──▶
  ● [PREFERENCE] Prefers local-first — no data leaves device unless necessary
    └─[PREFERS]──▶
  ● [ENTITY]     Developer
    └─[WORKS_ON]──▶
  ● [ENTITY]     Agent project
    └─[CO_OCCURS]──▶
  ● [EVENT]      [2026-03-01] Switched inference backend to local Ollama instance

  ✗ Flat search: returns both endpoints as separate results. No connecting path.
| Query | Traversal | What it answers |
|---|---|---|
| Q1 Supersession | SUPERSEDES edges |
What changed and when |
| Q2 Chronicle | TEMPORALLY_AFTER chain |
Full session history in order |
| Q3 Dependencies | USES traversal (depth 2) |
What a project actually needs |
| Q4 Semantic Path | BFS across typed edges | How two concepts connect |
| Q5 Provenance | SUPPORTS_FACT traversal |
What proves a specific fact |
| Q6 Belief Grounding | SUPPORTS_FACT + BELIEF |
Which beliefs have evidence |
Benchmark results
LongMemEval (ICLR 2025), oracle split, 500 questions.
| Version | Extract | Answer | n | Score |
|---|---|---|---|---|
| v0.1 | Haiku | Haiku | 500 | 54.4% |
| v0.1 | Sonnet | Sonnet | 500 | 66.8% |
| v0.3 | Sonnet | Sonnet (direct API) | 500 | 79.8% |
| v0.4 | Haiku | Claude Code (MCP) | 500 | 80.6% |
| v0.5 | Haiku | Claude Code (MCP) | 500 | 79.6% |
| v0.6 | Haiku | Claude Code (MCP) | 500 | 84.0% |
| v0.7 | Haiku | Claude Code (MCP) | 500 | 84.2% |
| v0.8 | Sonnet | Claude Code (MCP) | 500 | 84.2% |
| v1.0 | Opus 4.8 | Opus 4.8 | 500 | 84.8% |
Category breakdown for v1.0 (Opus 4.8 extract + answer, Haiku judge):
| Category | Score | Δ vs v0.8 |
|---|---|---|
| single-session-user | 91.4% | -2.9pp |
| temporal-reasoning | 90.2% | +7.5pp |
| single-session-assistant | 89.3% | +8.9pp |
| multi-session | 80.5% | -3.0pp |
| knowledge-update | 83.3% | -3.9pp |
| single-session-preference | 60.0% | -10.0pp |
v1.0 gains are driven by the verbatim extraction fix (+8.9pp on ss-assistant) and Opus 4.8's stronger temporal reasoning (+7.5pp). Multi-session improved significantly from v0.9.3 (68.4% → 80.5%) due to the FTS sweep fix.
Artifacts:
Note: LongMemEval oracle split uses pre-filtered context (~15K tokens per question). Performance with live, unfiltered conversations will differ.
Reproducing the benchmark
Canonical benchmark entry points live under benchmarks/.
Full oracle run with the checked-in harness:
cd Dory
source .env
./run_benchmark.sh
That script runs with Haiku for both extract and answer by default. For the v1.0 result (Opus 4.8):
python3 benchmarks/longmemeval.py \
  --data benchmarks/data/longmemeval/longmemeval_oracle.json \
  --output benchmarks/predictions_$(date +%Y%m%d_%H%M%S).jsonl \
  --backend anthropic \
  --extract-model claude-opus-4-8 \
  --answer-model claude-opus-4-8 \
  --api-key "$ANTHROPIC_API_KEY" \
  --verbose
Then evaluate the predictions:
source .env
ANTHROPIC_API_KEY="$ANTHROPIC_API_KEY" \
python3 benchmarks/evaluate_qa_claude.py \
  benchmarks/predictions_YYYYMMDD_HHMMSS.jsonl \
  benchmarks/data/longmemeval/longmemeval_oracle.json
For cheaper iteration, use a spot dataset first:
python3 benchmarks/longmemeval.py \
  --data benchmarks/spot_micro.json \
  --output benchmarks/predictions_spot.jsonl \
  --backend anthropic \
  --extract-model claude-haiku-4-5-20251001 \
  --answer-model claude-haiku-4-5-20251001 \
  --api-key "$ANTHROPIC_API_KEY"
Benchmark caveats:
- LongMemEval oracle is a filtered-context benchmark, not a raw multi-month transcript benchmark.
- Claude Code MCP runs and direct API runs are both useful, but they are not identical execution environments.
- Exact scores can move with prompt, extraction logic, model version, and evaluation backend updates.
Current priorities
- Automatic expiry —
dory forgeterases on demand; erasing automatically after N consolidation cycles in the expired zone is not yet wired up. - Privacy layer —
privacy_levelfield on Node (default/private/sensitive) to mark content for shorter retention. Erasure and receipts are done; classification is not. - v2.0 unified retrieval — replace heuristic routing with spreading activation → top-k → single LLM reasoning step. Required to break the ~85% benchmark ceiling.
Research basis
- LongMemEval (ICLR 2025) — evaluation benchmark
- Collins & Loftus (1975) — spreading activation in semantic memory
- Hebb (1949) — neurons that fire together wire together
- Hopfield (1982) — associative memory energy landscape (Nobel Prize in Physics, 2024)
License
Apache 2.0 — see LICENSE.
Named after Dory from Finding Nemo, because most agent sessions still have the memory of a goldfish.
1 maintainer

Metadata
1 maintainer
Release files for dory-memory 1.2.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| dory_memory-1.2.1.tar.gz | 134.6 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| dory_memory-1.2.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 247.8 kB
Release files / dory_memory-1.2.1.tar.gz
| Download URL | dory_memory-1.2.1.tar.gz |
|---|---|
| Size | 134.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6093deb333e54278a86d7cc754dd1b211b0560720b9702cc097daf30d190dad6
|
|
BLAKE2b-256 checksum How to use checksums |
8ed2cb10c4350e0a86940bf8b8211c9412b7f787c12ff8b5c872e6d4d049021b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.14.7
|
Release files / dory_memory-1.2.1-py3-none-any.whl
| Download URL | dory_memory-1.2.1-py3-none-any.whl |
|---|---|
| Size | 113.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
35dd11040627bf814d7e599645672240b96b2e4ea0d2fdda93276cfe9530e9e1
|
|
BLAKE2b-256 checksum How to use checksums |
c396adb05971e952c7c6c0772d3d04aa0bcaa56ce40f8fce62f352930778a47f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.14.7
|
Security for dory-memory 1.2.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














