
EdgeVoiceAI
A modular, full-duplex conversational voice AI framework for Python 3.10+
Built for edge devices (Raspberry Pi, Linux) and laptops (macOS, Windows) powered by Google Gemini Live.



🌟 Overview
EdgeVoiceAI is a developer-first Python library designed to build low-latency, full-duplex conversational voice assistants from scratch. It connects physical hardware microphones and speakers directly with Google Gemini's real-time bidirectional streaming API (bidiGenerateContent), enabling natural spoken interactions with instant turn-taking and conversational barge-in interruptions.
Unlike traditional voice wrappers that chain disjointed Speech-To-Text (STT) $\rightarrow$ LLM $\rightarrow$ Text-To-Speech (TTS) pipelines with noticeable latency, EdgeVoiceAI operates over a single, continuous, bidirectional audio WebSocket connection.
🏗️ Architecture
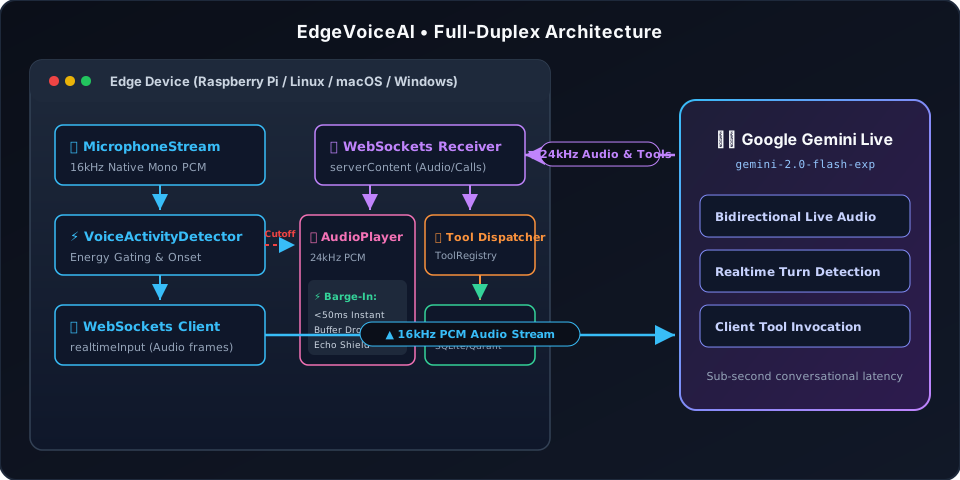
+-----------------------------------------------------------------------+
|        Client Device (macOS / Linux / Windows / Raspberry Pi)         |
|                                                                       |
|   [🎙️ MicrophoneStream (16kHz Native Mono PCM)]                       |
|                │                                                      |
|                ▼                                                      |
|   [⚡ VoiceActivityDetector (Energy Gating & Syllable Onset)]          |
|                │                                                      |
|                ▼                                                      |
|   [📤 WebSockets Client (realtimeInput audio frames)]                 |
|                │                                      ▲               |
+────────────────┼──────────────────────────────────────┼───────────────+
                 │                                      │
                 │ 16kHz PCM Stream                     │
                 ▼                                      │
+───────────────────────────────────────────────────────┼───────────────+
|                  Google Gemini Live Service           │               |
|                 (gemini-2.0-flash-exp / live)         │               |
+───────────────────────────────────────────────────────┼───────────────+
                 │                                      │
                 │ 24kHz Streaming Audio & Tool Calls   │
                 ▼                                      │
+────────────────┼──────────────────────────────────────┼───────────────+
|                ▼                                                      |
|   [📥 WebSockets Receiver (serverContent)]                            |
|          │                                                            |
|          ├─────────────────────────────┐                              |
|          ▼                             ▼                              |
|   [🔊 AudioPlayer (24kHz PCM)]   [🔧 Tool Dispatcher (ToolRegistry)]  |
|    • <50ms Instant Barge-In Cancel             │                      |
|    • Acoustic Echo Suppression                 ▼                      |
|                                  [🧠 Memory & Vector Stores]          |
|                                     (SQLite / Qdrant / Pinecone)      |
+-----------------------------------------------------------------------+
✨ Key Features
- ⚡ Ultra-Low Latency & Instant Barge-In: Real-time 16kHz continuous streaming. When you speak while the assistant responds, playback clears instantly (<50ms) to yield the floor naturally.
- 🧩 Self-Describing Tools with Prompt Composition: Each tool declares its own JSON schema, execution callback, and prompt etiquette instructions (
prompt_instruction). The framework automatically synthesizes these instructions into the agent's system prompt. - 🎙️ Cross-Platform Audio Engine: Powered by PortAudio with automatic hardware enumeration across macOS (CoreAudio), Linux / Raspberry Pi (ALSA/PulseAudio), and Windows (WASAPI/MME).
- 🔍 Plug-and-Play RAG Integration: Built-in
RAGRetrieverwith chunking and native vector store backends forInMemoryVectorStore,QdrantVectorStore, andPineconeVectorStore. - 🛡️ Conversational Guardrails: Turn-aware farewell detectors, topic safety guards, and entity memory management.
- 📲 Built-in Notification Tools: Two-turn confirmation WhatsApp dispatch tool with phone number normalization.
📦 Installation
1. Install System Audio Dependencies (PortAudio)
EdgeVoiceAI uses PortAudio for native, cross-platform audio streaming.
- macOS:
brew install portaudio
- Linux / Raspberry Pi:
sudo apt-get update
sudo apt-get install -y portaudio19-dev libasound2-dev python3-pyaudio
- Windows:
- Recommended Python:
3.10,3.11, or3.12. Official pre-compiled binary wheels forpyaudioare provided automatically—no compilers required. - Notice for Python 3.14+: Python 3.14 does not have pre-built wheels on PyPI yet. If you see
Microsoft Visual C++ 14.0 or greater is required, either:- (Recommended) Create your virtual environment with Python 3.11 or 3.12:
py -3.11 -m venv venv - Or install Microsoft C++ Build Tools (select "Desktop development with C++").
- (Recommended) Create your virtual environment with Python 3.11 or 3.12:
- Recommended Python:
2. Install EdgeVoiceAI via pip
# Core package
pip install edgevoiceai

# With specific optional extras
pip install "edgevoiceai[qdrant]"    # Qdrant vector store support
pip install "edgevoiceai[pinecone]"  # Pinecone vector store support
pip install "edgevoiceai[media]"     # Pygame audio sound effects

# Or install all extras
pip install "edgevoiceai[all]"
🚀 5-Minute Quickstart
1. Set Your Gemini API Key
export GEMINI_API_KEY="your-google-ai-studio-api-key"
2. Run a Full-Duplex Voice Assistant
import asyncio
import os
from dotenv import load_dotenv
from edgevoiceai import (
    BaseTool,
    InMemoryMemoryStore,
    ToolExecutionContext,
    ToolRegistry,
    ToolResult,
    VoiceAgent,
    VoiceConfig,
)

# Load GEMINI_API_KEY from .env
load_dotenv()


# Define a custom tool with prompt instructions
class BookAppointmentTool(BaseTool):
    @property
    def name(self) -> str:
        return "book_appointment"

    @property
    def description(self) -> str:
        return "Schedules a consultation appointment for the user."

    @property
    def parameters_schema(self) -> dict:
        return {
            "type": "object",
            "properties": {
                "name": {"type": "string", "description": "Customer name"},
                "date": {"type": "string", "description": "Date of appointment (YYYY-MM-DD)"},
                "time": {"type": "string", "description": "Time (e.g. 10:00 AM)"},
            },
            "required": ["name", "date", "time"],
        }

    @property
    def prompt_instruction(self) -> str:
        return (
            "When scheduling, ask for the customer's name, desired date, and preferred time. "
            "Always verbally confirm all details before executing book_appointment."
        )

    async def execute(self, params: dict, context: ToolExecutionContext) -> ToolResult:
        name = params.get("name")
        date = params.get("date")
        time = params.get("time")
        # In a real app, write to database or calendar API
        return ToolResult(
            status="success",
            message=f"Appointment booked for {name} on {date} at {time}.",
            data={"status": "confirmed", "booking_id": "APT-1001"},
        )


async def main():
    api_key = os.environ.get("GEMINI_API_KEY")
    if not api_key:
        raise ValueError("Please set the GEMINI_API_KEY environment variable.")

    # Configure the voice session
    config = VoiceConfig(
        api_key=api_key,
        voice="Puck",  # Puck, Charon, Aoede, Fenrir, Kore
        system_instruction=(
            "You are a friendly, concise voice assistant. "
            "Keep responses natural, conversational, and direct."
        ),
    )

    # Register tools and memory
    registry = ToolRegistry()
    registry.register(BookAppointmentTool())
    memory = InMemoryMemoryStore()

    agent = VoiceAgent(config=config, tools=registry, memory=memory)

    print("🎙️ Starting Voice Assistant... Speak into your microphone!")
    try:
        await agent.run_edge()
    except KeyboardInterrupt:
        print("\nStopping...")
    finally:
        agent.stop()


if __name__ == "__main__":
    asyncio.run(main())
📖 Documentation
Comprehensive documentation, tutorials, architecture deep-dives, and API references are available at: https://merhasmukh.github.io/edgevoiceai/
📄 License
This project is licensed under the MIT License.
1 maintainer

Metadata
1 maintainer
Release files for edgevoiceai 0.1.3
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| edgevoiceai-0.1.3.tar.gz | 66.1 kB | Without provenance | Details for edgevoiceai-0.1.3.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| edgevoiceai-0.1.3-py3-none-any.whl | Python 3 | none | any | Details for edgevoiceai-0.1.3-py3-none-any.whl |
Total release size: 149.0 kB
Release files / edgevoiceai-0.1.3.tar.gz
| Download URL | edgevoiceai-0.1.3.tar.gz |
|---|---|
| Size | 66.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
57a7fcf729517f473ff5b6d4d62e2c23a816e6e2c485297e27dcb1cb254bf648
|
|
BLAKE2b-256 checksum How to use checksums |
0c6d9c123d12f41326e8ed03f66ddaf13bac7b00333b9b561499d10a148b8910
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.7
|
Release files / edgevoiceai-0.1.3-py3-none-any.whl
| Download URL | edgevoiceai-0.1.3-py3-none-any.whl |
|---|---|
| Size | 82.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
ad6436b242daf3b12c051b9b88aa3ede02bb349d7645d557441dc4ee9e0c3157
|
|
BLAKE2b-256 checksum How to use checksums |
4fc24558ce228d155d6d18f9c1d18a62f500ed1c21703ef00075670cddba081d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.7
|
Security for edgevoiceai 0.1.3
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














