
elbow-helper
Noise-robust knee and elbow detection: it reports a knee with uncertainty; it abstains outright otherwise.
An algorithm can answer the question "where might a knee or an elbow be?" and it will always return something, even on a straight line or on pure noise. elbow-helper wraps a from-scratch knee locator in a conservative decision procedure that answers a harder question instead:
Is any candidate knee strong, unique, persistent, reproducible, and unlikely under a no-knee model? If not, say so.
The design priority is to minimise false-positive knees, even at the cost of more abstentions.
Status
Published on PyPI, six semantic-versioned releases so far (v0.1.0 through v0.1.5, see git tag), with CI green on every commit (Python 3.12, plus a weekly sweep across 3.10 to 3.13) and 85 tests (96% line coverage) covering the pipeline end to end plus the CLI, HTTP API and MCP surfaces. Still an early release (v0.1.x): treat the calibrated thresholds in RobustKneeConfig as a validated starting point, not a universal constant, see Configuration and Limitations below.
Documentation
🌐 Web app — the pipeline in your browser: no install, nothing uploaded
Why it exists
A knee, on a curve of diminishing returns, marks the point past which extra input buys little extra output: more clusters in k-means, more iterations in an optimiser, more budget on a marketing channel. Existing knee-detection heuristics are excellent at proposing where that point sits, but they carry no notion of confidence. A single point estimate on a noisy curve is easy to over-trust in practice. This package turns that point estimate into a decision backed by evidence. It refuses to answer when the evidence is weak.
Dependencies
The whole package depends on numpy and os-helper only: nothing else, not even for the diagnostic figure. The knee-locating algorithm is implemented from scratch, in NumPy only, so there is no scipy, scikit-learn, statsmodels, or joblib runtime dependency. elbow_helper.plotting writes hand-authored SVG (see Diagnostics below) rather than reaching for matplotlib, so it needs no extra install. See Acknowledgements below for the implementation this algorithm follows.
Installation
pip install -e .            # everything: numpy + os-helper, diagnostics included
pip install -e ".[dev]"     # + pytest
Prefer conda? conda env create -f environment.yaml && conda activate elbow-helper sets up Python and pip, then installs from requirements.txt, the same dependency list pyproject.toml declares.
Quickstart
See EXAMPLES.md for more recipes: the k-means elbow, an explicit abstention, an exponential-saturation curve, the diagnostic figure, the standalone locator, and configuration tuning.
import numpy as np
from elbow_helper import robust_knee, RobustKneeConfig

x = np.linspace(0, 1, 80)
y = np.where(x <= 0.3, 3*x, 0.9 + 0.2*(x - 0.3))
y = y / y.max() + np.random.default_rng(0).normal(0, 0.02, x.size)

result = robust_knee(x, y, config=RobustKneeConfig(random_seed=0))

if result.is_clear:
    print(result.knee_x, result.ci90, result.detection_rate, result.null_p_value)
else:
    print("no clear knee:", result.reason)
curve and direction are optional: left unset, both are inferred from the data (see below) and can still be passed explicitly, e.g. robust_knee(x, y, curve="concave", direction="increasing", ...). y is optional too: call robust_knee(y) alone and x is taken to be the implicit 0, 1, ..., n-1.
For the classic k-means or scree "elbow" (convex, decreasing):
from elbow_helper import robust_elbow
result = robust_elbow(k_values, inertia)   # curve/direction fixed to convex/decreasing
Automatic shape and direction
Leaving curve or direction unset infers them from the cleaned, normalised data. direction comes from the sign of the trend between x and y. curve comes from whether the (lightly smoothed) curve lies above or below the straight chord connecting its first and last point: above is concave, below is convex, the mathematical definition, holding for both increasing and decreasing curves. This covers all four concave/convex × increasing/decreasing combinations without asking the caller to name the shape up front. Passing curve or direction explicitly always overrides the inferred value.
The contract: a tagged union
robust_knee always returns one of two types, both subclasses of KneeResult and distinguished by .is_clear:
ClearKnee:knee_x,knee_x_norm,knee_index,ci90(a 90% bootstrap interval, in data units, always containingknee_x),detection_rate,smoothing_window,sensitivity,prominence,slope_contrast,bic_improvement,null_p_value, and the fulldiagnostics.NoClearKnee: a machine-readablereasoncode, a plain-languagedetailsaying what was measured and what it had to clear, plusdiagnostics.
You are forced to handle abstention explicitly: there is no silent fallback to a guess.
How it decides: the pipeline
-
Preprocess. Clean, sort, deduplicate, and robustly normalise the data to the unit square, then screen its global shape with a Spearman correlation (a rank-based measure of how monotonic the curve is) and a magnitude-weighted monotonicity check.
The Spearman is measured over plateau-collapsed values, and that detail matters more than it looks. A saturating curve is mostly flat tail, and under a rank correlation a flat tail is one big block of tied ranks — so the sharper the knee, the worse its plain Spearman, and the screen ends up anti-correlated with the thing it screens for. Collapsing each plateau to one representative removes the artefact.
A plateau is detected within a tolerance read from the curve's own noise, not by exact equality: real measurements are never bit-identical, so an exact test would make the protection evaporate the moment any noise was present. The tolerance is capped at 2 % of the total range, so it can never grow large enough to collapse a genuine trend and loosen the gate it feeds.
-
Scale-space search. Run the from-scratch locator across a grid of Gaussian smoothing windows and sensitivities; collect every candidate it proposes.
-
Basic filters. Reject boundary knees, weak prominence, and a low prominence-to-noise ratio.
-
Persistence clustering. Keep only knees that recur at a stable location across consecutive smoothing scales and most sensitivities. Abstain if two knees look equally plausible (
MULTIPLE_PLAUSIBLE_KNEES). -
Model confirmation. Require a robust slope change, via a Theil-Sen estimator (a regression method that stays accurate even with outliers), plus a continuous broken-line fit that beats a single straight line on blocked cross-validation (holding out whole contiguous chunks of the curve rather than scattered points, so a held-out stretch cannot leak information from the smooth neighbours right next to it, the way a single held-out point could) and on the BIC (Bayesian Information Criterion, a score that rewards fit while penalising extra parameters).
-
Bootstrap. Re-run the whole search on an IID residual bootstrap (independent, identically distributed resampling of the leftover noise). The knee must be redetected at least 90% of the time, with a tight, unimodal interval.
-
No-knee null test. Run a Monte Carlo test against a straight-line null model that carries the accepted model's noise scale. The observed knee must be significant at p ≤ 0.01.
Only a candidate that clears every gate becomes a ClearKnee.
Abstention reason codes
INSUFFICIENT_DATA, INVALID_INPUT, ZERO_RANGE, INCOMPATIBLE_GLOBAL_SHAPE,
NO_KNEE_CANDIDATES, ALL_CANDIDATES_WEAK, NO_PERSISTENT_CLUSTER,
MULTIPLE_PLAUSIBLE_KNEES, BOUNDARY_KNEE, WEAK_SLOPE_CHANGE,
SEGMENTED_MODEL_NOT_BETTER, BOOTSTRAP_UNSTABLE, BOOTSTRAP_MULTIMODAL,
NULL_NOT_REJECTED, INTERNAL_NUMERICAL_FAILURE.
A code names the gate that closed. It does not say whether the curve is
hopeless or merely under-measured, and those call for opposite responses, so
every abstention also carries detail: the number that was measured, the
threshold it had to clear, and positions in your own x units rather than the
normalised ones the gate works in.
>>> result.reason
'SEGMENTED_MODEL_NOT_BETTER'
>>> result.detail
'a bent line fits no better than a straight one here: BIC improves by 6.824,
 not the 10 required, and held-out error actually rises by 126.0% when the
 bend is added'
The same sentence is mirrored into diagnostics["detail"], so the CLI, the
HTTP API and the MCP server hand it on without any extra work.
detail is prose, so it follows config.language — "en" (default) or
"fr". Only the wording changes: the reason code, every threshold and every
measurement are identical either way, so switching languages never switches the
verdict.
robust_elbow(x, y, config=RobustKneeConfig(language="fr"))
# NoClearKnee(reason='SEGMENTED_MODEL_NOT_BETTER', detail="une ligne brisée
#  n'ajuste pas mieux qu'une droite ici : le BIC ne gagne que 6.824 au lieu
#  des 10 exigés ; l'erreur hors échantillon augmente même de 126.0 %
#  lorsqu'on ajoute le pli")
Curves spanning orders of magnitude: take the log first
The detector works on the curve normalised to the unit square, so a y that
falls across several decades has everything past its first few points crushed
into the bottom percent of that square. The corner of the normalised shape is
then not the corner you read off the plot, and the detector will faithfully
report the former.
k-means inertia is the common case: on eight well-separated blobs it drops
from about 80000 to about 500 before the tail even begins. Run on the raw
curve, robust_elbow returns k = 6 or 7 (which is also where the Kneedle
construction puts it). Run on log(inertia), it returns exactly 8, the true
cluster count, on every seed tested. Plot such a curve on a log axis and you
are already looking at the transformed shape: hand the detector the same one.
result = robust_elbow(k_values, np.log(inertia))
Configuration
Every threshold lives in RobustKneeConfig, a frozen dataclass; call config.with_(...) to change one. All positional thresholds are expressed in normalised x-range units. The shipped defaults suit a first practical prototype: modest replicate counts, so a run finishes in seconds.
RobustKneeConfig(bootstrap_replicates=100, null_replicates=200)
# validation-grade:
config.with_(bootstrap_replicates=500, null_replicates=1000)
min_samples defaults to 20, and that is a deliberate floor rather than an arbitrary one: the persistence and bootstrap gates need a scale space to work across, and below about twenty points they measure noise instead. A sixteen-point reconstruction-error curve is a legitimate thing to want a knee on, so the floor is not a wall — pass config.with_(min_samples=8) and the pipeline runs. Read what comes back as indicative rather than confirmed; the gates still apply, they are simply working with less to go on. The INSUFFICIENT_DATA abstention says all of this in its detail.
A note on these thresholds: they are calibrated, conservative defaults, not universal constants. cluster_tolerance and max_neighbor_shift sit slightly above the reference plan's 0.05 to absorb the locator's one- or two-sample discretisation jitter at modest sample sizes (n of about 60 to 100). Recalibrate them against your own curve and noise family if needed.
Diagnostics
from elbow_helper.plotting import plot_diagnostics
plot_diagnostics(x, y, curve="concave", direction="increasing", out="diag.svg")
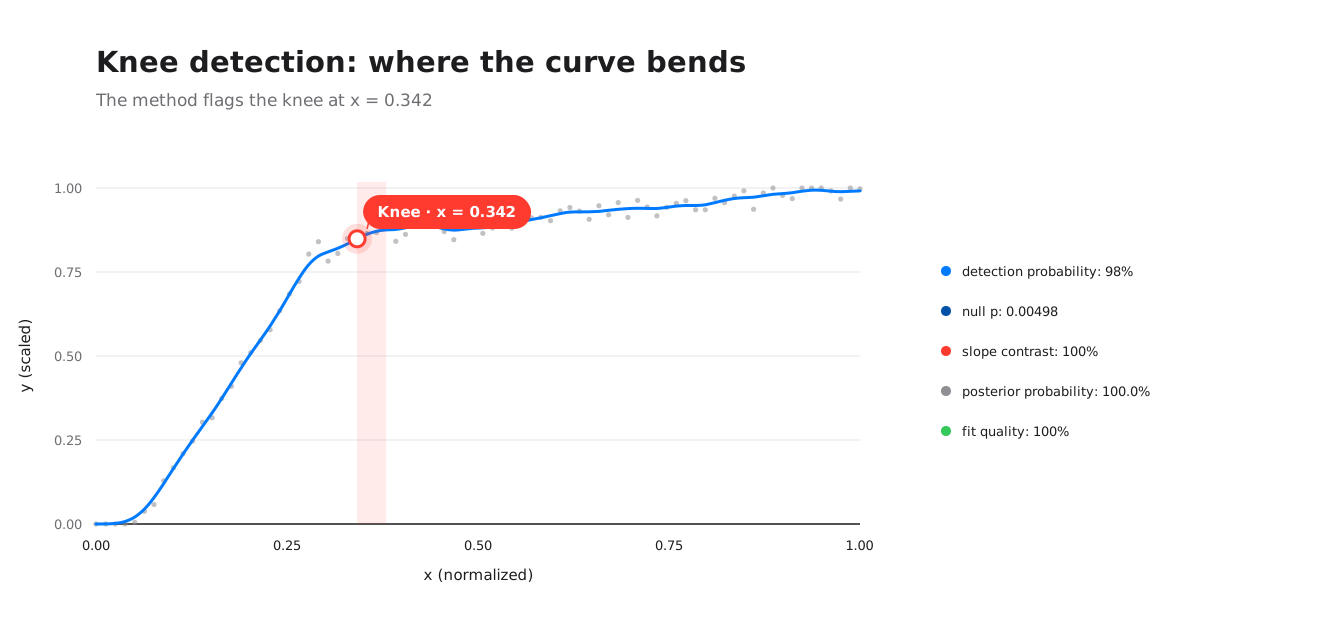
Hand-authored SVG, no matplotlib, no extra to install: the diagnostic is a core feature. The curve and its located knee sit next to a compact evidence legend backing the point estimate: the detection probability, the null-model p-value, the slope contrast, a BIC-derived posterior probability (the odds, under Kass & Raftery's Bayes-factor approximation, that the knee model is correct), and a fit-quality score normalized against a deliberately pessimistic worst case rather than the easily-beaten sample mean (see doc/ELBOW-en.tex for the derivation of both). When the evidence is too weak, the figure switches to an honest abstention state instead: a greyed, dashed curve and the reason, never a marker implying more confidence than the data supports. Pass language="fr" for the French chrome text.
Limitations
- The current smoother assumes a regular or near-regular spacing in
x. - Auto-detected
curveanddirectionneed a curve with a real, unambiguous trend; on data too weak or noisy to classify confidently, the pipeline abstains withINCOMPATIBLE_GLOBAL_SHAPErather than guessing, the same gate that already screens explicitcurve/directionarguments. - Detection is discretised to sample locations. On modest
n, the located knee can sit within a few samples of the truth (median error at or below about 5% of the x-range, on the supported synthetic family). - The straight-line null and the IID residual bootstrap suit roughly homoscedastic (constant-variance), uncorrelated noise. Wild or moving-block bootstrap variants are future work.
- No finite-data method is infallible. The targets above hold for the documented simulation family, not for every possible curve.
Standalone locator
The from-scratch locator is usable on its own:
from elbow_helper import KneeLocator
kl = KneeLocator(x, y, S=1.0, curve="concave", direction="increasing", online=True)
kl.knee, kl.all_knees
Multiple knees: robust_knees
robust_knee answers "is there one knee?". A curve with several genuine
regime changes, three pricing tiers on a demand curve, say, needs a
different question: how many breakpoints does this curve actually have and
where are they? robust_knees (plural) answers that one. It searches over every
possible number of segments with a dynamic program, scores each candidate
with a modified BIC (a fit-quality score that penalises extra breakpoints,
so adding one has to earn its keep), then confirms the winning count with a
permutation test: reshuffling the data thousands of times and checking that
the real fit stands out from nearly all of those random reshuffles, none of
which have any true breakpoint structure. Trying more breakpoint counts
means running more such tests; running more tests raises the odds that
one looks significant by pure chance. A Bonferroni correction counters this
by tightening the significance bar each individual test must clear, roughly
in proportion to how many are run, holding the overall false-positive rate
down as the search space grows.
import numpy as np
from elbow_helper import RobustKneesConfig, robust_knees

rng = np.random.default_rng(3)
x = np.linspace(0, 1, 100)
y = np.piecewise(
    x,
    [x < 0.3, (x >= 0.3) & (x < 0.65), x >= 0.65],
    [lambda t: 3 * t, lambda t: 0.9 + 0.2 * (t - 0.3), lambda t: 0.97 + 2.2 * (t - 0.65)],
) + rng.normal(0, 0.02, x.size)

result = robust_knees(x, y, config=RobustKneesConfig(random_seed=0, fwer_permutations=200))
print(result)
Knees(k=2, x=[0.2929, 0.6465])
The two breakpoints land close to the curve's true regime changes at 0.3 and
0.65. Unlike robust_knee, an empty result here is not an abstention: it is
the pipeline's confident conclusion that the curve has no real breakpoint,
having survived the same search and false-positive gates a nonempty result
would have had to survive. Only a preprocessing failure (bad input, too
little data, zero range) returns InvalidKnees instead of Knees. See
research/multiknee/RESULTS.md and doc/ELBOW-en.tex (sections 5-20) for
the validation behind this design.
Mathematics
doc/ELBOW-en.tex derives every formula this package runs: the single-knee pipeline's normalisation, Spearman screen, difference-curve knee search, persistence clustering, Theil-Sen slope, BIC, blocked cross-validation, bootstrap and null test, and the multi-knee research behind robust_knees (see also research/multiknee/RESULTS.md). It is written intuition-first, with a worked example before every formula, for readers anywhere from the end of high school to a Ph.D. in applied mathematics. Its Gaussian likelihood foundation, the general theory behind why L := exp(E[log p]) rather than a raw product, and how the same construction reads on a classification model, is factored out into a companion note, doc/LIKELIHOOD-en.tex, since that foundation doesn't depend on curve-fitting at all. Citations are in doc/references.bib, including a few pointers into my own Favourite AI books where a technique used here deserves a book-length treatment. Native LaTeX (not Markdown), given the audience: compile with latexmk -pdf ELBOW-en.tex (or LIKELIHOOD-en.tex) from inside doc/, or read the compiled copies directly, doc/ELBOW-en.pdf / doc/LIKELIHOOD-en.pdf. Both math notes are English-only; the rest of this project's docs (this README, EXAMPLES.md, LANDSCAPE.md) still ship a French twin.
Landscape
🗺️ Landscape (🇫🇷 PAYSAGE.md): how elbow-helper compares to kneed, ruptures, kneebow, Yellowbrick's KElbowVisualizer, R's segmented package, manual eyeballing and asking an LLM, rated on 11 criteria and positioned on a map built with principal component analysis (PCA), a method that finds the few directions along which the tools differ the most and collapses the 11 criteria down onto those two axes.
CLI / API / MCP
Beyond the Python library, elbow-helper exposes three more doors onto the same pipeline: an argparse CLI (always installed), a click CLI twin, and an HTTP API with an MCP server mounted on it. All four are thin adapters over the same shared core (elbow_helper._core_cli), so none of them can drift from what the library itself returns.
pip install -e .                 # library + argparse CLI
pip install -e ".[cli]"          # + the click twin
pip install -e ".[api]"          # + the FastAPI HTTP surface
pip install -e ".[mcp]"          # + the MCP server (pulls in [api] too)
# argparse (always available)
elbow-helper knee --y-values 0,0.1,0.3,0.6,0.85,0.9,0.92,0.93,0.94,0.95

# click twin
elbow-helper-click knee --y-values 0,0.1,0.3,0.6,0.85,0.9,0.92,0.93,0.94,0.95

# HTTP API
uvicorn elbow_helper.api:app --reload
curl -X POST localhost:8000/knee -d '{"x": [0,0.1,0.3,0.6,0.85,0.9]}'

# MCP (fastapi-mcp mounted on the same app, at /mcp)
uvicorn elbow_helper.mcp_server:app --port 8021
Every surface exposes the same four operations (knee, elbow, diagnostics, locator), matching robust_knee, robust_elbow, plot_diagnostics, and the standalone KneeLocator one-to-one. Data goes in as inline comma-separated values, a .npy file, or a CSV column (CLI), or a JSON body (x/y lists, HTTP). RobustKneeConfig overrides travel as --config-json '{"bootstrap_replicates": 500}' (CLI) or a config_overrides object (HTTP). The diagnostics operation returns the SVG itself, not a JSON wrapper around it.
Use it as an agent skill
skills/elbow-helper/ packages elbow-helper as a Claude Skill and an OpenCode
skill, so an agent can reach for it on your behalf. See
skills/README.md to install it (symlink into
~/.claude/skills/ and ~/.opencode/skills/), and
TRIGGERS.md for the exhaustive trigger catalogue —
scripts/check_triggers.py keeps the skill's description in sync with it, and
the test suite fails if a capability stops being named.
Author
Acknowledgements
The from-scratch Kneedle implementation in elbow_helper/locator.py follows the algorithm described by Satopää, Albrecht, Irwin and Raghavan (ICDCSW 2011). Its traversal logic, orientation table and sensitivity threshold closely follow the implementation choices of kneed by Kevin Arvai, released under the BSD-3-Clause license:
Copyright (c) 2017, Kevin Arvai All rights reserved.
Redistribution and use in source and binary forms, with or without modification, are permitted provided that the following conditions are met: (1) redistributions of source code must retain the above copyright notice, this list of conditions and the following disclaimer; (2) redistributions in binary form must reproduce the above copyright notice, this list of conditions and the following disclaimer in the documentation and/or other materials provided with the distribution.
elbow-helper has no runtime dependency on kneed: the algorithm is reimplemented in NumPy only, with the scipy calls replaced as documented in locator.py.
License
BSD-3-Clause.
1 maintainer

Metadata
1 maintainer
Release files for elbow-helper 0.3.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| elbow_helper-0.3.0.tar.gz | 118.5 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| elbow_helper-0.3.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 218.7 kB
Release files / elbow_helper-0.3.0.tar.gz
| Download URL | elbow_helper-0.3.0.tar.gz |
|---|---|
| Size | 118.5 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cbdc70f31e77fd2be485053897e4cb2a964cb6f8158259f42a05be0dbf0ca508
|
|
BLAKE2b-256 checksum How to use checksums |
4d837fcc01324a5fa8a0c4c71b3aa0b30f6319cc7b3afcc343cc29484be2dd62
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.13
|
Release files / elbow_helper-0.3.0-py3-none-any.whl
| Download URL | elbow_helper-0.3.0-py3-none-any.whl |
|---|---|
| Size | 100.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
84b83d5e159f8634087055d888aa5c07a3de81d36e9cfdd4318d2cd627ee4878
|
|
BLAKE2b-256 checksum How to use checksums |
3af152e51d342b4c422524befe0ad888d01ae9b408705111e3bb1cd908329e51
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.13
|
Security for elbow-helper 0.3.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.














