
Aleph Alpha Eval-Framework
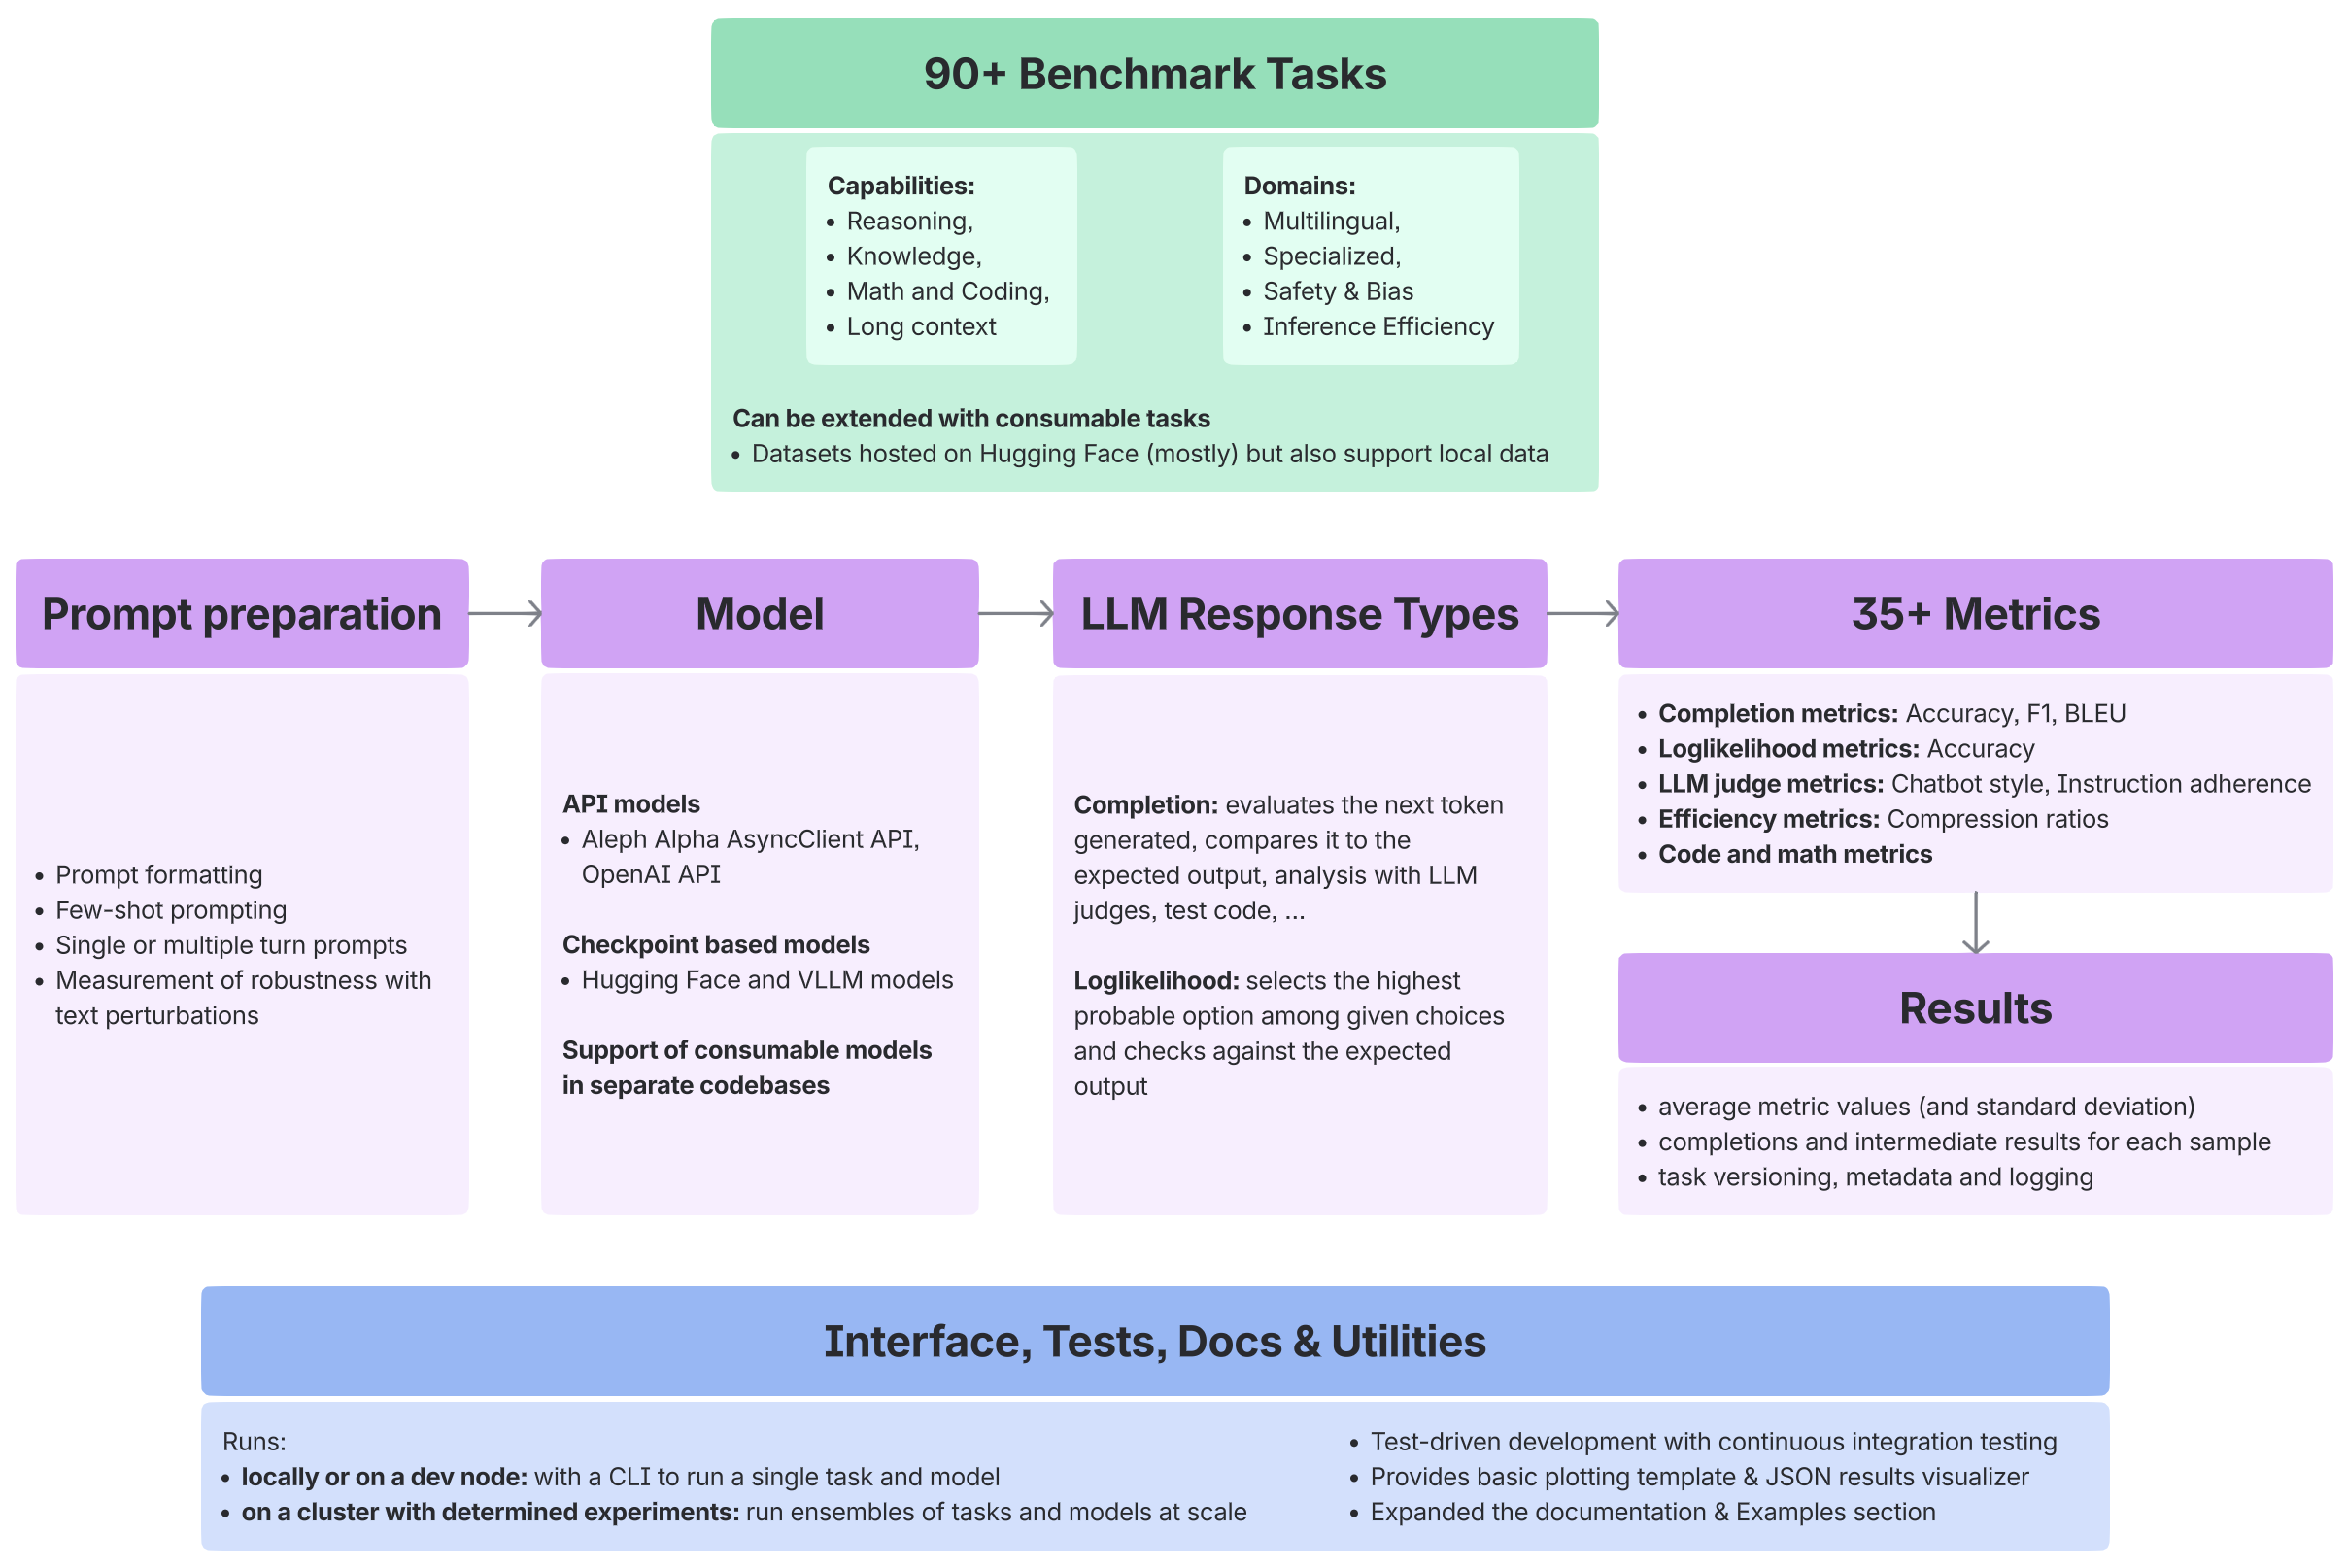
Comprehensive LLM evaluation at scale - A production-ready framework for evaluating large language models across 90+ benchmarks.


Why Choose This Framework?
- Scalability: Built for distributed evaluation. Currently providing an integration with Determined AI.
- Extensibility: Easily add custom models, benchmarks, and metrics with object-oriented base classes.
- Comprehensive: Comes pre-loaded with over 90 tasks covering a broad and diverse range, from reasoning and coding to safety and long-context. Also comes with a comprehensive set of metrics, including LLM-as-a-judge evaluations.
Other features
- Flexible Model Integration: Supports models loaded via HuggingFace Transformers or custom implementations using the BaseLLM class.
- Custom Benchmarks: Easily add new benchmarks with minimal code using the BaseTask class.
- Custom Metrics: Easily define new metrics using the BaseMetric class.
- Perturbation Testing: Robustness analysis with configurable perturbation types and probabilities.
- Rich Outputs: Generates JSON results, plots, and detailed analysis reports.
- Statistical Analysis: Includes confidence intervals and significance testing for reliable comparisons.
- Docker Support: Pre-configured Dockerfiles for local and distributed setups.
For full documentation, visit our Docs Page.
Quick Start
The codebase is tested and compatible with Python 3.12 and PyTorch 2.5. You will also need the appropriate CUDA dependencies and version installed on your system for GPU support. Detailed installation instructions can be found here.
The easiest way to get started is by installing the library via pip and use it as an external dependency.
pip install eval_framework
There are optional extras available to unlock specific features of the library:
apifor inference using the aleph-alpha client.determinedfor running jobs via determined.openaifor inference against OpenAI-compatible HTTP endpoints.transformersfor inference using the transformers library.
As a short hand, the all extra installs all of the above.
We use uv to better resolve dependencies when downloading the extras. You can install uv with:
curl -LsSf https://astral.sh/uv/install.sh | sh
or by follwing the uv installation docs.
Now, you can safely install the project with all optional extras:
uv sync --all-extras
or with pip
uv pip install eval_framework[all]
Tip: ensure python is properly installed with uv:
uv python install 3.12 --reinstall
We provide custom groups to control optional extras.
flash_attn: Installflash_attnwith correct handling of build isolation
Thus, the following will setup the project with flash_attn
uv sync --all-extras --group flash_attn
To evaluate a single benchmark locally, you can use the following command:
eval_framework \
    --models src/eval_framework/llm/models.py \
    --llm-name Smollm135MInstruct \
    --task-name "MMLU" \
    --task-subjects "abstract_algebra" \
    --output-dir ./eval_results \
    --num-fewshot 5 \
    --num-samples 10
For more detailed CLI usage instructions, see the CLI Usage Guide.
Benchmark Coverage & Task Categories
Core Capabilities
Subset of core capabilities benchmarks coverd by eval-framework:
| Reasoning | Knowledge | Math | Coding | Structured outputs | Long Context |
|---|---|---|---|---|---|
| COPA, BalancedCOPA | ARC | AIME | BigCodeBench | IFEval | InfiniteBench |
| Hellaswag | MMLU | GSM8K | HumanEval | StructEval | QUALITY |
| Winogrande | Openbook QA | MATH-500 | MBPP | ZeroSCROLLS |
Languages & Domains
Subset of language-specific and domain-specific benchmarks coverd by eval-framework:
| Multilingual | Specialized | Safety & Bias | Efficiency Metrics |
|---|---|---|---|
| WMT Translation | MMLU | TruthfulQA | Compression ratios |
| FLORES-200 | Legal (CaseHold) | Winogender | Runtime |
| Multilingual MMLU | Scientific (SciQ) | ||
| German/Finnish tasks |
Completion
Tasks focused on logical reasoning, text distillation, instruction following, and output control. Examples include:
- AIME 2024: Logical Reasoning (Math)
- DUC Abstractive: Text Distillation (Extraction)
- Custom Data: Complaint Summarization: Text Distillation (Summarization)
Loglikelihoods
Tasks emphasizing classification, reasoning, and open QA. Examples include:
- Abstract Reasoning Challenge (ARC): Classification
- Casehold: Open QA
Long-Context
Tasks designed for long-context scenarios, including QA, summarization, and aggregation. Examples include:
- InfiniteBench_CodeDebug: Programming
- ZeroSCROLLS GovReport: QA (Government)
Metrics
Evaluation metrics include:
- Completion Metrics: Accuracy, Bleu, F1, Rouge
- Loglikelihood Metrics: Accuracy Loglikelihood, Probability Mass
- LLM Metrics: Chatbot Style Judge, Instruction Judge
- Efficiency Metrics: Bytes per Sequence Position
For the full list of tasks and metrics, see Detailed Task Table.
Getting Started
Understanding the Evaluation Framework
Eval-Framework provides a unified interface for evaluating language models across diverse benchmarks. The framework follows this interaction model:
- Define Your Model - Specify which model to evaluate (HuggingFace, API, or custom)
- Choose Your Task - Select from 150+ available benchmarks or create custom ones
- Configure Evaluation - Set parameters like few-shot examples, sample count, and output format
- Run Evaluation - Execute locally via CLI/script or distribute via Determined AI
- Analyze Results - Review detailed JSON outputs, metrics, and generated reports
Core Components
- Models: Defined via
BaseLLMinterface (HuggingFace, OpenAI, custom APIs) - Tasks: Inherit from
BaseTask(completion, loglikelihood, or LLM-judge based) - Metrics: Automatic scoring via
BaseMetricclasses - Formatters: Handle prompt construction and model-specific formatting
- Results: Structured outputs with sample-level details and aggregated statistics
Your First Evaluation
- Install the framework (see Quick Start above)
pip install eval_framework[transformers]
- Create and run your first evaluation using HuggingFace model:
from functools import partial
from pathlib import Path

from eval_framework.llm.huggingface import HFLLM
from eval_framework.main import main
from eval_framework.tasks.eval_config import EvalConfig
from template_formatting.formatter import HFFormatter


# Define your model
class MyHuggingFaceModel(HFLLM):
    LLM_NAME = "microsoft/DialoGPT-medium"
    DEFAULT_FORMATTER = partial(HFFormatter, "microsoft/DialoGPT-medium")


if __name__ == "__main__":
    # Initialize your model
    llm = MyHuggingFaceModel()

    # Running evaluation on MMLU abstract algebra task using 5 few-shot examples and 10 samples
    config = EvalConfig(
        output_dir=Path("./eval_results"),
        num_fewshot=5,
        num_samples=10,
        task_name="MMLU",
        task_subjects=["abstract_algebra", "astronomy"],
        llm_class=MyHuggingFaceModel,
    )

    # Run evaluation and get results
    results = main(llm=llm, config=config)
- Review results - Check
./eval_results/for detailed outputs and use our results guide to interpret them
Next Steps
- Use CLI interface: See CLI usage guide for command-line evaluation options
- Evaluate HuggingFace models: Follow our HuggingFace evaluation guide
- Understand model arguments: Read out Model Arguments guide
- Create custom benchmarks: Follow our benchmark creation guide
- Scale your evaluations: Use Determined AI integration for distributed evaluation
- Understand your results: Read our results interpretation guide
- Log results in WandB: See how we integrate WandB for metric and lineage tracking
Documentation
Getting Started
- CLI Usage Guide - Detailed instructions for using the command-line interface
- Evaluating HuggingFace Models - Complete guide for evaluating HuggingFace models
- Understanding Results - How to read and interpret evaluation results
Advanced Usage
- Understanding Model Arguments - Thorough guide on each constructor argument for salient model classes
- Adding New Benchmarks - Complete guide with practical examples for adding new benchmarks
- Benchmarks and Metrics - Comprehensive overview of all available benchmarks and evaluation metrics
- Overview of Dataloading - Explanation of dataloading and task/sample/message structure
Scaling & Production
- Using Determined - Guide for distributed evaluation using Determined AI
- Controlling Upload Results - How to manage and control the upload of evaluation results
Contributing
- Contributing Guide - Guide for contributing to this project
- Testing - Guide for running tests comparable to the CI pipelines
Citation
If you use eval-framework in your research, please cite:
@software{eval_framework,
  author={Aleph Alpha Research},
  title={Aleph Alpha Eval Framework},
  year={2026},
  version = {x.y.z},
  url={https://github.com/Aleph-Alpha-Research/eval-framework}
}
License
This project is licensed under the Apache License 2.0.
The constituent tasks' datasets can be subject to specific, more restrictive license terms by third parties. By using eval-framework you agree to adhere to and be bound by such license terms in the individual case.
This project has received funding from the European Union’s Digital Europe Programme under grant agreement No. 101195233 (OpenEuroLLM).
The contents of this publication are the sole responsibility of the OpenEuroLLM consortium and do not necessarily reflect the opinion of the European Union.
1 maintainer

Release files for eval-framework 0.11.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| eval_framework-0.11.6.tar.gz | 233.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| eval_framework-0.11.6-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 557.9 kB
Release files / eval_framework-0.11.6.tar.gz
| Download URL | eval_framework-0.11.6.tar.gz |
|---|---|
| Size | 233.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
04a621c2ac8650db6399f26382232a2c0b4b67da8df27592a80366bf79c59067
|
|
BLAKE2b-256 checksum How to use checksums |
9c974c27e7a9cb64167ce8e4aca320f7830e56962ea483d51b31ceea102faf2e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 4, 2026.
Transparency logRelease files / eval_framework-0.11.6-py3-none-any.whl
| Download URL | eval_framework-0.11.6-py3-none-any.whl |
|---|---|
| Size | 324.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8c2eb32be01ed25c141a909b7c9fe808213a6c3a85c891460d7df92d93df575c
|
|
BLAKE2b-256 checksum How to use checksums |
46999c0347ff08b5dd48989aea382c72b809d3a27c90101bfa9b2f79f2206c3d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 4, 2026.
Transparency log













