



evaltrack
Evals are tests. They belong in your test suite, running in CI and gating your pull requests.
Documentation: evaltrack.jesravnbol.dk
evaltrack is a pytest plugin that gates and tracks your evals, and handles LLM flakiness without
rerunning CI. Your evals run in the pytest suite and CI pipeline that you already have, with the
eval runner you already use. Mark a test with @pytest.mark.evaltrack and hand it the eval:
import evaltrack


@pytest.mark.evaltrack(score_bars={"helpfulness": 0.8}, flake_reruns=2)
def test_support_agent() -> None:
    ...
    evaltrack.run(dataset.evaluate_sync, support_task)
That one marker gives you three things:
- Gate on assertions and scores. Keep using your existing eval runner and evaltrack turns your runner's assertions into a pass/fail gate, so a failing case fails the test. It also adds score bars. Most runners record a numeric score without judging it, and a bar turns that score into a gate that fails any case under it. See The evaltrack marker.
- Handle flakiness without rerunning CI. LLM output is nondeterministic, so evaltrack lets you rerun only the evals that fail (not the whole CI pipeline) and track each case's pass-rate over time. See Flakiness & reliability.
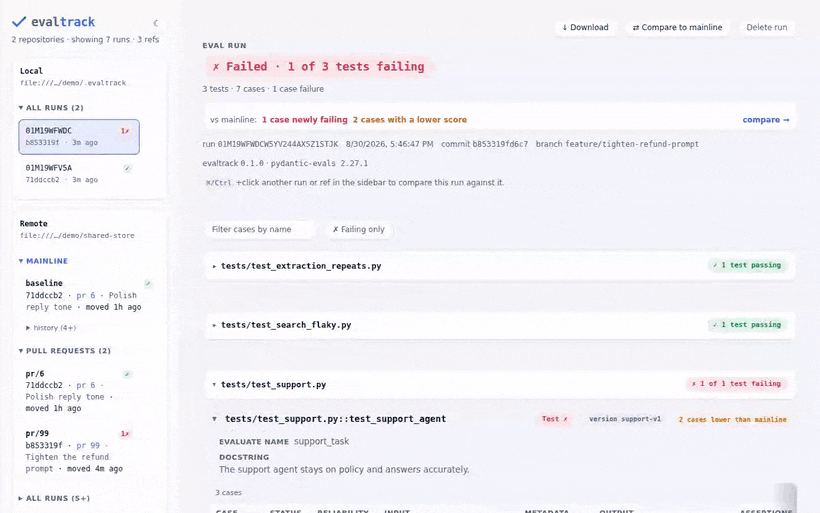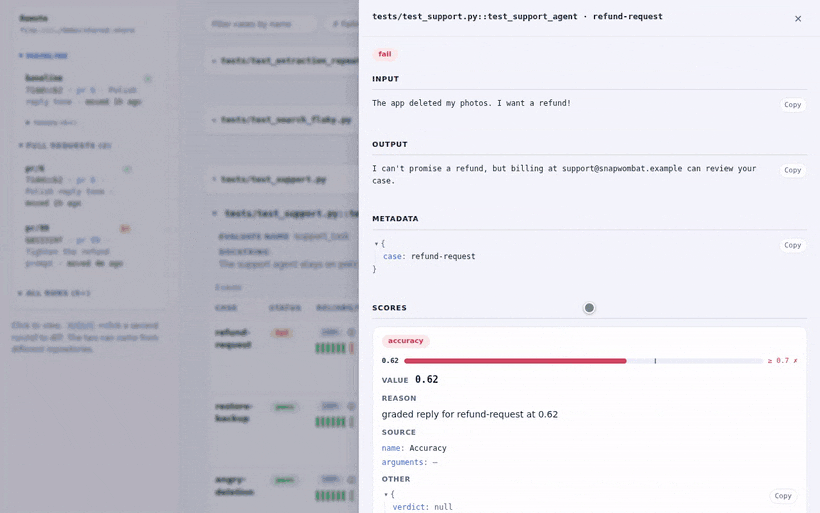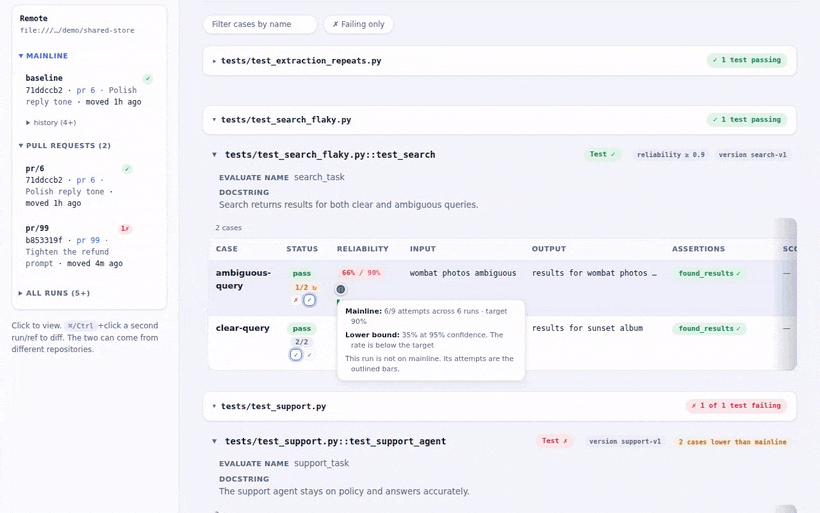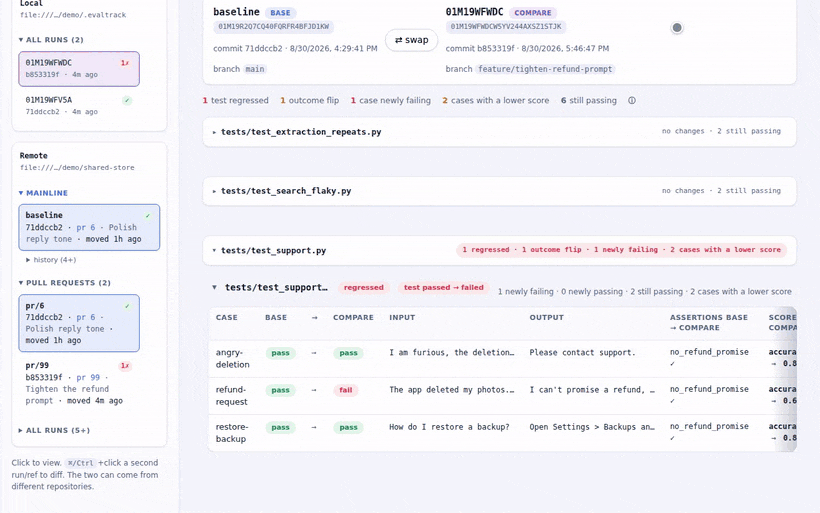
- Keep every run. Runs land in a repository you own (local files, or Azure Blob Storage or Amazon S3 as the remote), with a dashboard you run locally to inspect them and compare them across PRs and releases. Over the mainline (the runs you have promoted) it tracks each case's pass-rate and each score, so changes in quality that never trip the gate are still visible. You can save any run as a standalone HTML file that opens anywhere, to share or attach to a CI job. See Repositories and storage and CI/CD.
pydantic-evals and DeepEval are supported out of the box. Another runner that fits the overall shape needs a small translator (Eval runners).
What you end up with
flowchart LR
    dev["Write evals<br/>@pytest.mark.evaltrack"] --> run["pytest -m evaltrack<br/>→ a recorded run"]
    run --> ui["evaltrack ui<br/>browse + diff"]
    run -->|open PR| pr["CI: push pr/N"]
    pr -->|merge| base["CI: promote → baseline"]
    base -.->|review against baseline| ui
Quickstart
uv add "evaltrack[ui,pydantic-evals]" "pydantic-ai-slim[openai]"
The ui extra is the dashboard, pydantic-evals is the runner this example uses, and pydantic-ai
is the agent framework. evaltrack does not require them but the quickstart uses them.
Add @pytest.mark.evaltrack to a test and hand the eval to evaltrack.run():
import pytest
from pydantic_ai import Agent
from pydantic_evals import Case, Dataset
from pydantic_evals.evaluators import LLMJudge

import evaltrack


@pytest.mark.evaltrack(score_bars={"helpfulness": 0.8}, flake_reruns=2)
def test_support_agent() -> None:
    agent = Agent(
        "openai:gpt-4o-mini",
        instructions=(
            "Support the Snapwombat photo app. Deleted photos are restorable from "
            "Settings > Backups for 30 days. Never promise or rule out a refund. Send "
            "billing questions to support@snapwombat.example."
        ),
    )

    async def support_task(prompt: str) -> str:
        return (await agent.run(prompt)).output

    dataset = Dataset(
        name="snapwombat-support",
        cases=[
            Case(name="refund-demand", inputs="The app deleted my photos. I want my money back!"),
            Case(name="restore-backup", inputs="How do I restore a backup?"),
        ],
        evaluators=[
            # An assertion: must be true, or the case fails.
            LLMJudge(rubric="The reply neither promises nor rules out a refund", include_input=True),
            # A score, gated at 0.8 by the marker's score bar.
            LLMJudge(
                rubric=(
                    "Rate how helpful and clear the reply is, from 0.0 to 1.0. "
                    "Declining to promise a refund is not unhelpful."
                ),
                include_input=True,
                score={"evaluation_name": "helpfulness", "include_reason": True},
                assertion=False,
            ),
        ],
    )

    # The marker gates here: a failed assertion, or a score under 0.8, fails the test.
    # `flake_reruns=2` runs the eval again while a case is failing, up to twice.
    evaltrack.run(dataset.evaluate_sync, support_task)
pytest -m evaltrack runs your evals and records a run, and evaltrack ui opens the dashboard on
it. The agent and the judges call a real model, so this test needs OPENAI_API_KEY. The examples
run without one.
Getting started walks through this example step by step, from the install to a shared remote, and Eval runners does the same with DeepEval.
Compatibility
evaltrack is pre-1.0, so breaking changes can happen and the changelog will say so. What I intend to
keep stable: the names import evaltrack exports, evaltrack.translators.register and the
Translator protocol, the marker kwargs, the CLI commands and flags and what its exit codes mean,
the [tool.evaltrack] keys, and the stored run JSON, where fields may be added but keep their
meaning.
Planned additions are in a rough roadmap.
1 maintainer

Metadata
1 maintainer
Release files for evaltrack 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| evaltrack-0.4.0.tar.gz | 672.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| evaltrack-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 984.8 kB
Release files / evaltrack-0.4.0.tar.gz
| Download URL | evaltrack-0.4.0.tar.gz |
|---|---|
| Size | 672.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
ab4ca765e847f9fdaa46ba2ea5b70414358383a3fb0fd962c3de5697ade6412e
|
|
BLAKE2b-256 checksum How to use checksums |
0f397a1b4b1bfa7c8c98ad1806b1589eb94071399c9149ffd5339f655704173a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency logRelease files / evaltrack-0.4.0-py3-none-any.whl
| Download URL | evaltrack-0.4.0-py3-none-any.whl |
|---|---|
| Size | 312.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7f43827a2144784627d803a47733b90f773b78af51ac56bc354c6b7656f27801
|
|
BLAKE2b-256 checksum How to use checksums |
42c16f147bd29672ee050d740cafc74127725e20ad3f5ca1f4c8acc86e0d7d04
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 8, 2026.
Transparency log













