
evidential


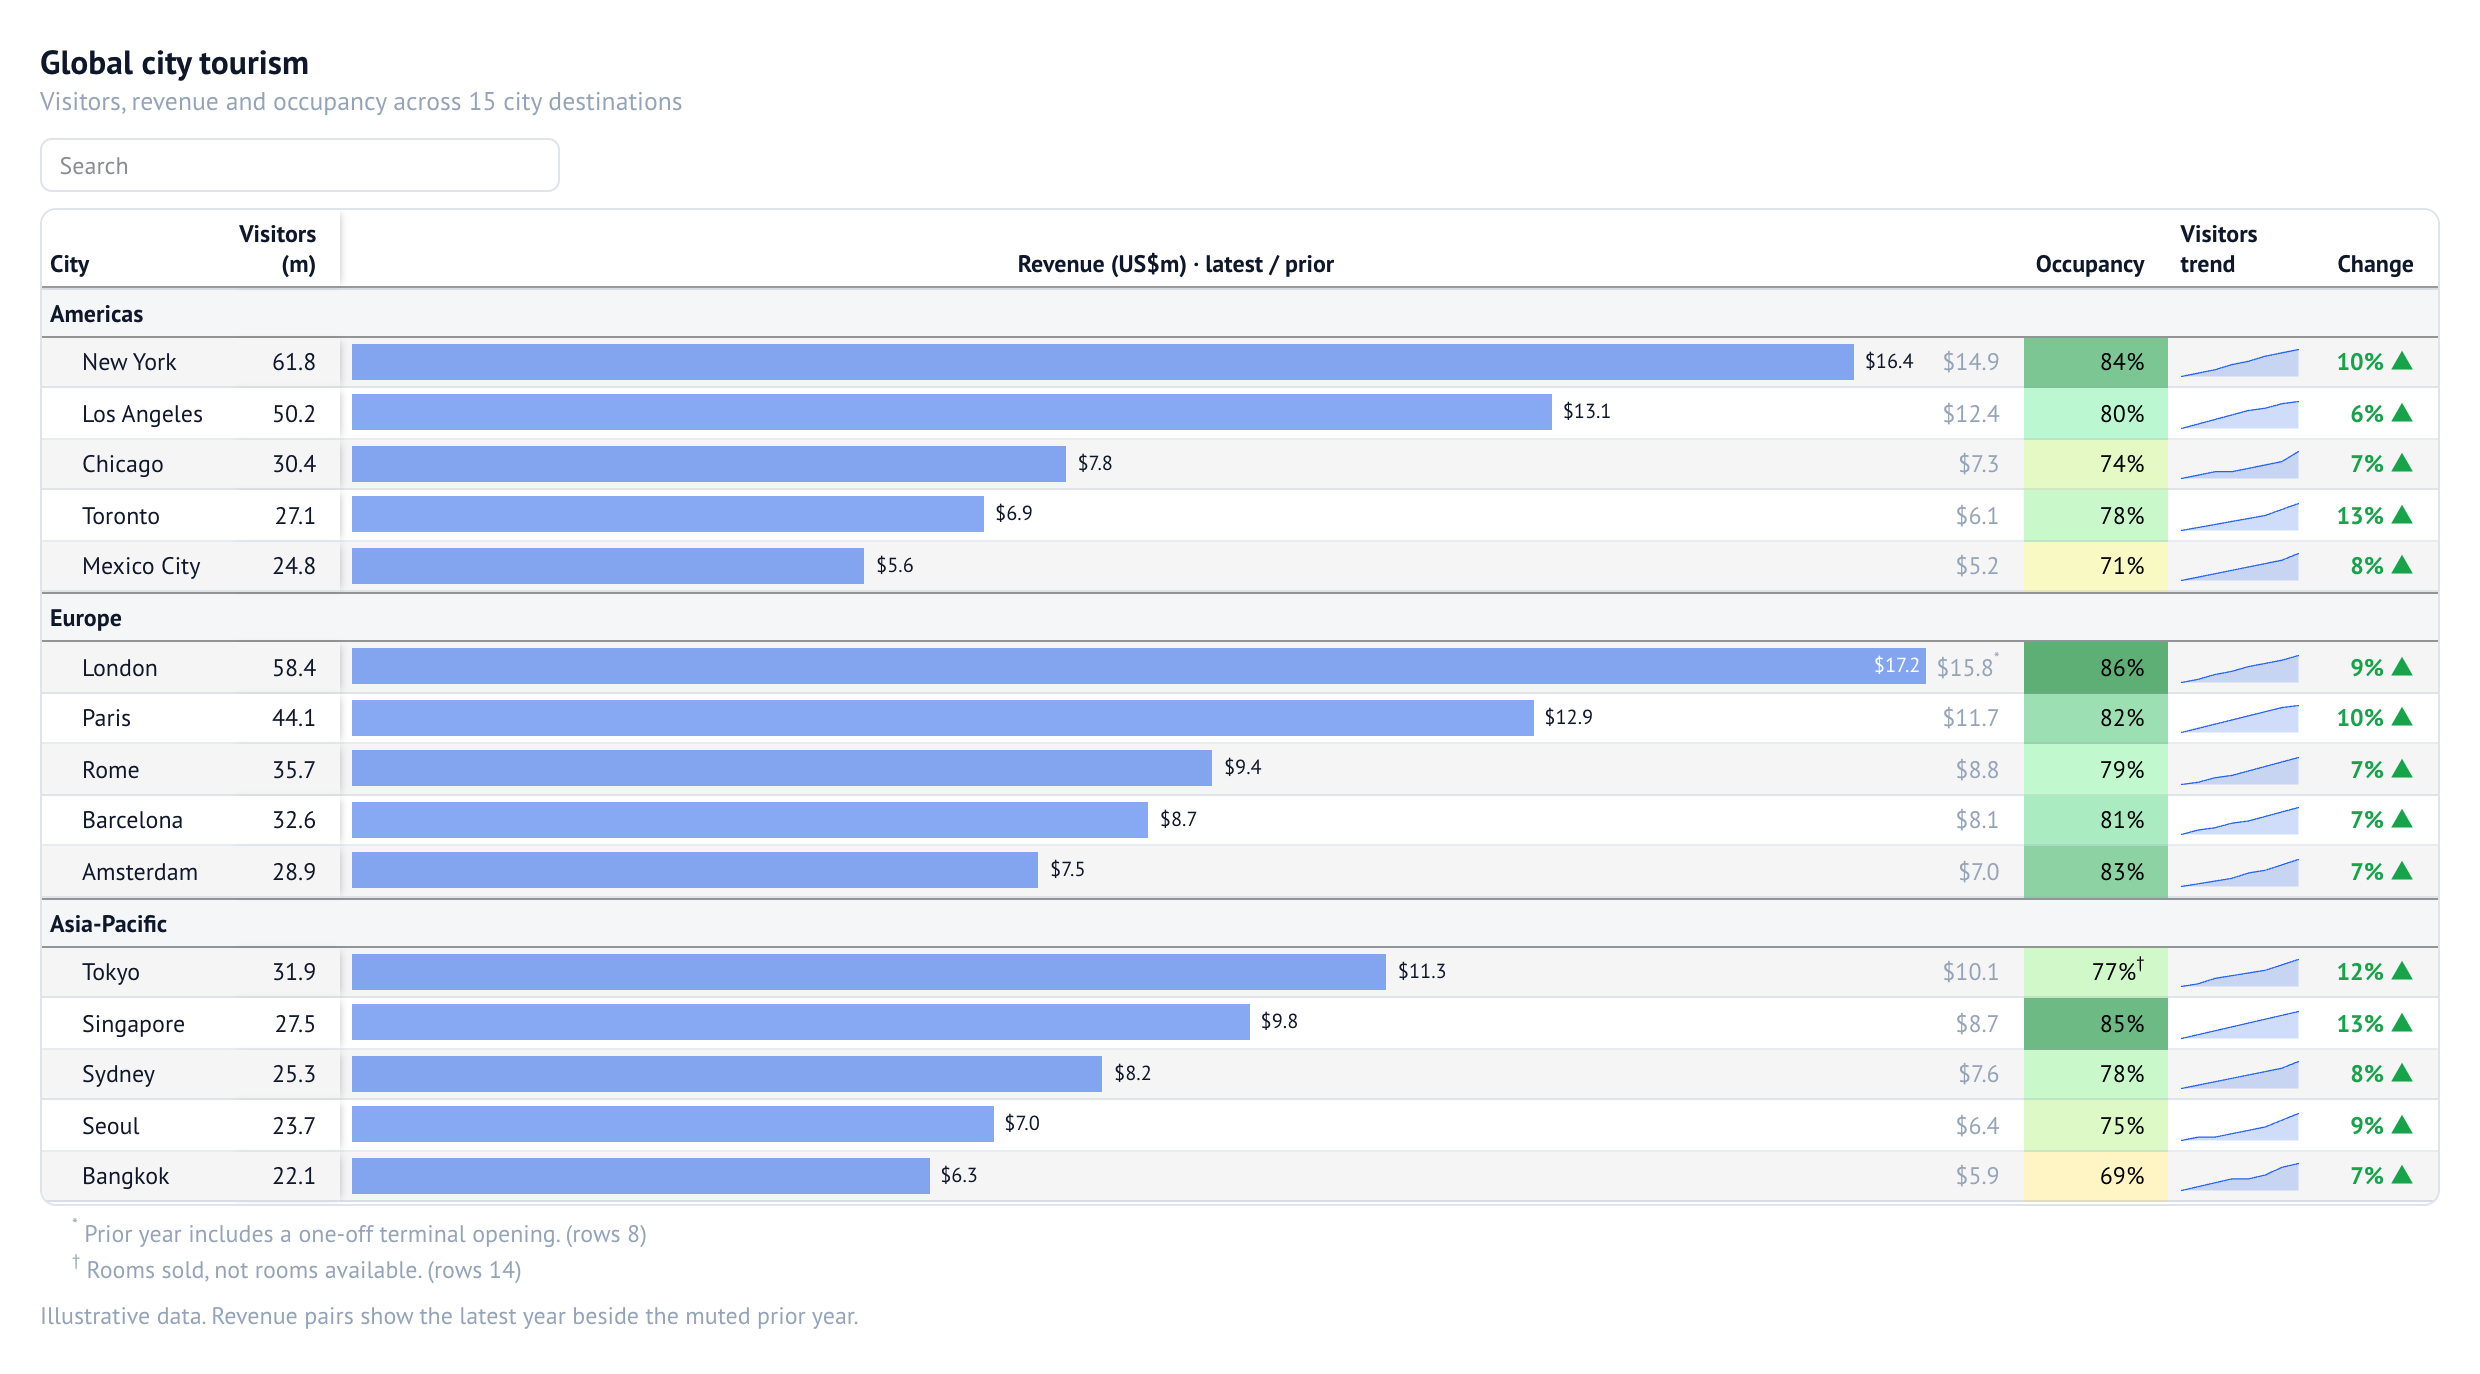
Evidence.dev-style interactive tables for Marimo, packaged as an anywidget and powered by DuckDB when you need it.
evidential is a display widget. SQL or pandas shapes the data, Python says
how to present it, and the browser renders it: sort, search, paginate, freeze
columns, group with subtotals, download CSV and open a fullscreen view.
Status: alpha (
0.1.0), not yet published on PyPI. Install from a checkout below. The API may change.
Install
git clone https://github.com/edouardp/evidential
cd evidential
uv sync
uv run marimo edit notebooks
The renderer bundle is committed, so users need no JavaScript toolchain.
Extras are evidential[duckdb], evidential[marimo] and evidential[studio]
(see pyproject.toml).
1. Your first table
from evidential import EvidentialTable

tips = [
    {"city": "Boston", "trips": 1284, "revenue": 48120.50, "tip_rate": 0.183},
    {"city": "New York", "trips": 3502, "revenue": 142880.25, "tip_rate": 0.171},
    {"city": "Chicago", "trips": 2118, "revenue": 76540.00, "tip_rate": 0.164},
    {"city": "San Francisco", "trips": 1907, "revenue": 98320.75, "tip_rate": 0.196},
    {"city": "Seattle", "trips": 1463, "revenue": 61140.10, "tip_rate": 0.188},
]

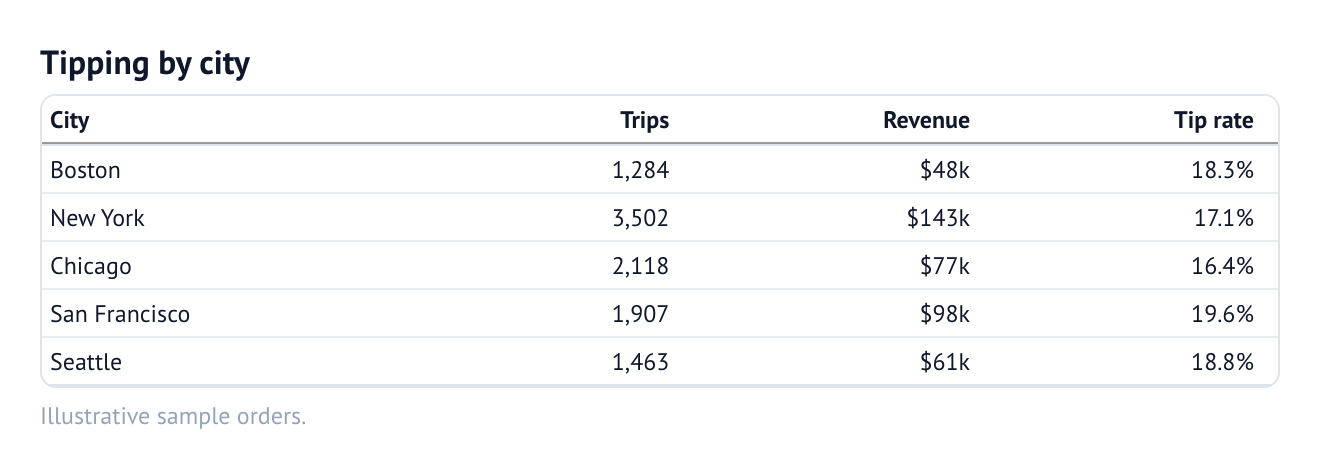
EvidentialTable(tips, title="Tipping by city")
Types are inferred from the data. Integers default to whole numbers (num0),
floats choose an auto-scaling format, dates render as dates, and lists become
sparkline input.
In Marimo, output the table directly. Wrap it with mo.ui.anywidget(...) only
when another cell needs to read widget state:
import marimo as mo

table = mo.ui.anywidget(EvidentialTable(tips, title="Tipping by city"))
table
2. Point it at your data
EvidentialTable accepts a list of dicts, a pandas DataFrame, a PyArrow
table, or a DuckDB relation:
EvidentialTable(frame)
EvidentialTable(arrow_table)
EvidentialTable(con.table("orders"))
EvidentialTable(con.sql("SELECT * FROM orders LIMIT 500"))
DuckDB is optional, but it makes the examples below concise:
from evidential import duck

con = duck.connect()  # DuckDB with httpfs loaded
A DuckDB table or view relation carries COMMENT ON COLUMN text into the
header tooltip. A raw con.sql(...) result does not know its source; pass the
comments explicitly:
from evidential import EvidentialTable, duck

comments = {name: {"info": text} for name, text in duck.column_comments(con, "orders").items()}
EvidentialTable(con.sql("SELECT * FROM orders LIMIT 500"), column_config=comments)
Arrow field metadata (comment, description or info) works the same way,
including through Parquet and Feather. You can also set a description directly:
col.currency("revenue").info("Net revenue in USD")
For Amazon S3 Tables, use duck.connect_s3_tables
or see notebooks/02_s3_tables.py.
3. Describe columns
Column descriptions are built one column at a time with col.*. Every factory
returns an immutable Column; every chain method returns a new one.
from evidential import EvidentialTable, col, settings

EvidentialTable(
    tips,
    columns=[
        col.text("city", title="City"),
        col.integer("trips", title="Trips"),
        col.currency("revenue", title="Revenue"),
        col.percent("tip_rate", decimals=1, title="Tip rate"),
    ],
    settings=settings(
        title="Tipping by city",
        caption="Illustrative sample orders.",
        width="620px",
    ),
)
Kinds
The factory chooses the kind; the chain refines it.
| Kind | Factories |
|---|---|
| Text | col.text, col.chip, col.icons, col.flag, col.boolean |
| Numbers | col.number, col.integer, col.currency, col.percent |
| Time | col.date, col.time, col.datetime |
| Marks | col.bar, col.point, col.points, col.range, col.stacked_bar, col.strip, col.boxplot, col.distribution |
| Values as marks | col.color, col.delta, col.sparkline, col.symbols, col.rating, col.repeat |
| Cells | col.link / col.url, col.image, col.logo, col.markdown, col.html |
| Composition | col.group, col.subcolumns, col.merge, col.array, col.auto |
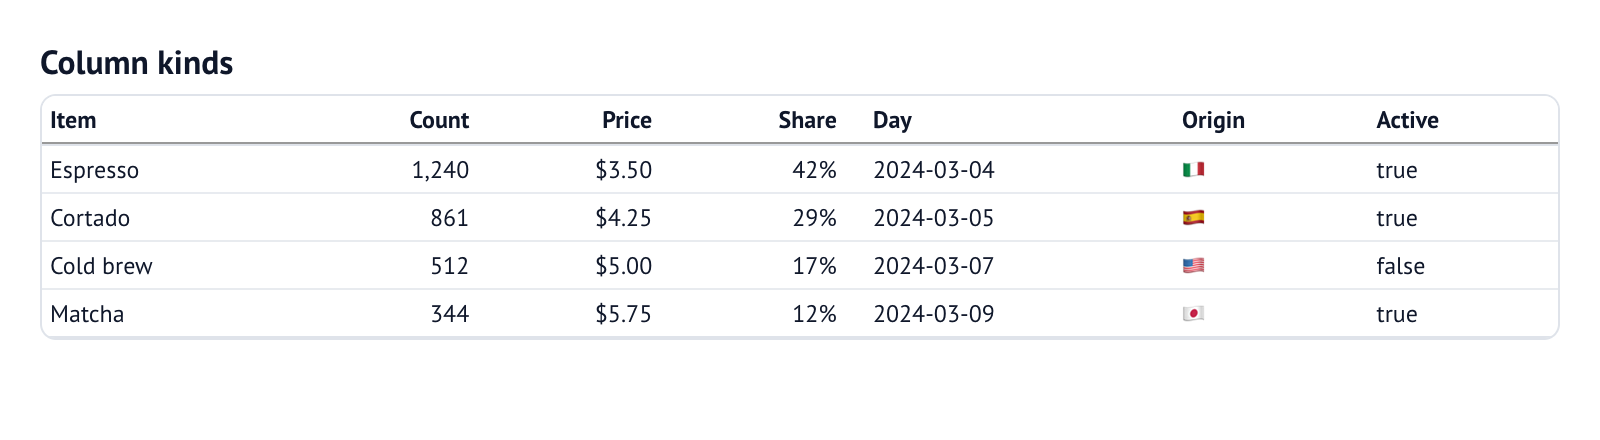
col.number auto-scales. col.currency takes code= (usd, eur, gbp, …)
and decimals=. col.percent treats values as proportions unless
whole=True. Dates and times accept relative=.
columns=[
    col.text("city"),
    col.currency("revenue", code="eur", decimals=0),
    col.percent("tip_rate", decimals=1),
    col.date("week", fmt="mmm-yy"),
    col.time("opened_at", fmt="hms"),
    col.datetime("updated_at", relative="hour"),
    col.flag("country"),
    col.boolean("active", true_symbol="✓", false_symbol="✗"),
]
Refine a column
col.currency("revenue", decimals=0).neg(bracket=True).bold()
col.percent("growth", decimals=1).delta(down_is_good=False).italic()
col.number("score").color(scale="Blues", min=0, max=100)
| Need | Chain methods |
|---|---|
| Formatting | .fmt(code) / .format(code), .total_fmt(), .subtotal_fmt(), .align(), .align_decimals(), .figure_style() |
| Text | .title(), .info(), .footnote(), .bold(), .italic(), .font(), .font_color(), .wrap(), .rotate_title() |
| Values | .neg(), .red_negatives(), .null_text(), .blank(), .blank_below(), .blank_above(), .highlight(), .cell_style() |
| Placement | .group(), .subcolumn(), .hide(), .repeat_values(), .sort_by(), .relative(), .fmt_column() |
| Rich cells | .markdown(), .html(), .link(), .image(), .logo(), .template() |
| Visualisations | .color(), .chip(), .delta(), .sparkline(), .symbols(), .bar(), .point(), .range(), .scale(), .label(), .domain() |
.fmt() is the escape hatch for an exact SSF
code. Common presets:
col.number("share").fmt("pct1")
col.number("distance").fmt("num1k")
col.currency("revenue").fmt("usd0")
col.date("month").fmt("mmm-yy")
col.number("bytes").fmt("bytes")
col.number("elapsed").fmt("duration")
col.number("rank").fmt("roman")
col.number("value").fmt("sci")       # 1.23 × 10⁵
col.auto("revenue") keeps the inferred type, format and metadata, then applies
your refinements. A Column is a Mapping, so to_config() returns the plain
dict and the dict form remains valid anywhere a column is accepted:
columns=[col.text("city"), col.auto("revenue").font_color("#334155")]
column_config={"revenue": col.currency("revenue", decimals=0)}
4. Set the table's presentation
Use settings(...) for a reusable bundle. Explicit keyword arguments win over
the bundle.
REPORT = settings(
    title="Monthly revenue",
    subtitle="By city and channel",
    caption="Source: orders.parquet",
    page_size=15,
    search=True,
    download=True,
    row_shading=True,
    row_lines=True,
    freeze_columns=1,
    width="900px",
    max_height="70vh",
)

EvidentialTable(tips, columns=[...], settings=REPORT, title="This month")
| Goal | Options |
|---|---|
| Frame and type | title, subtitle, caption, info, info_link, width, max_height, border, compact, font_size, theme, header_color, header_font_color, background_color |
| Columns | freeze_columns, wrap, wrap_titles, format_titles, stretch, order_columns_by_group, column_stats, align_decimals, figure_style, rotate_titles |
| Interaction | search, sortable, page_size, download, row_numbers, default_sort, select |
| Rows | row_shading, row_lines, group_gap, stub, stub_head, null_text |
| Groups and totals | show_total_row, total_label, total_position, subtotal_position, collapsible, collapsed, groups_open, group_type |
The API reference lists every option and value.
5. Add visualisations
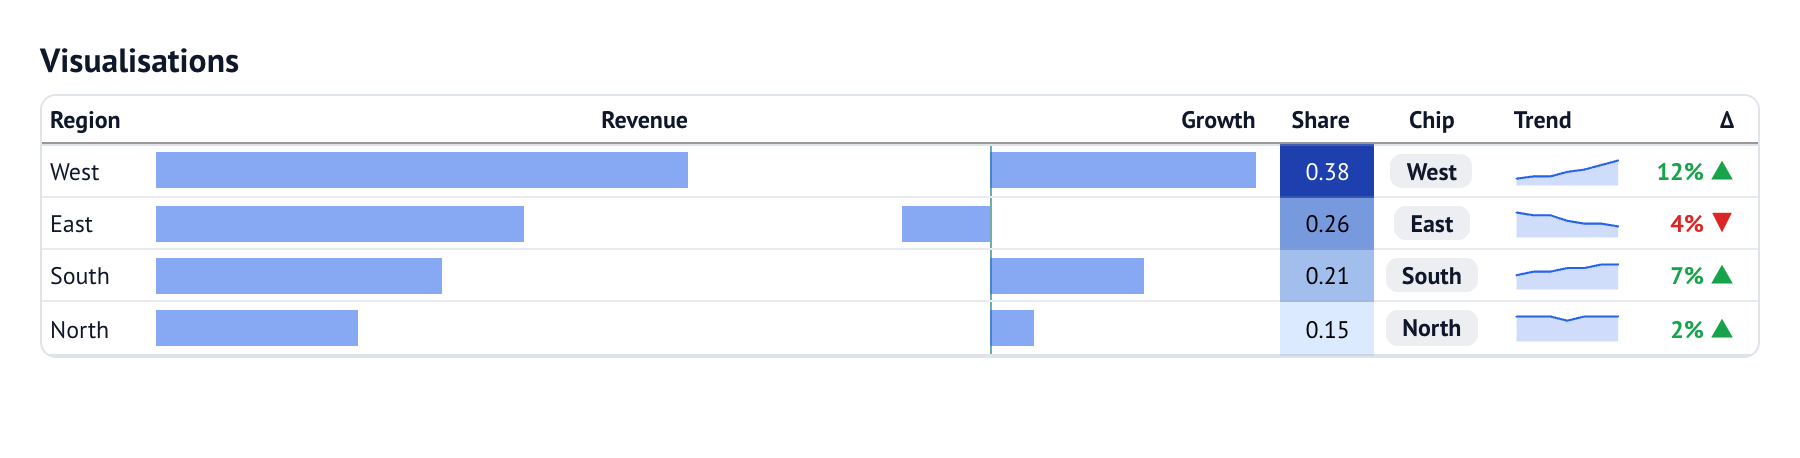
A visualisation presents the underlying value; sorting, search, statistics and CSV export still use the raw value.
columns=[
    col.text("region", title="Region"),
    col.bar("revenue", format="usd0", label=True, title="Revenue"),
    col.bar("growth", center=True, format="pct1", label=True, title="Growth"),
    col.number("share").color(scale="Blues").title("Share"),
    col.chip("status", min_width=80),
    col.percent("change", decimals=1).delta(down_is_good=False, neutral_range="0.02"),
    col.sparkline("trend", type="area", title="Trend"),
    col.rating("stars", max=5),
]
Graphic gallery
Every graphic type, with the Python that builds it. The images come from
notebooks/50_graphics_gallery.py, captured
by make api-screenshots.
Bar
columns=[
    col.text("region"),
    col.bar("sales", format="usd0", label=label.auto_position("outside end"), title="Sales"),
]
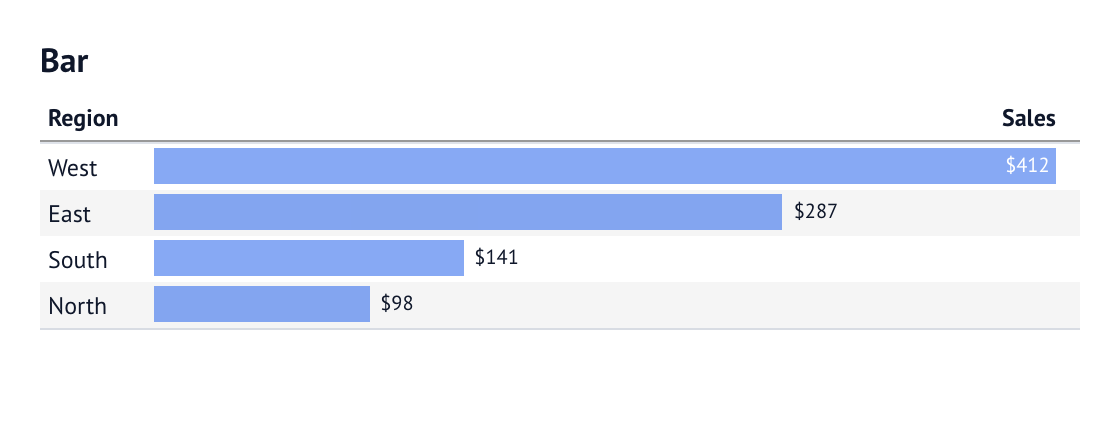
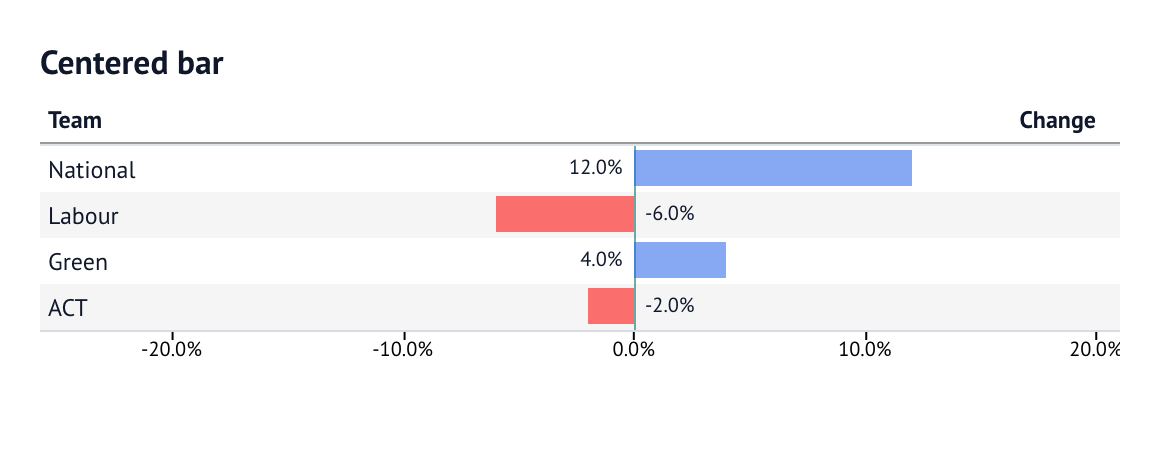
Centered bar
columns=[
    col.text("team"),
    col.bar("change", center=True, format="pct1", label=True, title="Change")
       .scale(domain=(-0.2, 0.2), axis=True, axis_position="bottom"),
]
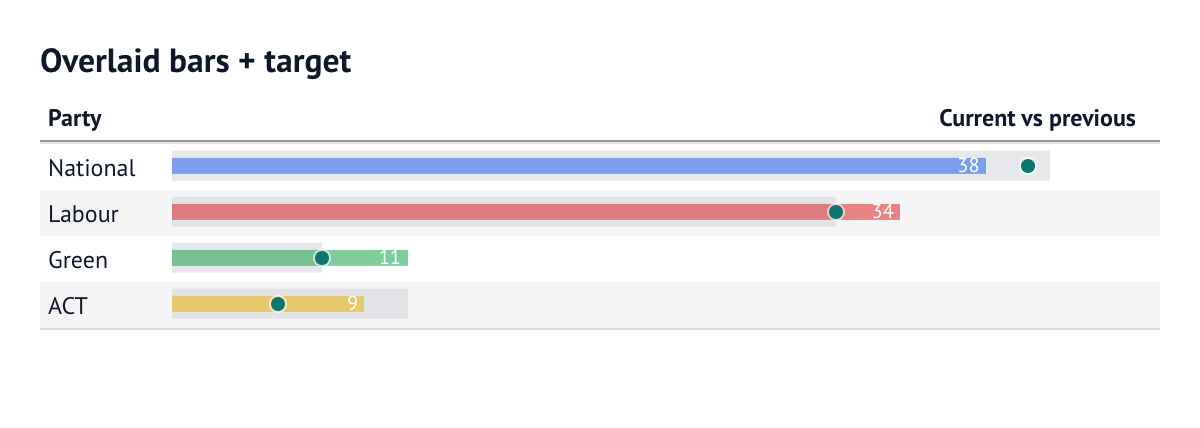
Overlaid bars with a target
columns=[
    col.text("party"),
    (
        col.bar("previous", format="num0", color="#d1d5db", size=0.85)
        .bar("current", format="num0", color="@colour", size=0.45,
             label=label.position("inside end"), title="Current vs previous")
        .point("target", color="#0f766e", size=7)
        .scale(domain=(0, 45))
    ),
]
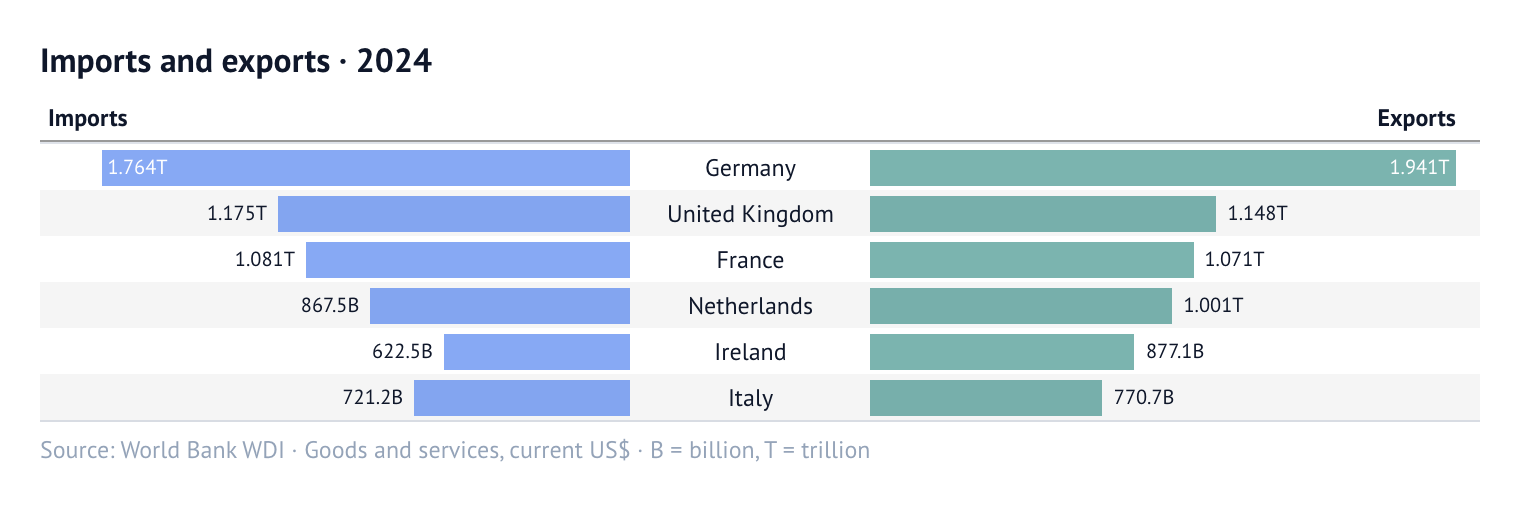
Back-to-back bars
columns=[
    col.bar("spend", format="usd1", direction="left", color="@color",
            label=label.auto_position("outside end"), pad=3).align("left"),
    col.text("country", title=""),
    col.bar("rate", format="num2", color="@color",
            label=label.auto_position("outside end"), pad=3).align("right"),
    col.auto("color").hide(),
]
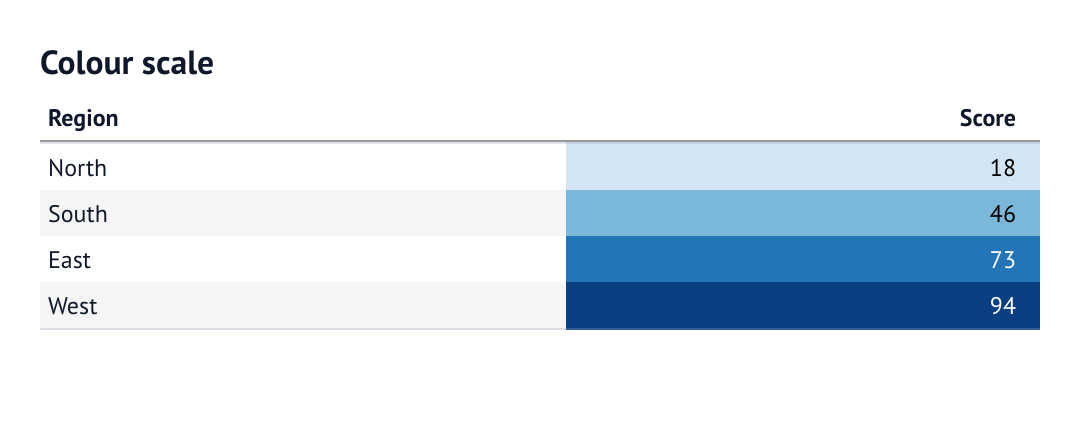
Color scale
columns=[
    col.text("region"),
    col.number("score", fmt="num0").color(scale="Blues", min=0, max=100).title("Score"),
]
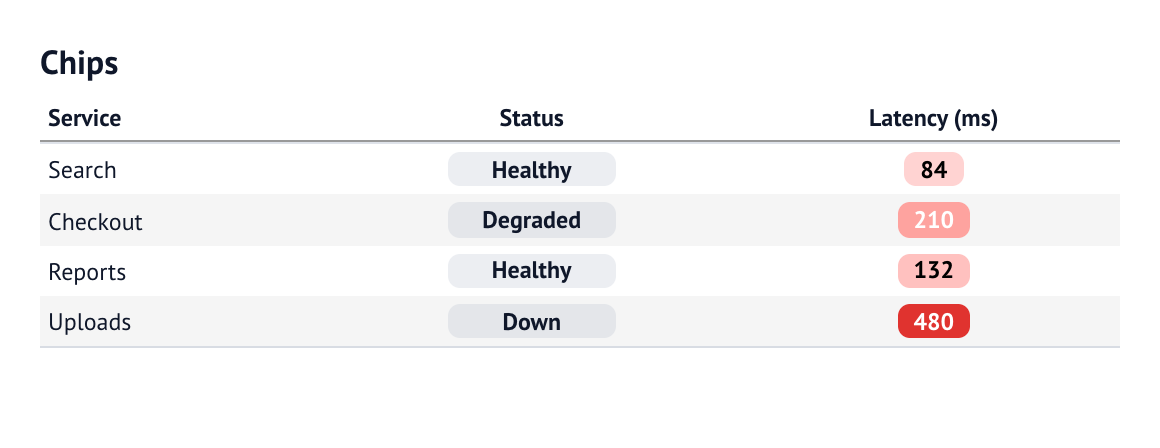
Chip
columns=[
    col.text("service"),
    col.chip("status", min_width=84, title="Status"),
    col.number("latency", fmt="num0").chip(scale="red", min=0, max=500).title("Latency (ms)"),
]
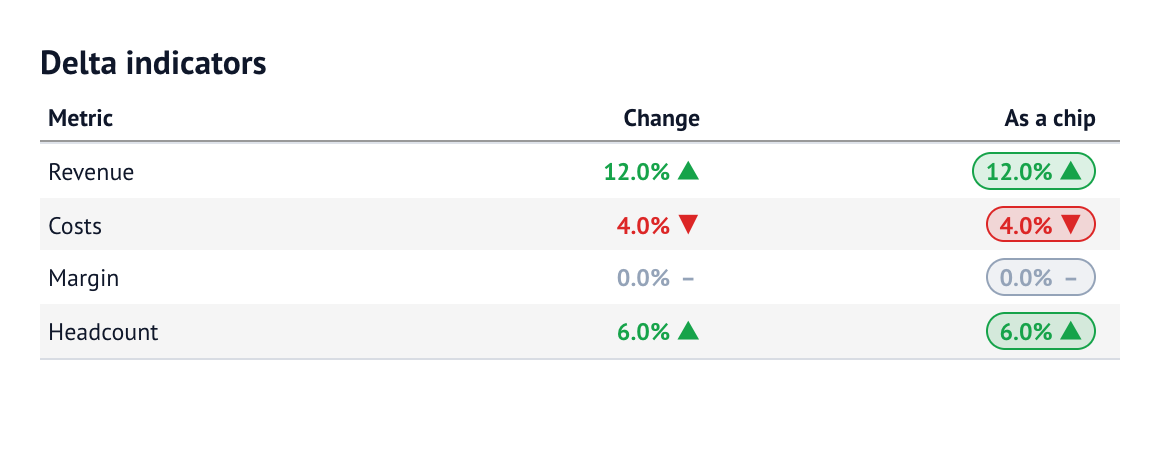
Delta
columns=[
    col.text("metric"),
    col.percent("change", decimals=1, title="Change")
       .delta(down_is_good=False, neutral_range="-0.02:0.02"),
    col.percent("change", decimals=1, title="As a chip")
       .delta(down_is_good=False, neutral_range="-0.02:0.02", chip=True),
]
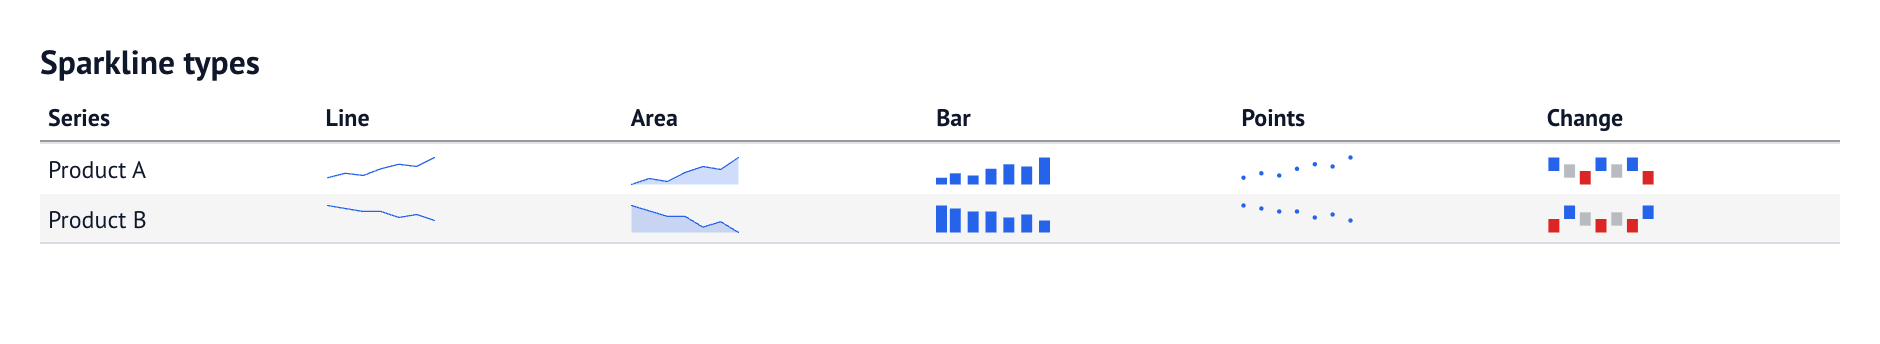
Sparklines
columns=[
    col.text("series"),
    col.sparkline("line", type="line", title="Line"),
    col.sparkline("area", type="area", fit_to_data=True, title="Area"),
    col.sparkline("bar", type="bar", title="Bar"),
    col.sparkline("points", type="points", markers=True, title="Points"),
    col.sparkline("change", type="change", title="Change"),
]
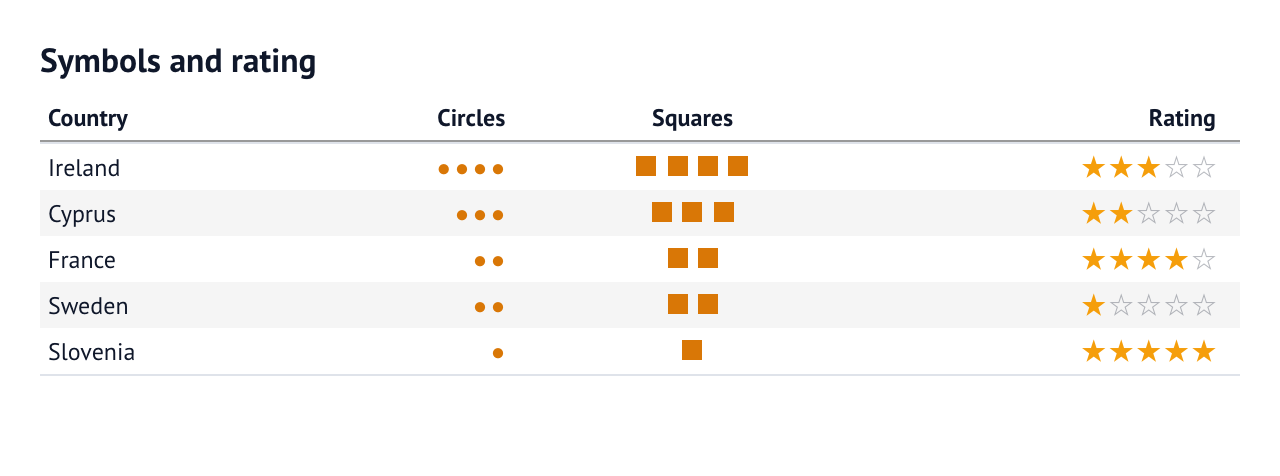
Symbols and rating
columns=[
    col.text("country"),
    col.symbols("gold", symbol="■", color="#d97706", title="Glyph"),
    col.symbols("gold", shape="square", color="#d97706", title="Squares"),
    col.rating("score", title="Rating"),
]
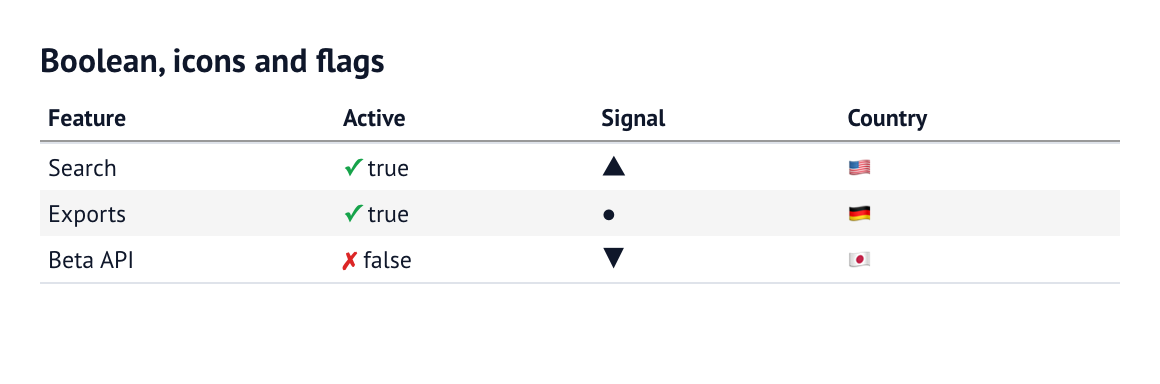
Boolean, icons and flags
columns=[
    col.text("feature"),
    col.boolean("active", true_symbol="✓", false_symbol="✗", title="Active"),
    col.icons("signal", map={"up": "▲", "flat": "●", "down": "▼"}, title="Signal"),
    col.flag("country", title="Country"),
]
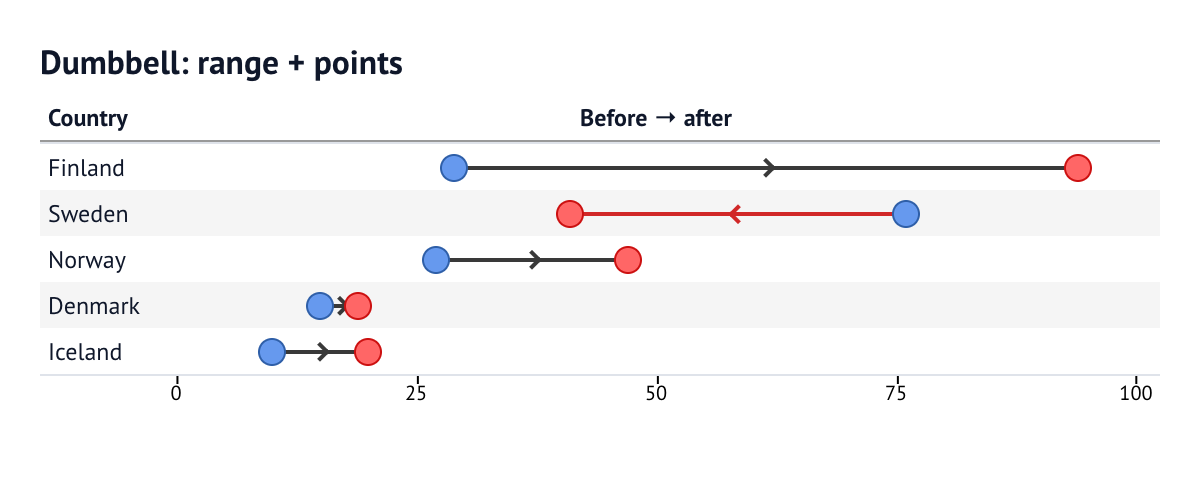
Dumbbell: range plus points
columns=[
    col.text("country"),
    (
        col.range("before", "after", color="#222222", color_negative="#cc1111",
                  size=2, direction_marker=True)
        .point("before", color="#6699ee", outline="#2f5fa8", size=12)
        .point("after", color="#ff6666", outline="#cc1111", size=12)
        .title("Before → after").align("center")
        .scale(domain=(0, 100), axis=True, axis_position="bottom")
    ),
]
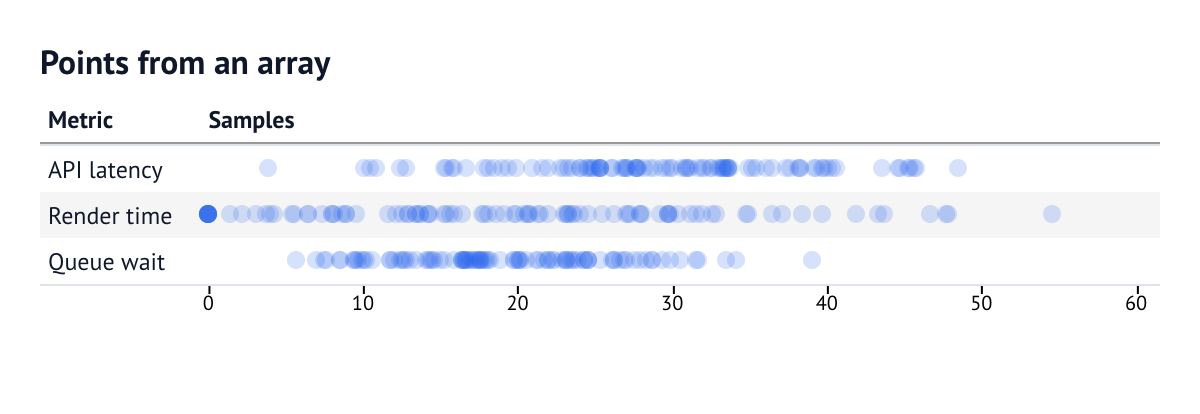
Points from an array
columns=[
    col.text("metric"),
    col.points("samples", color="#2563eb", outline=False, title="Samples")
       .scale(domain=(0, 60), axis=True, axis_position="bottom"),
]
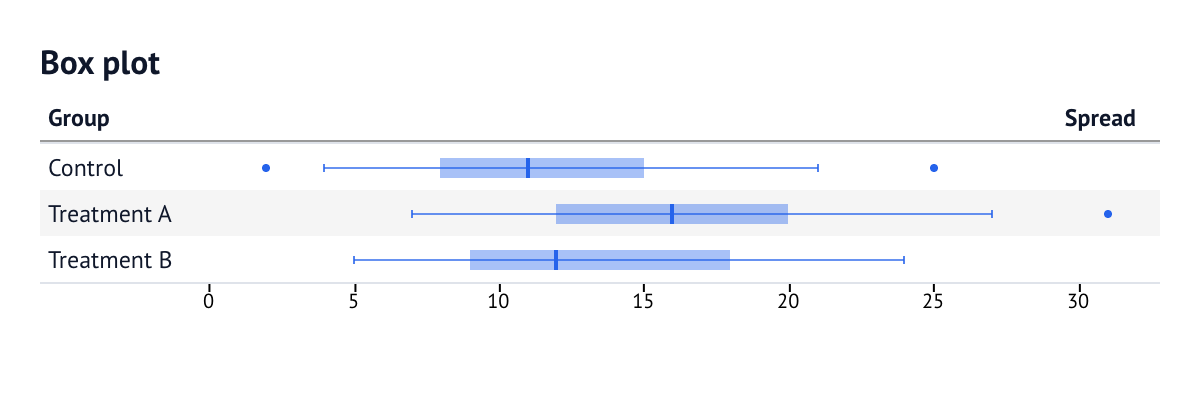
Box plot
columns=[
    col.text("group"),
    col.boxplot("lo", "q1", "med", "q3", "hi", outliers="outs",
                whisker="iqr", title="Spread")
       .scale(domain=(0, 32), axis=True, axis_position="bottom"),
]
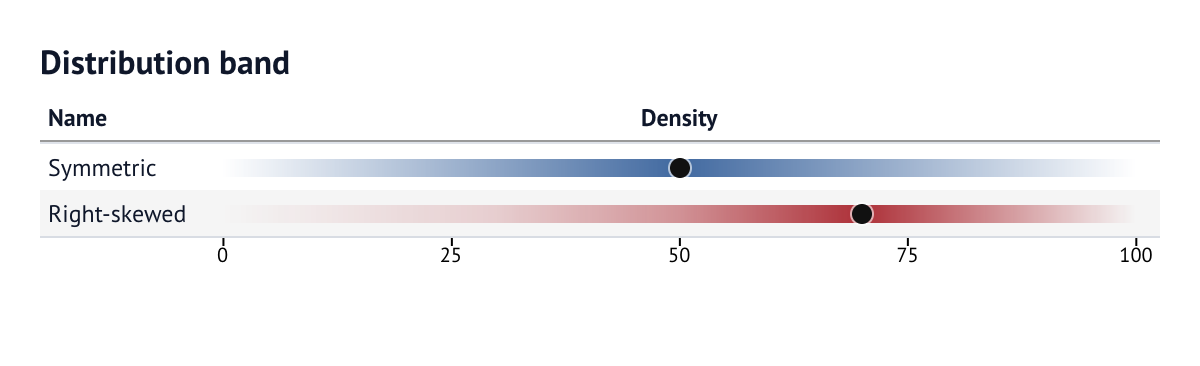
Distribution band
columns=[
    col.text("name"),
    (
        col.distribution("curve", x="x", y="pdf", color="@ink")
        .point("median", color="#111111", outline=False)
        .title("Density").align("center")
        .scale(domain=(0, 100), axis=True, axis_position="bottom")
    ),
]
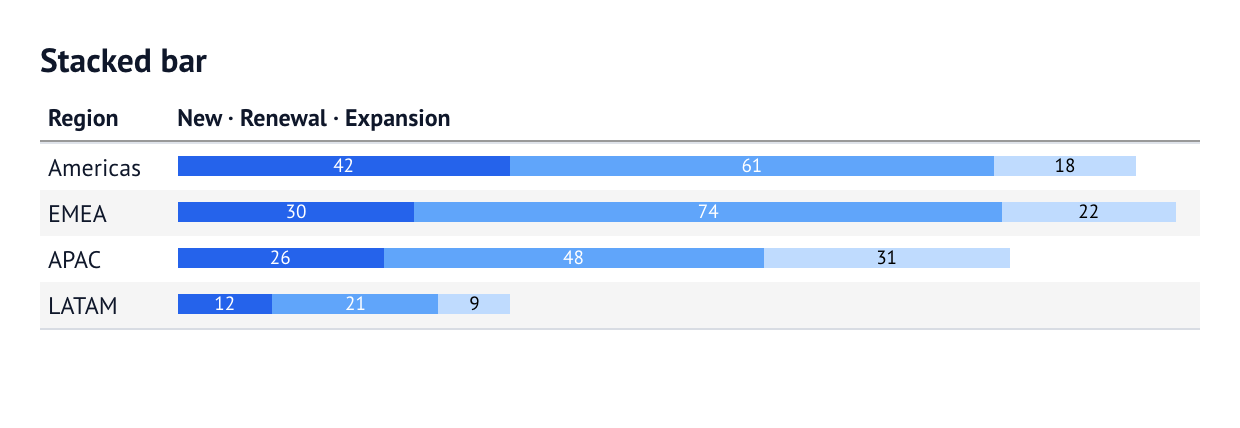
Stacked bar
columns=[
    col.text("region"),
    col.stacked_bar("new", "renewal", "expansion",
                    colors=["#2563eb", "#60a5fa", "#bfdbfe"],
                    labels=True, format="num0", size=0.6,
                    title="New · Renewal · Expansion"),
]
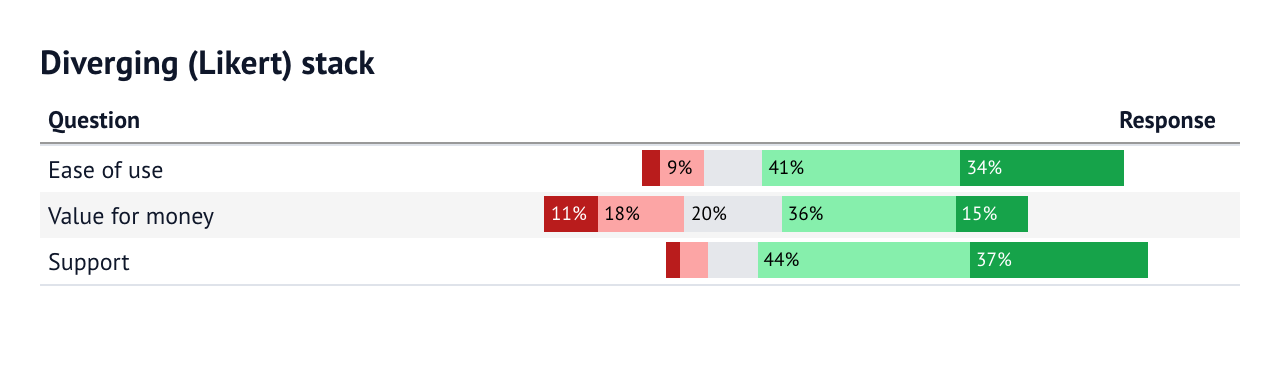
Diverging Likert stack
columns=[
    col.text("question"),
    col.stacked_bar("sd", "d", "n", "a", "sa",
                    colors=["#b91c1c", "#fca5a5", "#e5e7eb", "#86efac", "#16a34a"],
                    labels="percent", label_align="begin",
                    diverge_at="n", neutral="split", normalize="percent",
                    size=1, title="Response"),
]
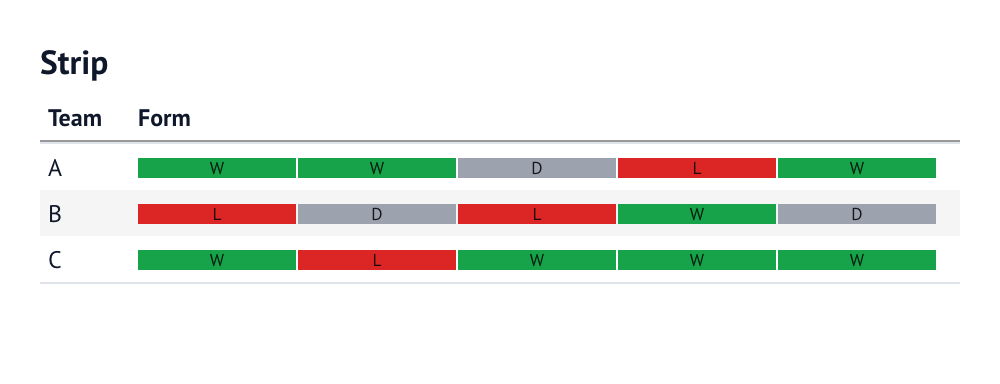
Strip
columns=[
    col.text("team"),
    col.strip("form", colors={"W": "#16a34a", "D": "#9ca3af", "L": "#dc2626"},
              labels=True).title("Form"),
]
Axis, reference line and band
columns=[
    col.text("team"),
    col.bar("score", format="num0", label=label.auto_position("outside end"),
            title="Score")
       .scale(domain=(0, 100), axis=True, axis_position="bottom", gridlines=True)
       .reference_band(60, 80, color="#fef3c7")
       .reference_line(70, color="#dc2626"),
]
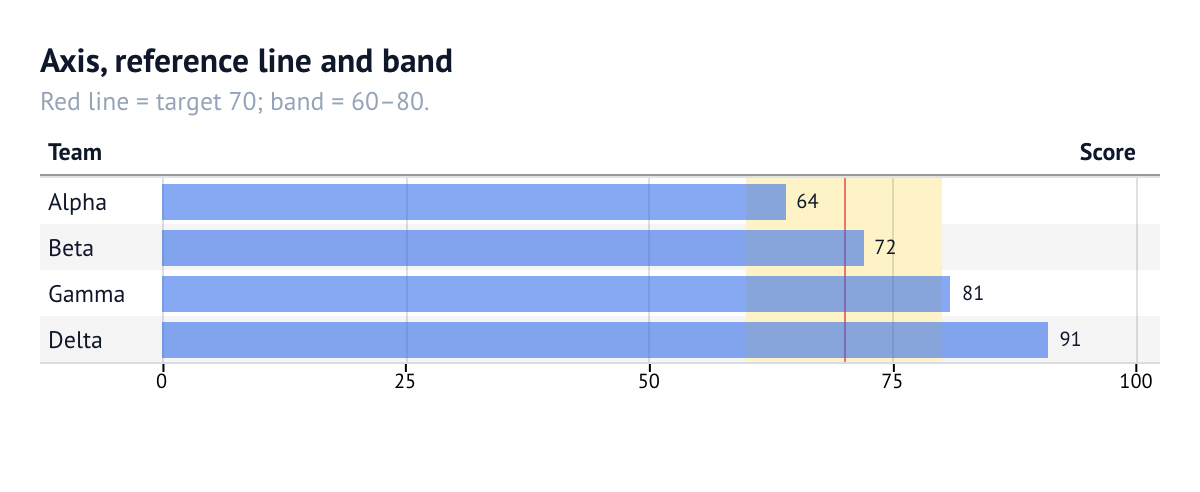
Labels and shared domains
from evidential import col, domain, label

annotation = label.fmt("usd0").bold().auto_position("inside end")

payments = domain.numeric("payments").include_zero().palette("Blues")

columns=[
    col.bar("card", label=annotation).domain(payments),
    col.number("cash").color().domain("payments"),
]
A label can show the mark's value, another field (label="@candidate"), or fixed
text. A named domain pools values across columns so bars, heatmaps and
sparklines share one scale and palette. See
notebooks/47_shared_domains.py.
6. Build header structures
columns=[
    col.text("country"),
    col.subcolumns("Latest", [
        col.number("gdp", fmt="num1", align="right").neg(),
        col.auto("quarter").align("left").font_color("#94a3b8"),
    ]),
    col.group("Forecast", [
        col.number("next_year", fmt="num1", title="Next year"),
        col.number("long_run", fmt="num1", title="Long run"),
    ]),
]
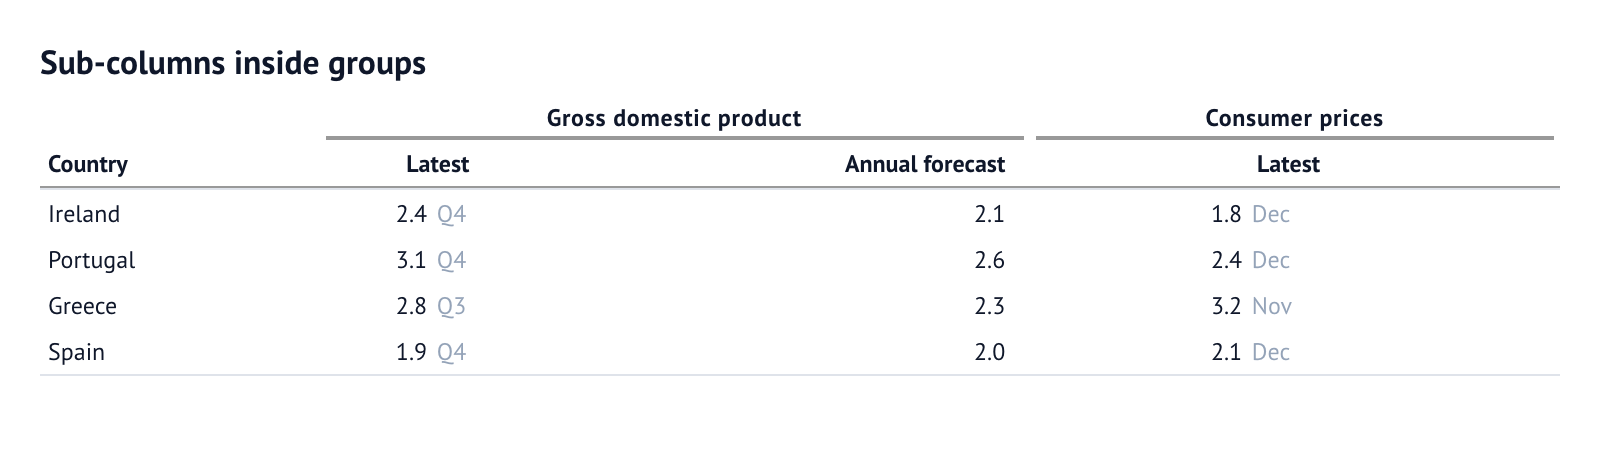
col.subcolumns(label, [...]) gives its members one shared leaf header.
col.group(label, [...]) adds a spanner over a run of columns. Both nest.
A column named "GDP Measure.GDP nominal" groups under GDP Measure
automatically; column_groups={...} is the equivalent mapping form.
The stub setting marks row-label columns, and stub_head labels the stub:
settings(stub="country", stub_head="Country")
7. Derive values and add display rules
Merged columns build one cell from several source columns:
from evidential import col, cols_merge_n_pct, cols_merge_range, cols_merge_uncert

columns=[
    col.text("site"),
    col.merge("range", cols_merge_range("low", "high", fmt="num0", title="Range")),
    col.merge("measurement", cols_merge_uncert("value", "uncert", fmt="num1")),
    col.merge("share", cols_merge_n_pct("n", "pct", title="Share")),
]
Display rules transform values at render time. Rules run in order; the last match wins.
from evidential import cells_body, tab_format, tab_style, text_transform

EvidentialTable(
    tips,
    columns=[col.text("city"), col.currency("revenue"), col.percent("tip_rate")],
    rules=[
        text_transform(cells_body("city"), str.upper),
        tab_style(cells_body("revenue"), color="#b45309"),
        tab_format(cells_body("revenue"), "usd0"),
    ],
)
Substitutions are also rules: sub_missing, sub_zero, sub_small_vals,
sub_large_vals and sub_values. Location selectors accept column names and
either 0-based row indices or a Python predicate.
Presentation parts
A table also has a frame, notes and optional dividers:
section_row("Label")/spacer_row()create display-only rows inrows.col.text("product").footnote("note")marks cells;footnotes=[...]adds static notes, andfootnote_marks="numbers"|"letters"|"symbols"chooses the mark scheme.caption=...adds source notes;stub/stub_headdefine row labels.column_stats=Trueadds min/max/avg/null under each header.null_text,.blank_below,.blank_aboveand.blank(...)control missing values.
8. Group, pivot and compare
The aggregate helpers accept the same col.* builders, run their aggregation
in DuckDB, and return a normal EvidentialTable.
from evidential import col, grouped_table, settings

grouped_table(
    con,
    "SELECT category, payment, sales FROM orders",
    dimensions=["category", "payment"],
    measures=["sum(sales) AS sales", "count(*) AS orders"],
    dimension_config={"category": col.text("category")},
    measure_config={
        "sales": col.bar("sales", format="usd0", label=True),
        "orders": col.integer("orders"),
    },
    settings=settings(title="Sales by category and payment", page_size=12),
)
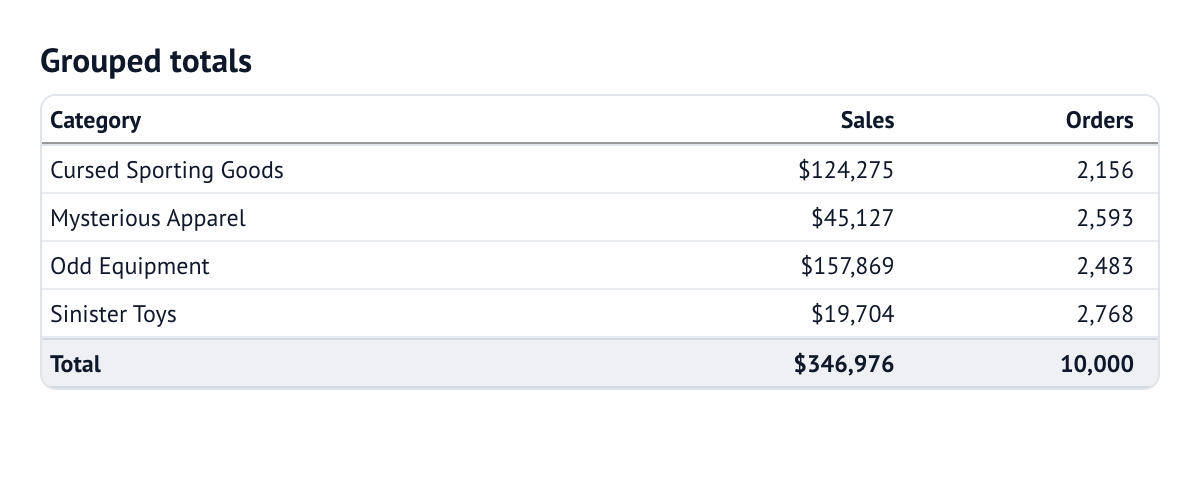
Aggregations for subtotals/totals
aggregations={"sales": "mean"} recomputes subtotals from detail values with a
built-in name or a Python callable. Use weight_columns={"sales": "weight"}
for weighted means.
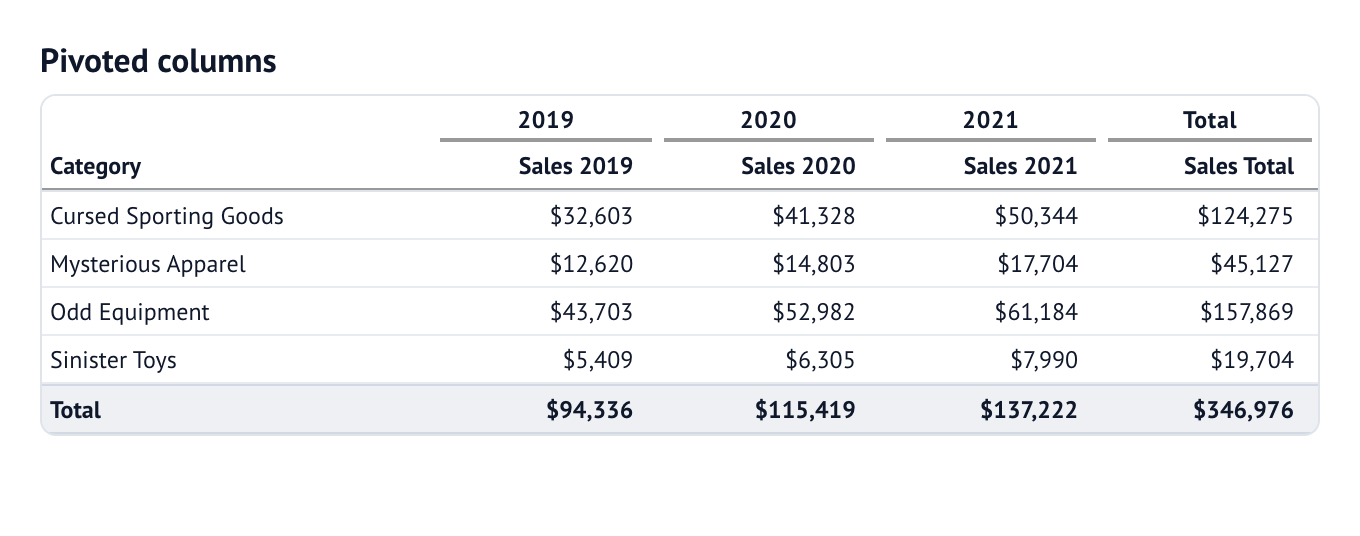
Pivot, compare and query
from evidential import comparison_table, pivot_table, query_table

# One column per pivot value, grouped under shared headers.
pivot_table(
    con,
    "SELECT category, year, sales FROM orders",
    dimensions=["category"],
    pivots=["year"],
    measures=["sum(sales) AS sales"],
    measure_config={"sales": col.currency("sales", decimals=0)},
)

# Adds <measure>_prior, <measure>_delta and <measure>_pct columns.
comparison_table(
    con,
    "SELECT region, order_date, sales FROM orders",
    dimensions=["region"],
    measures=["sum(sales) AS sales"],
    date_column="order_date",
    compare_vs="prior year",
)

# Ad-hoc SQL with Evidence-style where / order / limit / date_range.
query_table(
    con,
    "SELECT * FROM orders",
    where="sales > 0",
    order="sales DESC",
    limit=100,
    date_range="last 30 days",
    date_column="order_date",
)
For rows already in Python, grouped_records(rows, group_by=..., measures=...)
does the same grouping without a database.
Display-only headings and summaries
rows adds headings and summaries without making them source records.
from evidential import EvidentialTable, col, rows

layout = (
    rows.group_by("region")
    .section(values={"category": rows.count(suffix=" products"), "sales": "sum"})
    .summary("Region total", values={"sales": "sum"})
    .grand_summary("All regions", values={"sales": "sum"})
)

EvidentialTable(
    products,
    row_layout=layout,
    columns=[col.text("product"), col.text("category"), col.bar("sales", format="usd2")],
    page_size=3,
    section_indent=1,
)
Search recalculates named aggregations; a callable keeps its source scope until
the next set_data. table.rows contains details only, while
table.display_rows is an inspection snapshot that includes synthetic rows.
rows.of(products).group_by("region").summary(...).build() returns a view that
can be passed directly to EvidentialTable.
9. Live tables and row selection
LiveEvidentialTable re-runs a parameterised query without recreating the
widget, so sort, search and page state survive.
from evidential import LiveEvidentialTable, col

# 1. controls
min_fare = mo.ui.slider(0, 80, value=10, label="Minimum fare")
min_fare

# 2. persistent widget: no control references in this cell
live = LiveEvidentialTable(
    con,
    "SELECT * FROM trips WHERE fare_amount >= {min_fare}",
    auto_run=False,
    columns=[col.number("fare_amount", fmt="usd2"), col.number("trip_distance", fmt="num1")],
)
live

# 3. reactive cell: re-runs whenever the slider changes
_ = live.set_controls(min_fare=min_fare)
Values are bound as SQL parameters, never spliced into the SQL text. Outside a
reactive host, bind_controls=True makes the widget re-run itself.
query_values(con, sql) returns one column as a list for populating selectors.
The cell that creates the widget must not reference a control. Referencing one registers a Marimo dependency and recreates the widget on every change.
Set select="country_code" to make rows clickable. The clicked value crosses to
Python through the widget's selected trait:
countries = mo.ui.anywidget(
    EvidentialTable(
        rows,
        columns=[col.text("country"), col.integer("population")],
        select="country_code",
        empty_message="Click a country",
    )
)
countries
# another cell
selected = countries.widget.selected
detail.widget.set_data(con.sql(detail_sql, params={"code": selected or ""}))
set_data keeps the widget and its layout in place; update_options and
set_column change presentation without rebuilding it.
10. Marimo Studio views
A marimo Studio view projects named cells from a notebook, so one table can back a dashboard, report or slide deck.
@app.cell
def revenue_table(EvidentialTable, col, filtered):
    EvidentialTable(filtered, columns=[col.bar("revenue", format="usd0", label=True)])
<marimo-cell name="revenue_table"></marimo-cell>
<strong mo-value="kpis.revenue"></strong>
uv run --with "marimo-studio[deno]" marimo-studio view create dashboard --target analysis.py
make studio-serve
make studio-validate
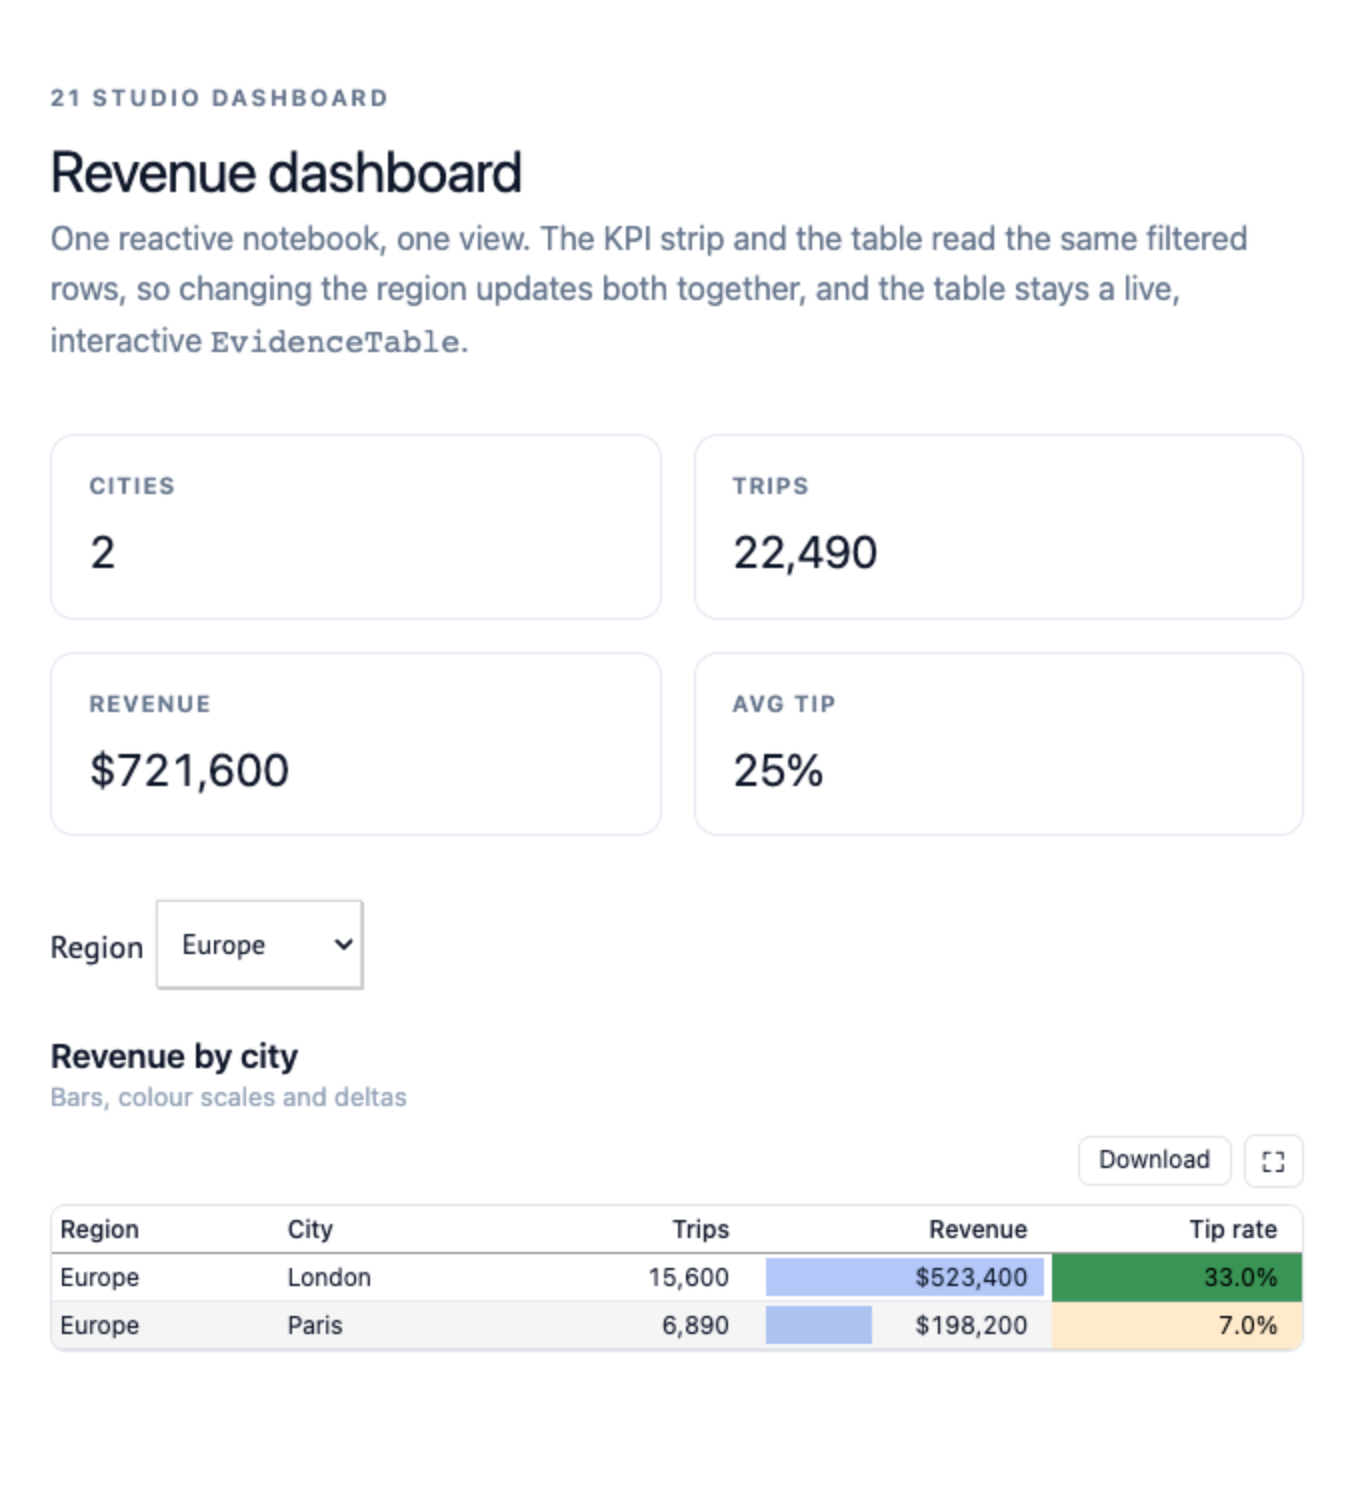
The interactive table needs Studio's Server runtime. See
docs/marimo-studio.md and
notebooks/21_studio_dashboard.py.
11. Amazon S3 Tables
from evidential import duck

con = duck.connect_s3_tables(table_bucket_arn="arn:aws:s3tables:...:bucket/...")
con.sql("SELECT * FROM s3tables.taxi.yellow_trips LIMIT 100")
This attaches an Iceberg REST catalog using ambient AWS credentials. See
notebooks/02_s3_tables.py.
Compatibility
The fluent API is the preferred surface, but the older spellings still work:
column_config={"revenue": {"fmt": "usd0"}}is merged onto inferred columns.- Raw
viz="bar"dictionaries are accepted. column_groups={...}remains the mapping form ofcol.group(...).fmt=andformat=are equivalent; the same applies to the other alias pairs listed in the API reference.
The scalar col.number(...).bar() shortcut was removed. Use the mark factory:
col.bar("sales", format="usd0", label=True)
Reference
- API reference — the full factory, chain, mark, settings and module reference, with screenshots.
- Design & DX — why the table works the way it does.
- Technical architecture — wire format, render pipeline and diagrams.
- marimo Studio views — projections and troubleshooting.
- ADRs — the decisions behind the API.
notebooks/— runnable examples of every feature.
The public surface is re-exported from evidential:
| Import | Purpose |
|---|---|
EvidentialTable, LiveEvidentialTable |
tables and live queries |
col, label, domain, rows |
column, annotation, scale and row-layout builders |
settings, TableOptions, ColumnOptions |
typed table and column configuration |
grouped_table, grouped_records, pivot_table, comparison_table, query_table |
aggregate and query helpers |
cells_body, tab_style, tab_format, text_transform, sub_*, cols_merge_* |
display rules and merged values |
duck, query_values, date_range_sql |
DuckDB and query utilities |
Development
make install            # Python and JavaScript dependencies
make install-hooks      # pre-commit hooks
make lint               # ruff · bandit · pip-audit · pyrefly · shellcheck · checkmake · rumdl
make format             # auto-fix formatting and lint issues
make test               # Python tests (with coverage) and JavaScript tests
make test-browser       # Playwright functional tests
make check-notebooks    # marimo check on every notebook
make check-artifact     # build a wheel/sdist and verify their contents
make validate           # lint + notebook checks + tests + bundle check + build
make api-screenshots    # capture docs images from the screenshot notebooks
make frontend-build     # rebuild static/table.js and static/table.css
The gates are mirrored in .pre-commit-config.yaml
(on commit) and scripts/lint.sh (local validation).
tests/release/ checks the repository workflow itself, including that the wheel
contains the committed renderer assets.
Relationship to Evidence
This is a focused reimplementation for the Python/Marimo ecosystem. Formatting
presets, colour-scale maths and table presentation are ported from Evidence's
formatValue, table-viz, table-styles and color-scale-utils modules.
Evidence is MIT licensed; the same license applies here.
License
MIT.
1 maintainer

Metadata
1 maintainer
Release files for evidential 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| evidential-0.1.0.tar.gz | 163.6 kB | Without provenance | Details for evidential-0.1.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| evidential-0.1.0-py3-none-any.whl | Python 3 | none | any | Details for evidential-0.1.0-py3-none-any.whl |
Total release size: 328.7 kB
Release files / evidential-0.1.0.tar.gz
| Download URL | evidential-0.1.0.tar.gz |
|---|---|
| Size | 163.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
89ad063e1caa8db567f16c7458fa344b58d51d5ebcf670cddbfc052e56e5a657
|
|
BLAKE2b-256 checksum How to use checksums |
12bfd8bf84ce421ec5999cd3c92ef197df08113ab4c60e8a2bfb7ae217252440
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.13.4 {"installer":{"name":"uv","version":"0.13.4","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"macOS","version":null,"id":null,"libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / evidential-0.1.0-py3-none-any.whl
| Download URL | evidential-0.1.0-py3-none-any.whl |
|---|---|
| Size | 165.1 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
6f6efcd2d0af9d6c8dea2364bb96daf348d4fcc0c7815d758ca93107cf5ce26b
|
|
BLAKE2b-256 checksum How to use checksums |
cc6143c859818bdc14b2f52d26781490e4ba1993f8ab7d802e03a1ece924203b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.13.4 {"installer":{"name":"uv","version":"0.13.4","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":{"name":"macOS","version":null,"id":null,"libc":null},"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Security for evidential 0.1.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














