
Fast Attention Residuals



Fast Attention Residuals (Fast-AttnRes) makes
Attention Residuals a single PyTorch
operation: pass ordered full-width residual sources and one learned query, get
one full-width residual back. The same attnres(values, query) call handles
standard and sliced low-rank AttnRes in Full and Block schedules, with packed
tensors or ordered source lists.
Start with the standard quickstart, choose a Full or Block schedule, and try sliced LR-AttnRes for a smaller routing query.
Why use Fast-AttnRes
- One PyTorch call: full-width output and ordinary first-order autograd, including gradients through routing keys and shared residual sources.
- One schedule primitive: Full and Block use the same operator; the caller controls source order, block sums, and learned queries.
- BF16 training: CUDA BF16 values and queries, FP32 internal reductions,
torch.compile, and CUDA Graph replay on H100 and B200.
Training performance
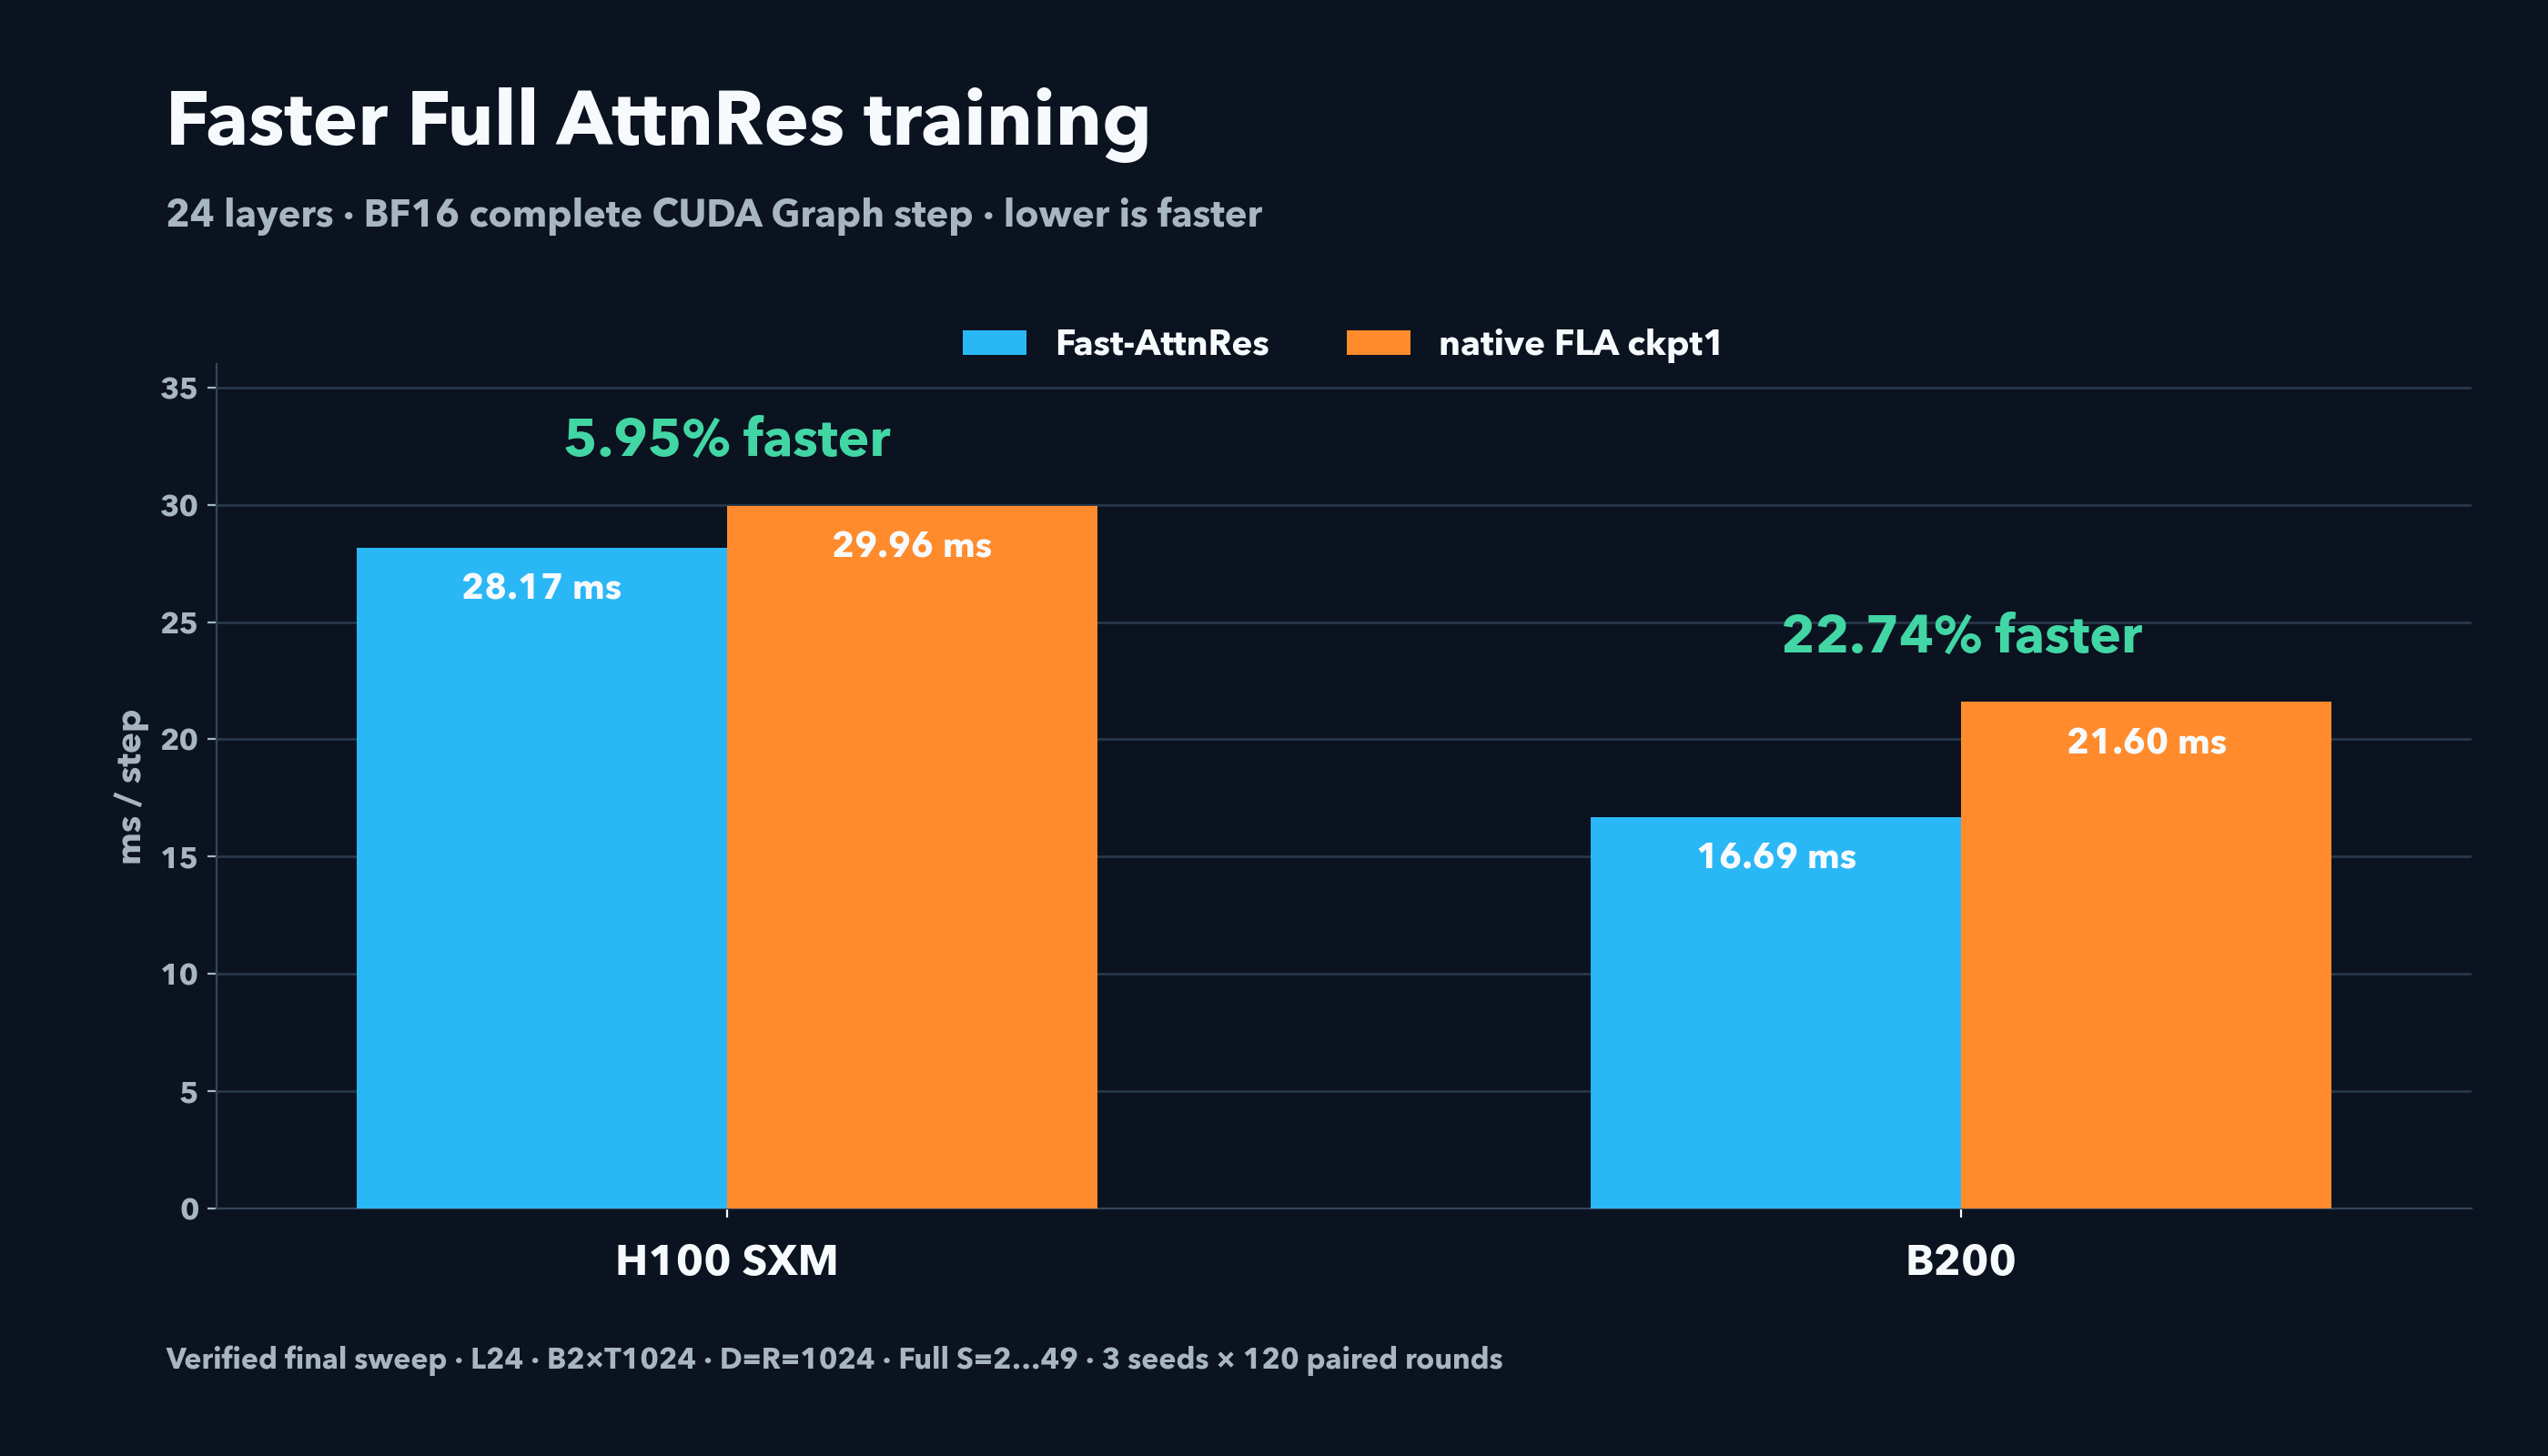
On the 24-layer Full workload, Fast-AttnRes reduces step latency by 5.95% on H100 SXM and 22.74% on B200 against native FLA Triton checkpoint 1 (median of three paired seed estimates).
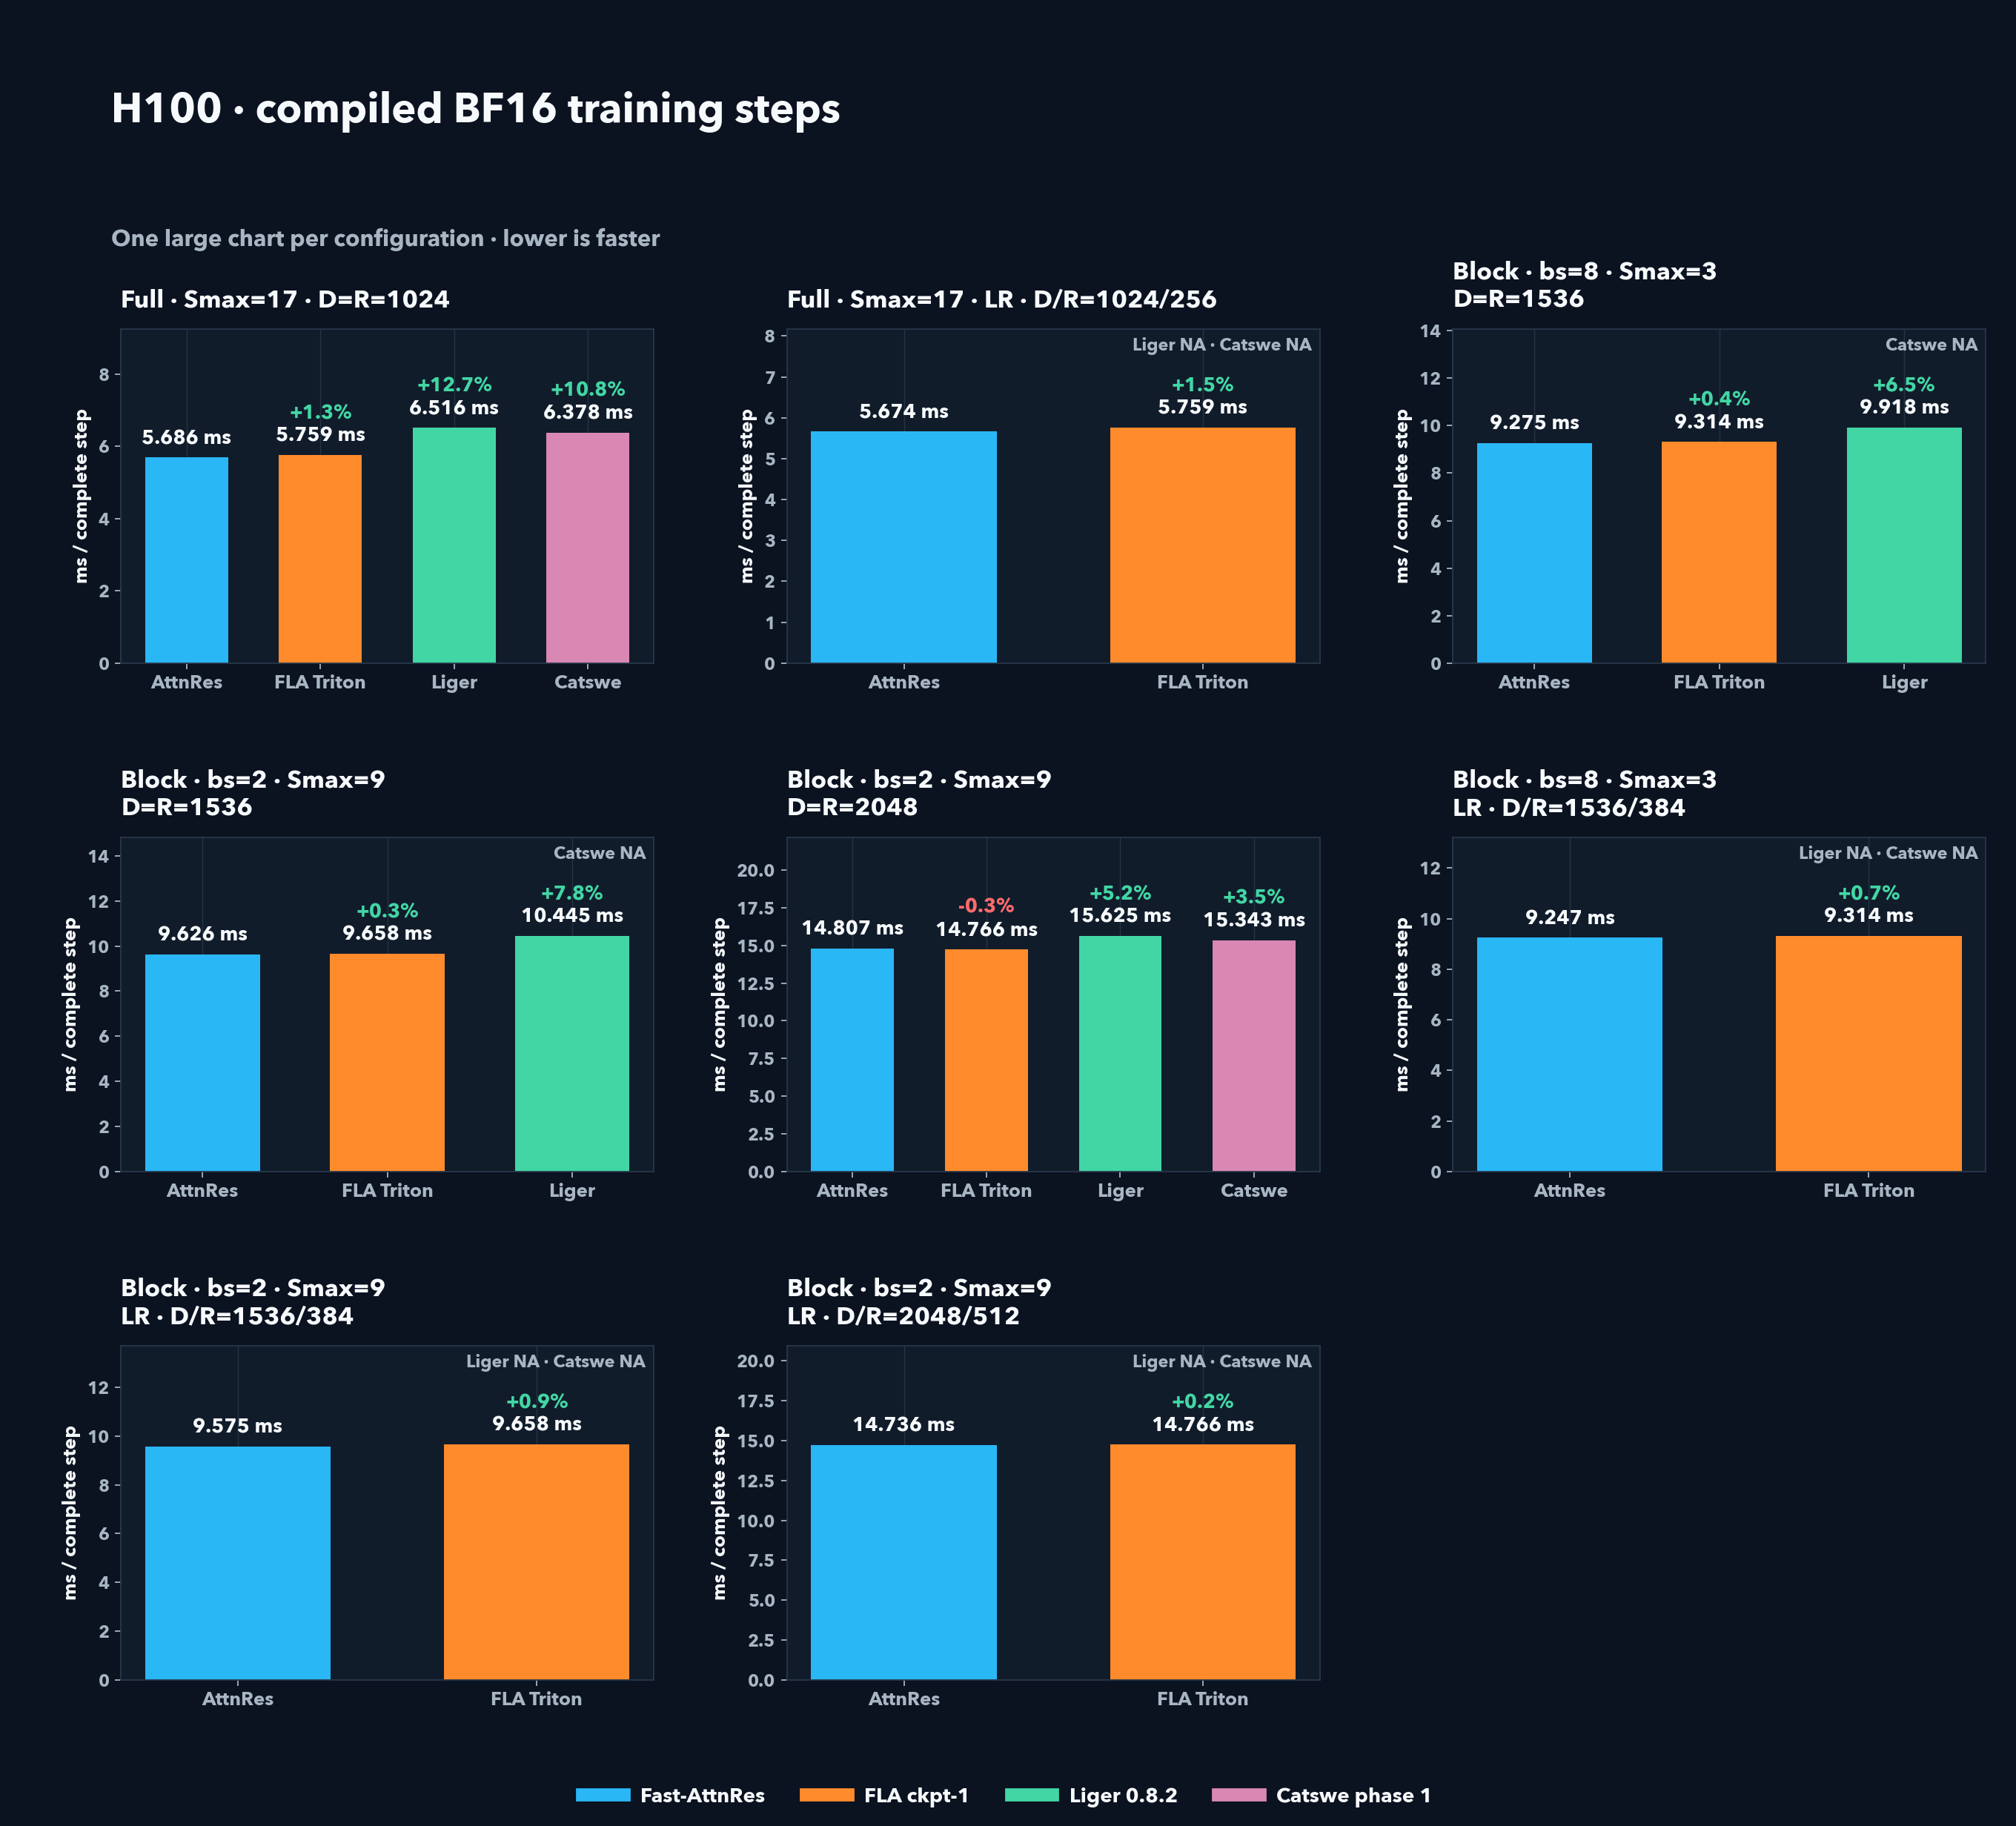
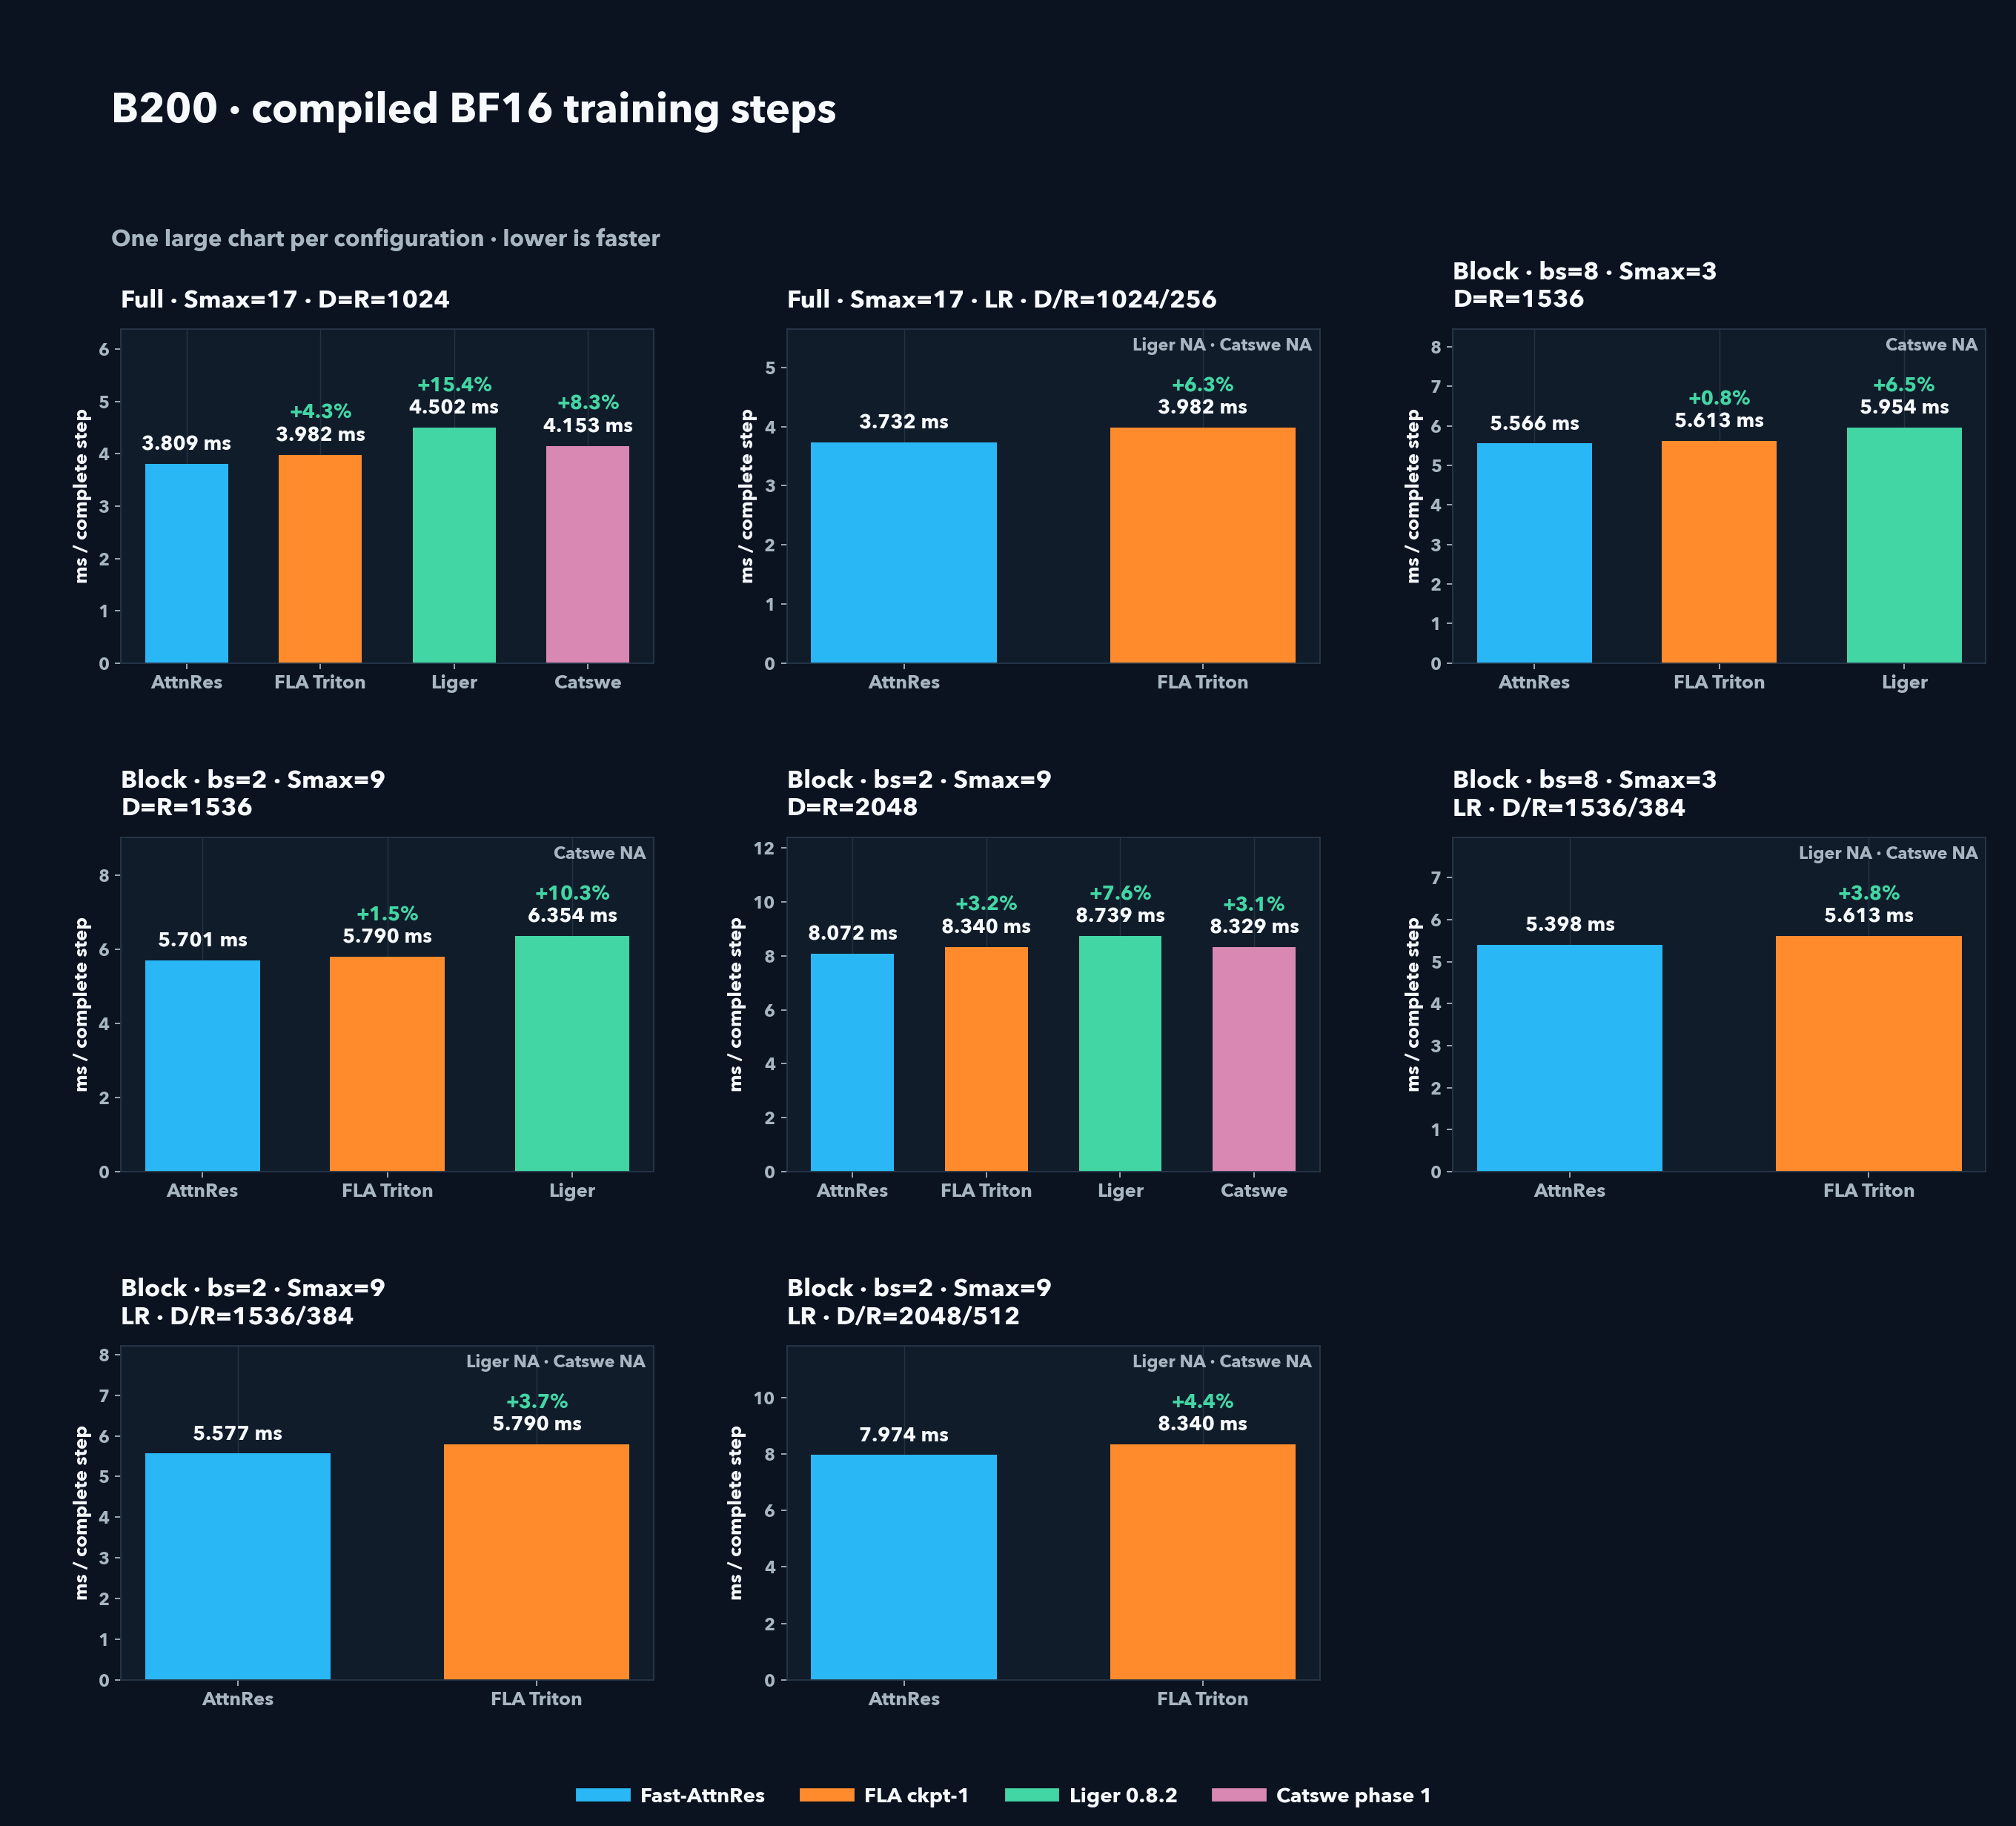
The figures measure complete BF16 CUDA Graph training steps on H100 SXM and B200, including forward, backward, and the optimizer update. Full and Block use the same per-read Fast-AttnRes backend.
The 24-layer headline uses three seeds with 120 paired rounds each. The 8-layer comparisons use one seed with 40 paired rounds per configuration. See the benchmark protocol and reproducible results for workloads, source versions, confidence intervals, and reproduction commands.
Compiled BF16 training steps
Comparators are native FLA Triton checkpoint 1, Liger 0.8.2, and Catswe phase 1. Unsupported and failed arms remain labelled. Quarter-rank comparisons against standard FLA compare different routing equations. The D2048 results retain disclosed normalization-rounding deviations. On H100, standard D2048 is 0.28% slower than FLA, within the declared 1% parity band.
Quarter-rank routing
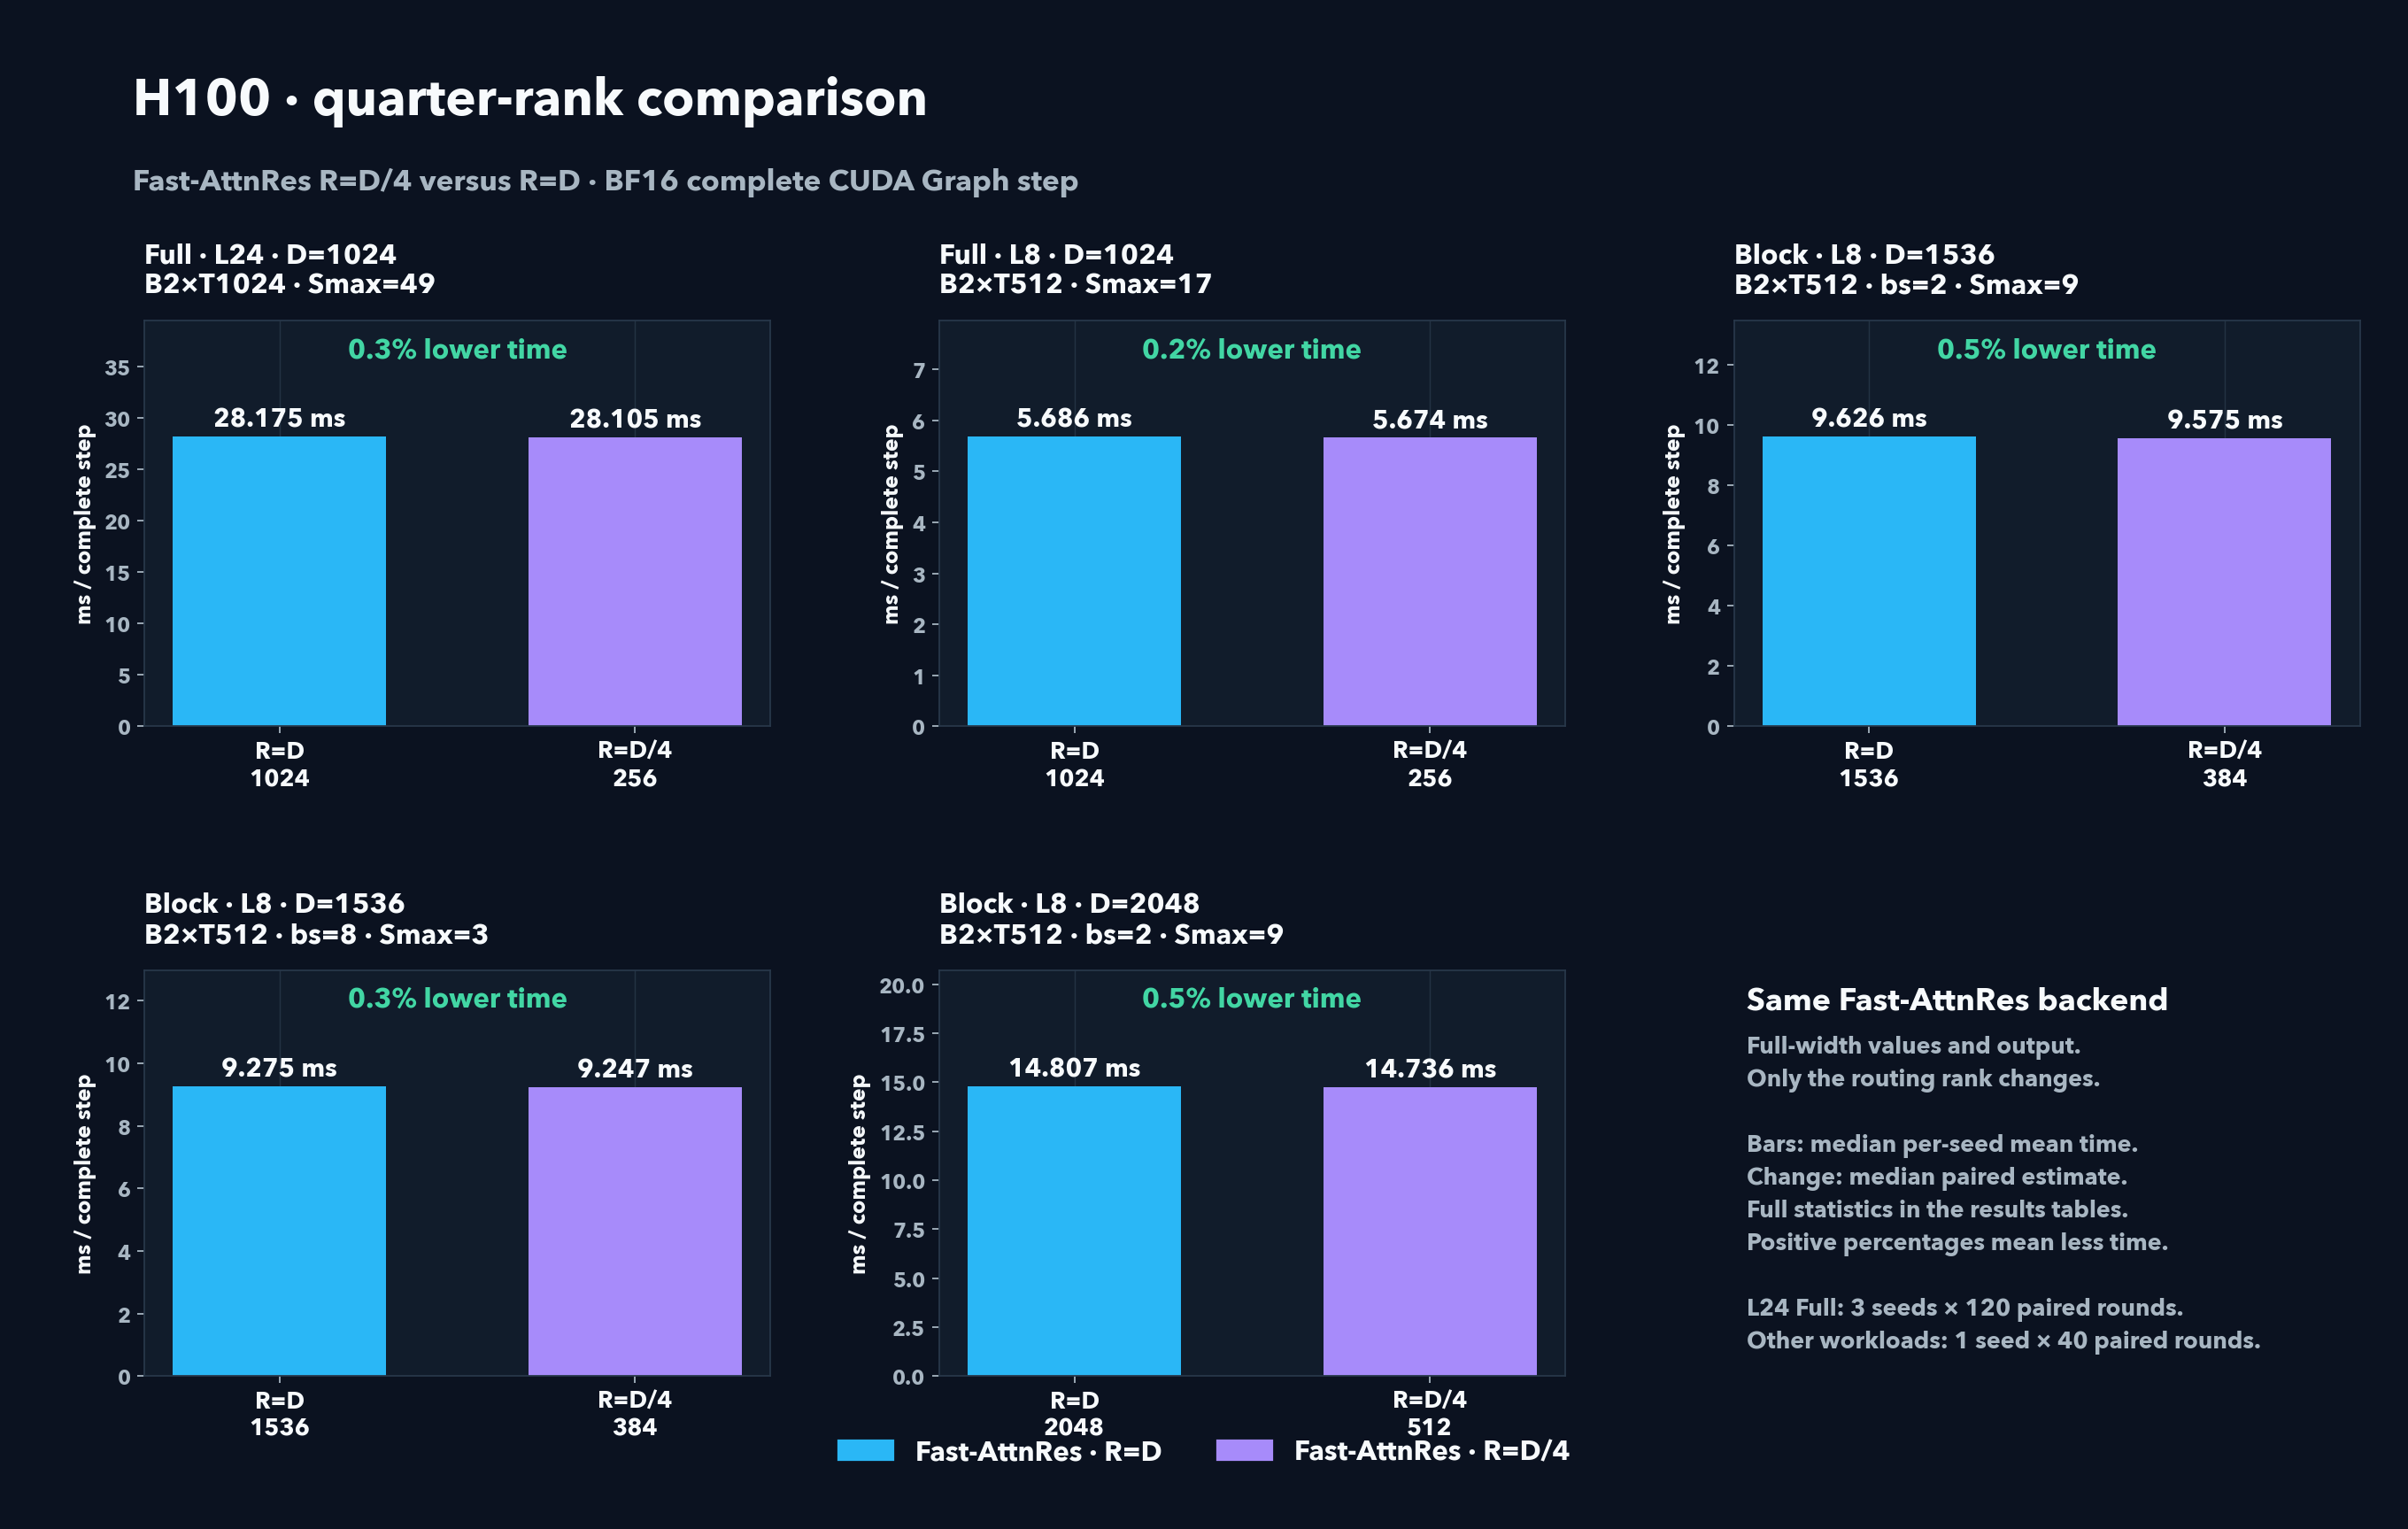
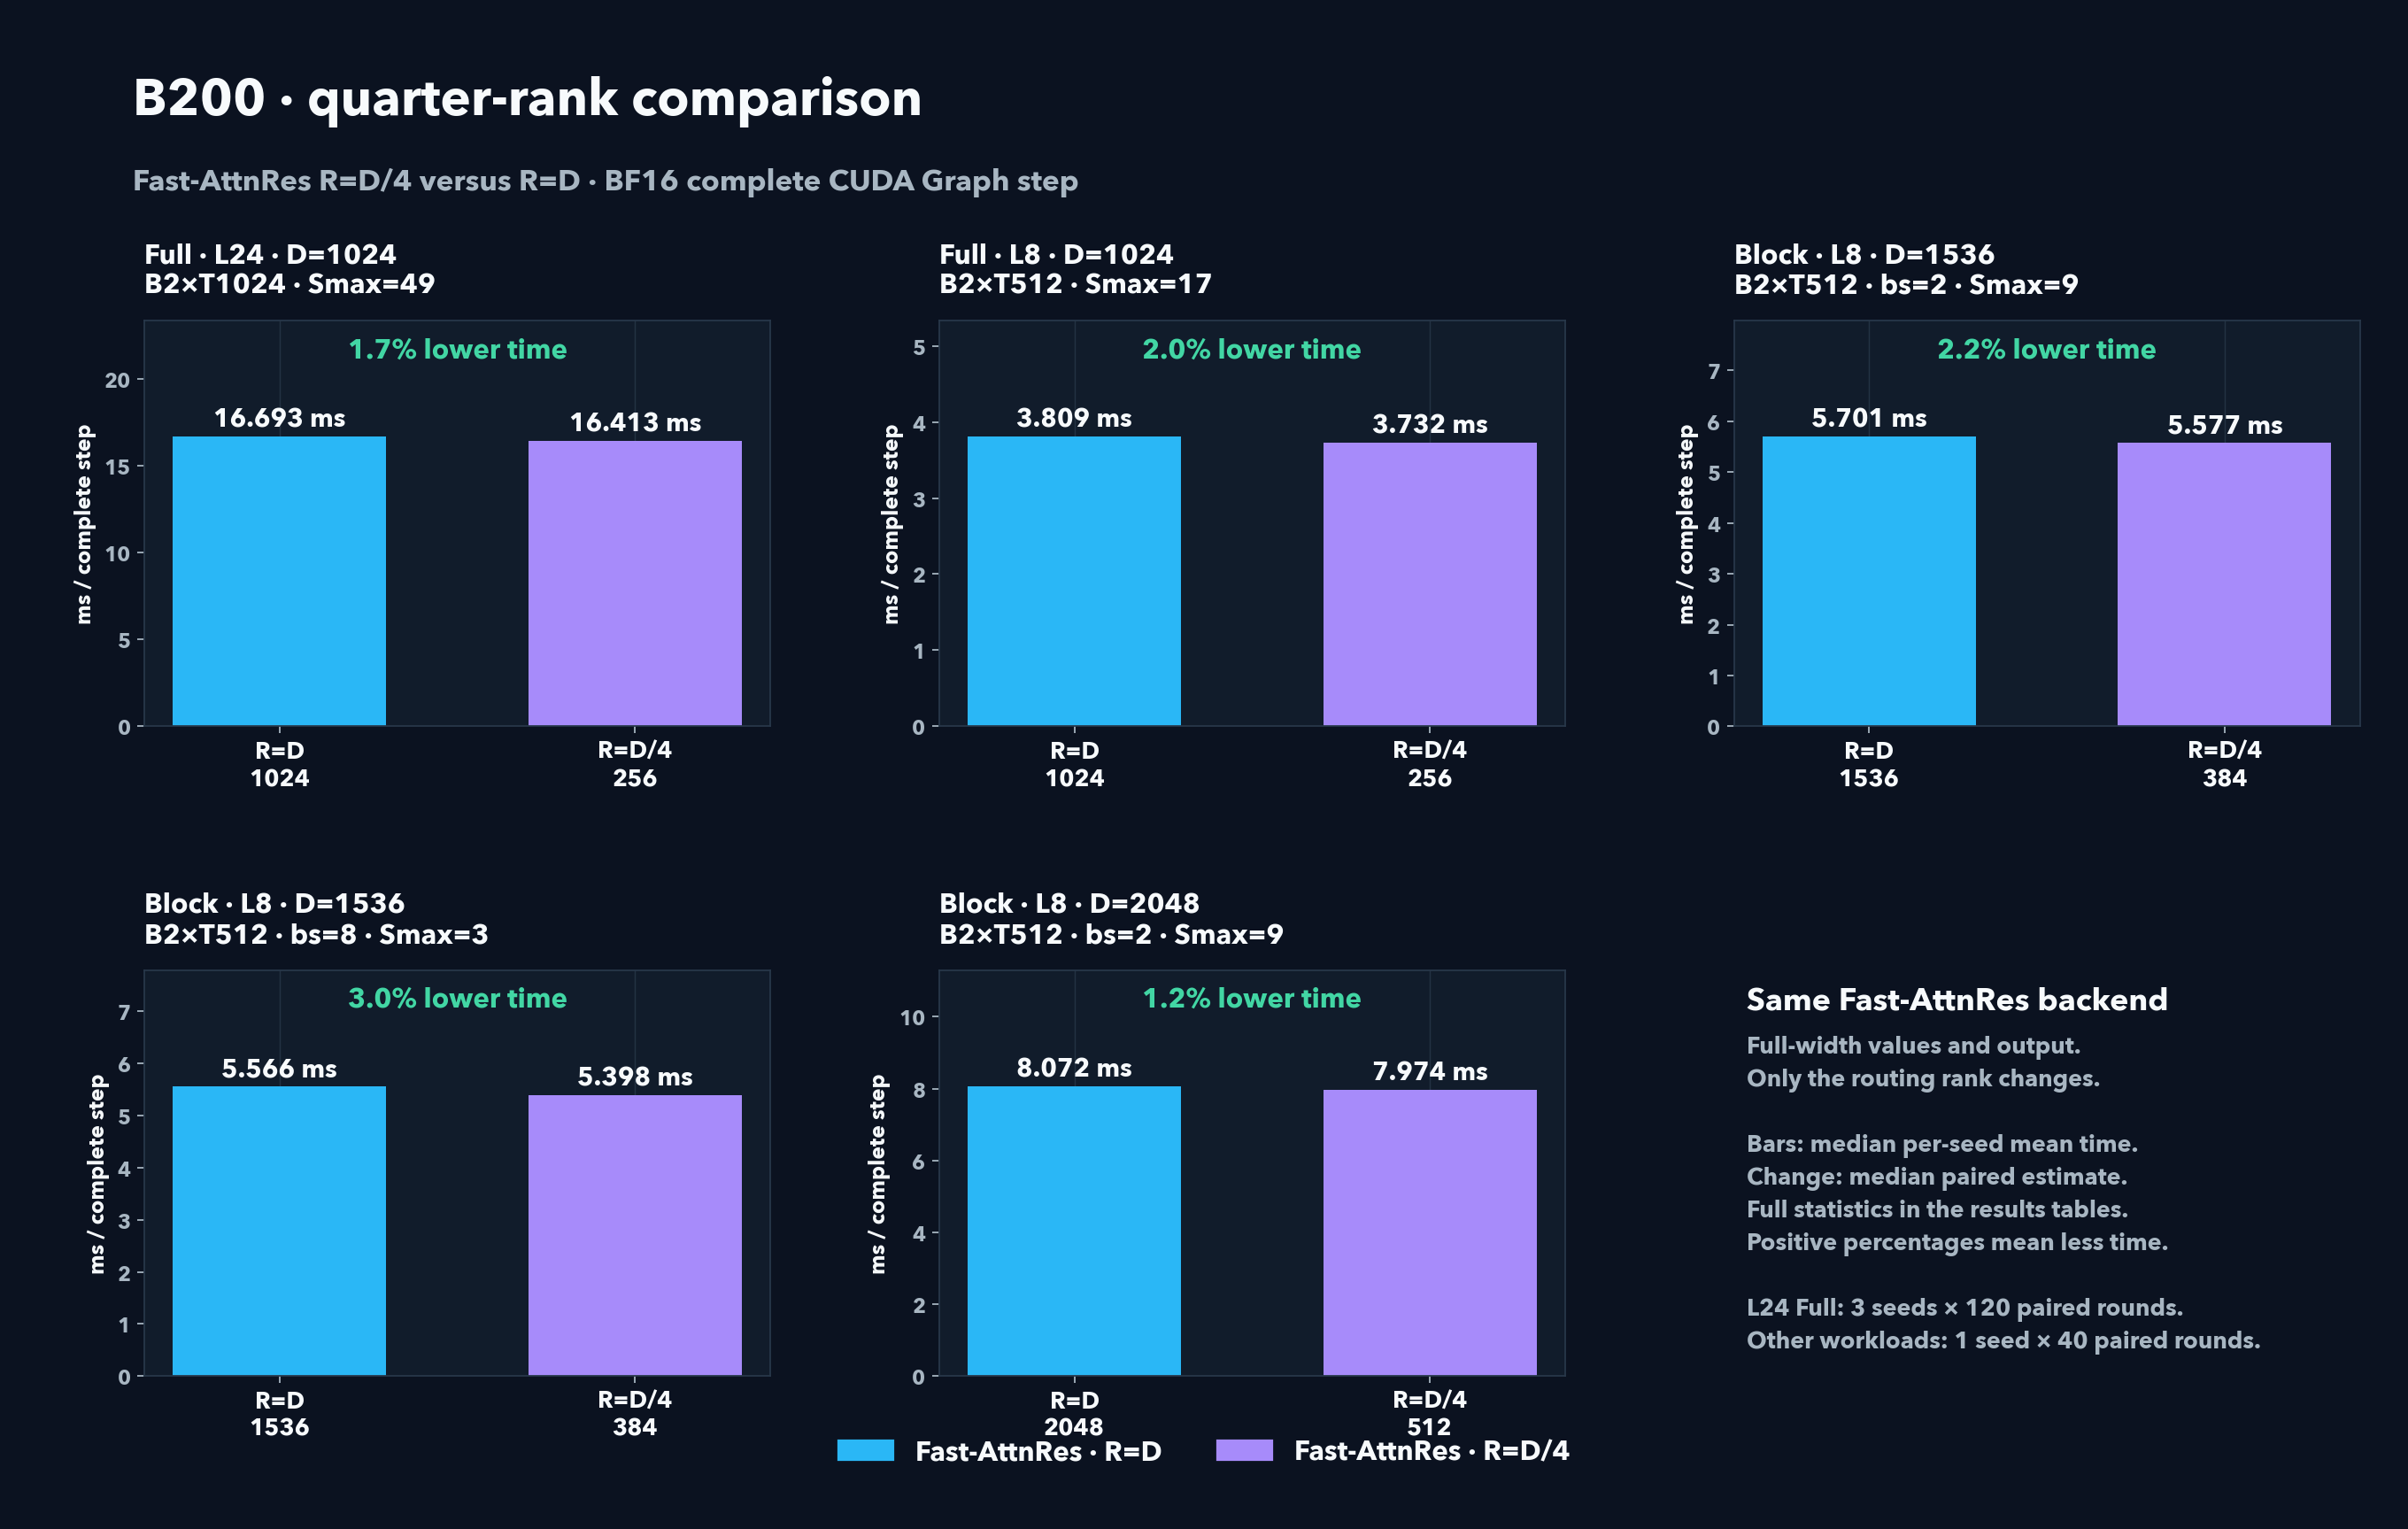
These figures compare our R=D/4 kernel with our R=D kernel on each workload.
Values and outputs retain width D; only the routing rank changes.
Quarter rank reduces step latency in all ten measured device/workload pairs.
Install
Install the release with the pinned CUDA runtime:
python -m pip install --index-url https://download.pytorch.org/whl/cu130 torch==2.13.0
python -m pip install "fast-attnres[cuda]==2.0.1"
For development, clone the repository and run python -m pip install -e ".[cuda]".
Version 2 requires CUDA BF16 tensors; the CPU/FP32 execution and exported reference from version 1 are no longer part of the public API.
The pinned runtime is Python 3.11, PyTorch 2.13.0 with CUDA 13.0, and Triton 3.7.1.
Quickstart: standard AttnRes
import torch
from attnres import attnres

values = torch.randn(8, 2, 1024, device="cuda", dtype=torch.bfloat16, requires_grad=True)
source_list = tuple(values.unbind(0))
query = torch.randn(1024, device="cuda", dtype=torch.bfloat16, requires_grad=True)
read = torch.compile(attnres, fullgraph=True, dynamic=False)
output = read(source_list, query)
output.square().mean().backward()
The public signature is attnres(values, query, *, eps=2**-23, scale=1.0).
values is either packed [S, ..., D] or an ordered list/tuple of [ ..., D ]
tensors. The query is [R], with 1 <= R <= D; the output retains width D.
Values, query, output, and first-order operator gradients are CUDA BF16. Internal
FP32 accumulators may be used for normalization, logits, softmax, and reductions.
Equation
For source value v_s, take its final R coordinates as the implicit key:
t_s       = v_s[..., D-R:D]
r_s       = sqrt(mean(t_s ** 2) + eps)
k_s       = t_s / r_s
score_s   = scale * dot(k_s, query)
p_s       = softmax(score, axis=source)_s
output    = sum_s p_s * v_s
Normalization and softmax run independently at each carried batch or token
position. The output is not normalized, source-count weighted, or source averaged.
See docs/equation.md for the complete contract.
Full and Block schedules
Full supplies the embedding and every preceding writer output. Block supplies the embedding, completed block sums, and an optional current partial sum. The caller owns block boundaries and sums a partial block before the read; it is passed as one ordinary source and is not averaged.
full_output = attnres((embedding, *writers), query)

completed = (embedding, first_block, second_block)
block_sources = completed if partial is None else completed + (partial,)
block_output = attnres(block_sources, query)
Every read evaluates its routing weights and mixture from the supplied sources.
Both schedules use the same query, eps, scale, and operator contract.
Sliced LR-AttnRes
Sliced LR-AttnRes keeps full-width values and output while using a shorter implicit key and query:
rank = 64
query = torch.randn(rank, device="cuda", dtype=torch.bfloat16)
output = attnres(source_list, query)  # [..., D], BF16
For a trainable static query, use LearnedQuery(rank):
from attnres import LearnedQuery
learned_query = LearnedQuery(rank).to(device="cuda", dtype=torch.bfloat16)
output = attnres(source_list, learned_query())
Standard AttnRes is the R == D case; sliced routing uses R < D and the final
R value coordinates. Projected keys, routing priors, and architectural changes
are outside this package contract.
Optimization targets common ranks: powers of two from 16 upward, plus widths such as 384 and 640. Other ranks retain the same mathematical support.
Validation scope
Correctness checks compare BF16 outputs and first-order gradients with an
independent BF16 PyTorch reference with FP32 internal accumulation at
rtol=0.05 and atol=0.05. Coverage
includes packed/list sources, repeated reads, partial Blocks, changed inputs,
non-contiguous layouts, shared sources, and compiled replay. See the
validation protocol.
Timing reports identify the exact source, device, runtime, workload, and measurement boundary. Failed, incomplete, and inconclusive comparisons remain visible in the results.
License
Fast-AttnRes is released under the MIT License. FLA-derived source
list attribution remains in NOTICE.
1 maintainer

Metadata
1 maintainer
Release files for fast-attnres 2.0.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| fast_attnres-2.0.1.tar.gz | 1.0 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| fast_attnres-2.0.1-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.0 MB
Release files / fast_attnres-2.0.1.tar.gz
| Download URL | fast_attnres-2.0.1.tar.gz |
|---|---|
| Size | 1.0 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
1af71000a3551d638bde10c386ac3ab9035da74fc6417e770521261d4794e1c0
|
|
BLAKE2b-256 checksum How to use checksums |
baac13bbf09bf54e1b4d566268eb42324e6347e1608b95e9cfcd7a1be7b21e76
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 6, 2026.
Transparency logRelease files / fast_attnres-2.0.1-py3-none-any.whl
| Download URL | fast_attnres-2.0.1-py3-none-any.whl |
|---|---|
| Size | 31.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d413bf7f089465f403c98f3177e00e32faacb771150cb8981e4c90bb6460f9d1
|
|
BLAKE2b-256 checksum How to use checksums |
f808f752ad15fc241f0cb7bc0e18852399fca5c6d446b16f8d3a0c9cdb989284
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 6, 2026.
Transparency log













