
Flake8-pyspark-with-column


Getting started
pip install flake8-pyspark-with-column
flake8 --select PSRPK001,PSPRT002,PSPRK003,PSPRK004
Alternatively you can add the following tox.ini file to the root of your project:
[flake8]
select =
    PSPRK001,
    PSPRK002,
    PSPRK003,
    PSPRK004
About
A flake8 plugin that detects of usage withColumn in a loop or inside reduce. From the PySpark documentation about withColumn method:
This method introduces a projection internally. Therefore, calling it multiple times, for instance, via loops in order to add multiple columns can generate big plans which can cause performance issues and even StackOverflowException. To avoid this, use select() with multiple columns at once.
What happens under the hood?
When you run a PySpark application the following happens:
- Spark creates
Unresolved Logical Planthat is a result of parsing SQL - Spark do analysis of this plan to create an
Analyzed Logical Plan - Spark apply optimization rules to create an
Optimized Logical Plan
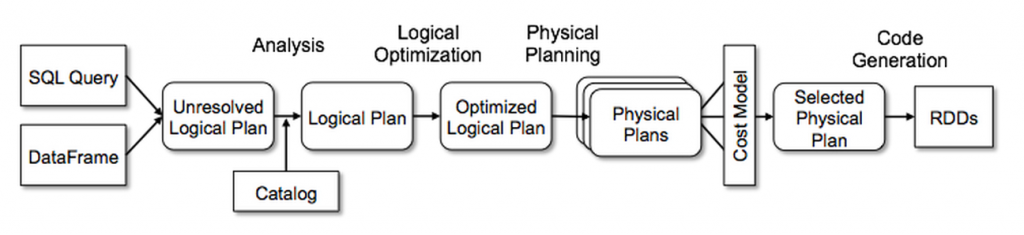
What is the problem with withColumn? It creates a single node in the unresolved plan. So, calling withColumn 500 times will create an unresolved plan with 500 nodes. During the analysis Spark should visit each node to check that column exists and has a right data type. After that Spark will start applying rules, but rules are applyed once per plan recursively, so concatenation of 500 calls to withColumn will require 500 applies of the corresponding rule. All of that may significantly increase the amount of time from Unresolved Logical Plan to Optimized Logical Plan:
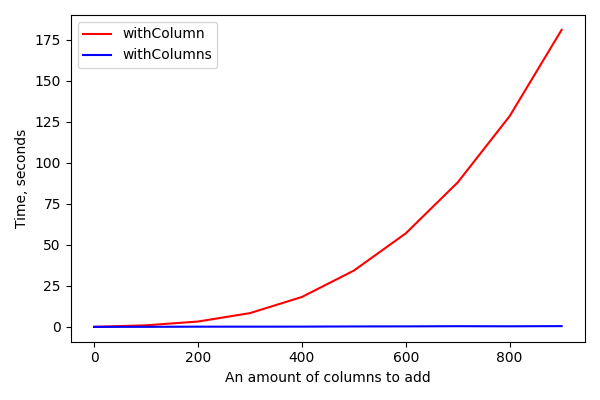
From the other side, both withColumns and select(*cols) create only one node in the plan doesn't matter how many columns we want to add.
Rules
This plugin contains the following rules:
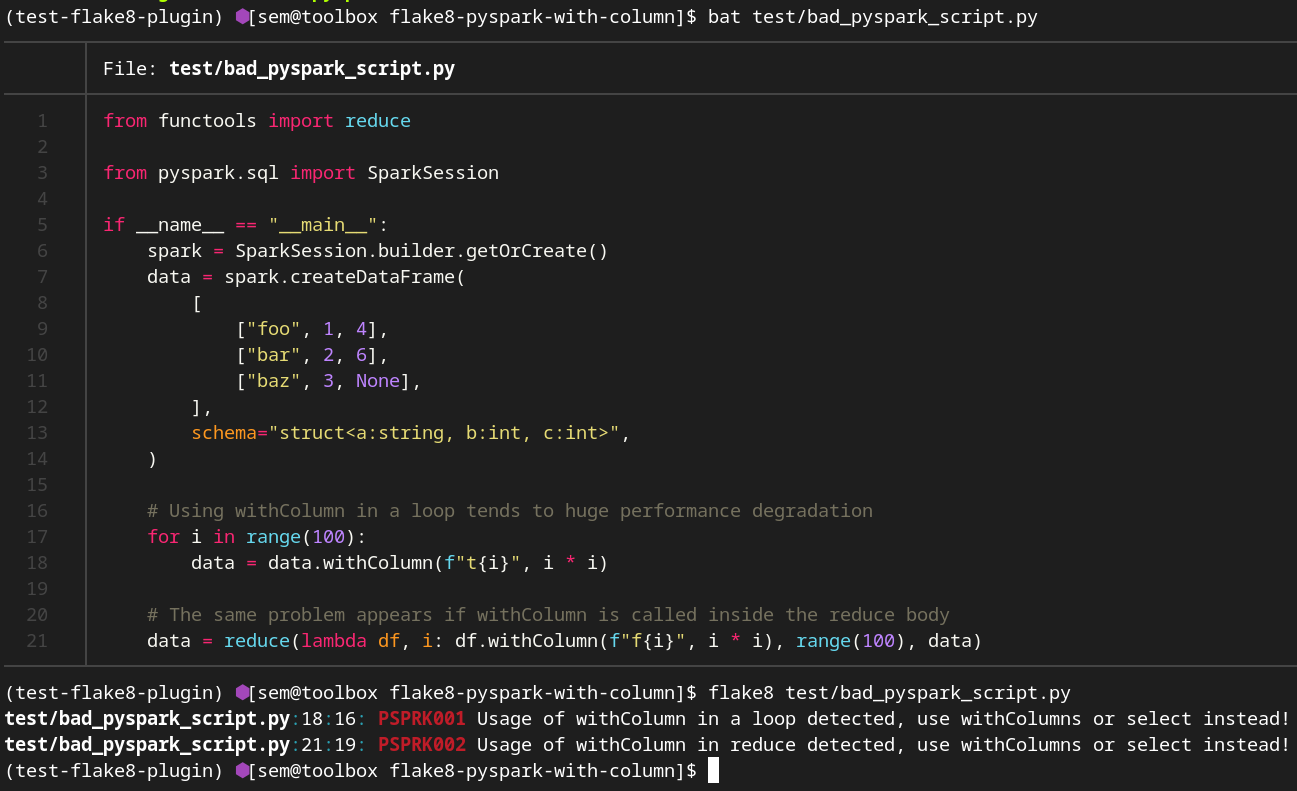
PSPRK001: Usage of withColumn in a loop detectedPSPRK002: Usage of withColumn inside reduce is detectedPSPRK003: Usage of withColumnRenamed in a loop detectedPSPRK004: Usage of withColumnRenamed inside reduce is detected
Examples
Let's imagine we want to apply an ML model to our data but our Model expects double values and our table contain decimal values. The goal is to cast all Decimal columns to Double.
Implementation with withColumn (bad example):
def cast_to_double(df: DataFrame) -> DataFrame:
  for field in df.schema.fields:
    if isinstance(field.dataType, DecimalType):
      df = df.withColumn(field.name, col(field.name).cast(DoubleType()))
  return df
Implementation without withColumn (good example):
def cast_to_double(df: DataFrame) -> DataFrame:
  cols_to_select = []
  for field in df.schema.fields:
    if isinstance(field.dataType, DecimalType):
      cols_to_select.append(col(field.name).cast(DoubleType()).alias(field.name))
    else:
      cols_to_select.append(col(field.name))
  return df.select(*cols_to_select)
Usage
flake8 %your-code-here%
1 maintainer

Metadata
1 maintainer
Release files for flake8-pyspark-with-column 0.0.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| flake8_pyspark_with_column-0.0.6.tar.gz | 8.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| flake8_pyspark_with_column-0.0.6-py2.py3-none-any.whl | Python 3, Python 2 | none | any | Details |
Total release size: 16.9 kB
Release files / flake8_pyspark_with_column-0.0.6.tar.gz
| Download URL | flake8_pyspark_with_column-0.0.6.tar.gz |
|---|---|
| Size | 8.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
68780e1af6488e340ce6e2b48bd43d625dccb4e31a9241421863c85a73f95798
|
|
BLAKE2b-256 checksum How to use checksums |
b1e2403a982e601ad41c547672220a818655a8c6e27d0cd7ebb3c13a13b391a9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.12.9
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 20, 2025.
Transparency logRelease files / flake8_pyspark_with_column-0.0.6-py2.py3-none-any.whl
| Download URL | flake8_pyspark_with_column-0.0.6-py2.py3-none-any.whl |
|---|---|
| Size | 8.2 kB |
| Tags | Python 2 Python 3 |
|
SHA-256 checksum How to use checksums |
2ae59b72609c421edb4f5027ce8edbce65cbcebcd3ee9ae746d2f979a007fa92
|
|
BLAKE2b-256 checksum How to use checksums |
8a12ab99dbd73ccfcae2b89fa0157b5cf21da192b4f2a84abb472ecc4e02f2ce
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.12.9
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 20, 2025.
Transparency log













