
This release is a pre-release and may not be stable for production use.
FlowBlueprint

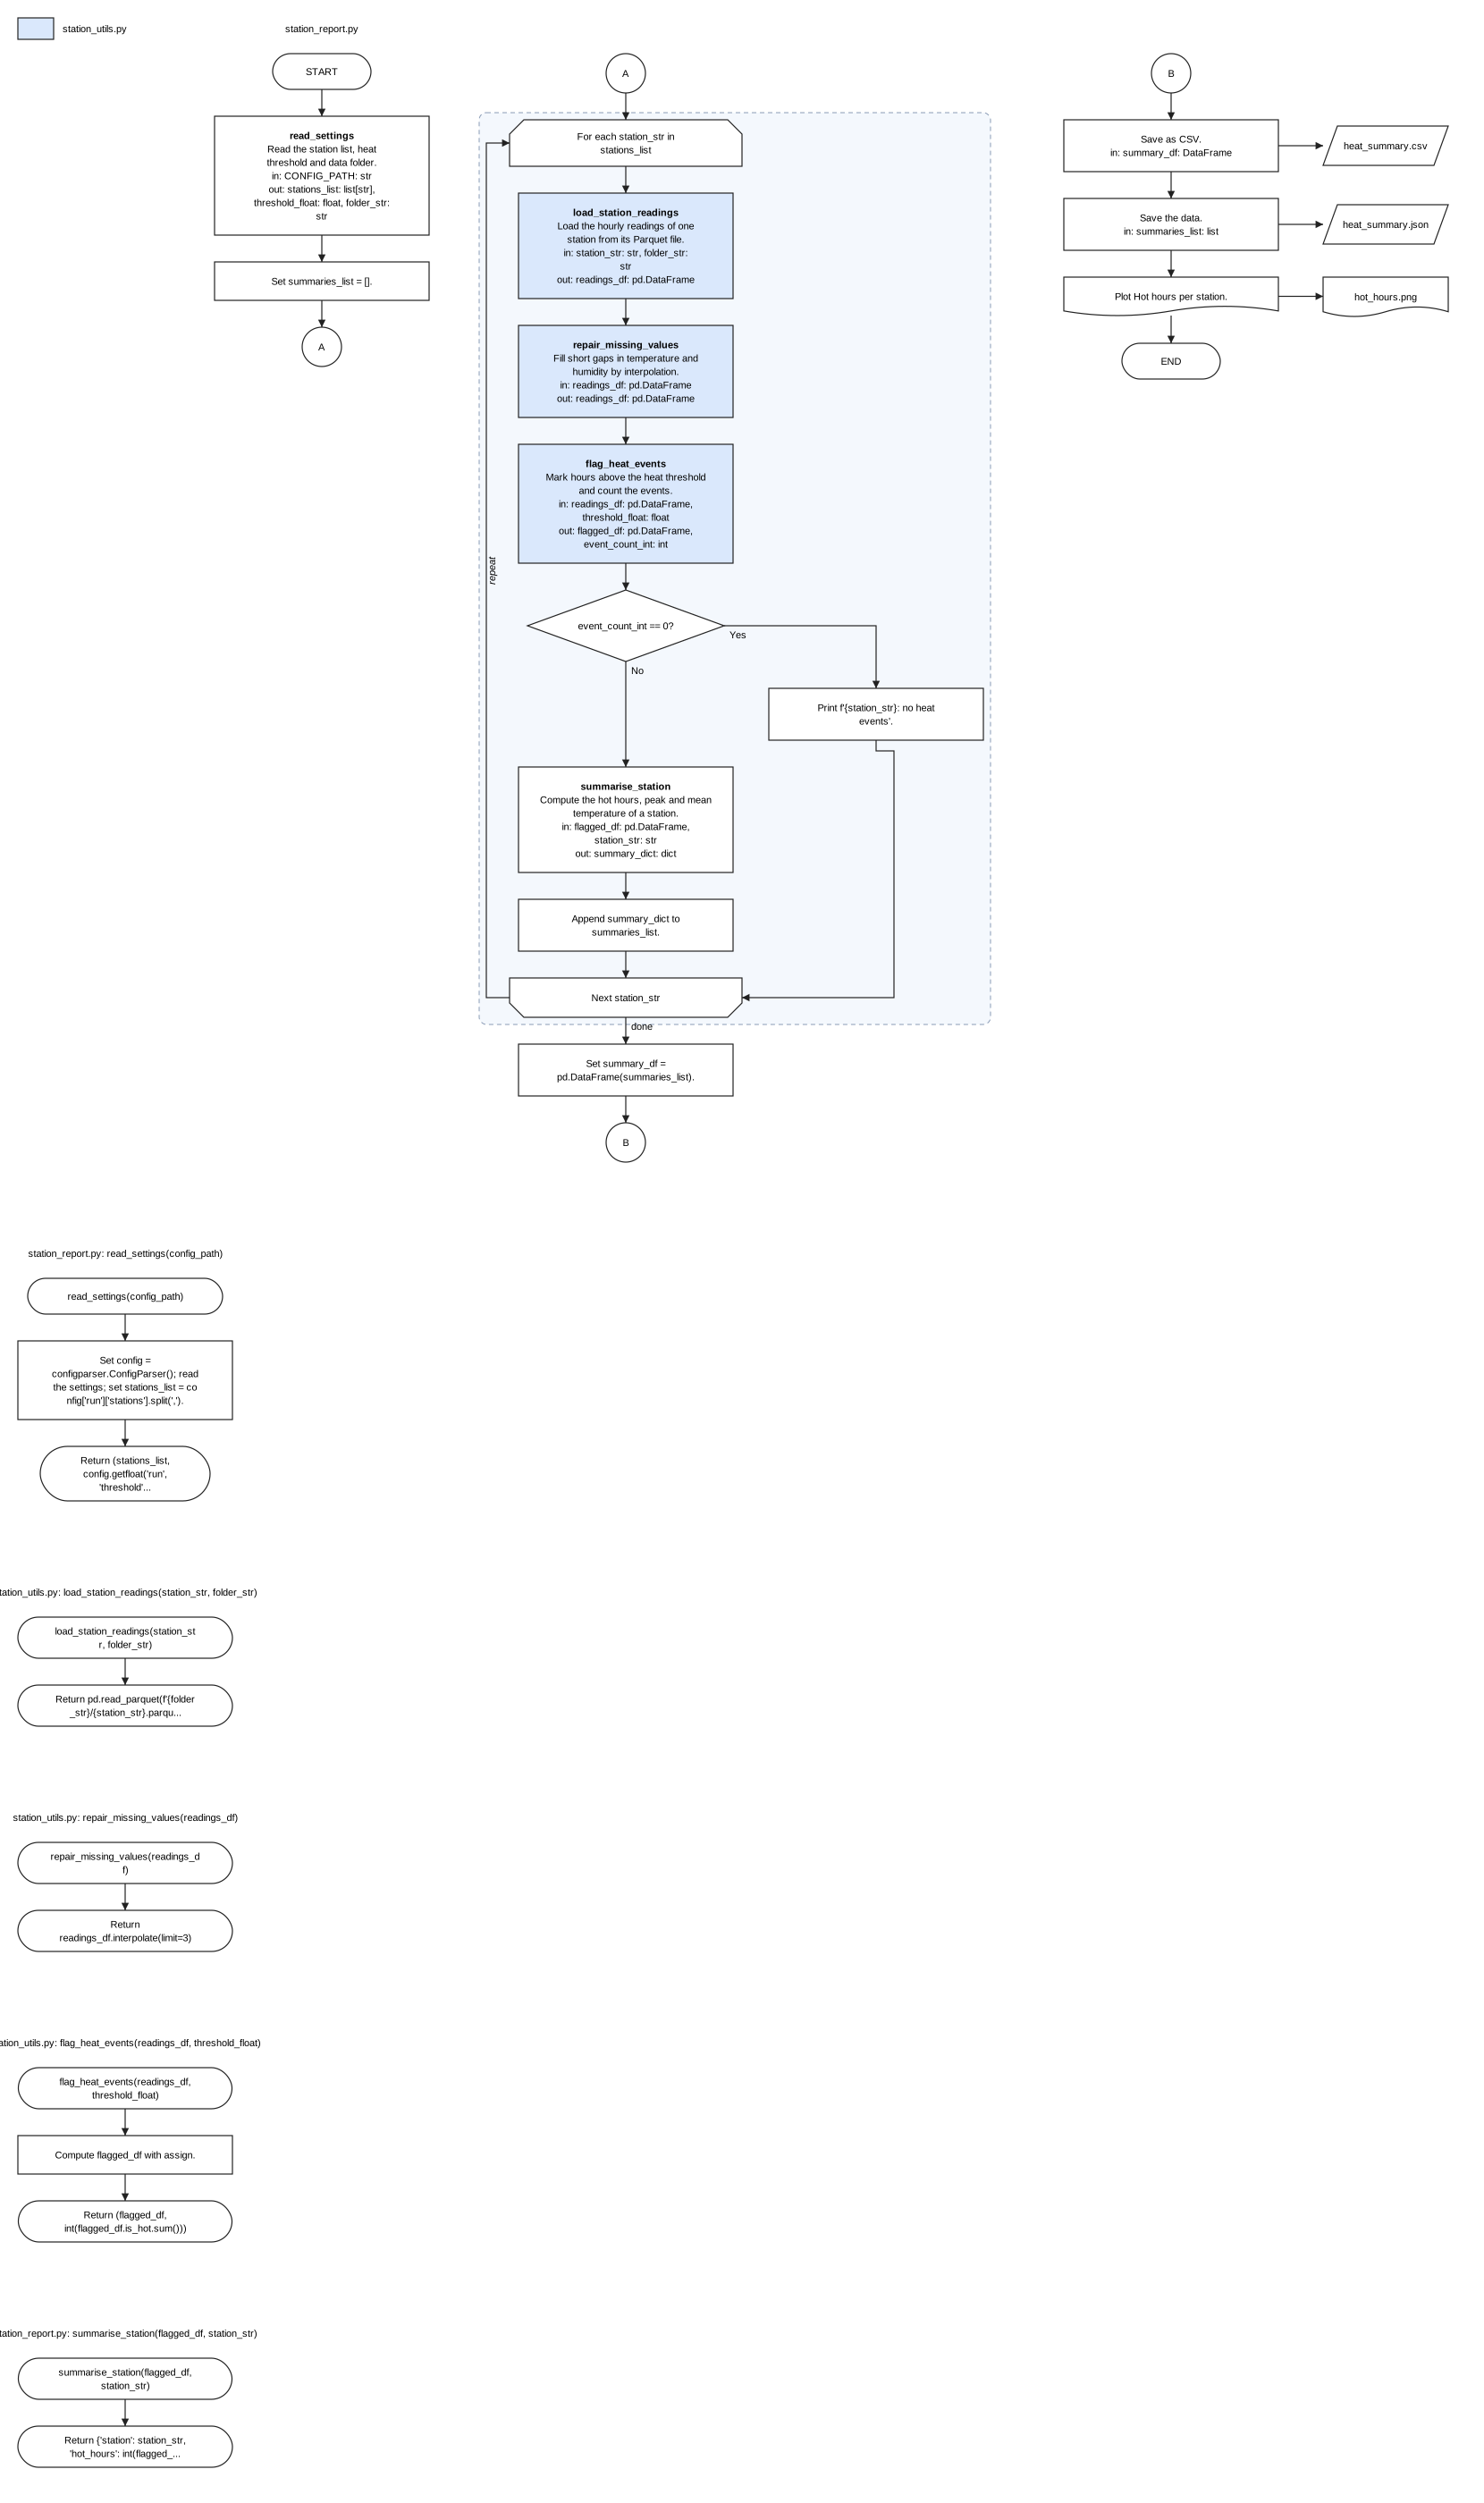
The Python architect: turn any Python script, Jupyter notebook or whole project folder into a clear architecture diagram (draw.io, SVG, HTML or Mermaid for your README), without running it.
Website: samtherocket.github.io/flowblueprint
FlowBlueprint reads your code and draws how it flows: what runs first, which functions are called, what goes in and out of each step (with data types), where loops and decisions are, which files, databases and storage are read or written, and where plots are made. Managers, product owners and new team members can understand a pipeline before reading a single line of code; developers get an architecture diagram that stays in step with the source.
Part of a family of standalone Python tools: FuncLoom (functionizer), RefacTrail (refactorizer) and FlowBlueprint (architect).
Status: alpha. 0.2.0a0 is an experimental alpha, published on PyPI. Python 3.12 or newer is required. No LLM, account or network connection is needed.
Quick start
pip install flowblueprint
flowblueprint my_script.py                  # writes my_script.drawio
flowblueprint analysis.ipynb                # notebooks work too
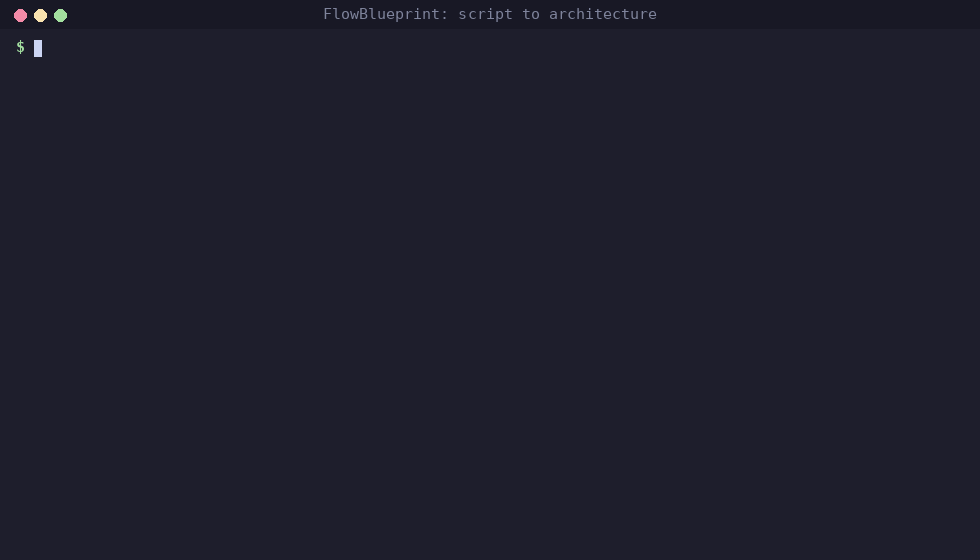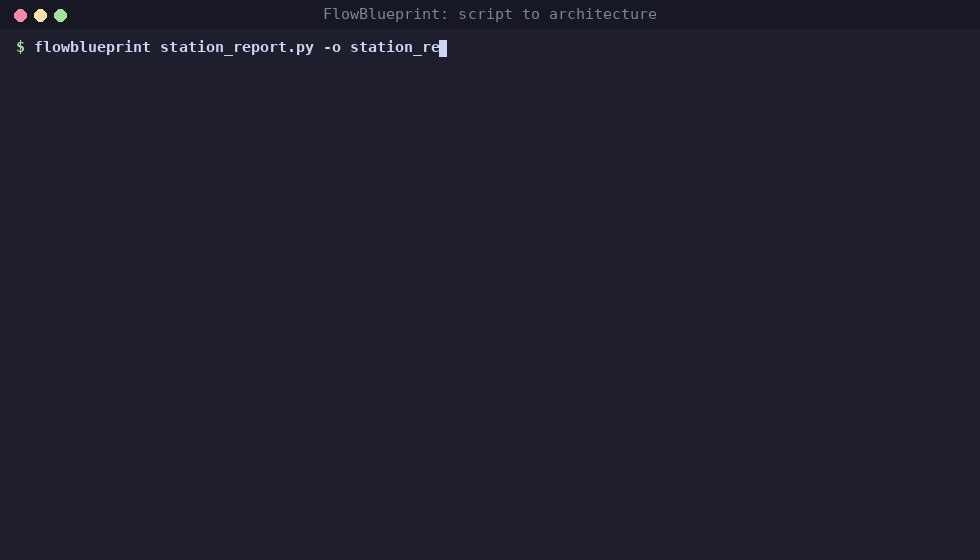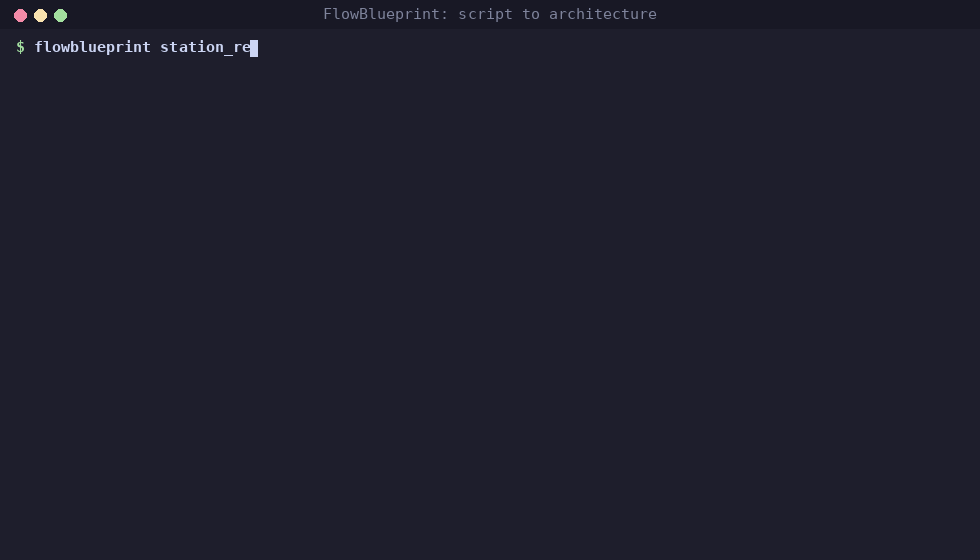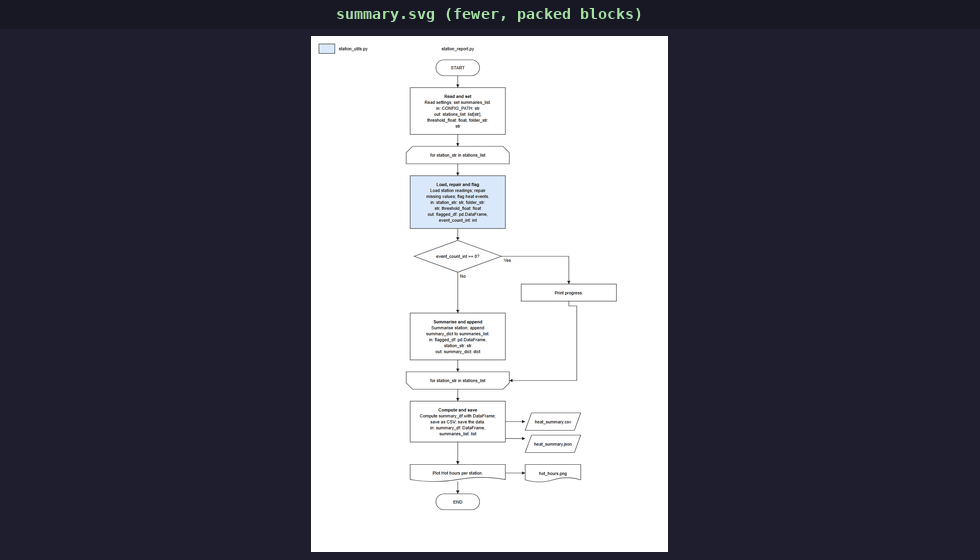
flowblueprint my_script.py --level summary  # fewer, higher-level blocks
flowblueprint my_script.py -o overview.svg  # an image for slides/READMEs
flowblueprint my_script.py -o FLOW.md       # Mermaid: renders on GitHub
flowblueprint my_project/                   # the whole project at a glance
flowblueprint my_project/ -o ARCHITECTURE.md
pip install flowblueprint also installs FuncLoom and RefacTrail.
Open the .drawio file in diagrams.net or the
VS Code Draw.io Integration extension, where you can edit it freely or
save it as an editable .drawio.png.
Office machines and older Python
FlowBlueprint needs Python 3.12 or newer, but your project does not: the tool only reads your code, so it can run on its own Python next to a project that stays on 3.9, 3.10 or 3.11. Neither of these needs administrator rights; uv downloads its own Python 3.12 into your user folder:
uvx --python 3.12 flowblueprint my_script.py
uv tool install --python 3.12 flowblueprint
flowblueprint my_project/ -o ARCHITECTURE.md
pipx install --python <path to a Python 3.12> flowblueprint works the same
way. If pip says from versions: none, your Python is older than 3.12
or pip is pointed at a company mirror that does not carry the package
(check with python -m pip config list, and ask IT to allow it).
Output formats
The suffix of -o picks the format:
| Suffix | You get | Good for |
|---|---|---|
.drawio (default) |
An editable diagram | diagrams.net, the VS Code Draw.io extension |
.svg |
An image | Slides, documents, READMEs |
.html |
A self-contained web page with the image and notes | E-mail, tickets, sharing without tools |
.md |
Markdown with a Mermaid flowchart | GitHub and GitLab READMEs, wikis, Obsidian |
.mmd |
Mermaid text | Notion, documentation sites, Mermaid tools |
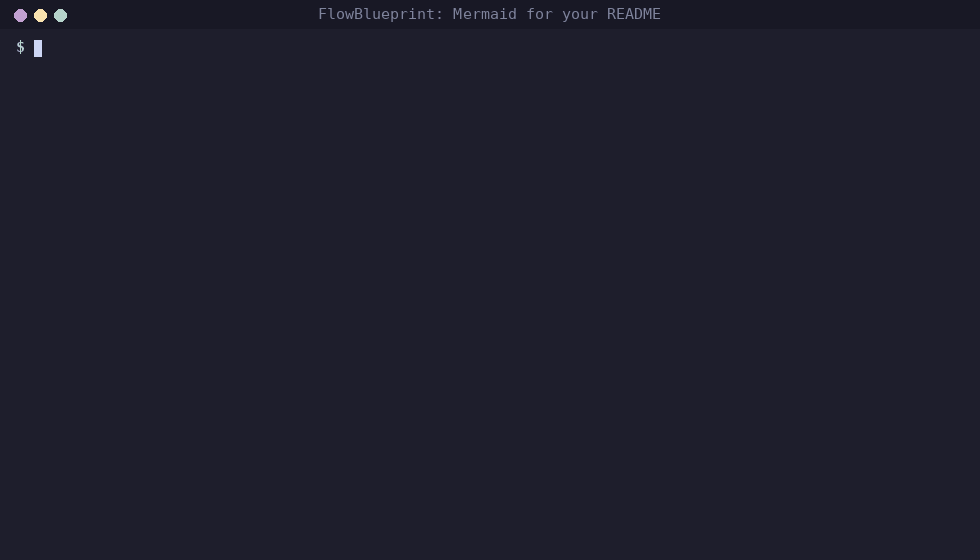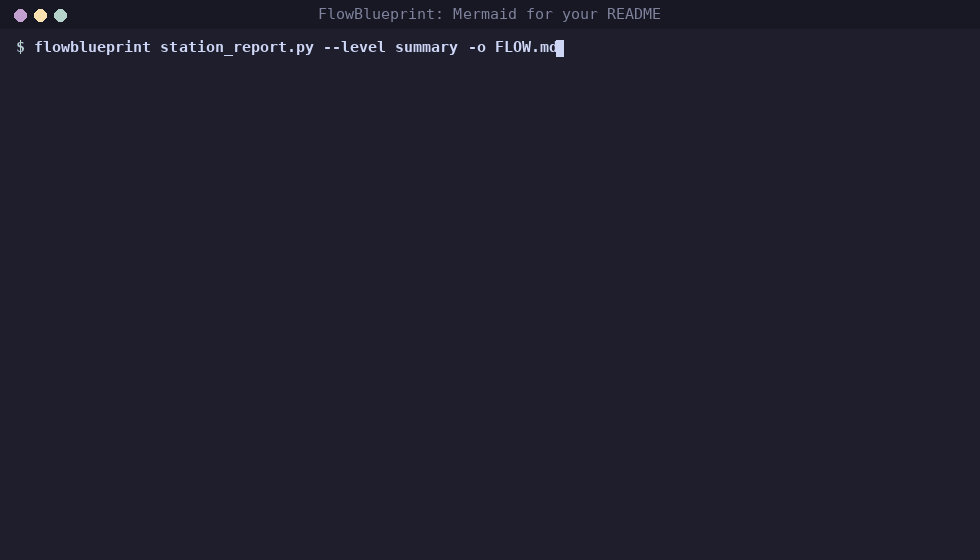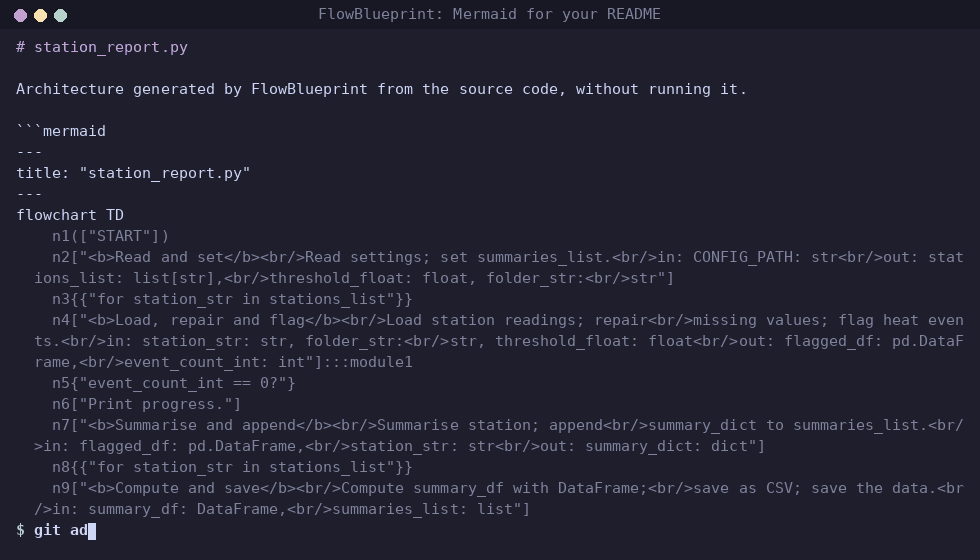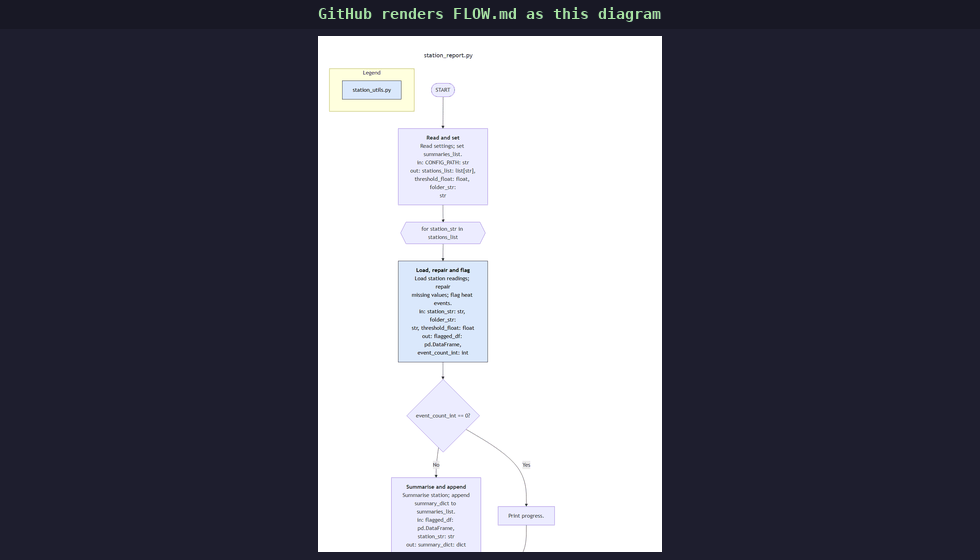
A Mermaid diagram lives in your repository as text and GitHub draws it.
This one is flowblueprint station_report.py --level summary -o FLOW.md:
---
title: "station_report.py"
---
flowchart TD
    n1(["START"])
    n2["<b>Read and set</b><br/>Read settings; set summaries_list.<br/>in: CONFIG_PATH: str<br/>out: stations_list: list[str],<br/>threshold_float: float, folder_str:<br/>str"]
    n3{{"for station_str in stations_list"}}
    n4["<b>Load, repair and flag</b><br/>Load station readings; repair<br/>missing values; flag heat events.<br/>in: station_str: str, folder_str:<br/>str, threshold_float: float<br/>out: flagged_df: pd.DataFrame,<br/>event_count_int: int"]:::module1
    n5{"event_count_int == 0?"}
    n6["Print progress."]
    n7["<b>Summarise and append</b><br/>Summarise station; append<br/>summary_dict to summaries_list.<br/>in: flagged_df: pd.DataFrame,<br/>station_str: str<br/>out: summary_dict: dict"]
    n8{{"for station_str in stations_list"}}
    n9["<b>Compute and save</b><br/>Compute summary_df with DataFrame;<br/>save as CSV; save the data.<br/>in: summary_df: DataFrame,<br/>summaries_list: list"]
    n10[/"heat_summary.csv"/]
    n11[/"heat_summary.json"/]
    n12>"Plot Hot hours per station."]
    n13>"hot_hours.png"]
    n14(["END"])
    n1 --> n2
    n2 --> n3
    n3 --> n4
    n5 -->|"Yes"| n6
    n4 --> n5
    n5 -->|"No"| n7
    n7 --> n8
    n9 -.-> n10
    n9 -.-> n11
    n8 --> n9
    n12 -.-> n13
    n9 --> n12
    n12 --> n14
    n6 --> n8
    subgraph legend["Legend"]
        legend1["station_utils.py"]:::module1
    end
    classDef module1 fill:#dae8fc,stroke:#222222,color:#000000
Whole projects
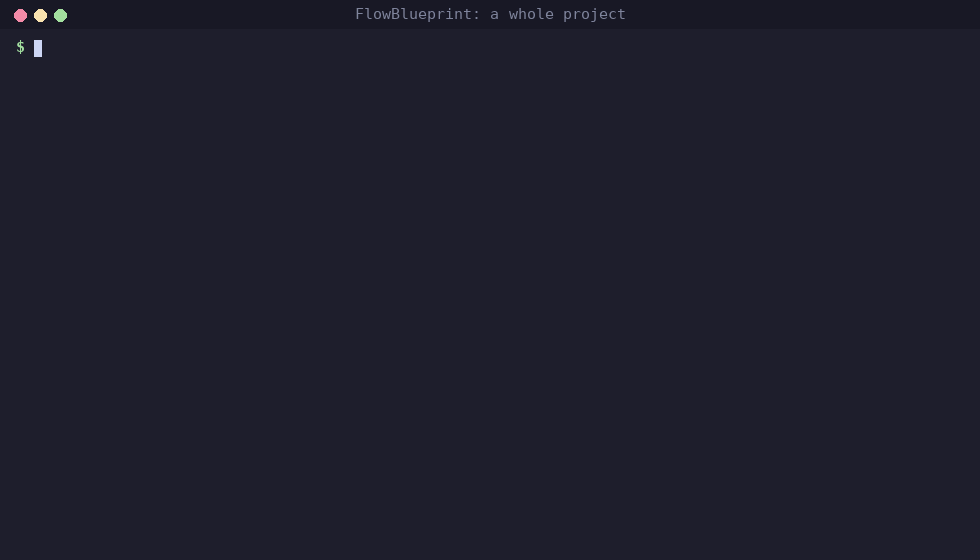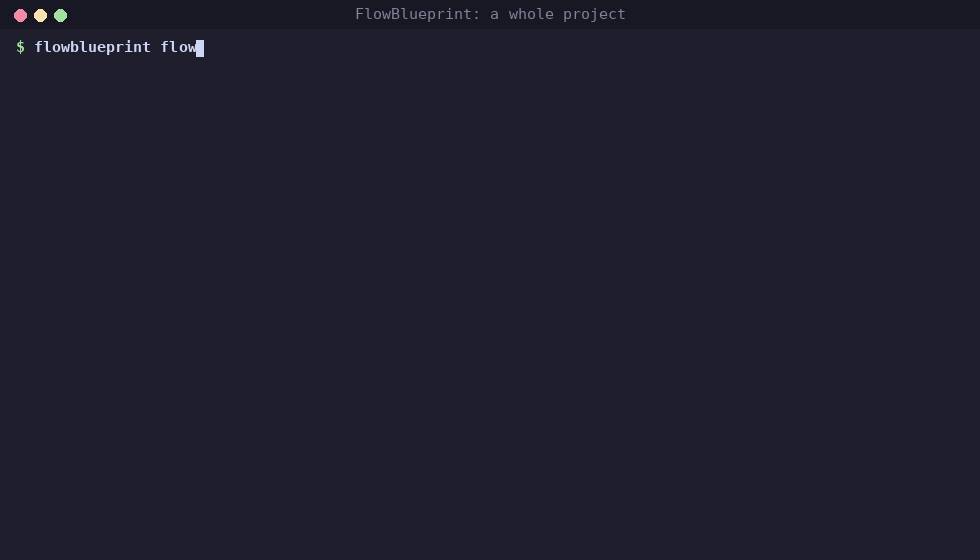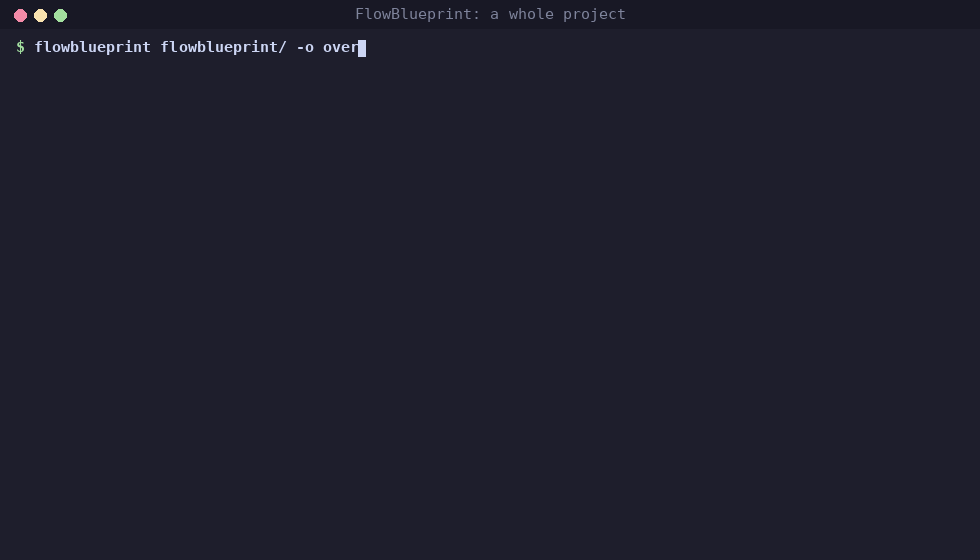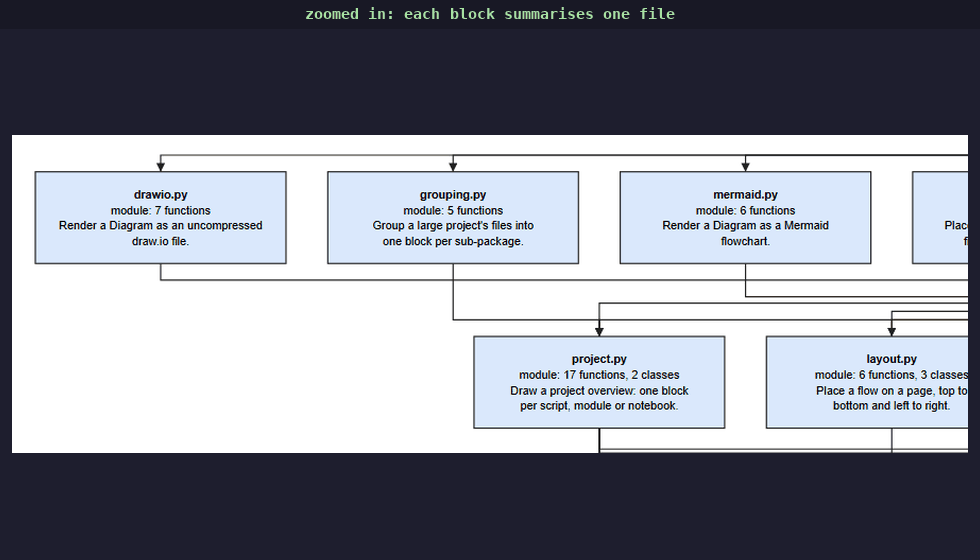
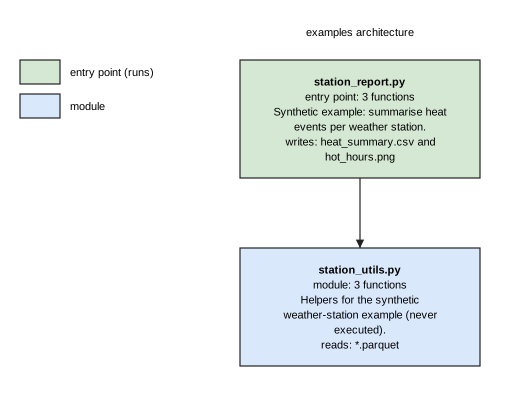
Point FlowBlueprint at a folder to see the whole project: one block per script, module, package and notebook, with an arrow from each file to the project files it imports. Entry points sit at the top and the modules they rely on below them. Each block says what the file is (its docstring, the steps it runs, or the functions it provides), how many functions and classes it defines, and which files, databases and storage it reads and writes.
flowblueprint my_project/                        # my_project/architecture.drawio
flowblueprint my_project/ -o ARCHITECTURE.md     # Mermaid for the README
flowblueprint my_project/ --include-tests -o overview.html
Large projects stay readable: above 40 files, files are grouped into one
block per sub-package (the deepest folder level that fits 40 blocks),
each summing its files, functions, classes and data and naming the
scripts it runs. --group-depth 2 picks the level yourself;
--group-depth 0 draws every file.
Absolute, relative and sibling-script imports are resolved, including
src layouts and folders inside packages. Virtual environments,
caches, build output and hidden folders are skipped; test files are
skipped unless you pass --include-tests. Files that cannot be parsed
are listed as notes instead of stopping the run. In the draw.io and SVG
output, an arrow that skips rows runs in its own lane beside the blocks,
so it never passes behind one; the Mermaid output is laid out by Mermaid
itself.
What you get
| In your code | In the diagram |
|---|---|
| The script or notebook name | A title above the flow |
| Start and end of the run | START and END terminators |
| A call to your own function or method | A block: name, one-line description, in: and out: with data types |
| Several small operations | One plain block, or one packed block at --level summary |
| Functions from your own modules | Coloured blocks, with a colour legend per module |
for / while loops |
Opening and closing loop-limit shapes |
Notebook Markdown headings, # %% Title cell markers |
Dashed section banners that split the flow |
if / elif / else |
A decision diamond with Yes and No paths |
continue, break, return in a branch |
An arrow to the loop end, past the loop, or to END |
| CSV, Parquet, Excel, JSON, config files | Data shapes on the left (read) or right (written) |
| SQL reads and writes | Database cylinders |
s3://, gs://, network shares |
Storage shapes |
| matplotlib, seaborn, plotly | A plot block, with saved figures as documents |
| Long flows | Columns of at most 10 blocks joined by A/B connectors |
Descriptions come from docstrings. Without one, FlowBlueprint writes a
short, deterministic description from the code itself ("Calculate
distance." for calculate_distance). Types come from annotations,
well-known library calls, literals and naming conventions such as _df
or _list; anything else is shown as unknown rather than guessed.
Two levels: detailed and summary
One function is not always one block. --level detailed (the default)
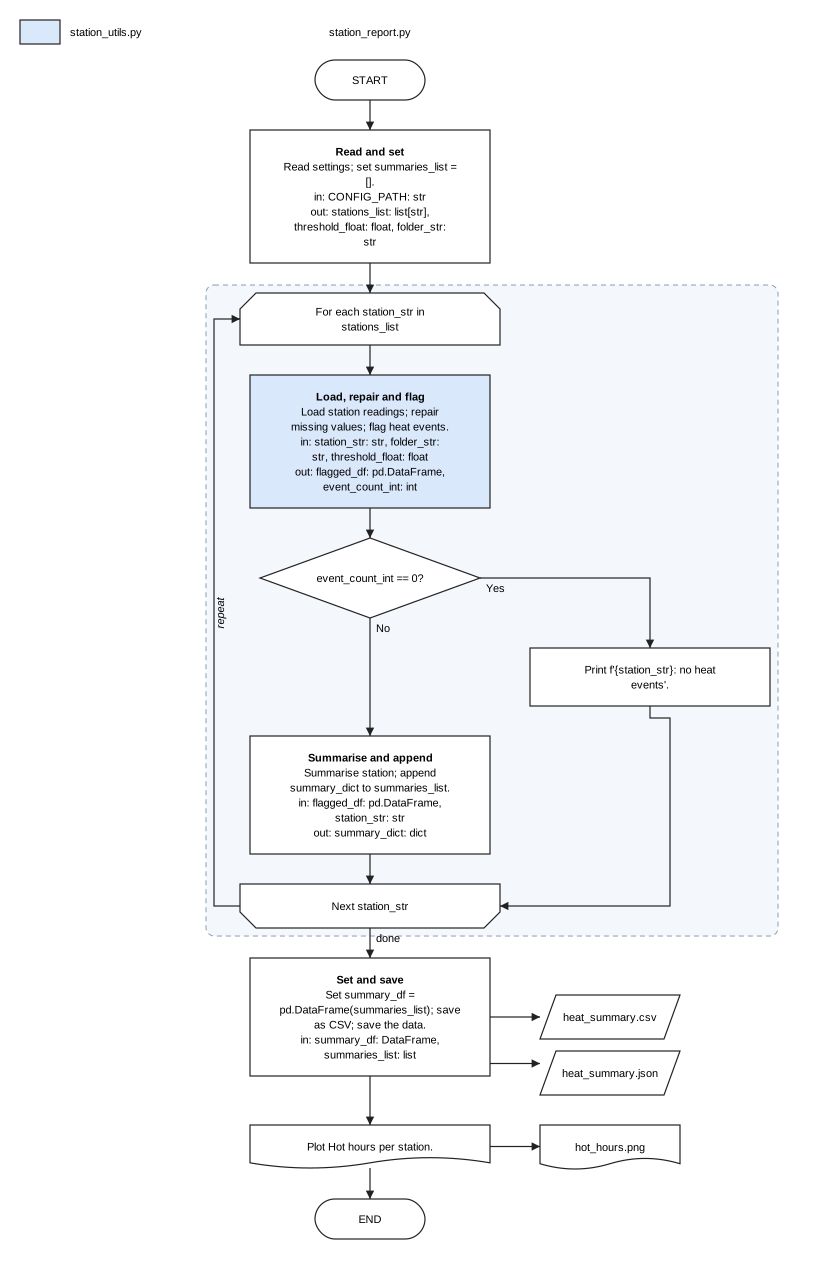
draws one block per call. --level summary packs consecutive operations
into higher-level blocks (up to --group-size, default 4), each listing
its operations with the inputs it needs and the outputs it leaves:
You choose the grouping when it matters, with an override file:
# blueprint.toml
[[groups]]
title = "prepare_readings"
description = "Load and clean the readings of one station."
functions = ["load_station_readings", "repair_missing_values"]

[blocks.flag_heat_events]
description = "Find the hours above the heat threshold."
flowblueprint station_report.py --overrides blueprint.toml
Classes and well-structured code
FlowBlueprint works directly on any readable script; you do not need to
run FuncLoom or RefacTrail first. Classes are understood: Pipeline(...)
becomes a Create the Pipeline block, pipeline.load() resolves to the
method and its docstring, and when the entry point only hands over to one
method (Pipeline(config).run()), that method's steps are drawn.
FlowBlueprint's own ARCHITECTURE.md is drawn this way
(flowblueprint src/flowblueprint -o ARCHITECTURE.md).
Keep the diagram up to date
In GitHub Actions, the FlowBlueprint action draws the diagram on every push; commit it, or keep it as a build artifact:
- uses: actions/checkout@v4
- uses: SAMtheROCKET/flowblueprint@main
  with:
    path: .                     # a script, notebook or folder
    output: ARCHITECTURE.md     # .md, .mmd, .drawio, .svg or .html
    args: --level summary       # optional extra options
- uses: actions/upload-artifact@v4
  with:
    name: architecture
    path: ARCHITECTURE.md
With pre-commit, the
flowblueprint-architecture hook redraws ARCHITECTURE.md whenever
Python files or notebooks change:
repos:
  - repo: https://github.com/SAMtheROCKET/flowblueprint
    rev: main
    hooks:
      - id: flowblueprint-architecture
Checks
Every diagram is checked against block-diagram rules: start and end
terminators, the script name, closed loops, no open-ended blocks, data
sources on the left, the per-column limit, a legend for every colour, and
verb-first titles. --check only checks and exits with 1 on errors.
Statements that are not drawn (for example exception handlers) are
reported with their line numbers.
Who uses it
- Developers and data scientists: document a pipeline, review a pull request, or explain a notebook to the team.
- Managers, product owners and project managers: see what a script does, step by step, before a review or planning meeting.
- Students and teachers: present coursework and assignments as a clear flowchart.
- Teams taking over code: get an architecture overview of unfamiliar scripts in seconds.
Safety
The code is parsed with Python's own ast module and is never imported or
executed. The source file is never changed. Existing output files are not
overwritten unless you pass --force.
Robustness: every file of the Python 3.12 standard library (584 files) and of a 6,988-file corpus of installed packages (NumPy, SciPy, SymPy, matplotlib, Twisted and others) is drawn in detailed and summary form and rendered as draw.io, SVG and Mermaid without an error, as are project overviews of all 92 packages in that corpus (SymPy's 801 files and 6,404 imports take under 5 seconds).
How it fits with FuncLoom and RefacTrail
FlowBlueprint installs FuncLoom and RefacTrail and uses them through absolute imports (for example RefacTrail's validated notebook reader). Use them together for one flow: FuncLoom turns long scripts and notebooks into functions and modules, RefacTrail checks, formats and refactors them, and FlowBlueprint draws the architecture.
Looking for a Python architecture diagram generator, code to flowchart, script to architecture, notebook to architecture, project architecture diagram, Python to Mermaid, workflow diagram generator or auto architecture generator (archgen)? That is what FlowBlueprint does.
Roadmap
- 0.3: cleaner arrow routing in large project overviews and more library knowledge for data types.
- Later, optional: AI-written descriptions, always shown with their source evidence and never required.
License
MIT. See LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for flowblueprint 0.2.0a0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| flowblueprint-0.2.0a0.tar.gz | 71.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| flowblueprint-0.2.0a0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 138.4 kB
Release files / flowblueprint-0.2.0a0.tar.gz
| Download URL | flowblueprint-0.2.0a0.tar.gz |
|---|---|
| Size | 71.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4791086aa21ed627ee76b22808330553c826958af34d465a9e95694602dbe0f9
|
|
BLAKE2b-256 checksum How to use checksums |
77c38f8fc81a8f108c5e1deb95342c06e872227b602fae86f7d518767810ce8a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency logRelease files / flowblueprint-0.2.0a0-py3-none-any.whl
| Download URL | flowblueprint-0.2.0a0-py3-none-any.whl |
|---|---|
| Size | 66.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
16a0d974026962c2be3e39a69906af5c5fa737f1b986a170999f8de8578de6ee
|
|
BLAKE2b-256 checksum How to use checksums |
c2da4cba8e61deab4dbfcd61106aba5baf3e64a4b8f19b4dbcb2d4dad070dcd9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 6, 2026.
Transparency log













