
Detached ML Execution Cache — the terminal client


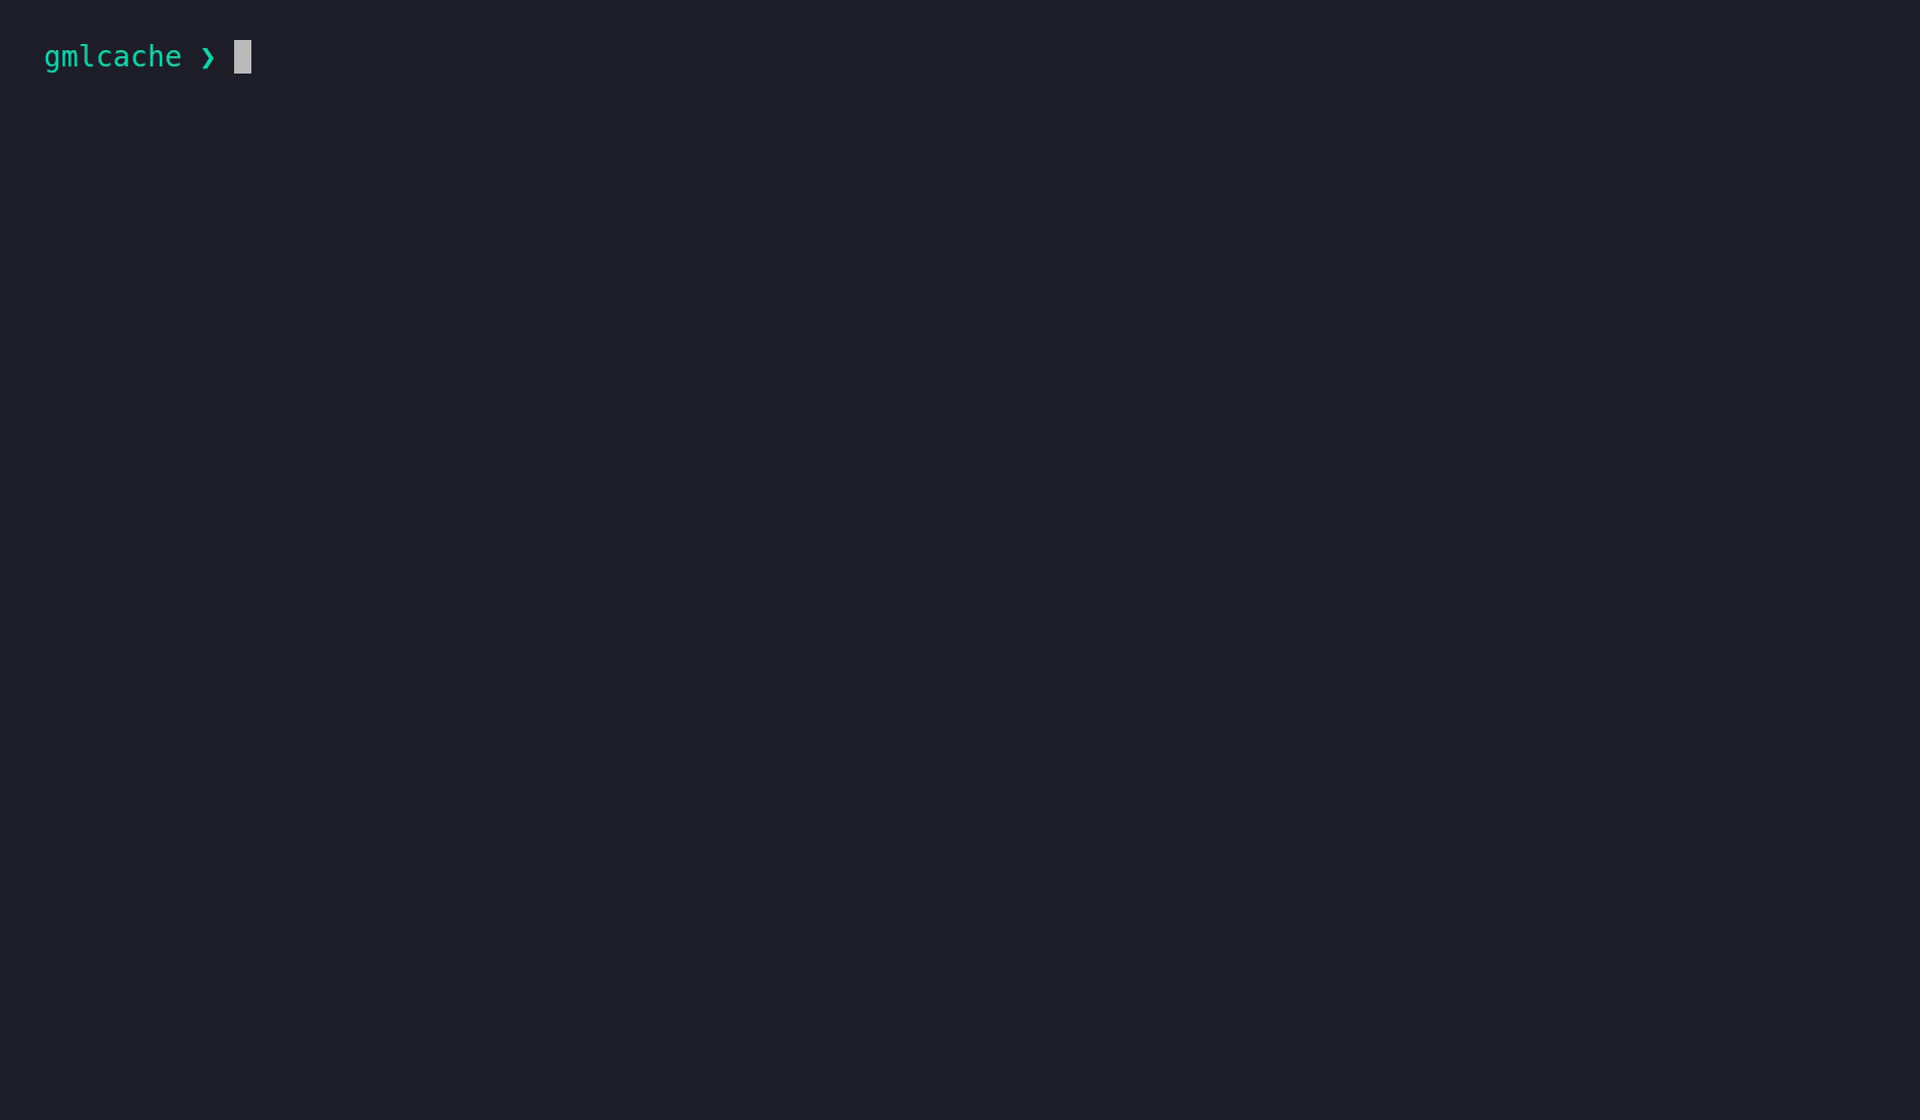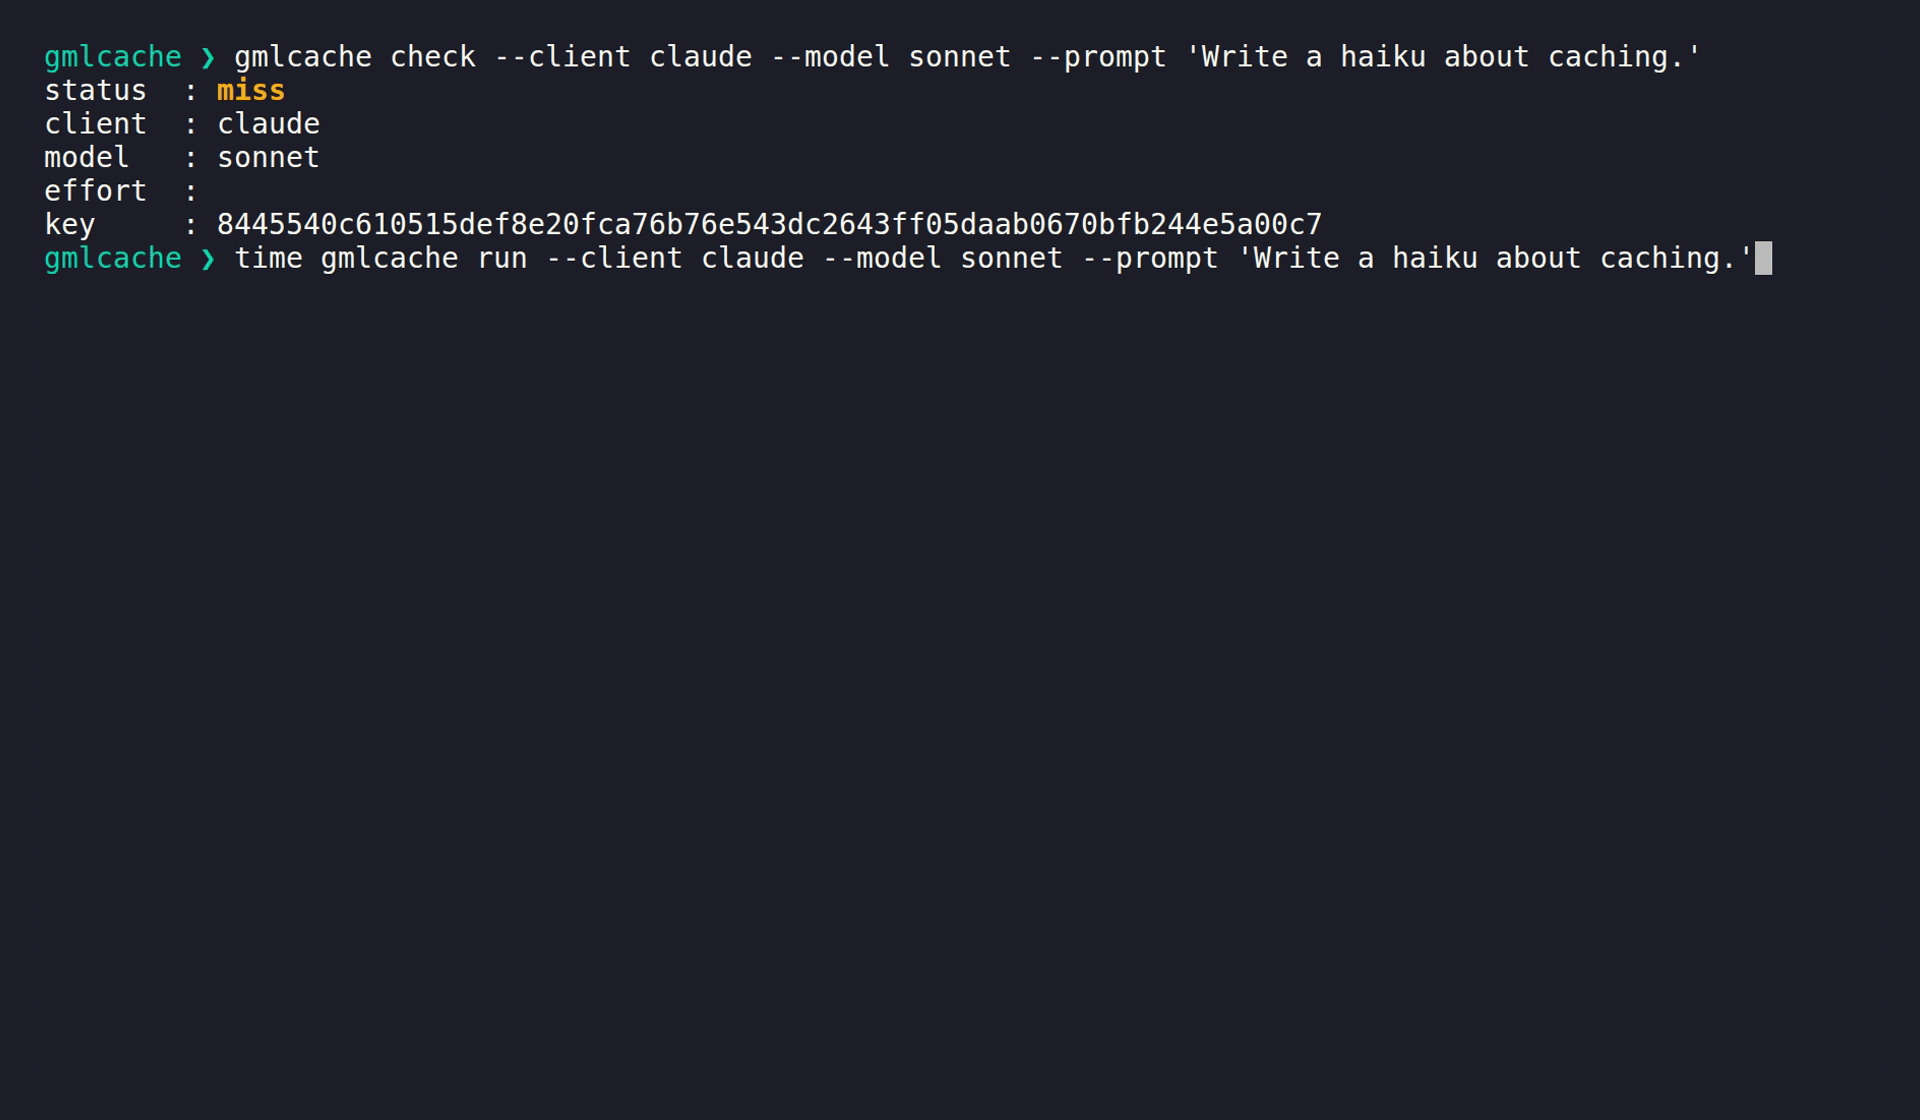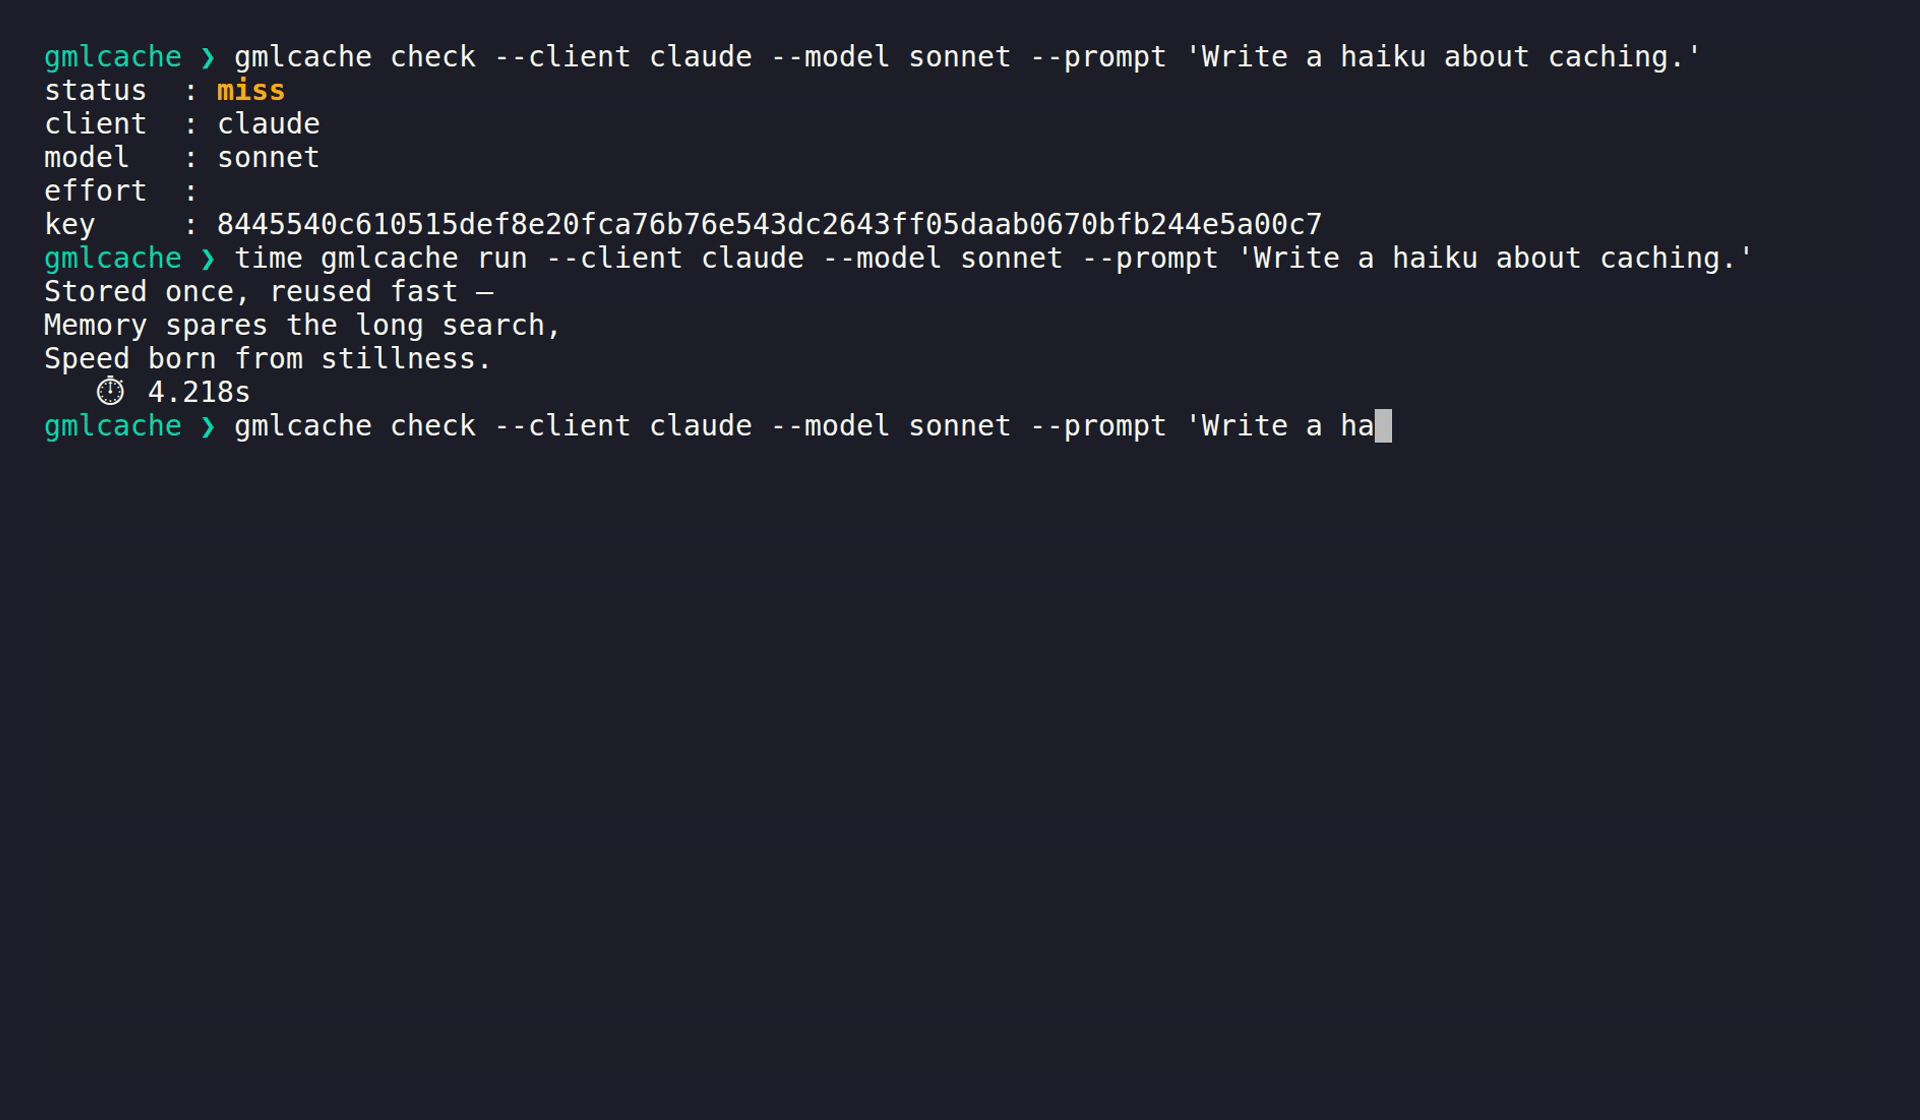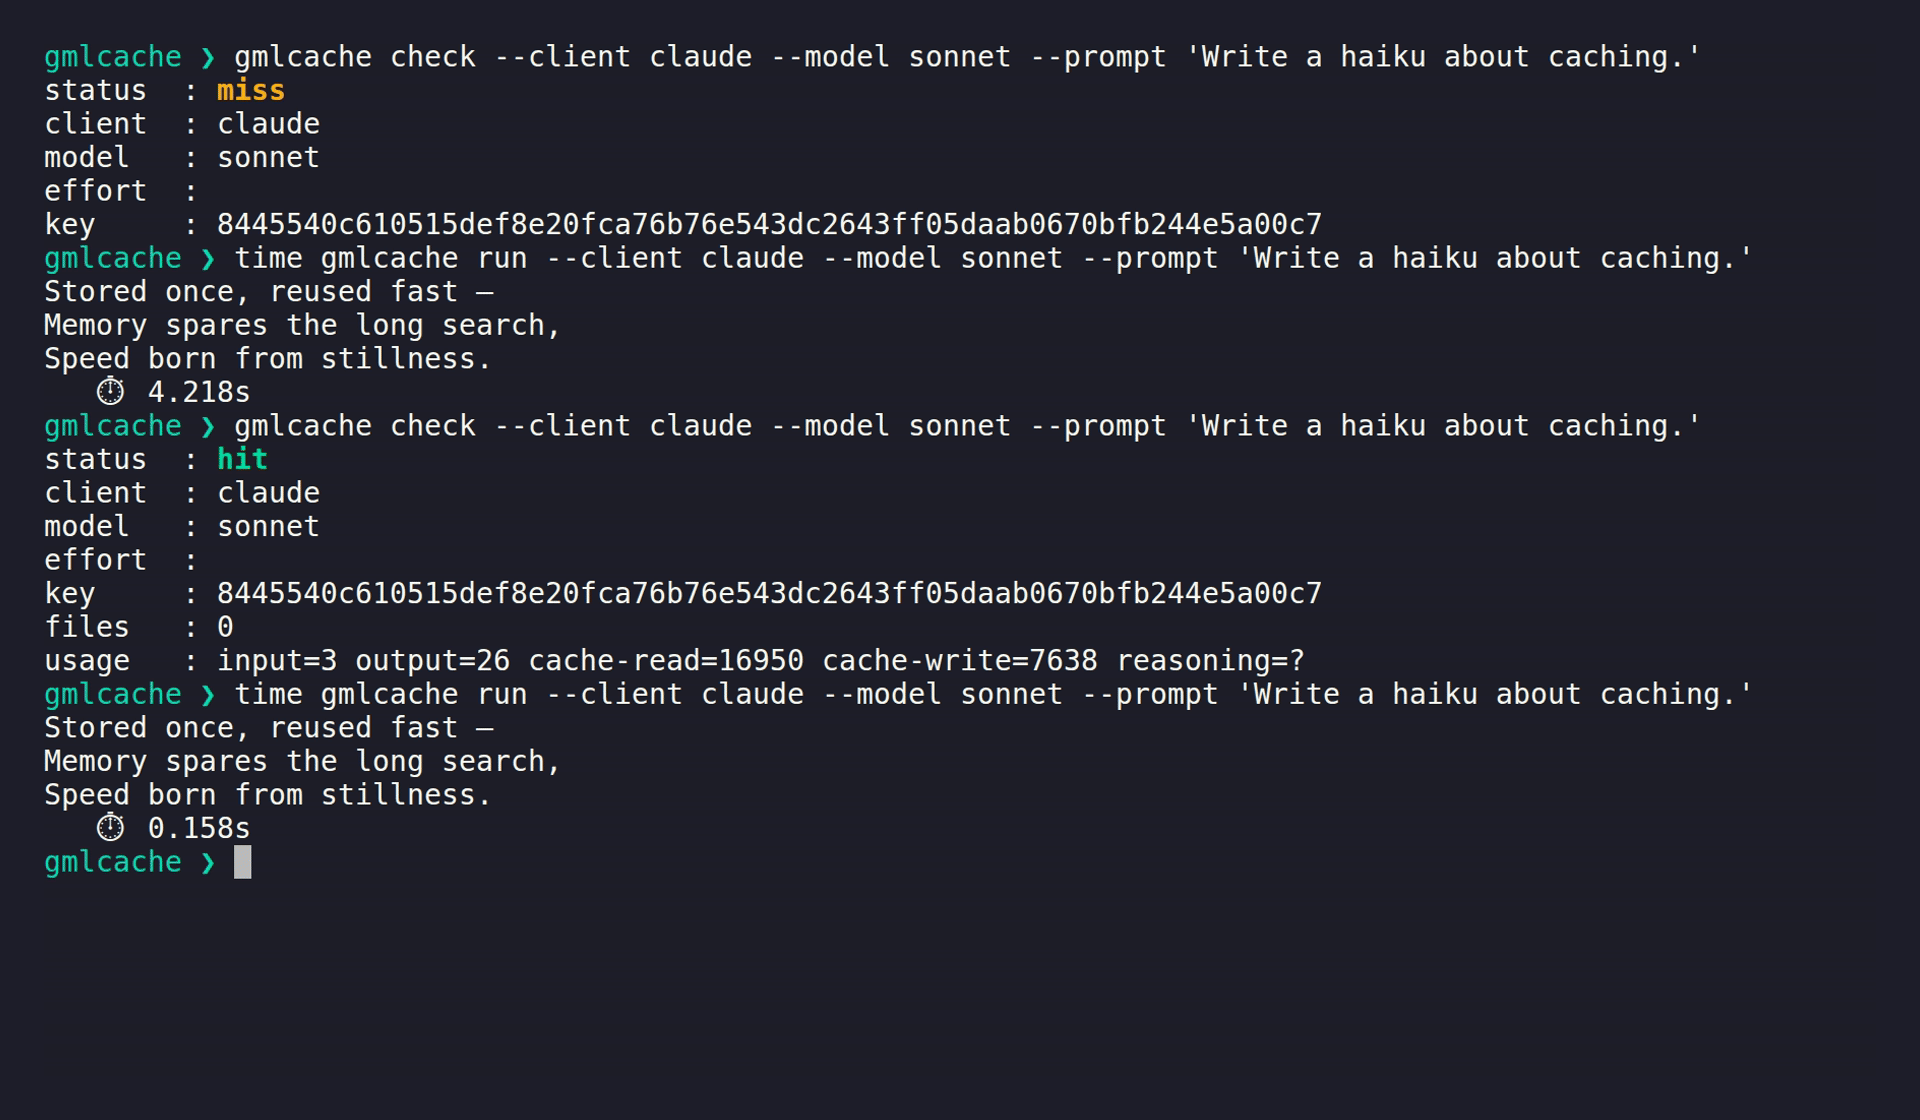
gmlcache runs, records, and replays detached ML workloads — record a real client (or
API) call once, replay it forever by its content key, offline and byte-for-byte.
Single-user, local — not a gateway. gmlcache runs on your machine, as you, across the subscriptions and APIs you already hold. It is not a multi-user router and not a way to share one subscription — see Positioning.
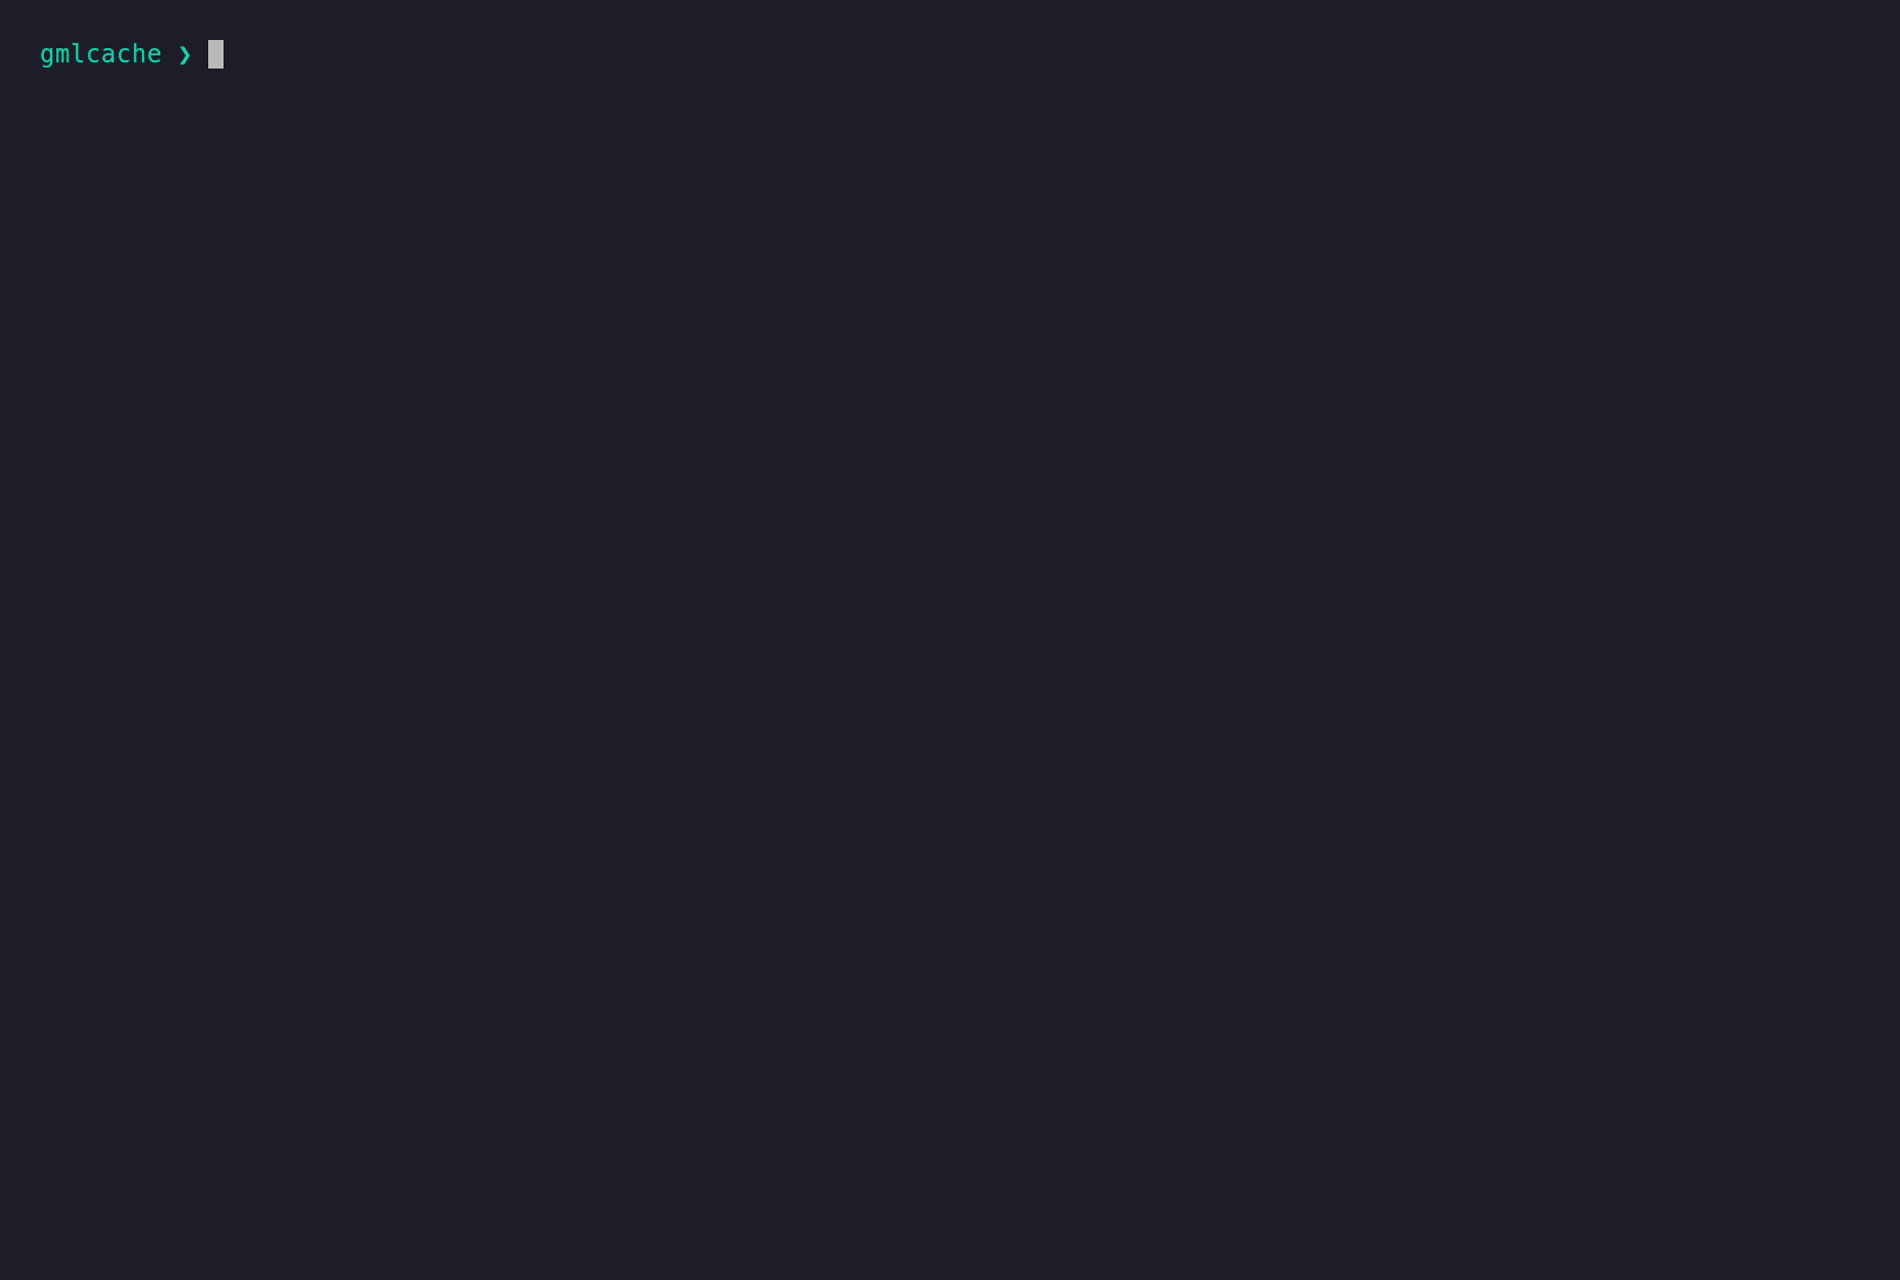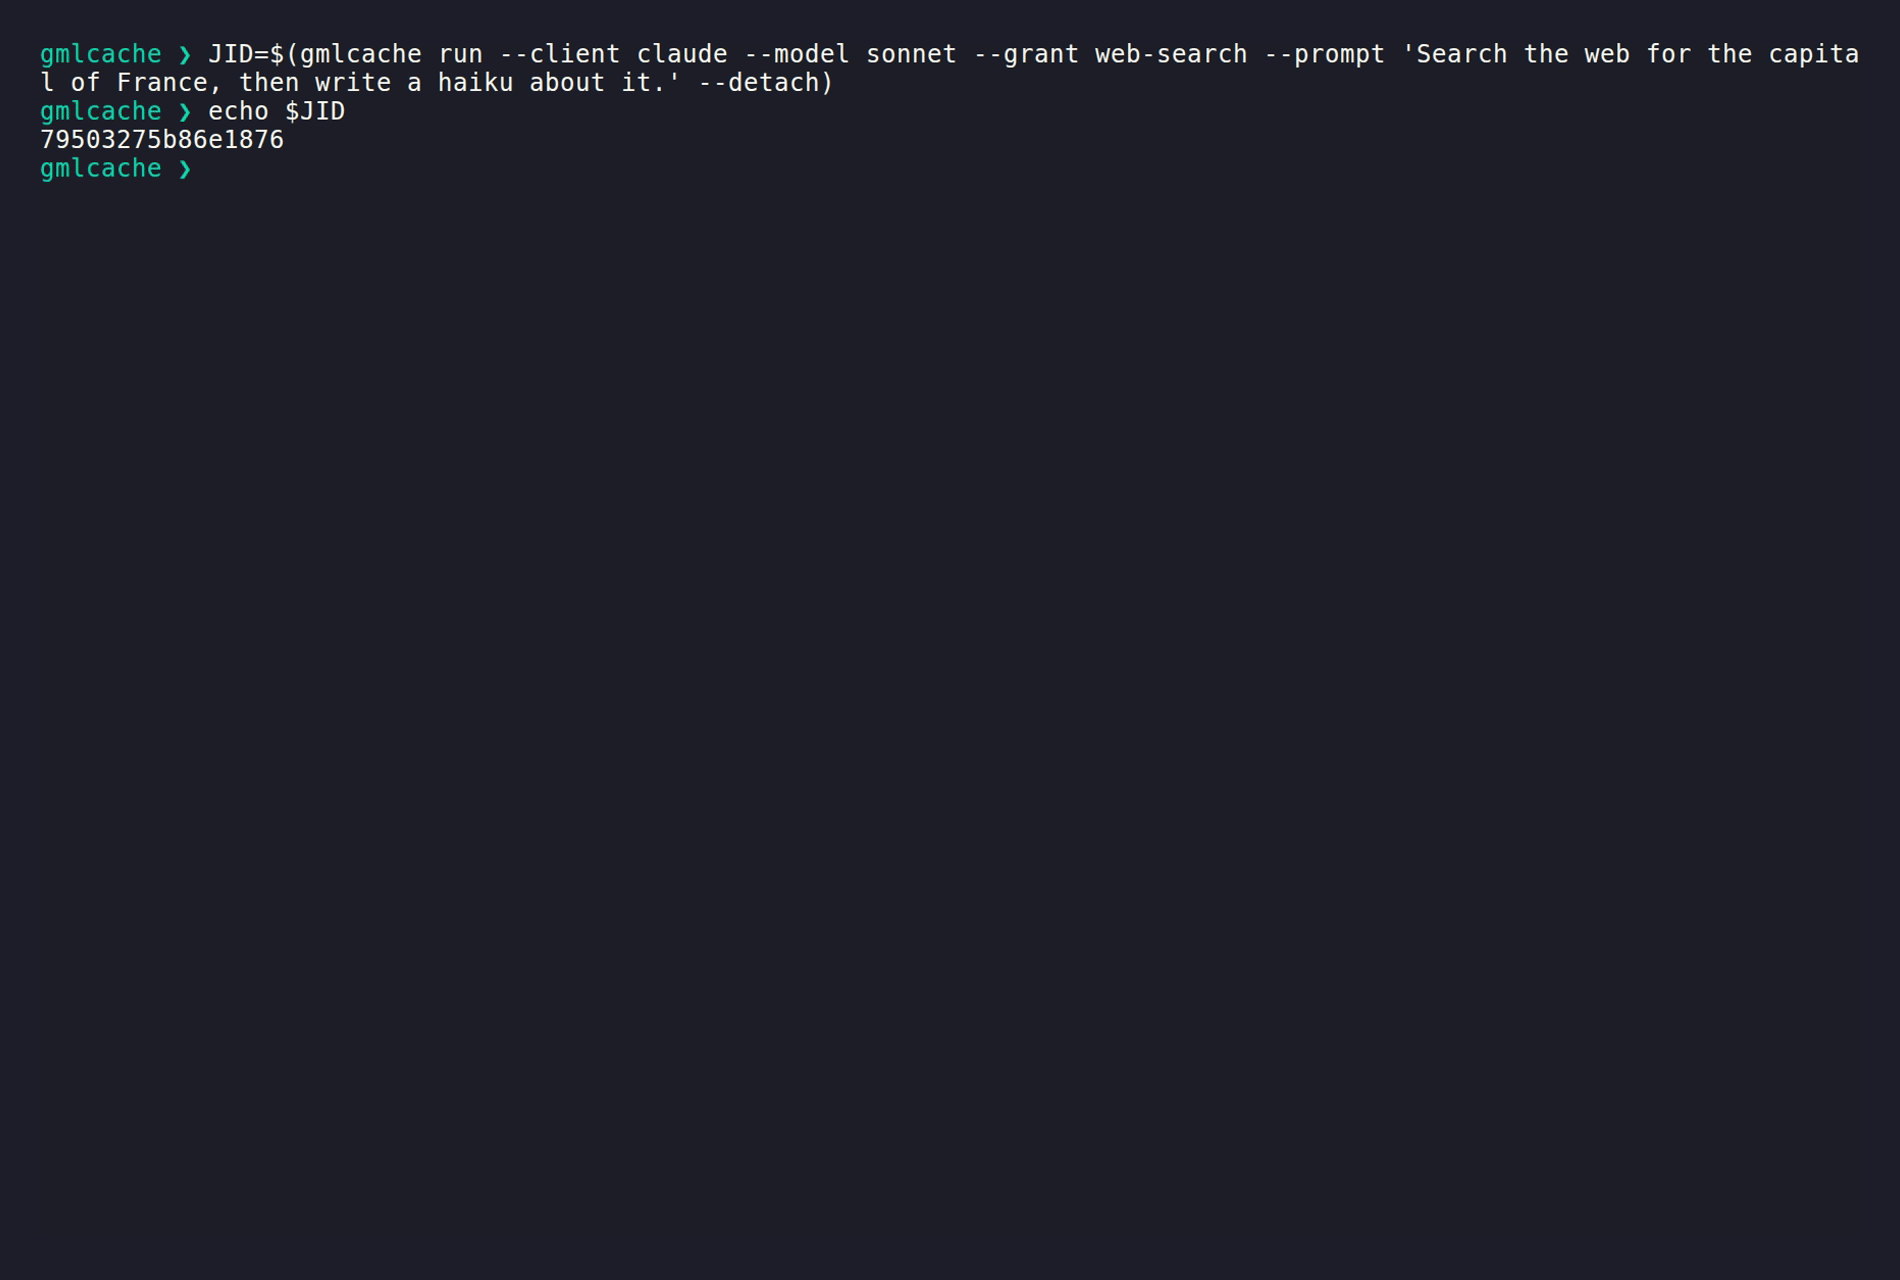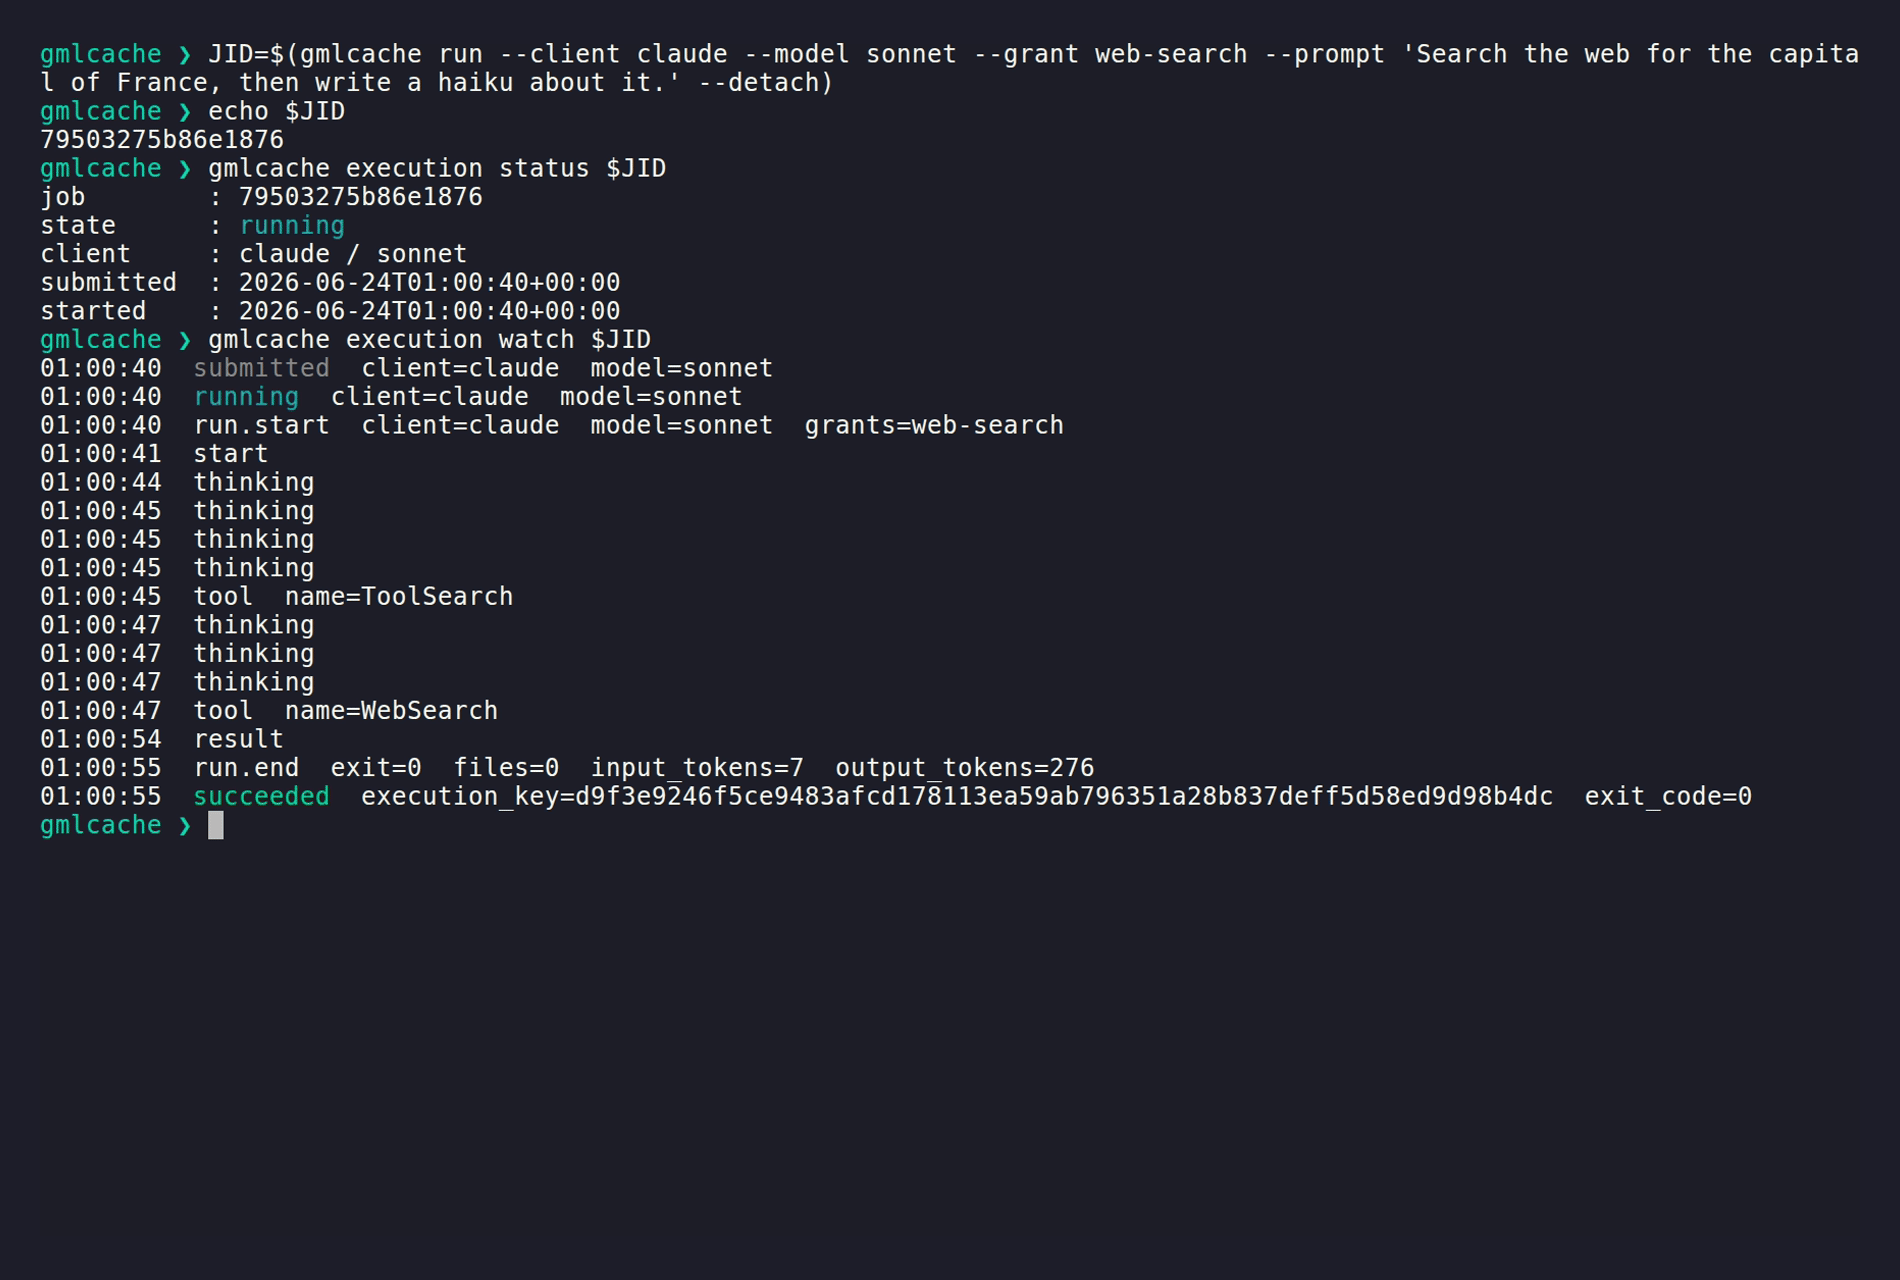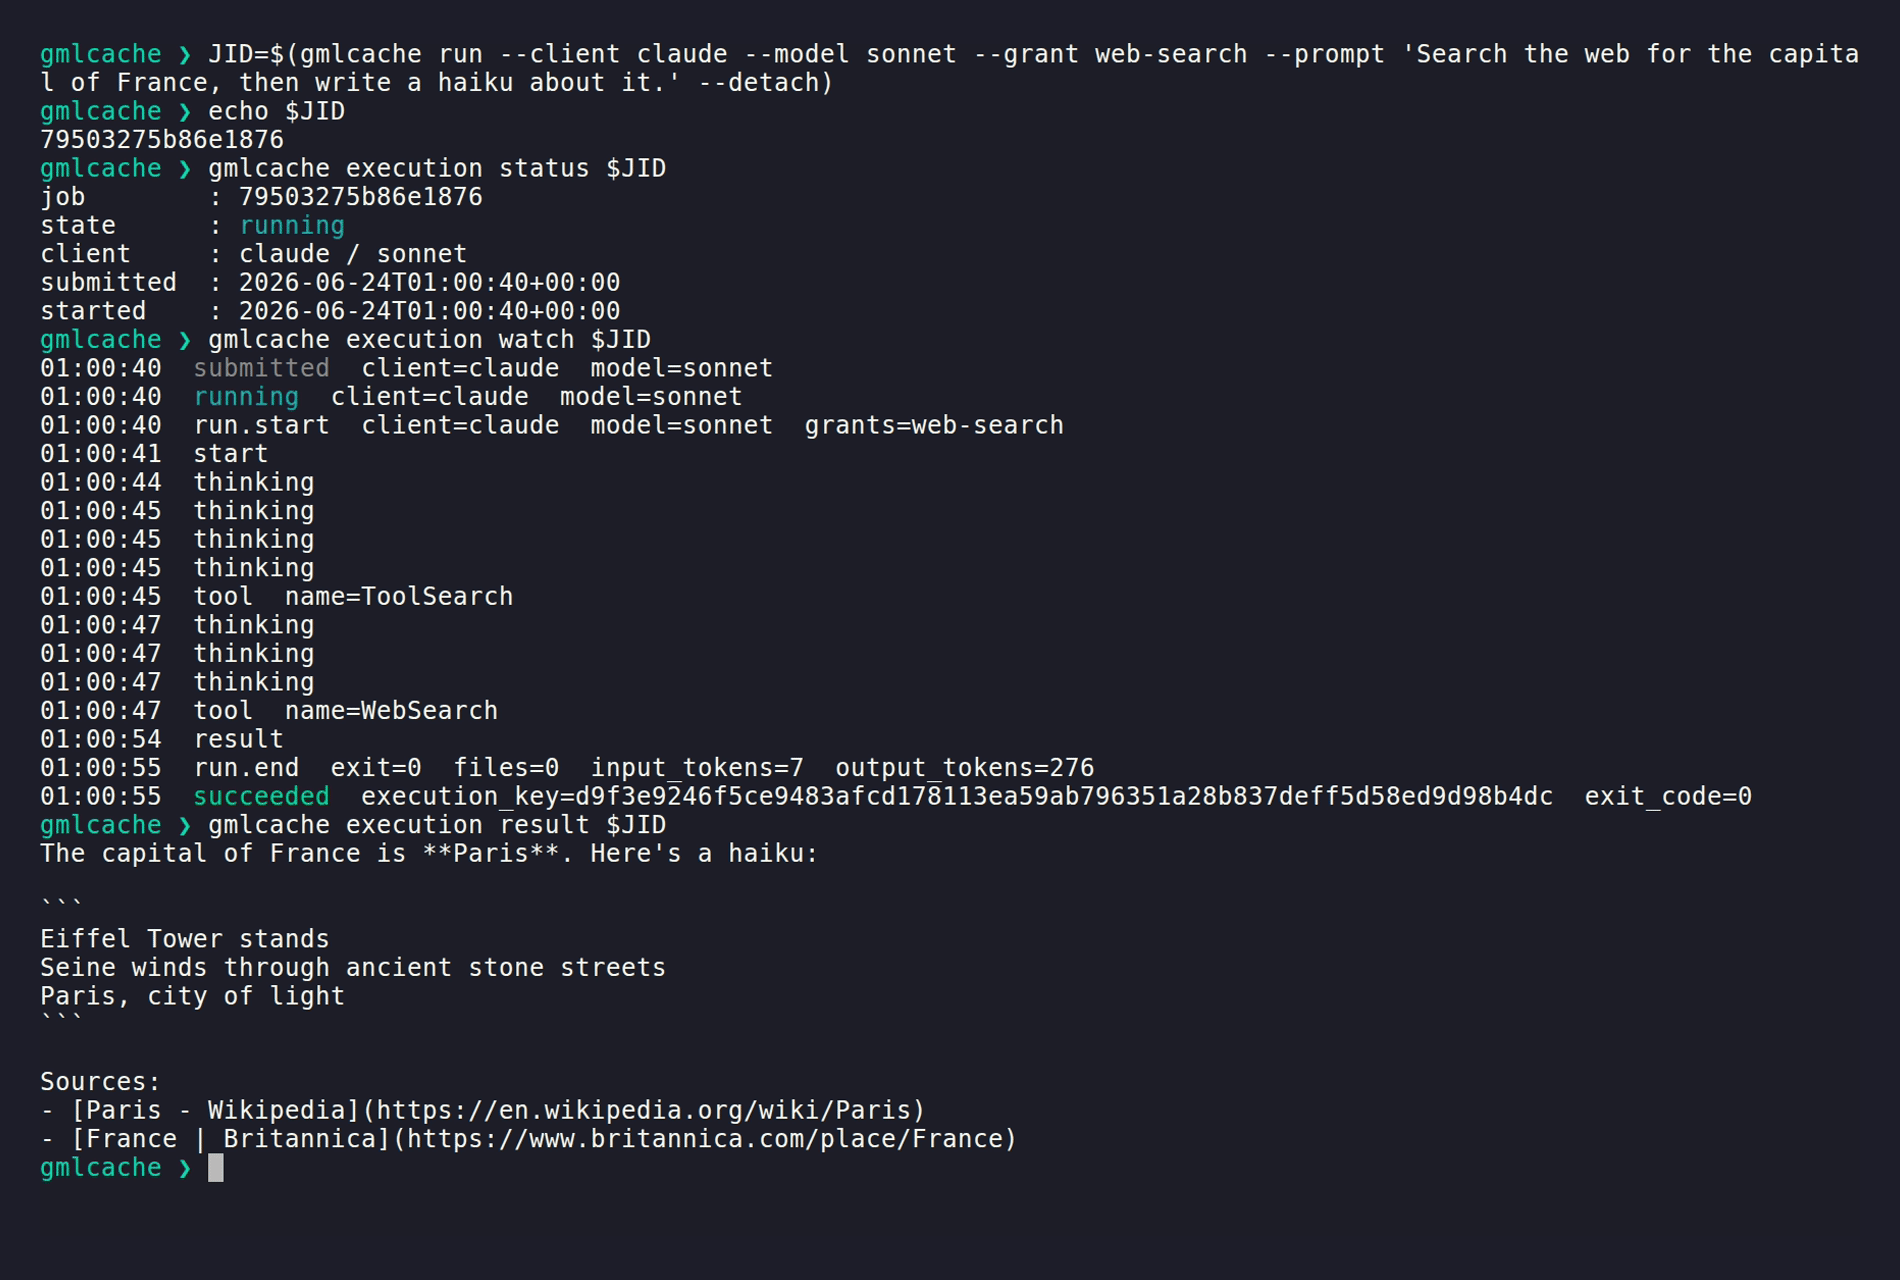
Detached + live streaming — run --detach returns an id; execution watch follows the client's live progress to the result
Install
pip install generic-ml-cache-cli
This installs the gmlcache command and pulls in the engine,
generic-ml-cache-core.
Use
gmlcache run    --client claude --model sonnet --prompt "…"            # record on a miss, replay on a hit
gmlcache check  --client claude --model sonnet --prompt "…"            # forecast: is this exact call cached?
gmlcache run    --client claude --model sonnet --prompt "…" --detach   # run detached → prints an execution id
gmlcache alias  claude -- -p "…" --model sonnet                        # thin wrapper: cache a raw native call
gmlcache execution watch <id>                                         # follow a detached run's live progress
gmlcache session report <id>                                          # token usage by provider/model for a workflow
gmlcache encrypt                                                      # encrypt the whole store at rest
gmlcache export --tag eval -o data.jsonl                              # export the (input, output) dataset corpus
gmlcache list | tags | stats | inspect <key>                          # browse stored executions
gmlcache doctor | models | status | init                             # environment & configuration helpers
What it does
- Records a real agentic CLI client (
claude,codex,cursor-agent) or an API call — stdout, stderr, exit code, generated files, and token usage. - Replays an identical request instantly and offline, byte-for-byte — gmlcache adds nothing to the client's output, so it is a transparent drop-in.
- Reports — list, group, inspect, and measure stored executions and their savings.
- And more — group a workflow's runs into sessions with per-provider/model usage
reports, encrypt the whole store at rest, run detached (
--detach) with a live progress stream, and export an(input, output)dataset.
Built on a reusable engine
gmlcache is the terminal client — one inbound driver over the engine. The whole cache
logic and every adapter live in
generic-ml-cache-core,
a stateless library. To embed the cache in your own application
instead of driving it from a terminal, depend on the core and inject your own data
source — you never reimplement the adapters.
Links
- Repository & docs: https://github.com/danielslobozian/generic-ml-cache
- Changelog (both packages, versioned in lockstep):
CHANGELOG.md - Security policy:
SECURITY.md
License
1 maintainer

Release files for generic-ml-cache-cli 0.11.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| generic_ml_cache_cli-0.11.0.tar.gz | 56.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| generic_ml_cache_cli-0.11.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 95.0 kB
Release files / generic_ml_cache_cli-0.11.0.tar.gz
| Download URL | generic_ml_cache_cli-0.11.0.tar.gz |
|---|---|
| Size | 56.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
0357f62aac820d9a3a1246f1f4a187554770bd2f7e0d3a634bd2ae1a2e50109b
|
|
BLAKE2b-256 checksum How to use checksums |
1b63c29731e63a32ba5ab9ef47a91ed1558bfedfbcddf5f9b8129ef4c33b9c58
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 25, 2026.
Transparency logRelease files / generic_ml_cache_cli-0.11.0-py3-none-any.whl
| Download URL | generic_ml_cache_cli-0.11.0-py3-none-any.whl |
|---|---|
| Size | 39.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
57a37e919bb3be633541c413f67aa1b660e128ca80fe6d6e04c922c4537cc33d
|
|
BLAKE2b-256 checksum How to use checksums |
75530b8ebc09f8ca79afee337e38c30e683567a93af7129a14cd6bf3d70b92ad
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 25, 2026.
Transparency log













