
Detached ML Execution Cache — the terminal client


gmlcache runs, records, and replays detached ML workloads — record a real client (or API)
call once, replay it forever by its content key, offline and byte-for-byte.
Single-user, local — not a gateway. gmlcache runs on your machine, as you, across the subscriptions and APIs you already hold. It is not a multi-user router and not a way to share one subscription — see Positioning.
Install
pip install generic-ml-cache-cli          # gmlcache command + the engine
pip install generic-ml-cache-daemon       # optional: HTTP API (gmlcache daemon)
run and check — record and replay
run calls the real client on a miss and replays from cache on a hit.
check forecasts the result without calling anything.
gmlcache run   --client claude --model sonnet --prompt "Write a haiku about caching."
gmlcache check --client claude --model sonnet --prompt "Write a haiku about caching."
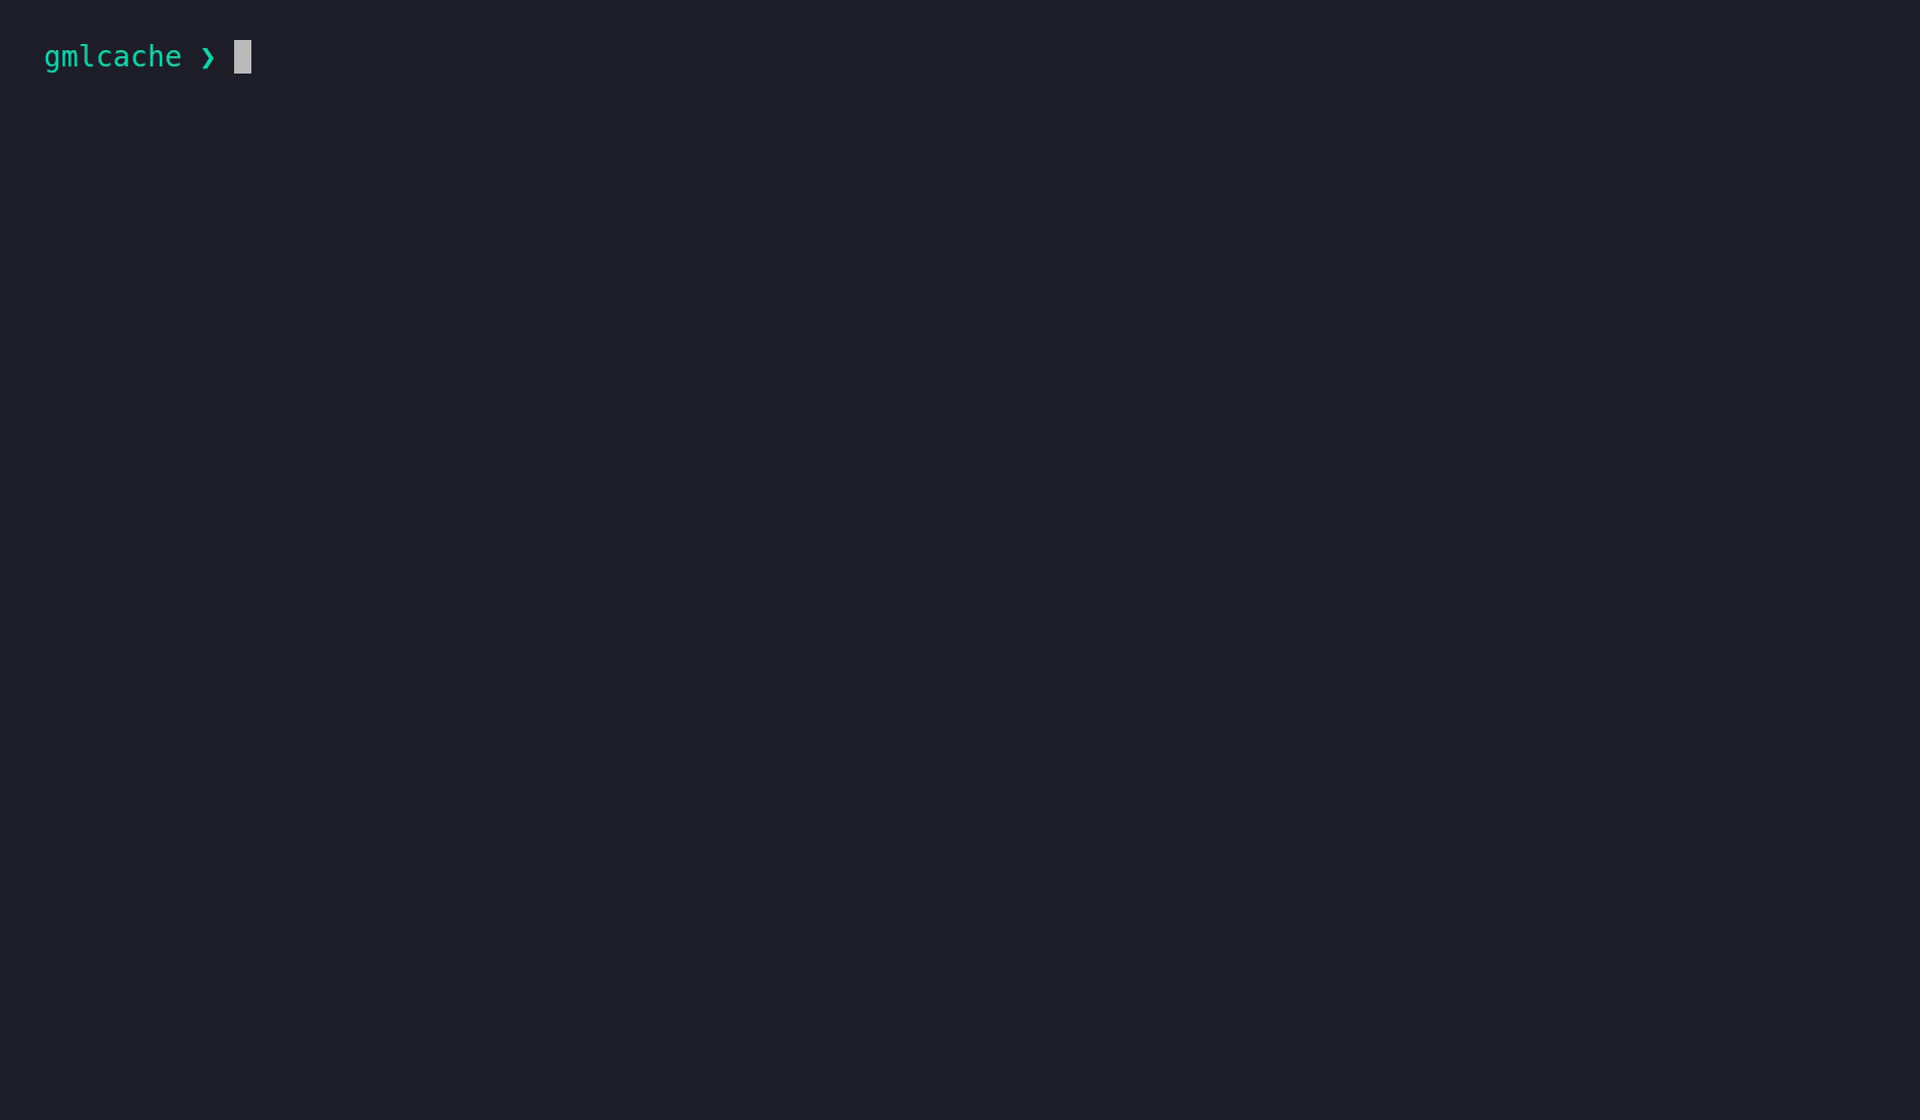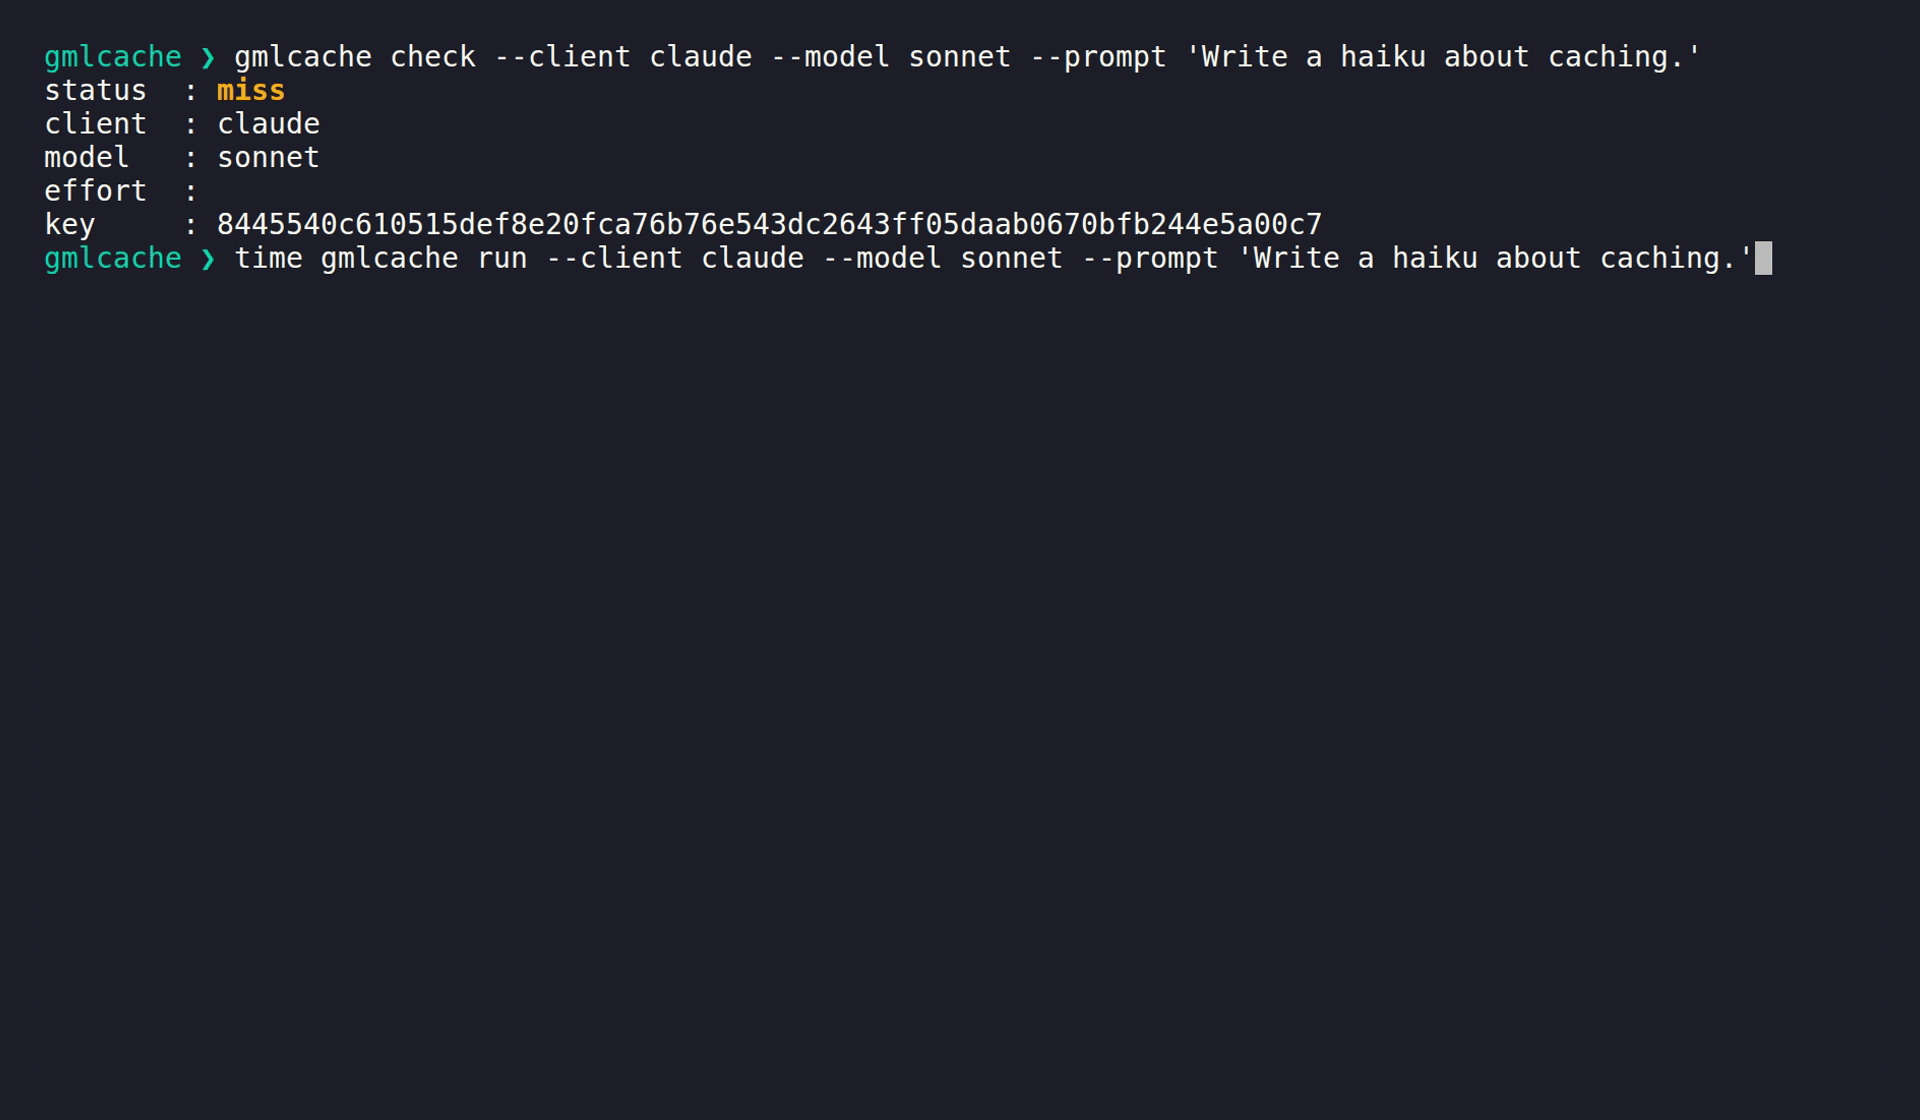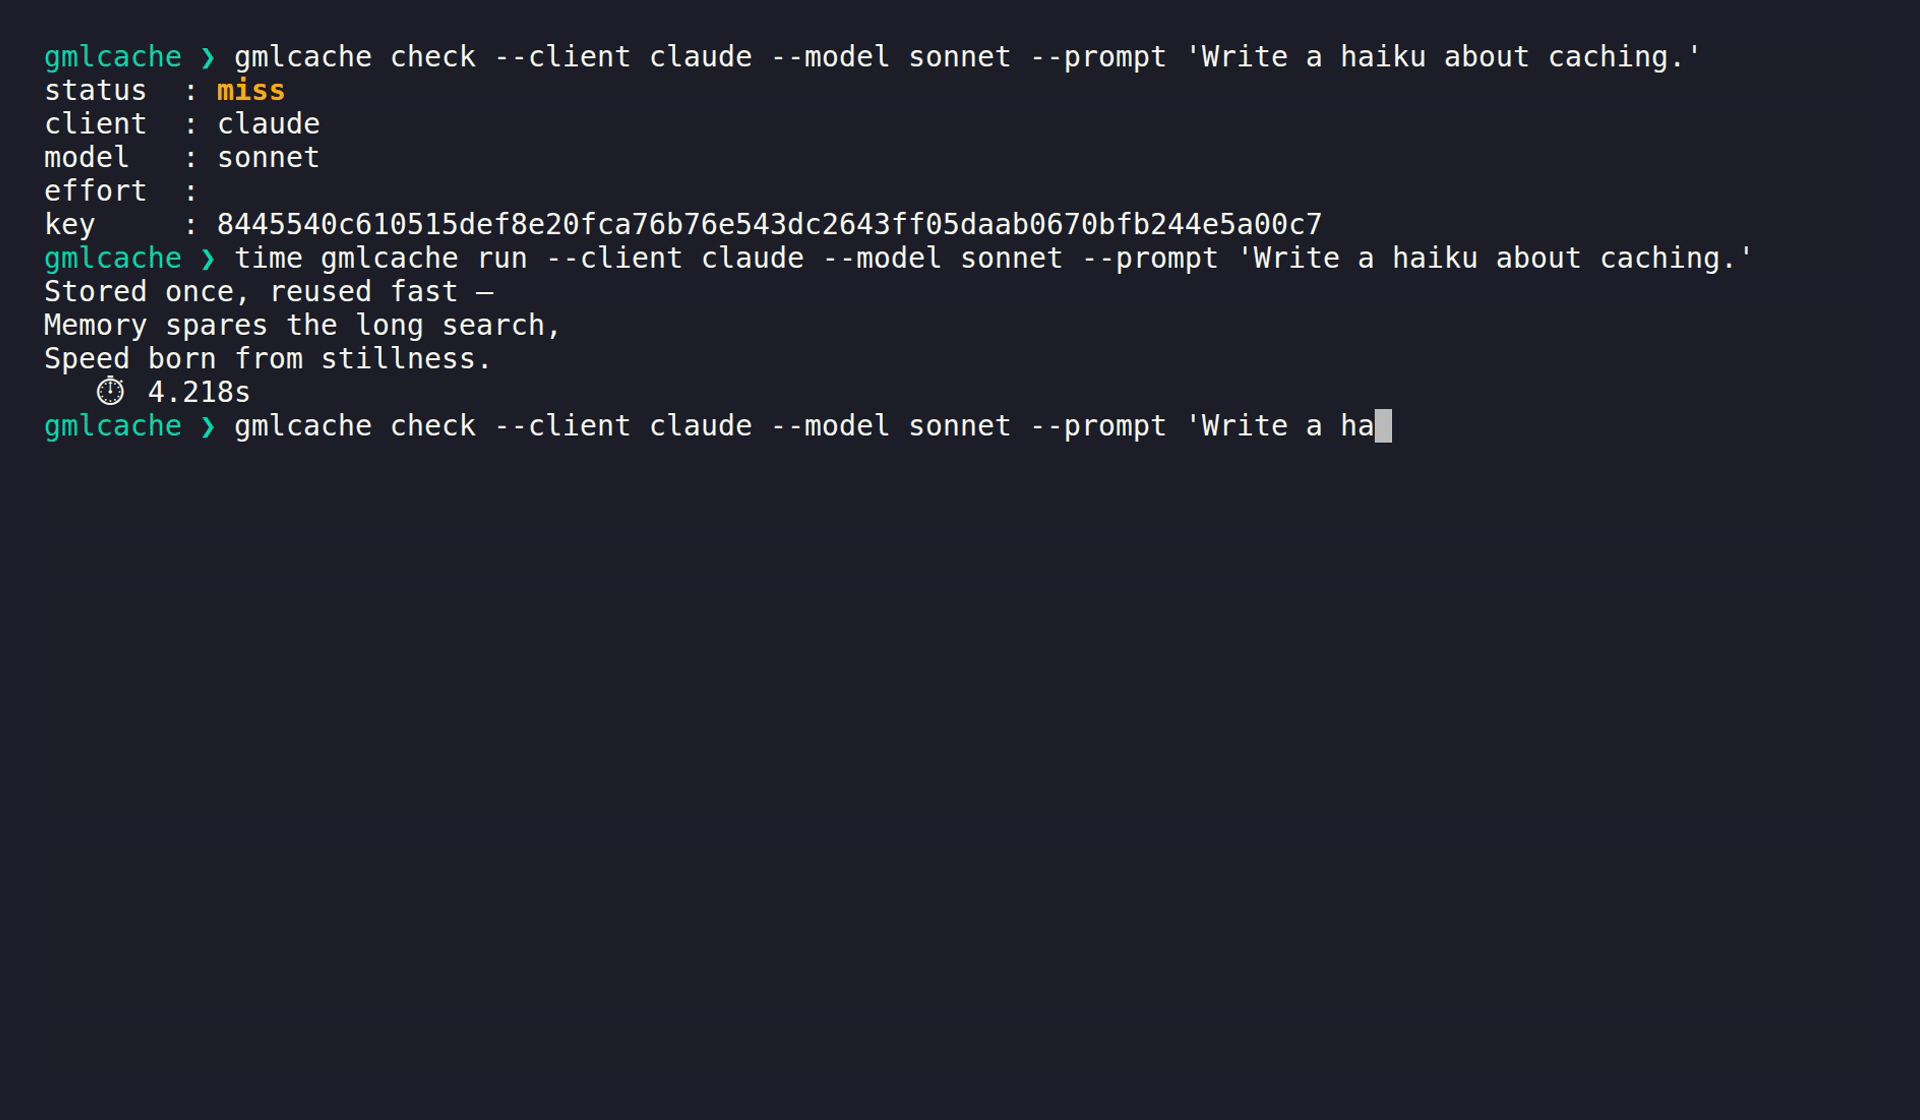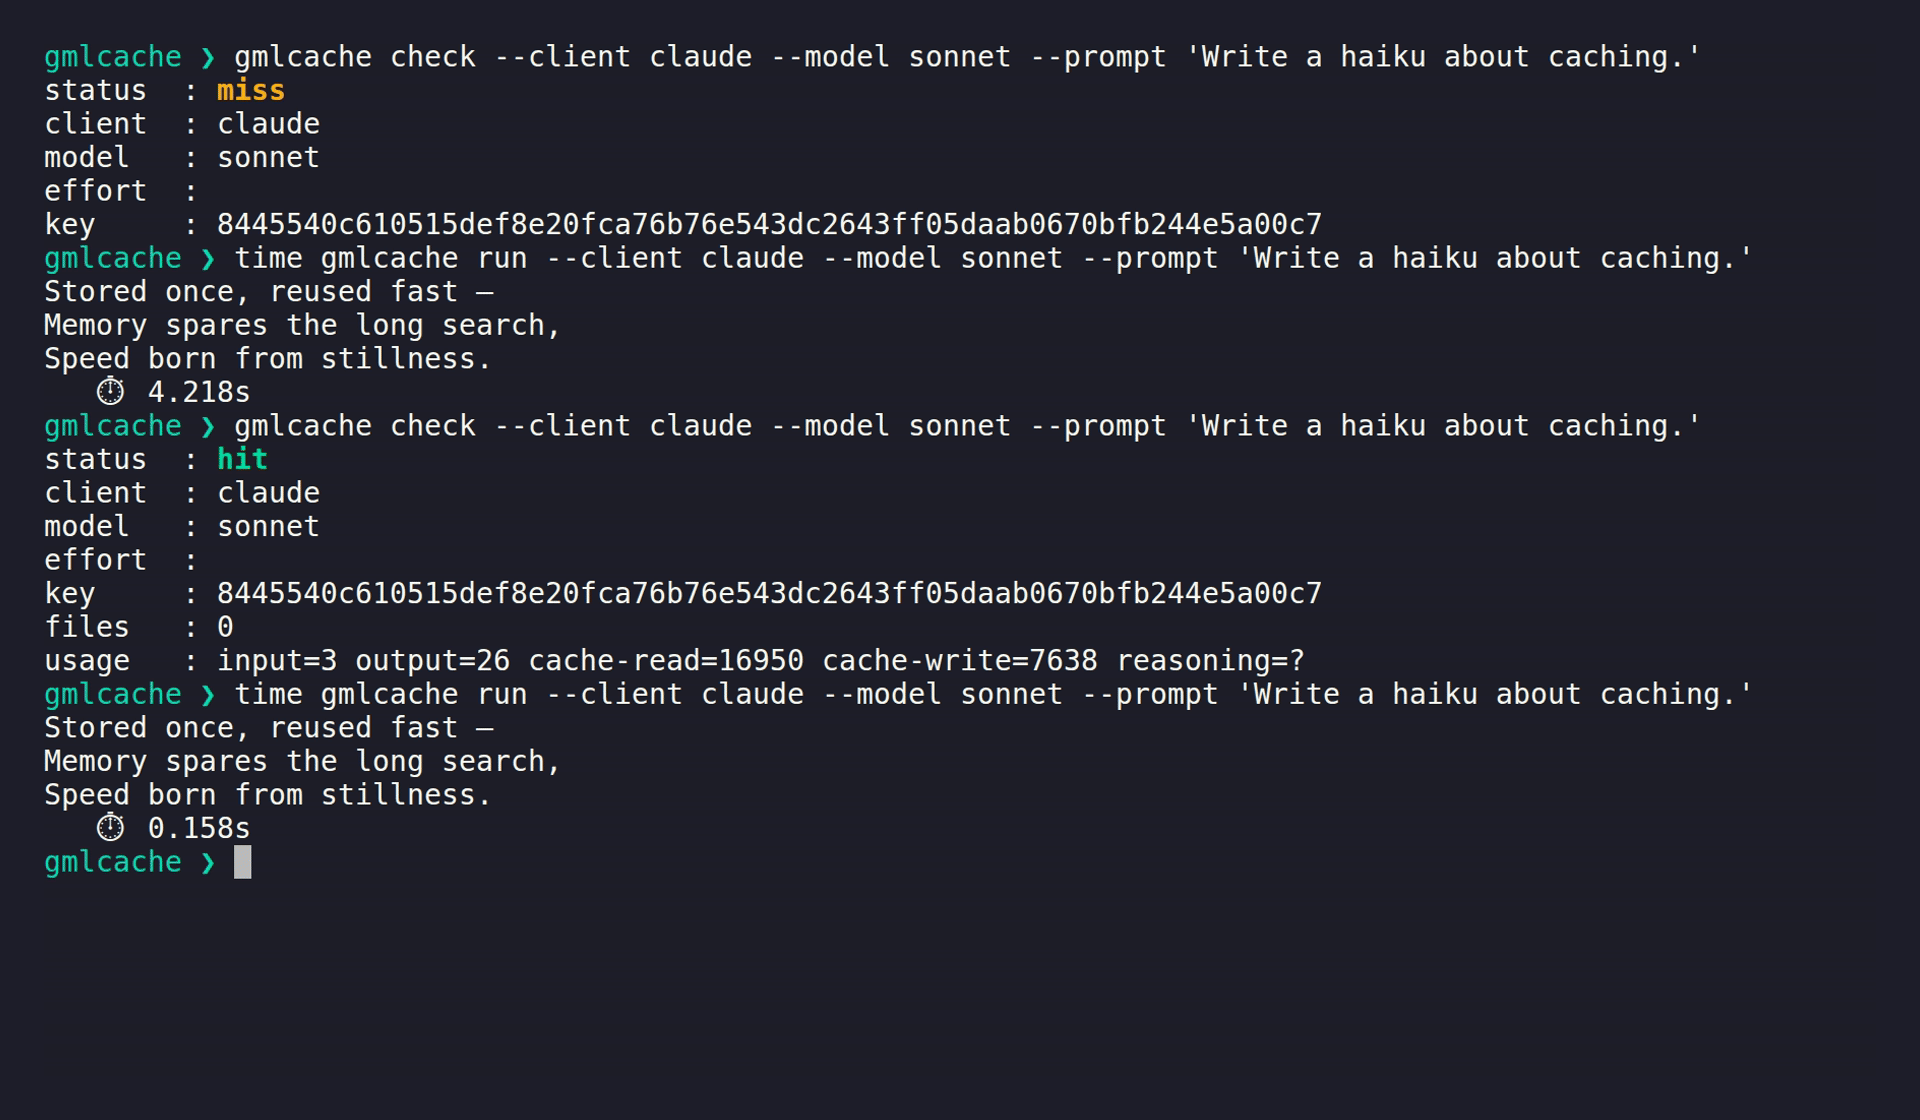
Same command twice: the first call runs the real client; the second is served from cache, instantly and byte-identical.
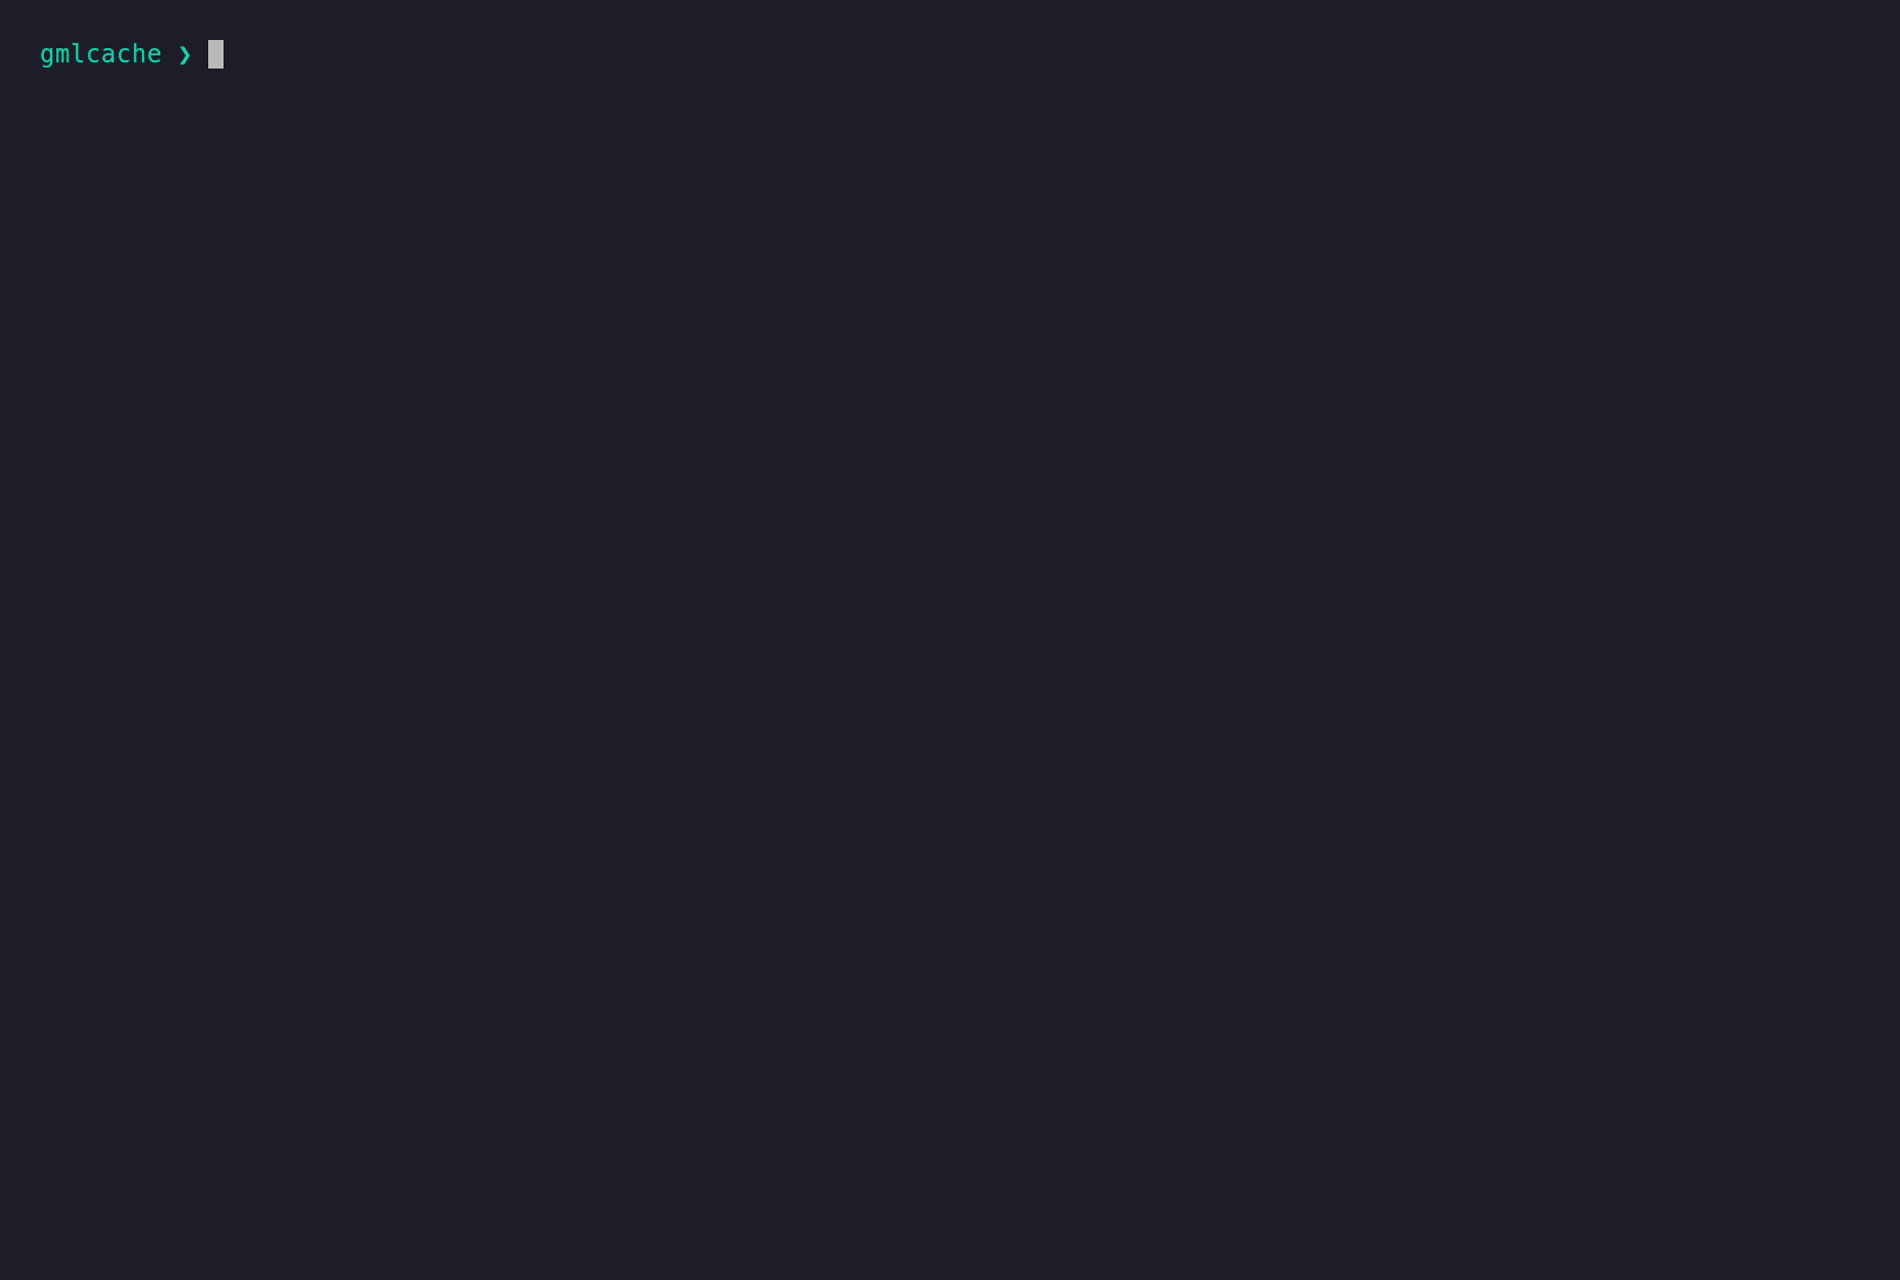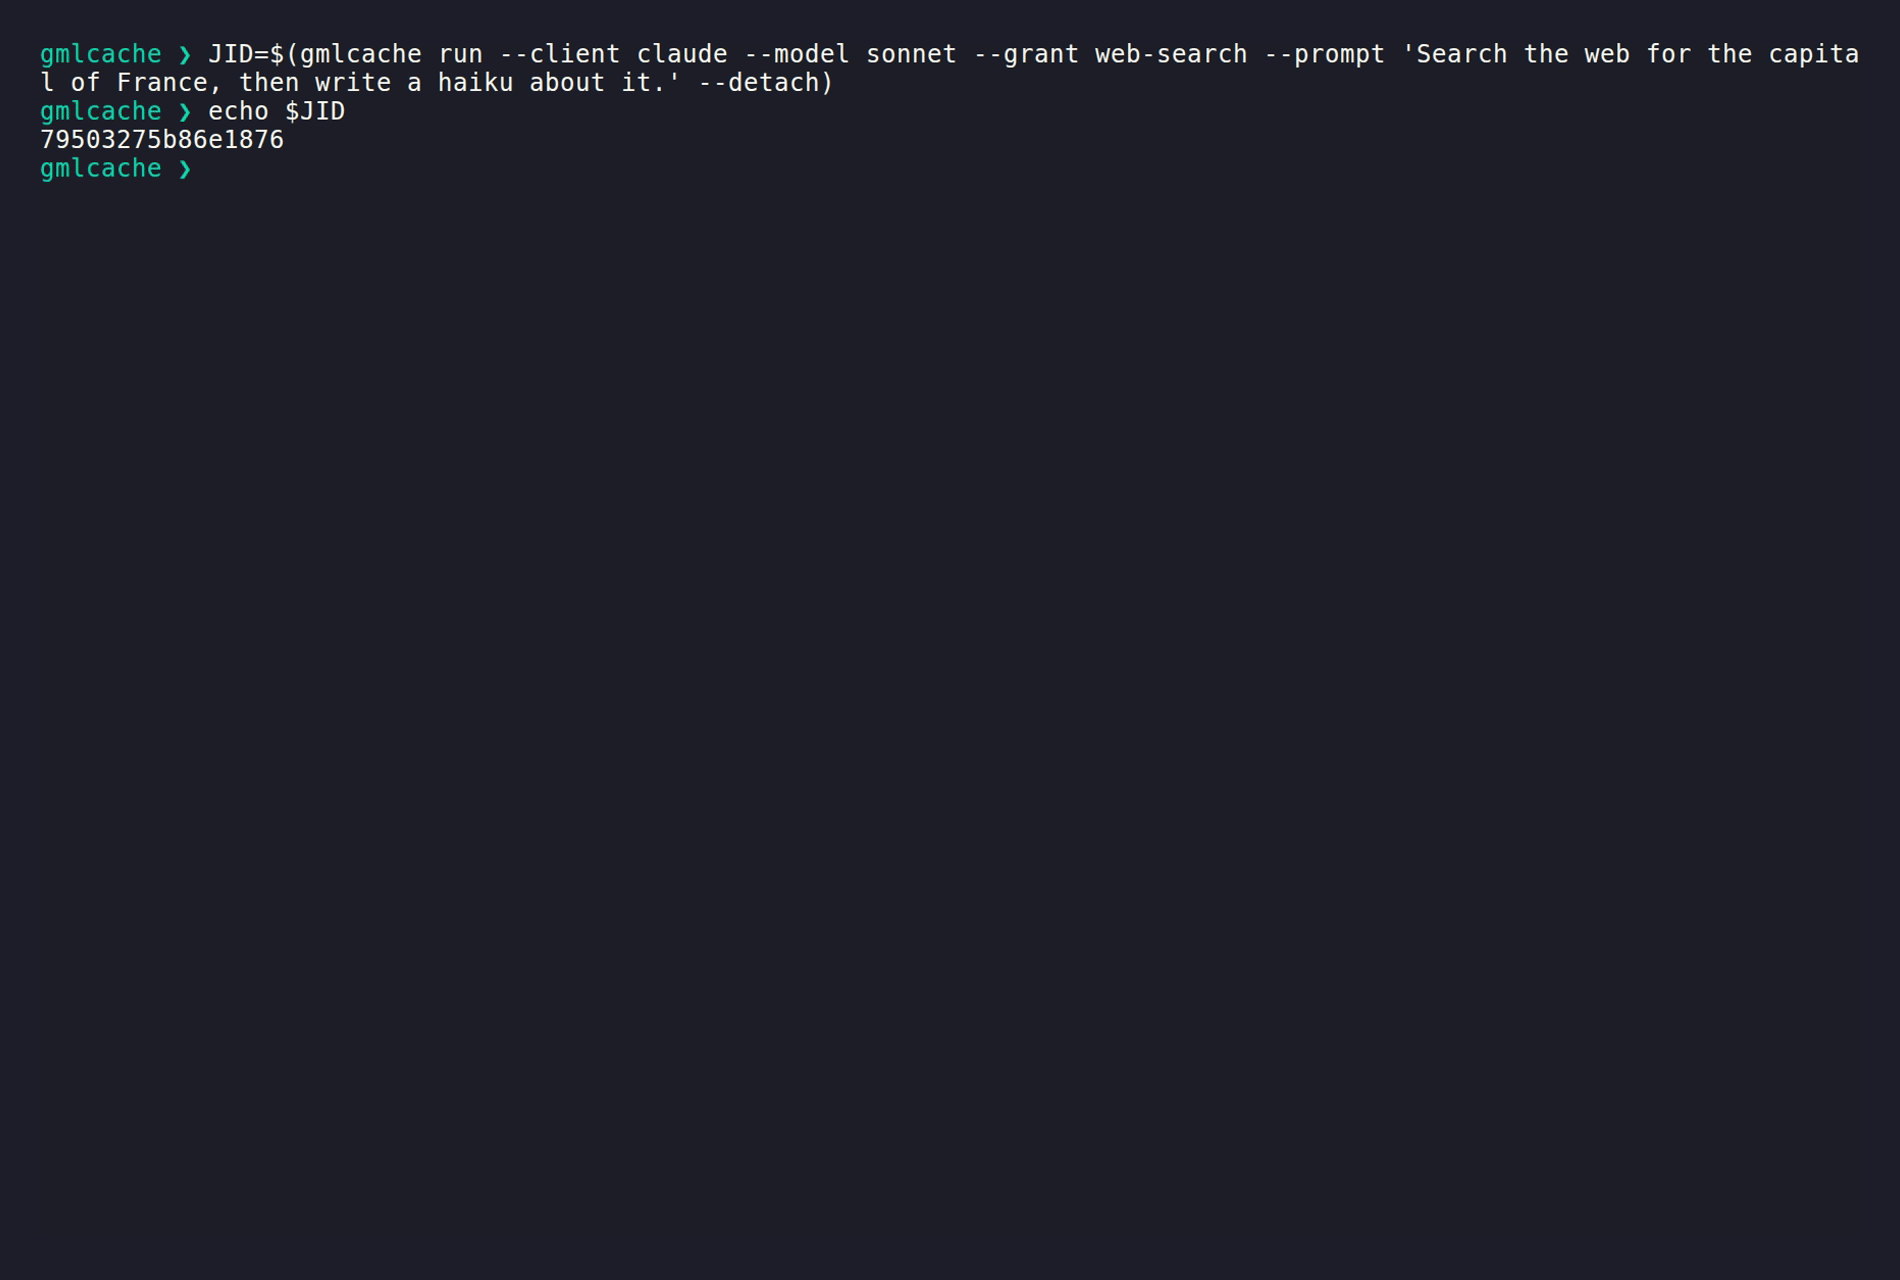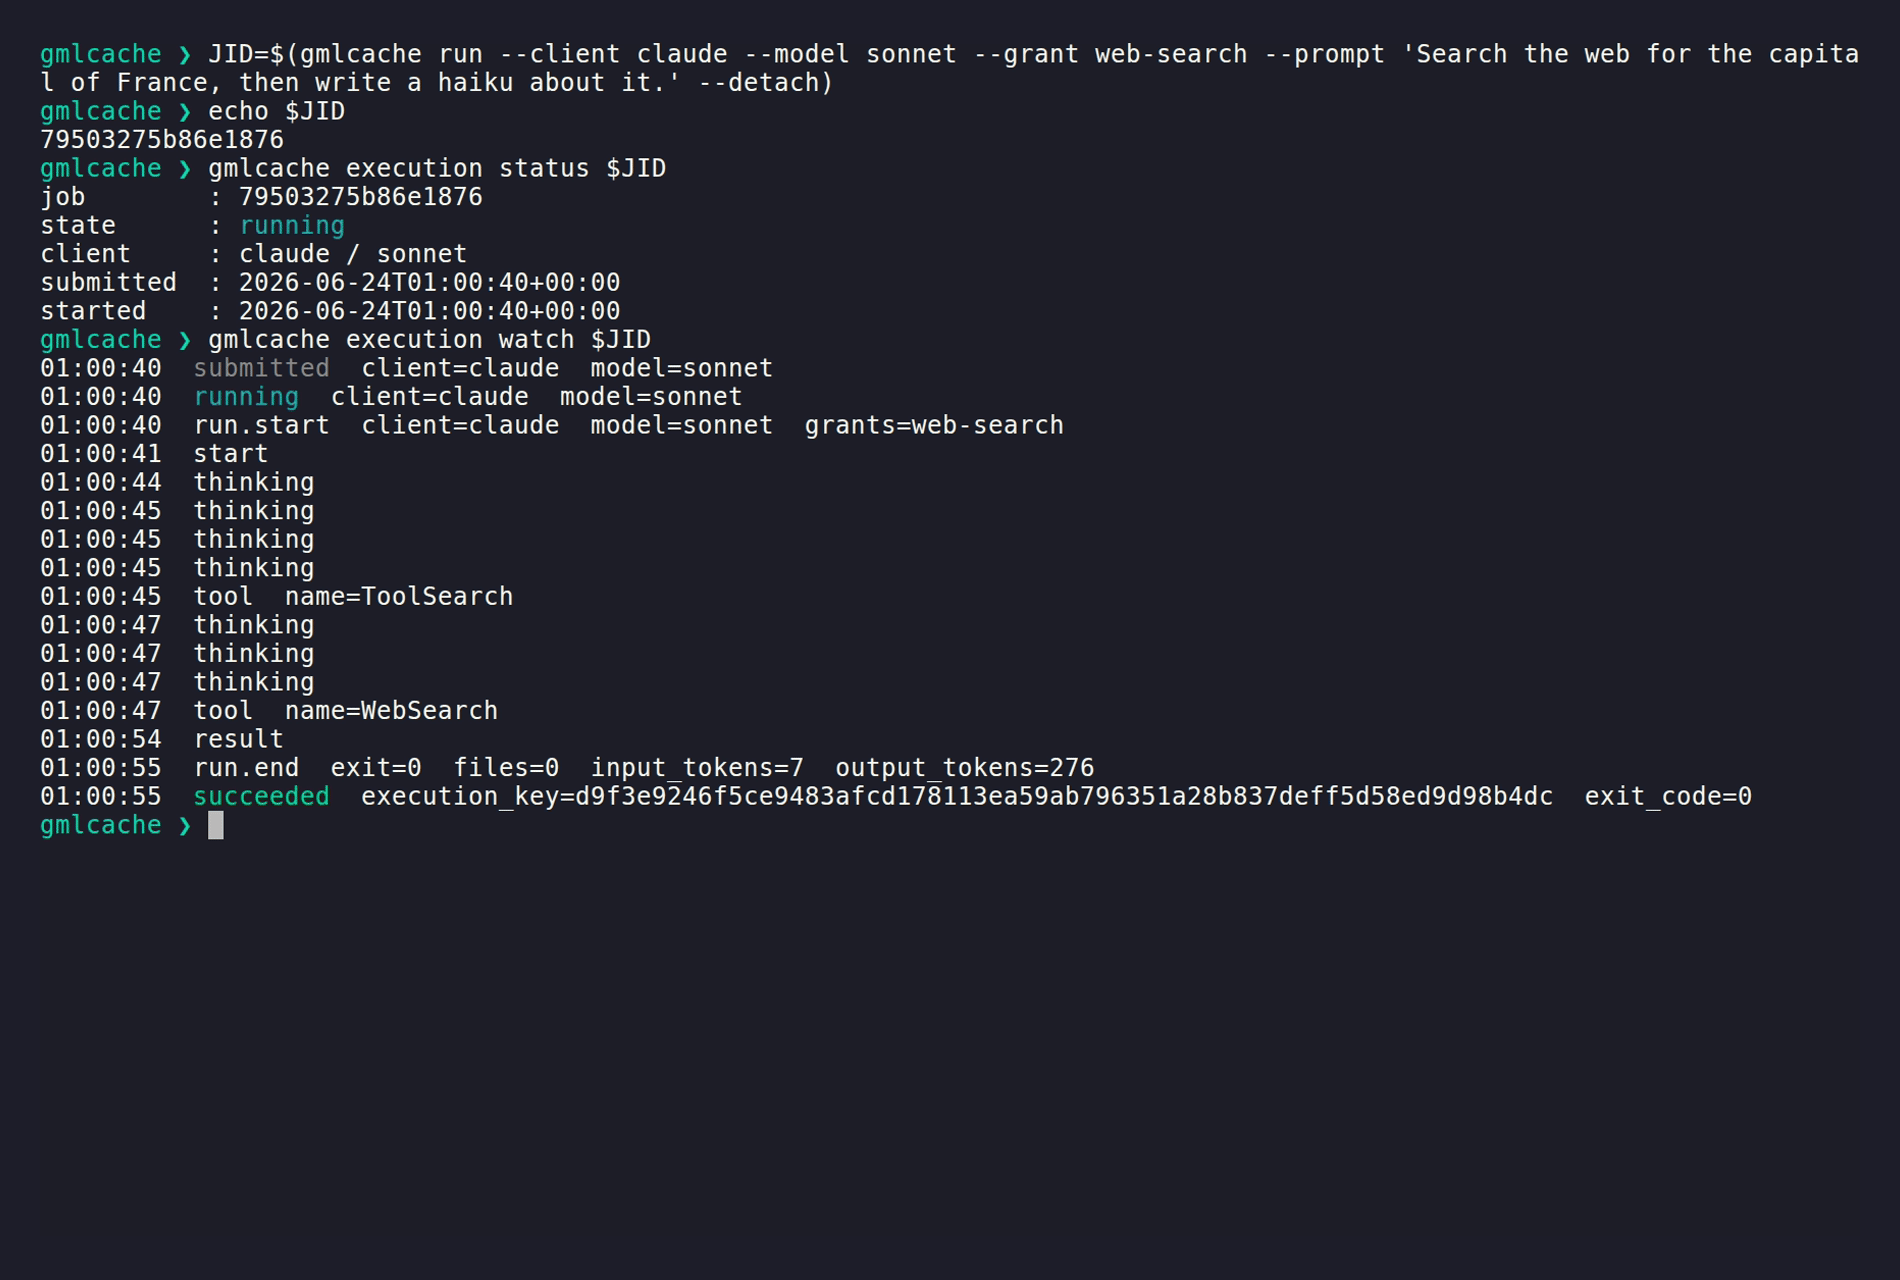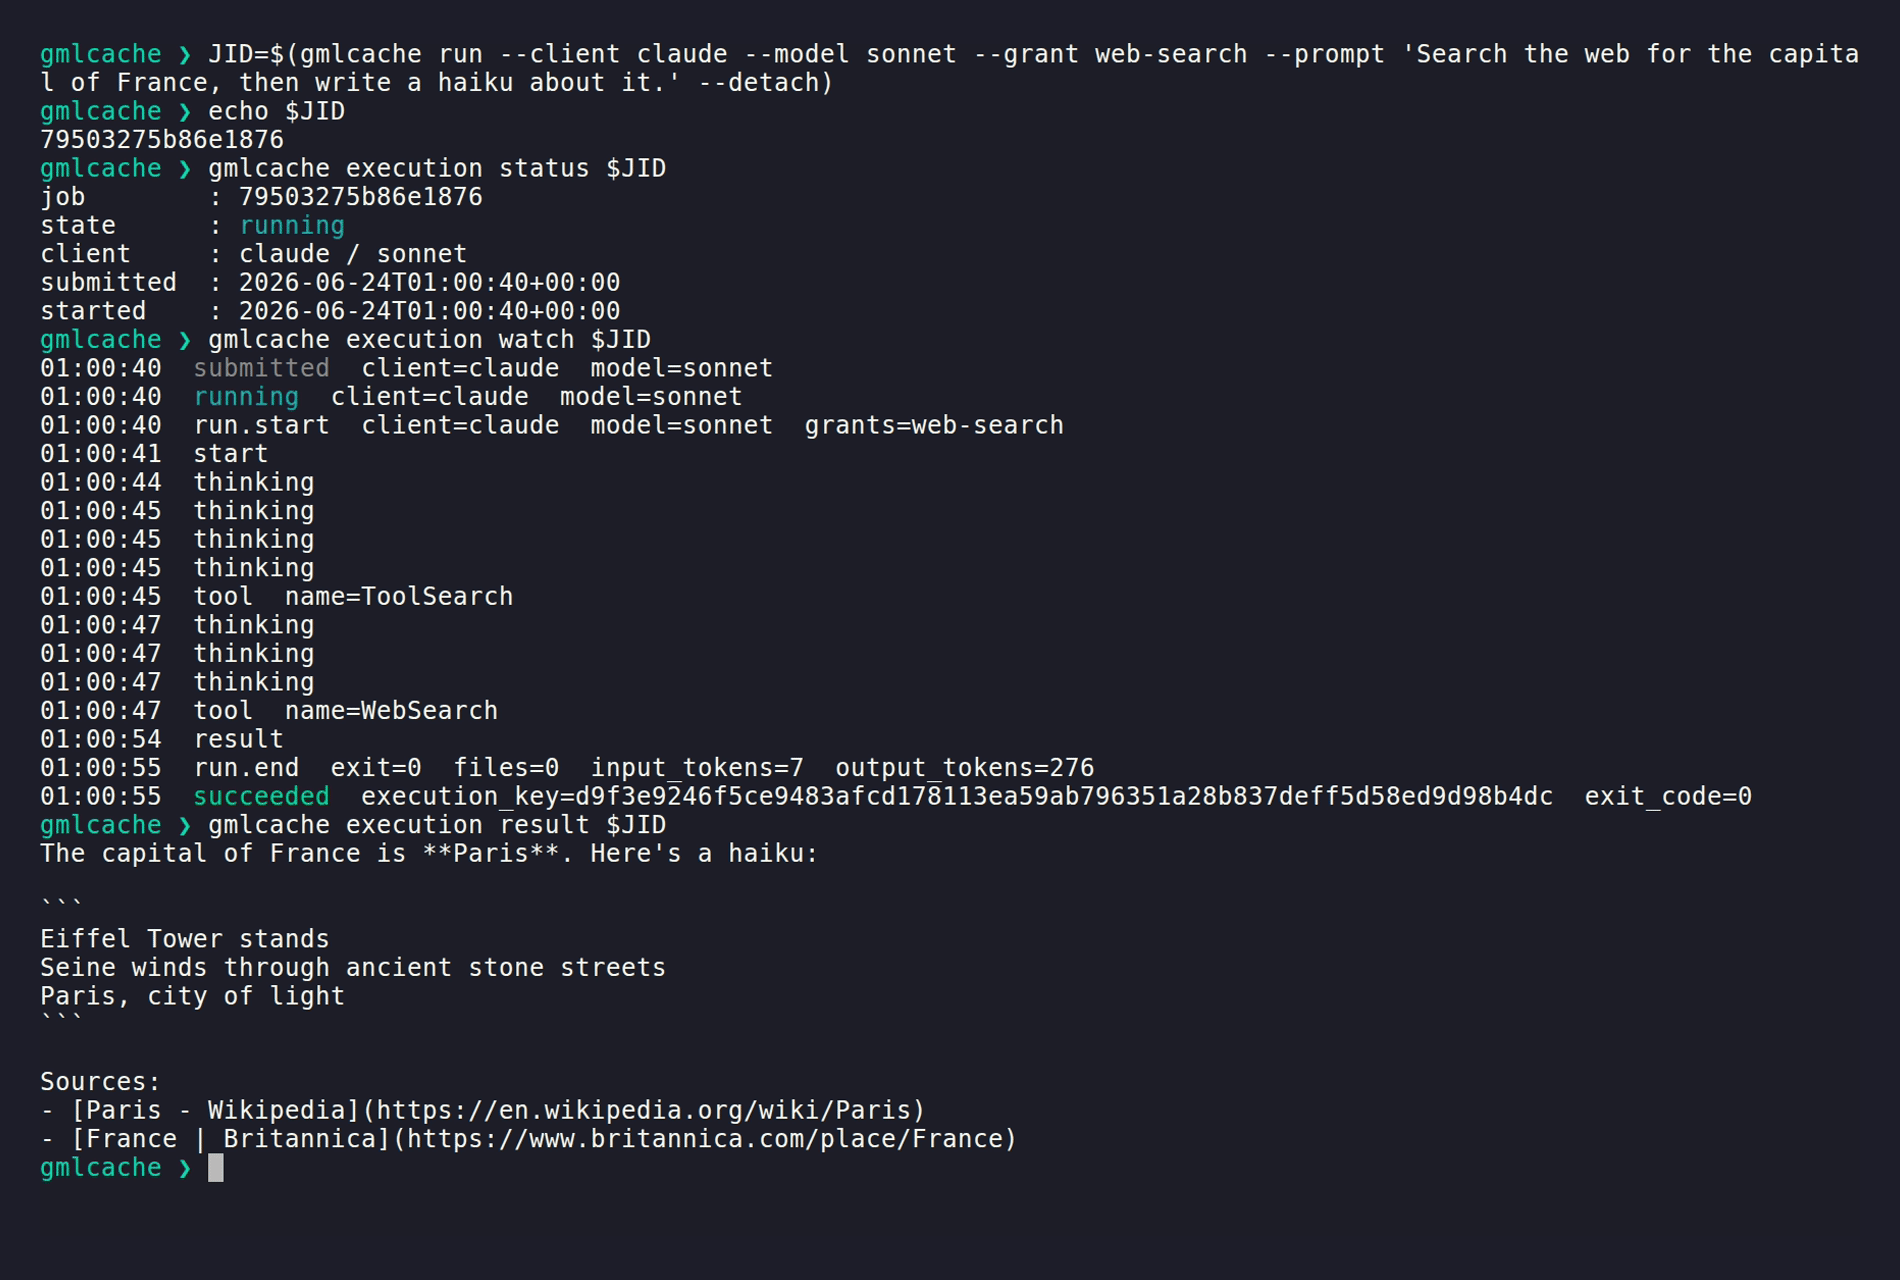
Detached executions — --detach
run --detach returns an execution id immediately.
execution watch follows the client's live progress (thinking, tool calls) to the result.
JID=$(gmlcache run --client claude --model sonnet --grant web-search \
          --prompt "Search for the capital of France and write a haiku." --detach)
gmlcache execution status $JID
gmlcache execution watch  $JID   # streams the client's live progress
gmlcache execution result $JID   # fetch the recorded result
Browse the store — list, inspect, stats, tags
Inspect what is in the cache at any time.
gmlcache list                  # all stored executions (key, client, model, state)
gmlcache list --tag tutorial   # filter by tag
gmlcache tags                  # all tags in the store
gmlcache stats                 # execution count, hit count, store size
gmlcache inspect <key>         # full detail for one execution

Sessions
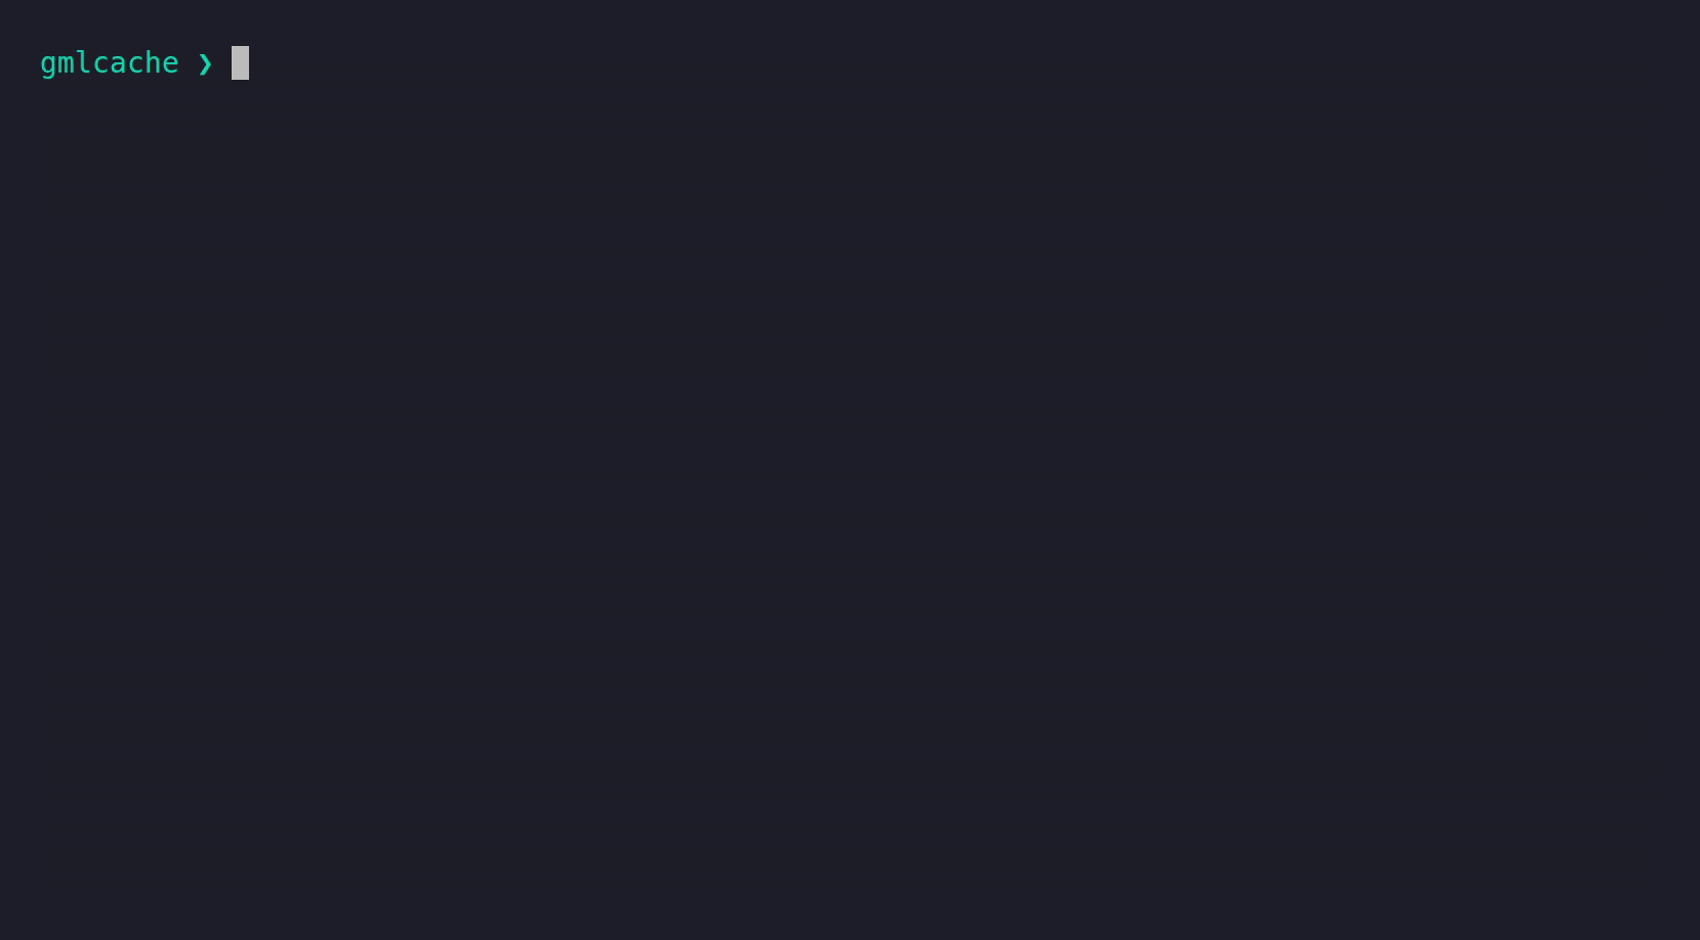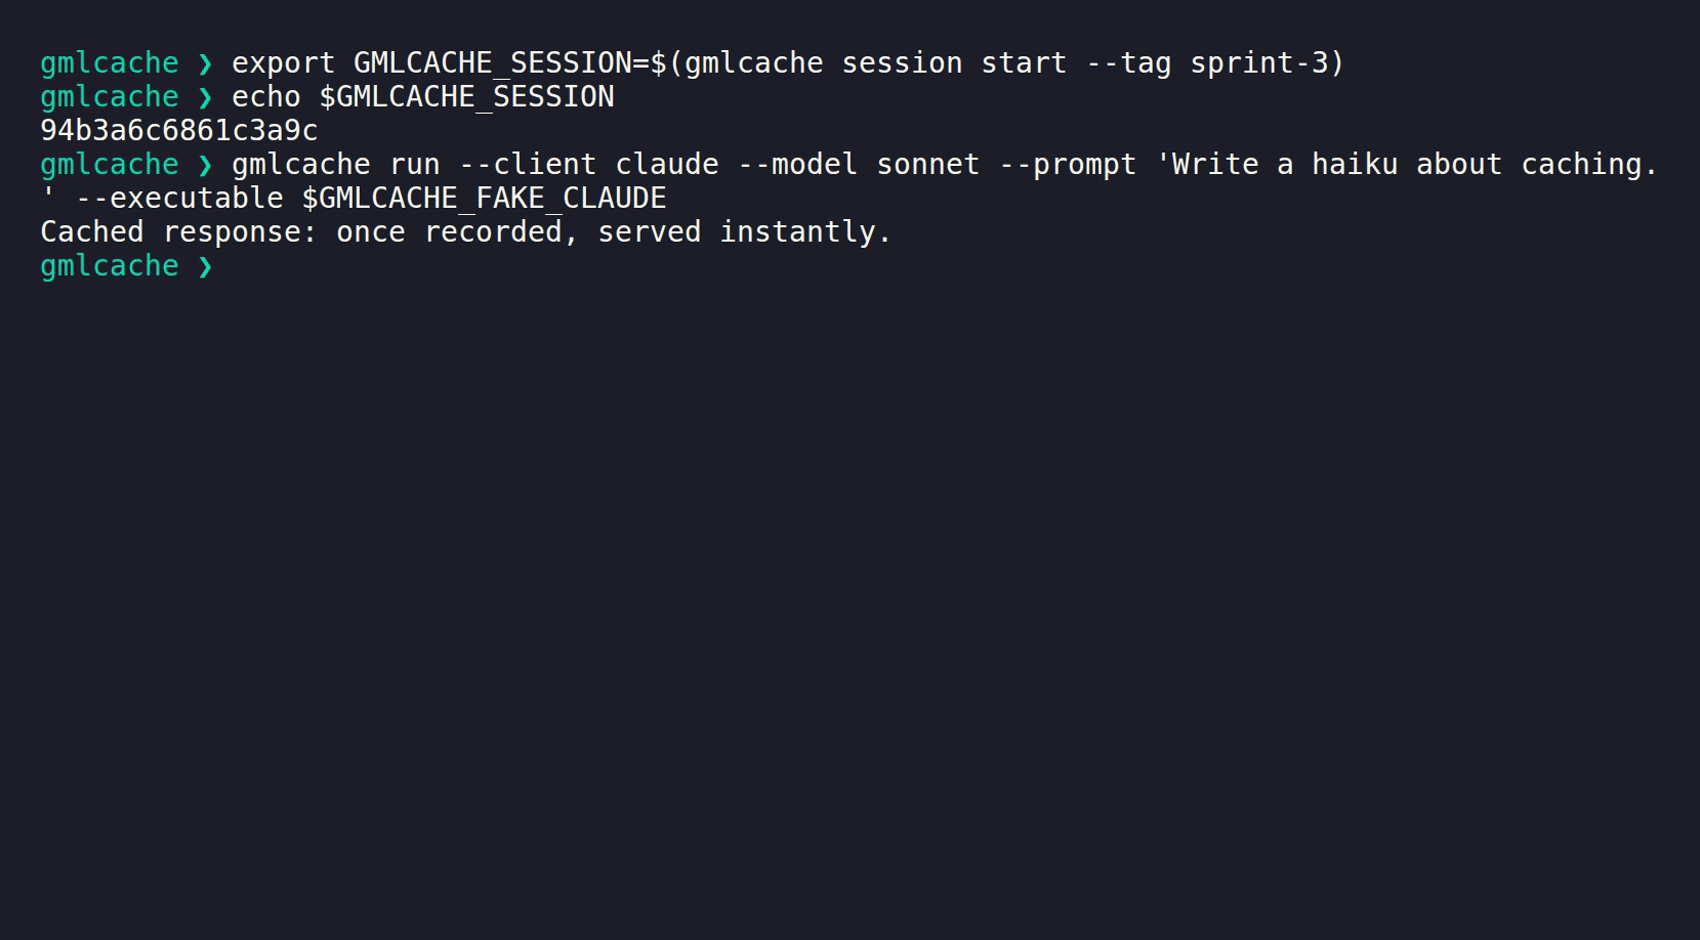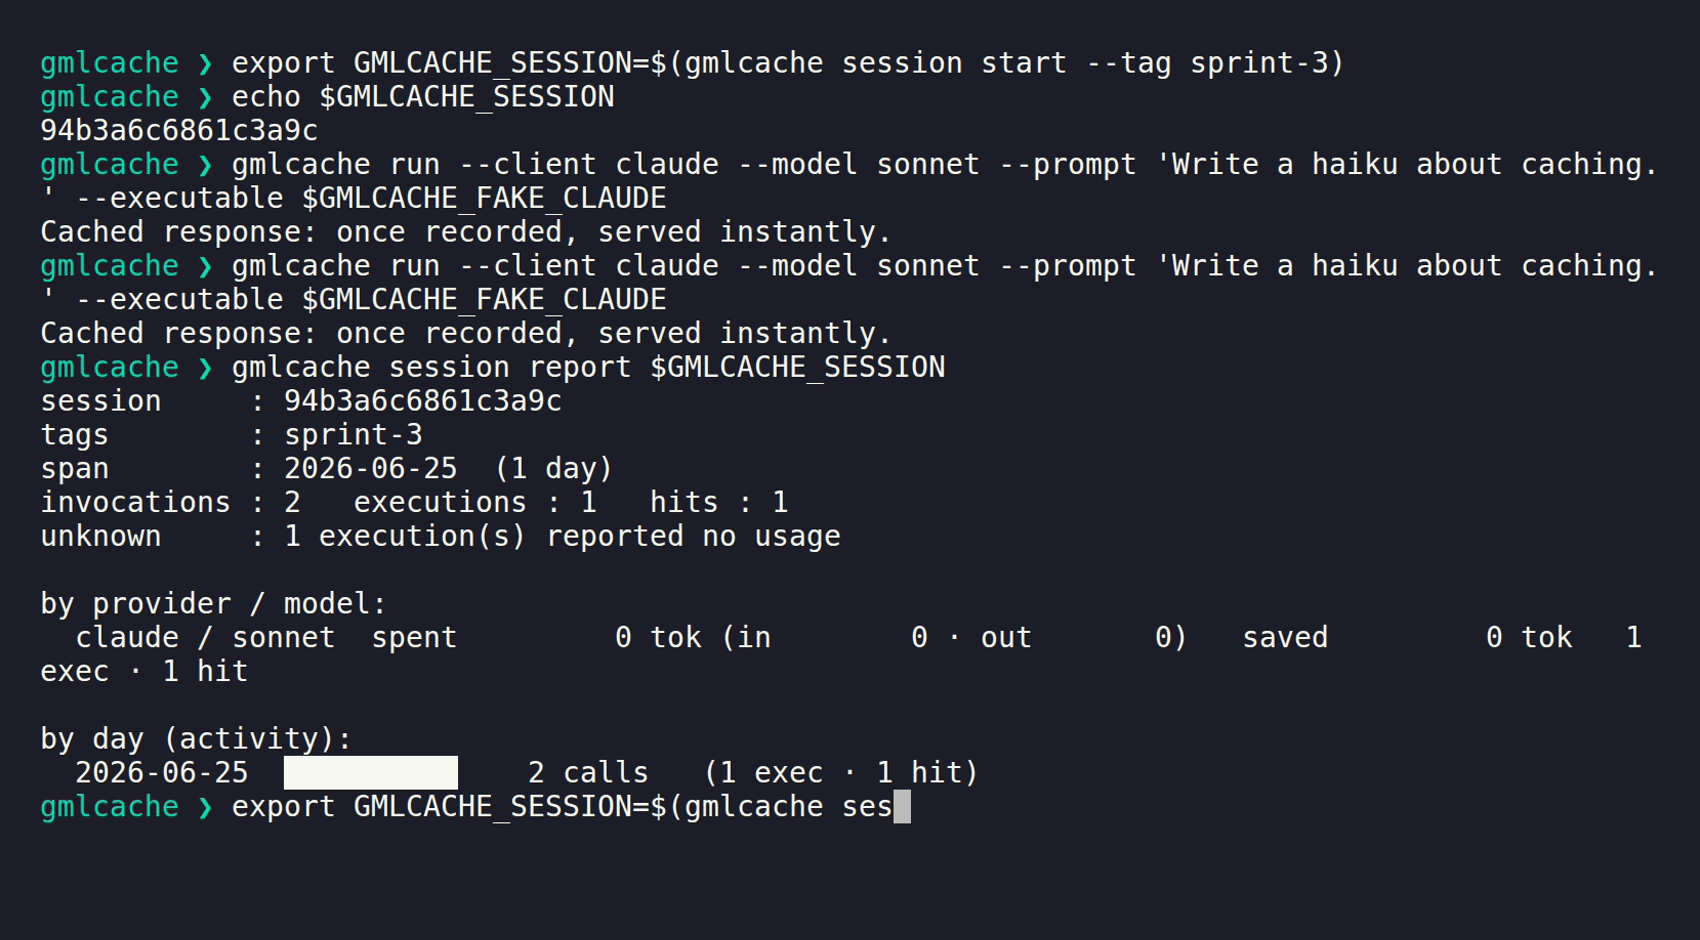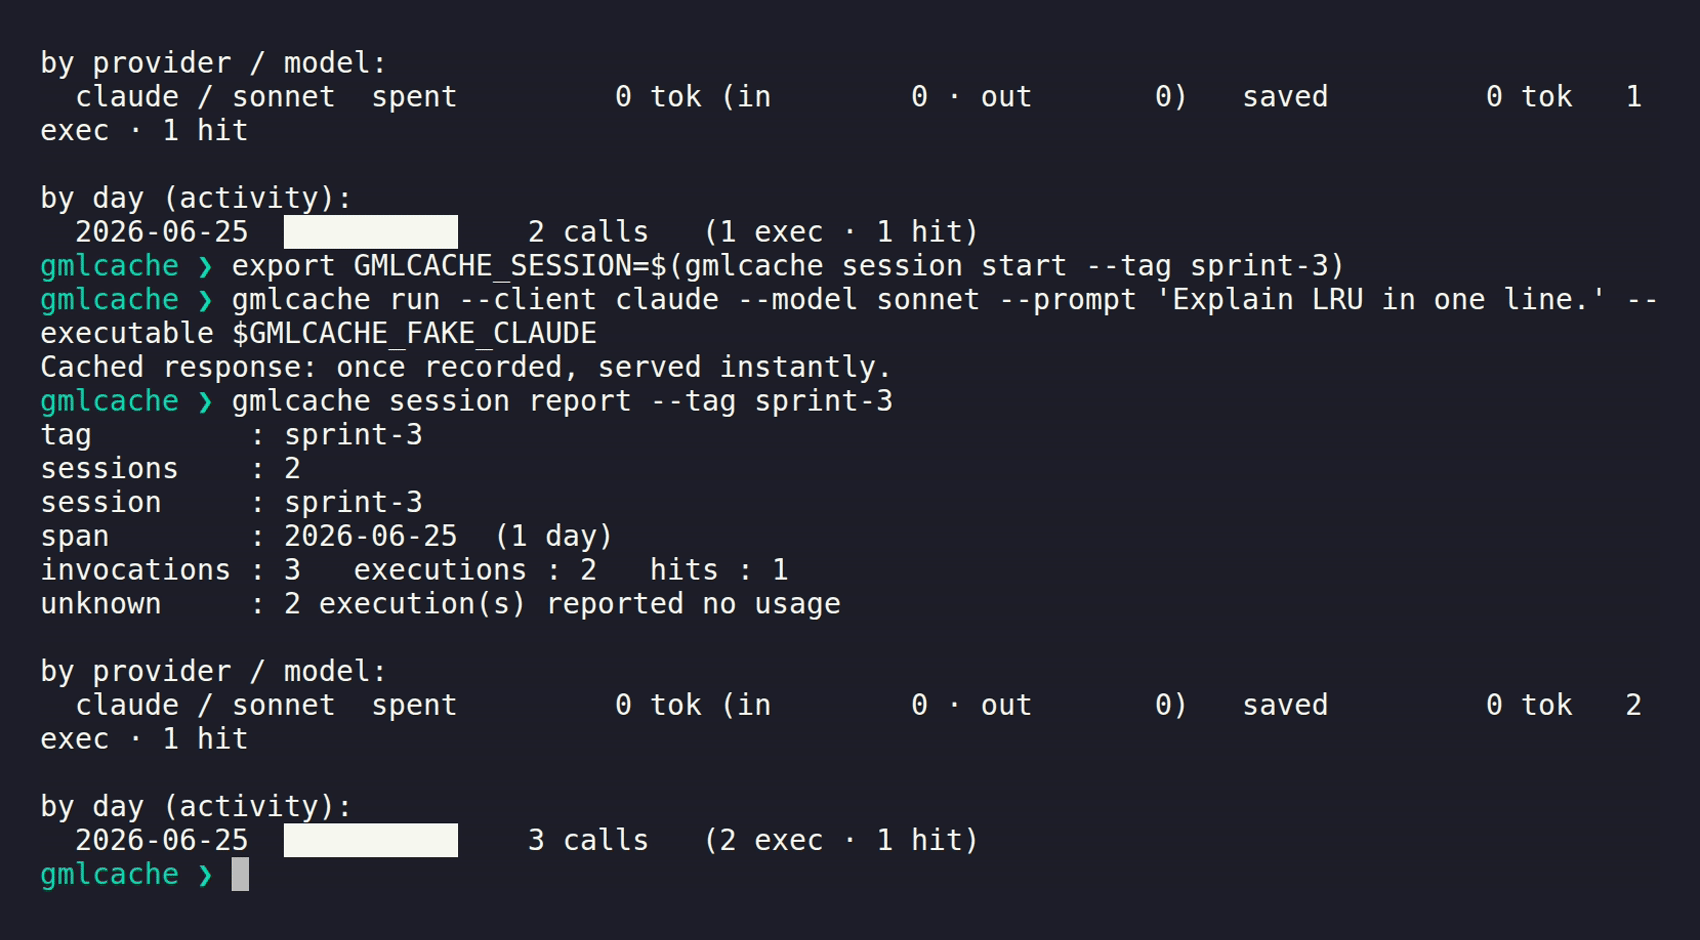
Group a workflow's runs into a named session and roll up usage by provider/model.
export GMLCACHE_SESSION=$(gmlcache session start --tag sprint-3)
gmlcache run --client claude --model sonnet --prompt "…"
gmlcache run --client claude --model sonnet --prompt "…"   # cache hit
gmlcache session report $GMLCACHE_SESSION                  # hits, tokens, cost saved
gmlcache session report --tag sprint-3                     # aggregate across all sprint-3 sessions
Session exec spec and tag management (0.13.0)
Pin an adapter, model, and effort to a session — the daemon gateway inherits it. Add and remove tags at any time.
SESSION=$(gmlcache session start --client anthropic --model claude-haiku-4-5-20251001 --effort low --tag sprint-4)
gmlcache session tag --add    $SESSION experiment   # add a tag
gmlcache session tag --remove $SESSION sprint-4     # remove a tag
gmlcache session update $SESSION --client openai --model gpt-4.1-mini --effort medium
gmlcache session clear-spec $SESSION

API adapters
Call Anthropic, OpenAI, and Gemini directly via REST — no CLI binary required.
gmlcache run --client anthropic --model claude-haiku-4-5-20251001 --prompt "What is a content-addressed cache?"
gmlcache run --client openai    --model gpt-4.1-mini              --prompt "What is a content-addressed cache?"
gmlcache run --client gemini    --model gemini-2.0-flash           --prompt "What is a content-addressed cache?"

Purge
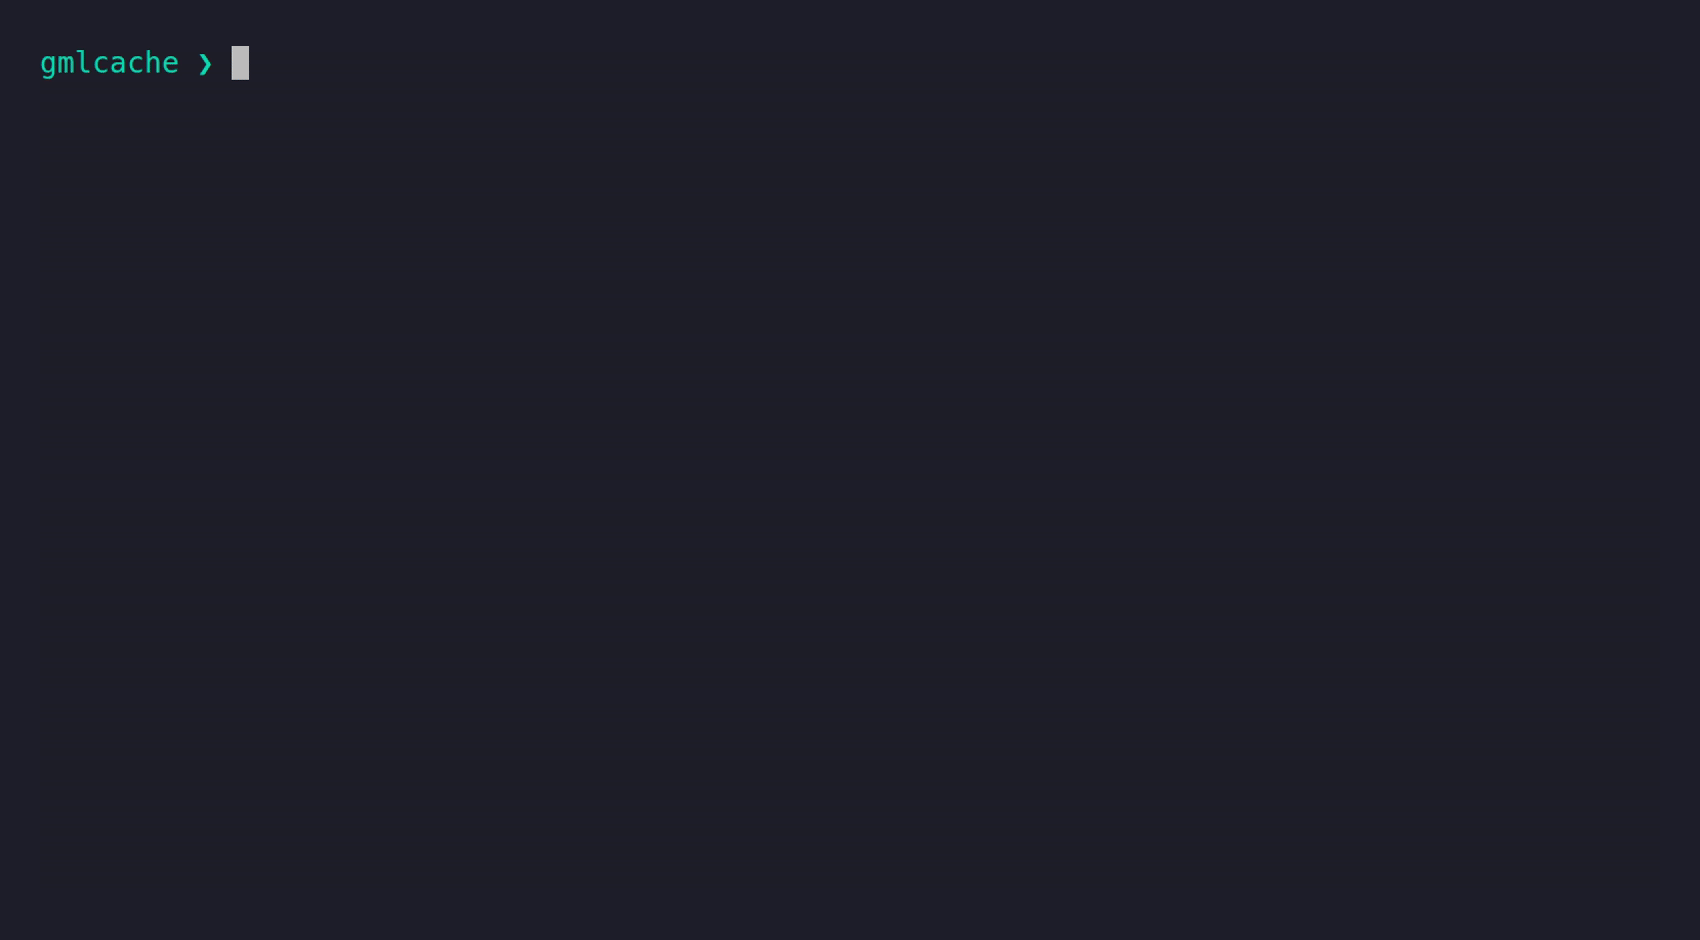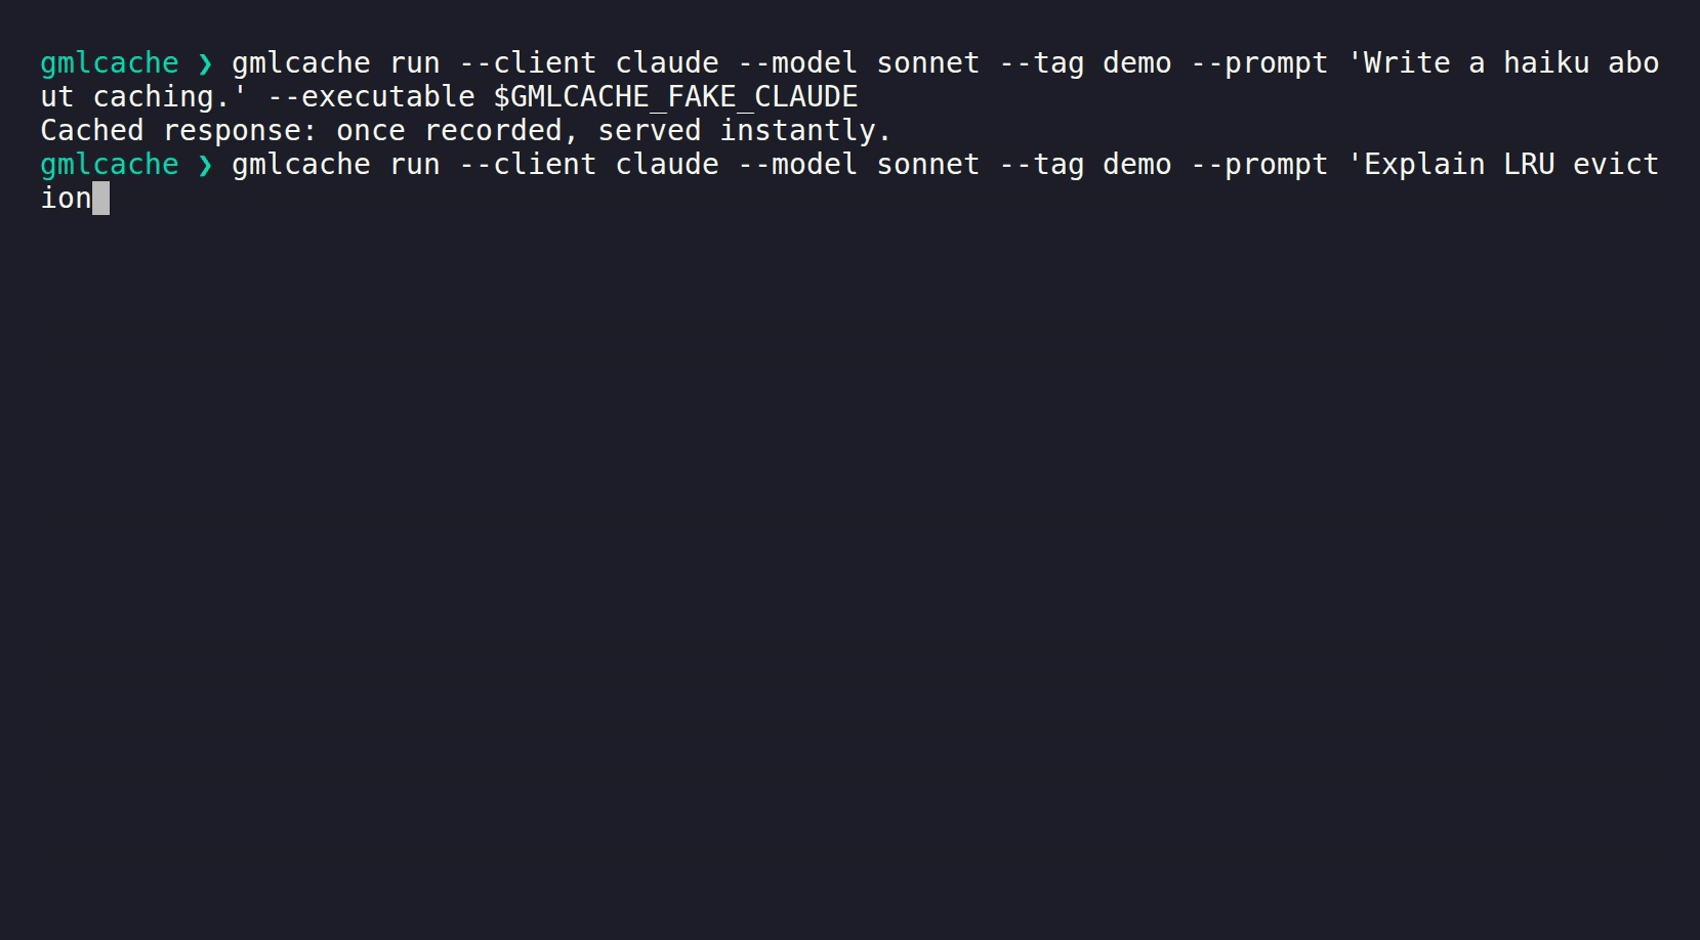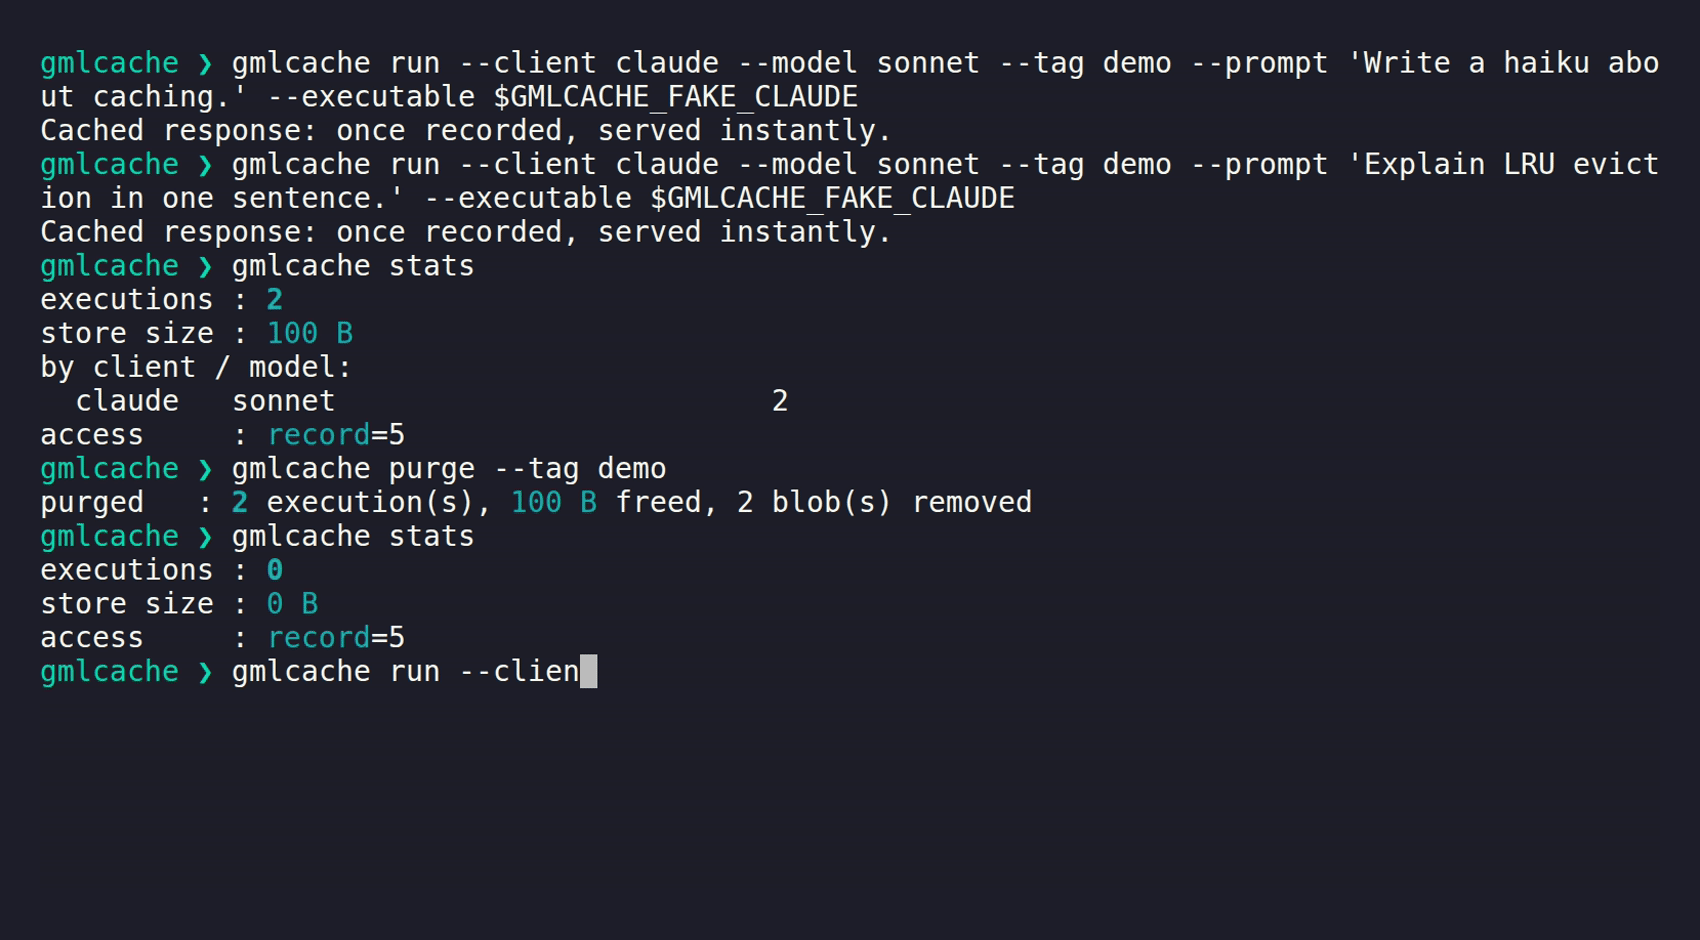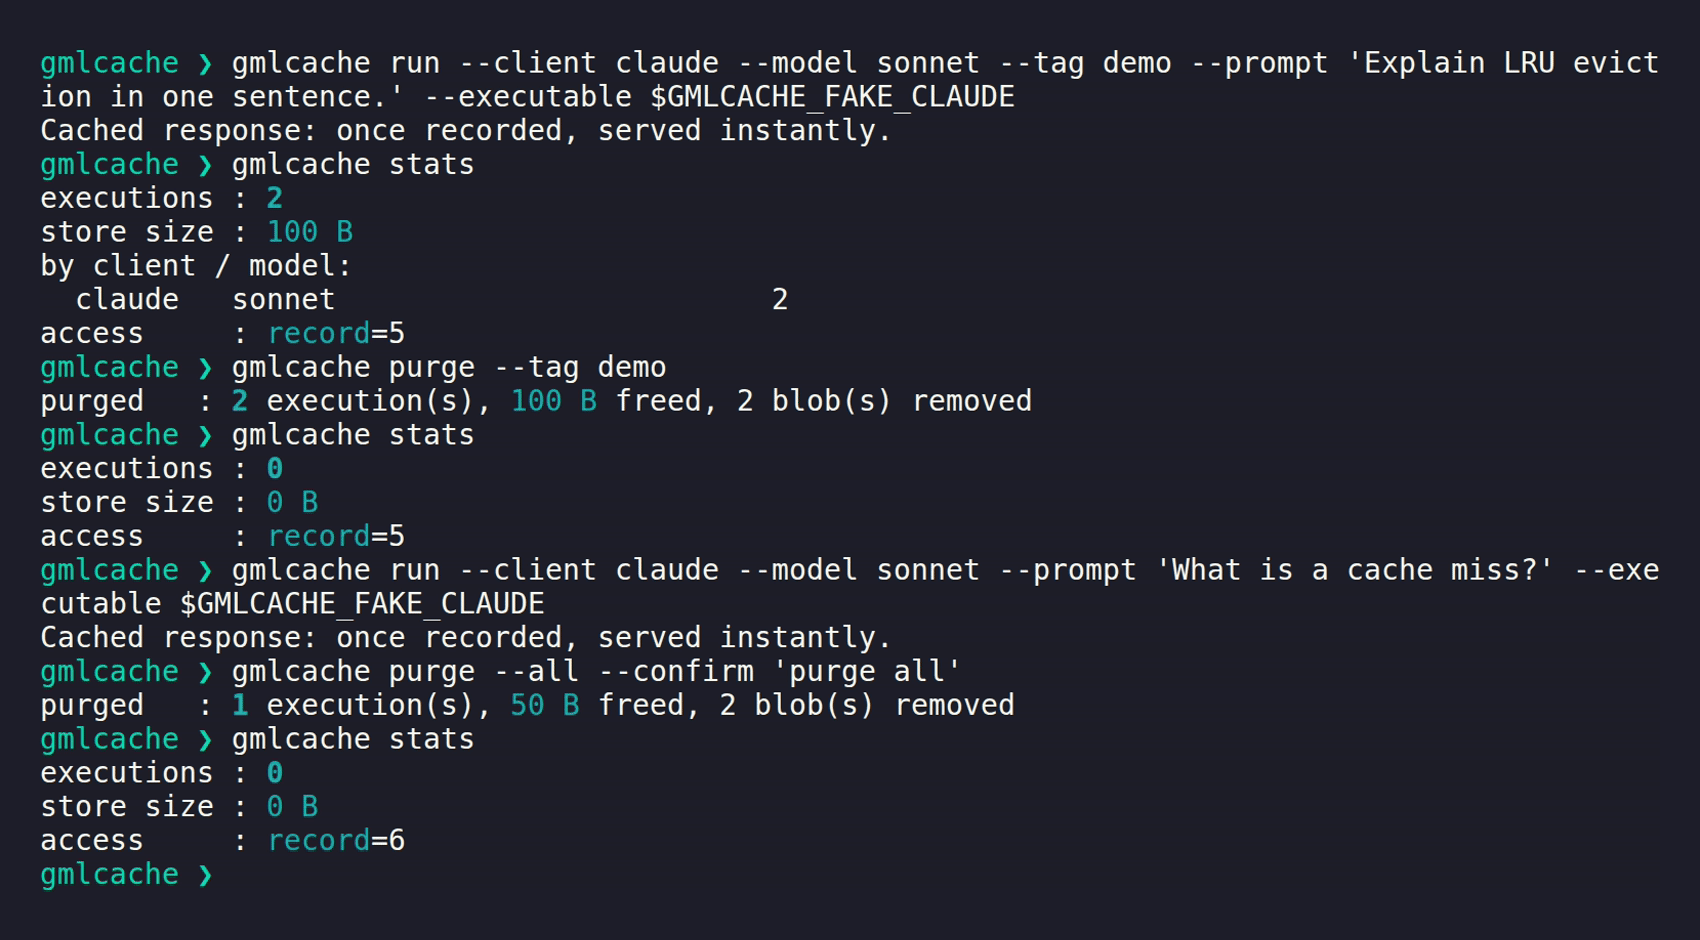
Reclaim space. Purge is soft by default — execution records and statistics are kept;
only the stored blobs are freed. --all wipes everything.
gmlcache purge --tag demo        # soft-purge by tag
gmlcache purge --key <key>       # soft-purge one execution
gmlcache purge --all --confirm 'purge all'   # wipe the entire store
Export
Export tagged executions as an (input, output) JSONL dataset.
gmlcache export --tag eval -o dataset.jsonl
gmlcache export --tag eval --include-tag verified -o dataset.jsonl
Encryption
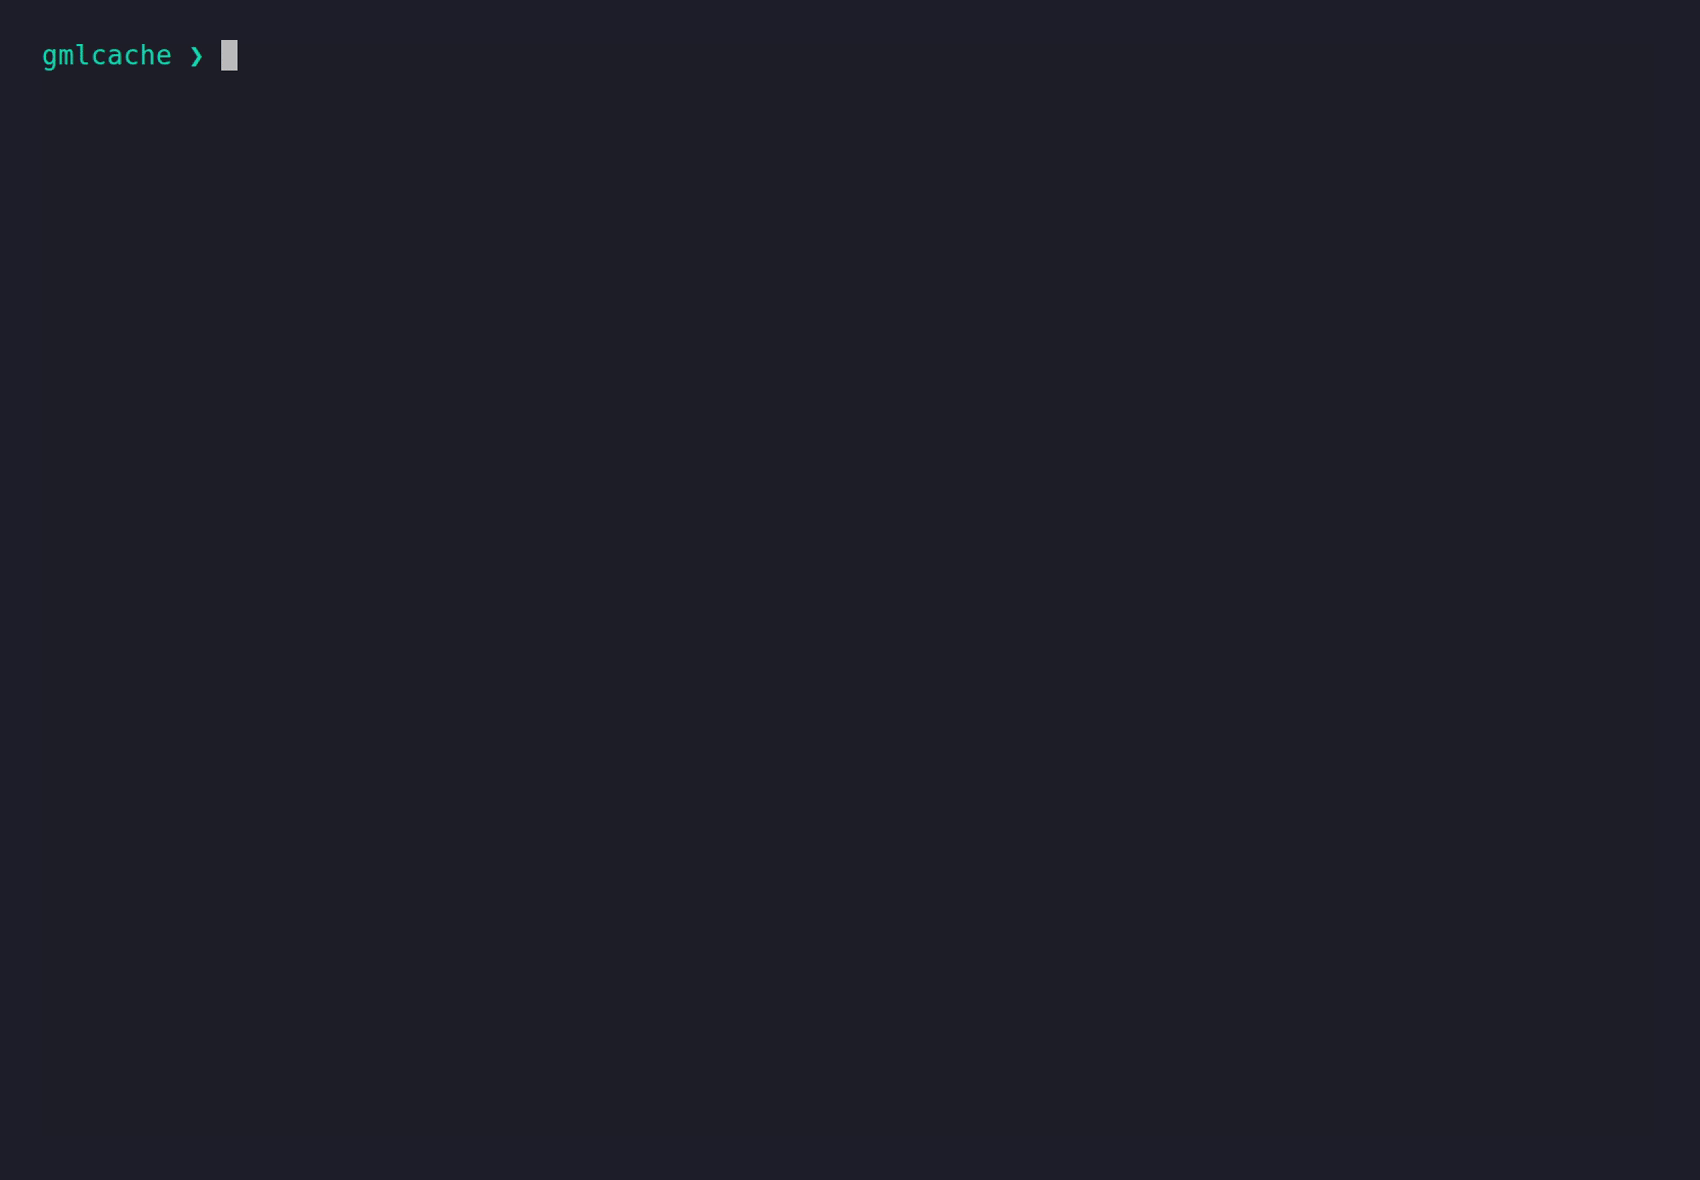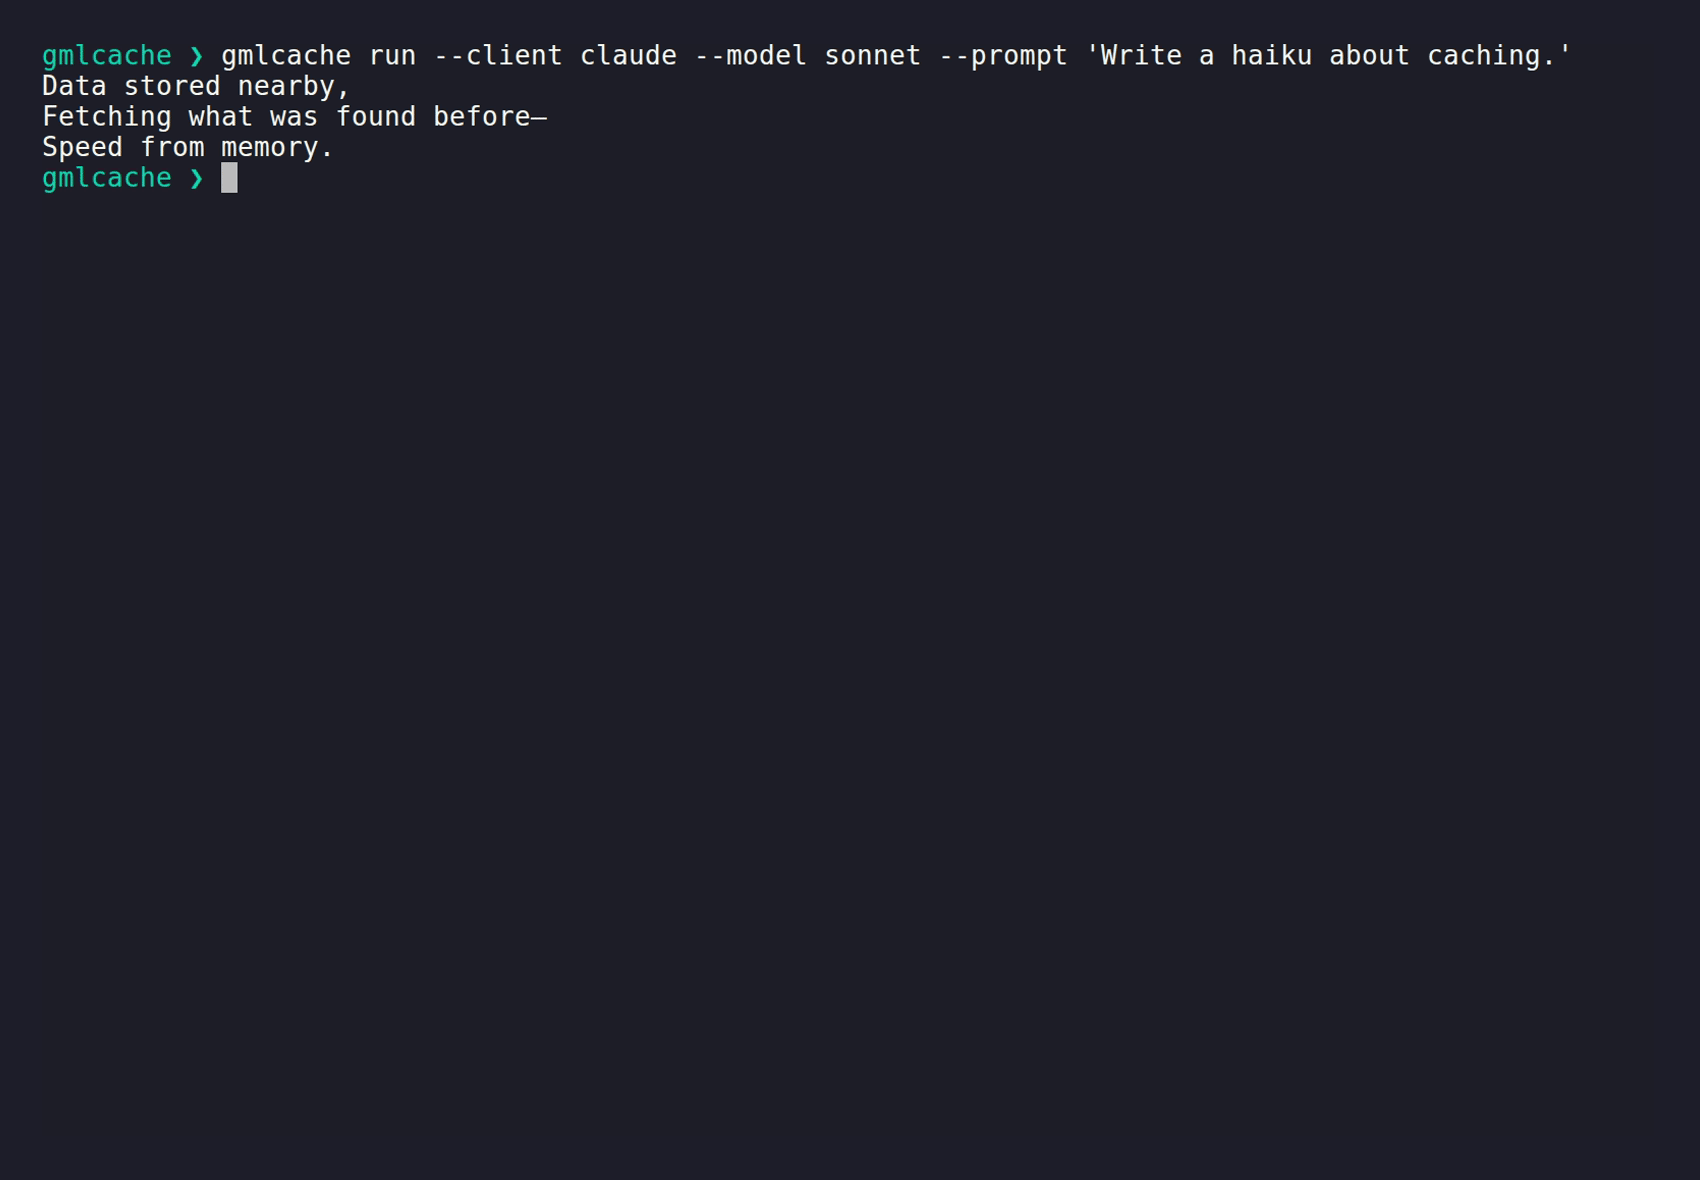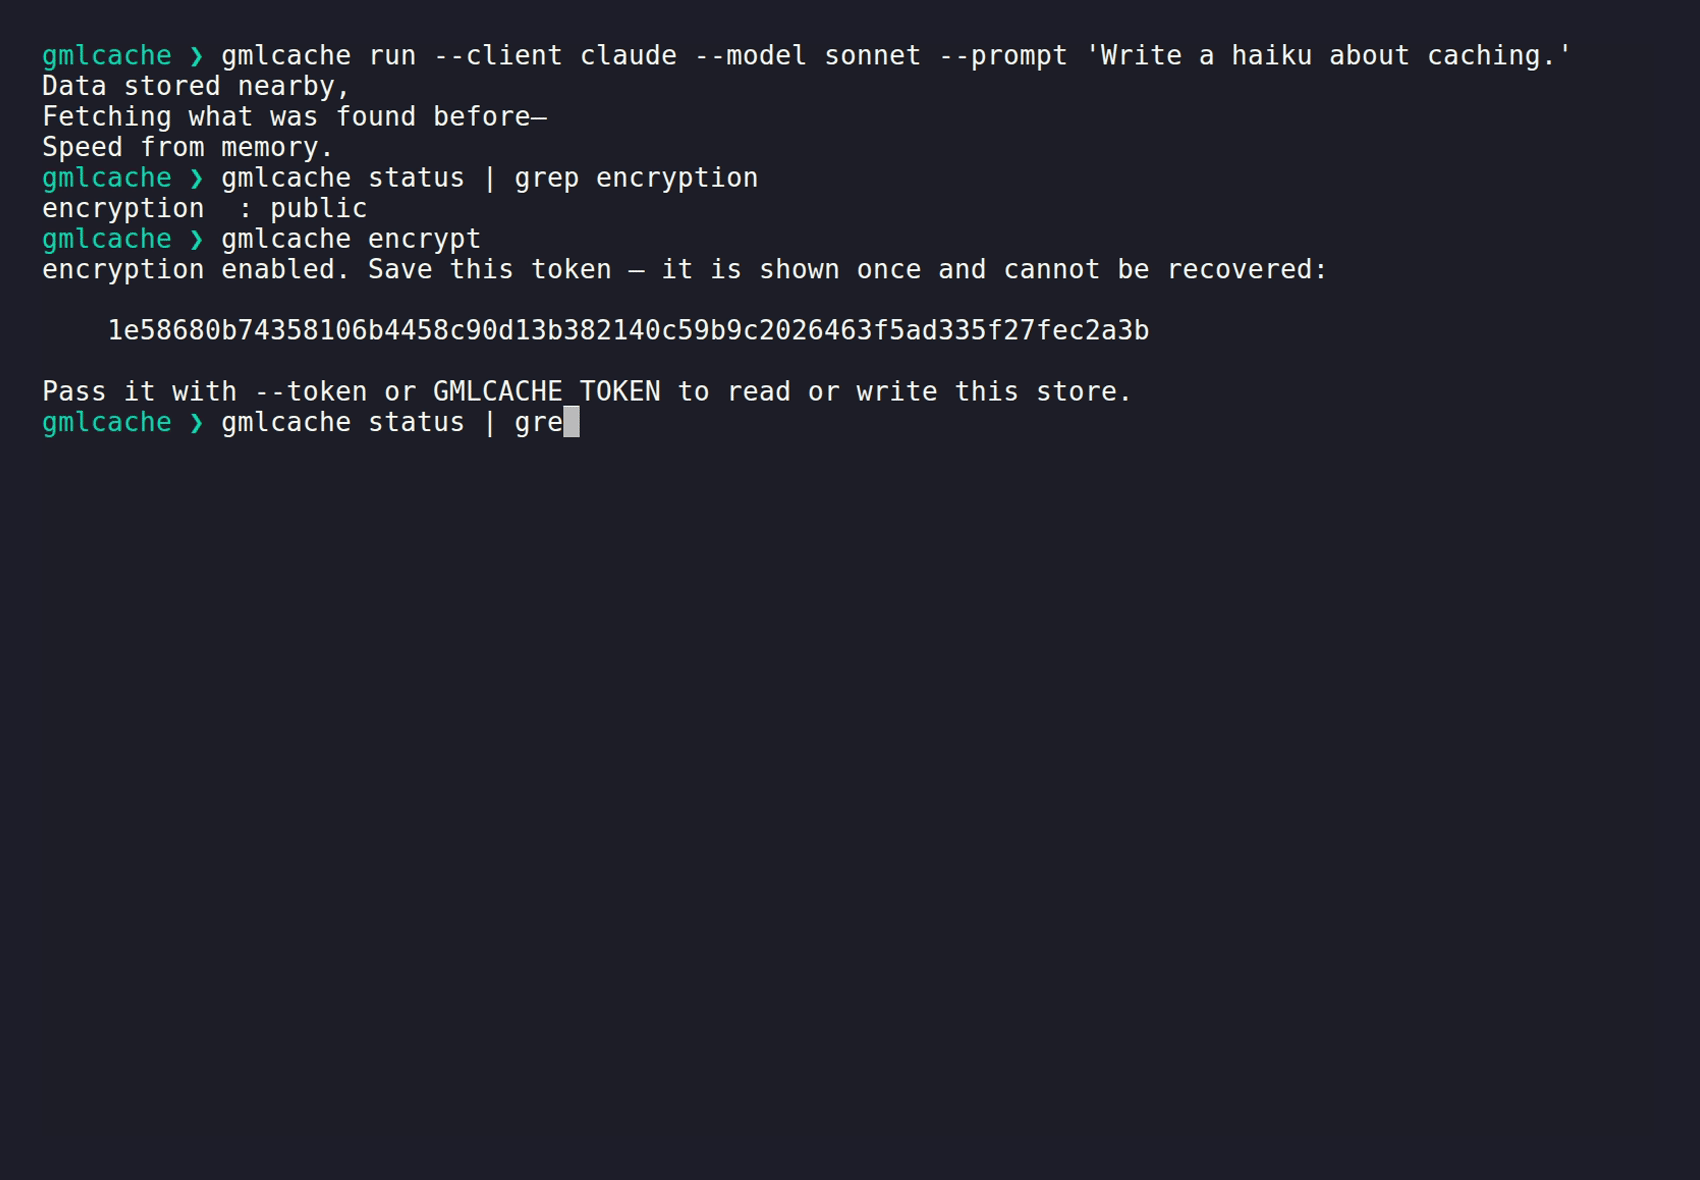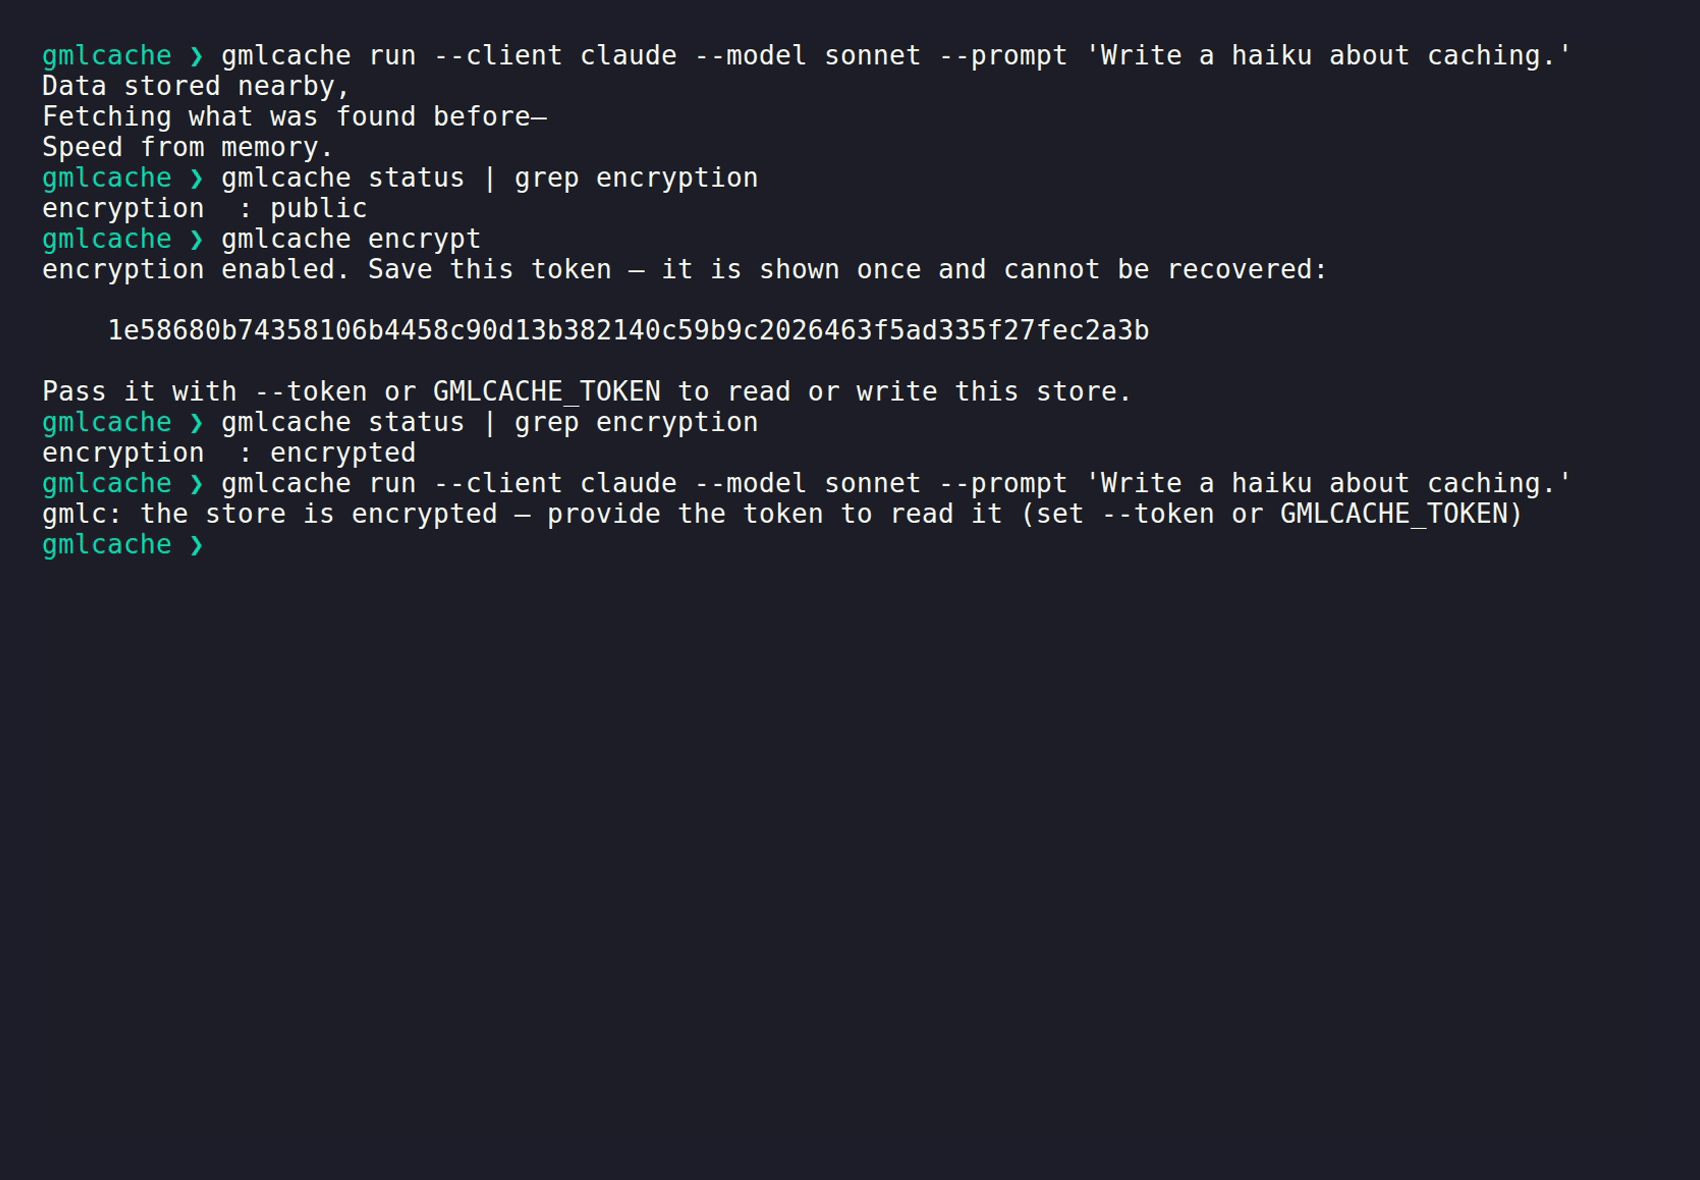
Encrypt the whole store at rest. gmlcache generates a token — keep it; without it the cache is unreadable even to gmlcache itself.
gmlcache encrypt                                    # lock the store; prints the token once
GMLCACHE_TOKEN=<token> gmlcache run --client …     # unlock on the fly for a single run
Daemon (0.13.0)
Start a local HTTP API over the cache store. Exposes every CLI capability as REST endpoints — useful for scripts, CI pipelines, and IDE integrations.
gmlcache daemon start            # foreground on 127.0.0.1:8765
gmlcache daemon start --port 9000 --session abc --metrics
gmlcache daemon status           # health check
gmlcache daemon stop             # SIGTERM
Hit the API directly:
curl http://127.0.0.1:8765/health
curl http://127.0.0.1:8765/stats
curl -X POST http://127.0.0.1:8765/sessions -H 'Content-Type: application/json' \
     -d '{"tags": ["ci-run-42"]}'
Or point any Anthropic SDK client at the cache-transparent gateway:
import anthropic
client = anthropic.Anthropic(api_key="…", base_url="http://127.0.0.1:8765/gateway/claude")

Full HTTP endpoint reference: packages/daemon/README.md
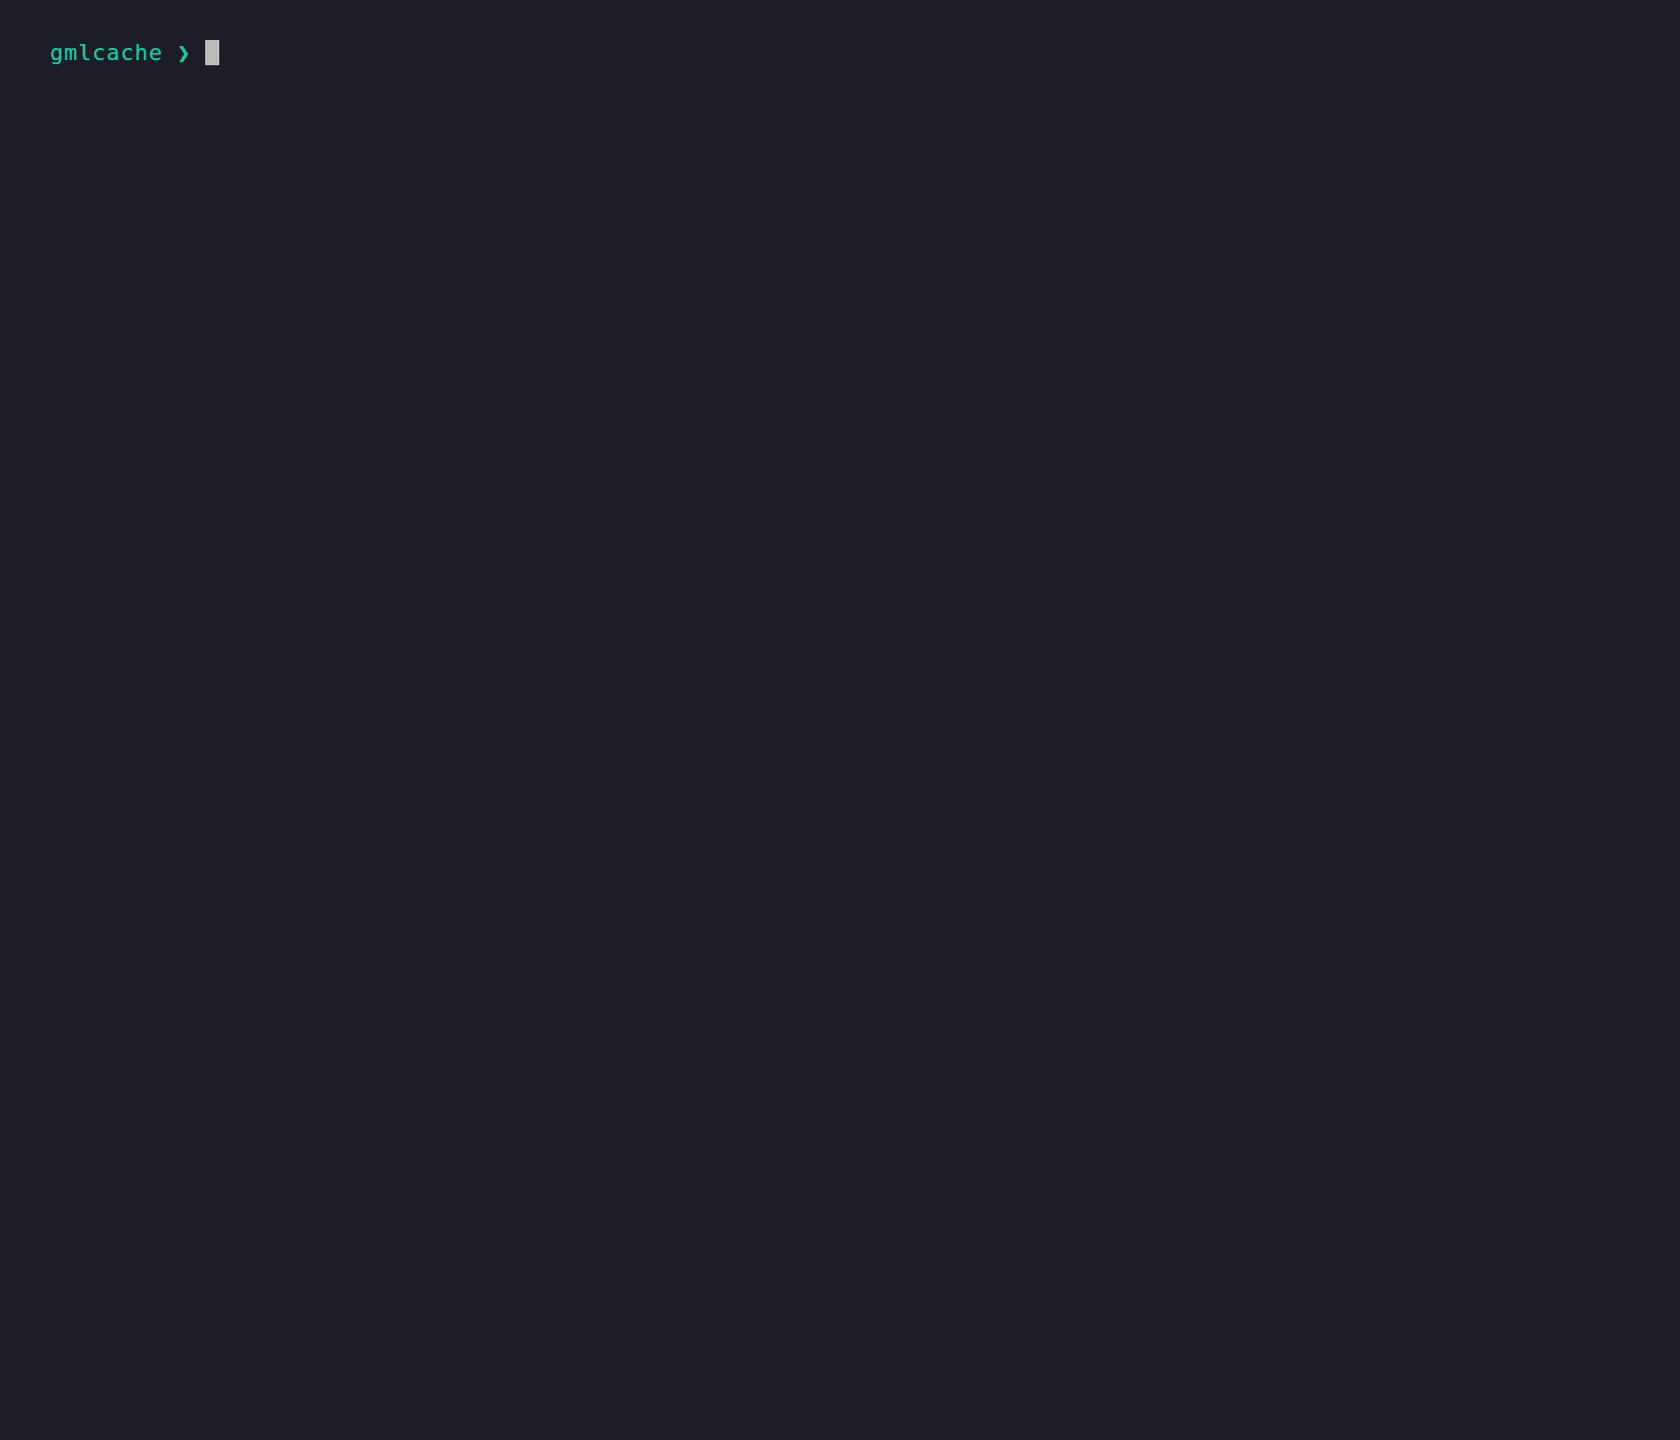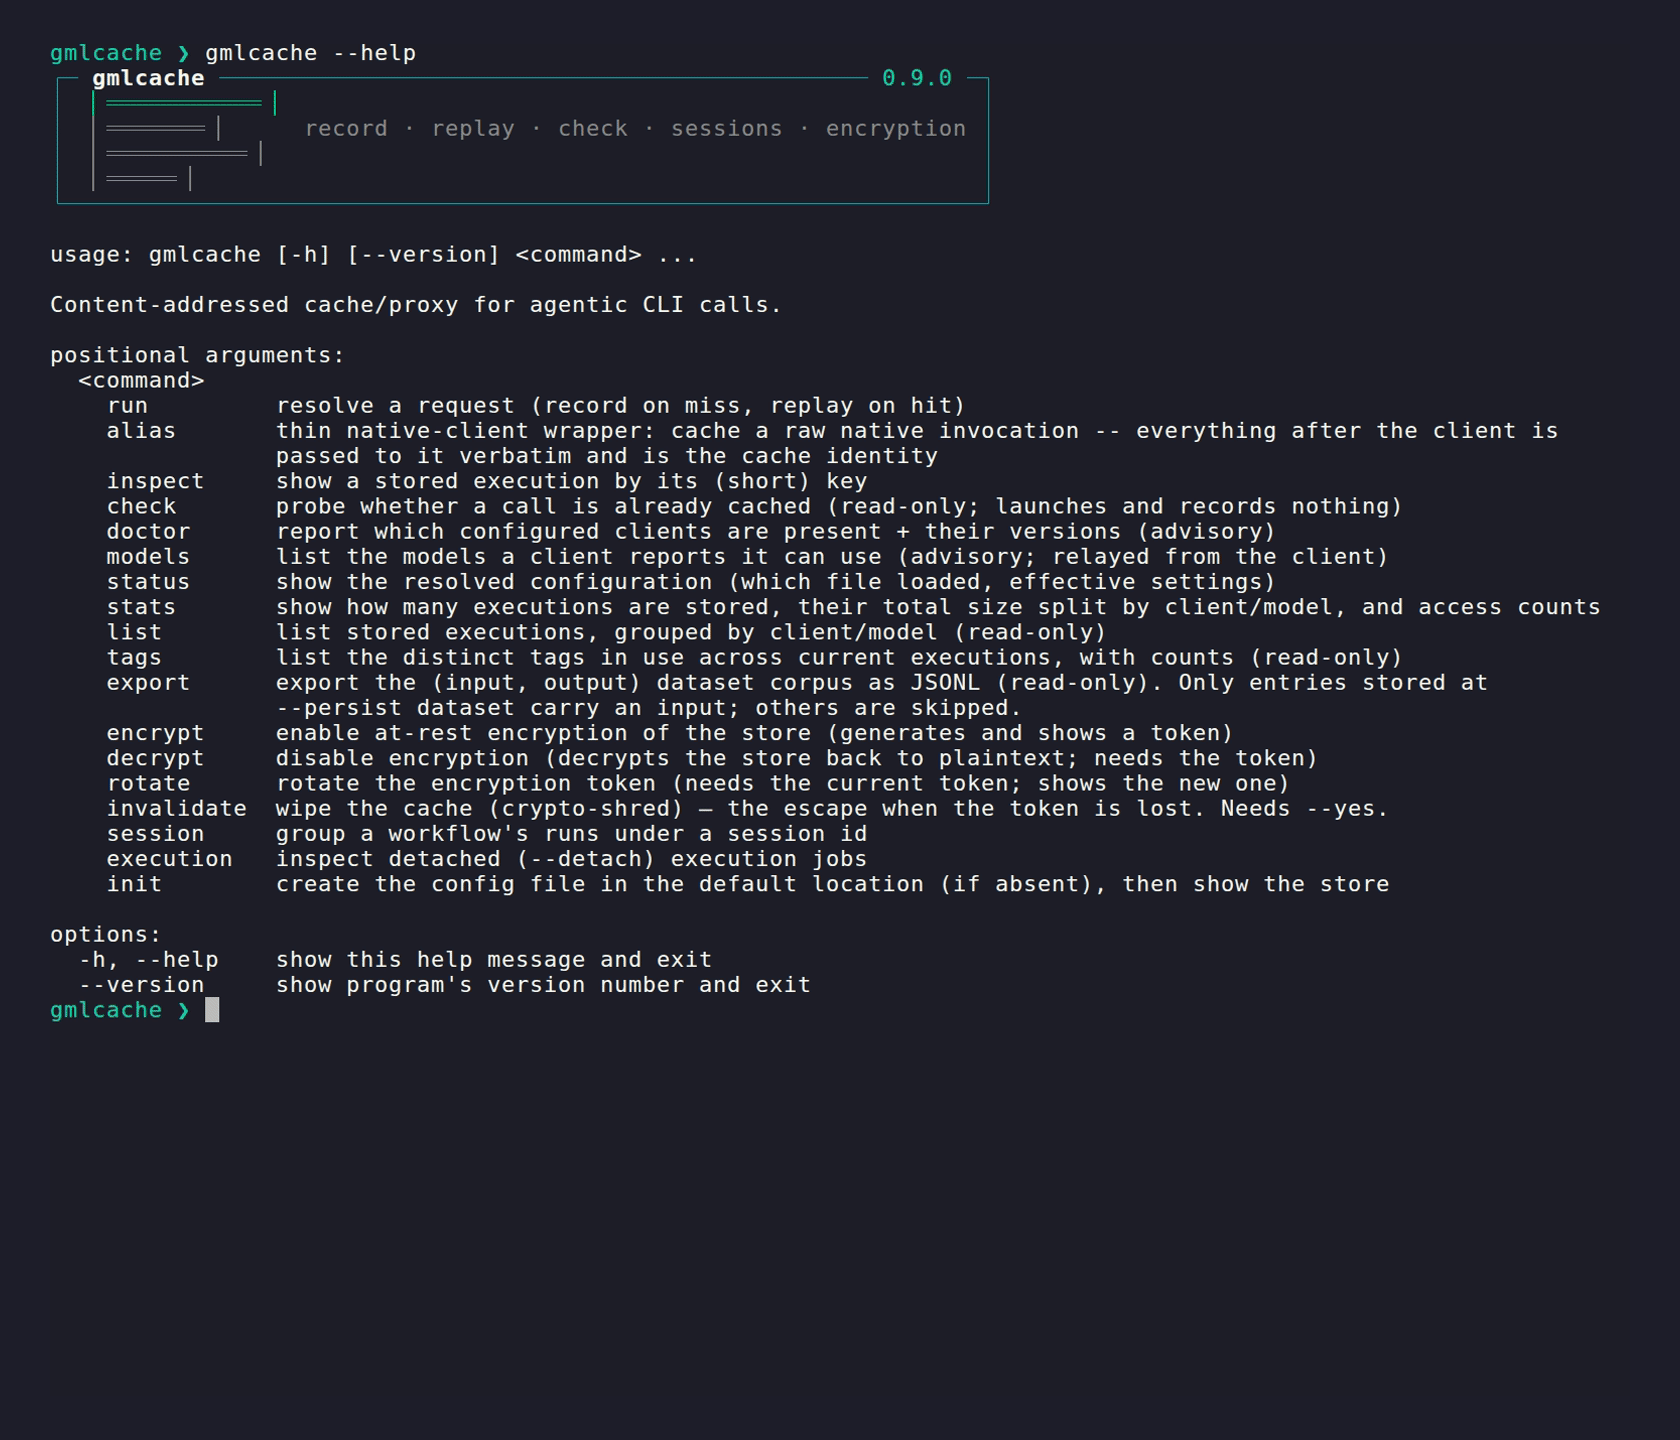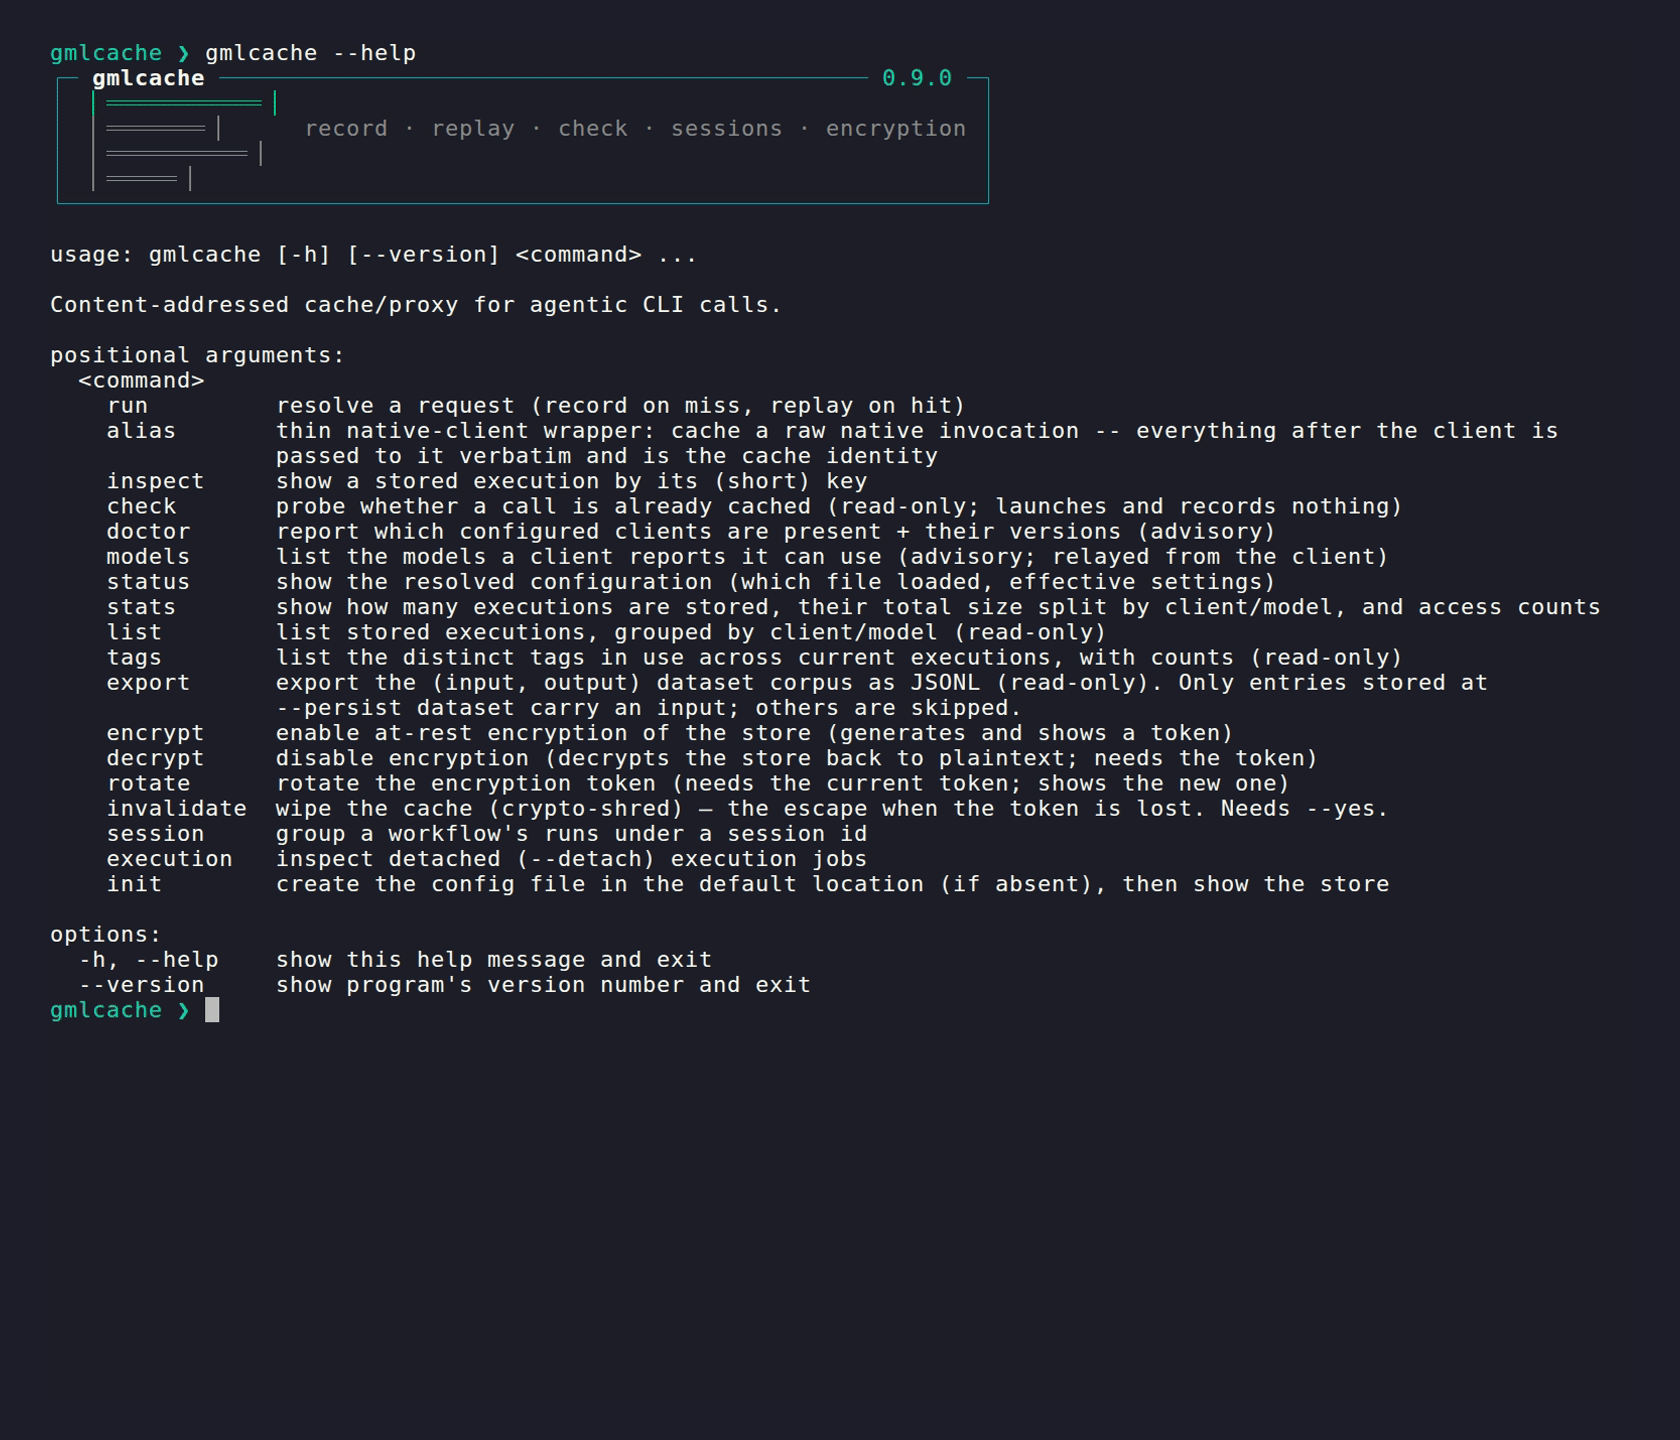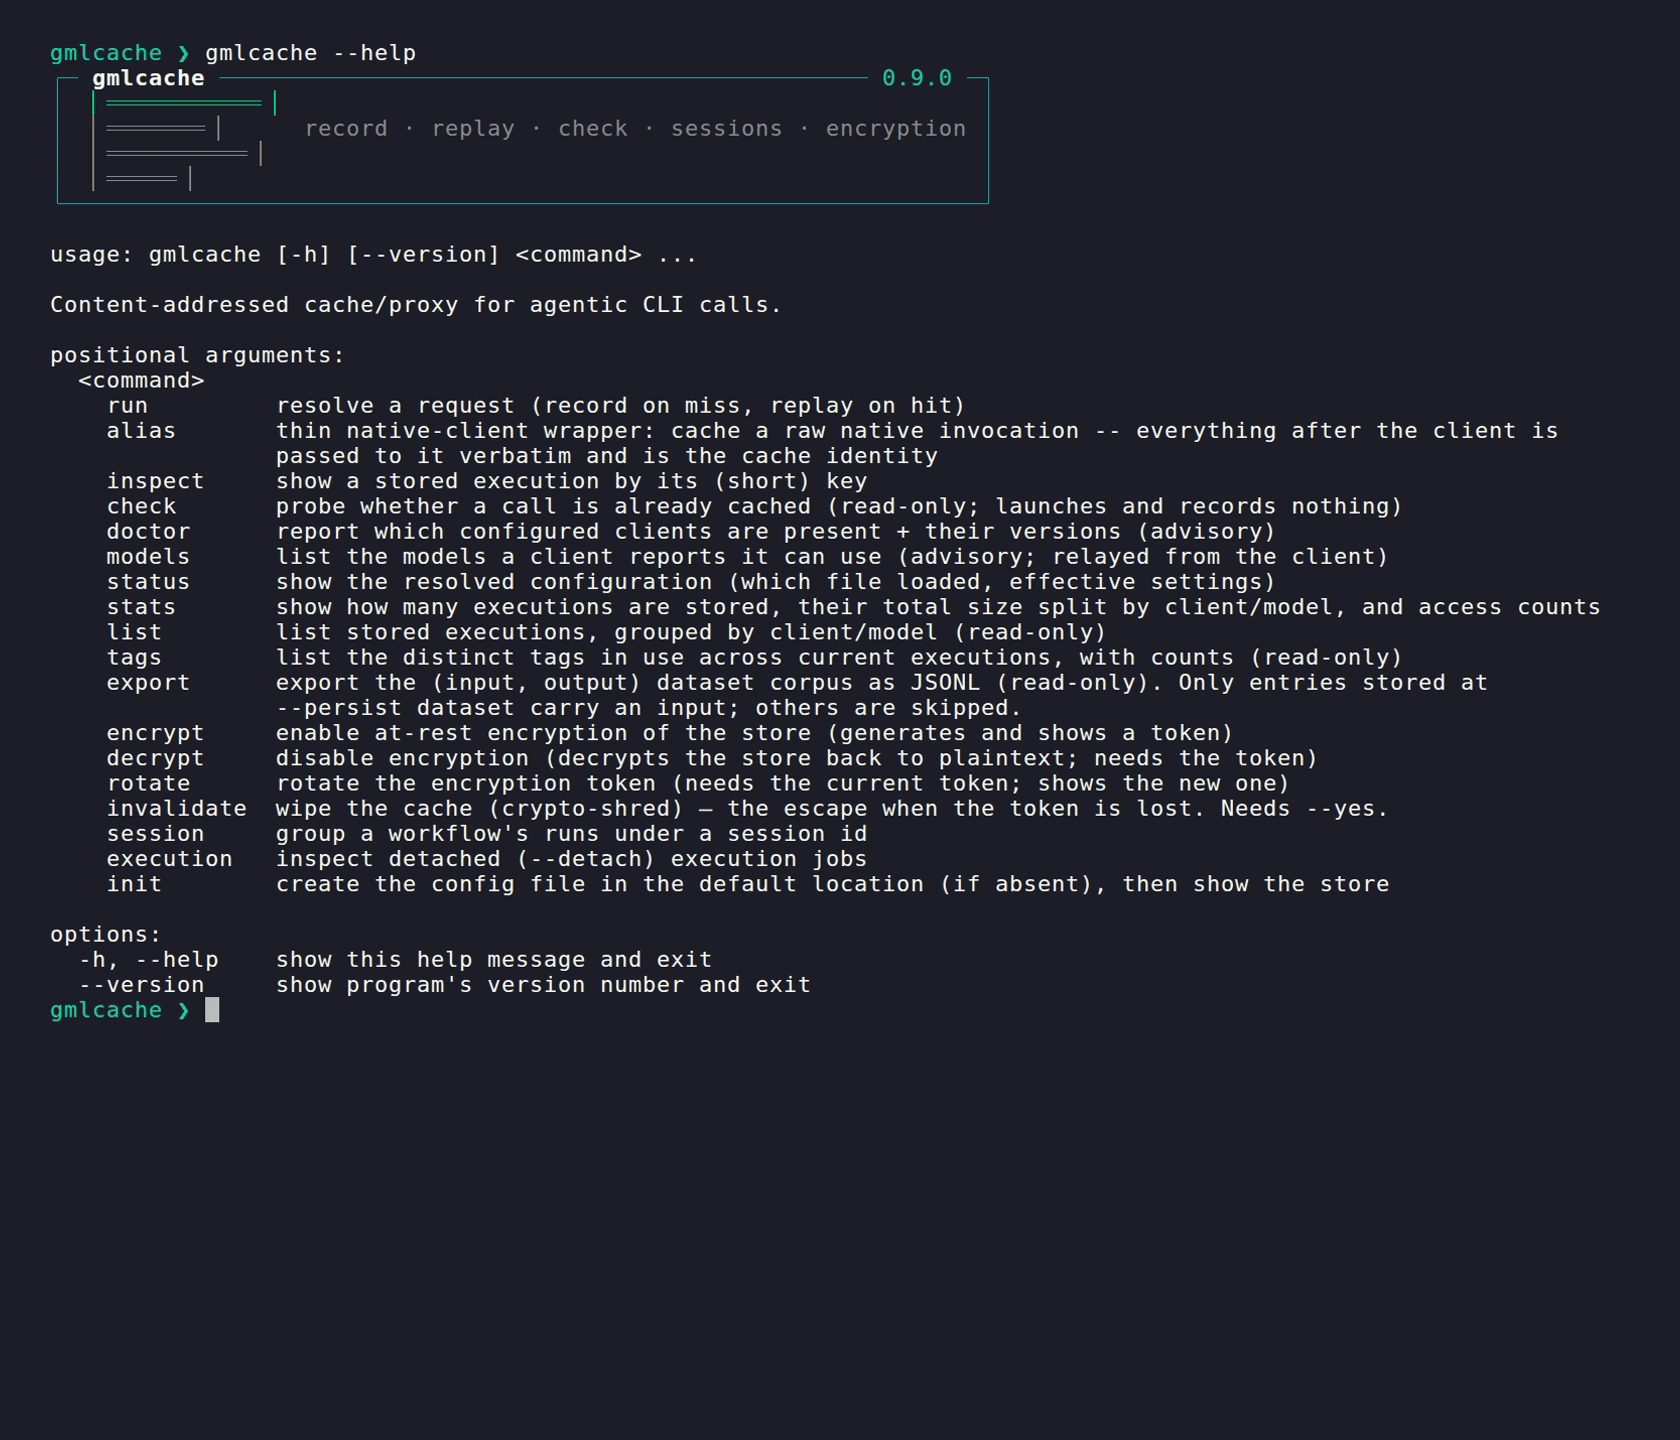
Command overview — --help
Built on a reusable engine
gmlcache is one inbound driver over
generic-ml-cache-core
— the stateless engine that ships the domain model, use cases, ports, and every adapter.
Embed it directly instead of driving it from a terminal:
from generic_ml_cache_core import build_use_cases

wired = build_use_cases(store_root="/path/you/choose")
execution = wired.run_ml.execute(command)
Links
- Repository & docs: https://github.com/danielslobozian/generic-ml-cache
- Daemon HTTP API:
packages/daemon/README.md - Changelog:
CHANGELOG.md - Security policy:
SECURITY.md
License
1 maintainer

Release files for generic-ml-cache-cli 0.25.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| generic_ml_cache_cli-0.25.0.tar.gz | 75.0 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| generic_ml_cache_cli-0.25.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 136.9 kB
Release files / generic_ml_cache_cli-0.25.0.tar.gz
| Download URL | generic_ml_cache_cli-0.25.0.tar.gz |
|---|---|
| Size | 75.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
730933ac2b6137668d53010ceabd6cd444a8e91dea84da18a4e7b8c02bb64b90
|
|
BLAKE2b-256 checksum How to use checksums |
2e87feec3f3a9c87a8d40d40be833146ecf2da0cc15f734afe1b01ef4081334c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 28, 2026.
Transparency logRelease files / generic_ml_cache_cli-0.25.0-py3-none-any.whl
| Download URL | generic_ml_cache_cli-0.25.0-py3-none-any.whl |
|---|---|
| Size | 61.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
f5e395d0445feb34bbf3882ffd87ccb20e7465ce607aca8e8f84dc44ecd8b019
|
|
BLAKE2b-256 checksum How to use checksums |
70273a091dfdc760685d20db920653841cd9de7f1253fe650a1ebec1fb4bb059
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.12
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jun 28, 2026.
Transparency log













