
EvalBench
EvalBench is a flexible framework designed to measure the quality of generative AI (GenAI) workflows. It supports two broad classes of evaluation:
- NL2SQL / database tasks — running and scoring DQL, DML, and DDL queries across multiple supported databases (AlloyDB, BigQuery, Spanner, PostgreSQL, MySQL, SQLite, and more).
- Agentic evaluations — driving real coding agents and CLIs (Gemini CLI, Claude Code, Codex CLI, Antigravity CLI) through multi-turn scenarios with an LLM-based simulated user, then scoring their tool-call trajectories, goal completion, and behavior.
Its modular, plug-and-play architecture allows you to seamlessly integrate custom components while leveraging a robust evaluation pipeline, result storage, scoring strategies, and dashboarding capabilities.
Getting Started 
Follow the steps below to run EvalBench on your local VM:
Note: Evalbench requires Python 3.10 or higher and uv for dependency management.
1. Clone the Repository
Clone the EvalBench repository from GitHub:
git clone git@github.com:GoogleCloudPlatform/evalbench.git
2. Set Up a Virtual Environment
Navigate to the repository directory and create a virtual environment using uv:
cd evalbench
uv venv
source .venv/bin/activate
3. Install Dependencies
Install the required Python dependencies using uv:
uv sync
4. Configure GCP Authentication (For Vertex AI | Gemini Examples)
If gcloud is not installed already, follow the steps in gcloud installation guide.
Then, authenticate using the Google Cloud CLI:
gcloud auth application-default login
This step sets up the necessary credentials for accessing Vertex AI resources on your GCP project.
We can globally set our gcp_project_id using
export EVAL_GCP_PROJECT_ID=your_project_id_here
export EVAL_GCP_PROJECT_REGION=your_region_here
5. Set Your Evaluation Configuration
For a quick start, let's run NL2SQL on some sqlite DQL queries.
- First, read through datasets/bat/example_run_config.yaml and see the configuration settings we will be running.
Now, configure your evaluation by setting the EVAL_CONFIG environment variable. For example, to run a configuration using the db_blog dataset on SQLite:
export EVAL_CONFIG=datasets/bat/example_run_config.yaml
6. Run EvalBench
Start the evaluation process using the provided shell script:
./evalbench/run.sh
Agentic Evaluations
Beyond single-turn NL2SQL, EvalBench evaluates agents — coding CLIs and data agents that reason across multiple turns, call tools, and act on their environment.
Each scenario starts from a prompt and is driven forward by an LLM-based simulated user that follows a conversation_plan until the goal is met, a terminal state is detected, or max_turns is reached. Every turn is captured — text, tool calls, parameters, latency, and tokens — and then scored. Runs are sandboxed, so agents never touch your local CLI settings and scenarios can run concurrently.
| Agent | Generator | Orchestrator | Guide |
|---|---|---|---|
| Gemini CLI | gemini_cli |
agent / geminicli |
Gemini CLI guide |
| Claude Code | claude_code |
agent |
Claude Code guide |
| Codex CLI | codex_cli |
agent |
Codex CLI guide |
| Antigravity (agy) CLI | agy_cli |
agent |
Antigravity CLI guide |
| Conversational data agents | dataagent |
dataagent / interact |
Data agent spec |
Agents can be evaluated against tools wired up as MCP servers, plugins, extensions, or skills — or against a fake MCP stub for fast, offline, zero-cost testing. Plugins are installed from a git repo or local directory through each CLI's marketplace and may bundle skills, MCP servers, or both. Trajectories are scored for tool-call accuracy, goal completion, hallucination and clarification behavior, latency, and token cost; see the scorer reference for all of them.
To try it without any cloud resources or cost:
export EVAL_CONFIG=datasets/gemini-cli-tools/example_run_fake_config.yaml
./evalbench/run.sh
Read Agentic evaluations for the execution model, sandboxing, and tool paradigms, and the agentic dataset format for how to write scenarios.
Overview
EvalBench's architecture is built around a modular design that supports diverse evaluation needs:
- Modular and Plug-and-Play: Easily integrate custom scoring modules, data processors, and dashboard components.
- Flexible Evaluation Pipeline: Seamlessly run DQL, DML, and DDL tasks while using a consistent base pipeline.
- Single-Turn and Agentic: Use the same pipeline, scorers, and reporting for one-shot NL2SQL generation and for multi-turn agent journeys driven by a simulated user.
- Sandboxed Agent Execution: Run real CLIs and MCP servers in isolated environments, in parallel, without touching your local configuration.
- Result Storage and Reporting: Store results in various formats (e.g., CSV, BigQuery) and visualize performance with built-in dashboards.
- Customizability: Configure and extend EvalBench to measure the performance of GenAI workflows tailored to your specific requirements.
Evalbench allows quickly creating experiments and A/B testing improvements (Available when BigQuery reporting mode set in run_config)
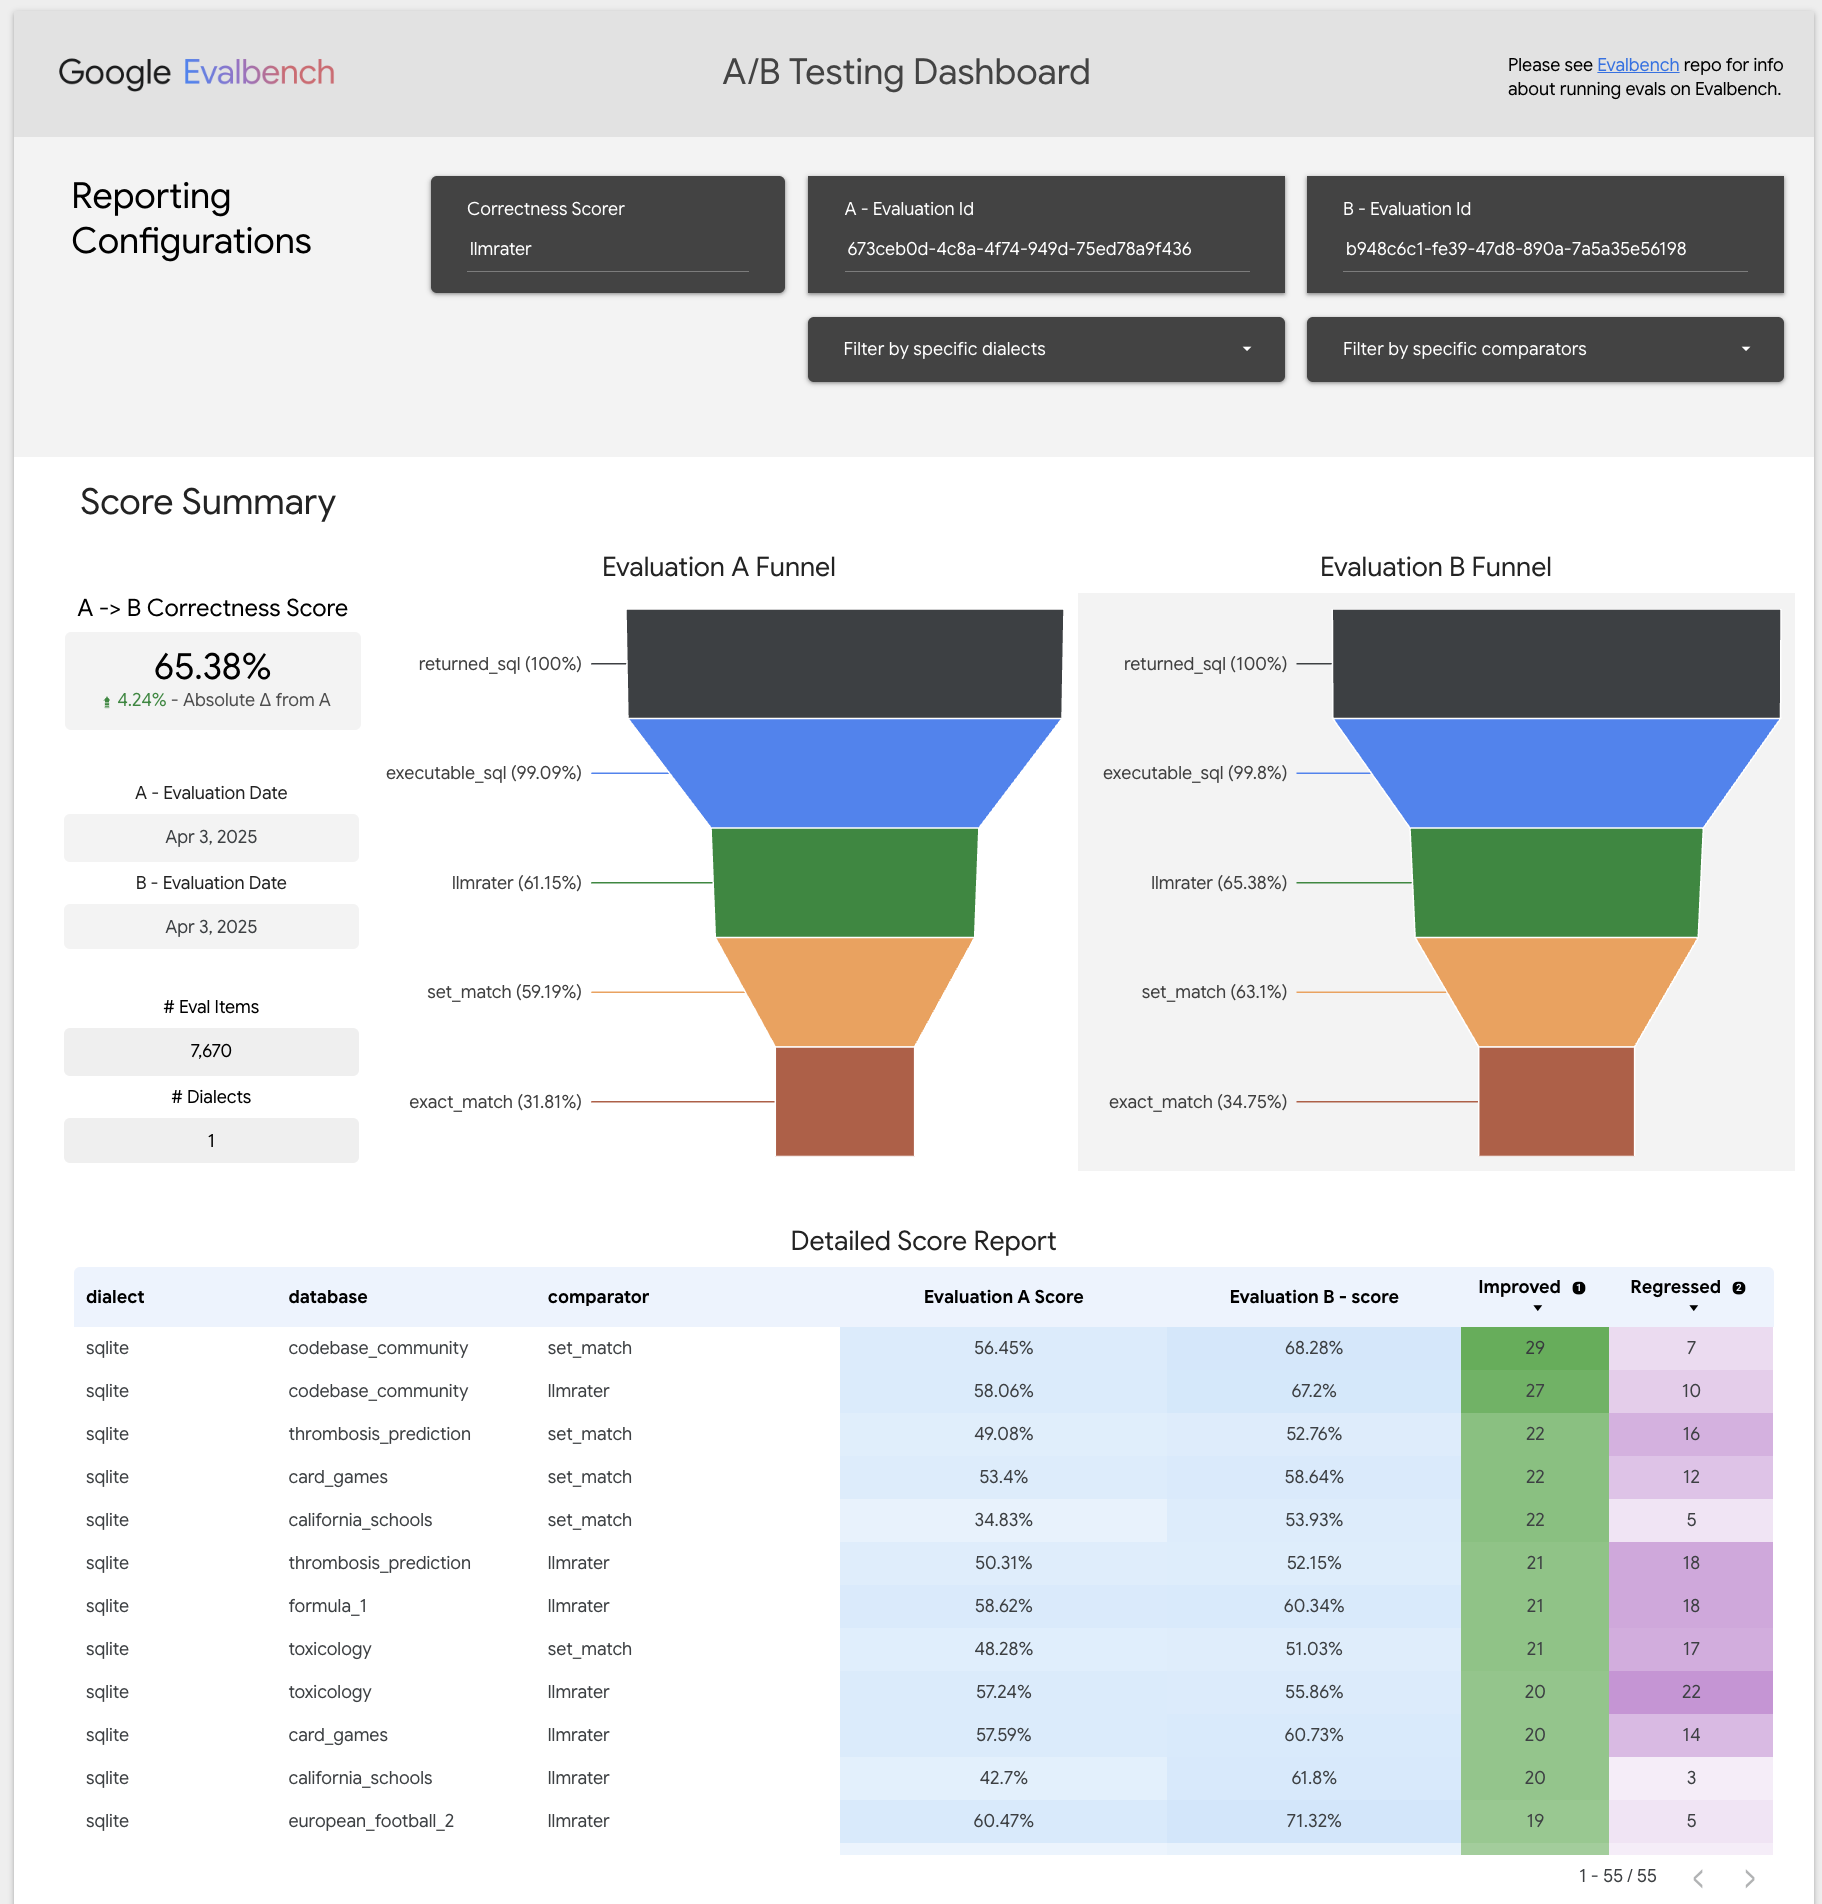
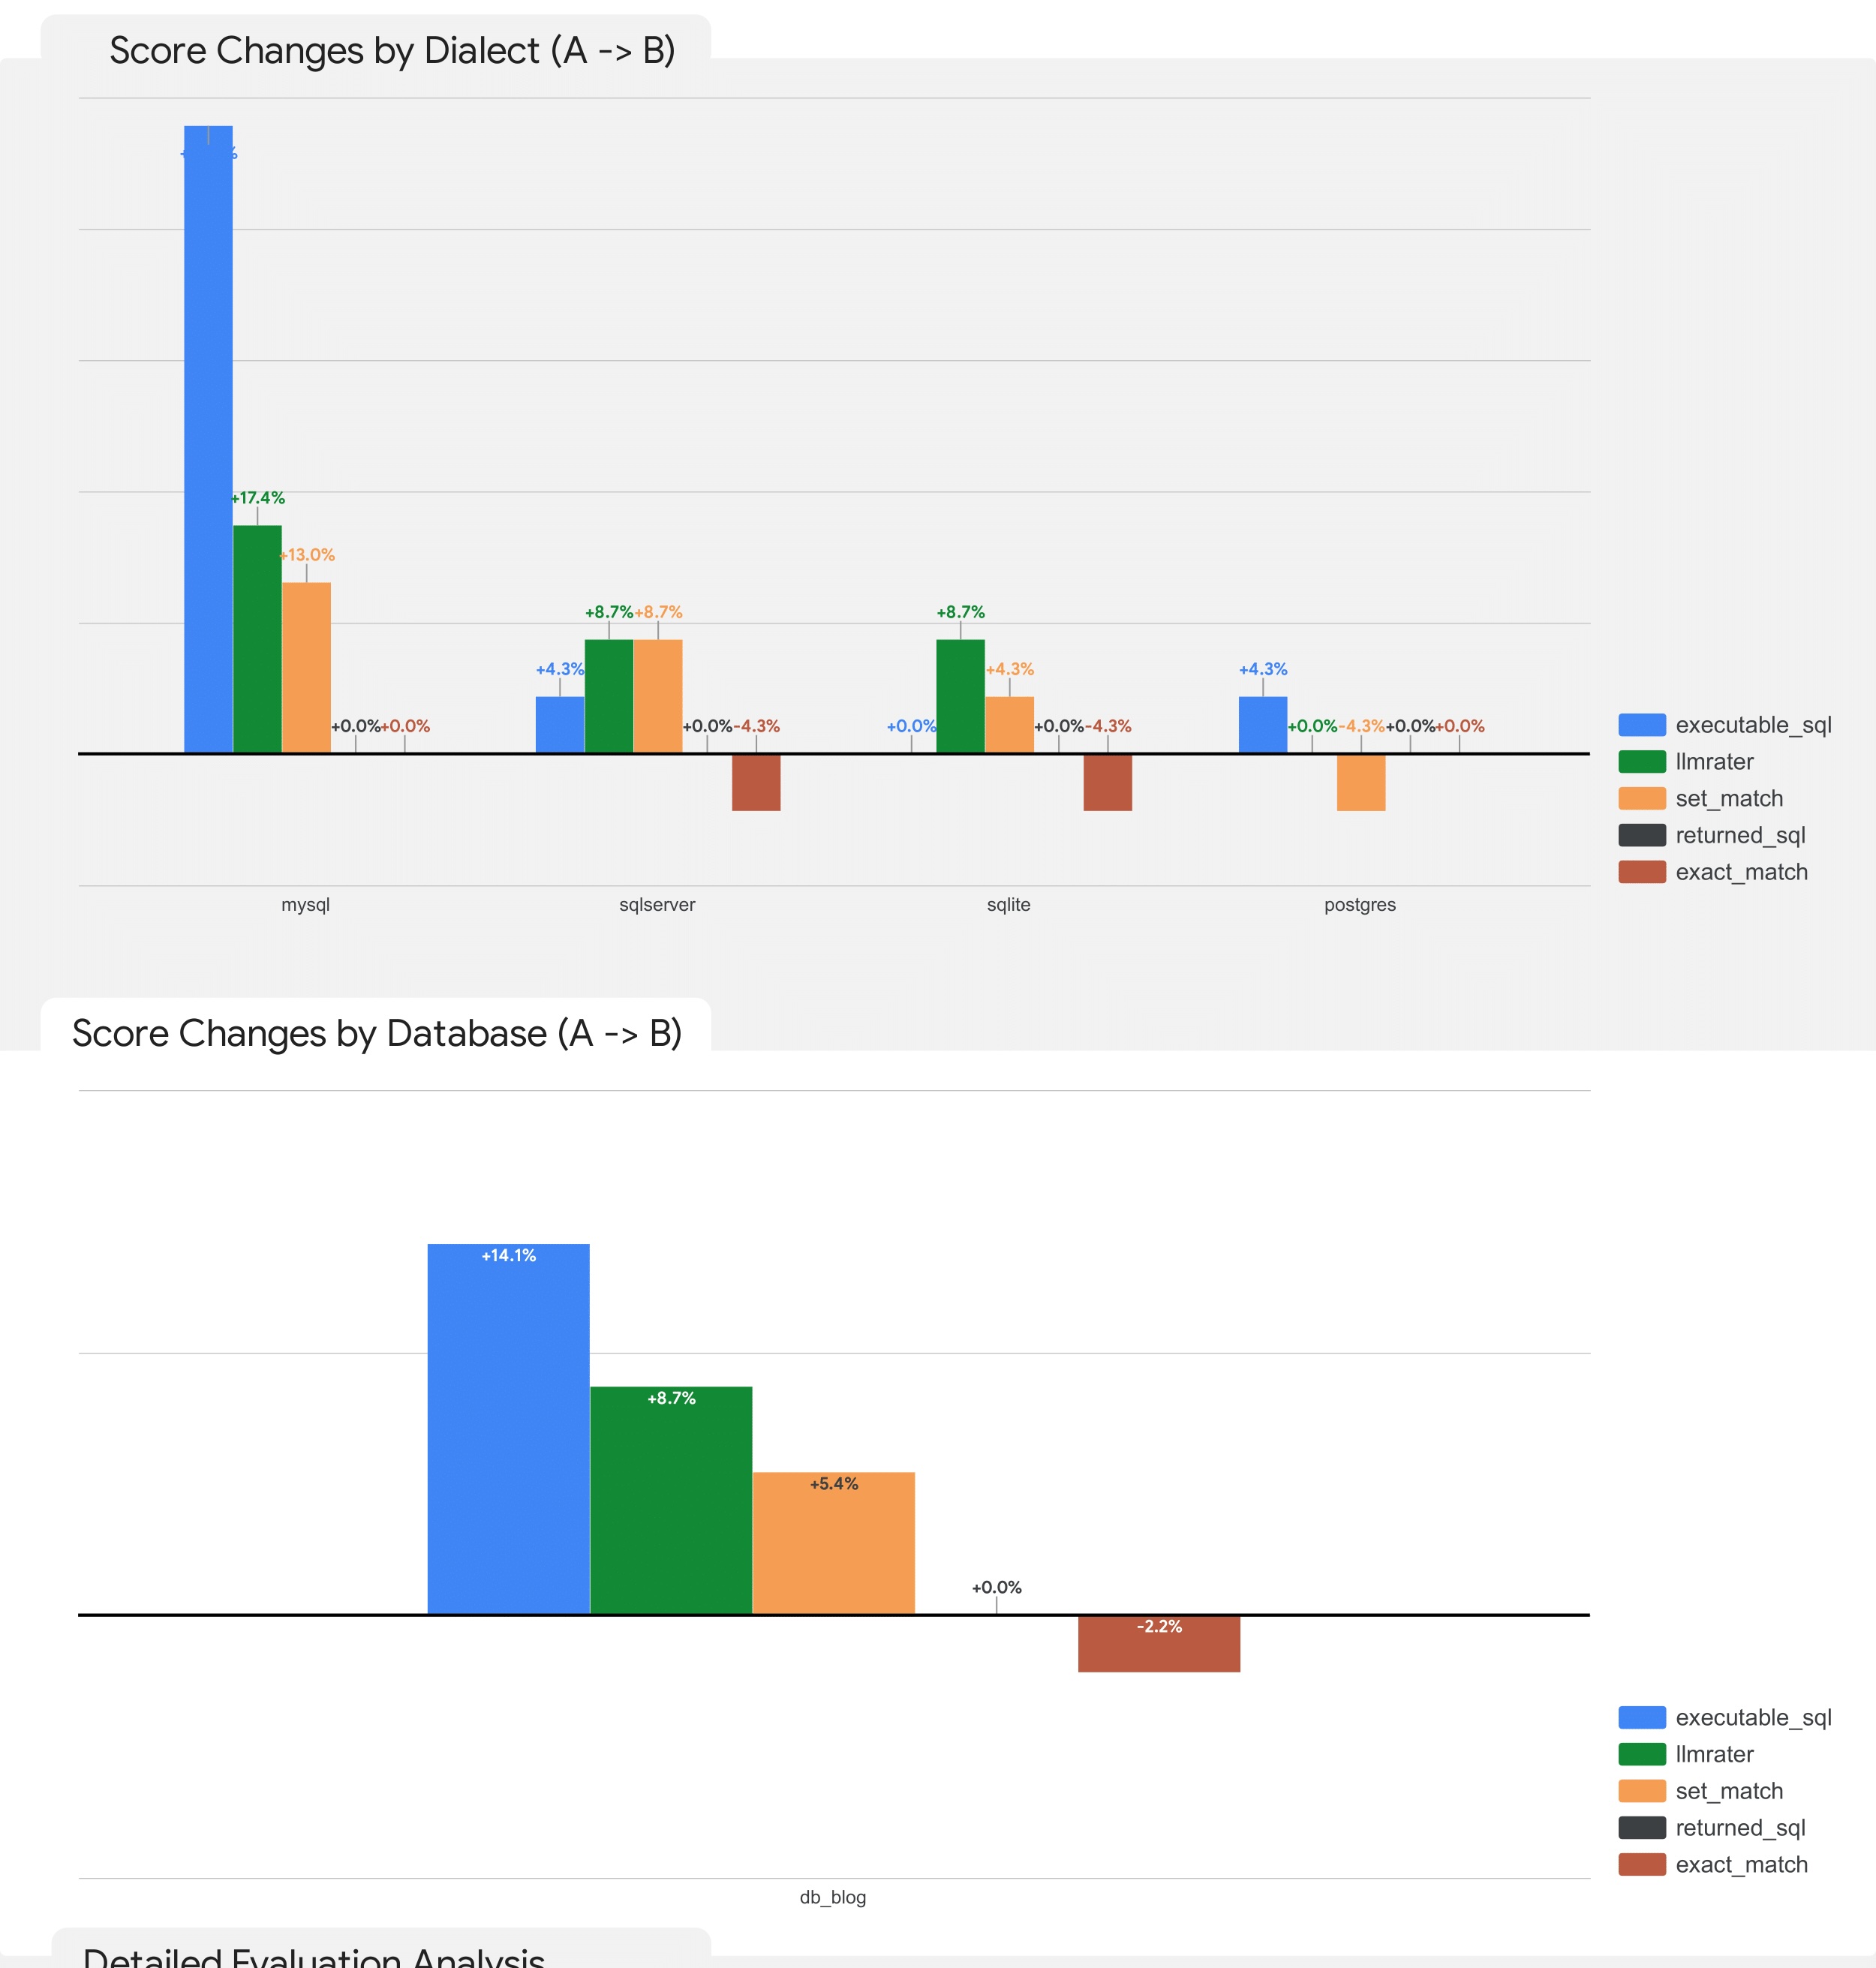
This includes being able to measure and quantify the specific improvements on databases or specific dialects:
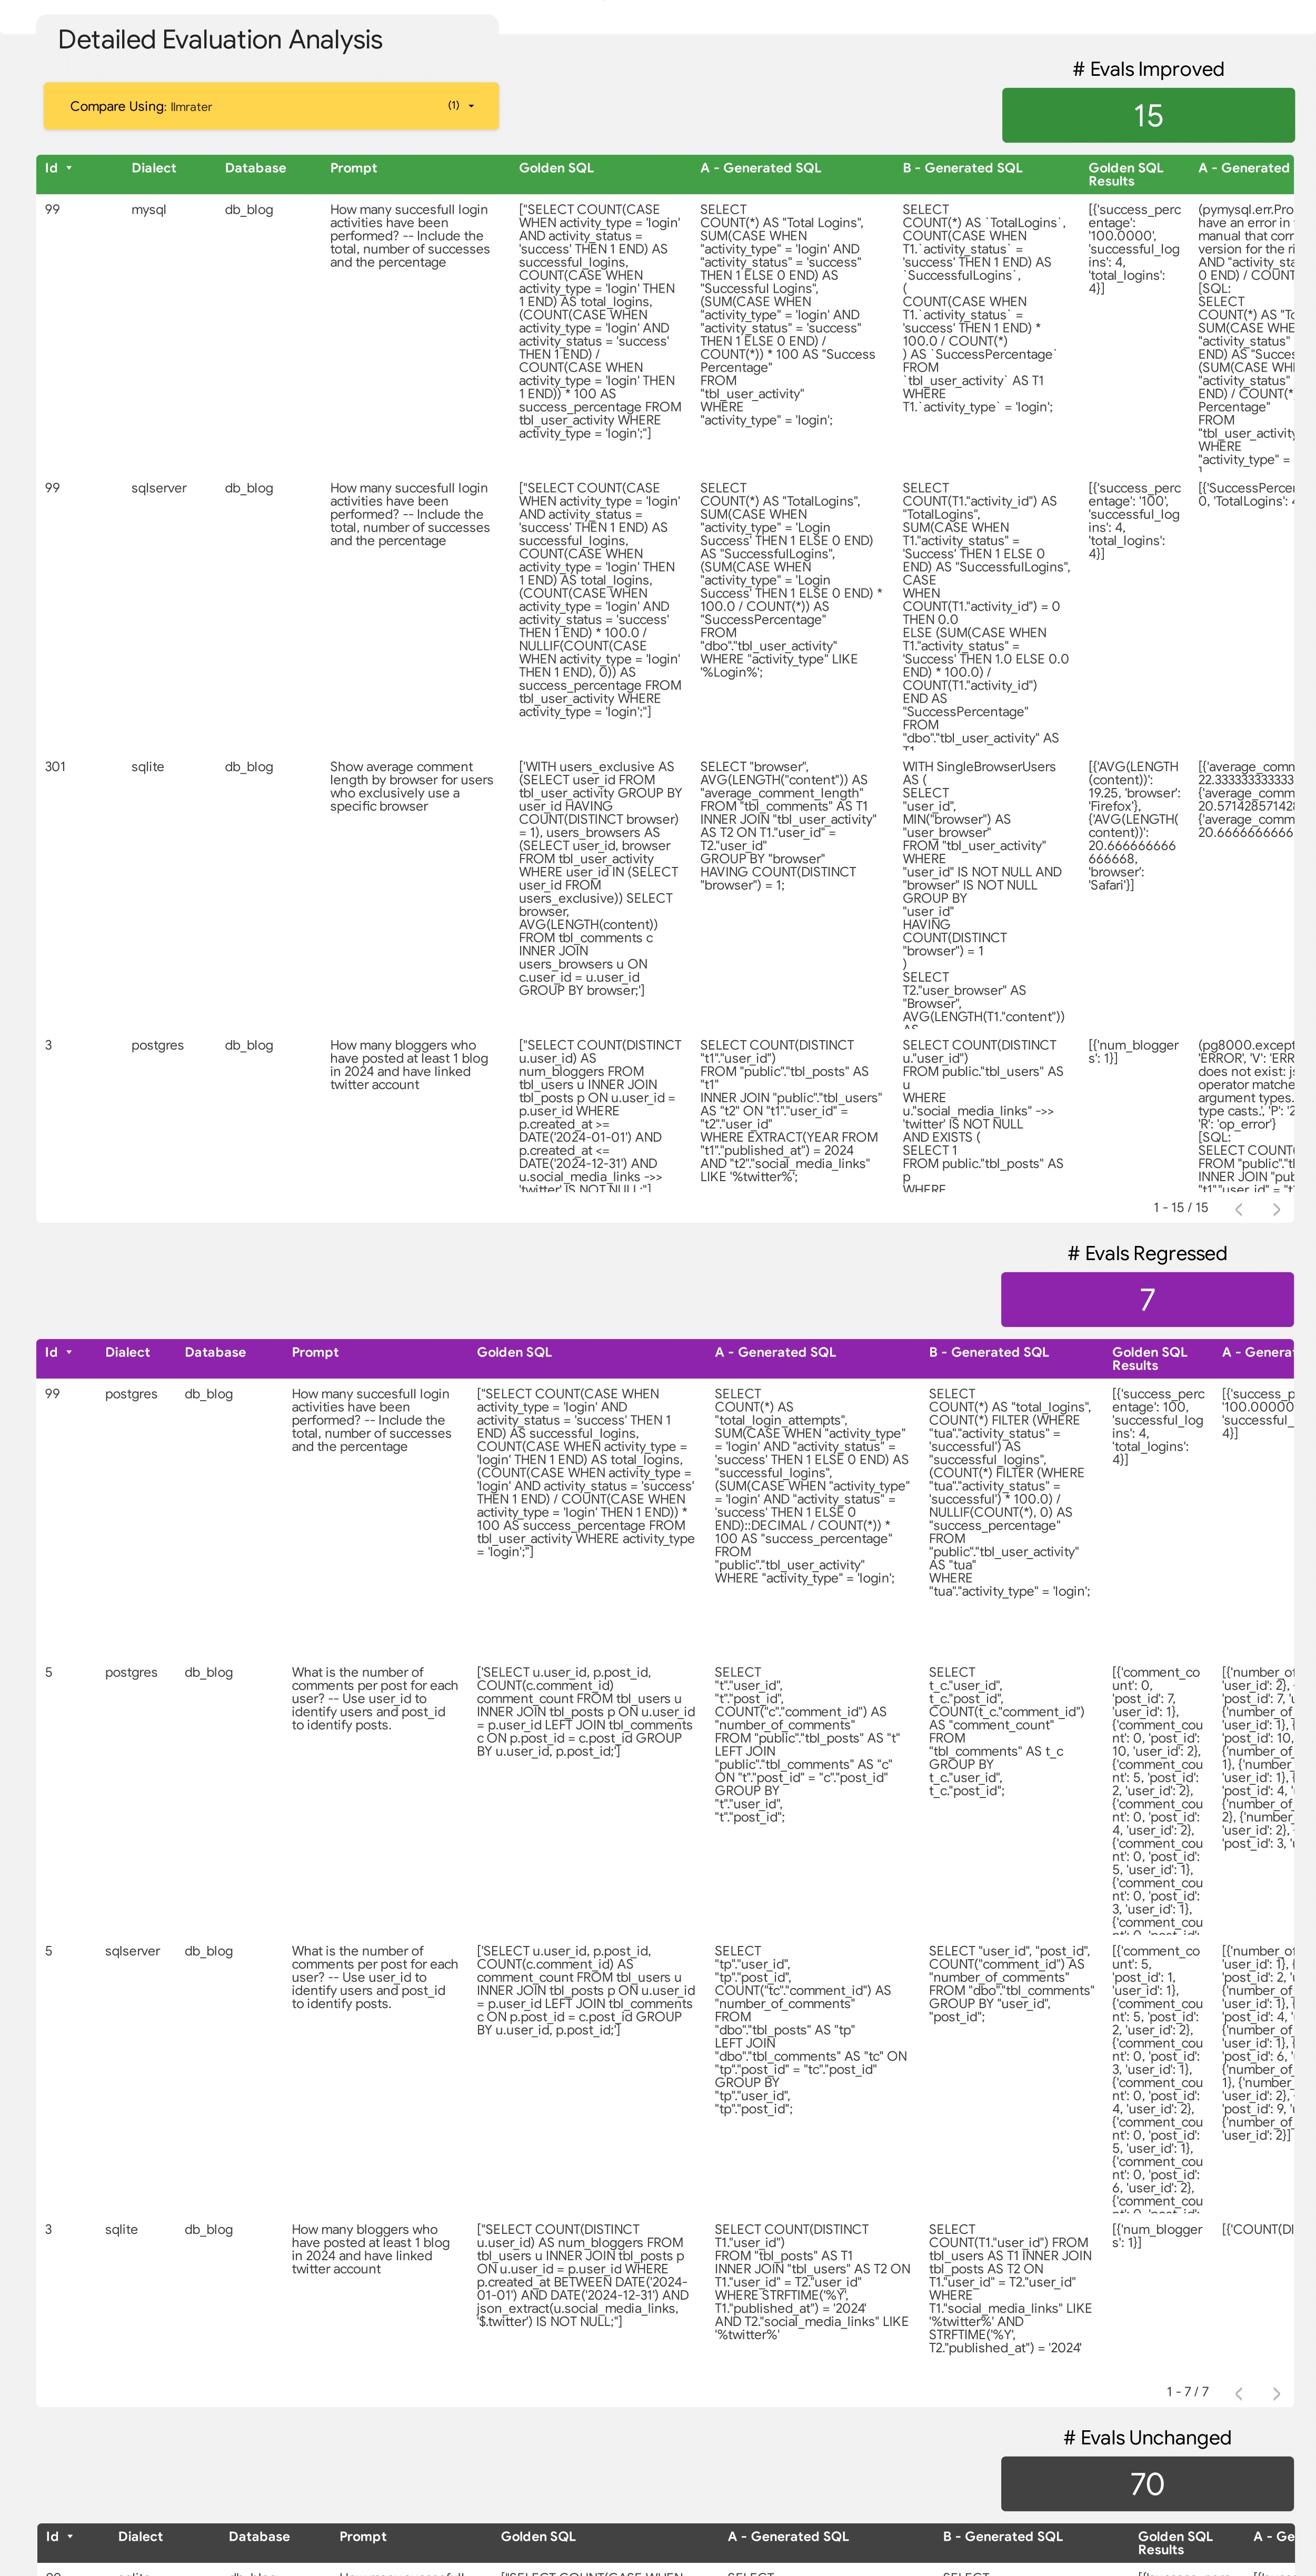
And allowing digging deeper into the exact details of the improvements and regressions including highlighting the changes, how they impacted the score and a LLM annotated explanation of the scoring changes if LLM rater is used.
Documentation
Full reference documentation lives in docs/.
| Doc | Contents |
|---|---|
| Run config | The top-level YAML that drives an evaluation run |
| Scorers | Every available scorer and its configuration options |
| Agentic evaluations | Execution model, sandboxing, and tool paradigms |
| NL2SQL dataset format | Prompts, golden SQL, and eval queries |
| Agentic dataset format | Scenarios, conversation plans, and expected trajectories |
| Database config | Connection details and supported dialects |
| Model config | Model selection and generation settings |
| Examples | Runnable notebooks for SQLite, Cloud SQL, and BigQuery |
Contributions are welcome — see contributing. Enjoy evaluating your GenAI models!
1 maintainer

Metadata
1 maintainer
Release files for google-evalbench 1.17.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| google_evalbench-1.17.0.tar.gz | 398.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| google_evalbench-1.17.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 920.2 kB
Release files / google_evalbench-1.17.0.tar.gz
| Download URL | google_evalbench-1.17.0.tar.gz |
|---|---|
| Size | 398.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b14259aba6f70dc9b0db4c4640351fb519b66e8c413a518dbe833770cde9a1df
|
|
BLAKE2b-256 checksum How to use checksums |
65e395e612771b2960536678268cb895c4d96403f6d6d7fb27b3c489729c2c4d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.2.0 CPython/3.11.2
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by Google Cloud, verified by PyPI on Sep 9, 2026.
Transparency logRelease files / google_evalbench-1.17.0-py3-none-any.whl
| Download URL | google_evalbench-1.17.0-py3-none-any.whl |
|---|---|
| Size | 521.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
e3ee45f3ada13a4a00bbadb04092004ddd41abb932f742e70072371d6f7e4252
|
|
BLAKE2b-256 checksum How to use checksums |
1824b39607035d847d3f4396988692bc72d2870b232b8f049ffa8b856dd34dc0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.2.0 CPython/3.11.2
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by Google Cloud, verified by PyPI on Sep 9, 2026.
Transparency log













