
GP_ELITE
Genetic-programming symbolic regression — discover interpretable laws from your experimental data.
Declare your units and the search only ever builds dimensionally valid equations — a hard constraint, not a soft penalty. The operating envelope is measured, not claimed: how many points it needs, how its runtime grows, and where it fails.
🇫🇷 Version française

GP_ELITE searches for a mathematical formula linking your variables to a target, instead of a black box. It is built for small experimental datasets (≤10 variables) where you want to understand the relationship: degradation laws, sensor calibration, engineering correlations, dose-response curves, physical laws.
On five Feynman equations (without normalisation), the returned model recovers the exact law of four of them at every size from 25 to 10,000 points, in every run; the fifth, the nested rational form I.16.6, comes back exact at 1,000 points and more (at 2,000 in a form other than the textbook one), and in 5 of the 13 runs below. The five fits take 38 s in total at 1,000 points and 103 s at 10,000 on one core of our 4-core machine (benchmarks/feynman_scaling.py, version 1.2.0; the times depend on the machine).
Since 0.4 "Lawful" you can also declare the physical units of your columns — the search itself then only ever builds dimensionally sound expressions, instead of formulas that fit the numbers while breaking the physics (see Dimensional constraints below).
Pure Python / NumPy — no Julia, no compilation, no GPU. pip install and you're ready.
Three case studies on public data (Kepler's law with units, Hubble's measurements of 1929, Nikuradse's pipes) show what it returns on public data and what it does not find, and what GP_ELITE does not do lists its known limits, each with the measurement behind it.
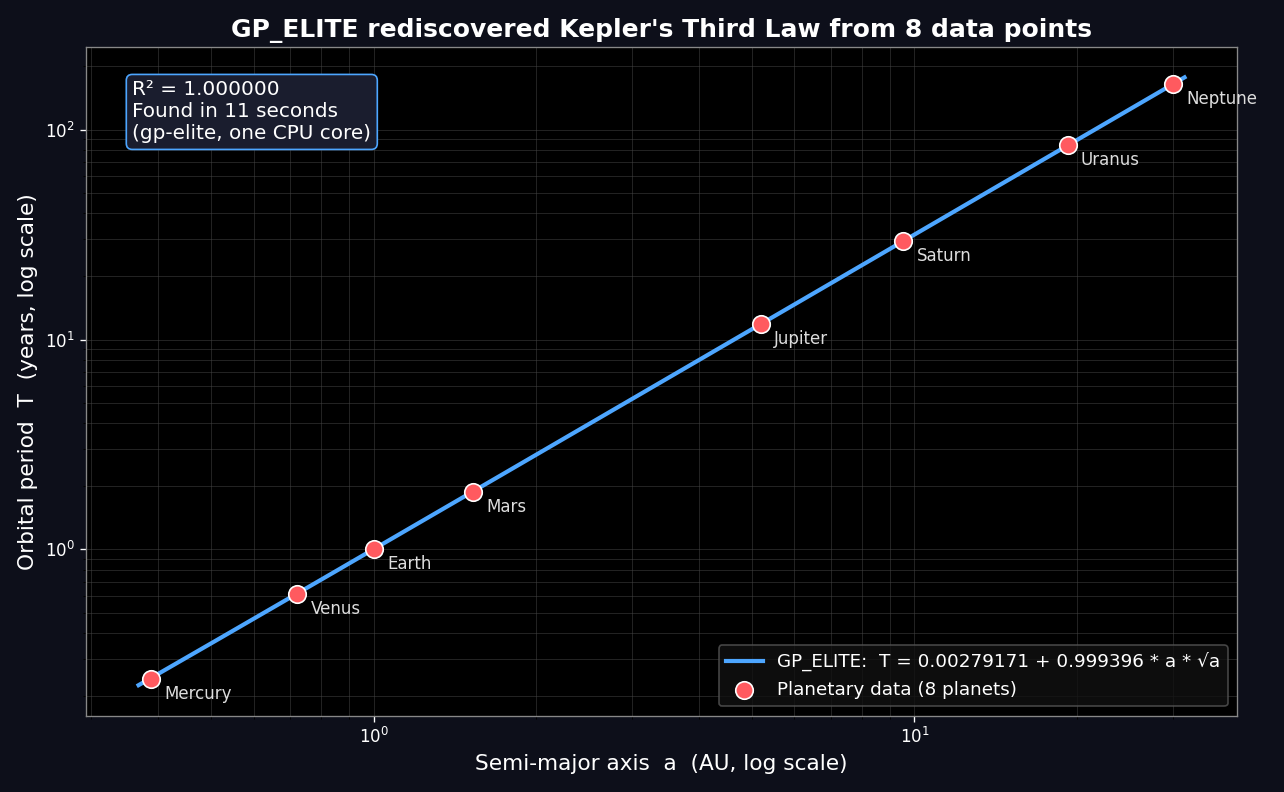
Given only the 8 planets' distance and orbital period, GP_ELITE rediscovered Kepler's Third Law,
T = a·√a = a^1.5— seeexamples/kepler_demo.py.
import numpy as np
from gp_elite import symbolic_regression

a = np.array([0.387, 0.723, 1.000, 1.524, 5.203, 9.537, 19.191, 30.069])   # AU
T = np.array([0.241, 0.615, 1.000, 1.881, 11.862, 29.457, 84.011, 164.79])  # years

result = symbolic_regression(a.reshape(-1, 1), T, feature_names=["a"], generations=40, seed=0)
print(result.expression)     # 0.00279171 + 0.999396 * a * sqrt(a)
The formula is written in your variables and units: in astronomical units and years, Kepler's constant is 1, and that is what comes back.
Is this for you?
You probably want GP_ELITE if at least one of these is true:
- You have a table of measurements and want the formula, not a prediction. A degradation curve, a sensor calibration, an engineering correlation. You care about the shape of the relationship, and you intend to read it, sanity-check it, maybe publish it.
- You cannot install a second language runtime. A locked-down university
machine, a corporate laptop without admin rights, a CI container you do not
control.
pip install gp-eliteand its three dependencies are all you need — no compiler, no Julia, no GPU. - You know the physical units of your columns. Declare them and the search will only ever build dimensionally sound formulas — and can tell you the units and value of a physical constant that is not in your data at all.
- You are teaching or learning genetic programming. The engine is plain Python you can read, step through and modify, and it ships with an interactive console that needs no code at all.
If none of these fit, other tools may serve you better: PySR and Operon are
faster and more accurate at scale — see Is it solid? below.
Installation
pip install gp-elite          # from PyPI
# or, from source:
git clone https://github.com/ariel95500-create/gp-elite
cd gp-elite && pip install -e ".[test]"
Dependencies: numpy, pandas, scikit-learn. Python 3.9 to 3.14, tested on Linux and Windows.
Usage
One line, on your own data (console UI)
gp-elite
Choose mode 6 (generic CSV), point to your file, and keep the defaults. GP_ELITE detects the columns, holds out a validation set, evolves, and prints the discovered law — written in your own column names and units, checked against its own predictions on your data.
Mode 6 also asks for the physical units of your columns. Declaring them is optional, and skipping is one keystroke — but if you do declare them, the search is restricted to dimensionally consistent formulas, and the engine can deduce the units and value of a missing physical constant. On a two-column CSV of Hooke's law it returns:
  Units for ['elongation'], comma-separated : m
  Unit for TARGET 'force' : N
  Deduce an unknown constant? [y/N] : y
  ...
  Formula in YOUR columns (checked on your data):
    force = 250 * elongation
  Deduced constant units : [kg / s^2]
  Deduced constant value : 250
Programmatically (notebooks, pipelines)
import numpy as np
from gp_elite import symbolic_regression

rng = np.random.RandomState(0)
X = rng.uniform(1, 5, (200, 2))
y = 2.0 + 3.0 * np.sqrt(X[:, 0]) - 0.5 * X[:, 1]

if __name__ == "__main__":        # needed in scripts, see the note below
    result = symbolic_regression(
        X, y,
        feature_names=["a", "b"],
        operators="physical",     # 'physical' | 'trig' | 'full' | 'poly' | 'conserve'
        generations=60,
        speed="fast",             # 'ultrafast' | 'fast' | 'normal' | 'thorough'
        seed=0,
        parallel=False,           # the same model on every machine, see below
    )
    print(result.expression)      # 2 + 3 * sqrt(a) - 0.5 * b
    print(result.r2_validation)   # 1.0
    print(result.size)            # 33 (nodes of the engine's tree)
    print(result.sympy())         # the same formula, parsable by sympy
Here the search returns the law it was given, written in your variables: the
engine's tree has 33 nodes, and the formula printed from it is 2 + 3·√a − 0.5·b;
the fit checks that this formula reproduces predict(). That is not guaranteed. On a harder law the same budget returns an
approximation that fits the hold-out almost perfectly and is still not the law
(0.7 returned one for this very example); reading the formula is how you find out.
restarts= and speed="thorough" spend more compute on the exact form, without a
guarantee.
speed:'ultrafast' | 'fast' (default) | 'normal' | 'thorough'.'thorough'(population 400, four islands, 200 generations) is the regime for looking for an exact law; with twice the default number of generations, it is slower, and not guaranteed to do better. Withoutgenerations=ortime_limit=, since 1.2, it too stops once it no longer improves (patience=, below).time_limit=(seconds): the search stops cleanly at the deadline and returns the best model found so far, instead of being killed without a result; the generation under way and the final selection add a little (in the release measurement of 1.2.0, the 1,987 fits stopped by a budget of 30 s took 30.5 s at the median and 31.9 s at most). A search that finds an exact law ends before its budget: with 15 s on 3,000 rows (benchmarks/time_limit_check.py), the law came back at 6.3 s in sequence and 12.5 s with the islands in parallel.patience=(since 1.2): when the call sets neithergenerationsnortime_limit, the search stops once its error on the hold-out rows (the training rows when there are none) has not improved by 1 % in 30 generations, then polishes and selects as usual. A fit of a ten-point lab table then takes seconds: the six of the French TP notebook (examples/tp_six_lois.ipynb) take 48 s in all, against 194 to 198 s with 1.1.0 on the same machine, and return the same formulas. A call that sets its budget (generations=ortime_limit=) gets all of it, as in 1.1. An integer k applies a patience of k generations whatever the budget, and 0 turns it off.GPEliteRegressoralways sets its number of generations, so the stop does not act there.restarts=: independent evolutions whose candidates are merged before the final choice.
Your data. X can be a NumPy array, a list of rows or a pandas DataFrame,
whose column names then become the variable names; y a 1-D array or a single
column. A missing or infinite value is refused with the row and the column
concerned (remove or impute it first), and a non-numeric column is named in the
error. With 0.7, a missing value in y or in a column the law uses went through,
and the fit returned an unrelated formula without a warning
(benchmarks/bad_input_check.py). Values far from 1 need no preparation: a
target of order 1e-9 or 1e20 is divided internally by a power of ten, a column of
order 1e-19 by its largest absolute value (the default normalisation), and the
formula comes back in your units (up to 0.7, such a target returned a constant or
a wrong line, with a negative R², and no warning that the fit had failed).
Reproducibility. With the same seed, the same data and the same settings, a
fit returns the same model, run after run, without setting PYTHONHASHSEED
(required up to 0.7). Parallel islands follow another path than the sequential
search, and parallel=None turns them on from four cores: set parallel= too.
On another machine the model can still differ: NumPy computes functions such as
exp and tanh with the instructions the processor offers, which can change
the last digit of a value, and the search can then take another path.
Scripts and parallel islands. On machines with four cores or more, islands run
in parallel worker processes. Those workers are started with spawn on every
system (Linux included) and re-import your script, so keep the top-level code
under if __name__ == "__main__":, as above.
Without the guard GP_ELITE detects the situation, finishes on one core with the
islands in sequence, and says so once; the islands in sequence take another path
than in parallel, so the model can differ. Hence parallel=False in the example
above: with the islands in parallel (the default from four cores) it returns
another model, an approximation of R² 0.99998. Notebooks need nothing.
Reading the result
expressionis written in your variables. The engine searches on rescaled columns internally; the formula it returns has the rescaling folded back into its constants, and the fit checks that the formula reproducespredict()on your data (result.formula_exact).result.sympy()gives the same formula as a stringsympy.sympifycan parse, andresult.sympy_expr()the sympy expression itself, with one symbol per column: use it when a column name is also a sympy constant or function (sympifyreadsEas 2.718...,Ias √-1) or is not an identifier;sympy()warns in that case. (Before 0.7, the displayed constants were those of the internal scaled space.) Since 1.2, a power of a number is written as an exponential, and an exponential of one variable with its scale:0.00538504 + 5.05644 * 0.00614708^(0.2 * t)comes back as0.00538504 + 5.05644 * exp(-t / 0.981975). The rewritten formula is kept only if it passes the same check, so the model andformula_exactdo not change. The formula is the plain mathematical function: where one of the engine's numerical safety nets acts on your data (a power clipped because its base exceeds 100 or its exponent 6 in absolute value, or its value a million; a division by a denominator within 1e-8 of zero), or, rarely, where rounding ruins an ill-conditioned expression, it departs frompredict()on those rows,formula_exactis False and the fit warns. In the measurements of 0.8 (benchmarks/results_0.8/), that was the case for 6 of the 205 Feynman fits of the release at 30 s per fit, for none of 60 fits on standardised real data and 8 of 70 on real data in their own units (campaigns 5b and 6b), and for 1 of the 105 fits of the equal-work comparison (100 generations). The warning also says how many entries ofresult.paretohave an exact formula and names the most accurate of them: forcing an exact formula on the returned model costs accuracy (measured for 0.9 inbenchmarks/results_0.9/PLAN_PHASE2.md), so the choice is left to you.r2_validationis a selection score. The hold-out it is computed on is also used to choose the returned model among the candidates, so it is optimistic. To estimate how the formula generalises, keep a test set of your own out of the fit.result.paretolists the other non-dominated candidates, simplest first, each with its ownexpression,r2_validationandpredict.predict()checks what it is given. It expects as many columns as the fit had (a single sample isX.reshape(1, -1)), and returns NaN for a row with a missing or infinite input, where 0.7 returned 0.
🛡️ Robust regression (outlier-resistant custom loss)
Real-world data is dirty. A handful of outliers can drag an ordinary least-squares fit far from the true relationship. GP_ELITE ships a one-switch robust mode meant to follow the bulk of the data rather than a few extreme points.
result = symbolic_regression(X, y, feature_names=["x"], robust=True)
Under the hood, robust=True switches the objective to a Huber loss and rescales the final coefficients with an IRLS (Iteratively Reweighted Least Squares) procedure. It stays a compact, readable formula.
Measured behaviour (recovering y = 2x + 1; RMSE against the true law on the clean points, lower is better; five seeds, median and worst seed):
| outliers | default (MSE) | robust=True |
|---|---|---|
| 0 % | 0.063 [0.063] | 0.063 [0.063] |
| 10 % | 1.398 [1.398] | 0.237 [0.237] |
| 20 % | 1.925 [1.925] | 1.925 [1.925] |
On clean data the two modes return slightly different lines, equally close to the true
law. With 10 % outliers, robust mode cuts the error six-fold. With 20 %, on this
example, it does no better than the default: the default returns the same line for all
five seeds, pulled by the outliers (y = 4.23319 + 1.32825 * x), and robust mode the same
line for four seeds out of five. Robustness is a tool to try when you suspect outliers,
not a guarantee — compare both modes on data of your own.
(Up to 0.6 this table reported the best of three runs, picked by comparing with the
true law, which no user can do.)
Reproduce: python examples/robust_regression.py.
⚖️ Dimensional constraints (physical laws only)
Declare the units of your inputs and target, and GP_ELITE will only search expressions that are dimensionally sound — no more formulas that fit the numbers while being physically meaningless.
from gp_elite import GPEliteRegressor

est = GPEliteRegressor(
    units=["kg", "m/s"],      # units of X0, X1
    target_units="J",         # unit of the target
)
est.fit(X, y)
Units accept plain strings — SI bases (m kg s A K mol cd), common derived units
(N J W Pa Hz C V ohm T), and * / ^ ( ): "m/s", "kg*m/s^2", "s^-1",
"1" for dimensionless. Dimension dicts ({"m": 1, "s": -1}) work too, as do
per-name ({"X0": "kg"}) and per-index ({0: "kg"}) forms. A malformed string
("m/(s", "kg^", "m garbage") raises an error instead of being guessed.
Measured effect — Feynman II.11.3, x = q·Ef/(m·(w0²−w²)), 5 variables,
5 seeds, 40 generations, identical budget for the first two arms:
no units= |
units= |
no units=, 4x generations |
|
|---|---|---|---|
| dimensionally valid | 5 / 5 | 5 / 5 | 5 / 5 |
| exact law recovered (holds out of domain) | 5 / 5 | 5 / 5 | 5 / 5 |
| median test R² | 1.00000 | 1.00000 | 1.00000 |
| median out-of-domain R² | 1.00000 | 1.00000 | 1.00000 |
| median model size | 20 nodes | 20 nodes | 20 nodes |
| median seconds / run | 0 | 1 | 0 |
Since 1.0 this law is one of the forms the engine fits directly, a monomial times
a power of a binomial, and the fitted form is placed in the starting population.
Since 1.1 this holds under units= too, where a fitted form is placed only if it
passes the gate of dimensions every typed tree must pass: both searches return
the law in every run, in about a second. With 1.0, whose fitted forms did not act
under units=, the constrained search found it in two runs of five and ended the
other three on approximations (median of its five runs: 27 nodes, 27 s). Up to 0.9 the
unconstrained search returned no valid model on this law, even with four times the
generations: its models took the logarithm of a frequency, added kilograms or
hertz to pure numbers, or raised a quantity to an exponent in coulombs, and the
constraint was the only way to a valid answer. It still is for the laws the
engine does not fit directly. (Since 0.9 a typed generation costs 1.4 times an
untyped one, against 8.5 times with 0.8. With a budget set, as here, a search
stops early only on an exact law, so the runs that end on an approximation, and
every run on noisy data, go through all their generations; time_limit= bounds
them, and under the defaults, since 1.2, patience= does.)
What it does not do. On a test set drawn outside the training domain (w/w0
pushed from [0.20, 0.67] towards resonance at [0.70, 0.90]), the exact law holds
(R² = 1.00000) and approximations degrade: the three constrained runs of 1.0 that
ended on one had an out-of-domain R² of 0.32 to 0.65. Timings are from a 4-core
Linux machine, two runs at a time, with the islands in sequence
(parallel=False). Reproduce with benchmarks/ab_ood.py.
When to use it. To guarantee that whatever the engine returns is physically
meaningful, and to deduce the units and value of a constant (below, and the
Kepler case study,
where the units also rule out a term the data alone would add). Since 1.1 the
forms the engine fits directly act under units= as well: on the 41 Feynman
equations of the decision bench with their units, five seeds at 30 s per fit,
165 exact laws of 205 against 108 with 1.0, and 163 without units.
Not for black-box prediction: the constraint rules out
dimensionally wrong but numerically good approximations, so it can lower R²
when fitting is the goal rather than finding a law.
Laws with a dimensioned constant (unknown_constant=). By default, fitted
constants are dimensionless — the AI Feynman convention — which puts a law like
Hooke's F = k·x out of reach: no dimensionless constant can relate metres to
newtons, and the search correctly reports that nothing valid can be built. Set
unknown_constant=True and the leading constant is allowed to carry a
dimension, deduced by homogeneity:
est = GPEliteRegressor(units=["m"], target_units="N", unknown_constant=True)
est.fit(X, y)
est.constant_units_string()   # '[kg / s^2]'
est.constant_value_           # 250.0
The engine then reports not only the shape of the law but the units and value of the missing physical constant. Measured on three reference laws:
| law | structure recovered | deduced units | value | true |
|---|---|---|---|---|
Hooke F = k·x |
yes | kg / s² |
250 | 250 |
Newton F = G·m₁·m₂/r² |
yes | m³ / kg s² |
6.674e-11 | 6.674e-11 |
ideal gas P = nRT/V |
yes | kg m² / K mol s² |
8.314462618 | 8.314462618 |
The returned formula itself carries the physical constant: the benchmark prints
(249.99999999999997*X0) for Hooke and (8.314462617999999*((X0*X1)/X2)) for
the ideal gas.
Budget: 25 generations, two restarts.
Reproduce with benchmarks/test_constante_mystere.py. Requires units= and
target_units=. If the expression is not a monomial in the input columns
(m₁ + m₂, say), no single raw constant exists and constant_value_ is None
while the deduced units remain valid.
Limitation. Under units= the internal linear scaling is multiplicative
only (no additive offset), which keeps every candidate dimensionally homogeneous.
Example on simulated battery-ageing data
python examples/battery_soh.py
The file examples/nasa_battery_simulation.csv
holds 168 simulated charge cycles (cycle number, temperature, current, capacity
state of health). Its origin is not documented beyond its name, so treat this as a
demonstration of the workflow, not as a result on real batteries. On it, the script
prints (abridged):
PROTOCOL 1 — random split (INTERPOLATION, leaks info)
  GP_ELITE      R² = +0.993
  RandomForest  R² = +0.997
  XGBoost       R² = +0.997

PROTOCOL 2 — forward split (EXTRAPOLATION): train on cycles 1..142, predict 143..168
  RandomForest (300)      R² = -2.521
  XGBoost (300 trees)     R² = -2.324
  GP_ELITE (one equation) R² = +0.162

  Equation: SOH = 0.428836 + 0.111661 * courant * exp(courant / 1.939) - 0.0181691 * sqrt(cycle)
A random split of sequential data is interpolation and flatters every method. On the forward split, the tree ensembles can only repeat values seen in training and fall far below the mean. The equation 1.0 to 1.2 return (1.2 writes its exponential with its scale), in the current and the cycle, does better than them, but not well (R² +0.16); 0.8 and 0.9 returned one at R² −0.31, below the mean too, and 0.7 one in the cycle and the current that kept following the trend (R² +0.594). A formula can extrapolate where a tree ensemble cannot; whether it does depends on which formula the search returns — on this simulated set, to be checked on yours.
Is it solid?
A fair question for a project you have never heard of. Here is where it stands against the alternatives, and where it does not.
| GP_ELITE | Neural networks | PySR (state of the art) | |
|---|---|---|---|
| Output | readable formula | black box | readable formula |
| Installation | pip install (pure Python) |
heavy | requires Julia |
| Held-out validation | built in (used for model selection) | do it yourself | do it yourself |
| Physical units | hard constraint during search (units=) |
no | soft penalty (X_units=) |
| Stability of the answer | bootstrap report (stability_analysis) |
no | no |
| Speed and accuracy at scale | lower | — | higher |
The last row is not a measurement of this project: it is a concession, from the published results of the compiled engines.
How changes are decided. Since 0.8, a change meant to improve the search or
the final selection becomes part of the default behaviour only if it passes a
comparison written in advance: the hypothesis and the decision criteria are
committed before the first run
(benchmarks/results_0.8/PLAN.md;
the plan of the first campaign was committed six minutes after its first fit had
started), the engine with the change is compared with the engine without it on 41
Feynman equations and on real datasets (six standardised, seven in their own
units) at 30 seconds per fit, one process per fit, and the results are published
whatever they are
(RESULTS.md),
including the changes that did not pass. When a change failed and a restricted
version of it was then tested, the restriction was designed after seeing the
failure and measured on the same problems; RESULTS.md says where. Corrections of
defects are not decided this way; the files of benchmarks/results_0.8/ show what
they change. The changes of 1.0 were decided the same way
(benchmarks/results_0.9/,
PLAN_PHASE4.md and PLAN_PHASE5.md), and since 0.9 each release is also
measured once on a test set frozen before any decision and never used to make
one: 78 other Feynman equations, 14 Strogatz systems and 25 real datasets. On its
Feynman equations, 1.0 recovers 213 exact laws of 390 against 145 for 0.9 measured
beside it; on its Strogatz systems, 7 exact fits of 70 against 8; on its real
datasets, the same median R² within 0.004 and the same number of collapses out of
the training range
(release_1.0/).
The change of 1.1 was decided the same way
(benchmarks/results_1.1/).
Measured beside 1.0 for the release of 1.1, both versions give the same counts of
exact laws without units on the frozen set (213 exact laws of 390 on its Feynman equations, 8
of 70 on its Strogatz systems: under a time budget the counts move a little from
one campaign to the next), and with their units 1.1 recovers 226 exact laws of 390
against 169. The changes of 1.2 were decided the same way
(benchmarks/results_1.2/);
measured beside 1.1 for the release of 1.2, both versions give the same counts on
the frozen set, with and without units (214 exact laws of 390 on its Feynman
equations, 10 of 70 on its Strogatz systems, and 229 of 390 with units).
GP_ELITE's niche: zero barrier to entry. A lab engineer, a student, or a technician points at a CSV file and gets a validated law back — without becoming a developer. PySR and Operon are faster and more accurate on large or hard problems; GP_ELITE does not claim otherwise.
What is GP_ELITE good (and less good) at?
Good at: physical / engineering laws with multiplicative or exponential structure, modest-size experimental data, problems where interpretability matters most.
On the frozen Feynman benchmark (15 physics equations, restarts=4, one seed),
judged on the model it returns: 15/15 exact symbolic recoveries (1−R² < 1e-9 on
held-out data), against 12/15 for 0.9; the three it adds are I.16.6 (relativistic
velocity addition, a nested rational form that is not among the forms 1.0 fits
directly, reached by the search) and two laws with a sine or a cosine, I.18.12
(r·F·sin θ) and III.15.12, which 1.0 fits directly. Head-to-head against
gplearn on identical data and splits (population 2000 × 30 generations), each
method judged on its returned model: 15/15 against 6/15 exact, 15/15 against 7/15
within 1e-3 — GP_ELITE ahead on 9 equations and tied on 6. Up to 0.9, a law with an
angle inside a sine or a cosine called for normalize='none', since dividing an
angle by its largest value changes the period the sine has to find (measured for
0.9 on the ten trigonometric laws of the 41-equation bench with five seeds each: 13
of 50 fits exact against 2 of 50 with the default; on real data, leaving the columns
of close scales as given, normalize='smart', predicted worse out of the training
range,
benchmarks/results_0.9/PLAN_TRIG.md);
with 1.0 the default returns the three laws of this showcase that have one, and
normalize='none' remains worth a try when such a law does not come back. With the
physical units declared (units=, same budget, no normalisation), 15/15 come back
exact (benchmarks/feynman_units.py), 14 in their textbook form; I.16.6, missed up
to 1.0, comes back with a factor 1.00758 above and below that cancels. One seed on
fifteen equations is
a showcase, not a statistical comparison:
benchmarks/results_0.8/RESULTS.md
measures 0.7.0 and each change of 0.8 to the search and the final selection on 41
equations with five seeds at 30 s per fit, and 0.7.0 against 0.8.0 side by side at
equal work on these fifteen equations with five seeds and on six real datasets.
Reproduce: python benchmarks/feynman_bench.py 0 15 and python benchmarks/duel.py.
Less good at: chaotic sequences (e.g. Collatz flight time — an intrinsically random component), >15–20 variables (the search space explodes — though units= substantially narrows it when physical units are known), large datasets where raw accuracy outweighs interpretability (ensemble models dominate there).
Technical features
- Stop on patience (v1.2): when the call sets neither
generationsnortime_limit, the search stops once its hold-out error (its training error when there is no hold-out) has not improved by 1 % in 30 generations (patience=) - Exponentials written as such (v1.2): a power of a number is printed as an
exponential, and an exponential of one variable with its scale,
exp(-t / τ), each kept only if it passes the check againstpredict() - Forms fitted directly (v1.0): a monomial times a power of a binomial, b·f·(1 + c·g)^p with p one of −1, −½, ½, 1 (rational laws, 1/√(1 − v²/c²), the root of a sum of two terms), and a monomial times a function of a monomial, b·f·exp(c·g), b·f·log(c·g), b·f·tanh(c·g), b·f/cosh(c·g) or f·(a + β·sin(ω·g) + γ·cos(ω·g)): each is fitted by a one-dimensional search and least squares, and placed in the starting population when it holds to numerical precision
- Noise-tolerant seeds (v1.0): when no form holds exactly, the power law and the forms above are sought again with their thresholds lifted, and placed if they leave at most 1.5 % of the variance unexplained
- Power-law seeds (v0.8): when the data follow a power law, the monomial fitted on the logarithms starts in the population
- Exact-law polish (v0.8): finalists get converged constants and a coefficient per term of each sum; a variant is admitted only if it is exact
- Constants fitted for the judged form (v0.8): Levenberg–Marquardt in variable projection (the scale and offset of the linear scaling solved inside the residual)
- Scale-free data (v0.8): a target of any magnitude is divided internally by a power of ten, and the default normalisation divides each column by its largest absolute value
- Formula in your variables, checked (v0.7): the internal rescaling is folded back into the constants;
formula_exactreports whether the formula reproducespredict()on the training data - Time budget (v0.7):
time_limit=stops cleanly and returns the best model found; underunits=, the typed start respects it too since v1.2 - Mystery-constant deduction (v0.5): the leading constant may carry a dimension, inferred by homogeneity; units and raw value exposed on the estimator, the value read on the predictions when the model is a monomial (v1.0)
- Dimensionally-constrained search (v0.4): constructive typed generation, dimension-preserving mutation and crossover, validity gate in
fitness()— one semantics shared with the post-hoc auditor (v0.7) - Scale-only linear scaling under
units=(v0.4.1): regression through the origin, so the form that is scored is the form that is delivered - Numerical guard in the LM optimizer (v0.4): no more float64 overflow on unbounded
sq/cube/*chains - Post-hoc dimensional audit (v0.3):
dimensions.py - Levenberg–Marquardt constant optimization (v0.2): deterministic, LM/Adam switchable
- Multi-restart + merged candidate archives (v0.2): seed variance turned into reliability
- Pareto front API (v0.2): non-dominated complexity/accuracy staircase
- Guarded extrapolation / forecasting mode (v0.2): beyond-domain probes, linear floor, frontier selection
- Composition motif seeding (v0.2): Pythagorean, reciprocal-sum, Gaussian templates for nested structures
- Asymmetric island model (explorer / cleaner / stigmergic) with periodic migration, in parallel worker processes on machines with four cores or more
- Linear scaling (Keijzer 2003): the engine searches for the shape; scale and offset are solved in closed form
- ε-lexicase selection (La Cava 2016) to preserve behavioral diversity
- Hold-out validation + parsimonious champion selection (R² tolerance)
- Shift-free normalization preserving multiplicative structure (x·y stays a clean product), for all data since 0.7
- Stigmergic memory exportable across runs (grammar export/import) — a documented feature, not a measured performance advantage
What's new
1.2 "Classroom" — a fit under the defaults stops once it no longer improves
(patience=): the six laws of the French TP notebook in 48 s, against 194 to
198 s for 1.1.0 on the same machine, with the same formulas; an exponential
comes back written as one, exp(-t / τ), the model unchanged; under units=,
Feynman III.19.51 without noise ends in about a second, where 1.1.0 took about
six minutes with a budget of 30 s. With a budget set, the models of 1.1 at equal work,
but for those whose typed start under units= the correction changes (III.19.51 on the
bench): in the 2,780 fits of the release measurement, no fit changes status. 1.1 "Coherent" — the forms 1.0 fits directly act under units= too, each placed only if
it passes the gate of dimensions: on the 41 Feynman equations of the decision
bench with their units, 165 exact laws of 205 against 108 for 1.0 measured beside
it; every one of the 1,005 models returned under units in the release
measurement (these equations with and without noise, and the frozen test set)
passed the audit of units; without units, the models of 1.0 at equal work. 1.0 "Families" — whole families of laws fitted directly (rational forms, roots,
exponentials, logarithms, sines and cosines of a monomial), on noisy data too: on
the 41 Feynman equations of the decision bench, 163 exact laws of 205 against 88
for 0.9 measured beside it, and on 78 other Feynman equations frozen before the
work, 213 of 390 against 145 (on the 14 Strogatz systems frozen with them, 7 of 70
against 8); on real data, the same median R² within 0.004 and the same number of
collapses out of the training range; three case studies on public data and a page of
what the engine does not do. 0.9 "Steady" — the search with units= faster, with the same models (more
than five times on Feynman II.11.3); a formula that departs from the model names
the exact formulas of the Pareto front; a test set frozen before any decision and
never used to make one, on which each release is measured. 0.8 "Swift" — faster (the speed-ups alone return the same models), more laws
recovered (power laws seeded, right structures finished into exact laws), data of
any scale, inputs checked; every change meant to improve the search decided by a
comparison written before it ran. 0.7 "Sound" — the formula you get is the model you got: written in your
variables for every normalisation and checked at fit time; a time_limit=
budget; dimensional guarantees made strict; every number of its README
re-measured on its final code. 0.6 "Bench" — physical units in the
console. 0.5 "Unknown" — units and value of a law's missing constant.
0.4 "Lawful" — dimensionally-constrained search. 0.3 "Trust" —
diagnostics and stability.
Full history, with the measurements behind each claim, in
CHANGELOG.md. Every benchmark behind a number here lives in
benchmarks/, with its raw results.
Did it fail on your data? Please say so
GP_ELITE is tuned on published benchmarks — Feynman, Strogatz — which are clean, noise-free and well-scaled. Real measurements are none of those things, and that gap is where the engine most needs work.
So if it returns nonsense on your data, that is useful information, not user error. Open an issue with the shape of your data and what you got back. You do not need to share the data itself, you do not need to know why it failed, and you can write in English or French.
Failure reports on real measurements are the single most valuable contribution this project can receive. See CONTRIBUTING.md.
Tests
pip install -e ".[test]"
python -m pytest tests/ -q
tests/test_guarantees.py pins down every defect found so far — each test was
checked to fail on the code that had the defect. The suite runs on every push
that changes code (Linux, Python 3.9–3.14, and Windows).
License
MIT — see LICENSE. Free to use, including commercially, with retention of the copyright notice.
Citing GP_ELITE
If GP_ELITE is useful in academic work, see CITATION.cff.
1 maintainer

Metadata
1 maintainer
Release files for gp-elite 1.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| gp_elite-1.2.0.tar.gz | 288.0 kB | Without provenance | Details for gp_elite-1.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| gp_elite-1.2.0-py3-none-any.whl | Python 3 | none | any | Details for gp_elite-1.2.0-py3-none-any.whl |
Total release size: 518.6 kB
Release files / gp_elite-1.2.0.tar.gz
| Download URL | gp_elite-1.2.0.tar.gz |
|---|---|
| Size | 288.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
3b8db7273f52ed1332afeeb12f23edcdfa54ec3bfcbfb956f8f8dd9275cfcfda
|
|
BLAKE2b-256 checksum How to use checksums |
5f0e450814402fc2b766cf80e1957506302f9a8cf95e49a7ad03c2b558b3cc20
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.4
|
Release files / gp_elite-1.2.0-py3-none-any.whl
| Download URL | gp_elite-1.2.0-py3-none-any.whl |
|---|---|
| Size | 230.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
052ee69a173289bf23396268104b7012b6d233c9b3f4e23bad307c98d879c7e5
|
|
BLAKE2b-256 checksum How to use checksums |
c46ef991e85bd1fd23fcec936fd37740554be90143dd4ca32fdfda8d2da1b5df
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.14.4
|
Security for gp-elite 1.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














