
Green-Bit-LLM
This Python package uses the Bitorch Engine for efficient operations on GreenBitAI's Low-bit Language Models (LLMs). It enables high-performance inference on both cloud-based and consumer-level GPUs, and supports full-parameter fine-tuning directly using quantized LLMs. Additionally, you can use our provided evaluation tools to validate the model's performance on mainstream benchmark datasets.
News
- [2025/5]
- Qwen-3 and Deepseek support.
- [2024/10]
- Langchain integration, model server support.
- [2024/04]
- We have launched over 200 low-bit LLMs in GreenBitAI's Hugging Face Model Repo. Our release includes highly precise 2.2/2.5/3-bit models across the LLM family, featuring LLaMA 2/3, 01-Yi, Qwen, Mistral, Phi-3 and more.
- We released Bitorch Engine for low-bit quantized neural network operations. Our release support full parameter fine-tuning and parameter efficiency fine-tuning (PEFT), even under extremely constrained GPU resource conditions.
LLMs
We have released over 260 highly efficient 2-4 bit models across the modern LLM family, featuring Deepseek, LLaMA, Qwen, Mistral, Phi, and more. Explore all available models in our Hugging Face repository. green-bit-llm is also fully compatible with all 4-bit models in the AutoGPTQ series.
Installation
This package depends on Bitorch Engine and a first experimental binary release for Linux with CUDA 12.1 is ready. We recommend to create a conda environment to manage the installed CUDA version and other packages.
Conda
We recommend using Miniconda for a lightweight installation. Please download the installer from the official Miniconda website and follow the setup instructions.
After Conda successfully installed, do the following steps:
- Create Environment for Python 3.10 and activate it:
conda create -y --name bitorch-engine python=3.10
conda activate bitorch-engine
- Install target CUDA version:
conda install -y -c "nvidia/label/cuda-12.1.0" cuda-toolkit
- Install bitorch engine:
Inference ONLY
pip install \
"https://packages.greenbit.ai/whl/cu121/bitorch-engine/bitorch_engine-0.2.6-cp310-cp310-linux_x86_64.whl"
Training REQUIRED
Install our customized torch that allows gradients on INT tensors and install it with pip (this URL is for CUDA 12.1 and Python 3.10 - you can find other versions here) together with bitorch engine:
pip install \
  "https://packages.greenbit.ai/whl/cu121/torch/torch-2.5.1-cp310-cp310-linux_x86_64.whl" \
  "https://packages.greenbit.ai/whl/cu121/bitorch-engine/bitorch_engine-0.2.6-cp310-cp310-linux_x86_64.whl"
- Install green-bit-llm:
via pypi
pip install green-bit-llm
or from source
git clone https://github.com/GreenBitAI/green-bit-llm.git
cd green-bit-llm
pip install -r requirements.txt
Note: For Qwen3 model support, you need to install the development version of transformers:
pip install git+https://github.com/huggingface/transformers.git
This installs transformers version 4.53.0.dev0 which includes the necessary Qwen3 model support.
- Install Flash Attention (
flash-attn) according to their official instructions.
pip install flash-attn --no-build-isolation
Examples
Simple Generation
Run the simple generation script as follows:
CUDA_VISIBLE_DEVICES=0 python -m green_bit_llm.inference.sim_gen --model GreenBitAI/Qwen-3-1.7B-layer-mix-bpw-4.0 --max-tokens 1024 --use-flash-attention-2
FastAPI Model Server
A high-performance HTTP API for text generation with GreenBitAI's low-bit models.
Quick Start
- Run:
CUDA_VISIBLE_DEVICES=0 python -m green_bit_llm.serve.api.v1.fastapi_server --model GreenBitAI/Qwen-3-1.7B-layer-mix-bpw-4.0 --host 127.0.0.1 --port 11668
- Use:
# Chat
curl http://localhost:11668/v1/GreenBitAI-Qwen-3-17B-layer-mix-bpw-40/chat/completions -H "Content-Type: application/json" \
  -d '{"model": "default_model", "messages": [{"role": "user", "content": "Hello!"}]}'

# Chat stream
curl http://localhost:11668/v1/GreenBitAI-Qwen-3-17B-layer-mix-bpw-40/chat/completions -H "Content-Type: application/json"  \
  -d '{"model": "default_model", "messages": [{"role": "user", "content": "Hello!"}], "stream": "True"}'
Full-parameter fine-tuning
Full parameter fine-tuning of the LLaMA-3 8B model using a single GTX 3090 GPU with 24GB of graphics memory:
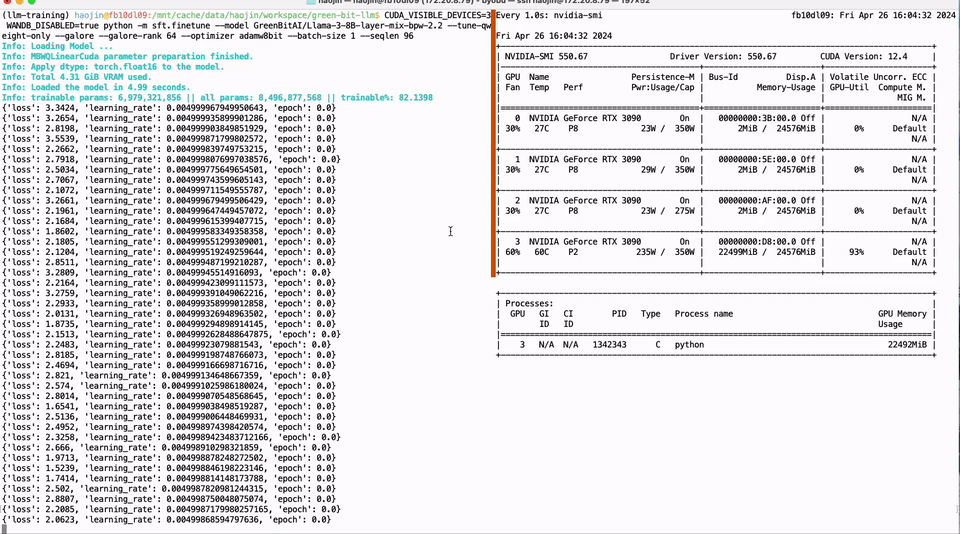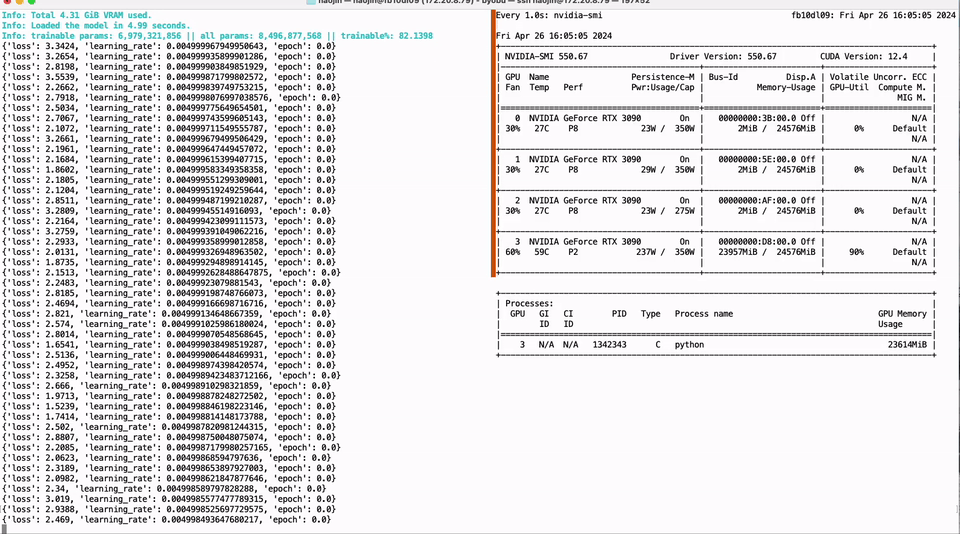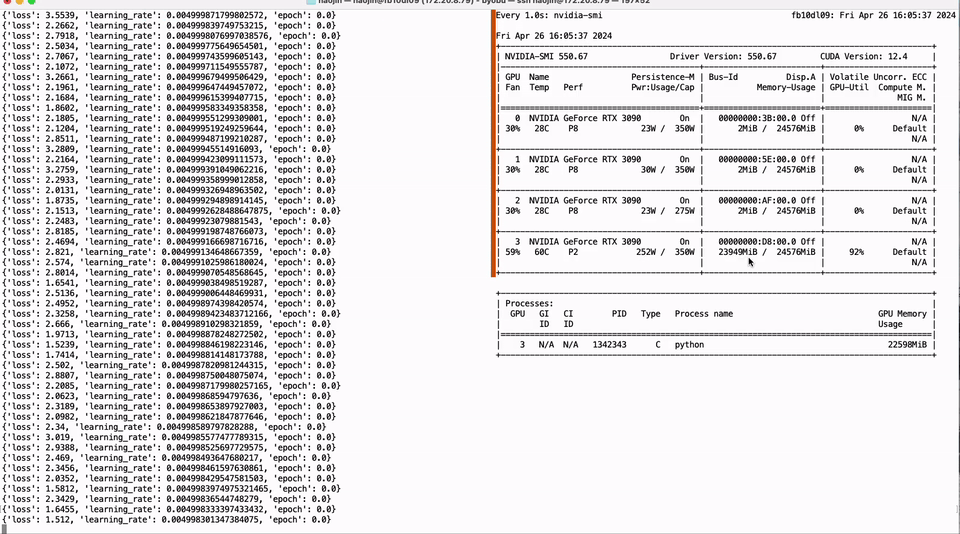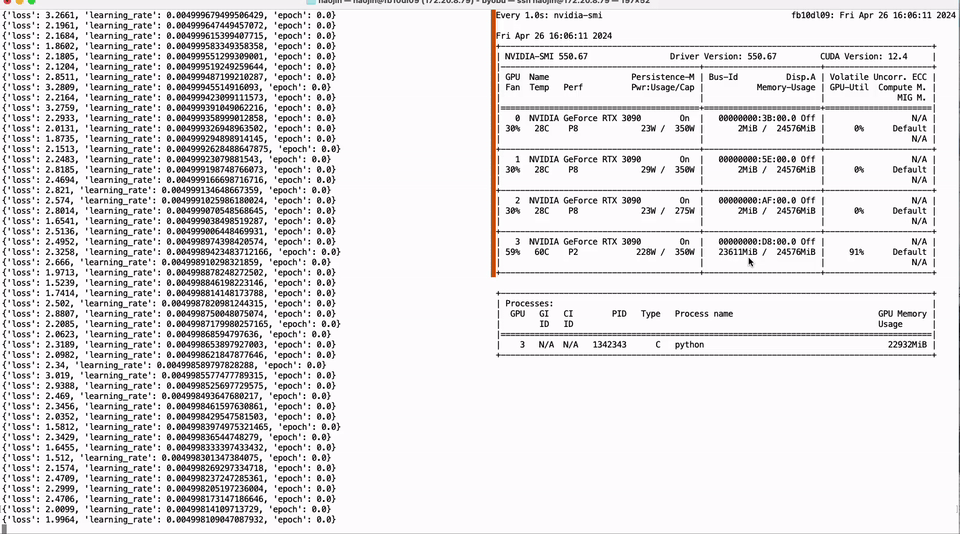
Run the script as follows to fine-tune the quantized weights of the model on the target dataset. The '--tune-qweight-only' parameter determines whether to fine-tune only the quantized weights or all weights, including non-quantized ones.
CUDA_VISIBLE_DEVICES=0 python -m green_bit_llm.sft.finetune --model GreenBitAI/Qwen-1.5-1.8B-layer-mix-bpw-3.0 --dataset tatsu-lab/alpaca --optimizer DiodeMix --tune-qweight-only

# AutoGPTQ model Q-SFT
CUDA_VISIBLE_DEVICES=0 python -m green_bit_llm.sft.finetune --model astronomer/Llama-3-8B-Instruct-GPTQ-4-Bit --dataset tatsu-lab/alpaca --tune-qweight-only --batch-size 1
Parameter efficient fine-tuning
PEFT of the 01-Yi 34B model using a single GTX 3090 GPU with 24GB of graphics memory:
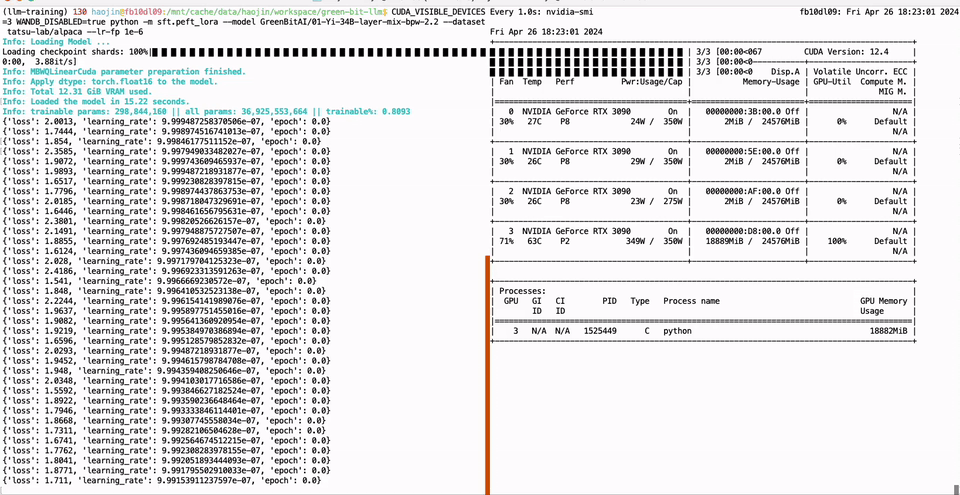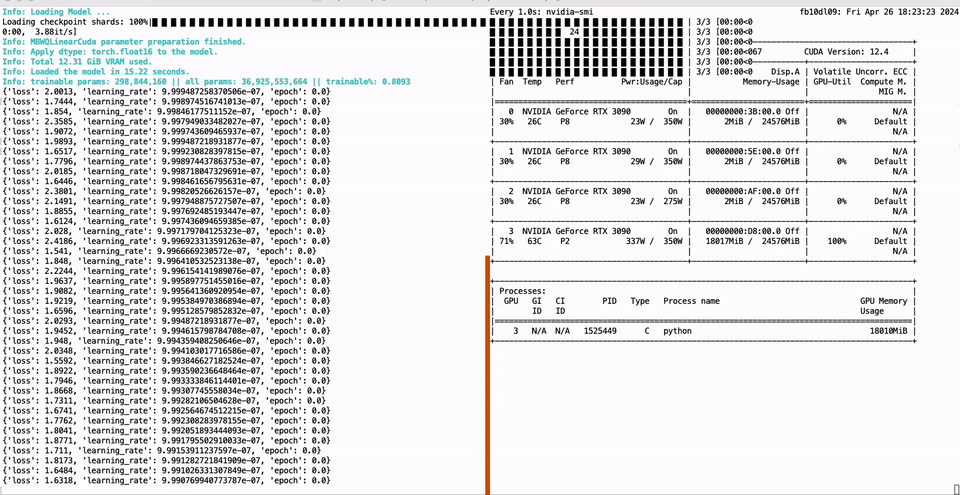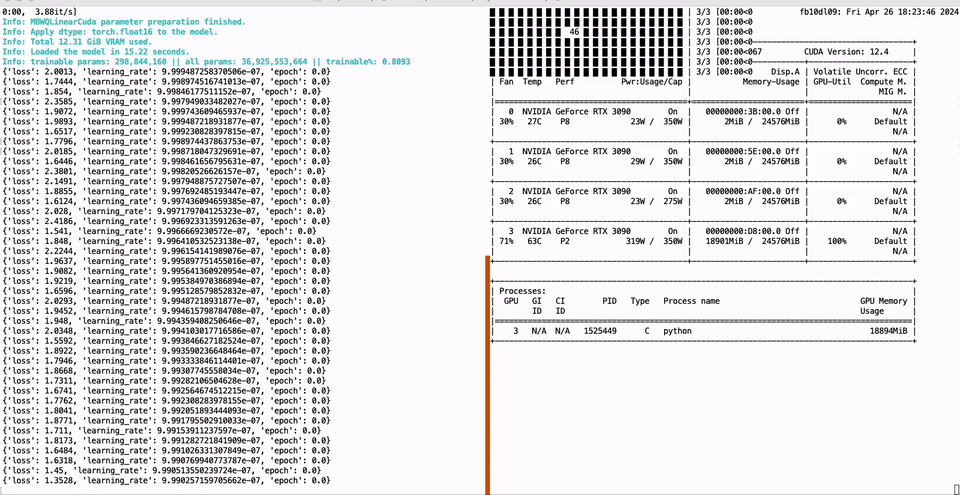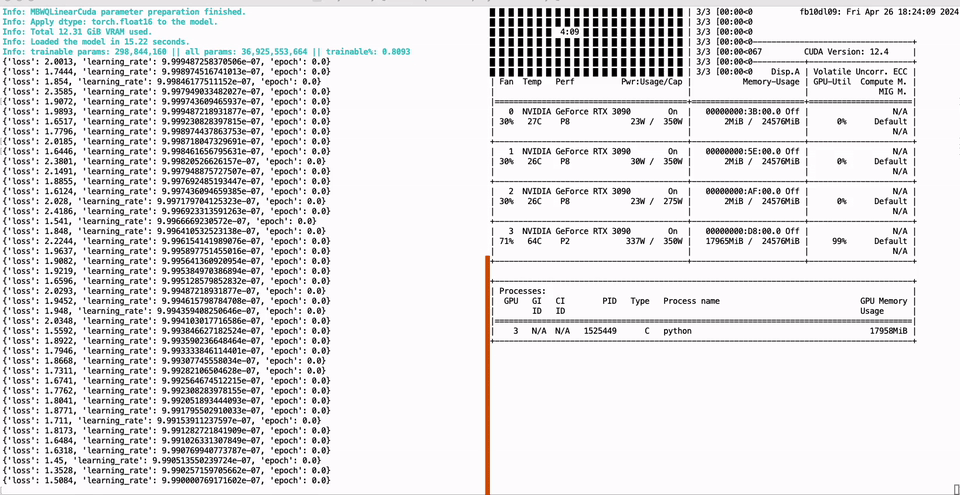
CUDA_VISIBLE_DEVICES=0 python -m green_bit_llm.sft.peft_lora --model GreenBitAI/Qwen-1.5-1.8B-layer-mix-bpw-3.0 --dataset tatsu-lab/alpaca --lr-fp 1e-6

# AutoGPTQ model with Lora
CUDA_VISIBLE_DEVICES=0 python -m green_bit_llm.sft.peft_lora --model astronomer/Llama-3-8B-Instruct-GPTQ-4-Bit --dataset tatsu-lab/alpaca --lr-fp 1e-6
Further Usage
Please see the description of the Inference, sft and evaluation package for details.
License
We release our codes under the Apache 2.0 License. Additionally, three packages are also partly based on third-party open-source codes. For detailed information, please refer to the description pages of the sub-projects.
2 maintainers


Metadata
2 maintainers
Release files for green-bit-llm 0.2.6
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| green_bit_llm-0.2.6.tar.gz | 85.9 kB | Without provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| green_bit_llm-0.2.6-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 190.6 kB
Release files / green_bit_llm-0.2.6.tar.gz
| Download URL | green_bit_llm-0.2.6.tar.gz |
|---|---|
| Size | 85.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
6454ba342031ce34eb996ae365d222e3a6a321e24e4e5cd1a99f2278b2b88113
|
|
BLAKE2b-256 checksum How to use checksums |
b194bb2cdd768dc26a168ca15be550b149715a54980b78a3fc8904066dd504c4
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/5.1.1 CPython/3.9.20
|
Release files / green_bit_llm-0.2.6-py3-none-any.whl
| Download URL | green_bit_llm-0.2.6-py3-none-any.whl |
|---|---|
| Size | 104.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
d12b05aacfe5b1f71f52c9640768b0418f2686126bf89dab16f5cbe91113bd38
|
|
BLAKE2b-256 checksum How to use checksums |
ef9adb2137eb4db63eae59d439fe41c46357e28de48cc83dde311d88516548cb
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/5.1.1 CPython/3.9.20
|
Security for green-bit-llm 0.2.6
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














