

GSV-TTS-Lite
A high-performance inference engine specifically designed for the GPT-SoVITS text-to-speech model



About
The original motivation for this project was the pursuit of ultimate performance. While using the original GPT-SoVITS, I found that the inference latency often struggled to meet the demands of real-time interaction due to the computing power bottlenecks of the RTX 3050 (Laptop).
To break through these limitations, GSV-TTS-Lite was developed as an inference backend based on GPT-SoVITS (V2/V2Pro/V2ProPlus). Through deep optimization techniques, this project successfully achieves millisecond-level real-time response in low-VRAM environments.
Beyond the leap in performance, GSV-TTS-Lite implements the decoupling of timbre and style, supporting independent control over the speaker's voice and emotion. It also features character-level timestamps alignment and voice conversion (timbre transfer).
To facilitate integration for developers, GSV-TTS-Lite features a significantly streamlined code architecture and is available on PyPI as the gsv-tts-lite library, supporting one-click installation via pip.
The currently supported languages are Chinese, Japanese, and English. The available models include V2, V2Pro and V2ProPlus.
Performance Comparison
| Backend | Settings | TTFT (First Packet) | RTF (Real-time Factor) | VRAM | Speedup |
|---|---|---|---|---|---|
| Original | streaming_mode=3 |
436 ms | 0.381 | 1.6 GB | - |
| Lite Version | Flash_Attn=Off |
150 ms | 0.125 | 0.8 GB | ⚡ 2.9x Speed |
| Lite Version | Flash_Attn=On |
133 ms | 0.108 | 0.8 GB | 🔥 3.3x Speed |
As shown, GSV-TTS-Lite achieves 3x ~ 4x speed improvements while halving the VRAM usage! 🚀
| GPU Model | Throughput (tok/s) | FlashAttention2 |
|---|---|---|
| RTX-PRO-6000 | 1122.72 | Enable |
| H200 | 886.47 | Enable |
| A100 | 660.73 | Enable |
| T4 | 281.06 | Disabled |
Core optimization technologies: CUDA Graph, Nested KV Cache, and Continuous Batching.
Deployment (For Developers)
Prerequisites
- CUDA Toolkit
Installation Steps
1. Environment Configuration
It is recommended to create a virtual environment using Python >=3.10.
# NVIDIA GPU (CUDA 12.8)
pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu128

# Apple Silicon (MPS) or Linux/Windows (CPU Only)
pip install torch torchvision torchaudio
2. Install GSV-TTS-Lite
If you have prepared the above basic environment, you can directly execute the following command to complete the integration:
pip install gsv-tts-lite==0.4.2.3
WebUI Visual Interface
- Install Dependencies:
cd WebUI
pip install -r requirements.txt
- Start the Program:
python web.py
API Service Interface
- Install Dependencies:
cd API
pip install -r requirements.txt
- Core Documentation: Go to API Detailed Guide Directory ➔
Python SDK Interface
1. Basic Inference
from gsv_tts import TTS

tts = TTS()
# tts = TTS(use_bert=True) # Recommended setting for better Chinese synthesis results.
# tts = TTS(use_flash_attn=True) # Recommended setting if Flash Attention is installed.

# Load GPT model weights from the specified path into memory; loads the default model here.
tts.load_gpt_model()

# Load SoVITS model weights from the specified path into memory; loads the default model here.
tts.load_sovits_model()

# Pre-load and cache resources to significantly reduce latency during the first inference.
# tts.init_language_module("ja")
# tts.cache_spk_audio("examples\laffey.mp3")
# tts.cache_prompt_audio(
#     prompt_audio_paths="examples\AnAn.ogg",
#     prompt_audio_texts="ちが……ちがう。レイア、貴様は間違っている。",
# )

# infer is the most rudimentary and basic inference method, suitable only for short text. It is generally recommended to use infer_batched instead of infer.
audio = tts.infer(
    spk_audio_path="examples\laffey.mp3", # Voice reference audio (Timbre)
    prompt_audio_path="examples\AnAn.ogg", # Style reference audio (Prompt)
    prompt_audio_text="ちが……ちがう。レイア、貴様は間違っている。", # The corresponding text for the style reference audio
    text="へぇー、ここまでしてくれるんですね。", # Target text to be generated
    # gpt_model = None, # Path to the GPT model for inference; defaults to the first loaded GPT model.
    # sovits_model = None, # Path to the SoVITS model for inference; defaults to the first loaded SoVITS model.
)

audio.play()
tts.audio_queue.wait()
# tts.audio_queue.stop() # Stop playback
https://github.com/user-attachments/assets/72635b40-7287-4318-a5e9-aea93adfabf9
2. Stream Inference / Subtitle Synchronization
import time
import queue
import threading
from gsv_tts import TTS

class SubtitlesQueue:
    def __init__(self):
        self.q = queue.Queue()
        self.t = None

    def process(self):
        last_i = 0
        last_t = time.time()

        while True:
            subtitles, text = self.q.get()

            if subtitles is None:
                break

            for subtitle in subtitles:
                if subtitle["start_s"] > time.time() - last_t:
                    time.sleep(subtitle["start_s"] - (time.time() - last_t))

                if subtitle["end_s"] and subtitle["end_s"] > time.time() - last_t:
                    if subtitle["orig_idx_end"] > last_i:
                        print(text[last_i:subtitle["orig_idx_end"]], end="", flush=True)
                        last_i = subtitle["orig_idx_end"]
                        time.sleep(subtitle["end_s"] - (time.time() - last_t))

        self.t = None

    def add(self, subtitles, text):
        self.q.put((subtitles, text))
        if self.t is None:
            self.t = threading.Thread(target=self.process, daemon=True)
            self.t.start()

tts = TTS(sovits_cache=[50, 55]) # 50 = stream_chunk * 2 = 25 * 2, 55 = stream_chunk * 2 + overlap_len = 25 * 2 + 5

# infer, infer_stream, and infer_batched all support returning character-level timestamps; infer_stream is used here just as an example.
subtitlesqueue = SubtitlesQueue()

# infer_stream implements token-level streaming output, significantly reducing first-token latency and enabling a ultra-low latency real-time feedback experience.
generator = tts.infer_stream(
    spk_audio_path="examples\laffey.mp3",
    prompt_audio_path="examples\AnAn.ogg",
    prompt_audio_text="ちが……ちがう。レイア、貴様は間違っている。",
    text="へぇー、ここまでしてくれるんですね。",
    stream_chunk = 25,
    overlap_len = 5,
    return_subtitles=True,
    debug=False,
)

for audio in generator:
    audio.play()
    subtitlesqueue.add(audio.subtitles, audio.orig_text)

tts.audio_queue.wait()
subtitlesqueue.add(None, None)
print()
https://github.com/user-attachments/assets/3d2758b3-a283-48b0-960e-a9389dd73129
3. Batched Inference
from gsv_tts import TTS

# TTS parameter gpt_cache: Static cache configuration for the GPT model's CUDA graph.
    # Expects a list of tuples: [(batch_size, sequence_length), ...].
    # Defining specific segments for batch_size and sequence_length based on your needs helps optimize CUDA memory usage and inference performance.
    # Note:
    # 1. The maximum batch_size determines the maximum throughput for batch processing.
    # 2. The maximum sequence_length within a batch determines the maximum generation length per request.

tts = TTS()

# infer_batched is optimized specifically for long-form text and multi-sentence synthesis scenarios. This mode not only offers significant advantages in processing efficiency but also supports assigning different reference audios to different sentences within the same batch, providing high synthesis freedom and flexibility.
audios = tts.infer_batched(
    spk_audio_paths="examples\laffey.mp3",
    prompt_audio_paths="examples\AnAn.ogg",
    prompt_audio_texts="ちが……ちがう。レイア、貴様は間違っている。",
    texts=["へぇー、ここまでしてくれるんですね。", "The old map crinkled in Leo’s trembling hands."],
    bert_batch_size=20,
    sovits_batch_size=10,
)

for i, audio in enumerate(audios):
    audio.save(f"audio{i}.wav")
https://github.com/user-attachments/assets/c2edeb24-b2a8-4360-9d68-8866efbed30c
4. Voice Conversion
from gsv_tts import TTS

tts = TTS(always_load_cnhubert=True)

# Although infer_vc supports zero-shot voice conversion and offers convenience, its conversion quality still has room for improvement compared to specialized voice conversion models like RVC or SVC.
audio = tts.infer_vc(
    spk_audio_path="examples\laffey.mp3",
    prompt_audio_path="examples\AnAn.ogg",
    prompt_audio_text="ちが……ちがう。レイア、貴様は間違っている。",
)

audio.play()
tts.audio_queue.wait()
5. Speaker Verification
from gsv_tts import TTS

tts = TTS(always_load_sv=True)

# verify_speaker is used to compare the speaker characteristics of two audio clips to determine if they are the same person.
similarity = tts.verify_speaker("examples\laffey.mp3", "examples\AnAn.ogg")
print("Speaker Similarity:", similarity)
6. Other Function Interfaces
1. Model Management
init_language_module(languages)
Preload necessary language processing modules.
load_gpt_model(model_paths)
Load GPT model weights from specified paths into memory.
load_sovits_model(model_paths)
Load SoVITS model weights from specified paths into memory.
unload_gpt_model(model_paths) / unload_sovits_model(model_paths)
Unload models from memory to free up resources.
get_gpt_list() / get_sovits_list()
Get the list of currently loaded models.
to_safetensors(checkpoint_path)
Converts PyTorch checkpoint files (.pth or .ckpt) into the safetensors format.
2. Audio Cache Management
cache_spk_audio(spk_audio_paths)
Preprocess and cache speaker reference audio data.
cache_prompt_audio(prompt_audio_paths, prompt_audio_texts, prompt_audio_languages)
Preprocess and cache prompt reference audio data.
del_spk_audio(spk_audio_list) / del_prompt_audio(prompt_audio_paths)
Remove audio data from the cache.
get_spk_audio_list() / get_prompt_audio_list()
Get the list of audio data in the cache.
3. Asynchronous Invocations
infer_async(...)
Asynchronous version of the infer method.
infer_stream_async(...)
Asynchronous version of the infer_stream method.
infer_batched_async(...)
Asynchronous version of the infer_batched method.
Flash Attn
If you are looking for lower latency and higher throughput, it is highly recommended to enable Flash Attention support.
Since this library has specific compilation requirements, please install it manually based on your system:
-
🐧 Linux / Build from Source
- Official Repo: Dao-AILab/flash-attention
-
🪟 Windows Users
- Pre-compiled Wheels: lldacing/flash-attention-windows-wheel
Credits
Special thanks to the following projects:
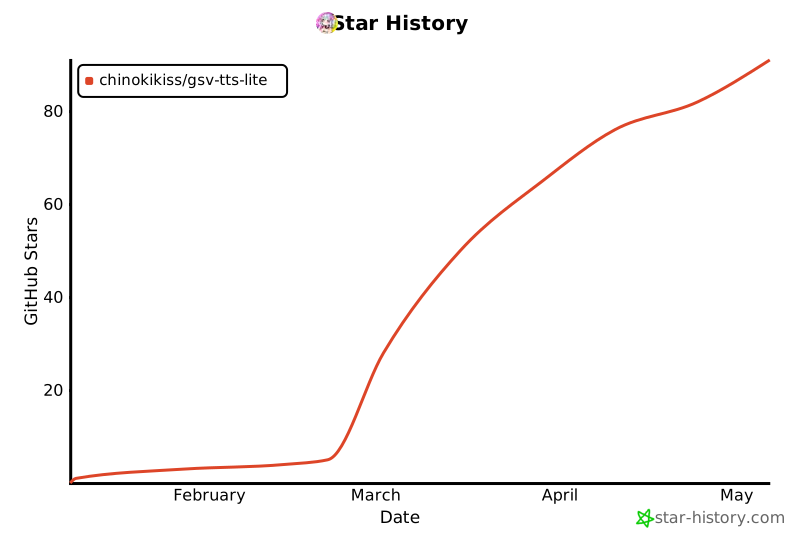
⭐ Star History
1 maintainer

Metadata
1 maintainer
Release files for gsv-tts-lite 0.4.7
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| gsv_tts_lite-0.4.7.tar.gz | 97.0 kB | Without provenance | Details for gsv_tts_lite-0.4.7.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| gsv_tts_lite-0.4.7-py3-none-any.whl | Python 3 | none | any | Details for gsv_tts_lite-0.4.7-py3-none-any.whl |
Total release size: 206.6 kB
Release files / gsv_tts_lite-0.4.7.tar.gz
| Download URL | gsv_tts_lite-0.4.7.tar.gz |
|---|---|
| Size | 97.0 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5a79c987583b3b339c5b653a32411a5868764f07bab54d06ad93341f54367d19
|
|
BLAKE2b-256 checksum How to use checksums |
559694db853ce3b31647252d6e49a3192405d731b5f42c7ccc4beec1627f0fea
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.11.14
|
Release files / gsv_tts_lite-0.4.7-py3-none-any.whl
| Download URL | gsv_tts_lite-0.4.7-py3-none-any.whl |
|---|---|
| Size | 109.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
70b8101bae0d53367fe750c75571a5eff43b97a455964eaacda1879f06a50b6a
|
|
BLAKE2b-256 checksum How to use checksums |
fc6c7002f46930a2666f1262f31fc524e8a4c6b63b11a75f9b0a46c18d76dd5a
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.11.14
|
Security for gsv-tts-lite 0.4.7
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














