
HGQ2: High Granularity Quantization 2


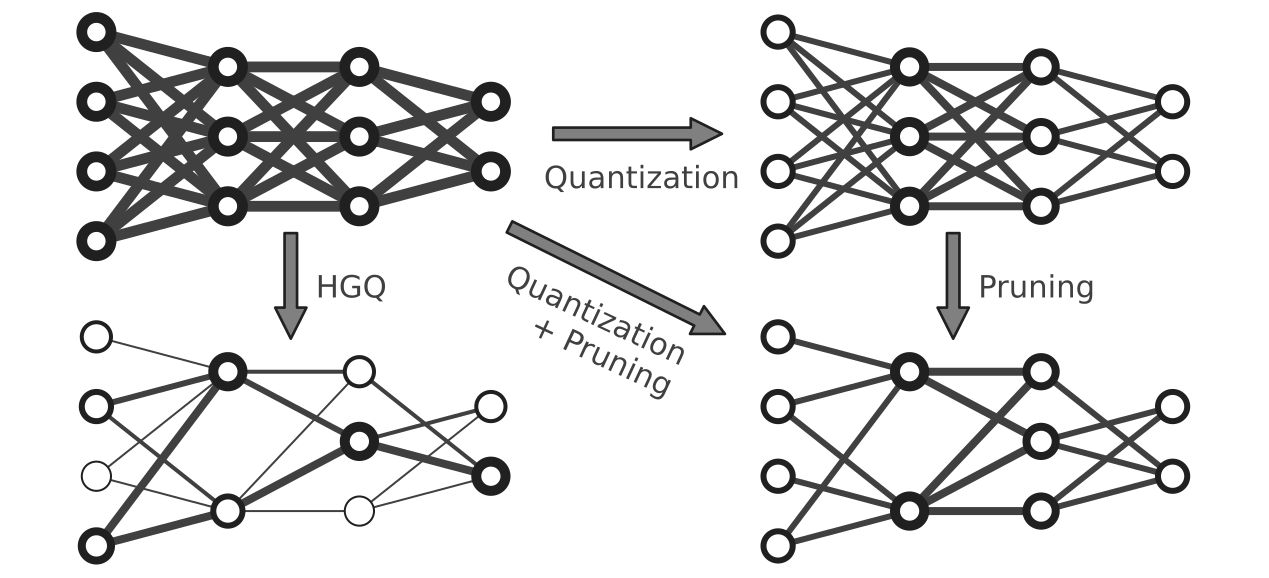
HGQ2 (High Granularity Quantization 2) is a quantization-aware training framework built on Keras v3, targeting real-time deep learning applications on edge devices like FPGAs. It provides a comprehensive set of tools for creating and training quantized neural networks with minimal effort.
HGQ2 implements an gradient-based automatic bitwidth optimization and quantization-aware training algorithm. By laveraging gradients, it allows for bitwidth optimization at arbitrary granularity, up to per-weight and per-activation level.
- High Granularity: HGQ supports per-weight and per-activation bitwidth optimization, or any other lower granularity.
- Automatic Quantization: Bit-widths are optimized via gradients, no need to manually tune them in general.
- What you see is what you get: One get exactly what you get from
Kerasmodels fromRTLmodels.- still subject to machine float precision limitation.
- Accurate Resource Estimation:
EBOPsestimated by HGQ gives a good indication of the actual resource usage on FPGA, either upper limit ofLUT(da4ml) orLUT + 55 * DSP(hls4ml).
In addition, this framework improves upon the old HGQ implementation in the following aspects:
- Scalability: HGQ2 supports
TensorFlow,JAX, andPyTorch. As XLA compilation inJAXandTensorFlowcan significantly speed up the training process. Training speed on HGQ2 can be 1.2-5 times faster than the previous implementation. - Quantizers:
- Fixed-point: While the last implementation only optimizes the number of floating bits with one way of parameterizing the fixed-point numbers, HGQ2 supports multiple ways of parametrizing them, and allows of optimizing any part of them via gradients.
- Minifloat: Training with minifloat quantization is supported, also with surrogate gradients support (alpha quality).
- More Layers: More layers are supported now, including the powerful
EinsumDense(BatchNorm)layer and theMultiHeadAttentionlayer with bit-accurate softmax and scaled dot-product attention.
Installation
pip install HGQ2
If you are using da4ml, please make sure it is at least version 0.6:
pip install da4ml>=0.6
If you are using hls4ml, please make sure it is at least version 1.2:
pip install hls4ml>=1.2.0
Usage
Please refer to the documentation for more details on how to use the library.
A minimal example is shown below:
   import keras
   from hgq.layers import QDense, QConv2D
   from hgq.config import LayerConfigScope, QuantizerConfigScope

   # Setup quantization configuration
   # These values are the defaults, just for demonstration purposes here
   with (
      # Configuration scope for setting the default quantization type and overflow mode
      # The second configuration scope overrides the first one for the 'datalane' place
      QuantizerConfigScope(place='all', default_q_type='kbi', overflow_mode='SAT_SYM'),
      # Configuration scope for enabling EBOPs and setting the beta0 value
      QuantizerConfigScope(place='datalane', default_q_type='kif', overflow_mode='WRAP'),
      LayerConfigScope(enable_ebops=True, beta0=1e-5),
   ):
      model = keras.Sequential([
         QConv2D(32, (3, 3), activation='relu'),
         keras.layers.MaxPooling2D((2, 2)),
         keras.layers.Flatten(),
         QDense(10)
      ])
Citation
If you use HGQ2 in your research, please consider citing the following paper:
@inproceedings{hgq,
  author = {Sun, Chang and Que, Zhiqiang and Aarrestad, Thea and Loncar, Vladimir and Ngadiuba, Jennifer and Luk, Wayne and Spiropulu, Maria},
  title = {HGQ: High Granularity Quantization for Real-time Neural Networks on FPGAs},
  year = {2026},
  isbn = {9798400720796},
  publisher = {Association for Computing Machinery},
  address = {New York, NY, USA},
  url = {https://doi.org/10.1145/3748173.3779200},
  doi = {10.1145/3748173.3779200},
  booktitle = {Proceedings of the 2026 ACM/SIGDA International Symposium on Field Programmable Gate Arrays},
  pages = {79–91},
  numpages = {13},
  keywords = {quantization-aware training, fpga, real-time inference, neural networks, hardware-software codesign, low-latency, quantization},
  location = {USA},
  series = {FPGA '26}
}
If LUT-based layers are used, please also cite the following paper:
@inproceedings{hgq-lut,
  author={Sun, Chang and Que, Zhiqiang and Zadeh, Bakhtiar and Liu, Qibin and Alvarez, Kevin H. and Luk, Wayne and Spiropulu, Maria},
  booktitle={2026 IEEE 34th Annual International Symposium on Field-Programmable Custom Computing Machines (FCCM)},
  title={HGQ-LUT: Fast LUT-Aware Training and Efficient Architectures for DNN Inference},
  year={2026},
  volume={},
  number={},
  pages={19-28},
  keywords={Modeling;Table lookup;Training;Field programmable gate arrays;Timing;Manuals;Hardware;Accuracy;Neural networks;Elementary particles;machine learning;lookup-based inference;quantization;co-design;fpga},
  doi={10.1109/FCCM68464.2026.00017},
  series = {FCCM '26}
}
1 maintainer

Metadata
1 maintainer
Release files for hgq2 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | |
|---|---|---|---|---|
| hgq2-0.2.0.tar.gz | 214.2 kB | With provenance | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| hgq2-0.2.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 339.3 kB
Release files / hgq2-0.2.0.tar.gz
| Download URL | hgq2-0.2.0.tar.gz |
|---|---|
| Size | 214.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
9b10d53d13c9c88ff68ff6258ff744294d36ccd66374069e2890255598c9a59e
|
|
BLAKE2b-256 checksum How to use checksums |
1e12c8da359b843b6e2e8a16058b7b6b35a9e1a09cdf8a0adae6ca2cde0000dd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 28, 2026.
Transparency logRelease files / hgq2-0.2.0-py3-none-any.whl
| Download URL | hgq2-0.2.0-py3-none-any.whl |
|---|---|
| Size | 125.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c47086535b2bae33bdd186590733f44cebd7a0160029cab2b1d3eb05cb8c1164
|
|
BLAKE2b-256 checksum How to use checksums |
9c8c0fe11c8254911e93ab403531884602c628928c07e8429c3084c744f13159
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 28, 2026.
Transparency logSecurity for hgq2 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for hgq2-0.2.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Aug 28, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














