
hindko-embeddings
Hindko text embeddings as a Python package. One install gives you semantic search, similarity, clustering and classification for Hindko text.
Hindko (Northern hno, Southern hnd) is the Indo-Aryan language of Peshawar, Hazara and Kohat in Khyber Pakhtunkhwa, Pakistan, written in Urdu (Perso-Arabic) script. The model turns a Hindko headline, sentence, verse or passage into a 1,024-dimensional vector, so that texts about the same thing end up close together.
pip install hindko-embeddings
Quick start
from hindko_embeddings import HindkoEmbedder

embedder = HindkoEmbedder.from_pretrained()   # first run downloads the model (1.1 GB), then it is cached

passages = [
    "ایہہ بہت کہٹ لوک جانڑدین کہ ڈرامے دی پیدائش کسراں تے کتھے ہوئی آئی۔",
    "اج اساں اگر آپڑیں بزرگاں دی انہاں گلاں تے غور نہ کیتا تے پچھتاوے دے سوا کج ہتھ نہ آسی۔",
    "اسی طراں خیبر پختونخوا اچ بولی جانڑیں ولی دیگر زباناں دے ادب و ثقافت دی بی نمائندگی کیتی گئی اَئی۔",
]

for hit in embedder.search("ڈرامے دی پیدائش", passages, top_k=3):
    print(round(hit["score"], 3), hit["text"])
The SDK applies the two conventions the model was trained with, so you don't have to:
- it puts text in canonical form with
normalize()fromhindko-tokenizer, which is installed with this package; - it adds the
query:orpassage:prefix the model expects.
What you can do
q = embedder.encode_queries(["ڈرامے دی پیدائش"])   # search queries, headlines, titles
p = embedder.encode_passages(passages)             # documents to be found
scores = embedder.similarity(q, p)                 # cosine similarity matrix

emb = embedder.encode(texts)                       # similarity, clustering, classification ("query" side)
vector = embedder.encode("ڈرامے دی پیدائش")         # one string gives one vector

hits = embedder.search(query, passages, top_k=5)                         # ranked [{index, score, text}]
hits = embedder.search(query, passages, passage_embeddings=p)            # reuse embeddings across queries

embedder.prepare(texts, kind="passage")   # see exactly what the model receives
embedder.model                            # the underlying SentenceTransformer
from_pretrained() takes device="cuda", a pinned revision= and a cache_folder=. On a CPU the float16 weights are cast to float32 automatically.
Results
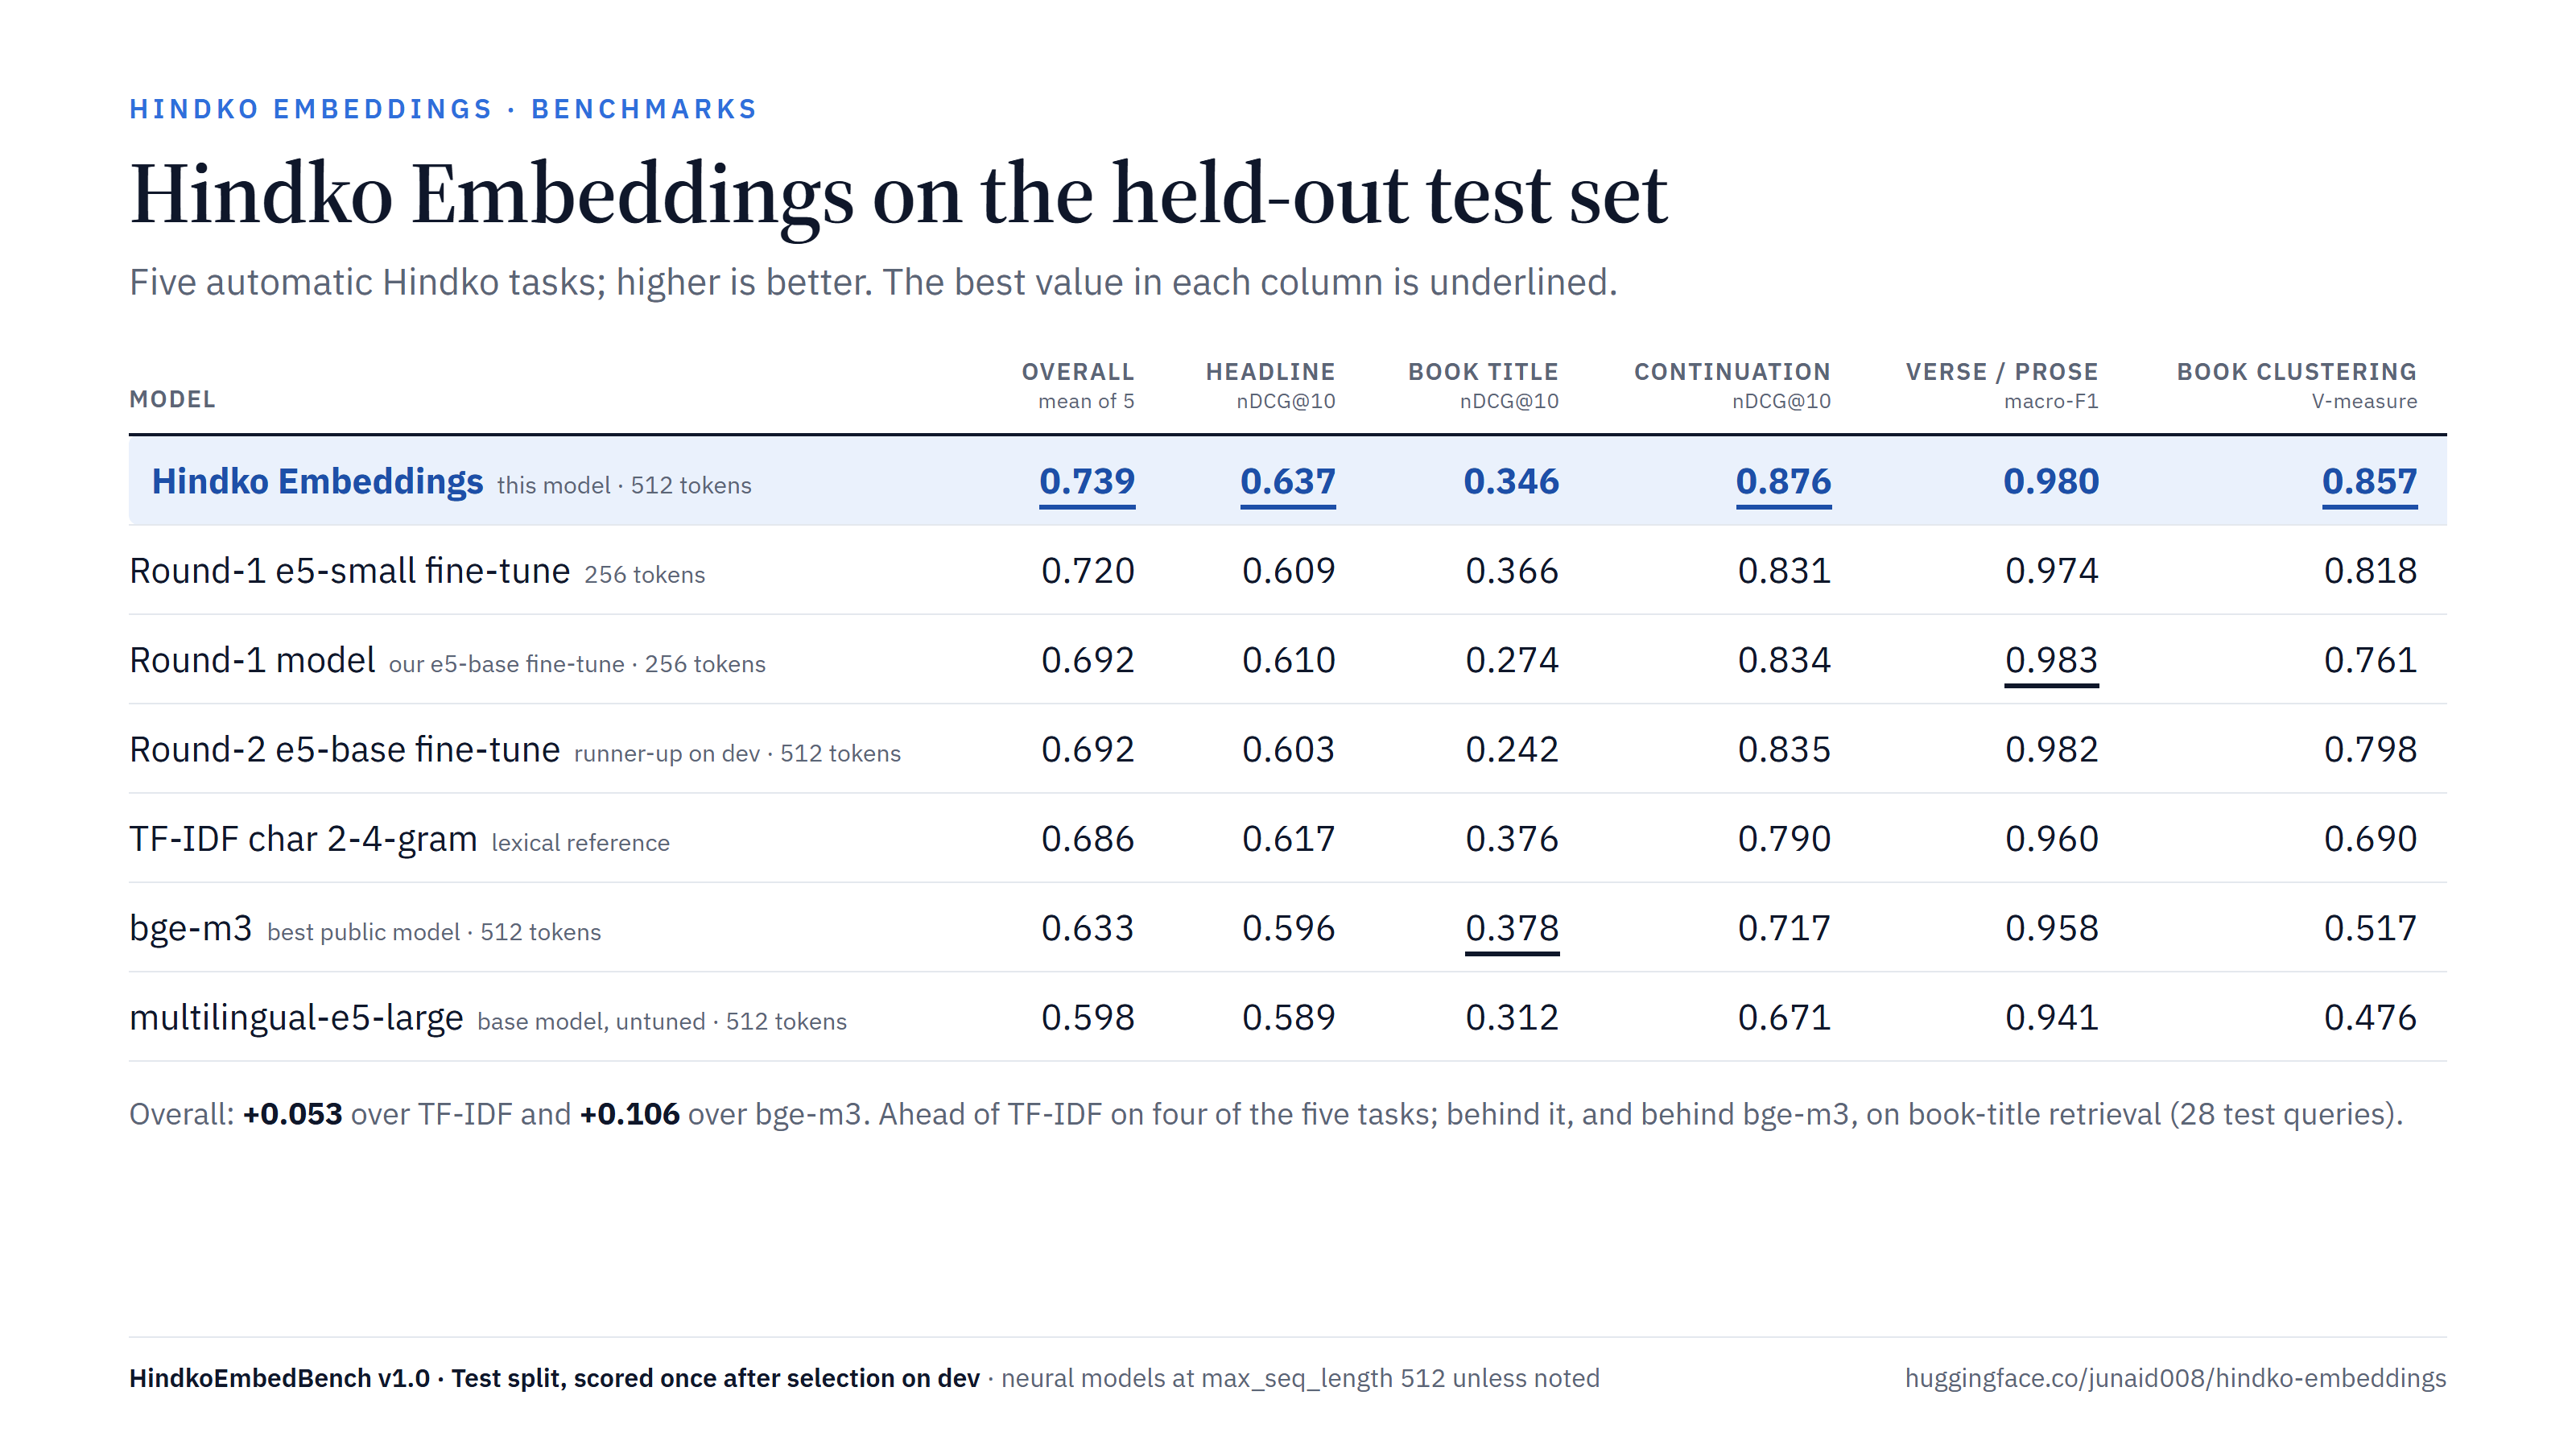
On the held-out test split of HindkoEmbedBench v1.0 (five tasks: headline retrieval, book-title retrieval, passage continuation, verse/prose classification and book clustering):
| Model | Test score |
|---|---|
| hindko-embeddings | 0.7391 |
| Character n-gram TF-IDF | 0.6864 |
| bge-m3 (best public embedding model tested) | 0.6332 |
| multilingual-e5-large (its base model, not fine-tuned) | 0.5977 |
It has the highest overall test score of the 12 models scored on test, and it is ahead of TF-IDF on four of the five tasks (behind it on book-title retrieval). Every number, chart and the full protocol are on the model card.
Requirements
Python 3.10 or later, sentence-transformers 6.0 or later and transformers 5.x. Older versions may not load the saved model configuration. Input longer than 512 tokens is truncated.
Links
- Model card, benchmark and evaluation: huggingface.co/junaid008/hindko-embeddings
- Hindko tokenizer:
hindko-tokenizer
License
CC BY-NC 4.0 (non-commercial): open for research, teaching and other non-commercial use. Commercial use needs written permission from the author. The base model, intfloat/multilingual-e5-large, is MIT-licensed; its notice is kept in LICENSE.
1 maintainer

Metadata
1 maintainer
Release files for hindko-embeddings 1.0.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| hindko_embeddings-1.0.0.tar.gz | 12.2 kB | Without provenance | Details for hindko_embeddings-1.0.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| hindko_embeddings-1.0.0-py3-none-any.whl | Python 3 | none | any | Details for hindko_embeddings-1.0.0-py3-none-any.whl |
Total release size: 25.0 kB
Release files / hindko_embeddings-1.0.0.tar.gz
| Download URL | hindko_embeddings-1.0.0.tar.gz |
|---|---|
| Size | 12.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
922142ea8927a8b18353217bdfa7bba2f03189a1ac6a6d3c5f833cadd110de51
|
|
BLAKE2b-256 checksum How to use checksums |
2633d6b978568f6591fadf0444efb8b6ea685800087617db7a067cfbc87a0592
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.11.9
|
Release files / hindko_embeddings-1.0.0-py3-none-any.whl
| Download URL | hindko_embeddings-1.0.0-py3-none-any.whl |
|---|---|
| Size | 12.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
c1a147164d1d701765ff91809a4fa6c8522719ecb902c12dab3b19d21ac96a0b
|
|
BLAKE2b-256 checksum How to use checksums |
ba02d97ce0d6d451d1cb5f9d702bec46143d833c64a8937cdb9b9a4383e53357
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.11.9
|
Security for hindko-embeddings 1.0.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.













