
Hugmunn
Huginn and Muninn are Odin’s two ravens in Norse mythology. Their names mean “thought” and “memory”: they travel through the world and return to tell Odin what they have seen. Hugmunn takes its name from the pair.





Hugmunn is a desktop application and Python library for working with language models. It connects to local models through llama.cpp and to Claude and ChatGPT through the Claude Code and Codex CLIs, using their subscription logins, as in spaCR. No API key is required.
You can chat, attach instruction packs, let a model read files or run tools, and return to saved conversations. The desktop application and Python API use the same model clients and tool policies. Local model weights and llama-server are separate downloads; they are not included in the Python package or desktop installers.
Use CLI default for your account’s current Claude or Codex model, or select a Claude alias or a model from Codex’s local catalogue. Local additions include Qwen3.8-27B and unlocked Qwen/Gemma variants. See the model catalogue for downloads, compatibility and sources.
Install
Install from PyPI with Python 3.10 or newer in a separate environment:
python -m venv .venv
source .venv/bin/activate          # Windows: .venv\Scripts\activate
python -m pip install hugmunn
hugmunn
Or install directly from GitHub:
python -m pip install "hugmunn @ git+https://github.com/EinarOlafsson/hugmunn.git"
hugmunn
python -m hugmunn also launches the application. hugmunn --version prints the
installed version without opening a window. For development, install a checkout
with python -m pip install -e ..
Download desktop packages from
GitHub Releases: a
Linux .deb, Windows setup .exe, or macOS .dmg. These bundle Python and Qt.
See the installer guide
for installation, portable bundles, and platform requirements.
System requirements
A CUDA GPU is optional. Cloud models run on the provider's hardware. Local models can use CPU, NVIDIA CUDA, Apple Metal, or Vulkan on compatible AMD, Intel and NVIDIA devices. An existing ROCm or SYCL llama-server can also be selected.
These are practical starting points, not measured guarantees for every model:
| Use | Minimum starting point | Recommended |
|---|---|---|
| Desktop + Claude/Codex | 64-bit, 2 CPU cores, 4 GB RAM, 1 GB free disk, internet, current vendor CLI and eligible subscription | 4 cores, 8 GB RAM, 2 GB free disk |
| Small local chat (Qwen3.5-0.8B Q4) | 4 GB RAM, 2 GB extra disk for runtime/weights; CPU works | 4+ cores, 8 GB RAM; disable unneeded skills for the 4K context |
| Local 12B Q5 model | About 9.4 GB weights plus runtime/context; plan for at least 16 GB RAM | 32 GB RAM; 12–16 GB GPU memory or ample unified memory |
| Local 27B Q5 model | About 20 GB weights; plan for 32 GB RAM and 25 GB extra disk | 64 GB RAM, SSD, 24 GB+ GPU memory or 32–64 GB unified memory |
| Large 80B–284B MoE models | Model-specific; often 55–128+ GB RAM and 50–100+ GB disk | Check the model card and leave room for context and other applications |
RAM and discrete GPU memory are different pools; their sum is not a guarantee that a model fits. Longer contexts consume more memory. CPU inference works but large models can be slow. Start with Qwen3.5-0.8B · small CPU starter to check local setup; use larger models for substantial coding work.
- Python: 3.10–3.13 tested; 3.12 recommended. Desktop installers bundle Python.
- Linux: Ubuntu 22.04/24.04 or a compatible recent desktop distribution; X11/Wayland and Qt system libraries. The release installer is x86-64.
- macOS: macOS 13+ for current Qt; Apple Silicon uses Metal and shared RAM. The release installer is ARM64; Intel Macs can install through pip.
- Windows: 64-bit Windows 10 1809+ or Windows 11; Windows 11 recommended. The release installer is x86-64.
OS compatibility also depends on the installed Qt version and your llama.cpp build. ARM Linux/Windows may use pip where matching Python/Qt wheels are available; native ARM installers are not currently built for them. See hardware and runtime setup for drivers and backend choices.
First launch
The welcome setup checks CPU, RAM, graphics and free model storage, previews themes, and offers optional AI and GitHub sign-in. The last page contains the noncommercial license and user agreement. It starts unchecked and must be accepted to launch the desktop application. Reopen it from hugmunn → Welcome and setup….
Automatic minimal error reports to EinarOlafsson/hugmunn issues are on by default, after agreement acceptance and connecting a GitHub account. These are public issues under that account. Reports exclude prompts, conversations, logs, error messages, file contents, paths and credentials. Turn reporting off in setup or Accounts → Automatically report errors to GitHub. See setup and reporting for exactly what is collected.
First conversation
- Launch
hugmunnand choose a provider in the Model tab. - For a local model, choose a registry entry and download its weights. If you already have them, use hugmunn → Find my models…. Use hugmunn → Set up llama-server… to select an existing runtime or install one.
- For a cloud model, sign in through Accounts, then select a model from
the CLI’s list. Install links and browser sign-in are provided. You can also
run
claude auth login --claudeaiorcodex loginin a terminal. Your plan’s model access and usage limits apply. - Enter a message and send it with Ctrl+Enter.
Local models need enough RAM, GPU memory, and disk space for their weights and context. The model picker shows estimated requirements. Start with a model that fits your machine; cloud models do not need a local GPU.
The Run tab selects a working directory, enables tools, and controls approval behavior. With the default Ask before changing anything setting, read tools run directly and writes or shell commands ask for approval. Higher autonomy levels permit more actions without asking. This policy is not an operating-system sandbox.
Cloud requests send prompts and tool results to the selected provider. Local inference stays on the local server, but web tools and downloads still use the network when requested.
Desktop controls
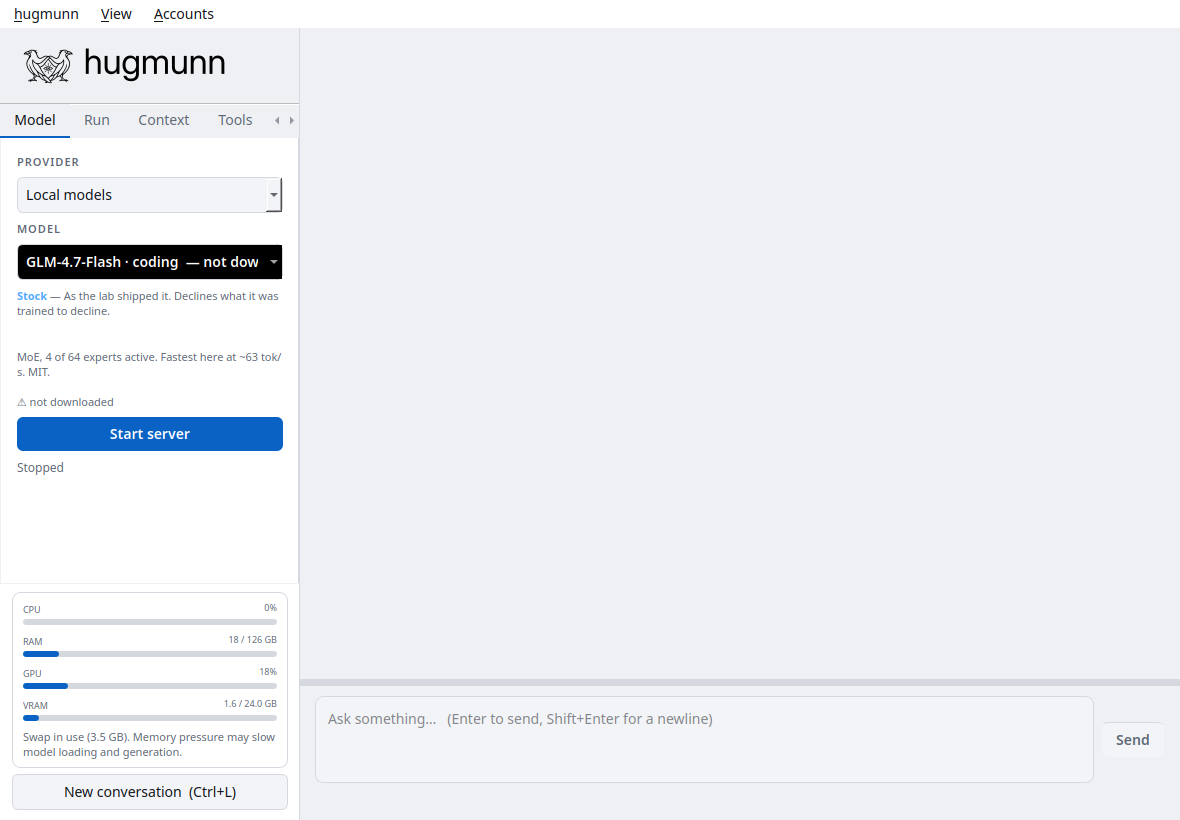
| Control | What it changes |
|---|---|
| Model | Provider, model, downloads, and server status |
| Run | Working directory, tools, effort, persistence, and autonomy |
| Context | Reasoning options, context size, and overflow handling |
| Tools | Instruction packs, custom tools, and prompt presets |
| Sessions | Saved conversations and their desktop settings |
| System | System prompt |
| View menu | Light, dark, system, and other colour themes |
Effort controls instructions and supported provider reasoning settings. Persistence sets the tool-round budget. Autonomy decides which tool calls need approval. These are separate settings.
Conversations are saved as you work. Ctrl+L starts a new one. Type /help
for commands, or /remote to open the same conversation in a browser through a
local, token-protected page. See the
desktop guide
for details.
Python API
Discover the models known to the installation:
import hugmunn

for model in hugmunn.models("local"):
    print(model.key, model.label, model.size_gb, model.downloaded)
After downloading a model and setting up llama-server, use its registry key:
import hugmunn

with hugmunn.agent("code-glm") as chat:
    print(chat.ask("Explain Python context managers with an example."))
    chat.save("conversation.json")
Stream a response with access to a limited set of read tools:
import hugmunn

with hugmunn.agent(
    "code-glm",
    workdir="/path/to/project",
    tools=["list_directory", "read_file", "search_text"],
) as chat:
    for event in chat.run("Read the README and describe this project."):
        if event.kind == "content":
            print(event.text, end="", flush=True)
        elif event.kind == "error":
            raise hugmunn.HugmunnError(event.text)
Tools are disabled by default in the Python API. When enabled, calls requiring
approval raise ApprovalRequired unless you supply an approve callback.
An agent closes the local server it started when its context exits; an already
running server is left running. Library conversations are saved explicitly with
save().
The API guide
covers cloud models, approval callbacks, streaming, cancellation, and sessions.
The reference
is generated from the public docstrings. Runnable examples are in
examples/.
Configuration and documentation
Settings and sessions normally live in ~/.config/hugmunn/; model weights
default to ~/.claude/models/. Override these with HUGMUNN_CONFIG_DIR and
HUGMUNN_MODELS_ROOT. Set LLAMA_SERVER to use an existing runtime.
| Guide | Contents |
|---|---|
| Installation | pip, environments, model setup, troubleshooting |
| Desktop | Controls, tools, sessions, remote access |
| Python API | Examples and behavior |
| Configuration | Paths, credentials, skills, custom tools |
| Installers | Native builds and release preparation |
| Contributing | Development, tests, documentation builds |
Hugmunn’s themes and packaging take inspiration from spacr, my microscopy analysis project. The applications are installed separately.
Development
python -m pip install -e ".[dev,docs,build]"
QT_QPA_PLATFORM=offscreen python -m pytest
python -m sphinx -W --keep-going -b html docs docs/_build/html
python -m build
python -m twine check dist/*.whl dist/*.tar.gz
Tests use fake model clients and offscreen Qt windows; they do not require model downloads or paid API calls. See CHANGELOG.md for changes.
License
Hugmunn’s source and raven artwork are distributed under the PolyForm Noncommercial License 1.0.0. It permits noncommercial use, modification, and redistribution under its terms. Commercial use requires separate permission from Einar Olafsson; contact einar.olafsson@gmail.com.
These terms apply to new releases beginning with 0.0.0.9. Previously published versions retain the license supplied with those versions. Model weights, llama.cpp, Qt, and other dependencies retain their own licenses; see the third-party notices.
1 maintainer

Metadata
1 maintainer
Release files for hugmunn 0.0.0.12
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| hugmunn-0.0.0.12.tar.gz | 1.5 MB | With provenance | Details for hugmunn-0.0.0.12.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| hugmunn-0.0.0.12-py3-none-any.whl | Python 3 | none | any | Details for hugmunn-0.0.0.12-py3-none-any.whl |
Total release size: 2.6 MB
Release files / hugmunn-0.0.0.12.tar.gz
| Download URL | hugmunn-0.0.0.12.tar.gz |
|---|---|
| Size | 1.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e513a48692d97d327beaaf9bf4d248d4cf733d124db0ed193f4775dc1befa127
|
|
BLAKE2b-256 checksum How to use checksums |
082a62036fc74f302fee4d4af0bf1e597ae9167b70e2594d0a0630689b6d3294
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 23, 2026.
Transparency logRelease files / hugmunn-0.0.0.12-py3-none-any.whl
| Download URL | hugmunn-0.0.0.12-py3-none-any.whl |
|---|---|
| Size | 1.1 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
399c4d0607c399988a2594c562ef7d6b71e3df2e02bfb094e26708bbaa37fe13
|
|
BLAKE2b-256 checksum How to use checksums |
54b415767e0b5a70992a364bd680e7dd955452691fd96d79aa588698cf23b266
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 23, 2026.
Transparency logSecurity for hugmunn 0.0.0.12
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for hugmunn-0.0.0.12.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 23, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














