


We Are Hiring!
Dear folks, we are offering challenging opportunities located in Beijing for both professionals and students who are keen on AutoML/NAS. Come be a part of DataCanvas! Please send your CV to yangjian@zetyun.com. (Application deadline: TBD.)
What is HyperGBM
HyperGBM is a full pipeline automated machine learning (AutoML) toolkit designed for tabular data. It covers the complete end-to-end ML processing stages, consisting of data cleaning, preprocessing, feature generation and selection, model selection and hyperparameter optimization.
Overview
HyperGBM optimizes the end-to-end ML processing stages within one search space, which differs from most existing AutoML approaches that only tackle partial stages, for instance, hyperparameter optimazation. This full pipeline optimization process is very similar to a sequential decision process (SDP). Therefore, HyperGBM utilizes reinforcement learning, Monte Carlo Tree Search, evolution algorithm combined with a meta-learner to efficiently solve the pipeline optimization problem.
HyperGBM, as indicated in the name, involves several gradient boosting tree models (GBM), namely, XGBoost, LightGBM and Catboost. What's more, it could access the Hypernets, a general automated machine learning framework, and introduce its advanced characteristics in data cleaning, feature engineering and model ensemble. Additionally, the search space representation and search algorithm inside Hyper GBM are also supported by Hypernets.
Installation
Conda
Install HyperGBM with conda from the channel conda-forge:
conda install -c conda-forge hypergbm
Pip
Install HyperGBM with different pip options:
- Typical installation:
pip install hypergbm
- To run HyperGBM in JupyterLab/Jupyter notebook, install with command:
pip install hypergbm[notebook]
- To support experiment visualization base on web, install with command:
pip install hypergbm[board] # Temporarily unavailable in version 0.3.x
- To run HyperGBM in distributed Dask cluster, install with command:
pip install hypergbm[dask]
- To support dataset with simplified Chinese in feature generation,
- Install
jiebapackage before running HyperGBM. - OR install with command:
- Install
pip install hypergbm[zhcn]
- Install all above with one command:
pip install hypergbm[all]
Examples
- Use HyperGBM with Python
Users can quickly create and run an experiment with make_experiment, which only needs one required input parameter train_data. The example shown below is using the blood dataset as train_data from hypernet.tabular. If the target column of the dataset is not y, it needs to be manually set through the argument target.
An example codes:
from hypergbm import make_experiment
from hypernets.tabular.datasets import dsutils

train_data = dsutils.load_blood()
experiment = make_experiment(train_data, target='Class')
estimator = experiment.run()
print(estimator)
This training experiment returns a pipeline with two default steps, data_clean and estimator. In particular, the estimator returns a final model which consists of various models. The outputs:
Pipeline(steps=[('data_clean',
                 DataCleanStep(...),
                ('estimator',
                 GreedyEnsemble(...)])
To see more examples, please read Quick Start and Examples.
- Use HyperGBM with Command line tools
Hypergbm also supports command line tools to perform model training, evaluation and prediction. The following codes enable the user to view command line help:
hypergbm -h

usage: hypergbm [-h] [--log-level LOG_LEVEL] [-error] [-warn] [-info] [-debug]
                [--verbose VERBOSE] [-v] [--enable-gpu ENABLE_GPU] [-gpu]
                [--enable-dask ENABLE_DASK] [-dask] [--overload OVERLOAD]
                {train,evaluate,predict} ...
The example of training a model for dataset blood.csv is shown below:
hypergbm train --train-file=blood.csv --target=Class --model-file=model.pkl
For more details, please read Quick Start.
GPU Acceleration
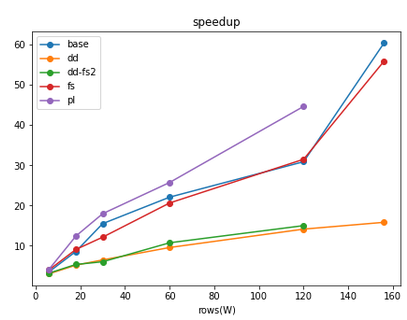
Hypergbm supports full pipeline GPU acceleration, including all steps from data processing to model training. In our experiments, we got a 50x performance improvement! Most importantly, the model trained on GPU could be deployed to the environment without GPU hardware and software (e.g.,CUDA and cuML), which greatly reduces the cost of model deployment.
Documents
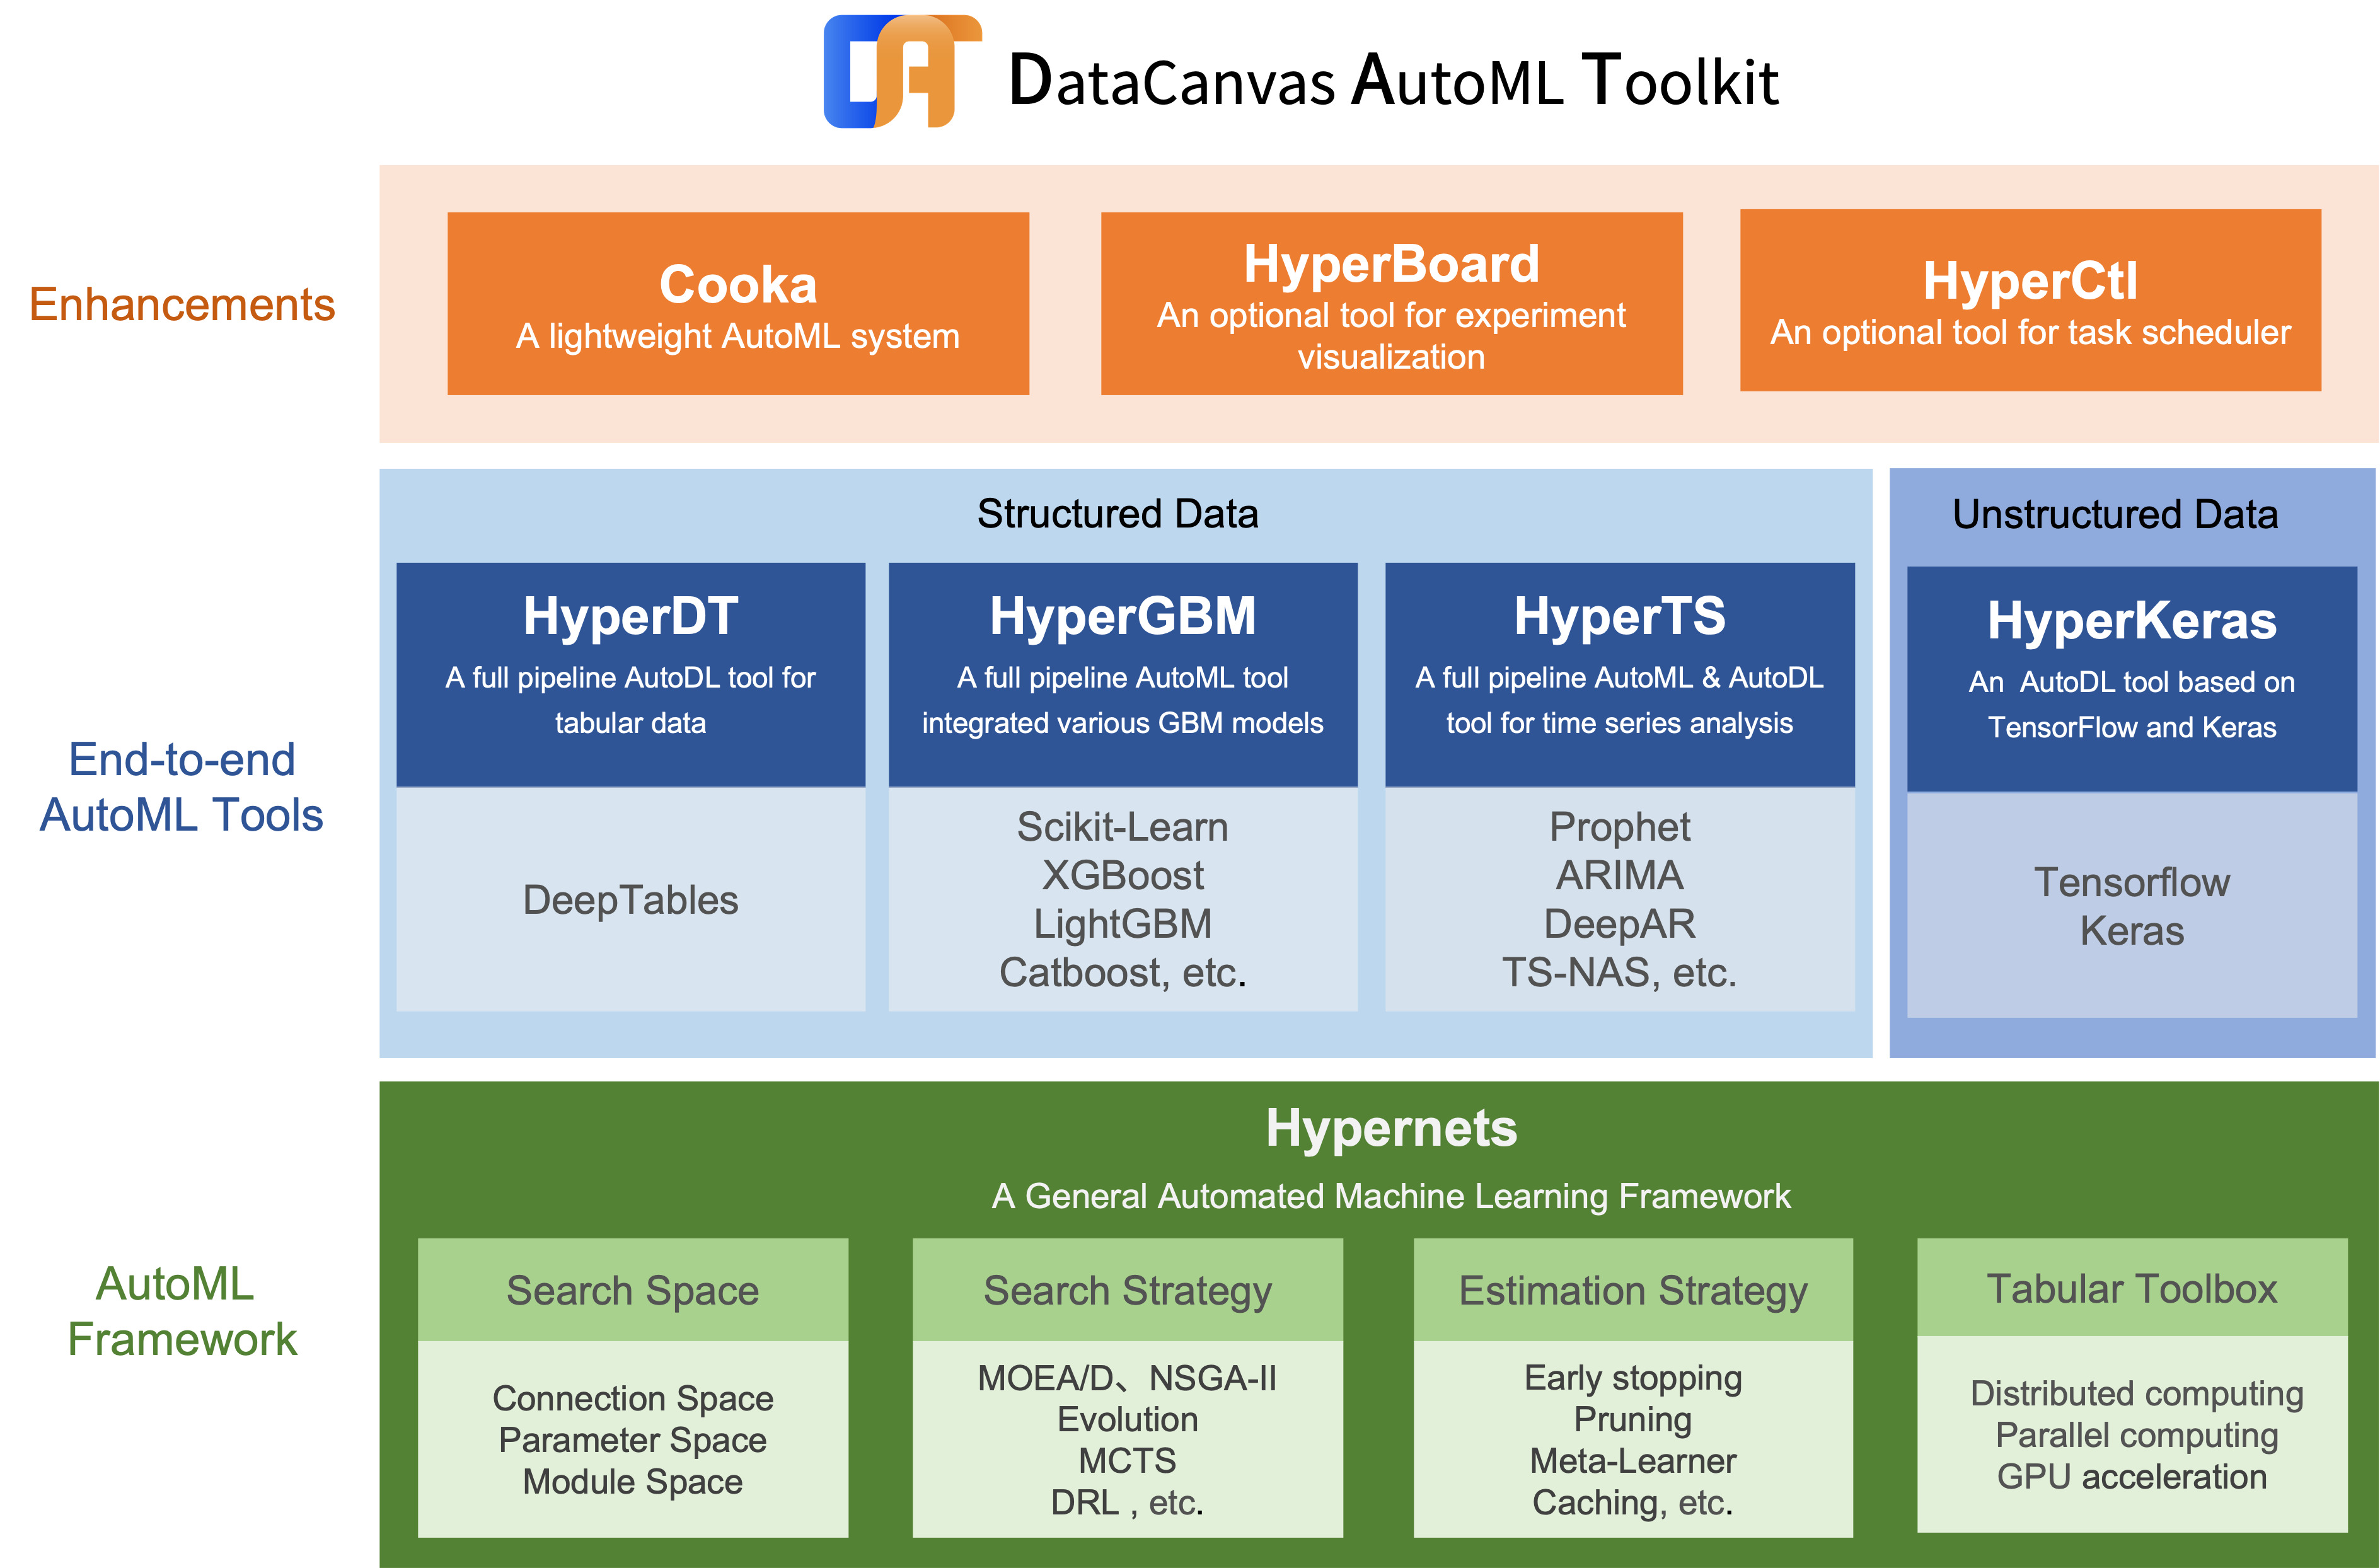
HyperGBM related projects
- Hypernets: A general automated machine learning (AutoML) framework.
- HyperGBM: A full pipeline AutoML tool integrated various GBM models.
- HyperDT/DeepTables: An AutoDL tool for tabular data.
- HyperTS: A full pipeline AutoML&AutoDL tool for time series datasets.
- HyperKeras: An AutoDL tool for Neural Architecture Search and Hyperparameter Optimization on Tensorflow and Keras.
- HyperBoard: A visualization tool for Hypernets.
- Cooka: Lightweight interactive AutoML system.
Citation
If you use HyperGBM in your research, please cite us as follows:
Jian Yang, Xuefeng Li, Haifeng Wu. HyperGBM: A full pipeline AutoML tool integrated with various GBM models. https://github.com/DataCanvasIO/HyperGBM. 2020. Version 0.2.x.
BibTex:
@misc{hypergbm,
  author={Jian Yang, Xuefeng Li, Haifeng Wu},
  title={{HyperGBM}: { A Full Pipeline AutoML Tool Integrated With Various GBM Models}},
  howpublished={https://github.com/DataCanvasIO/HyperGBM},
  note={Version 0.2.x},
  year={2020}
}
DataCanvas
HyperGBM is an open source project created by DataCanvas.
1 maintainer

Metadata
1 maintainer
Release files for hypergbm 0.3.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| hypergbm-0.3.2.tar.gz | 3.3 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| hypergbm-0.3.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 6.7 MB
Release files / hypergbm-0.3.2.tar.gz
| Download URL | hypergbm-0.3.2.tar.gz |
|---|---|
| Size | 3.3 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e27107836faccc29e4464b2977c10241049f6a5652facd2f0c3c1d66197ac009
|
|
BLAKE2b-256 checksum How to use checksums |
304dc657950d6f534beba6d22a7cb264830754e2c0f7372f00cc44bfb68ad37e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.9.17
|
Release files / hypergbm-0.3.2-py3-none-any.whl
| Download URL | hypergbm-0.3.2-py3-none-any.whl |
|---|---|
| Size | 3.4 MB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
471a9a4bf5a55e1d33812fac661c0c57351e4c1c63a0715d0770fdf60e41ce69
|
|
BLAKE2b-256 checksum How to use checksums |
180d0141cdc3dbc154d027ac142993fef019bd5a1c37f0e35d6ed0ae40a4e552
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/4.0.2 CPython/3.9.17
|














