Infinity-Parser2
🤗 Infinity-Parser2-Pro | 🤗 Infinity-Parser2-Flash | 📊 Dataset | 📄 Paper | 🚀 Demo
News
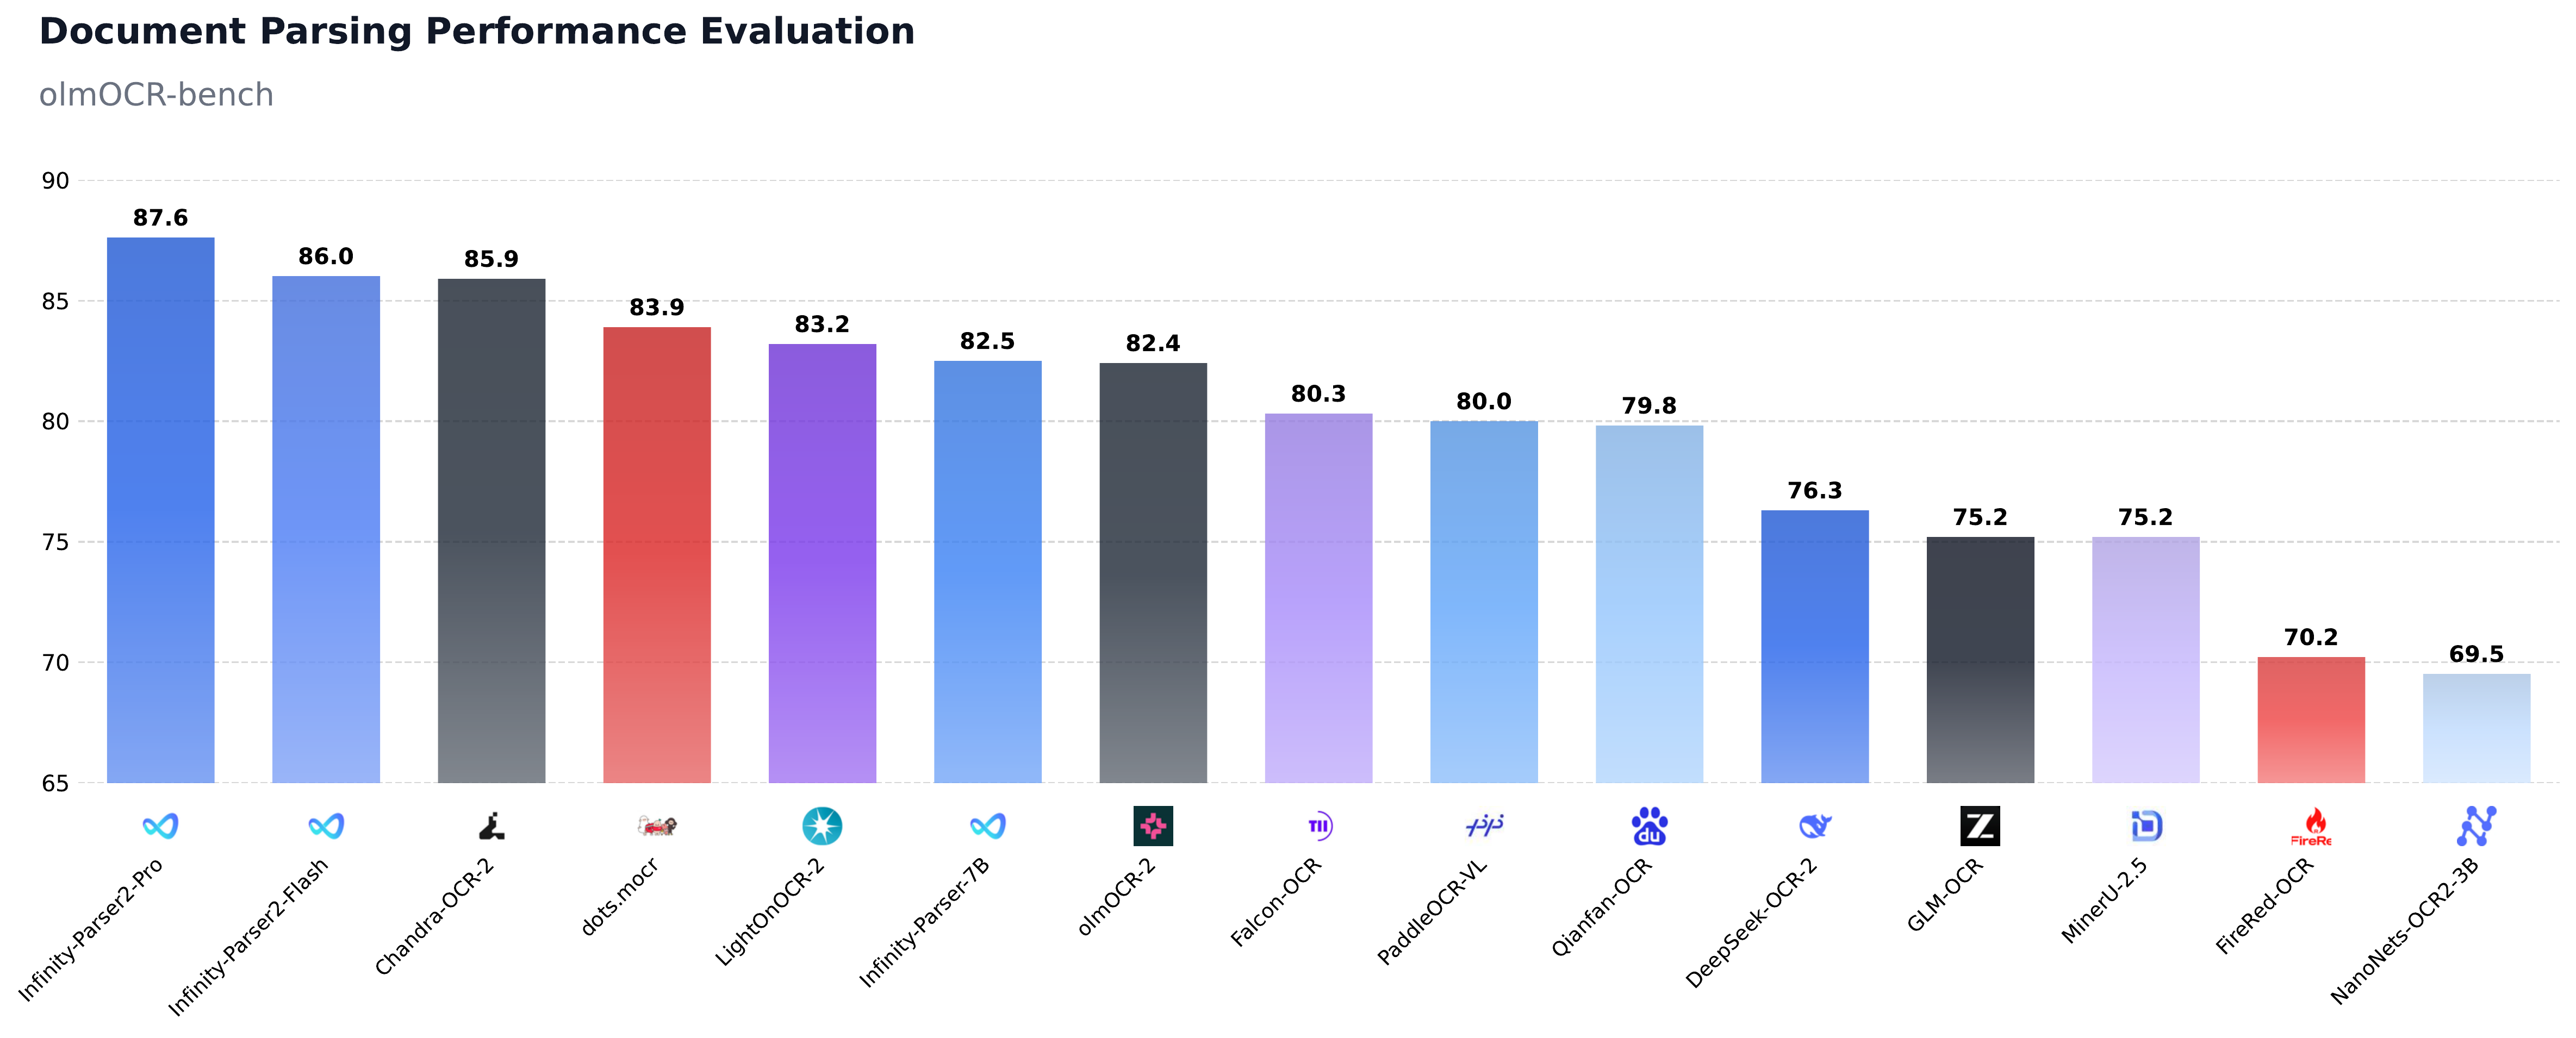
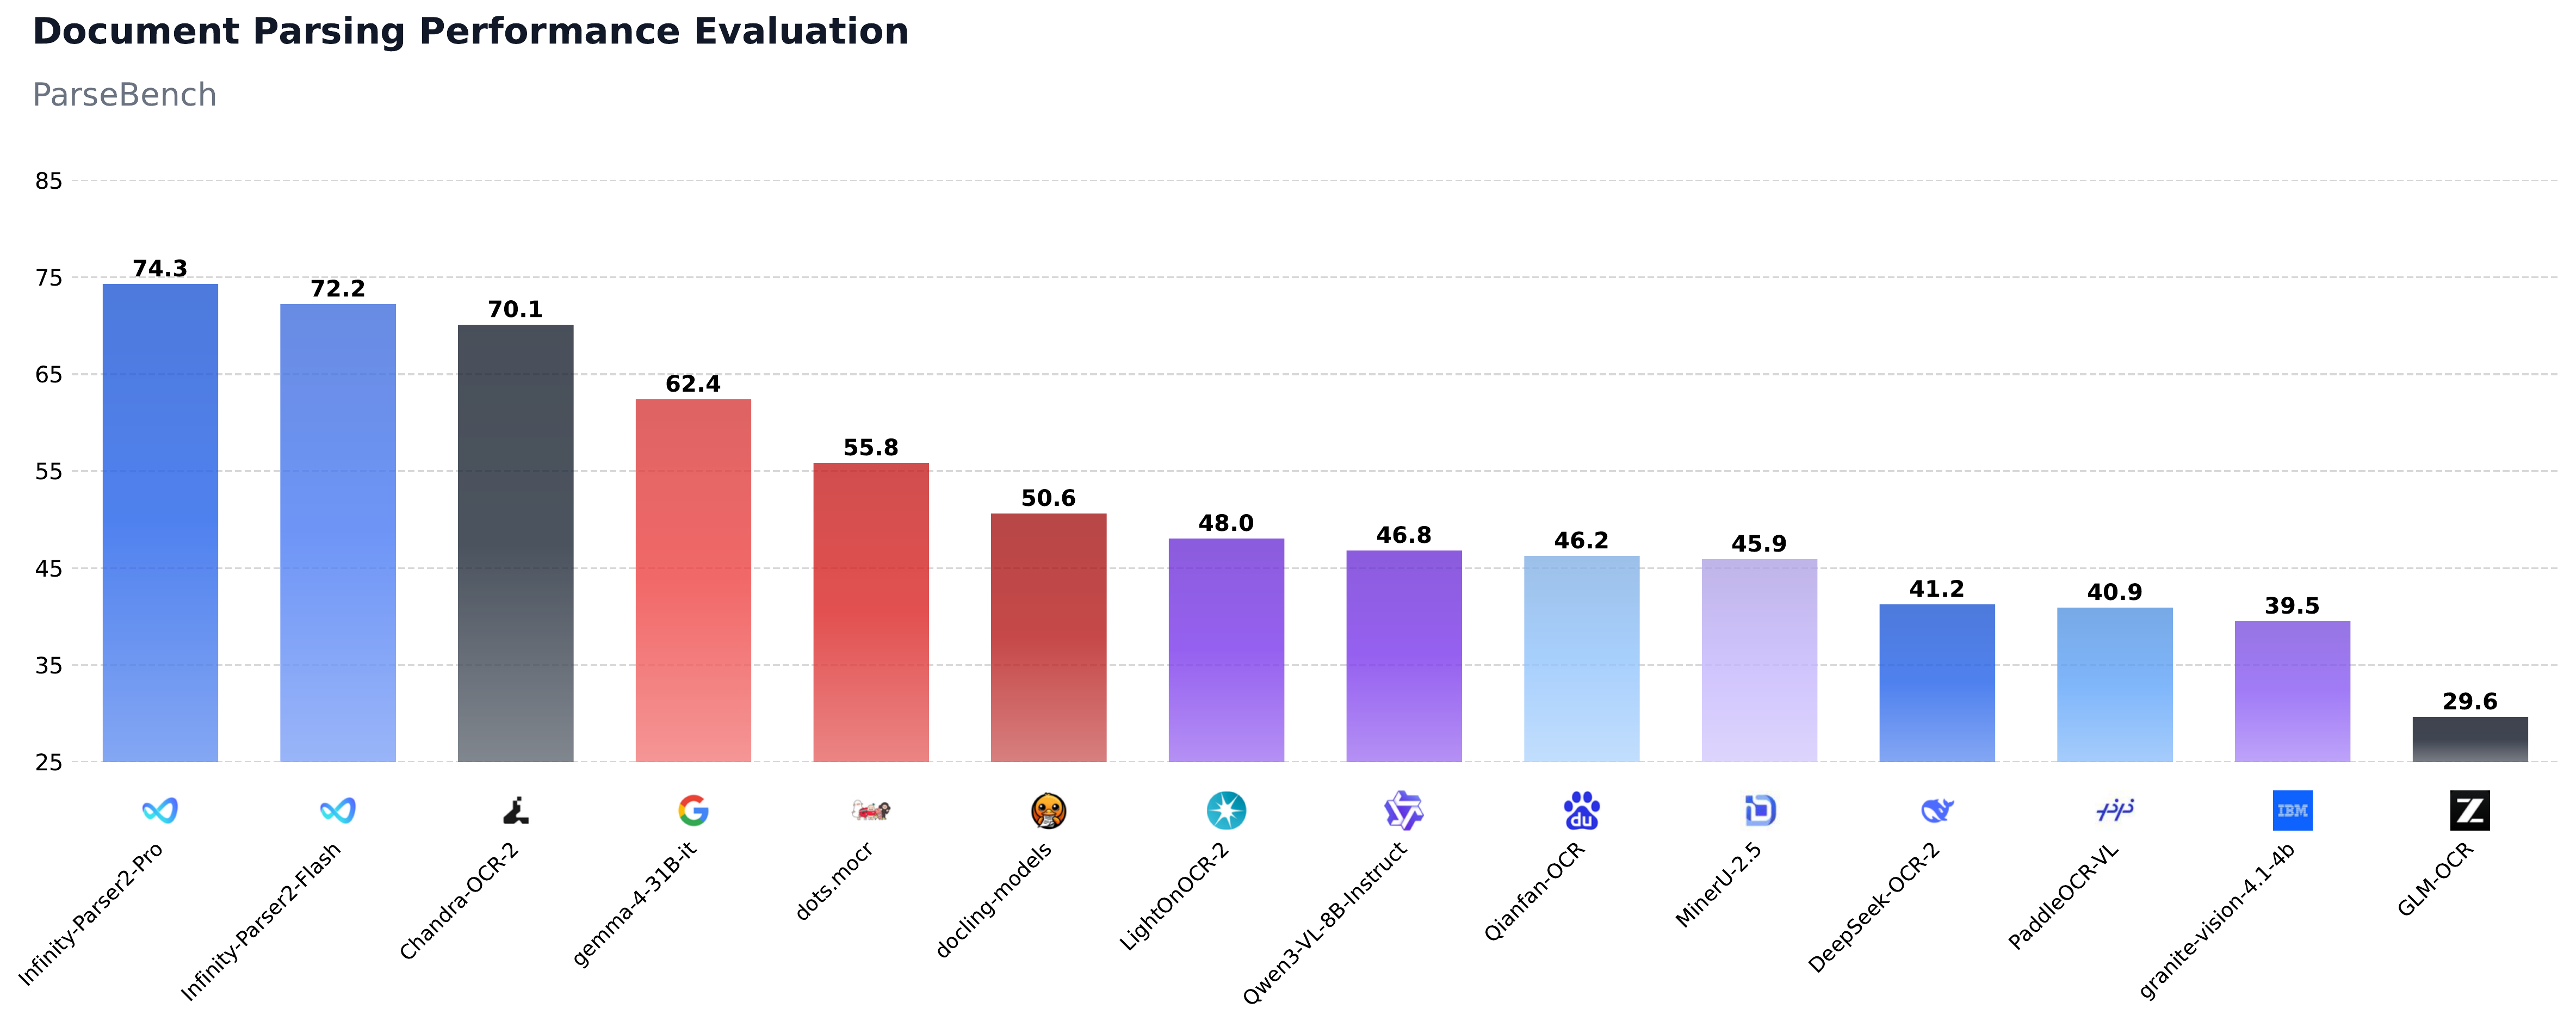
- [2026-05-11] Released flagship document parsing models: Infinity-Parser2-Pro, Infinity-Parser2-Flash, and the dataset Infinity-Doc2-5M. Infinity-Parser2 achieves SOTA results on olmOCR-bench and ParseBench.
Introduction
We are excited to release Infinity-Parser2, our latest flagship document understanding model. We offer two distinct variants to address diverse deployment constraints: Infinity-Parser2-Pro, optimized for maximum accuracy in precision-critical tasks, achieves state-of-the-art results on olmOCR-Bench (87.6%) and ParseBench (74.3%), surpassing frontier models including DeepSeek-OCR-2, PaddleOCR-VL-1.5, and MinerU2.5. Infinity-Parser2-Flash, engineered for low-latency inference, delivers a 3.68x speedup over our previous Infinity-Parser-7B model. With significant upgrades to both our data engine and multi-task reinforcement learning approach, the model consolidates robust multi-modal parsing capabilities into a unified architecture, unlocking brand-new zero-shot capabilities across a wide range of real-world business scenarios.
Key Features
- Upgraded Data Engine: We have comprehensively enhanced our synthetic data engine to support both fixed-layout and flexible-layout document formats. By curating nearly 5 million diverse document parsing samples across a wide range of layouts, combined with a dynamic adaptive sampling strategy, we ensure highly balanced and robust multi-task learning across various document types.
- Multi-Task Reinforcement Learning: We designed a novel verifiable reward system to support Joint Reinforcement Learning (RL), enabling seamless and simultaneous co-optimization of multiple complex tasks, including document parsing, element parsing, chart parsing, chemical formula parsing, document vqa, and general multimodal understanding.
- Breakthrough Parsing Performance: Infinity-Parser2-Pro substantially outperforms our previous 7B model, achieving 87.6% on olmOCR-Bench and 74.3% on ParseBench, surpassing frontier models such as DeepSeek-OCR-2, PaddleOCR-VL, and MinerU2.5.
- Inference Acceleration: Infinity-Parser2-Flash delivers significantly higher efficiency than Infinity-Parser-7B, with inference throughput increased by 3.68x (from 441 to 1,624 tokens/sec), reducing both deployment latency and costs.
Performance
| Task | Infinity-Parser2-Pro | Infinity-Parser2-Flash | PaddleOCR-VL-1.5 | DeepSeek-OCR-2 | MinerU2.5 | Gemini-3-Pro |
|---|---|---|---|---|---|---|
| Document Parsing | ||||||
| olmOCR-bench | 87.6 | 86.0 | 78.5 | 76.3 | 75.2 | - |
| ParseBench | 74.3 | 72.2 | 66.0 | 41.2 | 45.9 | 69.1‡ |
| OmniDocBench-v1.6 | 93.95 | 91.98 | 94.87 | 90.17 | 92.98 | 92.85 |
| Layout Analysis (mIoU) | ||||||
| DocLayNet | 64.93* | 64.97* | 71.05* | 45.62* | 67.74* | - |
| D4LA | 52.41* | 46.05* | 50.21* | 33.03* | 51.62* | - |
| OmniDocBench-v1.5-Layout | 74.56* | 73.07* | 74.80* | 55.28* | 76.28* | - |
| Element Parsing | ||||||
| OmniDocBench-v1.5-TextBlock | 95.05 | 94.31 | 94.97* | 84.13* | 86.00 | - |
| PubTabNet (val) | 94.76 | 92.41 | 84.60 | 89.53* | 89.07 | 91.40 |
| UniMERNet | 97.7 | 96.5 | 95.8* | 79.8* | 96.5 | 96.4 |
| Chart Parsing | ||||||
| Chart2Table | 86.5 | 80.49 | 86.2* | 49.7* | - | - |
| Chart2Json | 73.69 | 67.66 | - | - | - | - |
| Chemical Formula Parsing | ||||||
| CoSyn_Chemical | 73.19 | 63.34 | - | 47.02* | - | - |
| Document VQA | ||||||
| DocVQA (val) | 96.43 | 93.16 | - | 43.42* | - | 93.68* |
| InfoVQA (val) | 86.26 | 75.94 | - | 22.07* | - | 85.24* |
| General Multimodal Understanding | ||||||
| AI2D | 88.89 | 79.53 | - | 37.66* | - | 91.87* |
| MathVista (testmini) | 71.4 | 59.5 | - | - | - | 81.8* |
| MMBench-EN (dev) | 87.54 | 77.92 | - | - | - | 90.29* |
| MMBench-CN (dev) | 86.43 | 75.77 | - | - | - | 90.98* |
| MMMU (val) | 61.89 | 45.89 | - | - | - | 56.00* |
| MMStar | 69.66 | 57.13 | - | - | - | 83.78* |
| OCRBench | 86.20 | 81.60 | - | 47.20* | - | 89.30* |
Note: '*' denotes results evaluated using our internal evaluation tools. '‡' denotes results from the Gemini-3.1-Pro.
Quick Start
1. Minimal "Hello World" (Native Transformers)
If you are looking for a minimal script to parse a single image to Markdown using the native transformers library, here is a simple snippet:
from PIL import Image
import torch
from transformers import AutoModelForImageTextToText, AutoProcessor
from qwen_vl_utils import process_vision_info

# Load the model and processor
model = AutoModelForImageTextToText.from_pretrained(
    "infly/Infinity-Parser2-Pro",
    torch_dtype="float16",
    device_map="auto",
)
processor = AutoProcessor.from_pretrained("infly/Infinity-Parser2-Pro")

# Build the messages for the model
pil_image = Image.open("demo_data/demo.png").convert("RGB")
min_pixels = 2048  # 32 * 64
max_pixels = 16777216  # 4096 * 4096
prompt = """
- Extract layout information from the provided PDF image.
- For each layout element, output its bbox, category, and the text content within the bbox.
- Bbox format: [x1, y1, x2, y2].
- Allowed layout categories: ['header', 'title', 'text', 'figure', 'table', 'formula', 'figure_caption', 'table_caption', 'formula_caption', 'figure_footnote', 'table_footnote', 'page_footnote', 'footer'].
- Text extraction and formatting:
  1) For 'figure', the text field must be an empty string.
  2) For 'formula', format text as LaTeX.
  3) For 'table', format text as HTML.
  4) For all other categories (e.g., text, title), format text as Markdown.
- The output text must be exactly the original text from the image, with no translation or rewriting.
- Sort all layout elements in human reading order.
- Final output must be a single JSON object.
"""

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image",
                "image": pil_image,
                "min_pixels": min_pixels,
                "max_pixels": max_pixels,
            },
            {"type": "text", "text": prompt},
        ],
    }
]

chat_template_kwargs = {"enable_thinking": False}

text = processor.apply_chat_template(
    messages, tokenize=False, add_generation_prompt=True, **chat_template_kwargs
)
image_inputs, _ = process_vision_info(messages, image_patch_size=16)

inputs = processor(
    text=text,
    images=image_inputs,
    do_resize=False,
    padding=True,
    return_tensors="pt",
)

# Move all tensors to the same device as the model
inputs = {
    k: v.to(model.device) if isinstance(v, torch.Tensor) else v
    for k, v in inputs.items()
}

# Generate the response
generated_ids = model.generate(
    **inputs,
    max_new_tokens=32768,
    temperature=0.0,
    top_p=1.0,
)

# Strip input tokens, keeping only the newly generated response
generated_ids_trimmed = [
    out_ids[len(in_ids) :]
    for in_ids, out_ids in zip(inputs["input_ids"], generated_ids)
]
output_text = processor.batch_decode(
    generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text)
2. Advanced Pipeline (infinity_parser2)
For bulk processing, advanced features, or an end-to-end PDF parsing pipeline, we recommend using our infinity_parser2 wrapper.
Pre-requisites
# Create a Conda environment (Optional)
conda create -n infinity_parser2 python=3.12
conda activate infinity_parser2

# Install in this order: PyTorch -> vLLM -> FlashAttention.
# vLLM pins torch exactly and will replace a mismatched one; FlashAttention is compiled against
# the installed torch, so it must come last.

# 1. Install PyTorch (CUDA). These are the versions pinned by vLLM 0.26.0, whose wheels are CUDA 12.9 builds.
# Find the proper build for your CUDA version at https://pytorch.org/get-started/previous-versions
pip install torch==2.11.0 torchvision==0.26.0 torchaudio==2.11.0 torchcodec==0.16.0+cu129 --index-url https://download.pytorch.org/whl/cu129

# 2. Install vLLM. NOTE: you may need the command below first to resolve triton and numpy conflicts.
# pip uninstall -y pytorch-triton opencv-python opencv-python-headless numpy && rm -rf "$(python -c 'import site; print(site.getsitepackages()[0])')/cv2"
pip install "vllm==0.26.0+cu129" --extra-index-url https://wheels.vllm.ai/0.26.0/cu129/

# 3. Check that torch was not replaced. Expected: 2.11.0+cu129 0.26.0+cu129
python -c "import torch, torchvision; print(torch.__version__, torchvision.__version__)"

# 4. Install FlashAttention (FlashAttention-2 by default; compiles from source, ~10-30 min)
pip install flash-attn==2.8.3 --no-build-isolation
# Faster: download a wheel matching your torch (e.g. ...cu12torch2.11cxx11abiTRUE...) from
# https://github.com/Dao-AILab/flash-attention/releases, then run: pip install /path/to/<wheel_filename>.whl
# For Hopper GPUs (e.g. H100, H800), we recommend FlashAttention-3 instead. See: https://github.com/Dao-AILab/flash-attention
# NOTE: The code will prioritize detecting FlashAttention-3. If not found, it falls back to FlashAttention-2.
Install infinity_parser2
Install from PyPI
pip install infinity_parser2
Install from source code
git clone https://github.com/infly-ai/INF-MLLM.git
cd INF-MLLM/Infinity-Parser2
pip install -e .
Usage
Command Line
The parser command is the fastest way to get started.
# NOTE: The Infinity-Parser2 model will be automatically downloaded on the first run.

# Parse a PDF (outputs Markdown by default)
parser demo_data/demo.pdf

# Parse an image
parser demo_data/demo.png

# Batch parse multiple files
parser demo_data/demo.pdf demo_data/demo.png -o ./output

# Parse an entire directory
parser demo_data -o ./output

# Output raw JSON with layout bboxes
parser demo_data/demo.pdf --output-format json

# Convert to Markdown directly
parser demo_data/demo.png --task doc2md

# Visualize the layout of every page (./output/demo.pdf/layout/page_1.png, ...)
parser demo_data/demo.pdf -o ./output --visualize-layout
# View all options
parser --help
Python API
# NOTE: The Infinity-Parser2 model will be automatically downloaded on the first run.

from infinity_parser2 import InfinityParser2

parser = InfinityParser2()

# Parse a single file (returns Markdown)
result = parser.parse("demo_data/demo.pdf")
print(result)

# Parse multiple files (returns list)
results = parser.parse(["demo_data/demo.pdf", "demo_data/demo.png"])

# Parse a directory (returns dict)
results = parser.parse("demo_data")
Output formats:
| task_type | Description | Default Output |
|---|---|---|
doc2json |
Extract layout elements with bboxes (default) | Markdown |
doc2md |
Directly convert to Markdown | Markdown |
custom |
Use your own prompt | Raw model output |
# doc2json: get raw JSON with bbox coordinates
result = parser.parse("demo_data/demo.pdf", output_format="json")

# doc2md: direct Markdown conversion
result = parser.parse("demo_data/demo.pdf", task_type="doc2md")

# Custom prompt
result = parser.parse("demo_data/demo.pdf", task_type="custom",
                      custom_prompt="Please transform the document's contents into Markdown format.")

# Batch processing with custom batch size
result = parser.parse("demo_data", batch_size=8)

# Save results to directory
parser.parse("demo_data/demo.pdf", output_dir="./output")

# Save results plus a layout visualization of every page
parser.parse("demo_data/demo.pdf", output_dir="./output", visualize_layout=True)
Backends:
Infinity-Parser2 supports three inference backends. By default it uses the vLLM Engine (offline batch inference).
# vLLM Engine (default) — offline batch inference
parser = InfinityParser2(
    model_name="infly/Infinity-Parser2-Pro",
    backend="vllm-engine",        # default
    tensor_parallel_size=2,
)

# Transformers — local single-GPU inference
parser = InfinityParser2(
    model_name="infly/Infinity-Parser2-Pro",
    backend="transformers",
    device="cuda",
    torch_dtype="bfloat16",       # "float16" or "bfloat16"
)

# vLLM Server — online HTTP API (start server first)
parser = InfinityParser2(
    model_name="infly/Infinity-Parser2-Pro",
    backend="vllm-server",
    api_url="http://localhost:8000/v1/chat/completions",
    api_key="EMPTY",
)
To start a vLLM server:
vllm serve infly/Infinity-Parser2-Pro \
    --trust-remote-code \
    --default-chat-template-kwargs '{"enable_thinking": false}' \
    --chat-template-content-format openai \
    --host 0.0.0.0 \
    --port 8000 \
    --tensor-parallel-size 2 \
    --gpu-memory-utilization 0.85 \
    --max-model-len 65536 \
    --max-num-batched-tokens 32768 \
    --mm-encoder-tp-mode data \
    --mm-processor-cache-type shm \
    --enable-prefix-caching
API Reference
InfinityParser2
parser = InfinityParser2(model_name="infly/Infinity-Parser2-Pro")
| Parameter | Type | Default | Description |
|---|---|---|---|
model_name |
str |
"infly/Infinity-Parser2-Pro" |
HuggingFace model name or local path |
backend |
str |
"vllm-engine" |
Inference backend: "transformers", "vllm-engine", or "vllm-server" |
tensor_parallel_size |
int |
None |
GPU count by default. Tensor parallel size for vLLM Engine |
device |
str |
"cuda" |
Only "cuda" is supported |
api_url |
str |
"http://localhost:8000/v1/chat/completions" |
API URL for vLLM Server backend |
api_key |
str |
"EMPTY" |
API key for vLLM Server backend |
min_pixels |
int |
2048 |
Minimum pixel count for image input (transformers backend only) |
max_pixels |
int |
16777216 |
Maximum pixel count (~4096x4096), transformers backend only |
model_cache_dir |
str |
None |
Model cache directory (defaults to ~/.cache/infinity_parser2/) |
parse()
result = parser.parse("demo_data/demo.pdf")
| Parameter | Type | Default | Description |
|---|---|---|---|
input_data |
str | List[str] | PIL.Image |
Required | File path(s), directory path, or PIL Image object |
task_type |
str |
"doc2json" |
"doc2json" (layout to JSON) | "doc2md" (direct Markdown) | "custom" |
custom_prompt |
str |
None |
Custom prompt; required when task_type="custom" |
batch_size |
int |
4 |
Number of images to process per batch |
output_dir |
str |
None |
If set, saves results to this directory instead of returning them |
output_format |
str |
"md" |
"md" | "json". Only "md" is supported for doc2md / custom tasks |
pages |
str | List[int] |
None |
Physical page selection for PDF inputs, 1-based (e.g. "1-3,5" or [1, 3, 5]). All pages by default |
visualize_layout |
bool |
False |
If True, also saves a layout visualization of every page. Requires output_dir and task_type="doc2json" |
**kwargs |
— | — | Additional args passed to the model (e.g., max_new_tokens, temperature) |
Return Values
| Input | output_dir=None | output_dir set |
|---|---|---|
| Single file | str |
None |
| List of files | List[str] |
None |
| Directory | Dict[str, str] (path→content) |
None |
When output_dir is set, results are saved to output_dir/{filename}/result.md (or result.json).
With visualize_layout=True, each parsed page is additionally saved as output_dir/{filename}/layout/page_{n}.png, with the layout bboxes drawn on the page and colored per category.
Advanced Usage
Model Caching
Models are downloaded automatically on first use and cached at ~/.cache/infinity_parser2/. You can customize the cache location:
parser = InfinityParser2(
    model_name="infly/Infinity-Parser2-Pro",
    model_cache_dir="/path/to/cache"
)
Generation Parameters
result = parser.parse(
    "demo_data/demo.pdf",
    max_new_tokens=16384,
    temperature=0.01,
    top_p=0.95,
)
Utility Functions
from infinity_parser2 import (
    convert_pdf_to_images,
    convert_json_to_markdown,
    extract_json_content,
    get_files_from_directory,
    is_supported_file,
    SUPPORTED_TASK_TYPES,
    ModelCache,
    get_model_cache,
)

# Convert PDF pages to PIL Images
images = convert_pdf_to_images("demo_data/demo.pdf", dpi=300)

# Convert layout JSON to Markdown
markdown = convert_json_to_markdown(json_string)

# Check model cache
cache = get_model_cache()
print(cache.resolve_model_path("infly/Infinity-Parser2-Pro"))
Requirements
- Python 3.12+
- CUDA-compatible GPU
- vLLM >= 0.26.0 (vLLM backends only)
- See
setup.pyfor full dependency list.
Visual Parsing Examples
| Visualization | Note |
|---|---|
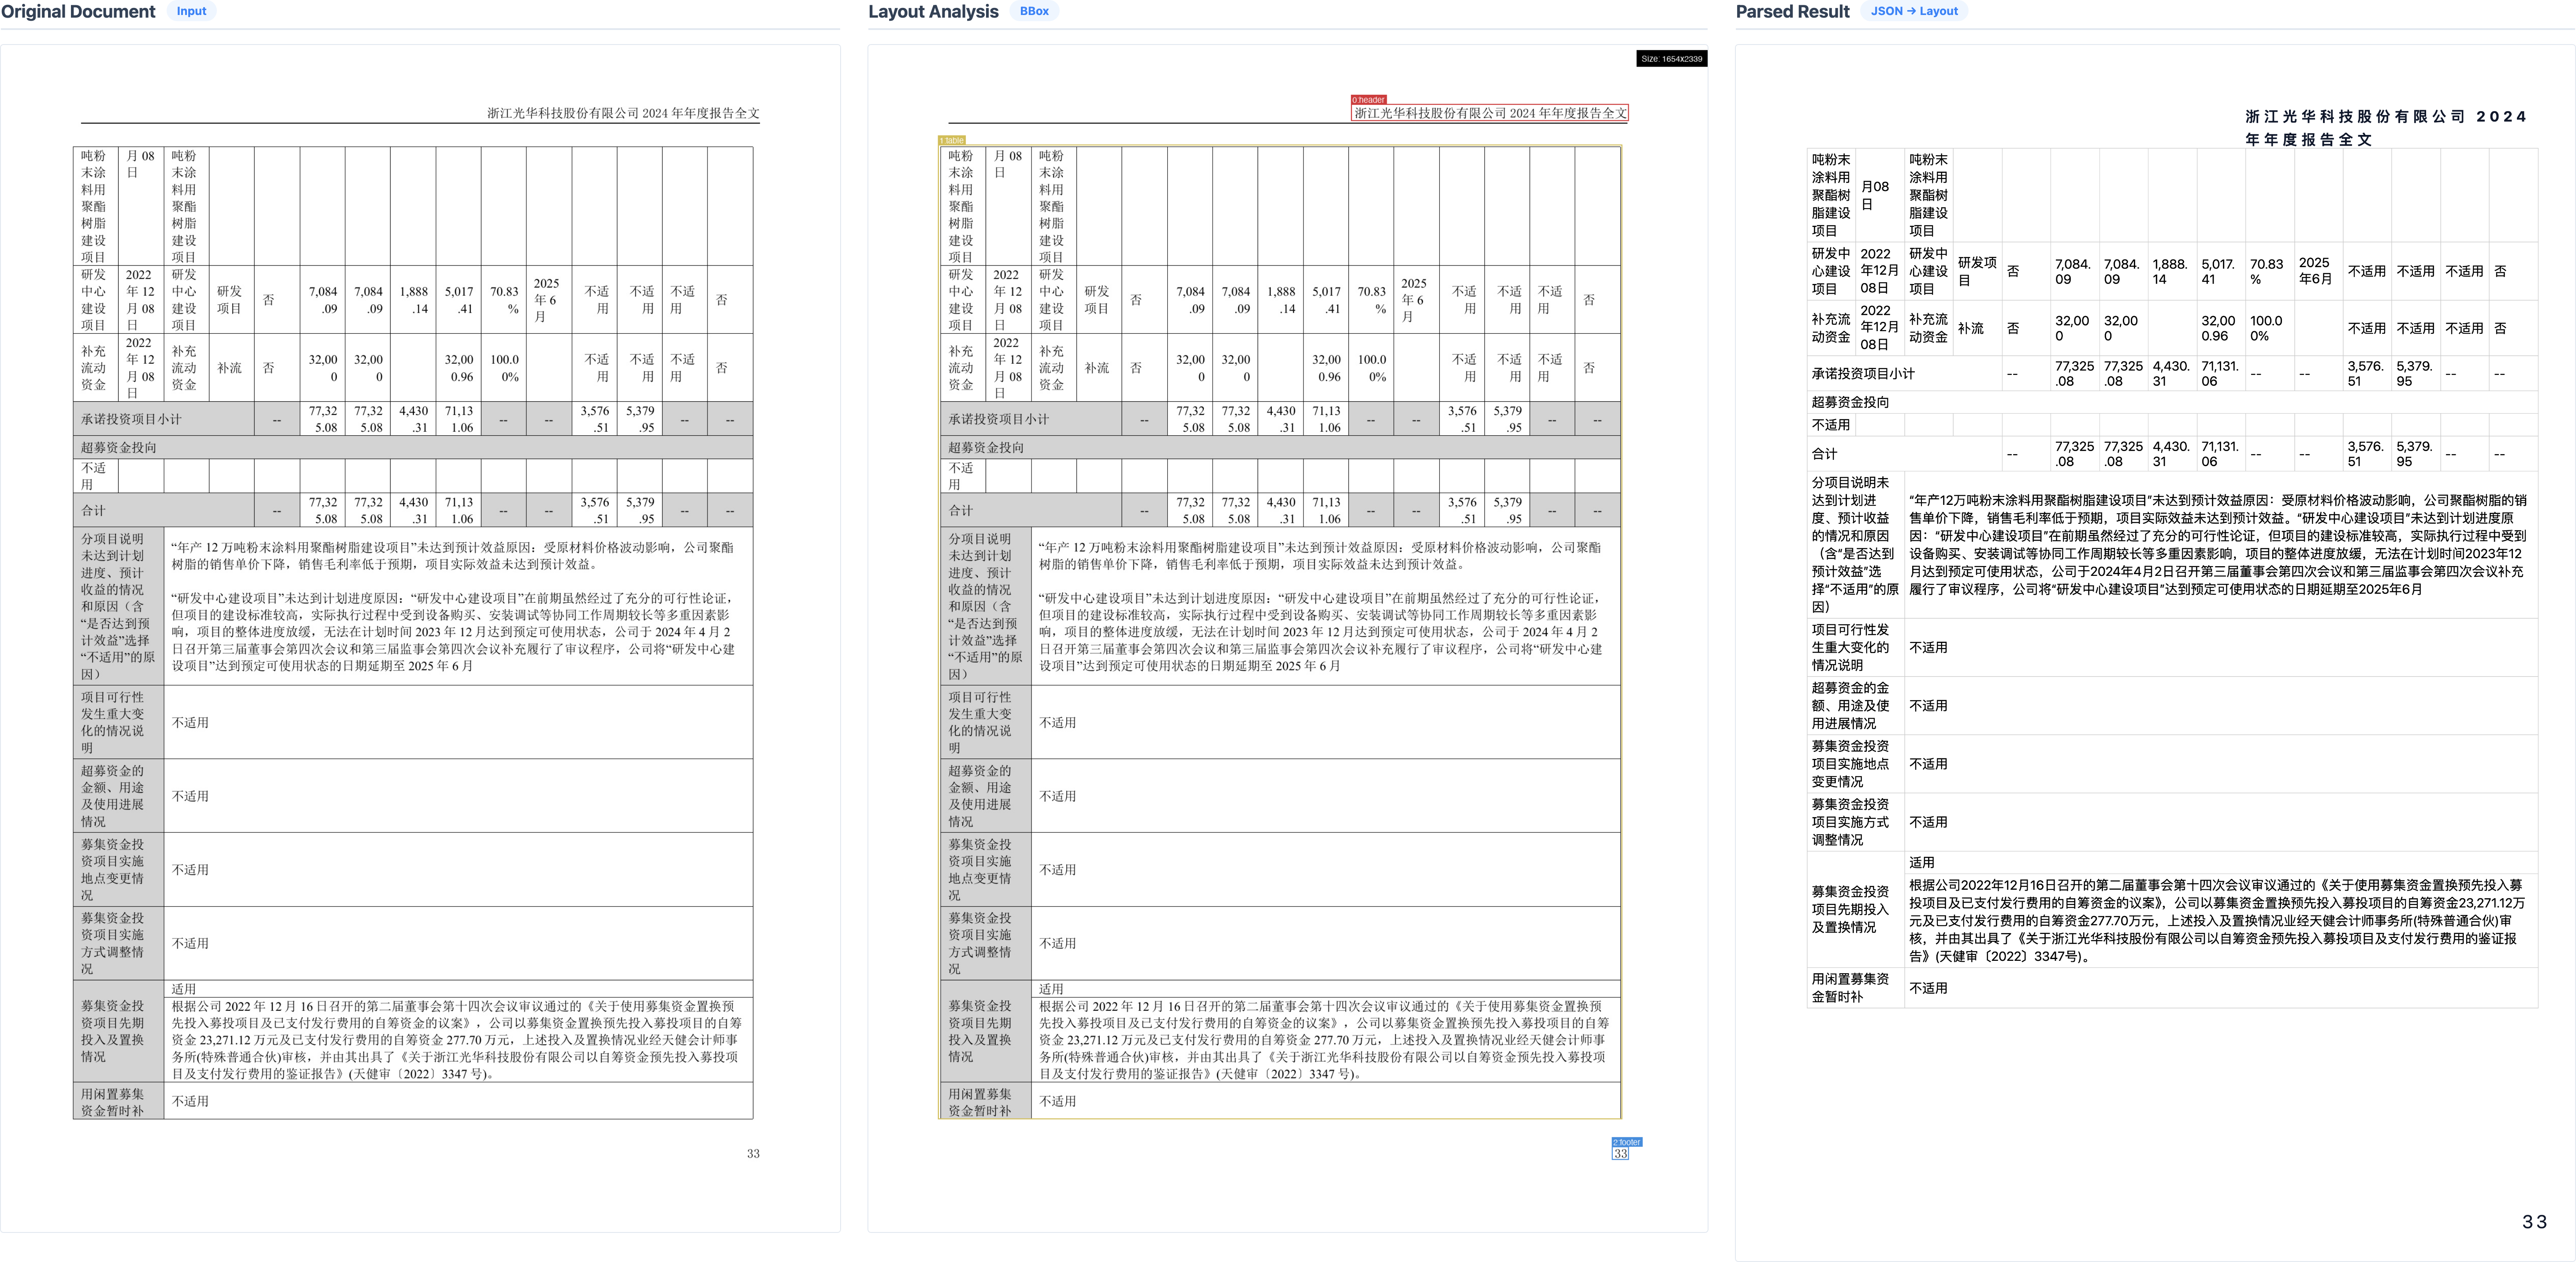
| A-Stock | Easy to miscount colspan in tables |
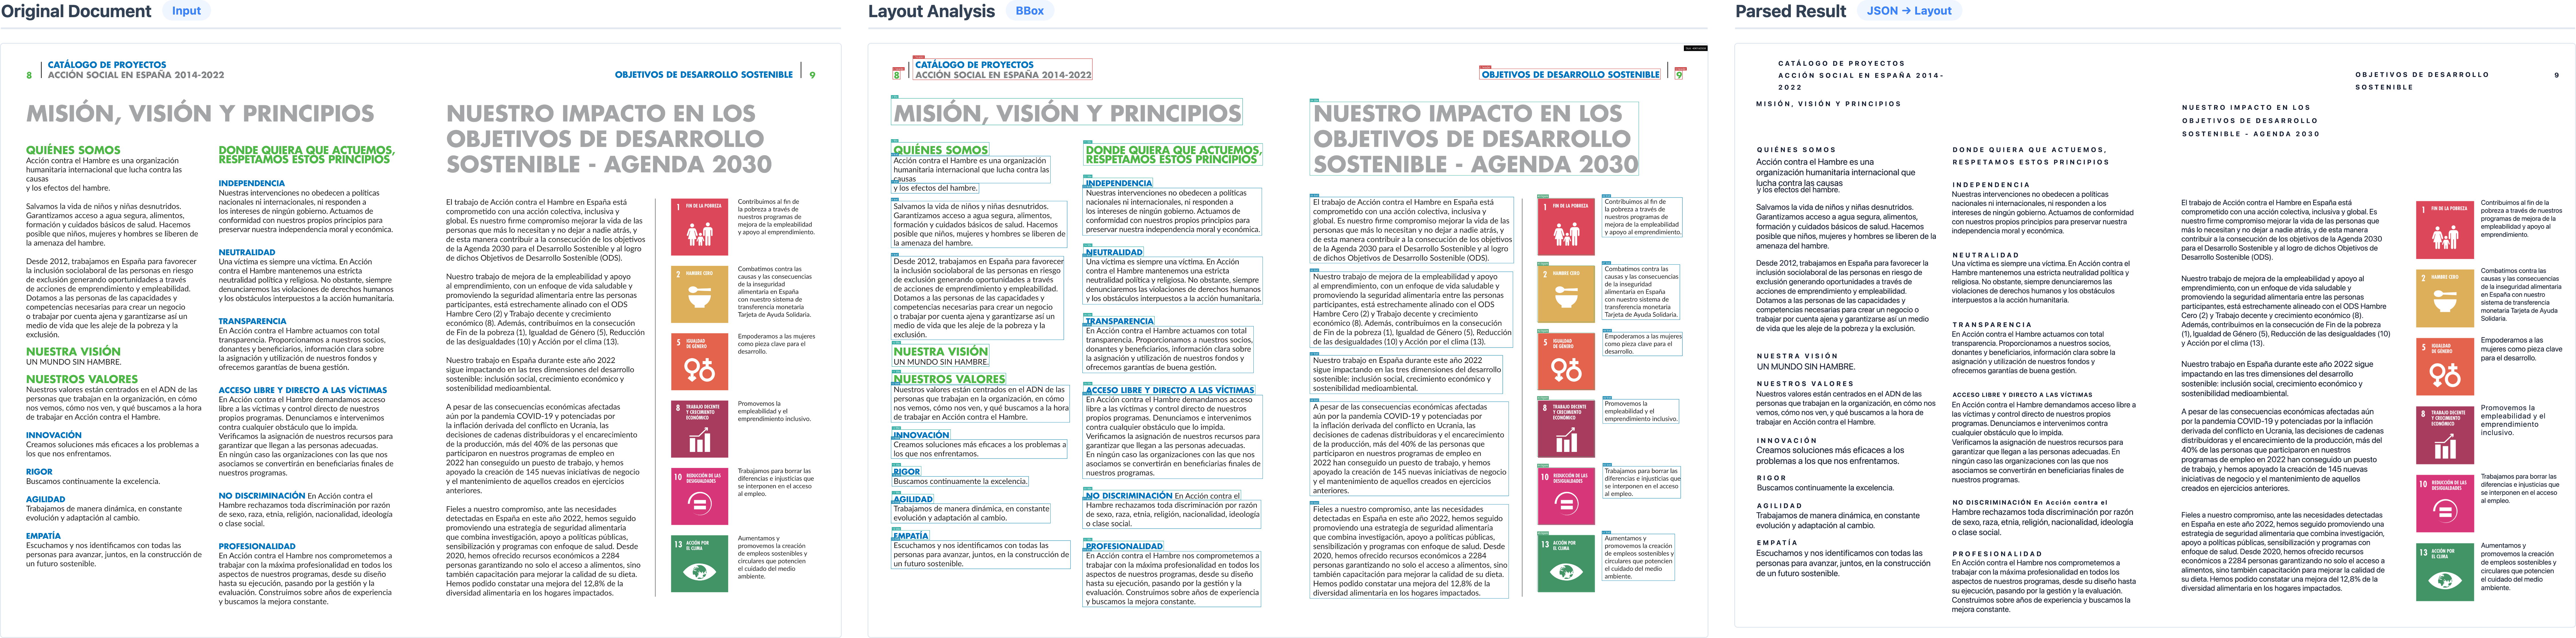
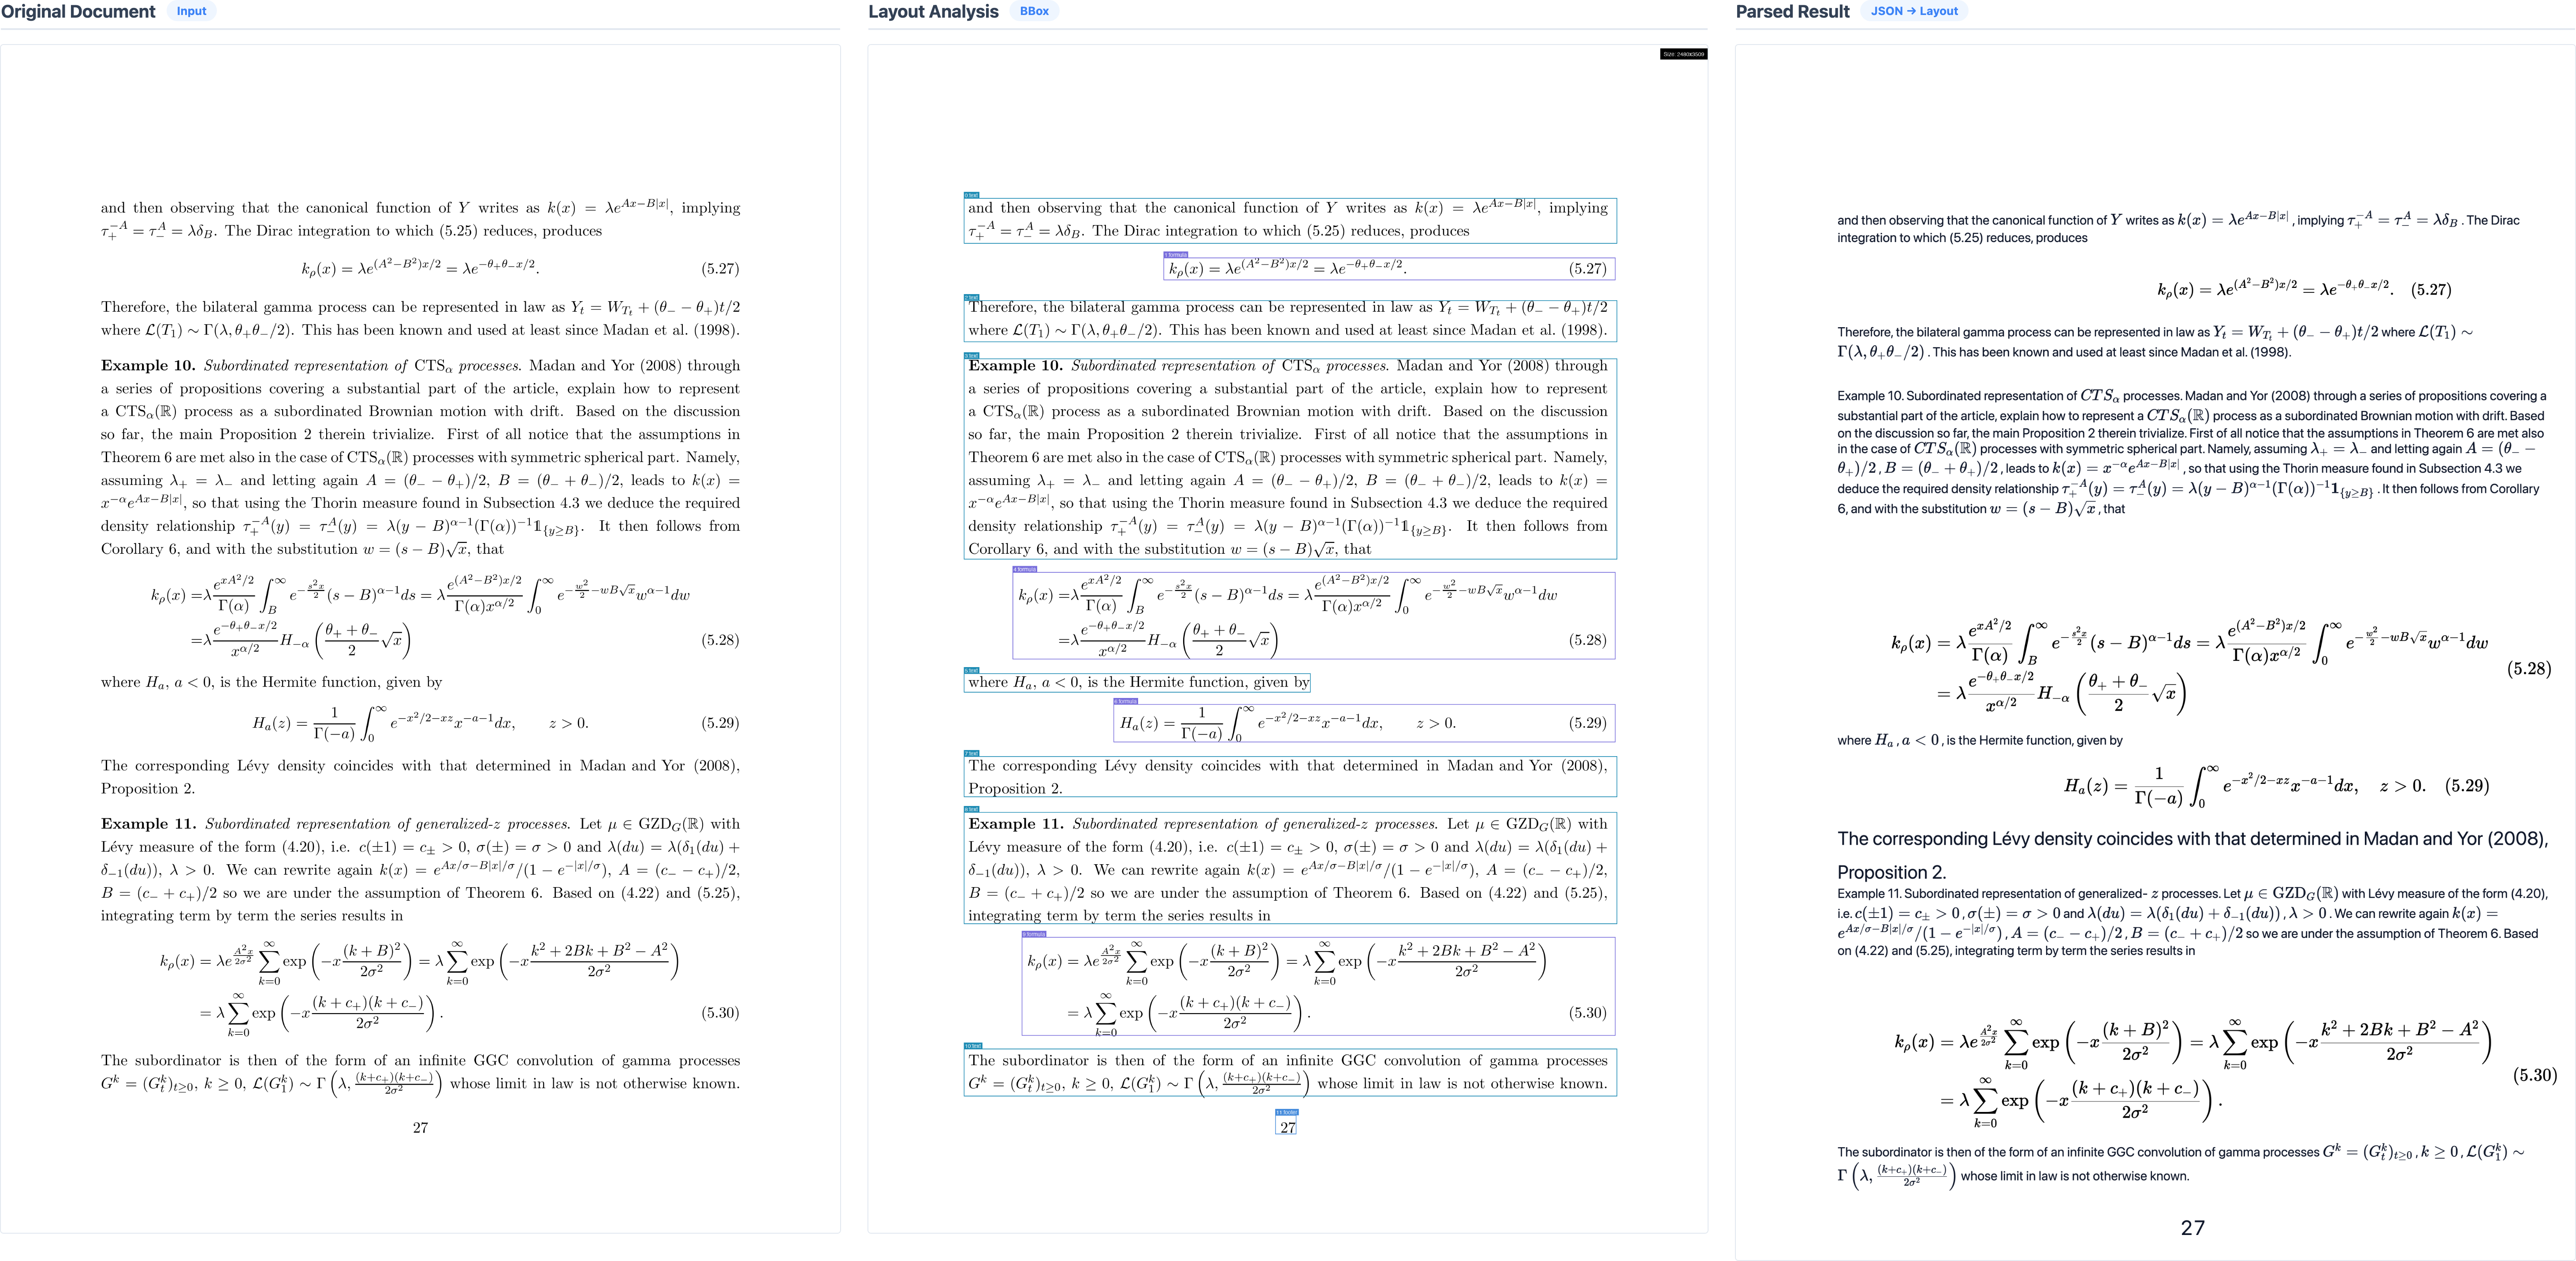
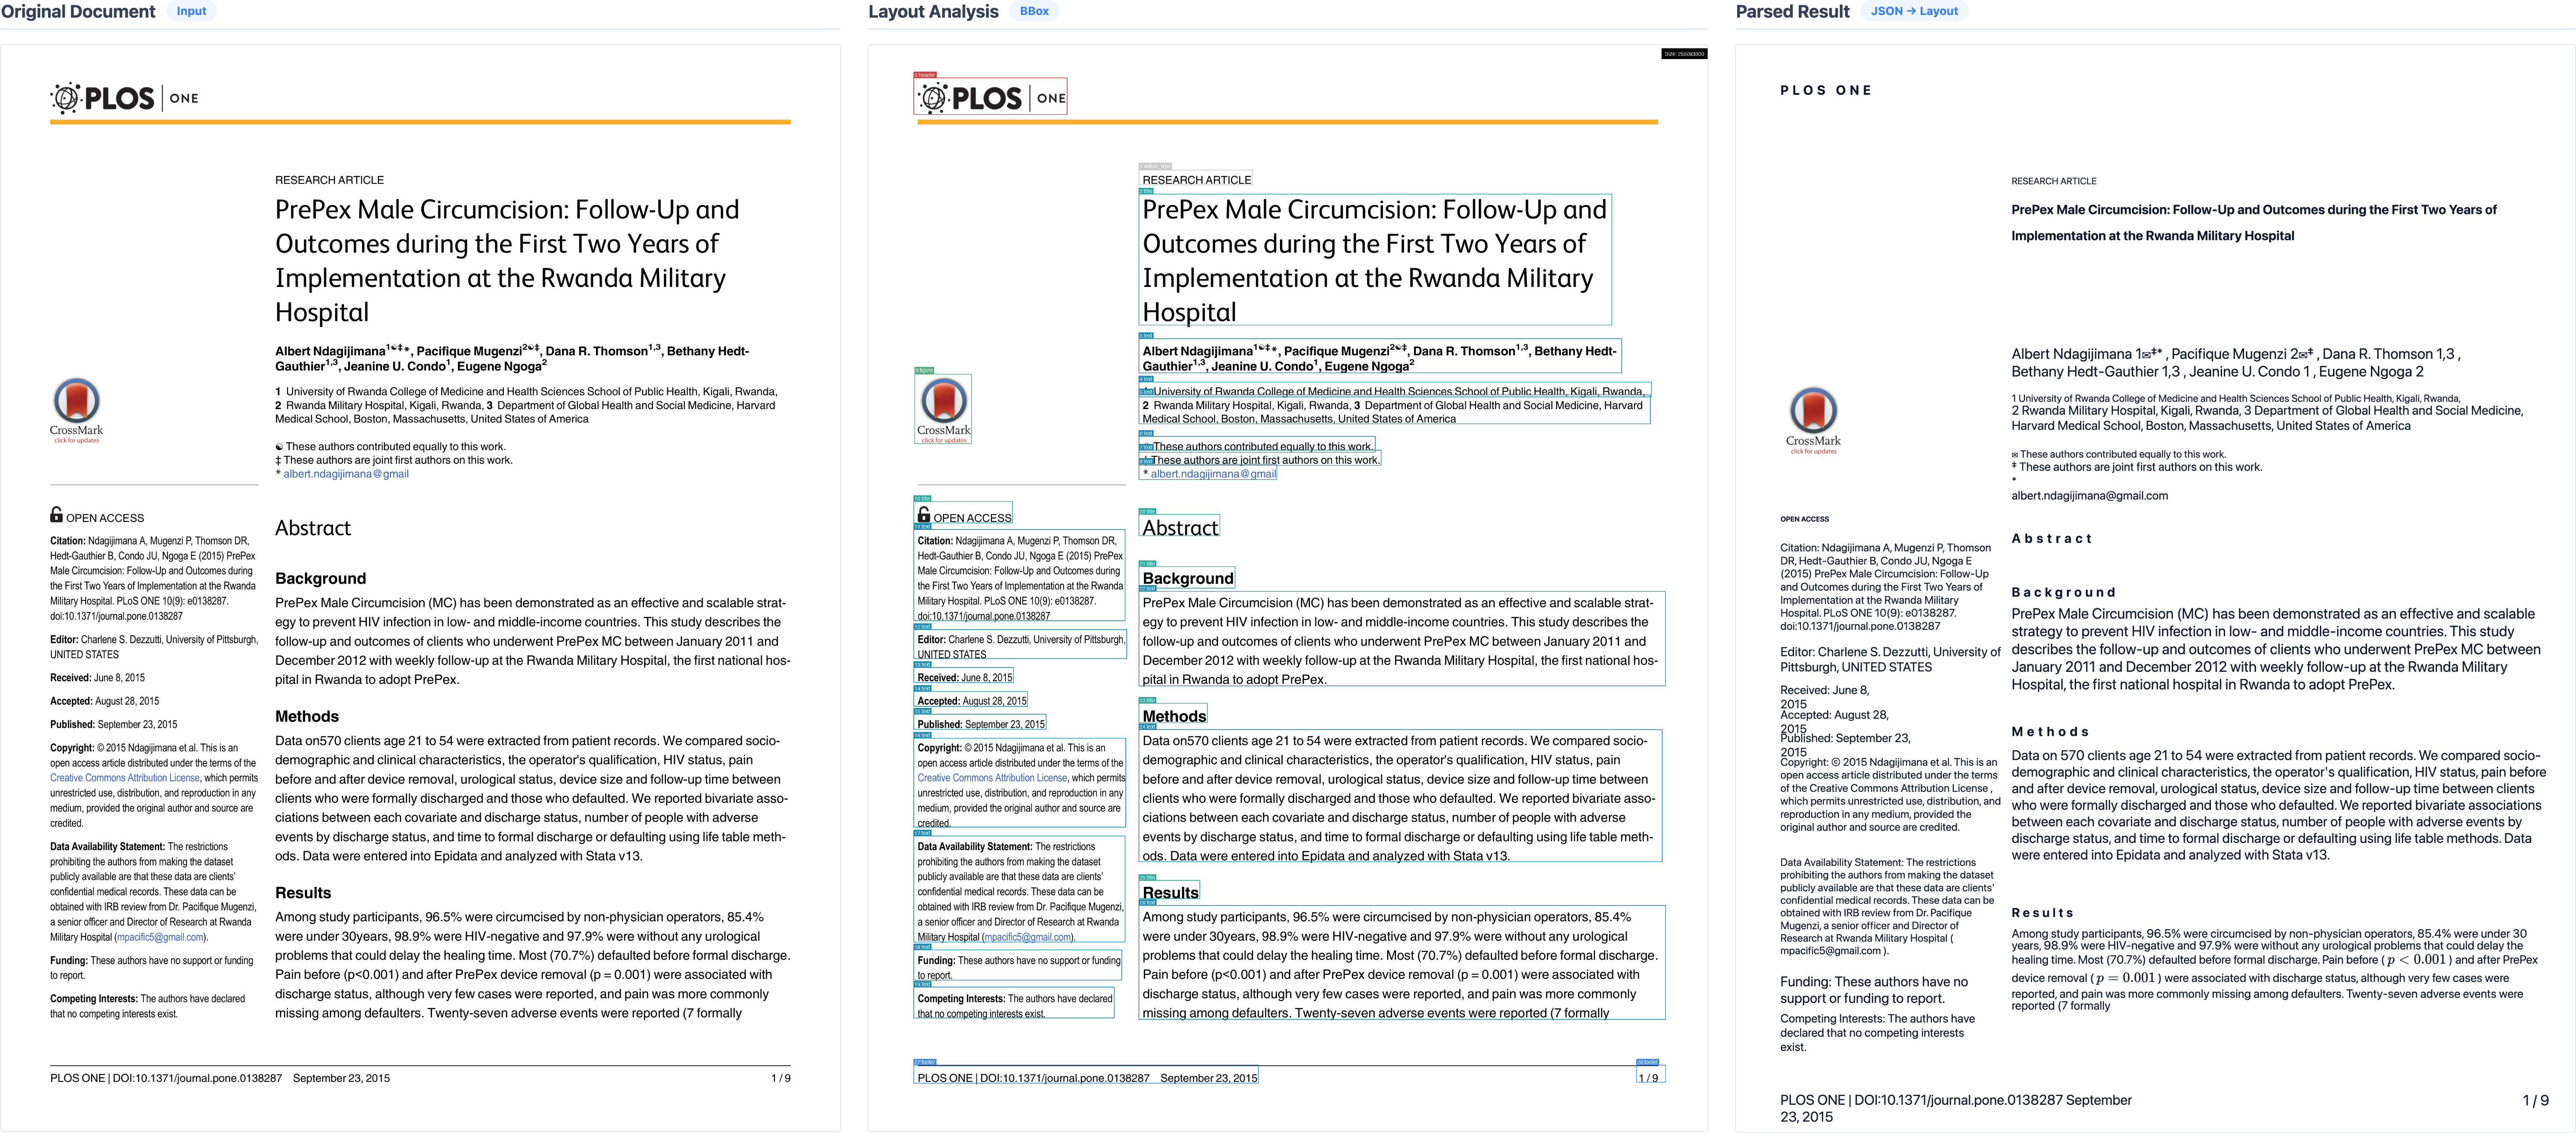
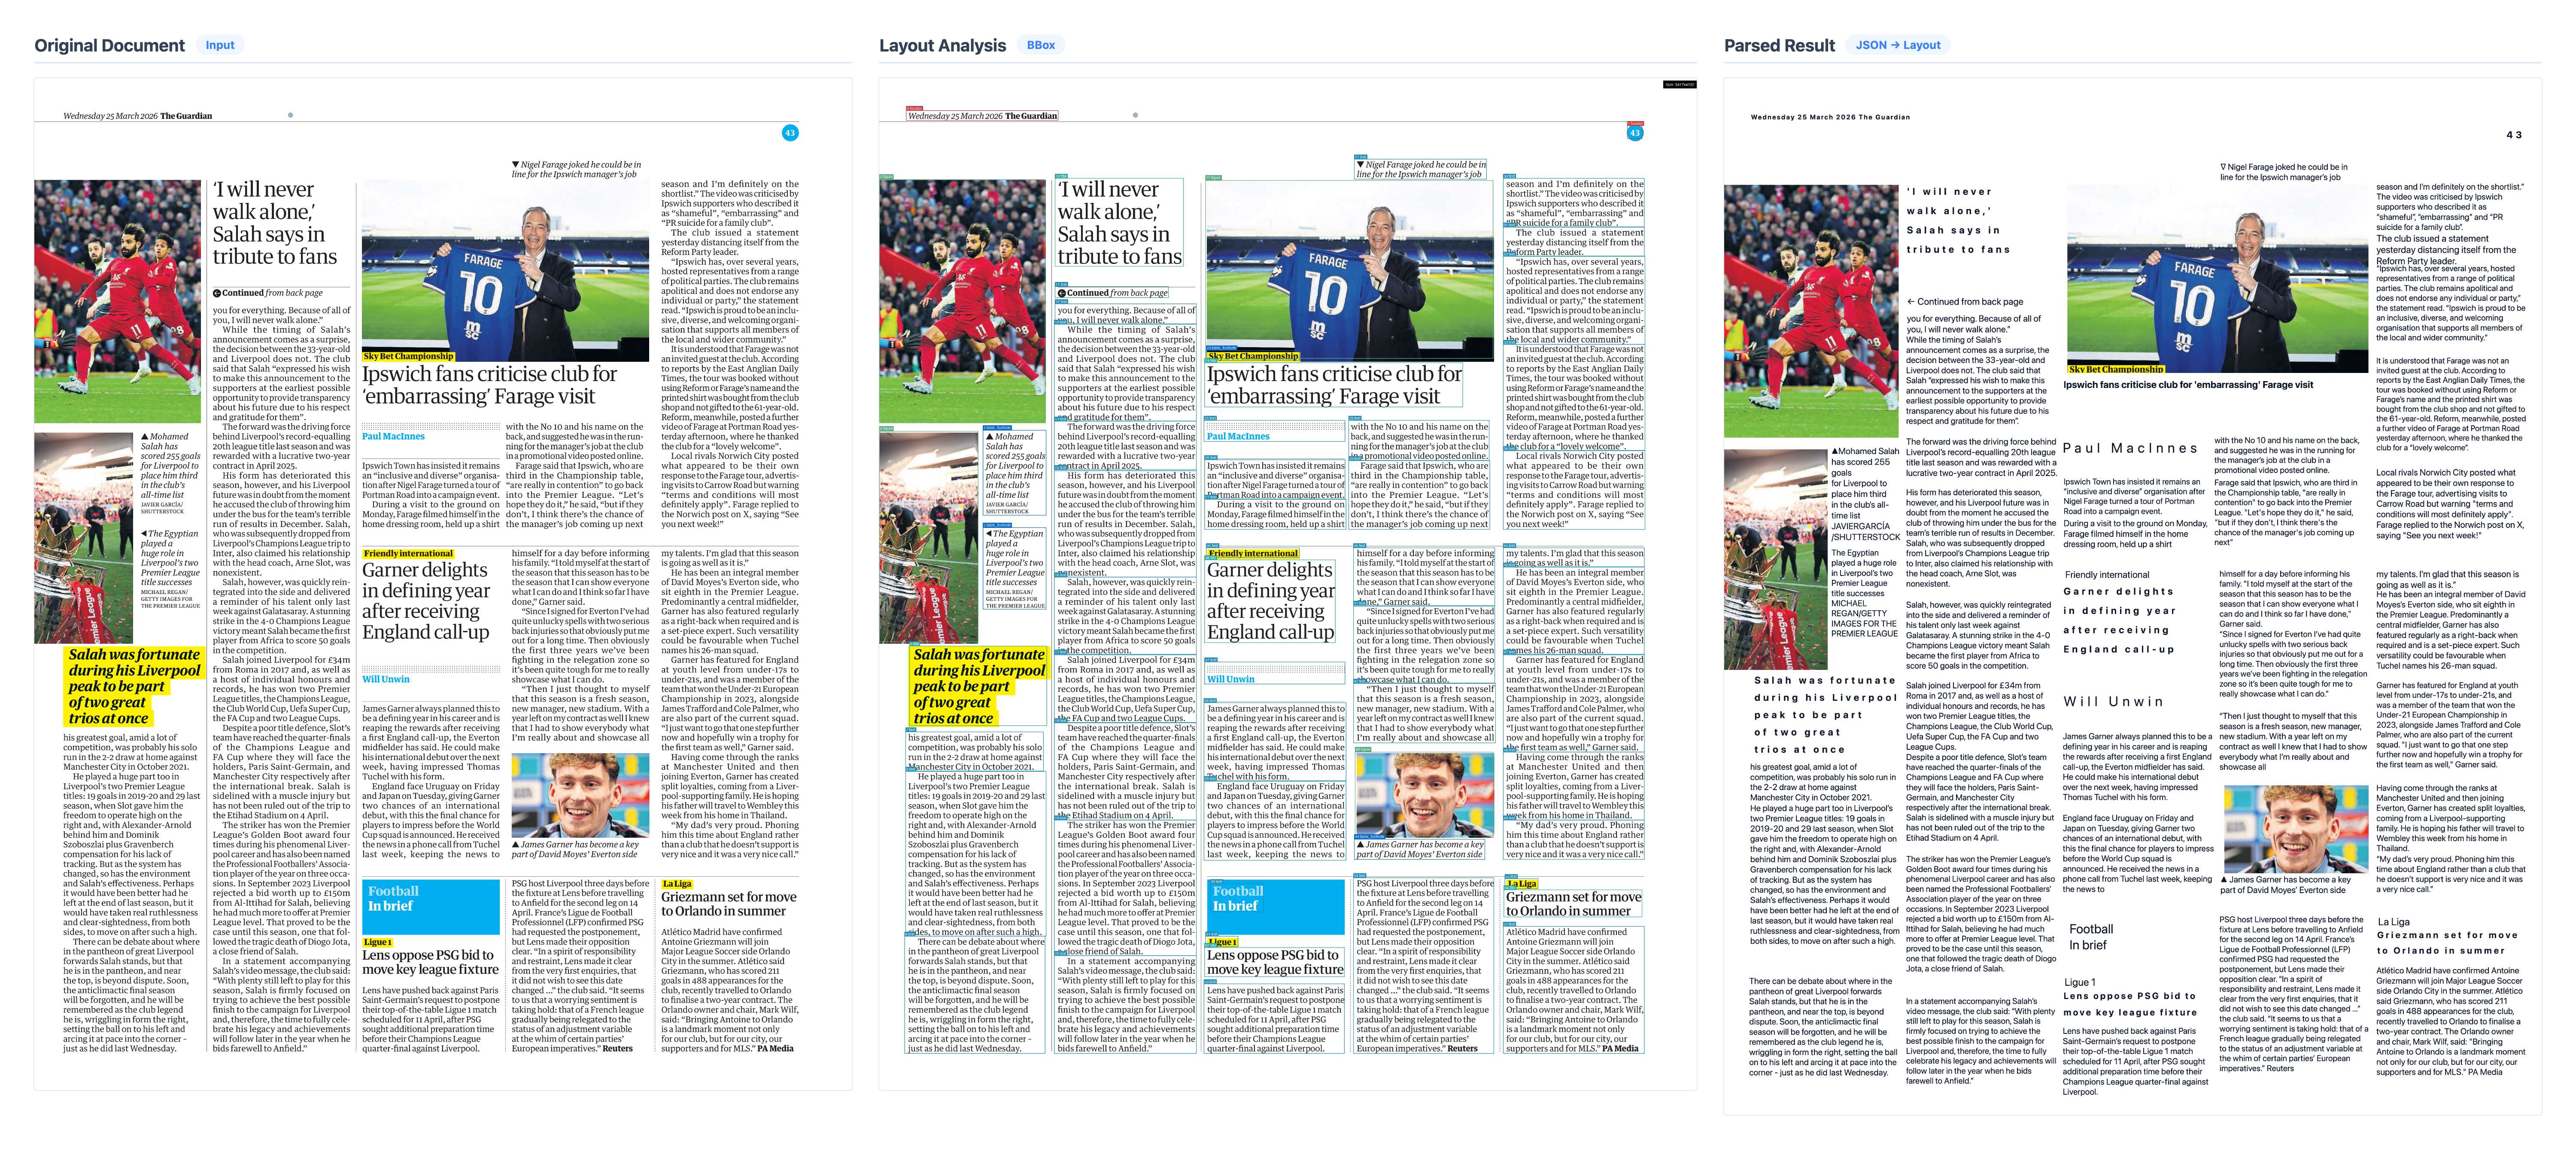
| Multi-Column Layout | Complex layout analysis and reading order recovery. |
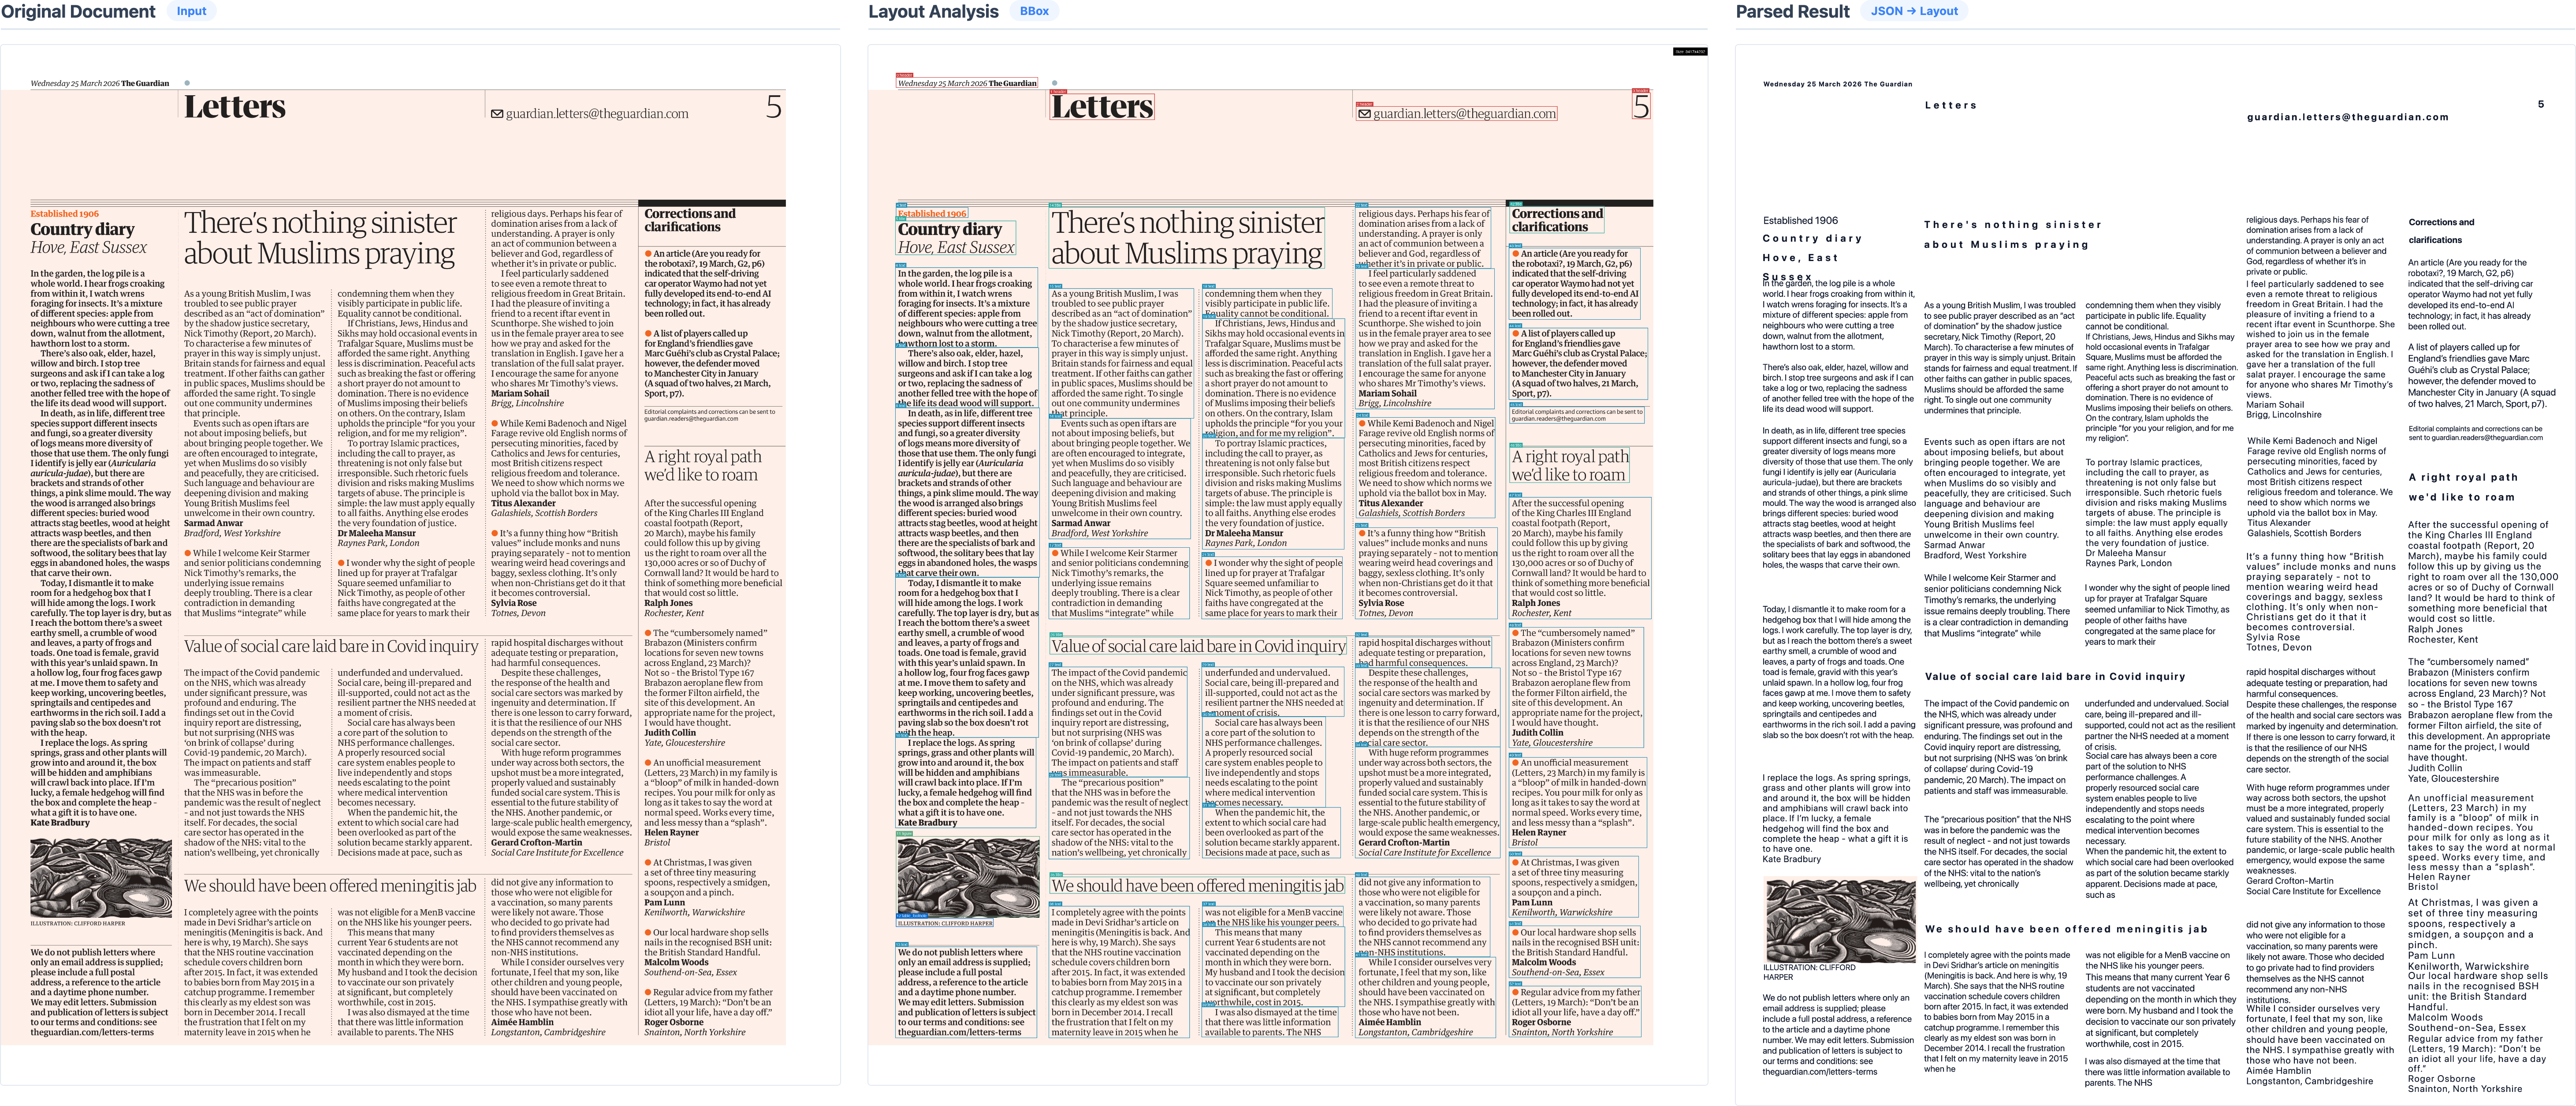
| Historical Newspaper | High probability of bounding box omission caused by ultra-dense text distribution, narrow column margins, and microscopic fonts. |
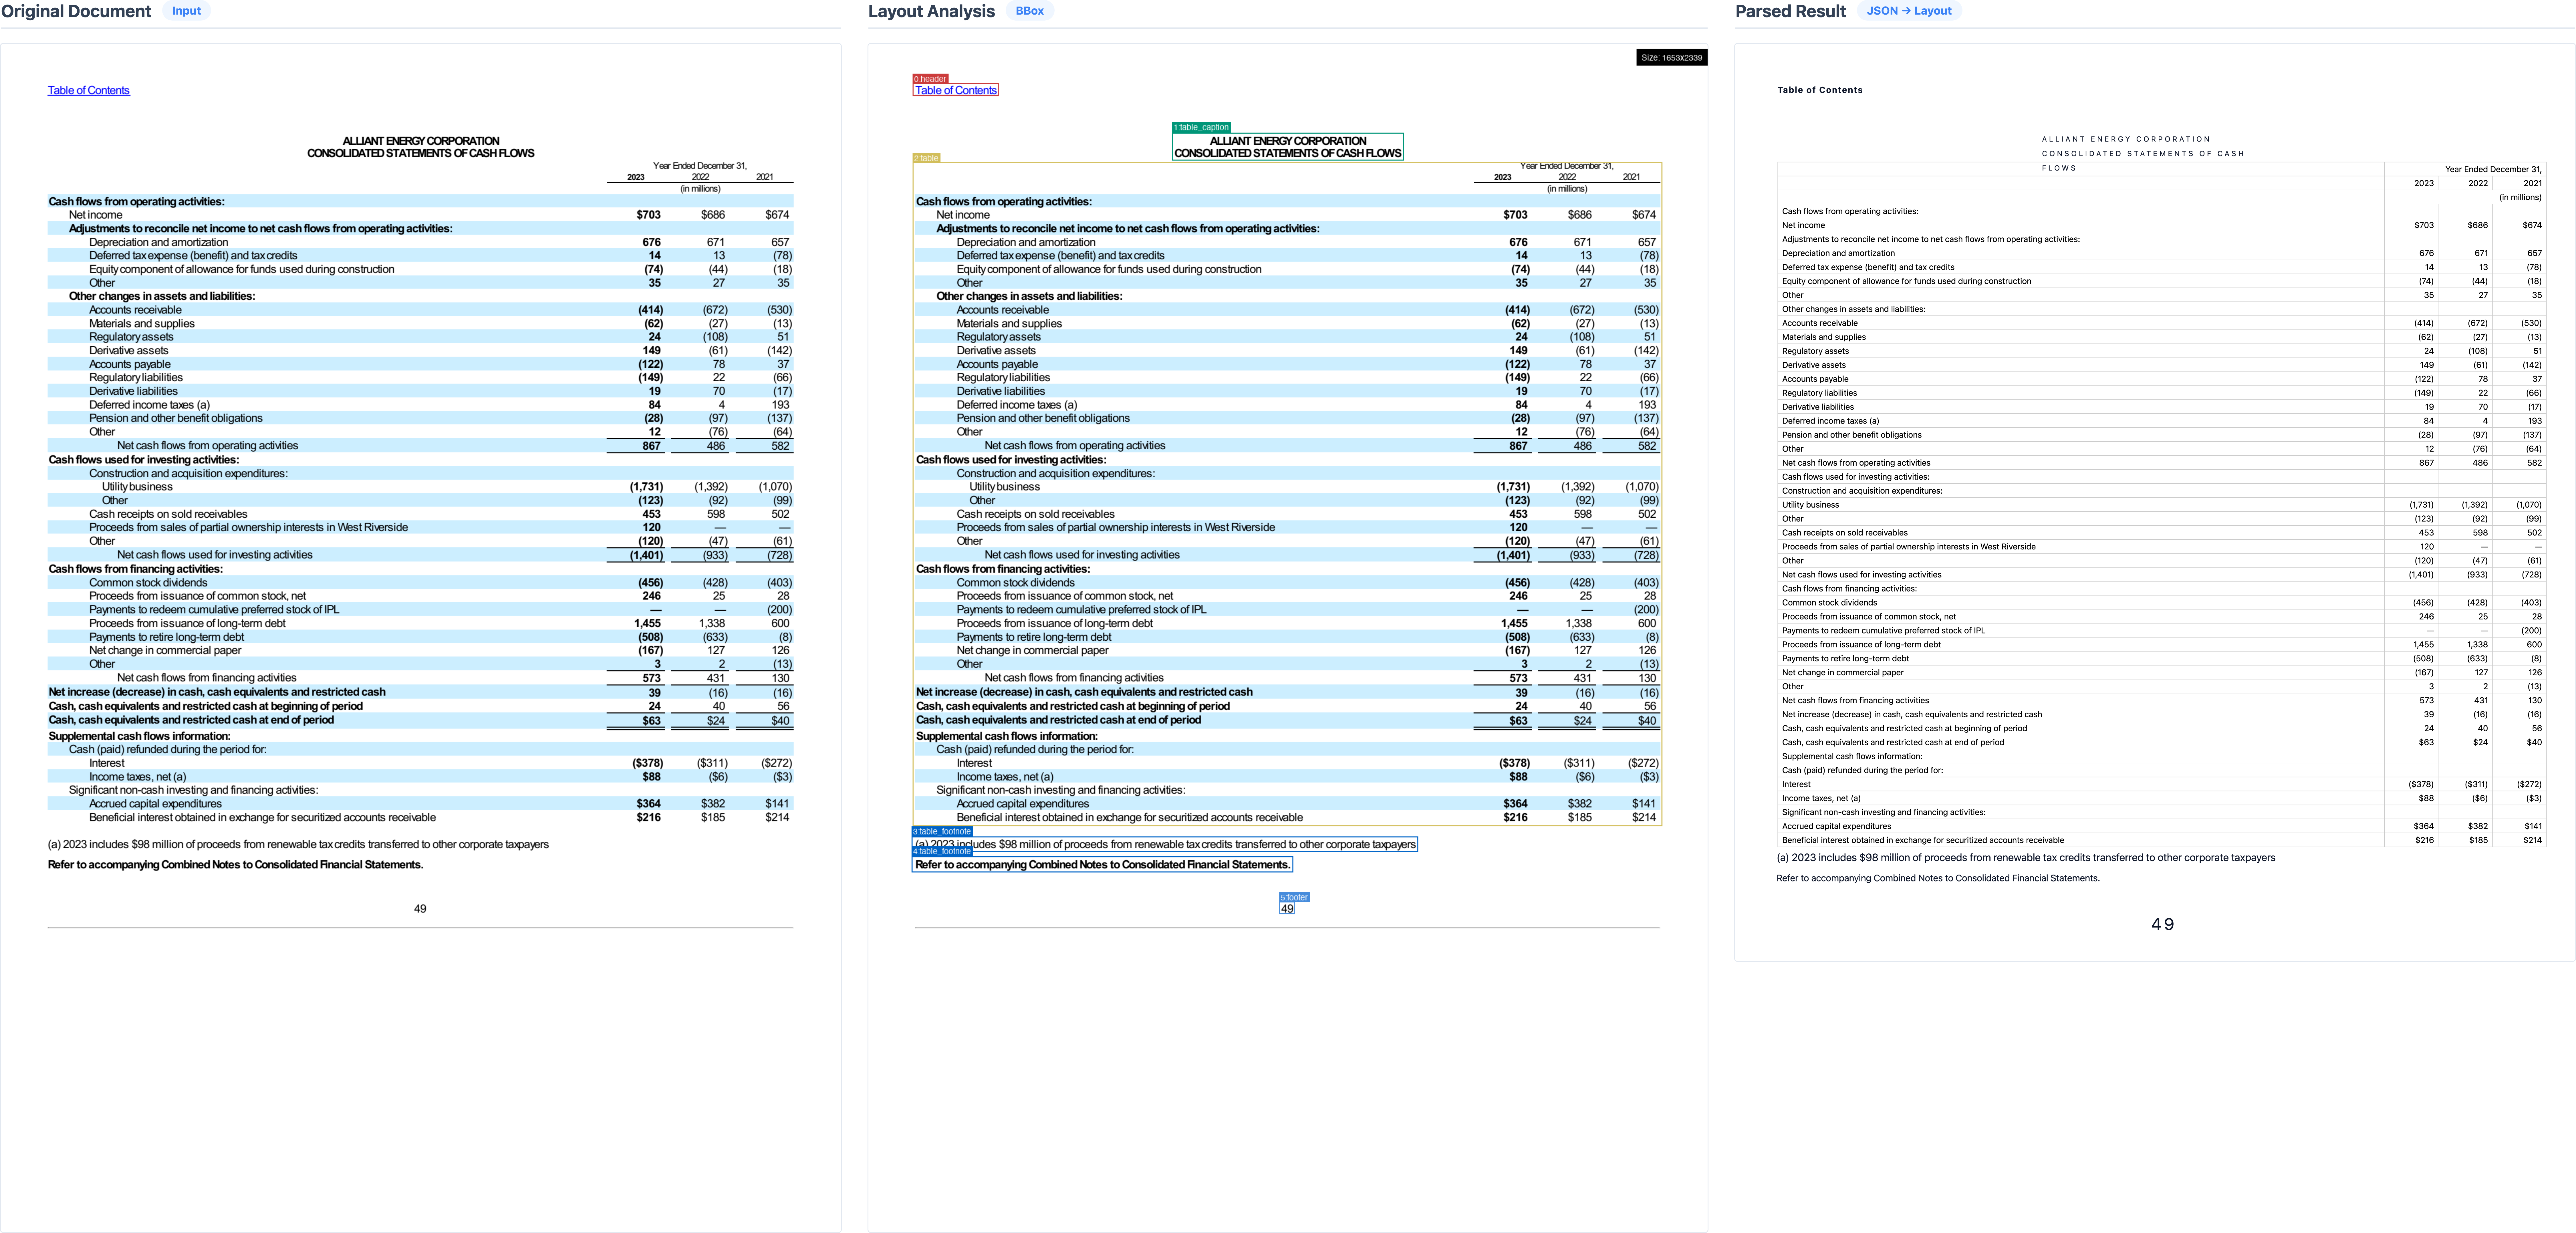
| US-Stock | Precise row alignment across wide frameless spaces and capturing the hierarchical semantics of indented headers. |
| Academic Paper (arXiv) | Accurate structural preservation of complex multi-line mathematical formulas, dense inline notations, and deeply nested subscripts/superscripts. |
| Magazine Page | Complex reading order recovery in an asymmetric multi-column layout. |
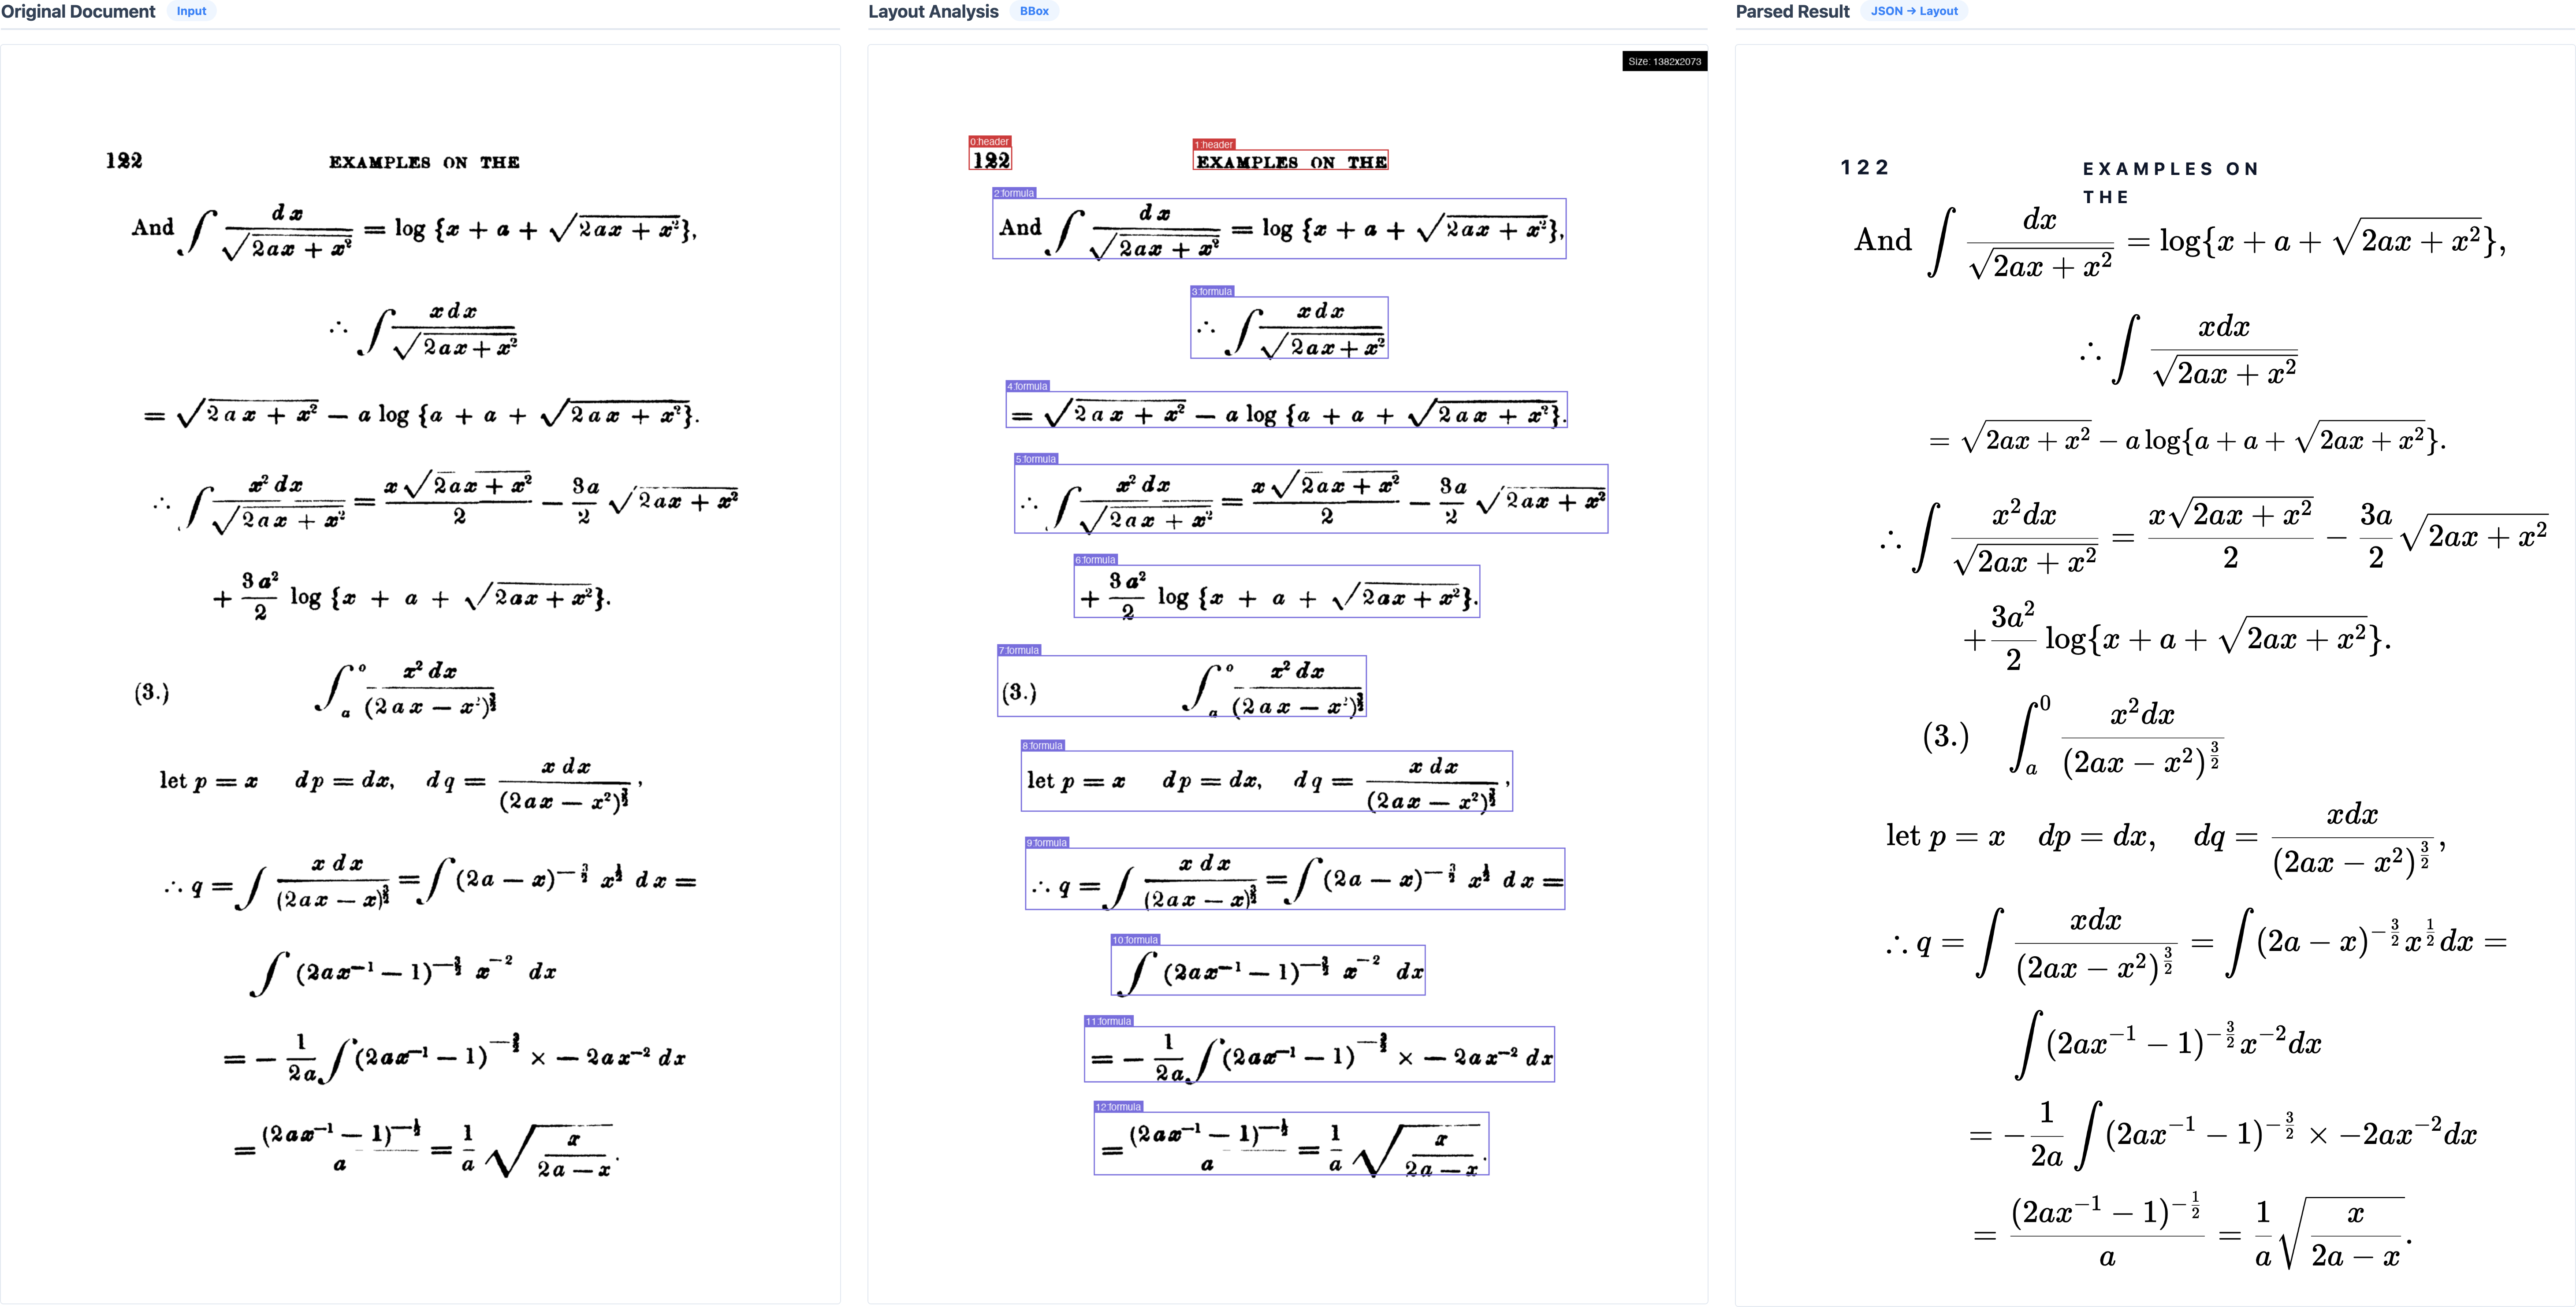
| Scanned Mathematics | Degraded and blurred print |
Limitations
Infinity-Parser2 has several known limitations to consider. It primarily supports English and Chinese documents, and performance degrades when processing multilingual content. Accuracy may also be reduced when parsing charts with complex layouts, as well as documents containing multi-oriented elements such as table rotated at varying angles. Additionally, the model does not capture fine-grained text formatting (e.g., bold, italic, strikethrough) and exhibits suboptimal multimodal instruction-following capability, meaning it may not always reliably follow complex multi-step visual instructions.
Acknowledgments
We would like to thank Qwen3.5, ms-swift, VeRL, lmms-eval, olmocr, PaddleOCR-VL, MinerU, dots.ocr, Chandra-OCR-2 for providing dataset, code and models.
Citation
@misc{huang2026infinityparser2technicalreport,
      title={Infinity-Parser2 Technical Report},
      author={Zuming Huang and Jun Huang and Kexuan Ren and Baode Wang and Weizhen Li and Jianming Feng and Yu Wang and Yichen Yao and Shijun Lin and Yige Tang and Cheng Peng and Weidi Xu and Wei Chu and Yinghui Xu and Yuan Qi},
      year={2026},
      eprint={2607.07836},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2607.07836},
}
1 maintainer

Metadata
1 maintainer
Release files for infinity-parser2 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| infinity_parser2-0.4.0.tar.gz | 62.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| infinity_parser2-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 110.0 kB
Release files / infinity_parser2-0.4.0.tar.gz
| Download URL | infinity_parser2-0.4.0.tar.gz |
|---|---|
| Size | 62.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
4829d63f46e9c6178401e817e10cd82e553215a8ba61ee0a69712a63787b4a30
|
|
BLAKE2b-256 checksum How to use checksums |
605309f777375903a3a1d58f8e6f27679af3d13de850e47b8b4d27708c8fc4c0
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.12
|
Release files / infinity_parser2-0.4.0-py3-none-any.whl
| Download URL | infinity_parser2-0.4.0-py3-none-any.whl |
|---|---|
| Size | 47.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
7a1faeff0212e2024bf735210ef3842e7c355e8124e056a65e0fd8a909117f8e
|
|
BLAKE2b-256 checksum How to use checksums |
75c852e3d9aa2e6e4929648deba625366052385b2b8247b352c69ed7b643aab5
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.12.12
|