
jev-lite
OpenAI-style Python client for TypeSafe Jev (System One).
Jev does not generate text. Send state plus typed questions; get structured
decisions with probabilities. jev-lite is the official TypeSafe HTTP client — sync
and async, same shape as the OpenAI Python SDK. jev-lite@0.0.2 added Dialogflow-style
system entities; jev-lite@0.0.3 adds a privacy filter and a reranker (all
three are previews, below); jev-lite@0.0.4 adds images and Box answers
for Jev 1.14; jev-lite@0.0.5 adds LocalTypeSafe, the same API answered by
an open model on your CPU with no API key; jev-lite@0.0.6 adds
OpenAIDecisions, the same API answered by OpenAI's Decisions API;
jev-lite@0.0.7 makes LocalTypeSafe read the state once per request, and
measures latency by question count for every
model on the board.
pip install jev-lite
# or: uv add jev-lite
Python 3.11+. Set TYPESAFE_API_KEY. Docs: https://docs.typesafe.ai/
Usage
from jev_lite import Choice, Noul, Score, TypeSafe

client = TypeSafe()  # TYPESAFE_API_KEY

result = client.system_one.create(
    state="I was charged twice. Please fix this ASAP.",
    questions={
        "billing": Noul(instructions="Is this ticket about billing?"),
        "tone": Choice(
            instructions="What is the customer's tone?",
            criteria={"calm": None, "frustrated": None, "angry": None},
        ),
        "urgency": Score(
            instructions="How urgent is this ticket?",
            criteria=["can wait", "this week", "today"],
        ),
    },
)

print(result.nouls["billing"].noul)
print(result.choices["tone"].choice)
print(result.scores["urgency"].score)
print(result.elapsed_ms, result.request_id, result.usage)
print(client.models.list())  # GET /v1/models
Async is the same surface with await:
from jev_lite import AsyncTypeSafe, Noul

async with AsyncTypeSafe() as client:
    result = await client.system_one.create(
        state="I was charged twice. Please fix this ASAP.",
        questions={"billing": Noul(instructions="Is this ticket about billing?")},
    )
    models = await client.models.list()
jev-latest is an alias that moves: on 2026-10-21 it answers as
jev-1.13.0, and jev-1.14.0 is opt-in. client.models.list() lists only
the aliases (jev-latest, jev-preview); response.model names the version
that answered. Pin a version with TypeSafe(model="jev-1.14.0") (or
TYPESAFE_DEFAULT_MODEL) when answers must repeat. Prefer one
system_one.create with many questions over a loop of calls. From 0.0.7 the
modules are pinned to jev-1.14.0 and use the client's model. On the same
day, 1.14 matched or beat 1.13 on every module below, and scored lower on
hard semantic decisions (461 vs 481 of 504 on semantic-decisions@v0.0.2).
Re-running unchanged questions can replay answers from disk
(pip install "jev-lite[cache]"):
client = TypeSafe(model="jev-1.14.0", cache="~/.cache/jev") # or a diskcache.Cache
Only 200 responses are stored, keyed on the request body (which carries the
model id). Pin a version: an alias such as jev-latest can move to a new model
while the cache keeps replaying the old one, so a cached alias warns. Leave the
cache off when you measure repeat or order stability.
Local decisions (CPU, no API key)
LocalTypeSafe answers the same system_one.create calls on this machine's
CPU with vllm-sr/d3-nano (2.2B,
Apache-2.0), exported to ONNX Runtime with int8 weights. No torch, no
transformers, no remote code.
pip install "jev-lite[local]" # about 40 MB download, 150 MB installed
from jev_lite import Choice, LocalTypeSafe

client = LocalTypeSafe()  # model "vllm-sr/d3-nano"
client.load()             # optional warm-up; the first run downloads 1.76 GiB
result = client.system_one.create(
    state="包裹顯示已送達,可是我家門口什麼都沒有。",
    questions={"route": Choice(criteria={"billing": "付款", "shipping": "配送"})},
)
print(result.choices["route"].choice)  # shipping
- Weights:
dockhardman/d3-nano-onnxat a pinned commit, each file checked against its sha256 and cached in~/.cache/jev-lite(cache_dir=); after that it runs offline. - Same API:
AsyncLocalTypeSafe,models.list(),cache=and the tracing spans work as forTypeSafe. Text only: an image or aBoxquestion raisesBadRequestError; a question over 8,192 tokens is refused, never truncated. - Quality: 449/504 on the zh-Hant
semantic-decisions@v0.0.2(hard 296/336), against 481 for hostedjev-1.13.0, with the same choice as the original bf16 model on all 504. The modules below are measured on hosted Jev only. - Speed: one question at a time on 20 Arm cores: a median of 0.5 s on short questions and 1.1 s on the bank's prompts, about 5 s at 1,100 tokens.
OpenAI Decisions
OpenAIDecisions sends the same system_one.create calls to OpenAI's
Decisions API (POST /v1/decisions). It needs no extra install; only the
client class changes.
from jev_lite import Choice, OpenAIDecisions

client = OpenAIDecisions()  # OPENAI_API_KEY; model "gpt-6-luna"
result = client.system_one.create(
    state="包裹顯示已送達,可是我家門口什麼都沒有。",
    questions={"route": Choice(criteria={"billing": "付款", "shipping": "配送"})},
)
print(result.choices["route"].choice)  # shipping
- Mapping:
Noul→ predicate (itstrue/falsetexts are appended to the instructions),Choice→ choice, andScore→ score levels. A question without instructions gets a short default.statethat is not a string is sent as compact JSON text. - Images: an
Imageinstateorinstructionsis sent as an image part. An image incriteriaand aBoxquestion raiseBadRequestErrorbefore anything is sent, as do counts the API refuses (1–400 questions, 2–255 options, 2–10 levels). - Same API:
AsyncOpenAIDecisions,cache=, typed errors,request_id,usageand the tracing spans work as forTypeSafe.models.list()returns thelunamodels. - Quality:
gpt-6-lunascored 442/504 on the zh-Hantsemantic-decisions@v0.0.2(hard 275/336), against 481 for Jevjev-1.13.0and 449 forLocalTypeSafe. It changed its answer with option order on 20 of 252 rows.
Images and Box (Jev 1.14, experimental)
Put an Image anywhere a value can go: in state, instructions or
criteria. The client uploads it as an asset and adds the
TypeSafe-Danger-Zone-Images header. A Box answer is where a target is,
as edges in fractions of the image; it needs jev-1.14.0.
from pathlib import Path
from jev_lite import Box, Image, Noul, TypeSafe

with TypeSafe(model="jev-1.14.0") as client:
    result = client.system_one.create(
        state={"photo": Image(Path("kitchen.jpg"))},  # PNG/JPEG, sides 280-1568 px
        questions={
            "has_mug": Noul(instructions="Is there a coffee mug in `photo`?"),
            "mug": Box(instructions="the coffee mug in `photo`"),
        },
    )

mug = result.boxes["mug"]
print(mug.box.left, mug.box.top, mug.box.right, mug.box.bottom, mug.confidence)
A Box always returns a box, so gate it on the Noul. An image costs about
2·⌈w/28⌉·⌈h/28⌉ input tokens. Measured limits (targets under ~40 px,
counting past five, text under 7 px); the benchmark is
image-questions@v0.0.1.
System entities (preview)
jev_lite.system_entities extracts the 59 Dialogflow ES system entities
(@sys.date-time, @sys.unit-currency, @sys.geo-city, …) and fills
typed slots, in ten languages (en and zh-Hant primary). Code proposes
candidates, Jev decides (the client's model), code normalizes. Preview: the API
may change within 0.0.x. Same install; no extra dependency.
from datetime import datetime
from zoneinfo import ZoneInfo

from jev_lite import TypeSafe
from jev_lite.system_entities import extract

now = datetime(2026, 10, 1, 16, 0, tzinfo=ZoneInfo("Asia/Taipei"))
with TypeSafe() as client:
    result = extract(client, "Book a table for 4 next Friday at 7pm", ["date-time", "number"], now=now)
for match in result.matches:
    print(match.entity, match.span.text, match.value)  # number 4 …; date-time … 2026-10-09 19:00
Slot filling (extract_slots), async (aextract, aextract_slots) and the
value models are documented in the module's docstrings. Extraction is not a
security boundary, probability is not calibrated, and th, ms and other
languages outside the ten get few matches. On the held-out set
system-entities-cases@v0.0.1 (301 cases, ten languages) jev-lite@0.0.5 (unchanged in 0.0.6) is
98.9% exact on accepted values with 98.9% coverage on jev-1.13.0
(jev-lite@0.0.4: 98.9% on jev-1.13.0, 99.3% on jev-1.14.0).
Privacy filter and reranker (preview)
jev_lite.privacy_filter and jev_lite.reranker ship in jev-lite@0.0.3
as previews: the APIs may change within 0.0.x. Import them as modules
(from jev_lite.privacy_filter import detect, from jev_lite.reranker import rerank). Both use the client's model and are pinned to jev-1.14.0 from
0.0.7; the numbers are on jev-1.13.0, with the same-day 1.14 run beside them.
Privacy filter: private-span detection. Public multilingual gold (ai4privacy OpenPII, Gretel finance, NVIDIA Nemotron-PII), 300 test texts, exact-span precision / recall:
| Setup | P / R | Over-redaction | Speed |
|---|---|---|---|
| openai/privacy-filter, local GPU | 63.4 / 62.9 | 5.2% | ~20 ms per text |
| openai/privacy-filter proposes, Jev decides | 75.4 / 60.1 | 2.5% | p50 210 ms |
| Jev only, no GPU (broader proposals, per-label cuts) | 68.6 / 60.5 | 2.4% | p50 215 ms |
| Jev only, round-04 default | 80.4 / 57.6 | 1.5% | p50 210 ms |
| Jev only, before the person proposer | 78.3 / 63.6 | 1.6% | p50 209 ms |
Jev only, default detect(client, text), no GPU |
79.3 / 69.2 | 1.6% | p50 ~0.7 s |
Same default on jev-1.14.0 (same-day 1.13: 79.7 / 69.7, 1.6%) |
82.4 / 68.2 | 1.3% | call p50 0.19 s |
The default uses per-label proposers and cuts fitted on dev, and finds
people with system_entities person spans plus a person detect Noul (person
recall 43.9 → 71.9), with an order-stable name boundary. On overlap it
scores 88.9 / 77.6; exact address recall is 0 because the gold splits an
address into components while the filter masks the whole address. It fails
most written robustness bars, so it is a preview. Hosted Jev sees the raw
text before masking.
Reranker: batched evidence Noul over a first-stage pool (balanced batches of at most 30, independent of the caller's order), nDCG@10:
| Bank | First stage | Reranked | Query p50 | Same day, 1.13 → 1.14 |
|---|---|---|---|---|
| SciFact (50 q) | .556 | .638 | 0.30 s | .635 → .634 |
| FiQA (50 q) | .219 | .346 | 0.26 s | .346 → .348 |
| zh, BM25 (50 q) | .526 | .587 | 0.30 s | .603 → .618 |
| zh, E5 (50 q) | .551 | .647 | 0.27 s | .640 → .656 |
| Mr. TyDi ko / ja / ar (30 q each) | .415 / .605 / .529 | .675 / .791 / .754 | 0.23–0.24 s | .687 / .791 / .741 → .675 / .808 / .741 |
A batch score is relative to the other passages in its request, not a
standalone probability. A passage that echoes the relevance criteria can be
lifted into the top 10; rerank(..., check_echo=True) (off by default)
re-checks the top-k and moves such passages down, at about +0.23 s.
Tracing
Off by default. Opt in and pick the destination:
from jev_lite import instrument

instrument(endpoint="http://127.0.0.1:4318")  # local Grafana LGTM
Or set OTEL_EXPORTER_OTLP_ENDPOINT and call instrument(), or install your
own TracerProvider first (Logfire, etc.). Spans record prompt, result, and
latency.
Upgrading from 0.0.1–0.0.5
- Pin the model.
jev-latestmoves to new versions, and answers and confidence shift with it. UseTypeSafe(model="jev-1.14.0")(0.0.7; it wasjev-1.13.0before), and refit any confidence cut when you move. A cached client asking for an alias warns (0.0.6). Noul(true=..., false=...)works from 0.0.5. Before that, the shorthand was silently ignored; usecriteria=NoulCriteria(...)there. Unknown question fields warn from 0.0.5.- Replay cache:
TypeSafe(cache="dir")(0.0.3,jev-lite[cache]) replaces hand-made caches.jev_lite.evalis research code, not a stable API. - Confidence comes with every Choice and Score answer; do not recompute
it. From 0.0.6,
TypeSafe,LocalTypeSafeandOpenAIDecisionsall report(n·p_max − 1)/(n − 1). - Other backends behind the same calls:
LocalTypeSafe(0.0.5, CPU, no key) andOpenAIDecisions(0.0.6). A self-hosted server that speaks/v1/systemoneworks throughTypeSafe(base_url=...). - Modules (
system_entities,privacy_filter,reranker) use the client's model from 0.0.5. From 0.0.7 they are pinned tojev-1.14.0; their tables give 1.13 and 1.14 from the same day.
Develop
uv sync --dev
uv run ruff check . && uv run pytest
The supported public API is the TypeSafe client. Optional local engines live
under jev_lite.engine (pip install 'jev-lite[ml]').
Semantic decisions v0.0.2
Dataset semantic-decisions@v0.0.2, versioned separately from the package.
252 frozen zh-Hant rows in 18 families (36 easy, 48 medium, 168 hard), gold derived from visible text. This natural zh-Hant v1 qualified freeze is v0.0.2, and it is the only semantic-decision eval in this repo. Every model answers the same 504 locked requests: each row in canonical and left-rotated option order. Charts are percent correct. The families were seen during development before the freeze, so this is not unseen confirmation.
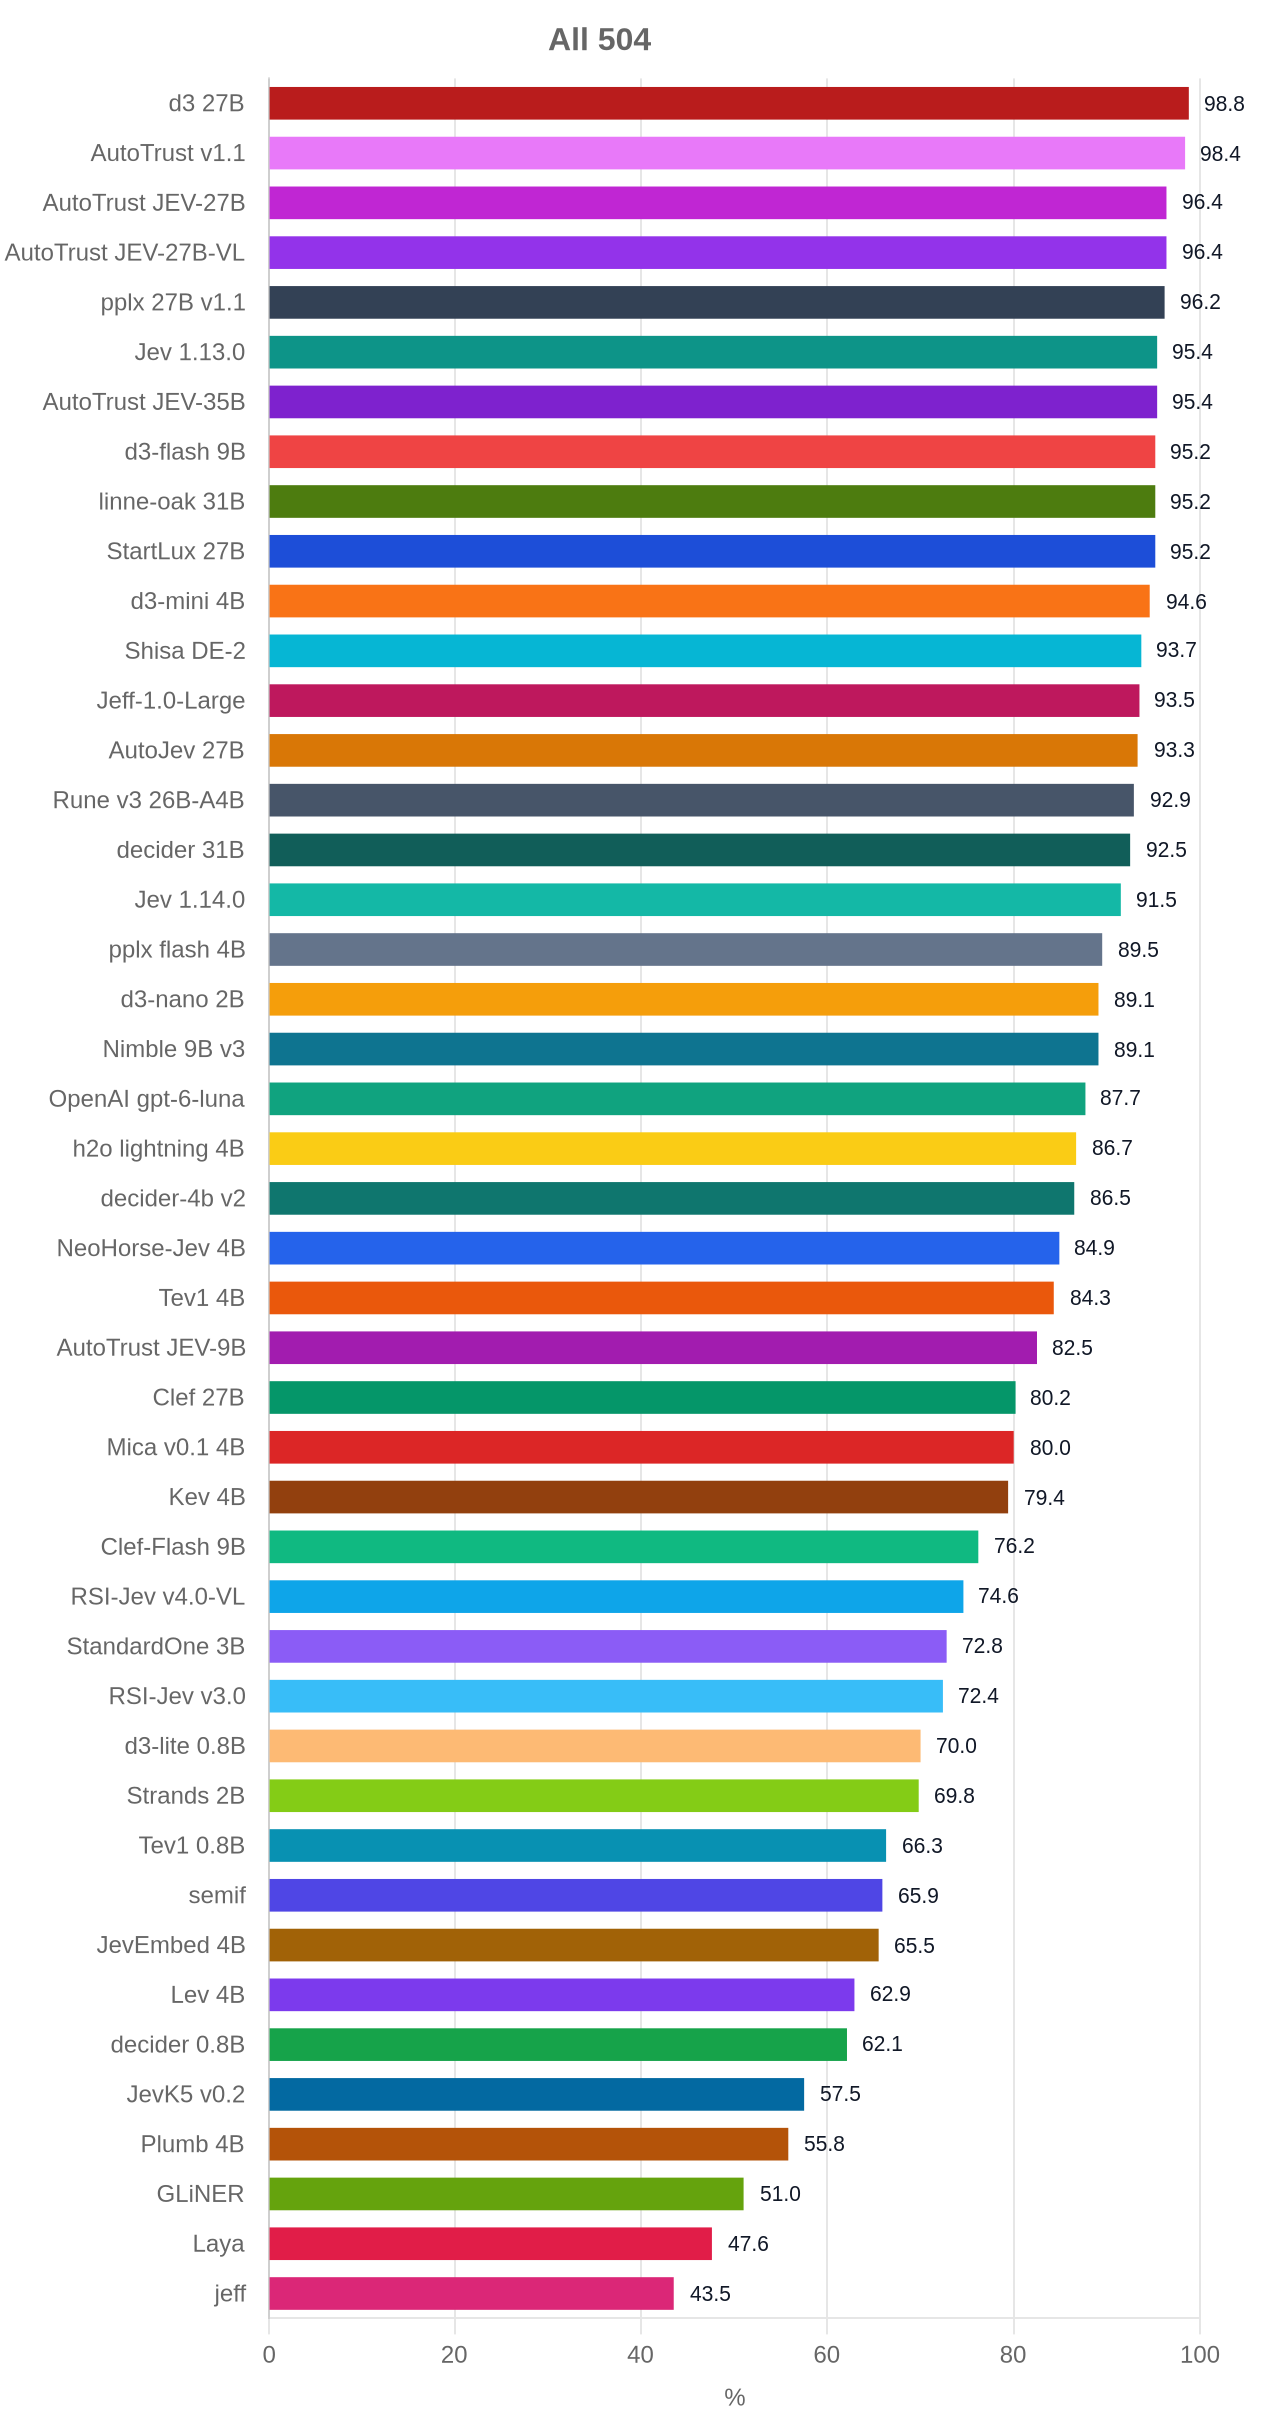
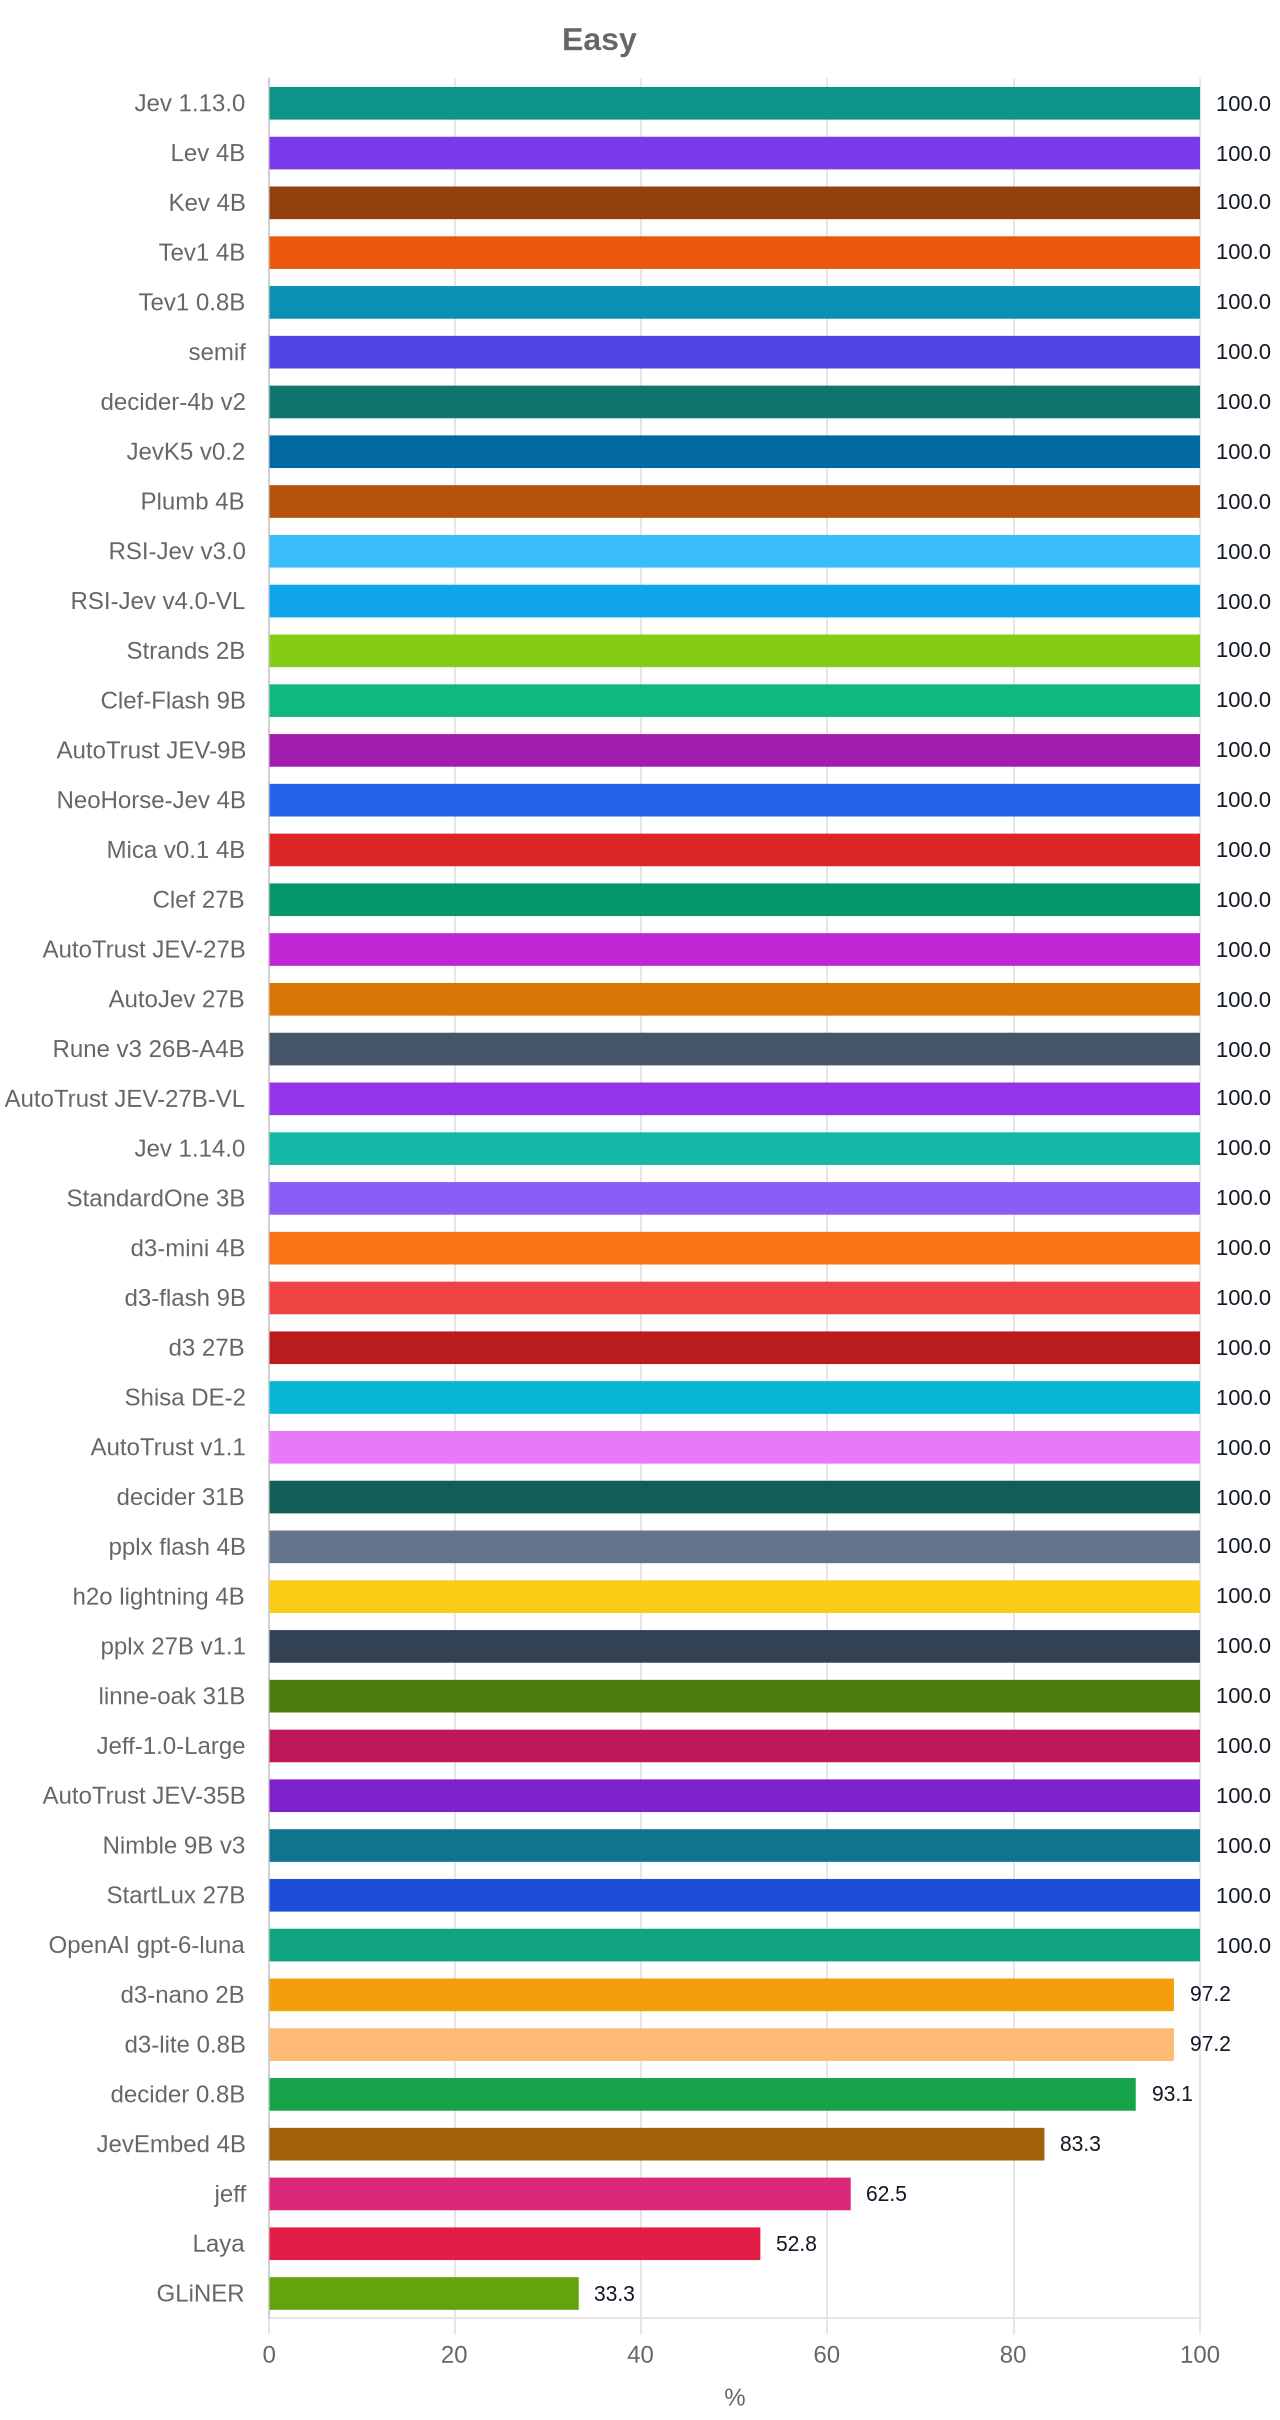
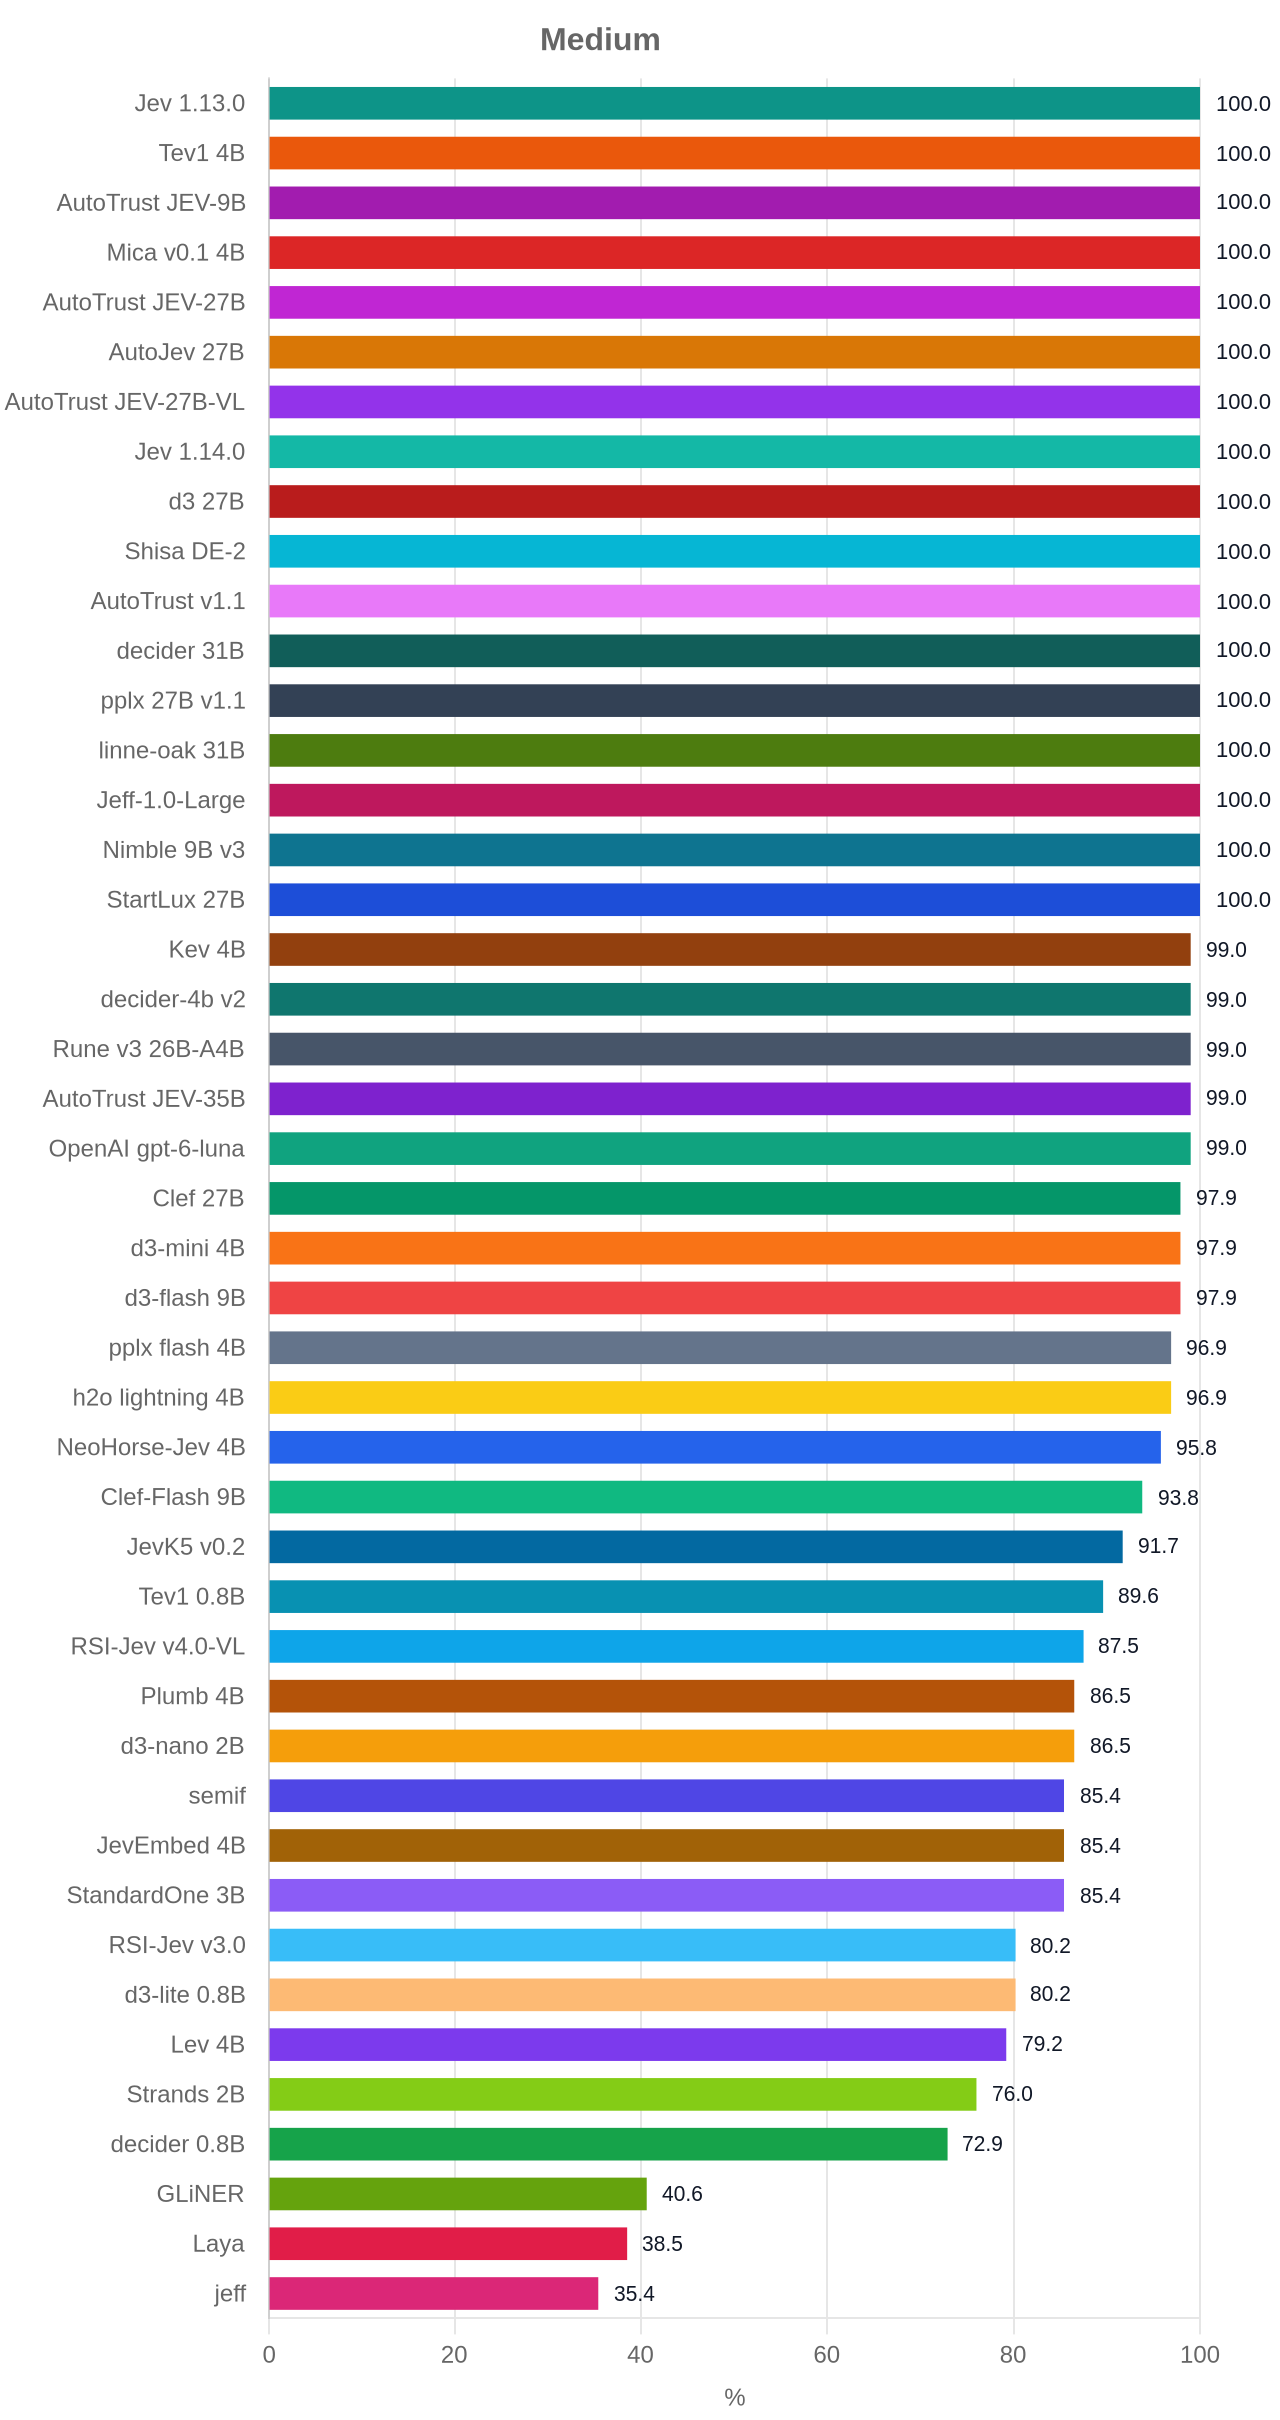
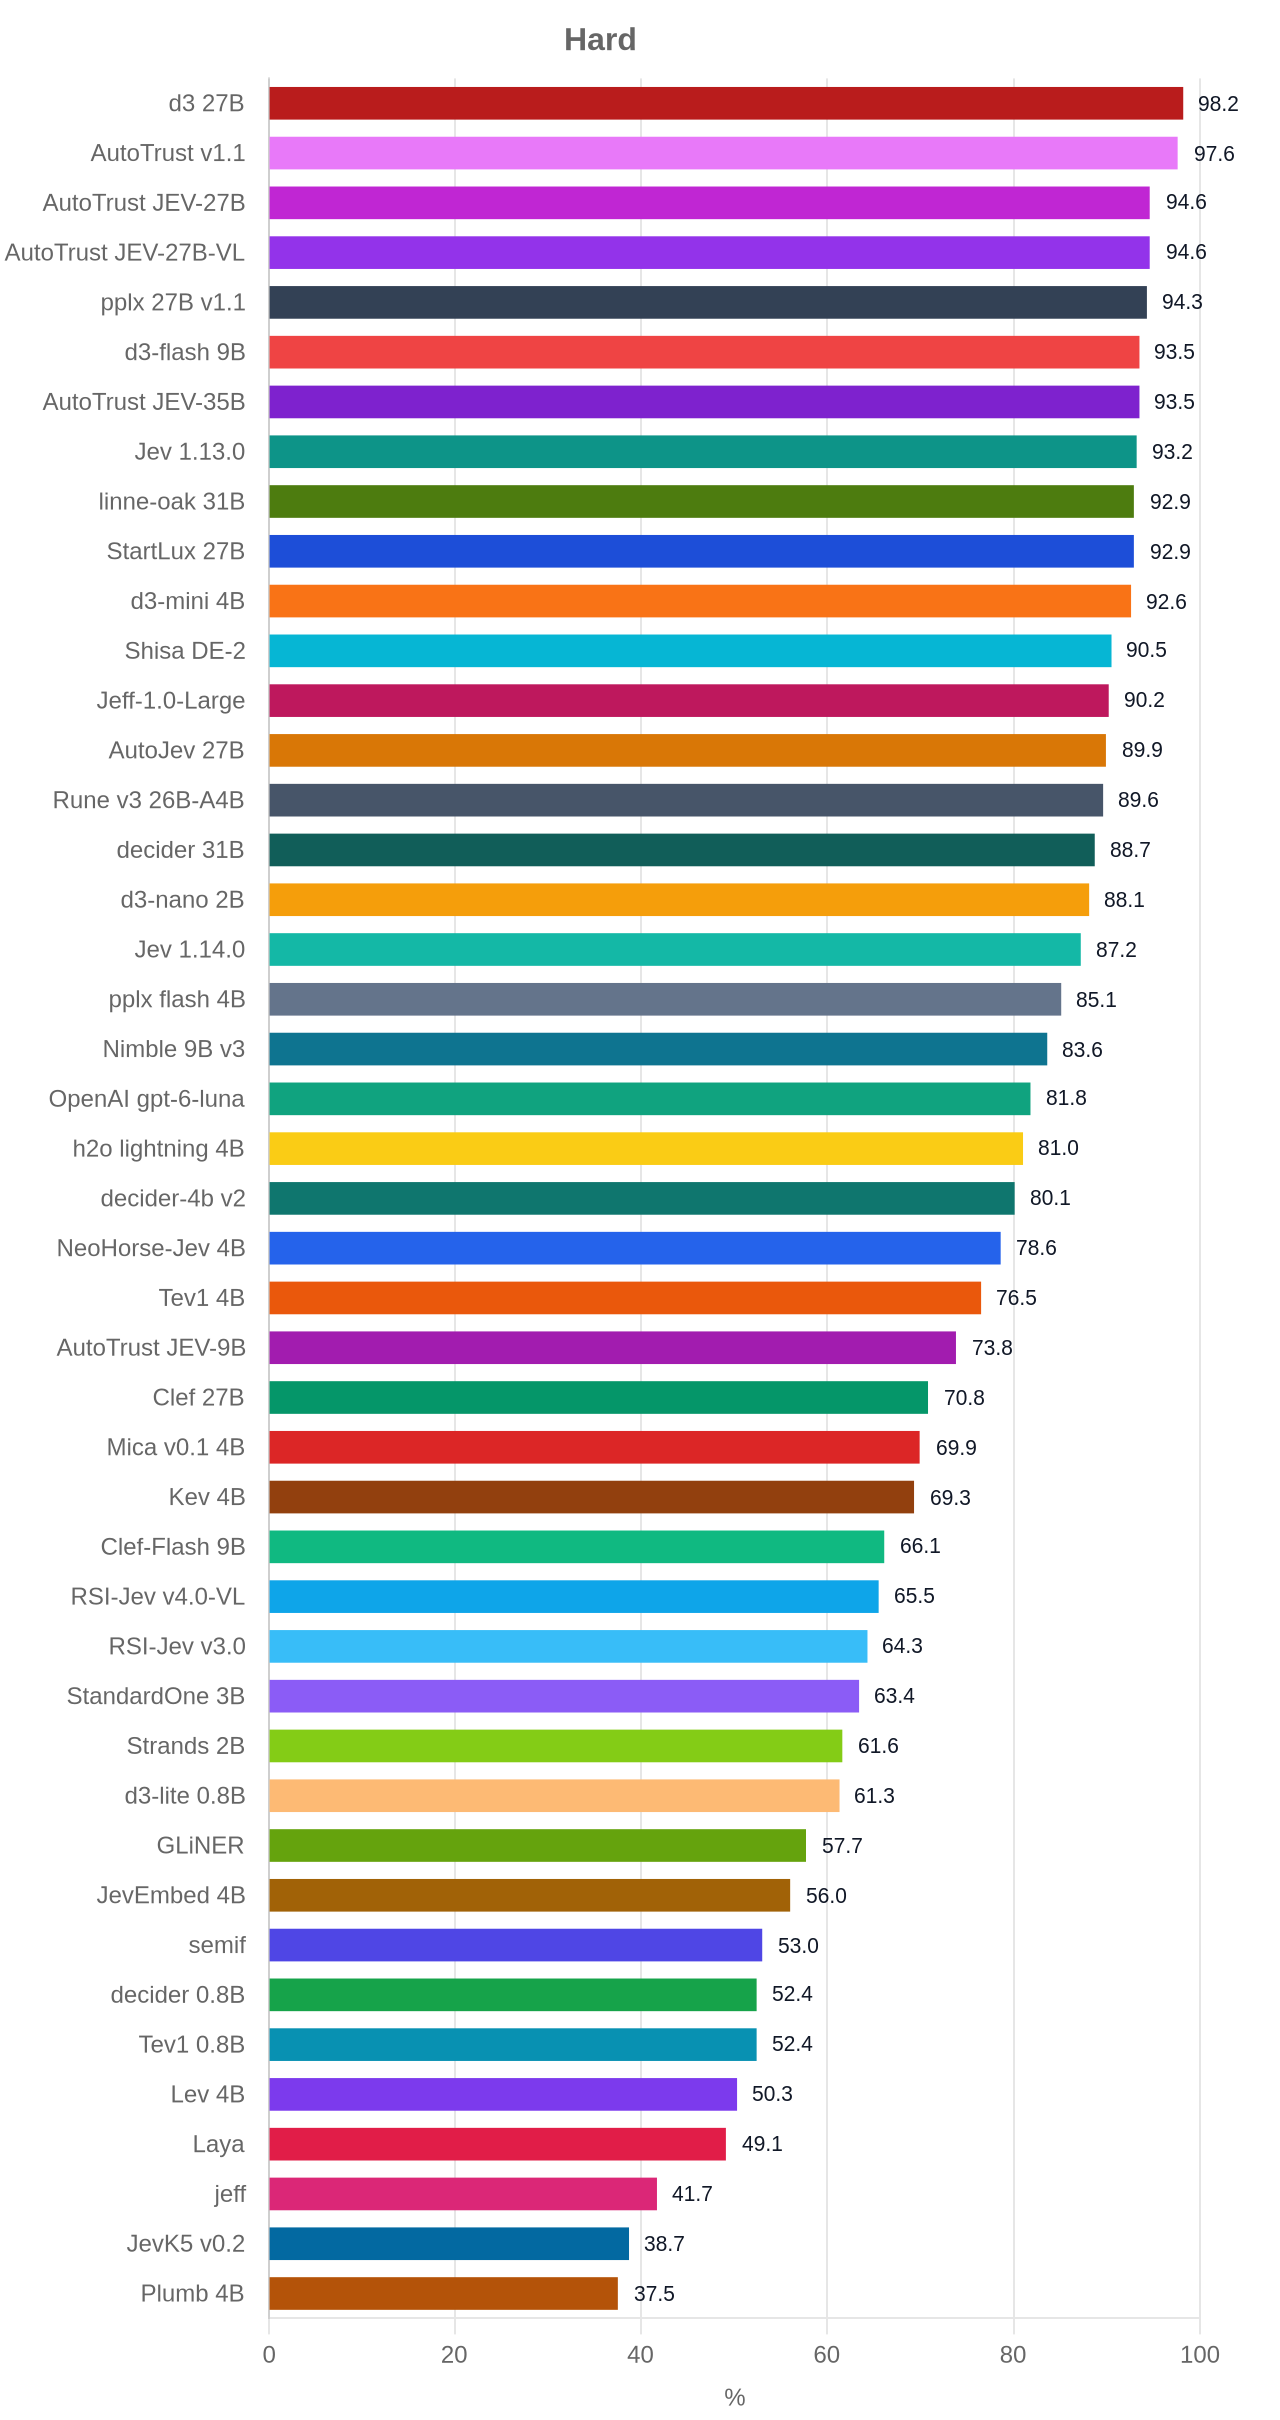
| Model | Easy /72 | Medium /96 | Hard /336 | All /504 | Hard priority reversals /29 |
|---|---|---|---|---|---|
| d3 27B | 72 | 96 | 330 | 498 | 29 |
| AutoTrust JEV-27B v1.1 | 72 | 96 | 328 | 496 | 29 |
| AutoTrust JEV-27B | 72 | 96 | 318 | 486 | 28 |
| AutoTrust JEV-27B-VL | 72 | 96 | 318 | 486 | 28 |
| pplx-decider v1.1 27B | 72 | 96 | 317 | 485 | 28 |
Jev jev-1.13.0 |
72 | 96 | 313 | 481 | 28 |
| AutoTrust JEV-35B | 72 | 95 | 314 | 481 | 27 |
| d3-flash 9B | 72 | 94 | 314 | 480 | 28 |
| linne-oak 1.0 31B | 72 | 96 | 312 | 480 | 28 |
| StartLux v1.1 27B Instant | 72 | 96 | 312 | 480 | 29 |
| d3-mini 4B | 72 | 94 | 311 | 477 | 28 |
| Shisa DE-2 26B-A4B | 72 | 96 | 304 | 472 | 26 |
| Jeff-1.0-Large 31B | 72 | 96 | 303 | 471 | 29 |
| AutoJev-27B | 72 | 96 | 302 | 470 | 29 |
| Rune v3 26B-A4B | 72 | 95 | 301 | 468 | 24 |
| decider-31b | 72 | 96 | 298 | 466 | 24 |
Jev jev-1.14.0 |
72 | 96 | 293 | 461 | 24 |
| pplx-decider-flash v1.2 4B | 72 | 93 | 286 | 451 | 21 |
| d3-nano 2B | 70 | 83 | 296 | 449 | 25 |
| Bespoke Nimble 9B v3 | 72 | 96 | 281 | 449 | 29 |
OpenAI gpt-6-luna (hosted) |
72 | 95 | 275 | 442 | 23 |
| h2o-lightning-4b | 72 | 93 | 272 | 437 | 14 |
| decider-4b v2 | 72 | 95 | 269 | 436 | 14 |
| NeoHorse-Jev-4B | 72 | 92 | 264 | 428 | 5 |
| Tev1-4B | 72 | 96 | 257 | 425 | 15 |
| AutoTrust JEV-9B | 72 | 96 | 248 | 416 | 4 |
| Clef 27B | 72 | 94 | 238 | 404 | 4 |
| Mica v0.1 4B | 72 | 96 | 235 | 403 | 7 |
| Kev 4B | 72 | 95 | 233 | 400 | 9 |
| Clef-Flash 9B | 72 | 90 | 222 | 384 | 3 |
| RSI-Jev v4.0-VL 2B | 72 | 84 | 220 | 376 | 0 |
| StandardOne-3B-SH v2 | 72 | 82 | 213 | 367 | 1 |
| RSI-Jev v3.0 2B | 72 | 77 | 216 | 365 | 2 |
| d3-lite 0.8B | 70 | 77 | 206 | 353 | 6 |
| Strands Decider 2B | 72 | 73 | 207 | 352 | 1 |
| Tev1-0.8B | 72 | 86 | 176 | 334 | 0 |
| SemIf, Qwen3.5-4B | 72 | 82 | 178 | 332 | 2 |
| JevEmbed Qwen3-Embedding-4B | 60 | 82 | 188 | 330 | 1 |
| Lev 4B | 72 | 76 | 169 | 317 | 1 |
| decider-0.8b | 67 | 70 | 176 | 313 | 1 |
| JevK5 4B v0.2 | 72 | 88 | 130 | 290 | 2 |
| Plumb-4B | 72 | 83 | 126 | 281 | 1 |
| GLiNER2.5-Decide | 24 | 39 | 194 | 257 | 0 |
| Laya multilingual | 38 | 37 | 165 | 240 | 0 |
| jeff (GLiFormer large) | 45 | 34 | 140 | 219 | 0 |
Easy and medium are regression and "insufficient information" controls.
Hard carries the difference: a priority reversal counts only if both ends
of a same-case pair are right in both orders. Always answering B already
scores 194/336 on hard. All 22,176 first attempts (44 models × 504) are
valid, with no errors. Adapters differ, so these are task-level scores, not
weight comparisons. Jev jev-1.14.0 scores 20 fewer than jev-1.13.0, all
on hard (293 vs 313; a repeat gave 462 in all). From 0.0.7 jev-lite pins
jev-1.14.0 anyway (owner decision): pin jev-1.13.0 yourself while it is
served if hard text decisions matter most. Self-host pick:
d3-nano (2.2B, Apache-2.0, 449/504),
which LocalTypeSafe runs (above). This bank ships in the jev-lite
0.0.2–0.0.4 sdists, so models released after 2026-10-03 may have seen it.
Earlier banks (semantic-decisions@v0.0.1, the controlled slices, r2) are
retired. v0.0.1 survives only at package tag v0.0.1, and none of their
scores is pooled with v0.0.2. The project redistributes no measured model's
weights, except the Apache-2.0 d3-nano export that LocalTypeSafe
downloads, which carries its LICENSE and NOTICE.
Latency by question count
One request, one state, N questions (1 → 255), on one machine (NVIDIA GB10,
local models on its GPU, LocalTypeSafe on its CPU; hosted rows over the
network). Speed depends on the hardware, so read the growth, not the
milliseconds. The state is 24 joined bank policies (about 2,000 tokens);
p50 of three uncached requests (each opens with a fresh request number, so
no server reuses an earlier prefix). A backend that scores one question per call
gets them one after another, as its client would. "cut" means a smaller N
already passed 45 s or ran out of memory (local models get at most 70% of the
GPU memory). Questions are numbered, so no two in a request are the same.
The charts show one model for each way of reading the state; the table lists
every model.
State read is inferred from the growth: a model that reads the state once per question takes about N times as long for N questions. Hosted rows also ran 384 and 512 questions (Jev 1.14: 458 and 528 ms); Jev answered 768 questions (about 37k tokens) with HTTP 400.
| Model | State read | 1 | 16 | 64 | 255 | 255 vs 1 | Largest N |
|---|---|---|---|---|---|---|---|
Jev jev-1.13.0 |
hosted | 185 | 190 | 220 | 327 | 1.8x | 512 |
Jev jev-1.14.0 |
hosted | 174 | 179 | 214 | 335 | 1.9x | 512 |
OpenAI gpt-6-luna (hosted) |
hosted | 222 | 306 | 511 | 770 | 3.5x | 384 |
LocalTypeSafe 0.0.7 (CPU) |
once | 4,627 | 7,484 | 16,184 | 52,292 | 11.3x | 255 |
| d3 27B, state once | once | 2,360 | 3,489 | 8,097 | 26,822 | 11.4x | 255 |
| d3-flash 9B, state once | once | 744 | 1,132 | 2,712 | 8,616 | 11.6x | 255 |
| StandardOne-3B-SH v2 | once | 425 | 596 | 1,288 | 5,057 | 11.9x | 255 |
| d3-mini 4B, state once | once | 506 | 788 | 1,918 | 6,221 | 12.3x | 255 |
| d3-nano 2B, state once | once | 216 | 327 | 836 | 2,720 | 12.6x | 255 |
| RSI-Jev v3.0 2B | once | 187 | 297 | 653 | cut | — | 64 |
| RSI-Jev v4.0-VL 2B | once | 187 | 296 | 651 | cut | — | 64 |
| Clef 27B | once | 2,154 | 3,606 | 8,824 | cut | — | 128 |
| d3-lite 0.8B, state once | once | 140 | 227 | 602 | 2,009 | 14.4x | 255 |
| decider-31b | once | 1,346 | 3,068 | 6,095 | 19,722 | 14.6x | 255 |
| Clef-Flash 9B | once | 710 | 1,224 | 2,898 | cut | — | 128 |
| Strands Decider 2B | once | 357 | 596 | 1,792 | 7,184 | 20.1x | 255 |
| Lev 4B, prefix fork (not its default) | once | 814 | 1,822 | 5,212 | cut | — | 128 |
| pplx-decider-flash v1.2 4B | once | 464 | 699 | 1,481 | 12,304 | 26.5x | 255 |
| Kev 4B | once, cut to 384 tokens | 115 | 293 | 976 | 4,316 | 37.5x | 255 |
| Bespoke Nimble 9B v3 | once | 1,078 | 2,102 | 6,468 | 47,206 | 43.8x | 255 |
| JevEmbed Qwen3-Embedding-4B | once | 850 | 4,306 | 15,660 | 56,498 | 66.5x | 255 |
| AutoTrust JEV-35B | per question | 737 | 6,300 | 24,226 | cut | — | 128 |
| h2o-lightning-4b | per question | 274 | 3,921 | 15,466 | 60,958 | 222.7x | 255 |
| AutoTrust JEV-27B v1.1 | per question | 1,519 | 22,456 | 88,019 | cut | — | 64 |
| linne-oak 1.0 31B | per question | 3,285 | cut | cut | cut | — | 8 |
| d3 27B | per question | 2,140 | 33,333 | cut | cut | — | 32 |
| d3-flash 9B | per question | 664 | 10,503 | 41,828 | cut | — | 128 |
| Tev1-0.8B | per question | 163 | 2,596 | 10,370 | 41,297 | 252.9x | 255 |
LocalTypeSafe 0.0.5–0.0.6 (CPU) |
per question | 4,573 | 72,932 | cut | cut | — | 16 |
| Jeff-1.0-Large 31B | per question | 3,317 | 53,070 | cut | cut | — | 16 |
| decider-4b v2 | per question | 468 | 7,358 | 29,721 | cut | — | 128 |
| SemIf, Qwen3.5-4B | per question | 454 | 7,254 | 29,053 | cut | — | 128 |
| pplx-decider v1.1 27B | per question | 2,139 | 34,239 | cut | cut | — | 32 |
| Mica v0.1 4B | per question | 463 | 7,408 | 29,669 | cut | — | 128 |
| AutoTrust JEV-27B | per question | 2,077 | 33,371 | cut | cut | — | 32 |
| Rune v3 26B-A4B | per question | 1,169 | 18,788 | 75,194 | cut | — | 64 |
| AutoTrust JEV-9B | per question | 665 | 10,708 | 42,942 | cut | — | 128 |
| AutoTrust JEV-27B-VL | per question | 2,042 | 32,852 | cut | cut | — | 32 |
| JevK5 4B v0.2 | per question | 488 | 7,840 | 31,604 | cut | — | 128 |
| Shisa DE-2 26B-A4B | per question | 2,405 | 38,762 | cut | cut | — | 32 |
| jeff (GLiFormer large) | per question | 2,405 | 38,556 | cut | cut | — | 32 |
| AutoJev-27B | per question | 2,071 | 33,331 | cut | cut | — | 32 |
| GLiNER2.5-Decide | per question | 9,867 | cut | cut | cut | — | 8 |
| Plumb-4B | per question | 483 | 7,776 | 31,105 | cut | — | 128 |
| d3-mini 4B | per question | 458 | 7,398 | 29,616 | cut | — | 128 |
| Tev1-4B | per question | 620 | 9,956 | 40,007 | cut | — | 128 |
| NeoHorse-Jev-4B | per question | 432 | 7,169 | cut | cut | — | 16 |
| Laya multilingual | per question | 20 | 346 | 1,350 | 5,287 | 271.1x | 255 |
| d3-nano 2B | per question | 194 | 3,334 | 13,379 | 53,317 | 274.1x | 255 |
| StartLux v1.1 27B Instant | per question | 1,489 | 28,838 | cut | cut | — | 32 |
| d3-lite 0.8B | per question | 124 | 2,287 | 9,133 | 36,344 | 293.6x | 255 |
| decider-0.8b | per question | 126 | 2,375 | 9,345 | 37,224 | 296.4x | 255 |
| Lev 4B | per question | 1,505 | 24,501 | cut | cut | — | 32 |
"State once" rows serve the d3 checkpoints with the state read once and the
questions batched on it; in d3's noncausal layers the state then no longer
sees the questions. The score on semantic-decisions@v0.0.2 (/504) changes
only for some sizes: nano 449 → 449, lite 353 → 342, mini 477 → 459, 27B
498 → 496 (flash: 67 → 67 on a 72-slot sample). jev-lite 0.0.7 ships only
the nano one, as LocalTypeSafe.
License
Apache-2.0
1 maintainer

Metadata
1 maintainer
Release files for jev-lite 0.0.7
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| jev_lite-0.0.7.tar.gz | 360.7 kB | With provenance | Details for jev_lite-0.0.7.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| jev_lite-0.0.7-py3-none-any.whl | Python 3 | none | any | Details for jev_lite-0.0.7-py3-none-any.whl |
Total release size: 753.4 kB
Release files / jev_lite-0.0.7.tar.gz
| Download URL | jev_lite-0.0.7.tar.gz |
|---|---|
| Size | 360.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
b9a9c7336bbcf5877914904aac15cf66c439112597229d0b4bb09ff7507f5d5e
|
|
BLAKE2b-256 checksum How to use checksums |
df49663b5c02aa6ffe11c378323fa874303f074bc03aa2979053cc6504a2fe30
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 28, 2026.
Transparency logRelease files / jev_lite-0.0.7-py3-none-any.whl
| Download URL | jev_lite-0.0.7-py3-none-any.whl |
|---|---|
| Size | 392.7 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0a81e9b1be82d1965e378ea0dc22e419a57c15926f914bd7be5a0877644c4375
|
|
BLAKE2b-256 checksum How to use checksums |
59417f065320b4a56ad7769c2744c5077d78c0a543b8bf50e095571723b7ef2e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 28, 2026.
Transparency logSecurity for jev-lite 0.0.7
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for jev_lite-0.0.7.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 28, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














