

Memory SDK — Python client for Kagura Memory Cloud


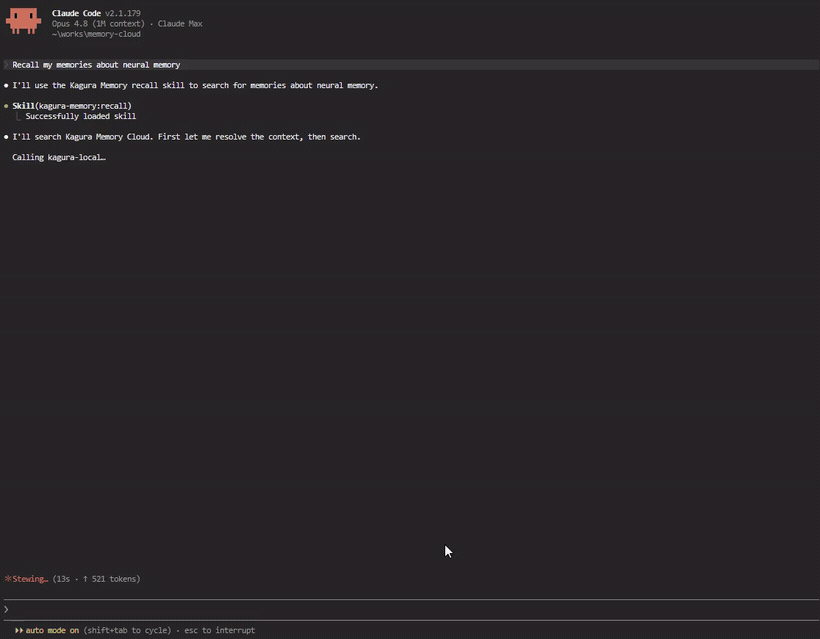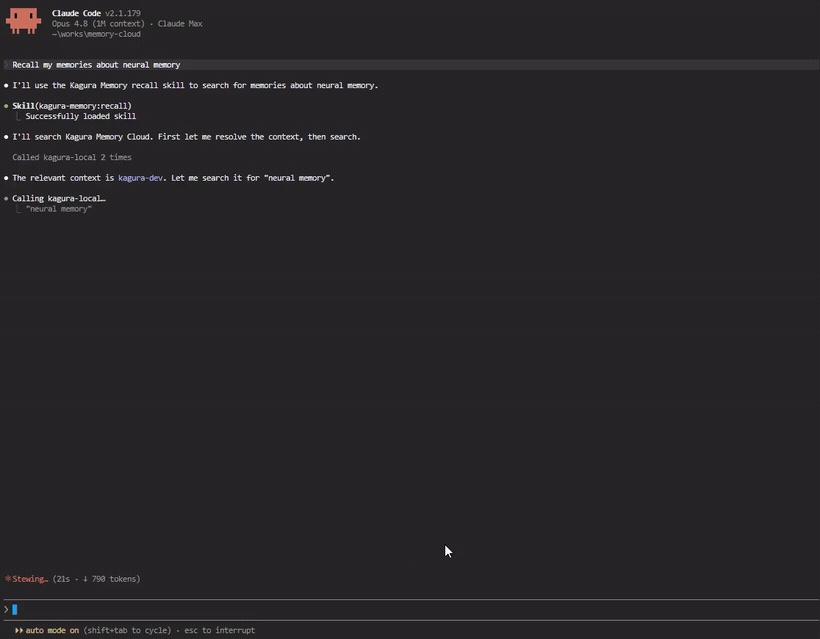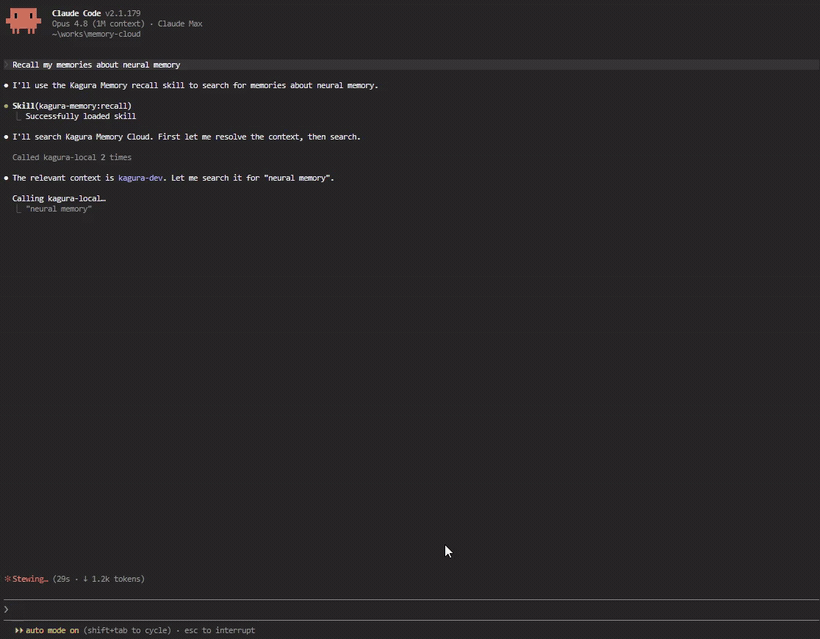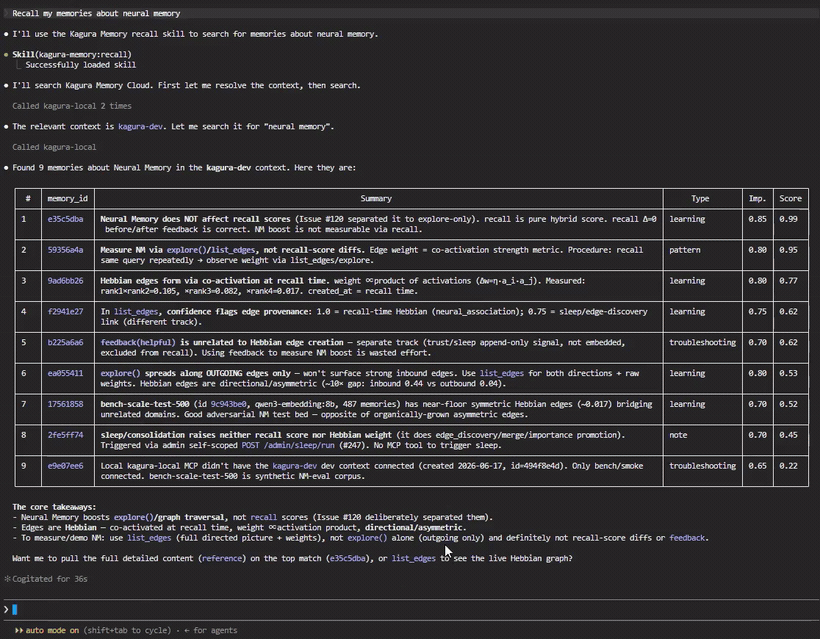
Recall past memories straight from Claude Code — Kagura Memory over MCP.
What is this?
This SDK connects your Python code to Kagura Memory Cloud, giving AI assistants the ability to remember, search, and learn from past interactions — and to ingest documents (PDFs, URLs) directly into a searchable memory graph. It provides six clients (plus a document ingestor) for different use cases:
| Client | Protocol | Use Case |
|---|---|---|
KaguraClient |
MCP (JSON-RPC) | Direct memory ops — remember, recall, explore, reference, forget |
ResourceClient |
REST API | External data ingestion — push data from Slack, CI/CD, CRM into Kagura |
FilesClient |
REST + presigned PUT | File uploads with sha256 integrity binding (R2); optional per-file context binding for ACL |
SecretClient |
REST + age crypto | Zero-knowledge secrets — age recipient encryption, local decryption (the server only ever stores armored ciphertext) |
WorkspaceClient |
REST API | Workspace member / invitation management + owner-provisioned member keys (owner API key only) |
AgentsClient |
REST API | Agent bootstrap — one-call session-start rehydration for API-key-only callers (server v0.49.0+) |
FileIngestor |
CLI + SDK | Document ingestion — PDF/Office/HTML/EPUB, audio & YouTube transcripts → memory graph + R2 archive |
60-second demo
Turn a PDF into a structured graph of memories — one overview memory plus per-section summaries, linked via declared_link edges. The original file is archived to your workspace's storage so you can always pull the bytes back.
pip install 'kagura-memory[ingest-pdf]'
kagura auth login
kagura ingest ./report.pdf

kagura recall "report findings" -k 5        # search across sections
kagura files download-url <file_id> -c <context-id>   # short-lived GET on the original
Ingestion extracts text — from PDFs, Office/HTML/EPUB documents, audio/video transcripts, and YouTube captions. Images embedded in a document are detected and counted (IngestResult.skipped_images) but not yet OCR'd: a vision provider (Gemini 2.5 Flash by default) is configured and validated, but the orchestrator does not currently invoke Provider.describe_image() — image-to-text memories are a planned follow-up. Pass --no-vision to skip provider configuration entirely, or --dry-run to see token / cost estimates without calling an LLM.
Installation
pip install kagura-memory                   # core SDK
pip install 'kagura-memory[ingest-pdf]'     # adds PDF ingestion support
pip install 'kagura-memory[ingest-all]'     # all document formats (see below)
# or
uv add kagura-memory
Supported document formats
kagura ingest (and FileIngestor) dispatch to a structural extractor based
on the file's MIME type / extension. Heavy parser dependencies are opt-in
extras — install only what you need, or ingest-all for everything:
| Format | Extensions | Extra | Parser |
|---|---|---|---|
| Plain text / Markdown | .txt, .md |
(none — base [ingest]) |
stdlib |
| HTML | .html, .htm |
[ingest-html] |
beautifulsoup4 |
.pdf |
[ingest-pdf] |
PyMuPDF | |
| Word | .docx |
[ingest-docx] |
python-docx |
| Excel | .xlsx |
[ingest-xlsx] |
openpyxl |
| PowerPoint | .pptx |
[ingest-pptx] |
python-pptx |
| EPUB | .epub |
[ingest-epub] |
PyMuPDF (reused) |
Each extractor is pure-parse — no network, no LLM. It maps the document
into structural sections (Markdown/HTML headings, Word heading styles, one
section per sheet/slide, PDF/EPUB outline) that the chunker and summarizer
then turn into memories. Office and EPUB files are ZIP containers, so each
extractor enforces decompression-bomb caps (max sheets/rows/slides/pages and
total decoded text). A missing extra surfaces as a clear
KaguraIngestError naming the package to install.
Quick Start
Configuration
Copy the example and fill in your credentials:
cp .kagura.json.example .kagura.json
# Edit .kagura.json — set api_key and mcp_url
Used by the CLI (kagura commands) and load_config() in Python code:
{
  "api_key": "kagura_your_api_key",
  "mcp_url": "http://localhost:8080/mcp/w/{workspace_id}",
  "context_id": "auto"
}
Or use environment variables: KAGURA_API_KEY, KAGURA_MCP_URL, KAGURA_CONTEXT_ID
Get your API key from the Kagura Memory Cloud Web UI: Integrations > API Keys
Looking for
KaguraAgent? The LLM-powered session-analysis actor was removed in v0.37.0 — its role moved to dedicated ecosystem packages: kagura-agent (memory-backed autonomous agent) with kagura-brain as its LLM head, while conversation→memory compilation is handled server-side (Memory Analysis) and by the connector workers. This SDK stays a pure substrate client, and base installs no longer pull thelitellmdependency tree (it now ships with the[ingest]extra).
Ollama for ingestion
kagura ingest reads OLLAMA_API_KEY and OLLAMA_API_BASE from the environment (litellm picks them up directly for the ollama_chat/ route), for both local Ollama and Ollama Cloud (ollama signin sets the key automatically):
export OLLAMA_API_KEY="..."          # Ollama Cloud only; local needs no key
export OLLAMA_API_BASE="https://ollama.com"
kagura ingest report.pdf --text-provider ollama
The ingest provider uses litellm's ollama_chat/ route (system messages preserved), so cloud and local share the same code path.
KaguraClient — Direct Memory Operations
For programmatic control without LLM:
from kagura_memory import KaguraClient

async with KaguraClient(api_key="kagura_...", mcp_url="https://...") as client:
    await client.remember(context_id="dev", summary="OAuth2 pattern", content="Use Authlib...")
    results = await client.recall(context_id="dev", query="OAuth2", k=5)
    await client.explore(context_id="dev", memory_id="uuid", depth=3)

    # Filtered recall — ALL listed tags, optional date range
    results = await client.recall(
        context_id="dev", query="budget",
        filters={"tags": ["予算", "2026"], "tags_match": "all",
                 "created_after": "2026-03-01T00:00:00Z"},
    )

    # Cross-context recall — search several contexts at once
    results = await client.recall(query="auth", context_ids=["ctx-1", "ctx-2"], k=10)

    # Trust-tier filter (provenance) — exclude untrusted / connector-ingested
    # memories from behaviour-influencing reads (OWASP LLM01/LLM03)
    safe = await client.recall(context_id="dev", query="policy",
                               filters={"trust_tier": "trusted"})
AI agent memory substrate
Primitives for autonomous agents — a deterministic load path, a retrieval-feedback signal, and a TTL-bounded run-state lane kept separate from knowledge:
async with KaguraClient(api_key="kagura_...", mcp_url="https://...") as client:
    # Deterministic delivery — pin on write, load the full pinned set every turn
    # (Goal / Guardrail / critical-policy memories, distinct from probabilistic recall)
    await client.remember(context_id="dev", summary="Guardrail: never delete prod",
                          content="...", delivery_mode="always")
    pinned = await client.load_pinned(context_id="dev")

    # Time Memories — deterministic "what's upcoming" query (no semantic search)
    upcoming = await client.recall_upcoming(context_id="dev", from_="now")

    # WHERE axis — deterministic "what's near here" query, nearest first
    # (SDK v0.38.0, server v0.53.0+). radius_m/k are keyword-only.
    # lat/lon must be JSON numbers; the server 422s string-typed coordinates.
    await client.remember(context_id="dev", summary="Coffee with Sato", content="...",
                          details={"location": {"lat": 35.68, "lon": 139.76, "label": "Tokyo HQ"}})
    nearby = await client.recall_nearby(context_id="dev", lat=35.68, lon=139.76, radius_m=500)
    # update_memory(details=...) REPLACES details wholesale — no deep-merge. Read the
    # current value with reference() and re-send location, or this drops off the map.

    # Supersede — store a newer version WITHOUT destroying history (server v0.45.0+).
    # The old memory is shadowed, not deleted: it leaves default recall but stays
    # reachable, and deleting the edge restores it. Prefer this over forget() +
    # remember(), which throws away the history the supersede edge exists to keep.
    await client.remember(context_id="dev", summary="Deploy target: ap-northeast-1",
                          content="...", supersedes="old-memory-uuid")
    # Read the history back. NOTE: a top-level argument, NOT a filters key.
    history = await client.recall(context_id="dev", query="deploy target",
                                  include_superseded=True)  # results carry superseded_by

    # Retrieval feedback — teach the substrate which recall results were useful
    await client.feedback(context_id="dev", memory_id="uuid", helpful=True, query="OAuth2")

    # Agent session-state lane — TTL-bounded, structurally excluded from recall()
    await client.set_state(context_id="dev", key="step", value={"n": 3}, ttl_seconds=3600)
    state = await client.get_state(context_id="dev", key="step")  # omit key → all live entries
Agent bootstrap — one-call session-start rehydration (v0.37.0, server v0.49.0+)
get_agent_bootstrap composes the primitives above (context guide + pinned +
trusted-only recall + upcoming time memories + agent state) into one envelope, so an
agent starts a session with a single round-trip. Components are fail-soft: a failing
component reports status="error" while the rest still return (top-level degraded
flag). Also available over REST (AgentsClient) for API-key-only callers such as
agent-bound member keys:
from kagura_memory import AgentsClient, KaguraClient

async with KaguraClient() as client:  # MCP surface
    # One-time provisioning (owner/admin): register the agent, bind its context
    agent = await client.register_agent("ci-agent", framework="claude-code")
    await client.bind_agent_context(agent.id, "ctx-uuid", is_default=True)

    bootstrap = await client.get_agent_bootstrap(
        "agent-uuid",                     # context_id omitted → default binding
        session_id="run-42",              # echoed in the correlation block
        query="current task",             # enables the trusted-only recall component
        include=["pinned", "recall", "state"],
    )
    pinned = bootstrap.components["pinned"]  # {"status": "ok", "memories": [...], ...}

async with AgentsClient.from_mcp_url() as agents:  # REST companion
    bootstrap = await agents.bootstrap("agent-uuid", include=["pinned"])
⚠️ Error handling changed in v0.29.0 (breaking). Every
KaguraClientMCP tool method now raises on a server domain error instead of returning an error dict: a missing context/memory raisesKaguraNotFoundError, any other domain error raisesKaguraError. Replaceresult["status"] == "error"checks withtry/except:from kagura_memory import KaguraNotFoundError, KaguraError try: results = await client.recall(context_id="dev", query="auth") except KaguraNotFoundError: ... # context or memory not found except KaguraError: ... # other server-side error
More operations — tag-vocabulary discovery (list_tags), merge_contexts, context lifecycle (create_context/update_context/delete_context), workspace get_usage, get_memory_stats, find_duplicates, get_embedding_status — are runnable in examples/client_advanced.py; the API Coverage table lists the full surface.
ResourceClient — External Data Ingestion
Push data from external systems into Kagura so AI can search it:
from kagura_memory import ResourceClient, ResourceEventRequest

async with ResourceClient.from_mcp_url(api_key="kagura_...", mcp_url="http://localhost:8080/mcp/w/...") as client:
    # One-call setup: create public context + set resource_id + create token
    token = await client.setup_resource(resource_id="products", summary="Product catalog")
    print(f"Save this token: {token.token}")  # Shown only once!

    event = ResourceEventRequest(
        op="upsert", doc_id="SKU-001", version=1,
        payload={"name": "Wireless Headphones", "price": 79.99},
    )
    await client.ingest_event("products", token.token, event)

    # Check ingestion stats
    stats = await client.get_resource_impact("products")
    print(f"Memories: {stats.memory_count}, Tokens: {stats.token_count}")
See examples/ for complete working examples.
FilesClient — File Uploads with Checksum Binding
Upload files to the workspace's object store via short-lived presigned PUT URLs. The SDK binds the body's sha256 into the PUT signature so the server (memory-cloud v0.15.1+, R2_CHECKSUM_BINDING_ENABLED=true) can reject tampered uploads with 400 BadDigest:
from pathlib import Path
from kagura_memory import FilesClient

async with FilesClient.from_mcp_url(api_key="kagura_...", mcp_url="https://memory.kagura-ai.com/mcp") as client:
    # Upload from a Path (read fully into memory; server caps file size at 100 MiB)
    f = await client.upload(context_id="ctx-uuid", source=Path("./report.pdf"))
    print(f"Uploaded {f.id}, sha256={f.sha256}, size={f.size_bytes}")

    # Upload from bytes — filename is required (server enforces non-empty)
    f2 = await client.upload(context_id="ctx-uuid", source=b"...", filename="payload.bin")

    # Optionally bind a file to an owning context for access control (server
    # v0.41.0+). binding_context_id is the wire `context_id` — distinct from the
    # `context_id` arg, which is the workspace. Omit it for a workspace-scoped
    # (NULL-context) file. FileObject.context_id reflects the binding (or None).
    f3 = await client.upload(
        context_id="ctx-uuid",
        source=Path("./plan.pdf"),
        binding_context_id="owning-ctx-uuid",
    )
    print(f3.context_id)  # -> "owning-ctx-uuid"

    # Short-lived presigned GET URL. download_url / delete require the owning
    # context_id (workspace) — server v0.41.0 scopes file-id lookups to it.
    url = await client.download_url(f.id, context_id="ctx-uuid")

    # List & delete
    page = await client.list(context_id="ctx-uuid", limit=50)
    await client.delete(f.id, context_id="ctx-uuid")
Re-uploading bytes whose sha256 already exists in the workspace returns the existing FileObject (idempotent dedup happy-path) — no exception.
A file bound via binding_context_id routes read/write/list/delete through that context's ACL (server v0.41.0+): you need write (EDITOR+) access to the context, and it must belong to the upload's workspace (else 403 / 422). A denied download surfaces as a 404 (existence-hiding), not a 403. Unbound uploads stay workspace-scoped and fully listable.
Runnable: examples/files_upload.py.
SecretClient — Zero-Knowledge Secrets
Client side of the secret store (memory-cloud v0.39.0+, requires the [secret] extra: pip install 'kagura-memory[secret]'). Secrets are encrypted to recipients' age/X25519 public keys and decrypted locally — memory-cloud only ever stores armored ciphertext, never plaintext. All crypto is delegated to the audited pyrage binding; the age private key is held in your OS keychain (keyring) and never transmitted.
from kagura_memory.secrets.client import SecretClient

async with SecretClient.from_mcp_url(api_key="kagura_...", mcp_url="https://memory.kagura-ai.com/mcp") as client:
    # Register your public key (lands in `pending` until an owner approves it).
    me = await client.register_pubkey("age1...", label="laptop")

    # Encrypt-and-store in one call. recipients_snapshot / grant_pubkey_ids are
    # derived 1:1 from the recipient set, so the server's grant-consistency
    # invariant holds by construction.
    actives = [p for p in await client.list_pubkeys() if p.status == "active"]
    await client.put_secret_for_recipients("db-prod", b"hunter2", actives)

    # Fetch ciphertext (decrypt locally with your own key — not shown here).
    sv = await client.fetch_secret("db-prod")
Most workflows use the CLI instead — see kagura secret below, which handles keychain custody and the get/put/grant/rotate flows with built-in misuse guards.
WorkspaceClient — Workspace Member Management
Owner-key operational tooling for workspace members and invitations (memory-cloud v0.42.0+). Every endpoint requires the workspace owner's static API key when called programmatically — OAuth tokens are rejected by the server with an actionable 403, and the assignable roles are member / admin / viewer (owner changes go through the ownership transfer flow):
from kagura_memory import WorkspaceClient

async with WorkspaceClient.from_mcp_url(api_key="kagura_...") as client:
    members = await client.list_members("workspace-uuid")
    for m in members:
        print(m.user_id, m.role, m.user_email)

    # Invite a new user by email. member/viewer invitations REQUIRE a
    # context grant (allowed_context_ids, min 1); expires_in_days accepts
    # only the server presets 7/30/90/365 (None = never expires).
    inv = await client.create_invitation(
        "workspace-uuid",
        "new@example.com",
        role="member",
        allowed_context_ids=["context-uuid"],
        expires_in_days=30,
    )
    print(inv.invitation_url)  # shown once — a join credential

    # Role changes / removal
    await client.update_member_role("workspace-uuid", "google_123", role="admin")
    await client.remove_member("workspace-uuid", "google_123")
Notes: add_member does not validate the user id server-side (a typo creates a dangling row — prefer create_invitation for onboarding); invitation ids are integers with no status field (derive pending from is_accepted/is_expired); listing invitations programmatically returns token/invitation_url as None (server-side token hygiene).
The same client also provisions member API keys (memory-cloud #1165): mint_member_key(ws, user_id, name, expires_days) (member/viewer targets only, never yourself — leaked-owner-key self-replication is blocked server-side; plaintext_key is returned exactly once), list_member_keys (metadata only), and revoke_member_key (soft revoke). CLI: kagura auth create-key|list-keys|revoke-key.
SDK ↔ memory-cloud Compatibility
| SDK | Min memory-cloud | Notes |
|---|---|---|
| 0.38.0+ | 0.17.1 (per-surface: see notes) | Client-surface parity — four server capabilities the SDK could not reach. recall_nearby() + details.location (the WHERE axis) need memory-cloud 0.53.0+ (#1331); remember(supersedes=…) and its read-back counterpart recall(include_superseded=True) need 0.45.0+ (#1208); list_tags(with_tags=…) faceted drill-down needs 0.17.2+ (#830); update_memory(details=…) works on any server that already accepted details on the MCP tool, and replaces details wholesale — the server does not deep-merge, so re-send location when revising or the memory drops off recall_nearby. CLI gains kagura remember --details/--location. All four are additive and omitted from the wire when unset, so existing calls are unchanged. MIN_SERVER_VERSION stays 0.17.1. |
| 0.37.0+ | 0.17.1 (0.49.0 for the agent control plane) | Agent control plane (RFC-0002 P0-1/2/3). KaguraClient.get_agent_bootstrap() (MCP) and AgentsClient.bootstrap() (REST, POST /api/v1/agents/{agent_id}/bootstrap) need memory-cloud 0.49.0+ (#1276); the same release covers the registry + binding wrappers (register_agent/get_agent/list_agents/update_agent/delete_agent on both surfaces; bindings as bind_agent_context/list_agent_bindings/update_agent_binding/unbind_agent_context on KaguraClient, mirrored as bind_context/list_bindings/update_binding/unbind_context on AgentsClient — owner/admin-gated server-side, #1274/#1275), so an SDK-only consumer can provision the agent + binding that bootstrap requires. Against an older server the MCP tools return "tool not found" and the REST routes 404. MIN_SERVER_VERSION stays 0.17.1. |
| 0.37.0+ | 0.17.1 | KaguraAgent removed (breaking, #233). The LLM-powered session-analysis actor, its models (Session/Message/ProcessResult/…), and kagura process are gone — the actor role lives in kagura-agent (with kagura-brain as its LLM head), and conversation→memory compilation is server-side Memory Analysis / connector workers. litellm moved from core dependencies to the [ingest] extra, so pure-client installs are much lighter; ingestion (including plain text) now requires pip install 'kagura-memory[ingest]'. |
| 0.36.0+ | 0.17.1 (0.42.0 for kagura workspace / kagura auth create-key) |
Workspace member management + owner-provisioned member keys (owner-key only). WorkspaceClient / kagura workspace member|invite and mint_member_key/list_member_keys/revoke_member_key / kagura auth create-key|list-keys|revoke-key need memory-cloud 0.42.0+ (owner-key programmatic access, #1164 / #1165). Requires the workspace owner's static API key — OAuth tokens are rejected on this surface, and a deployment can disable it via enable_owner_key_member_management=false. Key minting is privilege-downgrade only: member/viewer targets, never self, expires_days required. MIN_SERVER_VERSION stays 0.17.1. |
| 0.35.0+ | 0.17.1 (0.41.0 for file uploads/downloads) | FilesClient v0.41.0 compatibility (breaking). memory-cloud 0.41.0 requires workspace_id on the query of the file-id endpoints (confirm/download-url/delete) and presigns R2 PUT without the checksum header — so pre-0.35.0 SDKs get 403/422 on every upload/download/delete against it. This SDK sends workspace_id on those endpoints (harmlessly ignored by older servers) and only binds the checksum when the presign signed it. Breaking: FilesClient.download_url(file_id, *, context_id) and delete(file_id, *, context_id) now require context_id; kagura files download-url/delete require -c/--context-id (or a profile/.kagura.json workspace). MIN_SERVER_VERSION stays 0.17.1. |
| 0.34.0+ | 0.17.1 (0.41.0 for secret delete + file context binding) | Owner-only secret delete + file context binding. SecretClient.delete_secret / kagura secret delete (DELETE /api/v1/config/secrets/{name}) and FilesClient.upload(binding_context_id=…) / FileObject.context_id (context-scoped file ACL) need memory-cloud 0.41.0+. MIN_SERVER_VERSION stays 0.17.1 — only these surfaces require 0.41.0. |
| 0.33.0+ | 0.17.1 (0.39.0 for kagura secret) |
Zero-knowledge secret store. SecretClient / kagura secret need memory-cloud 0.39.0+ (the /api/v1/config/secrets endpoints). MIN_SERVER_VERSION is not bumped — the rest of the SDK still works on 0.17.1+; only the secret surface requires 0.39.0. Requires the [secret] extra. |
| 0.27.0 – 0.31.x | 0.17.1 | Agent memory substrate. load_pinned + delivery_mode pin-on-write, recall_upcoming, feedback, set_state/get_state, and the trust_tier recall filter each need a memory-cloud carrying the matching #885 agent-substrate APIs (≈ v0.23.0+); against an older server those specific tools return an MCP "tool not found". MIN_SERVER_VERSION stays 0.17.1 — the rest of the SDK still works on 0.17.1+. v0.29.0 also changed error handling (breaking): MCP tool methods now raise KaguraNotFoundError/KaguraError instead of returning {"status":"error"} dicts (see the KaguraClient error-handling note above). |
| 0.15.0 – 0.20.x | 0.15.1 | FilesClient + R2 checksum binding. list_tags() additionally needs 0.15.4 — MIN_SERVER_VERSION is intentionally not bumped, only that one method requires the newer server. |
| 0.14.x | 0.15.1 | FilesClient + R2 checksum binding (x-amz-checksum-sha256 on PUT) |
| 0.13.x | 0.13.0 | Pre-FilesClient |
MIN_SERVER_VERSION in src/kagura_memory/client.py is the SDK's tested floor, and it is advisory: the SDK does not pre-check the server version and block a call. check_server_version() only logs a warning, and kagura doctor is the one place a too-old server fails outright. Version mismatches therefore surface at call time, in two different ways: a tool the server doesn't have raises KaguraError ("tool not found"), while a newer parameter on a tool it does have is typically ignored server-side — silently. That silent case is why the per-surface floors above matter. When pointing the SDK at a backend with R2_CHECKSUM_BINDING_ENABLED=true, the SDK must be v0.14.0+; older versions don't send the signed checksum header and uploads fail with HTTP 403 SignatureDoesNotMatch.
CLI
Authentication (OAuth2 device flow)
Log in once with kagura auth login — the SDK stores credentials at
~/.kagura/credentials.json (mode 0600) and KaguraClient() plus all
kagura CLI commands pick them up automatically:
kagura auth login                                    # default: memory:read + memory:write
kagura auth login --read-only                        # read-only scope
kagura auth login --scope "memory:read profile:read" # custom scope set
kagura auth login --no-browser                       # SSH / headless
kagura auth login --profile work                     # named profile for a second workspace

kagura auth status                                   # show profile, server, expiry, scope
kagura auth list                                     # list all stored profiles (default marked *)
kagura auth list --json                              # machine-readable profile list
kagura auth refresh                                  # manual token rotation
kagura auth refresh --scope "memory:write"           # incremental consent (re-runs device flow)
kagura auth token                                    # raw access_token to stdout (CI use)
kagura auth logout                                   # revoke + delete profile
kagura auth logout --all --yes                       # remove every profile
Two integration paths:
| You want… | Use |
|---|---|
CLI / KaguraClient (terminal use, scripts) |
kagura auth login — refresh happens automatically |
Claude Code MCP (Claude Code reads .mcp.json) |
kagura setup claude --profile <name> — OAuth via the refresh-aware kagura-mcp proxy (recommended) |
| CI / service accounts | kagura setup claude with a long-lived API key from the web UI |
Claude Code's MCP client reads its config once at startup and never
refreshes tokens, so a short-lived OAuth access_token baked into
.mcp.json would 401 silently after it expires. kagura setup claude --profile <name> instead points .mcp.json at the kagura-mcp
stdio proxy, which owns ~/.kagura/credentials.json, forwards every
MCP request to the server, and injects an always-fresh bearer token —
so the same kagura auth login credentials power both the CLI and
Claude Code. Use the long-lived API-key path only for CI / service
accounts, where a static token is preferable.
Credential resolution order when KaguraClient() is called with no
arguments: KAGURA_API_KEY env (CI / service accounts always win) →
KAGURA_PROFILE env or explicit profile= arg → default_profile
from ~/.kagura/credentials.json → legacy .kagura.json.
Diagnostics (kagura doctor)
Run kagura doctor when a local setup is not behaving as expected:
kagura doctor                  # human-readable pass/warn/fail report
kagura doctor --profile work   # inspect a named OAuth profile
kagura doctor --json           # machine-readable output for CI/scripts
The report covers effective auth source, OAuth/static API-key health,
Claude Code .mcp.json mode, kagura-mcp PATH wiring, MCP URL HTTPS,
server reachability/version, optional ingestion extras, LiteLLM supply-chain
status, and local LLM provider key/model diagnostics. Provider diagnostics are
local-only: GEMINI_API_KEY, ANTHROPIC_API_KEY, OPENAI_API_KEY, and
OLLAMA_API_KEY are reported with redacted previews, and model/key mismatches
are warnings only. doctor exits non-zero only on fail checks; warnings do
not fail CI.
Other commands
# Direct memory operations
kagura remember -s "FastAPI DI" --content "Use Depends()..." -c dev
kagura remember -s "Coffee with Sato" --content "..." --location "35.68,139.76,Tokyo HQ"
kagura recall "dependency injection" -k 10
kagura explore -m "memory-uuid" --depth 3
kagura forget -m "memory-uuid"
kagura contexts

# Resource tokens
kagura resource tokens create -r products -d "Product sync"
kagura resource ingest -r products -k TOKEN --doc-id SKU-001 -V 1 -p '{"name":"Widget"}'
kagura resource ingest-batch -r products -k TOKEN -f events.json
kagura resource stats -r products
kagura resource schema -r products

# Sleep Maintenance — observability + rollback
kagura sleep history <context-id> --limit 5
kagura sleep report <context-id> <report-id>
kagura sleep rollback <context-id> <report-id> -y    # destructive: prompts unless --yes / -y is set

# File uploads (R2 checksum binding)
kagura files upload ./report.pdf -c <context-id>
kagura files upload ./plan.pdf -c <context-id> --binding-context-id <ctx>   # bind to an owning context for ACL (v0.41.0+)
kagura files list -c <context-id> --limit 50
kagura files download-url <file-id> -c <context-id>   # -c required (server v0.41.0)
kagura files delete <file-id> -c <context-id>         # -c required (server v0.41.0)

# Workspace member management — owner API key ONLY (server v0.42.0+; OAuth tokens are rejected)
kagura workspace member list [--json]
kagura workspace member add <user-id> --role member|admin|viewer   # user must already exist — prefer invite
kagura workspace member set-role <user-id> --role member|admin|viewer
kagura workspace member remove <user-id> --yes
kagura workspace invite create <email> --role member -c <context-id> --expires-days 30
kagura workspace invite list [--include-accepted]
kagura workspace invite revoke <invitation-id>

# Owner-provisioned member API keys — owner API key ONLY (server v0.42.0+)
kagura auth create-key --user <member-id> --name ci-bot --expires-days 90   # key printed ONCE; member/viewer targets only, never yourself
kagura auth list-keys --user <member-id>            # metadata only — plaintext is never re-shown
kagura auth revoke-key <key-id> --user <member-id>  # soft revoke (row kept for audit)

# Config
kagura config show
Zero-knowledge secrets (kagura secret)
Requires the [secret] extra (pip install 'kagura-memory[secret]') and memory-cloud 0.39.0+. Your age private key lives in the OS keychain; memory-cloud only ever stores armored ciphertext.
kagura secret keygen --label laptop          # generate keypair → keychain, register public key (pending)
kagura secret approve <pubkey-id>            # owner: approve a pending key (verify its fingerprint out-of-band)
kagura secret put db-prod < secret.txt       # value from stdin/--from-file — never from argv
kagura secret get db-prod | psql             # refuses to print to a TTY; pipe it, or use -o FILE (0600) / --reveal
kagura secret exec --as DATABASE_URL=db-prod -- ./server   # inject into a child env, no disk/scrollback
kagura secret grant db-prod --to <pubkey-id> # re-encrypt to the expanded recipient set
kagura secret revoke db-prod --to <pubkey-id># revoke a grant (then `rotate` — revoke ≠ invalidation)
kagura secret rotate db-prod                 # encrypt a NEW value to the remaining recipients
kagura secret list                           # secret metadata (never the values)
kagura secret delete db-prod                 # owner-only hard delete (cleanup, not invalidation — rotate first)
kagura secret audit-verify                   # verify the tamper-evident audit chain
deleteis cleanup, not a security control. It removes the stored ciphertext (all versions + grants) but does not un-share a value a recipient already fetched, nor rotate the live upstream credential. To contain a leak, rotate the upstream credential first, then delete. Owner-only; needs memory-cloud 0.41.0+.
Document ingestion (kagura ingest)
See the 60-second demo above for the happy path. The full option surface:
# Local file or URL → one overview + N sections + R2 archive
kagura ingest ./report.pdf
kagura ingest https://example.com/report.pdf --tags "Q1,research"

# Preview cost / sections without calling any LLM
kagura ingest ./report.pdf --dry-run

# Skip vision-provider configuration entirely (images are not OCR'd yet, so
# this just avoids validating a vision provider you don't need)
kagura ingest ./report.pdf --no-vision

# Storage: skip the R2 archive (no file_id stamped on the overview memory)
kagura ingest ./report.pdf --no-archive

# Machine-readable output for scripts
kagura ingest ./report.pdf --json
Exit codes: 0 when the overview memory is created (per-section errors are still 0, they show up in result.errors); 1 when the overview itself fails (corrupted PDF, network error, etc.); 0 for any --dry-run invocation.
For the SDK-level FileIngestor API, see examples/ingest_pdf.py.
Provider configuration (env vars, picked up automatically via litellm):
ANTHROPIC_API_KEY— text summarization (default modelclaude-sonnet-4-6via theclaudepreset)GEMINI_API_KEY— audio/video transcription (default modelgemini/gemini-2.5-flashvia thegeminipreset); also the default vision provider for image OCR, which is configured but not yet invoked (see above)- Override per invocation:
--text-provider {claude|gemini|ollama},--vision-provider {claude|gemini|ollama}
Claude Code Integration
Wire Kagura Memory into Claude Code as an MCP server. Recommended: OAuth via
the refresh-aware kagura-mcp proxy — log in once, then setup claude writes
the stdio .mcp.json form and tokens refresh automatically:
kagura auth login --profile default        # one-time OAuth device flow
kagura setup claude --profile default      # writes .mcp.json → kagura-mcp stdio proxy
This writes a .mcp.json that launches kagura-mcp as the MCP server (no secret
in the file), plus .claude/ hooks and /kagura-recall · /kagura-remember
skills. Check the active mode any time with kagura auth status (it reports
refresh-aware vs legacy static API-key token for the .mcp.json in the
current directory).
CI / service accounts — use a long-lived API key instead (static token, no refresh needed):
kagura setup claude --api-key kagura_xxx --mcp-url https://memory.kagura-ai.com/mcp
Or use the CLI directly:
kagura remember -s "FastAPIのDIパターン" --content "DIはDepends()を使う" -c dev
Claude Code plugin (CLI-as-skills)
This repo also ships a thin Claude Code plugin under
.claude-plugin/ + skills/ that wraps
the high-value CLI commands as skills (doctor, auth, setup, ingest,
resource, files, secret) — each shells out to the installed kagura CLI and returns
clear guidance when it is not installed/authenticated. The plugin is named
kagura-cli (distinct from the kagura-memory SDK package and the existing
kagura-memory MCP plugin). Registration in the kagura-plugins marketplace (so
it installs via /plugin install kagura-cli@kagura-plugins) is tracked as a
follow-up.
API Coverage
| Operation | SDK Client | Protocol | Auth |
|---|---|---|---|
| Memory (remember/recall/forget/explore/reference/update_memory) | KaguraClient |
MCP | API Key |
| Provenance / trust_tier recall filter | KaguraClient |
MCP | API Key |
| Deterministic delivery (load_pinned + delivery_mode pin-on-write) | KaguraClient |
MCP | API Key |
| Time Memory (recall_upcoming) | KaguraClient |
MCP | API Key |
WHERE axis (recall_nearby + details.location) |
KaguraClient |
MCP | API Key |
Tag vocabulary + faceted drill-down (list_tags, with_tags) |
KaguraClient |
MCP | API Key |
Supersede / memory history (remember supersedes=, recall include_superseded=) |
KaguraClient |
MCP | API Key |
| Retrieval feedback (feedback) | KaguraClient |
MCP | API Key |
| Agent session-state lane (set_state/get_state, TTL) | KaguraClient |
MCP | API Key |
| Agent bootstrap (get_agent_bootstrap — one-call session-start rehydration) | KaguraClient / AgentsClient |
MCP + REST | API Key |
| Agent registry + context bindings (register/list/update/delete, bind/unbind — owner/admin) | KaguraClient / AgentsClient |
MCP + REST | API Key |
| Context (create/update/list/delete/get_context_info) | KaguraClient |
MCP | API Key |
| Workspace (get_usage) | KaguraClient |
MCP | API Key |
| Search config (update_search_config) | KaguraClient |
MCP | API Key |
| Embedding status (get_embedding_status) | KaguraClient |
REST | API Key |
| Memory stats (get_memory_stats) | KaguraClient |
REST | API Key |
| Duplicate detection (find_duplicates) | KaguraClient |
REST | API Key |
| Sleep Maintenance (history / report / rollback) | KaguraClient |
MCP | API Key |
| Resource Token (create/list/update/revoke) | ResourceClient |
REST API | API Key |
| Resource Event ingestion | ResourceClient |
REST API | Resource Token |
| Resource Impact (stats) | ResourceClient |
REST API | API Key |
| Resource Schema | ResourceClient |
REST API | API Key |
| File upload (optional context binding) / download-url / delete / list | FilesClient |
REST + presigned PUT | API Key |
| Secret pubkey registry (register/list/me/approve/revoke) | SecretClient |
REST API | API Key / OAuth |
| Secret put / fetch / list / revoke-grant / delete / audit-verify | SecretClient |
REST API (age, local decrypt) | API Key / OAuth |
| Account erasure (GDPR Art.17 / APPI) | — | Web UI only | Session |
Context deletion is a soft delete available via KaguraClient.delete_context() and kagura context delete (the CLI prompts for confirmation). Account erasure (GDPR Art.17 / APPI) is intentionally Web UI only — it is irreversible and requires session authentication and confirmation. kagura sleep rollback runs over the MCP API Key but is itself destructive (reverses edge creation, merges, importance updates, promotions, and archives) and the CLI requires --yes to skip the interactive confirmation. The server commits per-action without a Saga, so a 5xx response after partial success means SOME actions may have been reversed before the error surfaced — re-run kagura sleep report to inspect the post-failure state.
Development
git clone https://github.com/kagura-ai/kagura-memory-python-sdk.git
cd kagura-memory-python-sdk
uv sync --dev
uv run ruff check src/ tests/   # Lint
uv run ruff format src/ tests/  # Format
uv run pyright src/              # Type check
uv run pytest tests/ -v          # Test
Development with Claude Code
This project is developed with Claude Code:
/quality                # Run lint, format, type check, tests
/simplify               # Review for reuse, quality, efficiency
/self-review            # Pre-PR self-review
/self-maint             # Audit .claude/ config against codebase
/test                   # Run the test suite
/release <level>        # Bump version, tag, push, create GitHub Release
/kagura-memory:guide    # SDK usage reference (kagura-memory plugin)
Typical flow: Issue → Branch → Implement → /quality → /simplify → /self-review → PR → Merge → /release
Links
- Kagura Memory Cloud — the server this SDK connects to
- Releases — changelogs
- Issues — bug reports & feature requests
License
MIT License — see LICENSE for details.
1 maintainer

Release files for kagura-memory 0.38.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| kagura_memory-0.38.0.tar.gz | 1.5 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| kagura_memory-0.38.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.7 MB
Release files / kagura_memory-0.38.0.tar.gz
| Download URL | kagura_memory-0.38.0.tar.gz |
|---|---|
| Size | 1.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e000519d9254379fe867280d33e0c089e3227f3a346d99dd24b80ecea327cd31
|
|
BLAKE2b-256 checksum How to use checksums |
4edec0ca718fd67252f0beea197c260d72050eb541af0a937ee247cae713dfd8
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 28, 2026.
Transparency logRelease files / kagura_memory-0.38.0-py3-none-any.whl
| Download URL | kagura_memory-0.38.0-py3-none-any.whl |
|---|---|
| Size | 263.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
fd3bb465de44d2b3012b6a07bb67be5b375f6ddb2705b7b1e2b3ced1c1394dbe
|
|
BLAKE2b-256 checksum How to use checksums |
7545721a92a742359ff2e1eb1bb437d4c100d8988121d6e1eb8f6c2c9279d7c9
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/6.1.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Jul 28, 2026.
Transparency log













