


Attention mechanism for processing sequence data that considers the context for each timestamp.

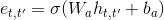


Install
pip install keras-self-attentionUsage
Basic
By default, the attention layer uses additive attention and considers the whole context while calculating the relevance. The following code creates an attention layer that follows the equations in the first section (attention_activation is the activation function of e_{t, t'}):
import keras
from keras_self_attention import Attention


model = keras.models.Sequential()
model.add(keras.layers.Embedding(input_dim=10000,
                                 output_dim=300,
                                 mask_zero=True))
model.add(keras.layers.Bidirectional(keras.layers.LSTM(units=128,
                                                       return_sequences=True)))
model.add(Attention(attention_activation='sigmoid'))
model.add(keras.layers.Dense(units=5))
model.compile(
    optimizer='adam',
    loss='categorical_crossentropy',
    metrics=['categorical_accuracy'],
)
model.summary()
Local Attention
The global context may be too broad for one piece of data. The parameter attention_width controls the width of the local context:
from keras_self_attention import Attention

Attention(
    attention_width=15,
    attention_activation='sigmoid',
    name='Attention',
)
Multiplicative Attention
You can use multiplicative attention by setting attention_type:

from keras_self_attention import Attention

Attention(
    attention_width=15,
    attention_type=Attention.ATTENTION_TYPE_MUL,
    attention_activation=None,
    kernel_regularizer=keras.regularizers.l2(1e-6),
    use_attention_bias=False,
    name='Attention',
)
Regularizer

To use the regularizer, the attention should be returned for calculating loss:
import keras
from keras_self_attention import Attention

inputs = keras.layers.Input(shape=(None,))
embd = keras.layers.Embedding(input_dim=32,
                              output_dim=16,
                              mask_zero=True)(inputs)
lstm = keras.layers.Bidirectional(keras.layers.LSTM(units=16,
                                                    return_sequences=True))(embd)
att, weights = Attention(return_attention=True,
                         attention_width=5,
                         attention_type=Attention.ATTENTION_TYPE_MUL,
                         kernel_regularizer=keras.regularizers.l2(1e-4),
                         bias_regularizer=keras.regularizers.l1(1e-4),
                         name='Attention')(lstm)
dense = keras.layers.Dense(units=5, name='Dense')(att)
model = keras.models.Model(inputs=inputs, outputs=[dense, weights])
model.compile(
    optimizer='adam',
    loss={'Dense': 'sparse_categorical_crossentropy', 'Attention': Attention.loss(1e-2)},
    metrics={'Dense': 'categorical_accuracy'},
)
model.summary(line_length=100)
model.fit(
    x=x,
    y=[
        numpy.zeros((batch_size, sentence_len, 1)),
        numpy.zeros((batch_size, sentence_len, sentence_len))
    ],
    epochs=10,
)
Load the Model
Make sure to add Attention to custom objects and add attention_regularizer as well if the regularizer has been used:
import keras

keras.models.load_model(model_path, custom_objects={
    'Attention': Attention,
    'attention_regularizer': Attention.loss(1e-2),
})1 maintainer

Metadata
1 maintainer
Release files for keras-self-attention 0.0.16
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| keras-self-attention-0.0.16.tar.gz | 5.2 kB | Details |
Release files / keras-self-attention-0.0.16.tar.gz
| Download URL | keras-self-attention-0.0.16.tar.gz |
|---|---|
| Size | 5.2 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e6c3a51fe29b88477454e233d1acc1cd6a22fc58bc3583fcfe14e3787590e584
|
|
BLAKE2b-256 checksum How to use checksums |
774403ddfa115da1db2875526c47cb1f48a4785fcc484248e16730fab06678ae
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/1.11.0 pkginfo/1.4.2 requests/2.18.4 setuptools/28.8.0 requests-toolbelt/0.8.0 tqdm/4.24.0 CPython/3.6.4
|














