
Video you can diff.
Motion graphics, video edits and voice-over written as JSON, checked by agents, rendered on the GPU.
Documentation · Source · Changelog · Launch video
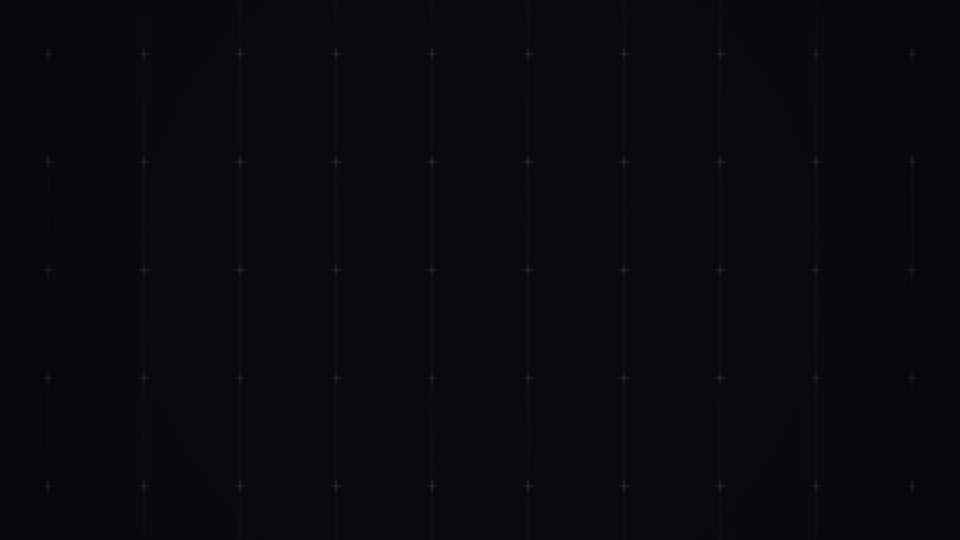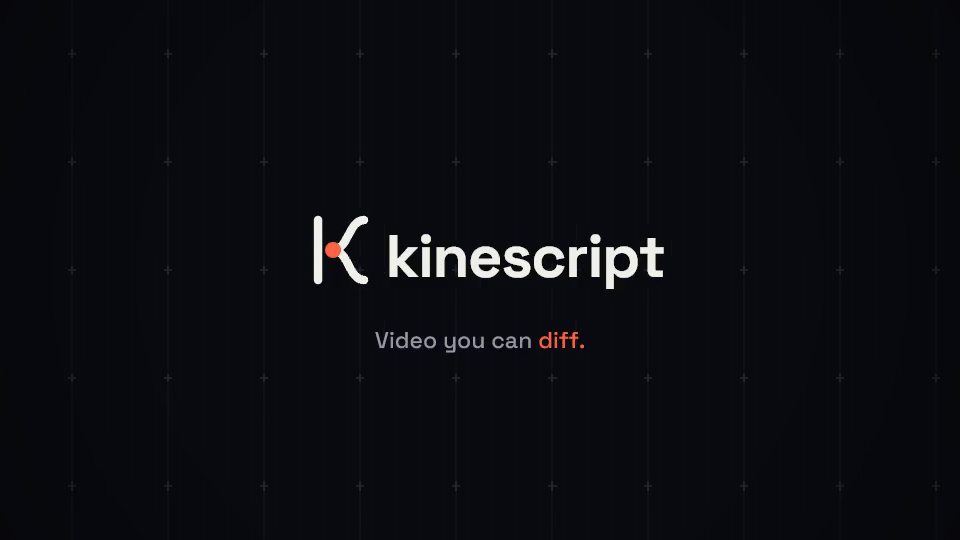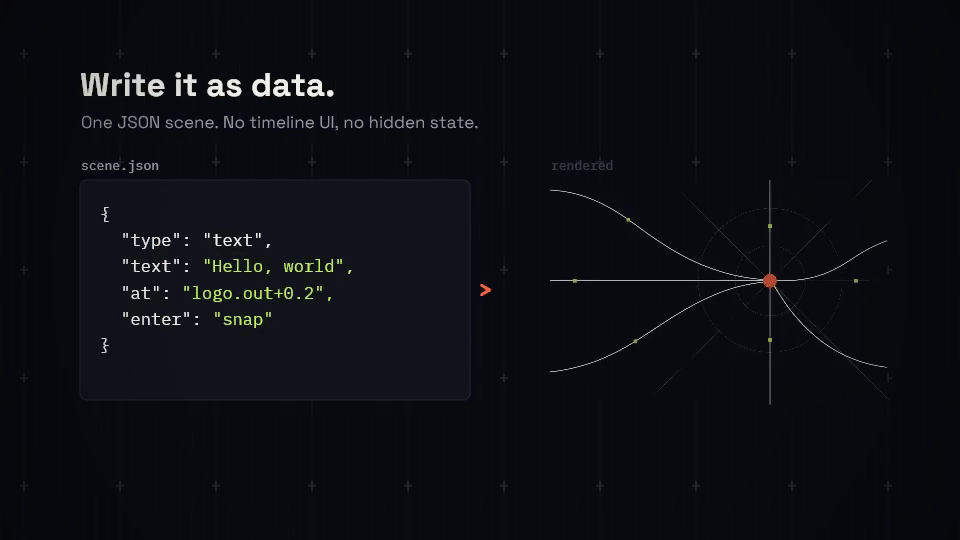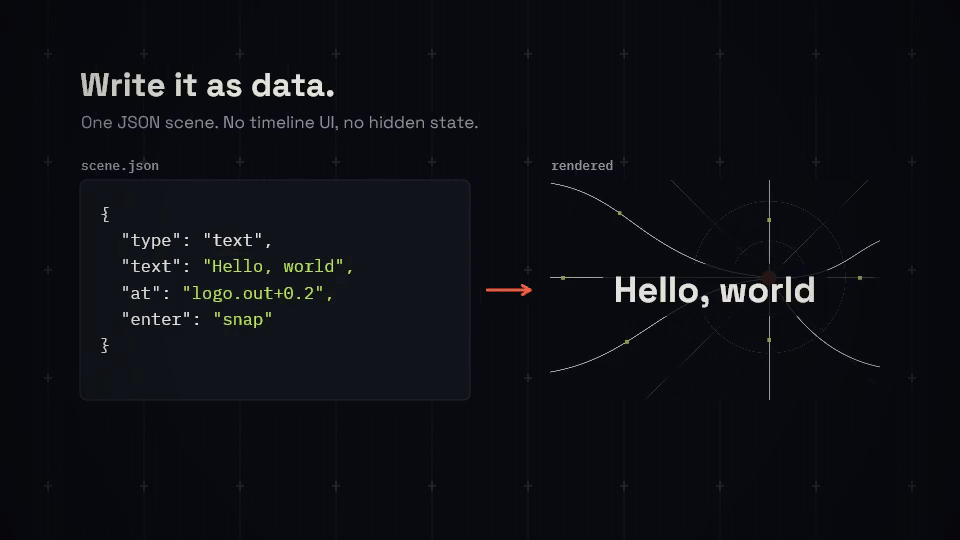
Kinescript turns a JSON scene into video. Every layer, keyframe, cut and sound is a line of data, so a scene can be generated, reviewed in a pull request, and changed by a script or an agent. A voice-over can start as a line of text. The renderer is a pure function of the frame number: any frame renders on its own, which makes previews instant and lets a render split across processes.
pip install kinescript
kine doctor
It needs Python 3.10 or newer and ffmpeg on your PATH (details).
The launch video is a Kinescript scene,
marketing/promo.json. It is 35
seconds of 1080p and renders, with audio, in about 3.3 seconds on the development machine. The
project site shows more demos, each next to the scene file it was
rendered from.
What it does
- Cue timing. Start and end times can name other layers:
"at": "title.out+0.2". Lengthen one layer and everything cued after it moves. Cycles and missing references are reported with the ids involved. - Animate anything. Numbers and colours take constants, keyframes (
[[0, 0], [0.6, 1, "outBack"]], with negative times counted from the layer's end), a tween object, or an expression such as"=540 + sin(t*3)*40". Colours interpolate in OKLab. - Text that moves per letter.
"split": "chars"(or words, or lines) with a staggered enter motion, a typewriter reveal with a caret,**emphasis**markup, and per-unit expressions ("unitY": "=sin(T*4 + i)*12"for a wave). - Footage. Video layers with trim, speed, loop, cover/contain fit, punch-in
zoomaround afocuspoint, and rounded picture-in-picture. Asequenceturns a cut list into clips with fade, wipe, slide, zoom or blur transitions. Clip audio and music beds are mixed automatically. - Sound on the same timeline. Voice-over, music and effects are cues like layers, a voice's words are cues too, a voice can be spoken from text, and sounds with a role are levelled and ducked for you (Sound).
- Captions from
.srt/.vtt, inline cues or a voice's word times, with karaoke and pop modes. - Shaders. SkSL layers with
mesh,aurora,gridandscorepresets, or your own source. - Finishing. Per-layer blur, shadow, blend modes and colour adjustments; a scene grade with vignette and film grain; optional motion blur.
- Components.
lowerThird,titleCard,callout,focus(dim everything but a region),progress,kinetic, plus your own with{{param}}placeholders. - Outputs. H.264
.mp4, ProRes 4444.movand VP9.webmwith alpha for compositing,.gif, PNG sequences.
3D
Depth and models are drawn by the same Skia renderer as everything else, with no extra dependency. Scenes that use no depth draw exactly as before.
- Camera and depth on any layer. Every layer takes
z,rotateX,rotateYandbackface. A top-levelcamerapans, dollies, orbits and rolls with perspective;fixedlayers ignore its moves, and a group with"sort": "depth"draws its children far to near. Theflip,flip-up,tumbleandpushmotions work on whole layers and per letter withsplit. A two-sided card is a group with"backface": "hidden"on each side. - Model layers.
"type": "model"draws a litcube,sphere,cylinder,cone,torusorplane, or several shapes merged aspartsso their triangles are depth-sorted together. Materials takefill,shine,metal,rimandbands(toon steps).light, for the scene or one model, takesstudio,soft,dramaticorflat, or your own amounts.explodesends faces outward and thebuildmotion assembles a model. - Extruded text and SVG paths.
"shape": "text"extrudes letters in any font and"shape": "path"extrudes SVG path data, filled, or stroked withstrokeWidthfor line icons. Both take adepthand a 45-degreebevel. - Model files.
srcreads.glband.gltf(glTF 2.0) and.objwith its.mtl: node transforms, base colours, and metallic and roughness asmetalandshine.groundputs a soft shadow under any model.
A 3D title that builds in and turns to face the camera:
{"id": "title3d", "type": "model", "shape": "text", "text": "LAUNCH",
 "x": "50%", "y": "50%", "size": 240, "weight": 800, "depth": 70, "bevel": 5,
 "rotateY": [[0, -40], [2.4, 0, "outCubic"]], "rotateX": [[0, 18], [2.4, 0, "outCubic"]],
 "shine": 0.6, "enter": {"name": "build", "dur": 1.2}}
Sound
Sounds are a top-level audio list, timed like layers and mixed by ffmpeg while the frames render.
- Cues both ways.
"at": "vo1.out+0.3"starts a layer 0.3 s after the voice ends, and a sound can start at"title.in". A layer's"sound": "pop.wav"plays when it appears and moves when it moves. A voice stretches anautoduration so it is never cut off. - Words are cues. A words file next to a voice (
vo1.words.json, or Whisper's JSON as it is) times each word:"at": "vo1:render"starts a layer as the voice says "render", and{"type": "captions", "voice": "vo1"}captions it, lighting each word as it is said. - Voice-over from text. Write what a voice says in
textandkine voicespeaks it through a plugin, writing the file and its word times: Kokoro (local, fast), Chatterbox (local, cloned voices) or ElevenLabs (cloud, needs an API key), picked per sound withbackend.[[go]]in the text names the next word, so a cue tovo1:gosurvives a rewrite of the line. Only a line whose text, speaker, rate, backend or options changed is spoken again, and rendering never calls a speech engine. - Delivery tags.
[whispers],[laughs]or[sighs]in the text tell ElevenLabs how to say what follows. Chatterbox takes them too but acts them only some of the time: in test takes it made a sound where[laughs]goes in six of nine and whispered in none of seven. Tags are not words, so cues, marks and captions skip them, and Kokoro says the line without them. - A mix without listening. Give a sound a
roleand it is set to that role's level: voice -18 LUFS, music -16, ambience -30, effects peaking at -6 dBFS. Music and ambience dip 14 dB while a voice speaks, an effect's leading silence is skipped so it lands on its cue, and the whole mix ends at -16 LUFS with peaks under -1.5 dBTP. A top-levelmixchanges the targets. Sounds without a role are mixed as given. - Checked and drawn.
kine checkmixes and measures the sound and reports a voice cut off or masked by the music, an effect that lands late, silence, and a mix off its targets.kine look --audiodraws the sound under the frames on the same time axis. - Everywhere. Gain takes keyframes and expressions like any property; sounds loop and pan; the mix goes into
MP4, MOV, WebM and
--from/--torenders, and-o mix.wavrenders the sound alone.
A narrated beat with a click on a marked word, over music that ducks under the voice:
"audio": [
  {"id": "vo", "role": "voice", "at": 0.6, "text": "Each word it says is a [[hit]]cue."},
  {"id": "bed", "role": "music", "src": "bed.m4a", "loop": true, "until": "end", "fadeOut": 1.5}
],
"layers": [
  {"id": "cue", "type": "text", "text": "Cue", "size": 200, "at": "vo:hit", "sound": "click.wav", "enter": "pop"},
  {"id": "cc", "type": "captions", "voice": "vo", "mode": "karaoke"}
]
kine voice scene.json speaks it once. The
voice demo on the project site plays the result with sound, next
to its scene file. Install the plugin for the voice you want next to Kinescript:
pip install kinescript-kokoro       # local and fast; Python 3.10 to 3.12
pip install kinescript-chatterbox   # local, copies a voice from a clip, tags hit or miss; installs PyTorch
pip install kinescript-elevenlabs   # ElevenLabs' API, acts on tags; needs ELEVENLABS_API_KEY
A plugin can also live in another Python, for Kokoro on Python 3.13 or newer or to keep PyTorch out of
Kinescript's environment: point KINE_VOICE_CMD, or KINE_VOICE_CMD_<NAME> for one backend, at it. Each plugin's
README has the details:
Kokoro,
Chatterbox,
ElevenLabs.
Built for agents
An agent cannot watch a video, so Kinescript gives it things it can read:
| Command | What the agent gets |
|---|---|
kine docs |
the full scene reference, short enough to keep in context |
kine check scene.json |
every problem at once as JSON, each with its layer, time range and a fix |
kine look scene.json --boxes |
one PNG of many labelled frames, with every layer outlined and the top-level ones named |
kine look scene.json --audio |
the same frames with the sound under them: a lane per role and the mix, the duck and issues, plus each sound's measured loudness |
kine probe scene.json --at 3.2 |
resolved in/out of every layer and each visible layer's screen box |
kine still / kine render |
a frame, a range (--from/--to), a draft (-q draft --scale 0.5) or the final file |
kine watch scene.json |
the contact sheet, made again every time the file is saved |
kine voice scene.json |
each sound with text spoken into its file, with its word times, skipping what has not changed |
kine check reports unknown keys and bad values, missing media and out-of-range trims, text off the canvas or
in the safe margin, overlapping text, contrast under 3:1 against what is actually behind the text, tiny text and
too little reading time. When the scene has sound it mixes and measures it, without drawing a frame, while the
frames are checked, and reports a voice cut off by the scene end, two voices at once, music less than 10 LU under a
voice, an effect whose first sound comes late, a silent sound, and a mix off its loudness target or at its peak
ceiling. An unknown key names the intended key first. Common names from other tools (color,
fontSize, duration, position) are read and reported as info notes. It exits with status 1 while there are
errors.
The same tools are available over MCP (kine mcp) as kine_docs, kine_check, kine_look, kine_still,
kine_probe, kine_render and kine_voice. They take a scene as a file path or as the JSON object itself, and kine_look
and kine_still return images inline.
{
  "mcpServers": {
    "kinescript": {"command": "kine", "args": ["mcp"]}
  }
}
Install
Requires Python 3.10+ and ffmpeg on PATH (for example winget install Gyan.FFmpeg, brew install ffmpeg or
sudo apt install ffmpeg). On Linux, skia-python also loads the system's EGL, GL and fontconfig libraries, even
with KINE_BACKEND=cpu. A bare container or server needs sudo apt install libegl1 libgl1 libfontconfig1, or
importing Kinescript fails with libEGL.so.1: cannot open shared object file.
pip install kinescript
kine doctor        # ffmpeg path, GPU availability, default font
From a checkout: pip install -e .
Dependencies are skia-python, numpy and glfw. Space Grotesk and IBM Plex Mono (both SIL Open Font License)
ship with the package, so default text looks the same on every machine.
Quick start
kine new scene.json
kine check scene.json
kine look scene.json --boxes
kine render scene.json -o scene.mp4
{
  "canvas": {"w": 1920, "h": 1080, "fps": 30, "bg": "#0a0c10"},
  "grade": {"vignette": 0.35, "grain": 0.04},
  "layers": [
    {"id": "dot", "type": "circle", "x": "50%", "y": "50%", "r": 26, "fill": "$accent",
     "dur": 1.1, "enter": {"name": "pop", "dur": 0.4}, "exit": "fade"},
    {"id": "title", "type": "text", "text": "Motion, **written.**", "x": "50%",
     "y": "46%", "size": 140, "weight": 700, "split": "chars", "at": "dot.out-0.1",
     "dur": 3.2, "enter": {"name": "snap", "stagger": 0.03}, "exit": "fade"},
    {"id": "sub", "type": "text", "text": "scenes as data", "x": "50%", "y": "62%",
     "size": 40, "fill": "$muted", "at": "title.in+0.6", "until": "title.out",
     "enter": "rise"}
  ]
}
More scenes in examples/:
hello.json: a title animation, 4.2 s.edit.json: a cut list with a punch-in, a transition, a lower third, a callout, karaoke captions and a music bed, 10.4 s.3d.json: a camera move past layers at several depths and a card that turns over, 6 s.model.json: lit primitives and a ring around a ball that builds in and flies apart, 6 s.title3d.json: the brand mark as an extruded SVG path and the wordmark as extruded text, 5 s.import.json: a glTF rocket on a ground shadow, 6 s.voiceover.json: titles cued from the words of a voice-over, karaoke captions of it, and a music bed that dips under it, 5.4 s.narrated.json: the same idea with a voice written as text, a marked word and a click on it. Runkine voice examples/narrated.jsonfirst.
edit.json, import.json, voiceover.json and narrated.json read sample media: run
python examples/make_media.py first to generate it.
Performance
Measured on the development machine (Intel Core Ultra 7 265, 20 threads, NVIDIA RTX 5060 Ti, Windows 11), 2026-10-30:
| Workload | Result |
|---|---|
| Drawing one 1080p frame of the launch video on the GPU, converted to I420 and read back as a render does | median 2.8 ms, p95 3.8 ms (all 1038 frames) |
Launch video, 34.6 s at 1080p30, -q high, with audio |
3.3 s wall, about 320 frames/s (median of 5 runs) |
examples/edit.json, 10.4 s with two decoded video clips |
2.25 s wall, 139 frames/s (median of 5 runs) |
python bench/stages.py splits the time
per frame into drawing, conversion and readback, and writing to ffmpeg for several workloads, and times whole
renders.
Rendering uses Skia on the GPU through a hidden OpenGL context, one per worker process. Frames are split into chunks, encoded in parallel and joined without re-encoding, while another ffmpeg process mixes the audio. Within one process, such as the MCP server, the workers stay warm for two minutes between renders.
Limits
- Without a usable GPU, Kinescript falls back to Skia's CPU rasteriser. With the Windows
skia-pythonwheel this is very slow (about 0.65 s per 1080p frame for the launch video); use--scale 0.5for previews on such machines.KINE_BACKEND=cpuforces this path. - 3D is drawn by Skia with a depth sort, not a GL pipeline: models have no image textures, skeletal animation or
shadows cast on each other, and separate model layers do not hide each other per pixel (merge touching
objects as
partsof one model). Draco- and meshopt-compressed model files are not read. - Audio is mixing and levelling (trim, gain over time, fades, speed, loop, pan, role levels, ducking, a loudness target), with no effects such as EQ, compression of single sounds or reverb.
- Kinescript does not speak by itself:
kine voiceneeds a plugin or a command. The Kokoro plugin times words for English voices only and needs Python 3.10 to 3.12; the Chatterbox plugin speaks and times English only; the ElevenLabs plugin needs an API key and a network connection. - Video is decoded and resampled by ffmpeg to the scene frame rate. Jumping backwards or far ahead reopens the decoder, which is slower than sequential playback.
- Text layout is single-script left-to-right with greedy wrapping. No shaping for complex scripts or bidi.
- Expressions are limited to arithmetic and the listed helpers; attribute access and other names are rejected.
Project layout
kinescript/   engine: timing, props, scene, components, render (Skia), space, render3d,
              mesh and models (3D), output (encoding and the audio mix),
              verify (check, look, probe), schema, docs, mcp, cli
examples/     example scenes and the generator for sample media
plugins/      voices for kine voice, each installed on its own: kinescript-kokoro, kinescript-chatterbox,
              kinescript-elevenlabs
marketing/    the launch video as a scene and its builder; build_site.py renders the site
site/         the project site: demo scenes next to the videos rendered from them
brand/        logo files, generated art and the brand guide
bench/        per-stage timing of frames and whole renders
content/      launch post and social copy
tests/        pytest suite
License
MIT, see LICENSE. The bundled fonts are under the
SIL Open Font License 1.1; their notices are in
kinescript/fonts/.
1 maintainer

Metadata
1 maintainer
Release files for kinescript 1.3.1
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| kinescript-1.3.1.tar.gz | 596.1 kB | With provenance | Details for kinescript-1.3.1.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| kinescript-1.3.1-py3-none-any.whl | Python 3 | none | any | Details for kinescript-1.3.1-py3-none-any.whl |
Total release size: 1.2 MB
Release files / kinescript-1.3.1.tar.gz
| Download URL | kinescript-1.3.1.tar.gz |
|---|---|
| Size | 596.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e47cb194fe42fc0912f04d2116d11afd41d36184c93210cca6594619e8d1ba01
|
|
BLAKE2b-256 checksum How to use checksums |
25910d29c1739f3d807a44e053e70d227a37ee4d9283bc9fcc4036b91b332080
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 31, 2026.
Transparency logRelease files / kinescript-1.3.1-py3-none-any.whl
| Download URL | kinescript-1.3.1-py3-none-any.whl |
|---|---|
| Size | 568.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8c796ba804af58b399ccb510fcaaa9e2392981934e7bb9e81900a36ca61e37a7
|
|
BLAKE2b-256 checksum How to use checksums |
c0ee6531c0b6c30f69eb7c84f942752a32a575a1208400e672b405bb78995130
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 31, 2026.
Transparency logSecurity for kinescript 1.3.1
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
All 2 files in this release have been uploaded with provenance metadata.
Attestation for kinescript-1.3.1.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 31, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














