
🧠 Langvio: Natural Language Computer Vision



Connect language models to vision models for natural language visual analysis
🚀 Quick Start • 📖 Documentation • 🎯 Examples • 🔧 Installation • 🤝 Contributing
✨ What is Langvio?
Langvio bridges the gap between human language and computer vision. Ask questions about images and videos in plain English, and get intelligent analysis powered by Qwen-VL — a vision-language model that grounds objects and generates explanations in a single pass.
🎯 Key Features
- 🗣️ Natural Language Interface: Ask questions like "Count all red cars" or "Find people wearing yellow"
- 🎥 Multi-Modal Support: Works with both images and videos
- 🤖 Qwen-VL at the Core: Qwen-VL does both grounding (detection) and language (query parsing, explanations) — one model, one coherent pipeline
- ☁️ API by Default, Local Fallback: Runs over an OpenAI-compatible endpoint (OpenRouter by default) with an API key; falls back to in-process Qwen2.5-VL weights when
langvio[vlm]is installed and no key is set - 📦 Legacy YOLO-World Path: Classic open-vocabulary detection via YOLO-World v2 + ByteTracker still available for users who want it
- 📹 Multi-Object Tracking: ByteTracker integration for video analysis with boundary crossing and speed estimation
- 📊 Advanced Analytics: Object counting, spatial relationships, temporal tracking
- 🎨 Visual Output: Generates annotated images/videos with detection highlights and tracking trails
- 🌐 Web Interface: Flask web app included for easy interaction
- 🔧 Extensible: Easy to add new models and capabilities
🎬 See It In Action
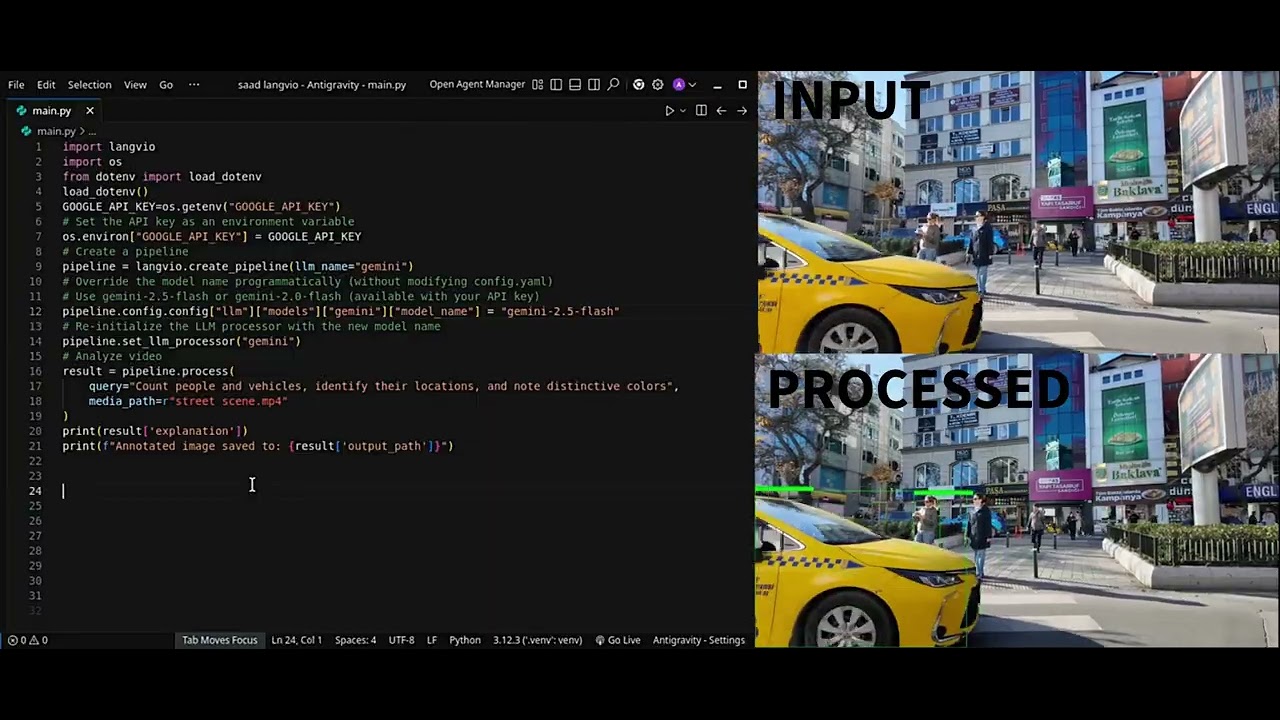
Python API Example
import langvio

# Create a pipeline (uses the hosted Qwen-VL API if OPENROUTER_API_KEY is set,
# otherwise falls back to local Qwen2.5-VL weights)
pipeline = langvio.create_pipeline()

# Analyze an image
result = pipeline.process(
    query="Count how many people are wearing red shirts",
    media_path="street_scene.jpg"
)

print(result['explanation'])
# Output: "I found 3 people wearing red shirts in the image.
#          Two are located in the center-left area, and one is on the right side."

# View the annotated result
print(f"Annotated image saved to: {result['output_path']}")
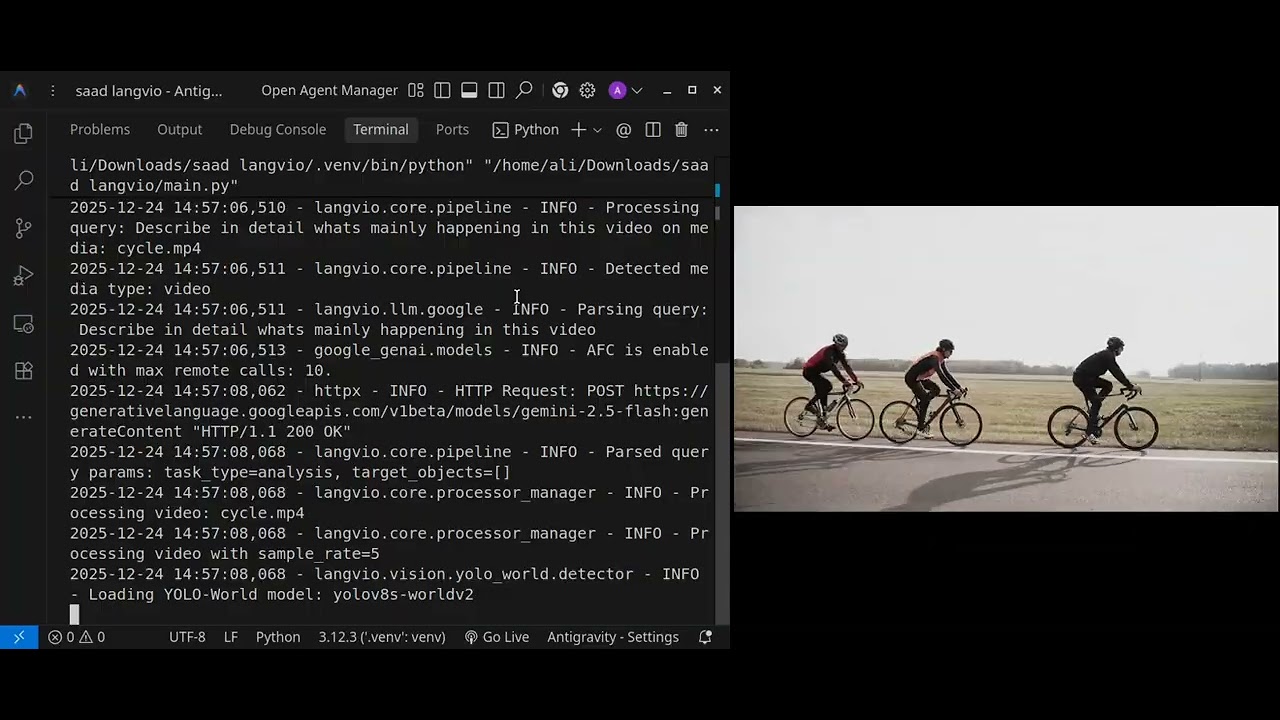
Command-Line Interface Example
# Basic usage — prompts for an OpenRouter key on first run, saves it to .env
langvio --query "Count the cars" --media image.jpg

# Pass a key inline (overrides env for this run)
langvio --api-key sk-or-... -q "Find red objects" -m scene.jpg

# Force the local backend (requires `pip install langvio[vlm]`)
langvio --backend local -q "What's in this image?" -m photo.jpg
🖼️ Example Output
A chair-detection run on a classroom video. The still is one annotated frame; click it to play the full MP4.

Query: "detect all chairs in the room" • Click the frame to play the processed video.
🔧 Installation
Basic Installation
pip install langvio
That's enough to use the hosted API backend (default). You only need the local VLM extra if you plan to run Qwen-VL on your own machine.
Optional: Local VLM Backend
# Run Qwen2.5-VL in-process via HuggingFace transformers (adds ~several GB on first run)
pip install langvio[vlm]

# Equivalent grouped extra
pip install langvio[all-llm]

# For development
pip install langvio[dev]
The first local run downloads Qwen2.5-VL weights from HuggingFace (several GB). A CUDA GPU is strongly recommended; CPU works but is slow.
Environment Setup
The default (hosted) backend needs an OpenRouter API key. Get one at openrouter.ai/keys and either export it or put it in a .env file at your project root — langvio auto-loads .env on import.
cp .env.template .env
# Required for the default API backend
OPENROUTER_API_KEY=your_openrouter_api_key_here

# Optional overrides
# QWEN_API_KEY=alternative_key              # alias for OPENROUTER_API_KEY
# QWEN_API_BASE_URL=https://openrouter.ai/api/v1
# QWEN_API_MODEL=qwen/qwen3-vl-30b-a3b-instruct
# LANGVIO_BACKEND=auto                      # auto | api | local
# LANGVIO_DEFAULT_LLM=qwen
# LANGVIO_DEFAULT_VISION=qwen_vlm

# Optional (local backend only)
# HF_HOME=/path/to/hf-cache
# HF_TOKEN=your_huggingface_token_here      # for gated models
If no key is set and you run the CLI interactively, langvio will prompt you for one and offer to save it to .env. Press Enter at the prompt to fall back to the local backend instead.
🚀 Quick Start
Basic Usage
import langvio

# Pipeline auto-resolves the backend: API if a key is configured, else local.
pipeline = langvio.create_pipeline()

# Process an image
result = pipeline.process(
    query="What objects are in this image?",
    media_path="path/to/your/image.jpg"
)

print(result['explanation'])
print(f"Output: {result['output_path']}")
Video Analysis
# Analyze videos with temporal understanding
result = pipeline.process(
    query="Count vehicles crossing the intersection",
    media_path="traffic_video.mp4"
)

print(result['explanation'])
Web Interface
# Launch the web interface
cd webapp
python app.py

# Visit http://localhost:5000 in your browser
🎯 Examples
Object Detection & Counting
# Count specific objects
pipeline.process("How many cars are in this parking lot?", "parking.jpg")

# Find objects by attributes
pipeline.process("Find all red objects in this image", "scene.jpg")

# Spatial relationships
pipeline.process("What objects are on the table?", "kitchen.jpg")
Video Analysis with ByteTracker
ByteTracker is wired into the legacy YOLO-World path for multi-object tracking across frames:
# Track movement patterns
pipeline.process("Track people walking through the scene", "crowd.mp4",
                 vision_name="yolo_world_v2_m")

# Boundary crossing (entry/exit counts)
pipeline.process("How many vehicles entered vs exited the intersection?",
                 "traffic.mp4", vision_name="yolo_world_v2_m")

# Speed analysis via tracked trajectories
pipeline.process("What's the average speed of vehicles?", "highway.mp4",
                 vision_name="yolo_world_v2_m")
Advanced Queries
# Complex multi-part analysis
pipeline.process(
    "Count people and vehicles, identify their locations, and note distinctive colors",
    "street_scene.jpg"
)

# Verification tasks
pipeline.process("Is there a dog in this image?", "park_scene.jpg")
🏗️ Architecture
graph TD
    A[User Query] --> B[Qwen-VL Query Parser]
    B --> C{Vision Processor}
    C -->|Default| D[Qwen-VL Grounding]
    C -->|Legacy| E[YOLO-World v2 Detection]
    D --> F[Attribute & Spatial Analysis]
    E --> F
    F --> G{Is Video?}
    G -->|Yes| H[ByteTracker Multi-Object Tracking]
    G -->|No| J[Qwen-VL Explanation]
    H --> I[Boundary Crossing / Speed / Trajectories]
    I --> J
    J --> K[Visualization]
    K --> L[Annotated Output]
Core Components
- 🧠 Qwen-VL Processor: Parses queries, grounds objects, and generates explanations. Runs over the OpenRouter API by default; locally via HuggingFace transformers with
langvio[vlm]. - 👁️ YOLO-World v2 Processor (optional): Legacy open-vocabulary detector for use cases where YOLO-level latency and class-flexible detection are preferred.
- 📹 ByteTracker: Multi-object tracker used with the YOLO-World path for videos — boundary crossing, counting, speed estimation.
- 🎨 Media Processor: Creates visualizations and handles I/O.
- ⚙️ Pipeline: Orchestrates the entire workflow and resolves the backend (
api/local/auto).
📊 Supported Models
Language / Vision Models (Qwen-VL)
Hosted API (default — needs OPENROUTER_API_KEY, selected via --api-model or QWEN_API_MODEL):
qwen/qwen3-vl-30b-a3b-instruct— default, sparse MoE, strong grounding at small-model costqwen/qwen3-vl-8b-instruct— cheaper, lower latencyqwen/qwen3-vl-235b-a22b-instruct— highest qualityqwen/qwen2.5-vl-72b-instruct— pixel-space bounding boxes
Any OpenAI-compatible endpoint works (OpenRouter, Alibaba Model Studio / DashScope, HuggingFace router, self-hosted vLLM) — set QWEN_API_BASE_URL.
Local backend (needs pip install langvio[vlm], model loaded in-process via HuggingFace):
qwen/qwen-3b—Qwen/Qwen2.5-VL-3B-Instruct(smallest, fastest)qwen-7b—Qwen/Qwen2.5-VL-7B-Instruct(higher quality)qwen2-vl-7b—Qwen/Qwen2-VL-7B-Instruct
Legacy Vision Models (YOLO-World v2)
Available by name when you want classic detection + ByteTracker instead of Qwen-VL grounding:
yolo_world_v2_s— Small (fastest)yolo_world_v2_m— Medium (balanced)yolo_world_v2_l— Large (most accurate)yolo_world_v2x— Extra-large
Aliases: yolo11n, yolo, yoloe → small; yoloe_medium → medium; yoloe_large → large.
🛠️ Configuration
Custom Configuration
# config.yaml
llm:
  default: "qwen"
  models:
    qwen:
      # Qwen-VL — same name for both backends; `backend` + `api_model` decide
      # which path is used.
      model_name: "Qwen/Qwen2.5-VL-3B-Instruct"   # used by local backend
      backend: "auto"                              # auto | api | local
      api_key_env: "OPENROUTER_API_KEY"
      api_model: "qwen/qwen3-vl-30b-a3b-instruct"  # used by API backend
      api_base_url: "https://openrouter.ai/api/v1"
      model_kwargs:
        temperature: 0.2
        max_new_tokens: 1024

vision:
  default: "qwen_vlm"
  models:
    qwen_vlm:
      model_name: "Qwen/Qwen2.5-VL-3B-Instruct"
    # Legacy detector:
    yolo_world_v2_m:
      type: "yolo_world"
      model_name: "yolov8m-worldv2"
      confidence: 0.45
      # ByteTracker configuration
      track_thresh: 0.3      # Detection confidence threshold for tracking
      track_buffer: 70       # Frames to keep lost tracks
      match_thresh: 0.6      # IoU threshold for track matching

media:
  output_dir: "./results"
  visualization:
    box_color: [0, 255, 0]
    line_thickness: 2
# Use custom configuration
pipeline = langvio.create_pipeline(config_path="config.yaml")
Command Line Interface
# Basic usage (prompts for key if none set; falls back to local on empty input)
langvio --query "Count the cars" --media image.jpg

# All CLI flags
langvio \
  --query "Find red objects" \
  --media scene.jpg \
  --config custom.yaml \
  --api-key sk-or-...                       \
  --api-model qwen/qwen3-vl-8b-instruct     \
  --api-base-url https://openrouter.ai/api/v1 \
  --backend auto                            \
  --vision qwen_vlm                         \
  --llm qwen                                \
  --output ./results

# List available models
langvio --list-models
🌟 Advanced Features
Video Tracking with ByteTracker
Used with the YOLO-World path for robust multi-object tracking across frames.
- Multi-Object Tracking: Persistent IDs across frames
- Boundary Crossing Detection: Entry/exit counts for defined regions
- Speed Estimation: Trajectory-based speed per track
- Track Persistence: Survives short occlusions via configurable buffer
- Configurable Thresholds:
track_thresh,track_buffer,match_thresh
Technical:
- Kalman filter-based motion prediction
- IoU-based data association
- High/low-confidence detection handling
- Automatic track initialization and termination
Spatial Relationship Analysis
- Positional Understanding: "objects on the table", "cars in the parking lot"
- Relative Positioning: left/right, above/below, near/far
- Containment Detection: objects inside other objects
Temporal Analysis (Video)
Powered by ByteTracker:
- Movement Patterns: Track trajectories and behaviors across frames
- Activity Recognition: Detect activities over time
- Temporal Relationships: Object co-occurrence and interactions
- Trajectory Analysis: Visualize movement paths
- Entry/Exit Tracking: Monitor region crossings
Color & Attribute Detection
- Color Recognition: Many color categories with confidence scoring
- Size Classification: Automatic small/medium/large categorization
- Multi-attribute Analysis: Combined color, size, and position
🚀 Performance & Optimization
Model Selection Strategy
# Defaults: Qwen-VL for both vision and language, API backend if a key is set.
pipeline = langvio.create_pipeline()

# Pick a larger local VLM for higher-quality explanations
pipeline = langvio.create_pipeline(llm_name="qwen-7b")

# Opt into the legacy YOLO-World + ByteTracker path for videos
pipeline = langvio.create_pipeline(vision_name="yolo_world_v2_l")
Optimization Tips
- Backend choice: The hosted API avoids large downloads and runs well on any machine; the local backend avoids per-request cost and keeps data on-device
- Hosted model choice:
qwen3-vl-8bfor cost/latency,qwen3-vl-30b-a3bfor quality (default),qwen3-vl-235b-a22bfor the strongest grounding - YOLO-World path: Smaller models (
yolo_world_v2_s) for speed, larger (yolo_world_v2_l) for accuracy; adjustconfidencefor precision/recall - Frame sampling: Control video processing speed vs accuracy (default: every 5th frame)
- Environment variables:
LANGVIO_DEFAULT_LLM,LANGVIO_DEFAULT_VISION, andLANGVIO_BACKENDset global defaults without a config file
🧪 Testing
# Install test dependencies
pip install langvio[dev]

# Run all tests
pytest

# Run with coverage
pytest --cov=langvio --cov-report=html

# Run specific test file
pytest tests/test_config.py
See tests/README.md for more testing information.
🤝 Contributing
Development Setup
# Clone the repository
git clone https://github.com/MugheesMehdi07/langvio.git
cd langvio

# Install in development mode
pip install -e .[dev]

# Run tests
pytest

# Format code
black langvio/
isort langvio/
Contributing Guidelines
- Fork the repository
- Create a feature branch (
git checkout -b feature/amazing-feature) - Commit your changes (
git commit -m 'Add amazing feature') - Push to the branch (
git push origin feature/amazing-feature) - Open a Pull Request
📚 Documentation
- 📖 Full Documentation: Comprehensive guides and API reference
- 🎯 Examples: Ready-to-run example scripts
- 🌐 Web App: Flask web interface for easy testing
- ⚙️ Configuration: Sample configuration files
🔗 Links & Resources
📄 MIT License
Copyright (c) 2026 LangVio
Permission is hereby granted, free of charge, to any person obtaining a copy of this software and associated documentation files (the "Software"), to deal in the Software without restriction, including without limitation the rights to use, copy, modify, merge, publish, distribute, sublicense, and/or sell copies of the Software, and to permit persons to whom the Software is furnished to do so, subject to the following conditions:
The above copyright notice and this permission notice shall be included in all copies or substantial portions of the Software.
THE SOFTWARE IS PROVIDED "AS IS", WITHOUT WARRANTY OF ANY KIND, EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO THE WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE AND NONINFRINGEMENT. IN NO EVENT SHALL THE AUTHORS OR COPYRIGHT HOLDERS BE LIABLE FOR ANY CLAIM, DAMAGES OR OTHER LIABILITY, WHETHER IN AN ACTION OF CONTRACT, TORT OR OTHERWISE, ARISING FROM, OUT OF OR IN CONNECTION WITH THE SOFTWARE OR THE USE OR OTHER DEALINGS IN THE SOFTWARE.
Usage and License Notices
This project uses certain datasets, models, APIs, and algorithms that are subject to their respective original licenses and terms of use. Users must comply with all terms and conditions of these original licenses, including but not limited to:
-
Qwen (Tongyi Qianwen) License: This project uses Alibaba Cloud's Qwen-VL family (Qwen3-VL via OpenAI-compatible APIs, and/or Qwen2.5-VL / Qwen2-VL run locally via HuggingFace transformers). Users must comply with the Qwen license terms published on the respective model cards.
-
YOLO-World License: The optional YOLO-World v2 detectors are developed by Ultralytics. Users must comply with the Ultralytics YOLO License (AGPL-3.0) and any additional terms specified by Ultralytics for YOLO-World.
-
ByteTracker License: The ByteTracker algorithm used for multi-object tracking is subject to its original license — see the ByteTracker repository.
-
OpenRouter / API Providers: When using the hosted API backend, usage is also governed by the terms of the chosen provider (OpenRouter, Alibaba Model Studio, etc.).
This project does not impose any additional constraints beyond those stipulated in the original licenses. Users are responsible for ensuring that their use of the datasets, models, APIs, and algorithms is in compliance with all applicable laws and regulations.
For the full license text, see the LICENSE file.
🙏 Acknowledgments
- Alibaba Cloud / Qwen for the Qwen-VL vision-language models
- OpenRouter and the broader OpenAI-compatible API ecosystem that makes the hosted backend portable
- HuggingFace for
transformersand model hosting - Ultralytics for YOLO-World v2 (optional legacy path)
- ByteTracker for robust multi-object tracking
- LangChain for the LLM integration framework
- OpenCV for computer vision utilities
⭐ Star us on GitHub if Langvio helps you!
1 maintainer

Metadata
1 maintainer
Release files for langvio 0.0.8
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| langvio-0.0.8.tar.gz | 137.4 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| langvio-0.0.8-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 260.4 kB
Release files / langvio-0.0.8.tar.gz
| Download URL | langvio-0.0.8.tar.gz |
|---|---|
| Size | 137.4 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
cb6536e4c9c172b9a345e61b8b033448ecce70b9e24727cab3234830b6aa9c87
|
|
BLAKE2b-256 checksum How to use checksums |
38e2880937bc5bdb09d079a2fe4e9a2c724b781f417d4745a375fcafa60ebbe3
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Release files / langvio-0.0.8-py3-none-any.whl
| Download URL | langvio-0.0.8-py3-none-any.whl |
|---|---|
| Size | 123.0 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
bba5019c8c77667c7eb4f6e7a0845a82a7bafd412613a191b3a40d921da1e4af
|
|
BLAKE2b-256 checksum How to use checksums |
52eb963012f77510a107db7d6ce47686a9e185411f698dc076210d4ef7e2cf0f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|














