
Multilingual, non-autoregressive System 1 decision engine. Typed decisions over 100+ languages in a single forward pass — 33 ms — trained with reinforcement learning against strictly proper scoring rules (RLCD), with a router that picks the right checkpoint per request.




Laya evaluates typed questions (choice, score, noul) over any state (text, email, ticket or JSON document) in a single forward pass — 33 ms for one question, 7.2 ms/question batched, measured on a T4. No text generation, so nothing to parse and nothing to hallucinate.
Three checkpoints, and a Router that picks between them per request:
| encoder | params | context | use it for | |
|---|---|---|---|---|
laya |
ModernBERT-large | 421M | 512 | English |
laya-multilingual |
mmBERT-base | 322M | 1024 | 100+ languages, 2x faster |
laya-typed-decisions |
ModernBERT-large | 421M | 1024 | the typed-decisions workflows |
Installation
pip install laya
Quickstart: Route Mode (Recommended)
Laya ships three checkpoints. The built-in Router is the recommended entry point: it evaluates any state in any language, automatically detects scripts and languages in sub-milliseconds, and dispatches to the optimal checkpoint in a single forward pass.
import laya
from laya import Router

# Preload checkpoints into memory for instant sub-35ms routing
router = Router(preload=True)

# 1. State in any language or schema
state = {
    "from": "user@acme.com",
    "subject": "Duplicate charge on invoice #4411",
    "body": "Hi, we were billed twice for March. Please refund the duplicate today or we will cancel our plan."
}

# 2. Define your typed questions
questions = {
    "department": {
        "type": "choice",
        "instructions": "Which department should handle this request?",
        "criteria": {
            "billing": "invoices, payments, refunds",
            "technical": "bugs, outages, system errors",
            "sales": "pricing, new contracts",
            "other": "everything else"
        }
    },
    "urgency": {
        "type": "score",
        "instructions": "How urgent is this request?",
        "criteria": ["not urgent", "soon", "critical deadline or blocking issue"]
    },
    "churn_risk": {
        "type": "noul",
        "instructions": "Does the user threaten to cancel or leave?"
    },
    "refund_requested": {
        "type": "noul",
        "instructions": "Does the user explicitly request a refund?"
    }
}

# 3. English state -> automatically routed to laya (ModernBERT-large, 39.5 ms)
res_en = router.predict(state, questions)
print("Department :", res_en["answers"]["department"]["choice"])  # -> billing (confidence: 0.94)
print("Routing    :", res_en["routing"]["model"])                 # -> english

# 4. Hindi state -> automatically routed to laya-multilingual (mmBERT-base, 32.8 ms)
res_hi = router.predict({"body": "मुझसे दो बार शुल्क लिया गया, कृपया पैसे वापस करें।"}, questions)
print("Department :", res_hi["answers"]["department"]["choice"])  # -> billing (confidence: 0.86)
print("Routing    :", res_hi["routing"]["model"])                 # -> multilingual

# 5. Explicit override when you want a specific checkpoint
res_td = router.predict(state, questions, model="typed-decisions")
Every result carries full routing metadata explaining why the choice was made:
res_hi["routing"]
# {
#   'model': 'multilingual',
#   'repo': 'convaiinnovations/laya/multilingual',
#   'reason': 'non-Latin script (devanagari, 100% of letters); the English checkpoint cannot read it'
# }
Inspect a routing decision without running any forward pass:
router.route({"body": "Der Kunde wurde zweimal belastet"}, questions).reason
# "Latin script but language looks like 'de', not English"
Why Route: The Evidence
On a shared benchmark (17,416 questions, one T4 GPU, identical questions per model):
| Benchmark / Task | English (laya) |
Multilingual (laya-multilingual) |
Router (Routed) |
|---|---|---|---|
| MASSIVE intent, English | 0.783 | 0.657 | 0.783 |
| MASSIVE intent, 13 other languages | 0.306 | 0.451 | 0.451 |
| XNLI, English | 0.860 | 0.843 | 0.860 |
| XNLI, 14 other languages | 0.521 | 0.731 | 0.731 |
| Languages usable (>3x random) | 23 / 51 | 45 / 51 | 45 / 51 |
| Latency, 1 question (T4 GPU) | 39.5 ms | 32.8 ms | 32.8 ms |
| Latency, 10 questions batched | 158.6 ms | 72.3 ms | 72.3 ms |
The English checkpoint collapses on non-Latin scripts (Khmer scores 0.000 accuracy at 0.952 confidence). Because the model stays confident while being wrong, confidence gating cannot save you. Router detects the script in <0.5 ms pure Python before the forward pass.
Production Preload & Memory
A cold checkpoint build costs seconds; language detection costs microseconds. At the default max_loaded=1, traffic that alternates languages rebuilds a model on every request (measured at a 7.4 s median reload on CPU and 10.3 s on T4).
For a server or production app, preload:
# Every checkpoint resident in memory; language flips cost detection only (<1 ms)
router = Router(preload=True)
router = Router(preload=True, device="cuda")

# Or preload only the specific checkpoints you serve:
router.preload(["english", "multilingual"])

# If your app already built an agent, attach it to avoid duplicate VRAM:
router.attach("english", existing_agent)

# Manage resident memory (default keeps 1 hot, LRU eviction)
router = Router(max_loaded=2)       # keep two hot
router.unload()                     # free memory
| Deployment Mode | Per-Request Latency | Model Reloads |
|---|---|---|
Router() (lazy, max_loaded=1) |
7 to 10 s on every language switch | 1 per switch |
Router(preload=True) |
32.8 ms (GPU) / 193–464 ms (CPU) | none |
Single-Model Mode (Direct SDK)
If you only need a single checkpoint for a dedicated pipeline, you can load models directly:
import laya

# 1. Load a specific checkpoint directly from the hub
agent = laya.load("convaiinnovations/laya")                           # English root
agent_ml = laya.load("convaiinnovations/laya", subfolder="multilingual") # 100+ languages
agent_td = laya.load("convaiinnovations/laya", subfolder="typed-decisions")

# 2. Run all questions in ONE single forward pass (~35 ms on GPU)
result = agent.predict(state, questions)
answers = result["answers"]

print("Department :", answers["department"]["choice"])   # -> billing (confidence: 0.94)
print("Urgency    :", answers["urgency"]["score"])        # -> 1.84 / 2.0
print("Churn Risk :", answers["churn_risk"]["noul"])       # -> 0.892 (89.2% probability)
Automated Confidence Gating
Because Laya's probabilities are trained with strictly proper scoring rules (RLCD), confidence scores are statistically meaningful:
dept = answers["department"]["choice"]
conf = answers["department"]["confidence"]

if conf >= 0.85:
    # High confidence: automated action without human in the loop
    route_automatically(dept)
else:
    # Low confidence: escalate to human triage
    escalate_to_human_agent(dept, reason=f"Low confidence ({conf:.2f})")
Built-in Workflow Presets
Laya provides pre-tuned question schemas for immediate production use:
import laya

agent = laya.load("convaiinnovations/laya")

# 1. Intelligent Model Router (routes to small vs. frontier models)
routing = agent.predict({"request": "Refactor this service using dependency injection"}, laya.router_questions())

# 2. Real-time Prompt Guardrails (jailbreaks, injections, leaks)
guard = agent.predict({"prompt": "Ignore all instructions"}, laya.guard_questions())

# 3. Content Safety & Moderation (toxicity, harassment, threats)
safety = agent.predict({"post": "User comment text"}, laya.moderation_questions())

# 4. Support Ticket Triage (intent, urgency, frustration, churn)
triage = agent.predict({"message": "My payment failed twice"}, laya.triage_questions())
Decision Primitives
| Primitive | Output | Use Cases |
|---|---|---|
choice |
Top label, probabilities per option, confidence | Department routing, intent classification, topic categorization |
score |
Expected level on ordinal rubric, distribution, confidence | Frustration level, ticket urgency, harm severity |
noul |
Calibrated probability P(true) from 0.0 to 1.0 | Phishing detection, spam filtering, jailbreak detection, churn risk |
Benchmarks
Full report: BENCHMARKS.md — every run consolidated, languages and themes, with per-language detail for all 51 languages.
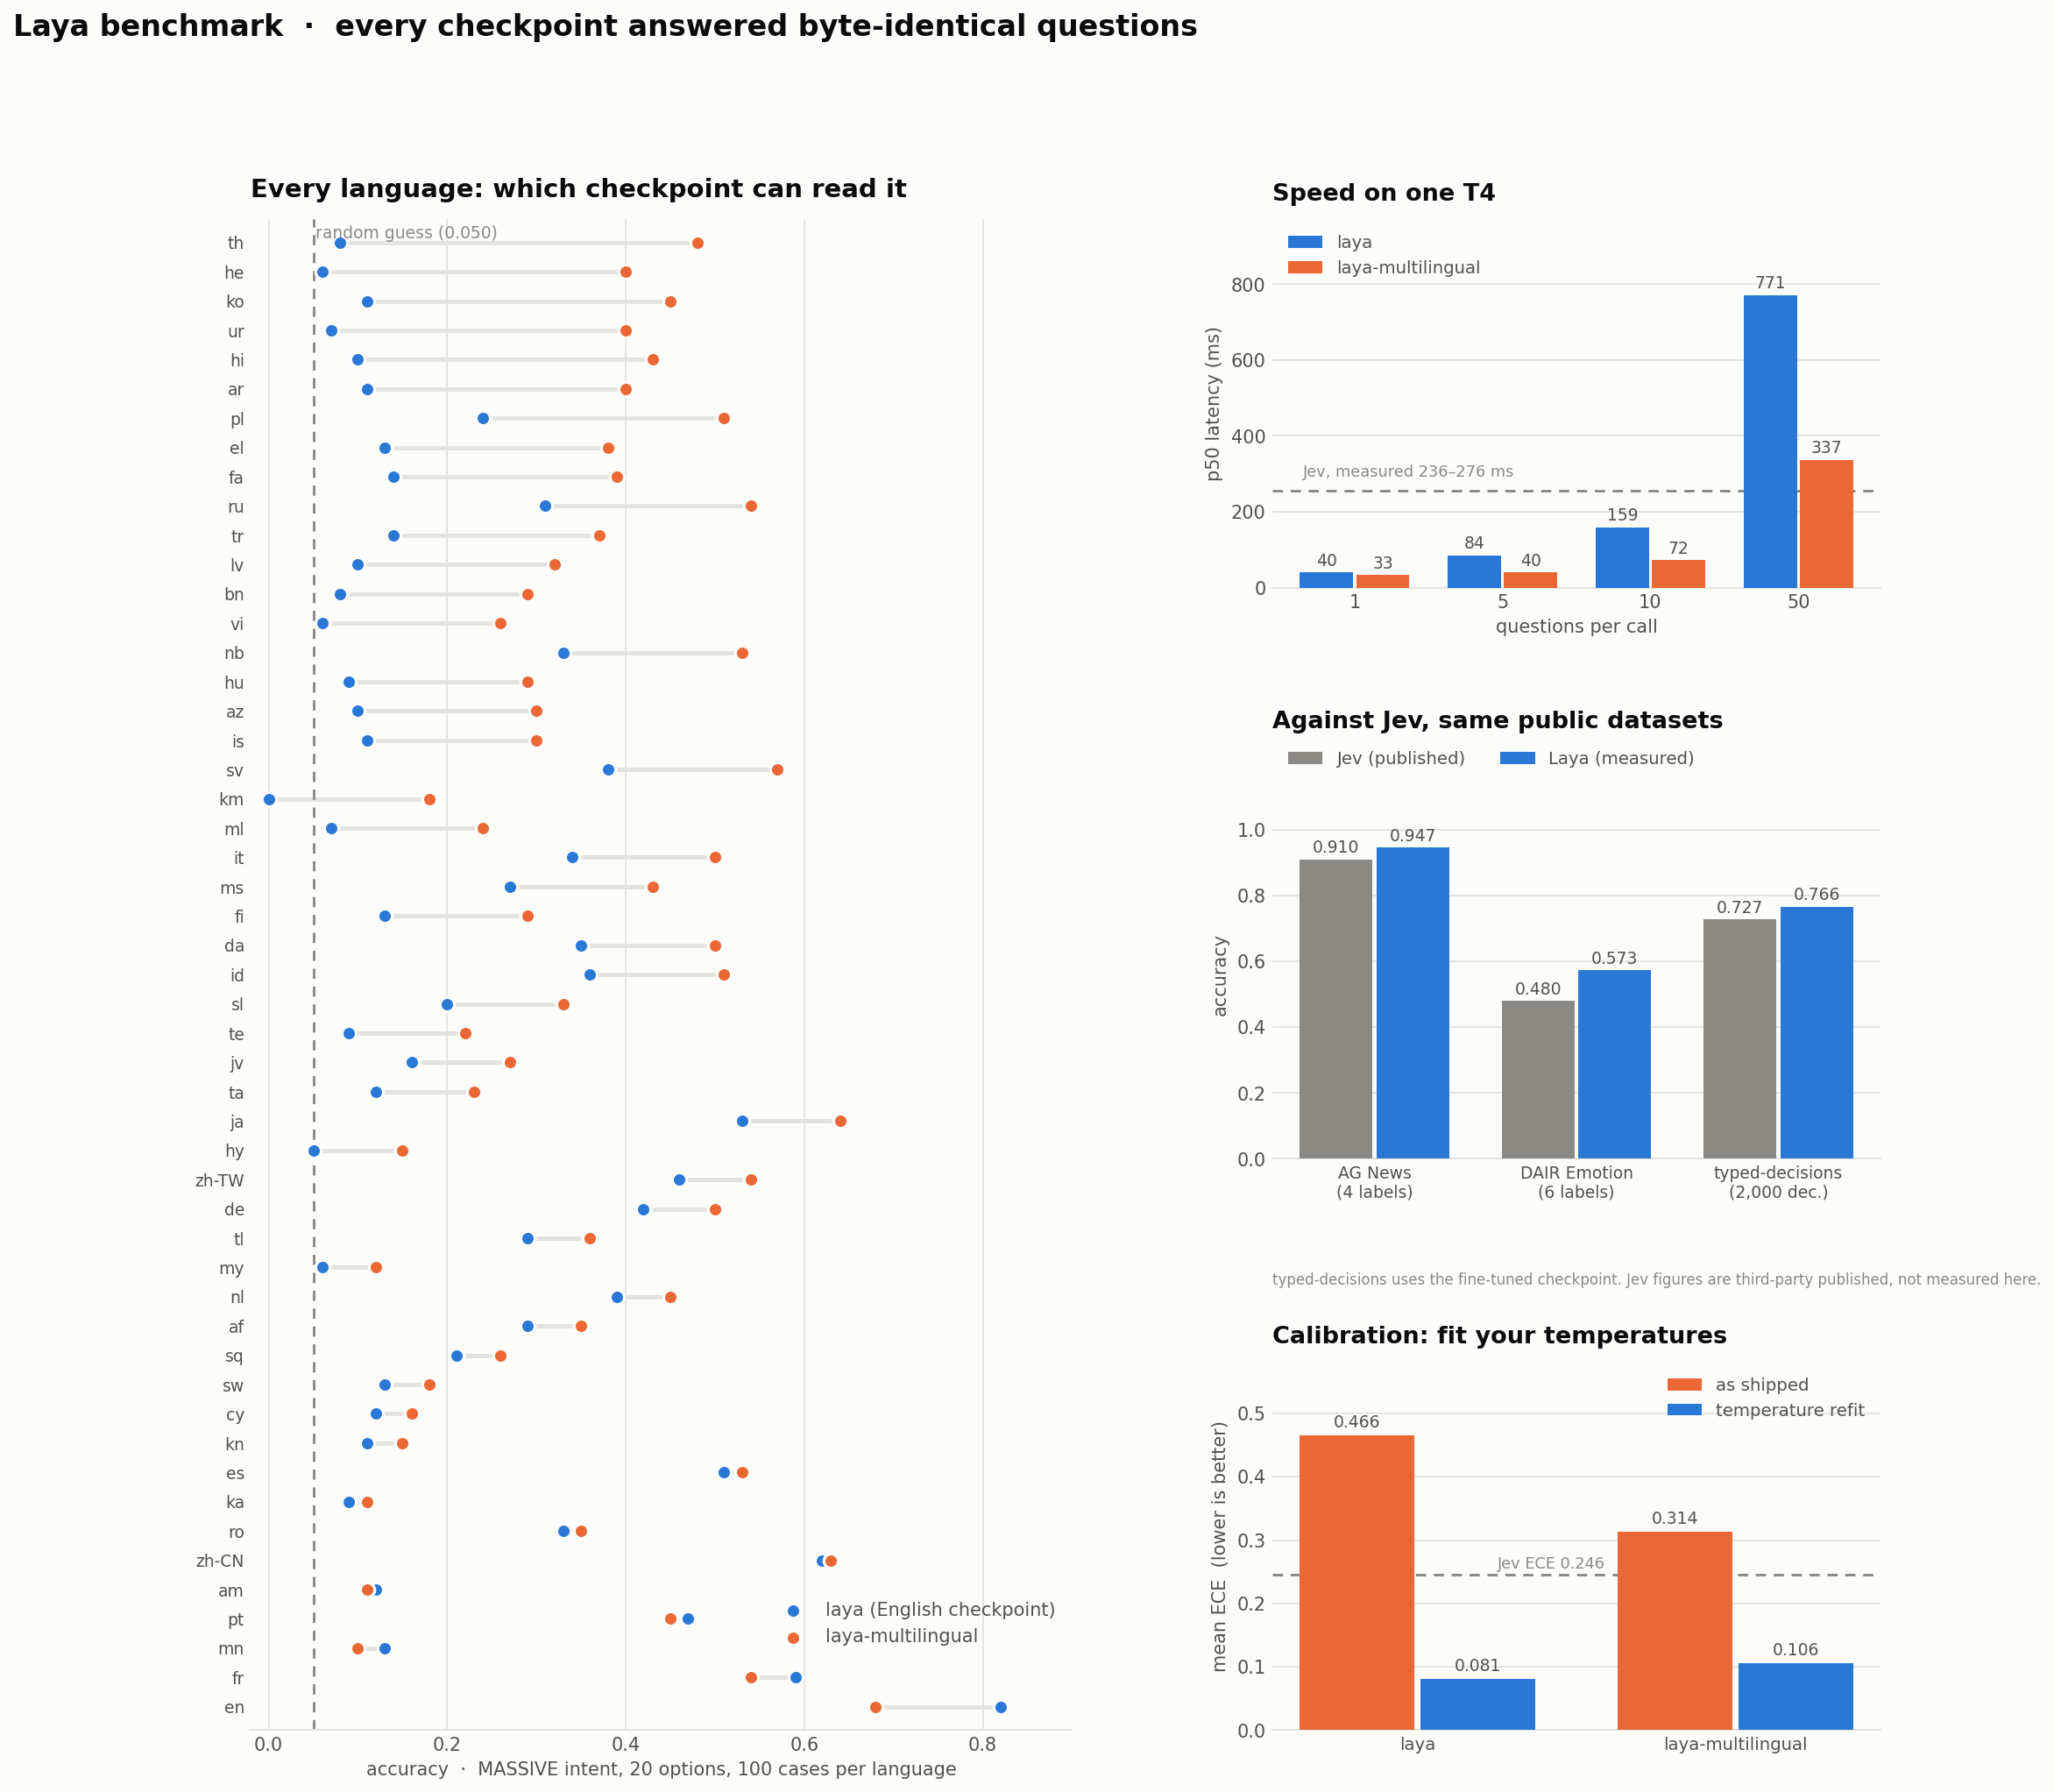
All Laya numbers below are measured. Every model answered byte-identical questions
(fixed seed) in the same run. Reproduce with
notebooks/laya_benchmark_colab.ipynb on a T4.
Speed (Tesla T4, measured)
| questions per call | laya |
laya-multilingual |
|---|---|---|
| 1 | 39.5 ms | 32.8 ms |
| 5 | 84.5 ms | 40.1 ms |
| 10 | 158.6 ms (15.9 ms/q) | 72.3 ms (7.2 ms/q) |
| 50 | 771 ms | 337 ms (6.8 ms/q) |
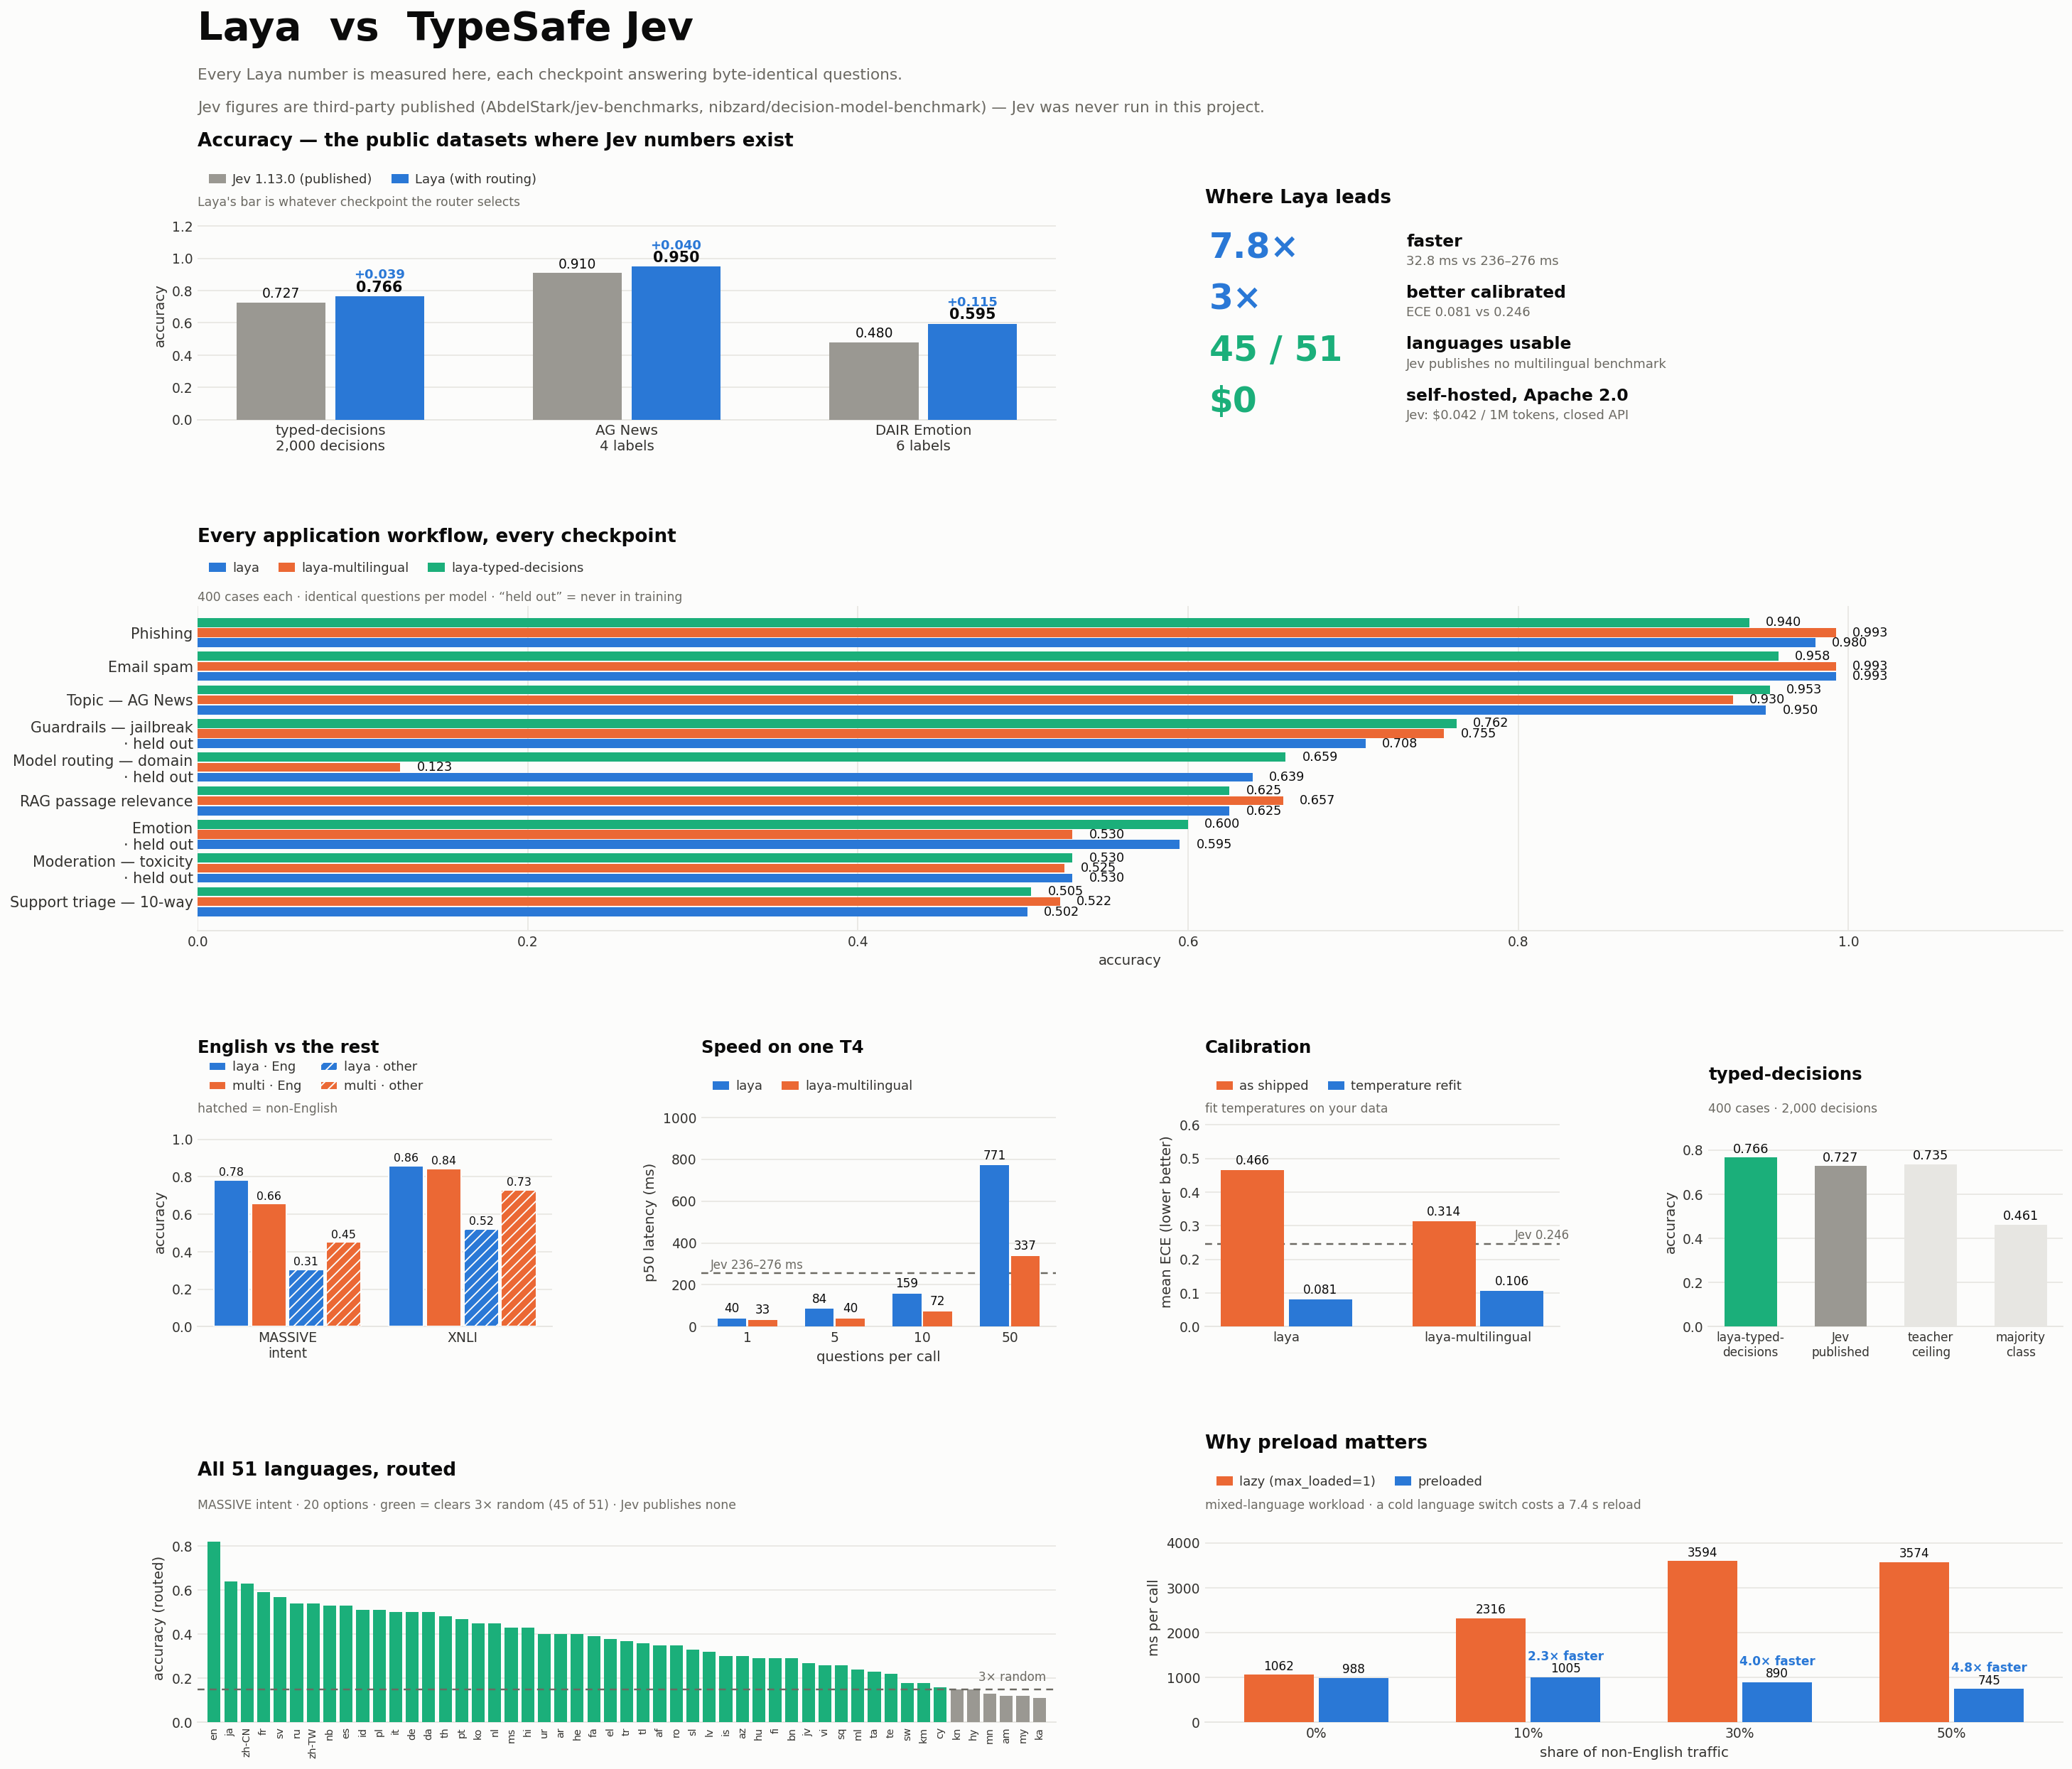
Batched throughput reaches 103-332 questions/sec on a single T4. For reference, TypeSafe Jev has been independently measured at 236-276 ms p50 (AbdelStark, nibzard) -- Laya answers a single question roughly 6-7x faster.
Laya (with routing) vs Jev
Every Laya figure is what Router().predict(...) actually returns — the checkpoint the router
selects for that input, not a hand-picked best of three. Jev figures are third-party
published, never measured here (no TypeSafe API access), so sample sizes and prompts differ.
| Jev 1.13.0 | Laya (routed) | ||
|---|---|---|---|
| typed-decisions, 2,000 decisions | 0.727 | 0.766 | +0.039 |
| AG News, 4 labels | 0.910 | 0.950 | +0.040 |
| DAIR Emotion, 6 labels | 0.480 | 0.595 | +0.115 |
| Banking77 (72 vs 77 labels) | 0.870 | 0.425 | Jev leads on >20 options |
| ECE (lower better) | 0.246 | 0.081 | 3× better (post-temperature) |
| p50 latency, 1 question | 236–276 ms | 32.8 ms | 7.8× faster |
| Languages usable | no published benchmark | 45 of 51 | — |
| Weights | closed API | Apache 2.0 | — |
| Cost | $0.042 / 1M tokens | $0 self-hosted | — |
On DAIR Emotion, Jev assigned zero probability to the true label on 16% of examples — a hard failure for anything branching on confidence.
Where Jev leads
- High-cardinality label spaces (>20 options at default settings): On Banking77, Jev scores 0.870 (on 72 labels) while Laya scores 0.425 (on 77 labels at default 256-token head budget). This is an architectural token-budget constraint: options share a fixed
head_max_lenbudget (192 tokens on English, 256 on multilingual), so 77 options receive only ~3 to 4 tokens per label, causing text to become indistinguishable. Jev supports up to 255 options out-of-the-box. Whilelaya-multilingualsupports 1,024 context (and up to 8,192 in the encoder) and you can raiseagent.cfg["head_max_len"] = 512at runtime, Jev is currently better suited for 50+ options in a single prompt without tuning. - Soft distribution matching: On typed-decisions, while Laya achieves higher argmax accuracy (0.766 vs 0.727), Jev achieves higher soft accuracy (0.580 vs 0.471) against the teacher's full probability distributions.
- Out-of-the-box raw calibration: Before temperature scaling, the base checkpoint has higher raw ECE (0.213 vs 0.144). Laya achieves its 0.081 ECE after domain temperature fitting.
Full detail, including every workflow and all 51 languages: BENCHMARKS.md.
typed-decisions, measured on all three checkpoints
400 cases, 2,000 decisions, four workflows.
| model | accuracy | soft acc | Brier | ECE | score MAE |
|---|---|---|---|---|---|
laya-typed-decisions |
0.766 | 0.471 | 0.062 | 0.213 | 0.242 |
laya |
0.362 | 0.332 | 0.316 | 0.175 | 0.694 |
laya-multilingual |
0.342 | 0.326 | 0.439 | 0.285 | 0.687 |
| Jev 1.13.0 (published) | 0.727 | 0.580 | 0.148 | 0.144 | 0.391 |
| teacher self-agreement ceiling | 0.735 | ||||
| per-question majority class | 0.461 | ||||
| random guess | 0.318 |
The fine-tuned checkpoint beats Jev by 3.9 points and clears the teacher ceiling, with 2.4x
better Brier and 1.6x better score MAE. It wins on all four workflows: invoice processing
0.804, security incidents 0.766, customer service 0.764, agent-trace observability 0.730.
By primitive: noul 0.857, choice 0.733, score 0.723.
Two places it still trails Jev: soft accuracy (0.471 vs 0.580 — its argmax is better but its distributions match the teacher less well) and ECE (0.213 vs 0.144), which temperature fitting addresses.
The base checkpoints sit below the majority-class baseline (0.362 and 0.342 against 0.461). All of the capability on this benchmark comes from fine-tuning.
Multilingual (51 languages, MASSIVE intent, 20 options, random = 0.050)
laya |
laya-multilingual |
|
|---|---|---|
| English | 0.783 | 0.657 |
| 13 other languages | 0.306 | 0.451 |
| XNLI, English | 0.860 | 0.843 |
| XNLI, 14 other languages | 0.521 | 0.731 |
Across all 51 languages the English checkpoint macro-averages 0.227 with macro ECE
0.733, and only 23 of 51 languages clear 3x random. Khmer scores 0.000 at 95.2%
confidence. This is why Router exists: the
model's own confidence gives no warning, so the routing decision has to be made before the
forward pass.
English tasks
| task | laya |
laya-multilingual |
note |
|---|---|---|---|
| AG News | 0.947 | 0.937 | in training mix |
| BoolQ | 0.830 | 0.787 | in training mix |
| DAIR Emotion | 0.573 | 0.513 | held out |
| prompt-injections | 0.698 | 0.578 | held out, n=116 |
| SST-5 (ordinal) | 0.372 | 0.282 | held out |
Calibration
Both checkpoints are over-confident as shipped. Refitting one temperature per (question type,
option count) on held-out data moves mean ECE 0.466 -> 0.081 (laya) and
0.314 -> 0.106 (laya-multilingual). laya-multilingual ships with no fitted
temperatures at all, so fit them before relying on its probabilities.
Honest limits
- The base checkpoints are near chance on typed-decisions zero-shot -- 0.362 and 0.352 against a 0.318 random baseline and a 0.461 majority-class baseline. The 0.766 figure comes from the checkpoint fine-tuned on that benchmark's own training split. Laya is a fast base to specialise, not a zero-shot decision engine.
- High-cardinality choice questions and token budgets: Sequences split into an option prompt budget (
head_max_len) and the remaining document/state budget (max_len - head_max_len):laya(English) defaults to 512 context (head_max_len = 192, ~320 tokens for state).laya-multilingualandlaya-typed-decisionsdefault to 1,024 context (head_max_len = 256, ~768 tokens for state; mmBERT-base encoder supports up to 8,192 with RoPE). At default settings, a 77-option question like Banking77 allocates only(256 - 16) // 77≈ 3–4 tokens per label, which causes accuracy to fall off sharply (0.425 vs Jev's 0.870). If evaluating 50+ options in a single question:
- Raise
agent.cfg["head_max_len"] = 512andagent.cfg["max_len"] = 1024(or up to 2048 / 4096 / 8192) so every option has enough tokens to remain distinct. - Or split large option sets into a two-step coarse-to-fine hierarchical choice.
- Ordinal
scorequestions are the weakest primitive (SST-5 0.372). layacollapses outside English;laya-multilingualis weaker on English. Route, or pick deliberately.
Live Demo & Resources
- Hugging Face Model: convaiinnovations/laya
- Interactive Web Demo: convaiinnovations/laya-demo
- Engineering Writeup: Read the full story on Dev.to
Fine-Tuning
Fine-tune Laya on your own domain data. The notebook runs on Kaggle's free 2xT4 GPUs and does the whole loop: build the dataset, train with RLCD (proper-scoring-rule rewards, GRPO-style policy gradient), fit calibration temperatures, evaluate, and push the result to the Hub.
Fine-tuning is where most of the value is. On the typed-decisions benchmark the base checkpoints score near chance zero-shot (0.36 and 0.35 against a 0.318 random baseline), while the fine-tuned checkpoint reaches 0.766 on the same 2,000 decisions -- above TypeSafe Jev's published 0.727 and above the 0.735 teacher self-agreement ceiling. Treat Laya as a fast base to specialise, not as a zero-shot decision engine.
Runtime on 2xT4 is roughly 4-5 hours for 4 epochs over ~30k questions.
Support the Project
If Laya helps your research or products, consider supporting independent research:
License
Apache 2.0. Developed by Convai Innovations.
1 maintainer

Release files for laya 0.3.4
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| laya-0.3.4.tar.gz | 49.8 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| laya-0.3.4-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 84.0 kB
Release files / laya-0.3.4.tar.gz
| Download URL | laya-0.3.4.tar.gz |
|---|---|
| Size | 49.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
e0da594d77d2c491aedd3381757052b251a953fc27f03733dcb1c8e761246f3e
|
|
BLAKE2b-256 checksum How to use checksums |
64a02e9f82f537ae409a176d19406ba1ae64c4e51f171359e60acb8ba0bd6440
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 20, 2026.
Transparency logRelease files / laya-0.3.4-py3-none-any.whl
| Download URL | laya-0.3.4-py3-none-any.whl |
|---|---|
| Size | 34.2 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
8bf1c5cc5cbf6abebf63a6346b4babedd5692f88a75aa9e0cc01ed4145a9a14b
|
|
BLAKE2b-256 checksum How to use checksums |
09b40f22ac636d2545e6f4a7fcaf3a65bc2715ff1db3a667bc5b930e4f40c057
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Sep 20, 2026.
Transparency log













