
LiteALPR

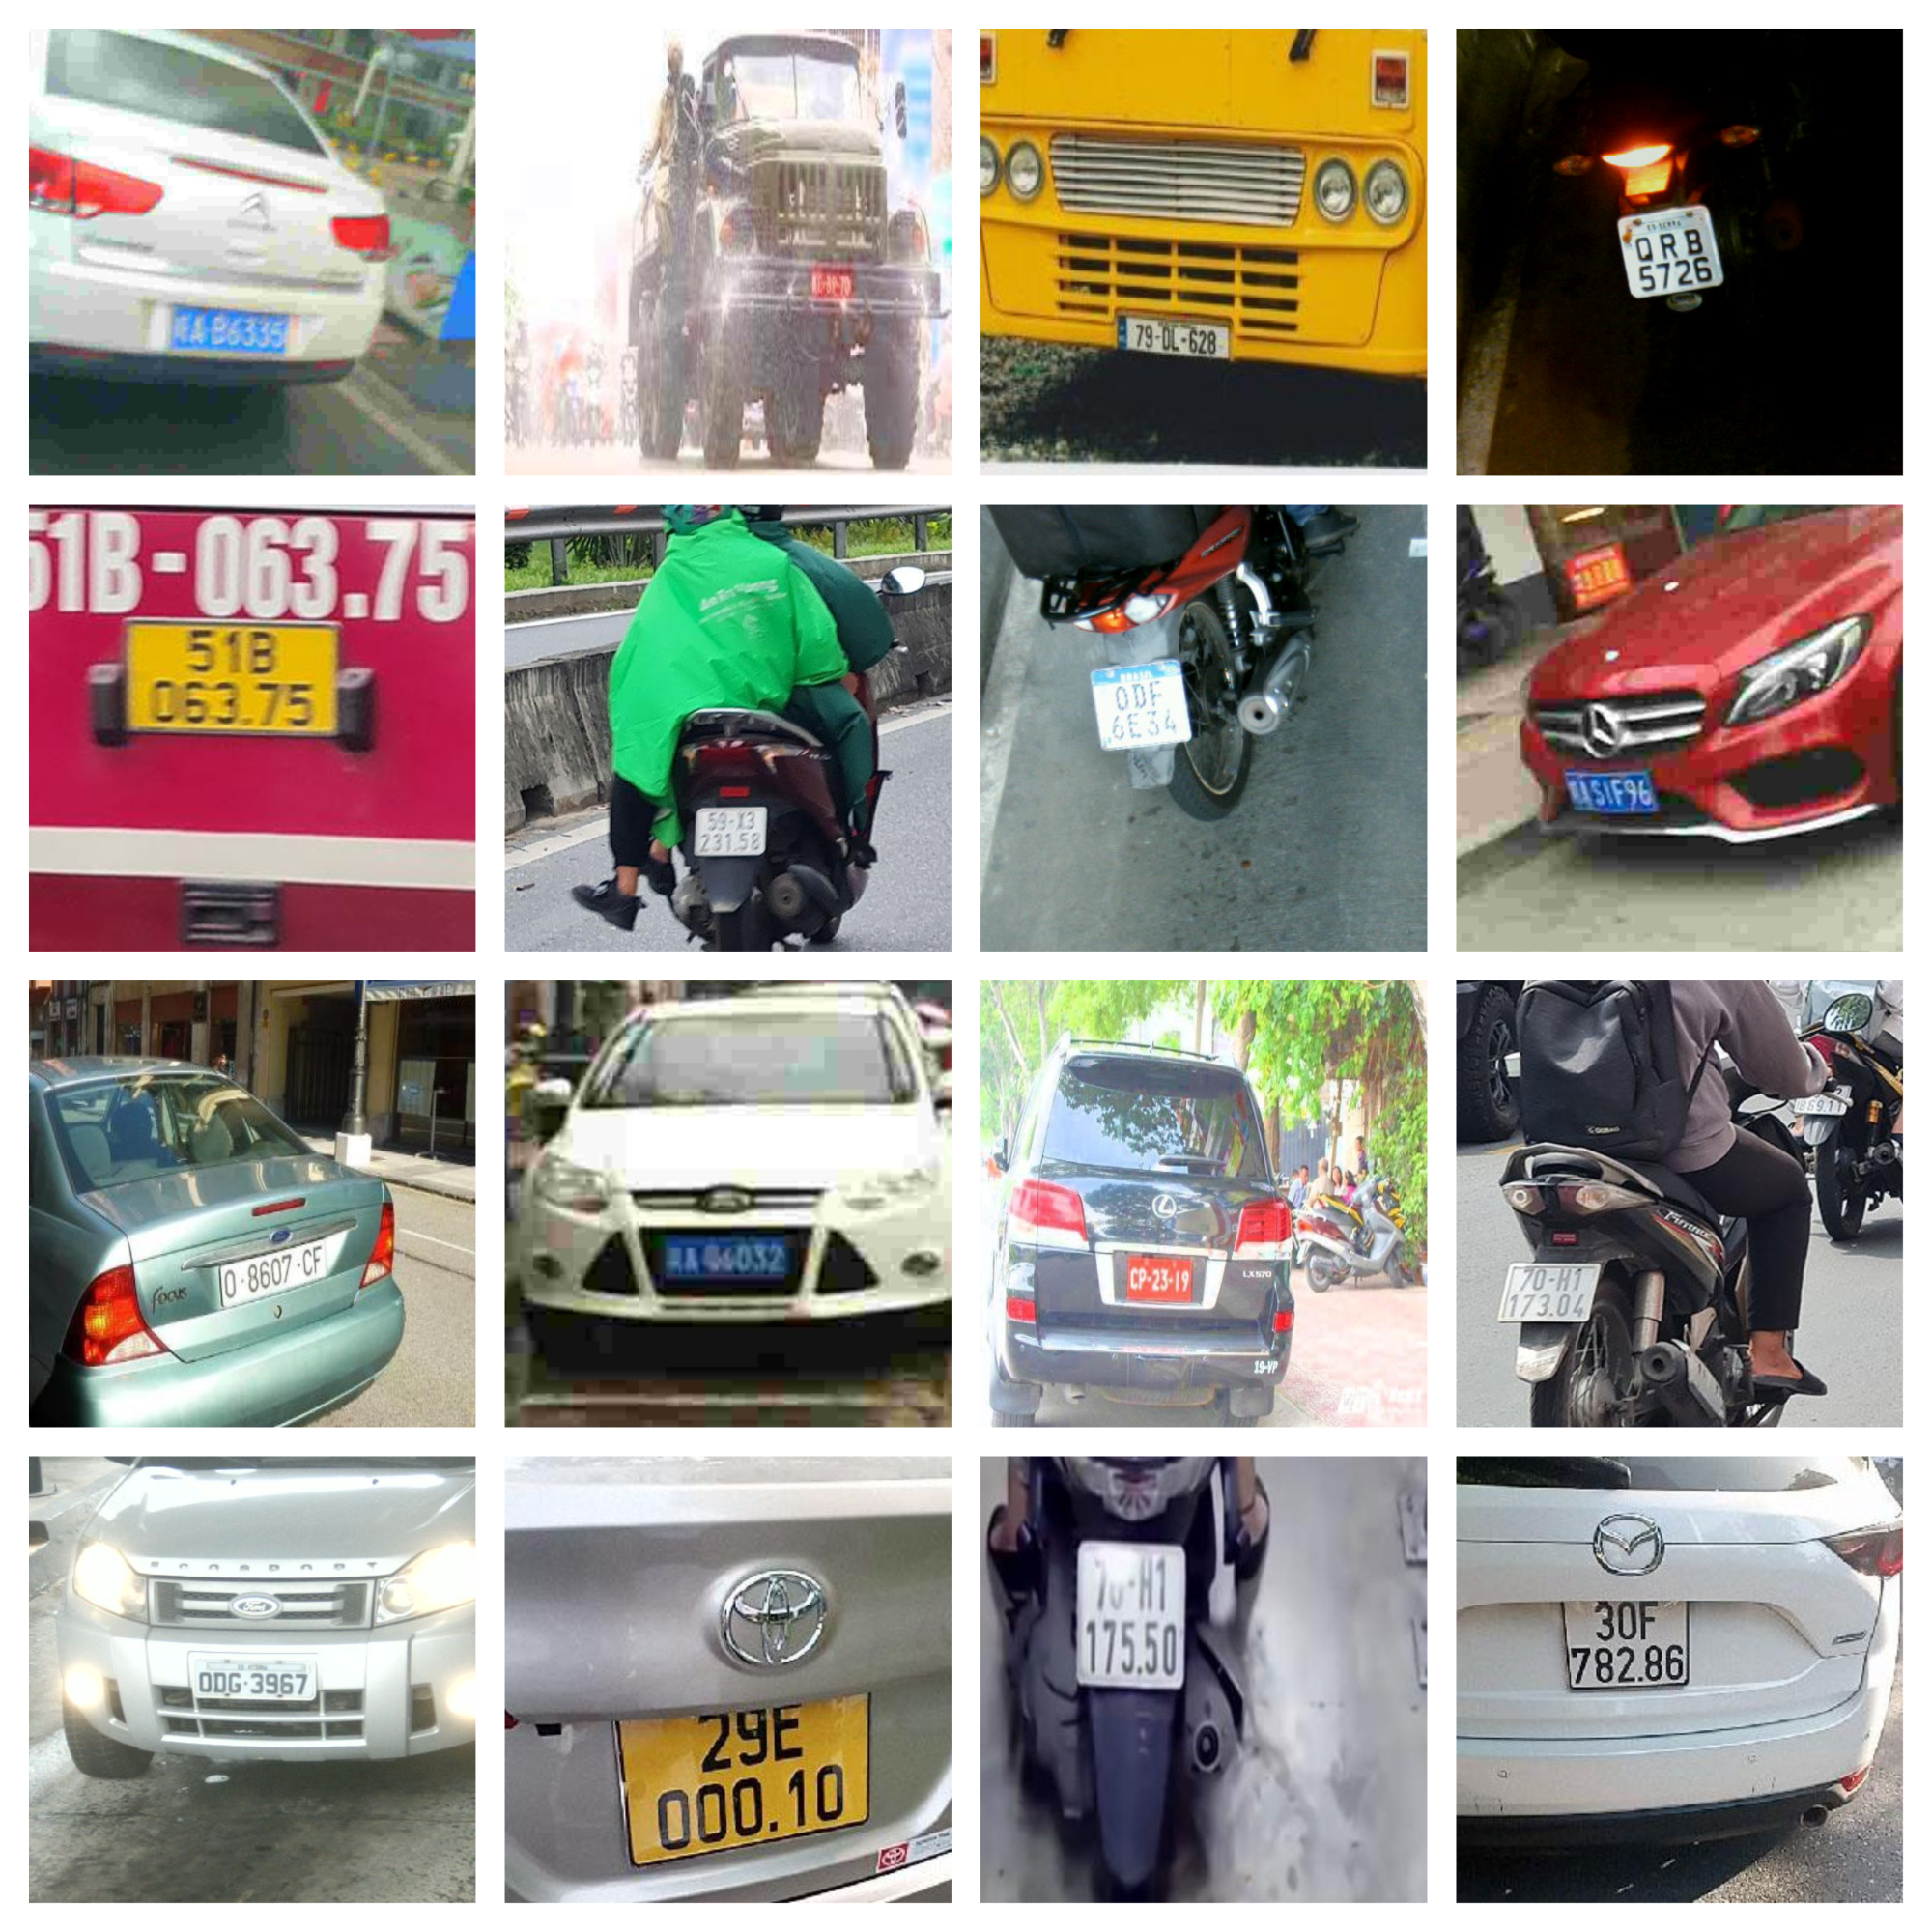
Visual samples of challenging real-world license plates (motion blur, diverse layouts, low light) that LiteALPR is built to handle.
🚀 LiteALPR is a lightweight, accurate, and flexible End-to-End License Plate Recognition library.
Unlike traditional ALPR (Automatic License Plate Recognition) systems that rely on heavy architectures, LiteALPR introduces structural improvements designed specifically for high-throughput applications. Our framework achieves fast inference speeds without sacrificing accuracy on blurry or degraded license plates through two major architectural optimizations.
📑 Table of Contents
- 🧩 LiteALPR Pipeline
- 🛠 Installation
- ⚡ Quick Start
- 🏋️ Training & Evaluation
- 🤝 Acknowledgements
- 📜 License
- 📧 Contact
🧩 LiteALPR Pipeline
The framework is structured as a highly optimized two-stage sequential pipeline:
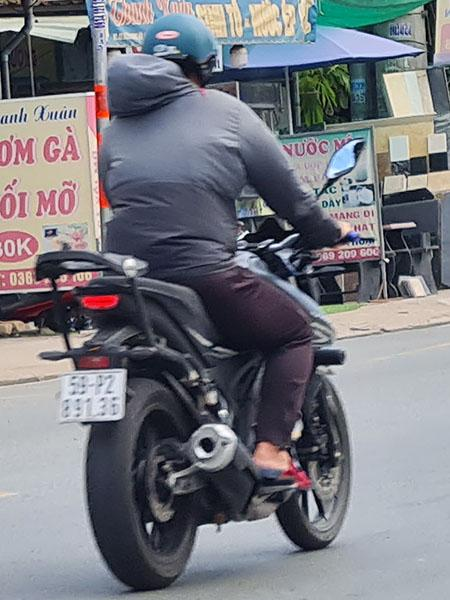

59P289136
Overview of the proposed highly optimized two-stage ALPR pipeline.
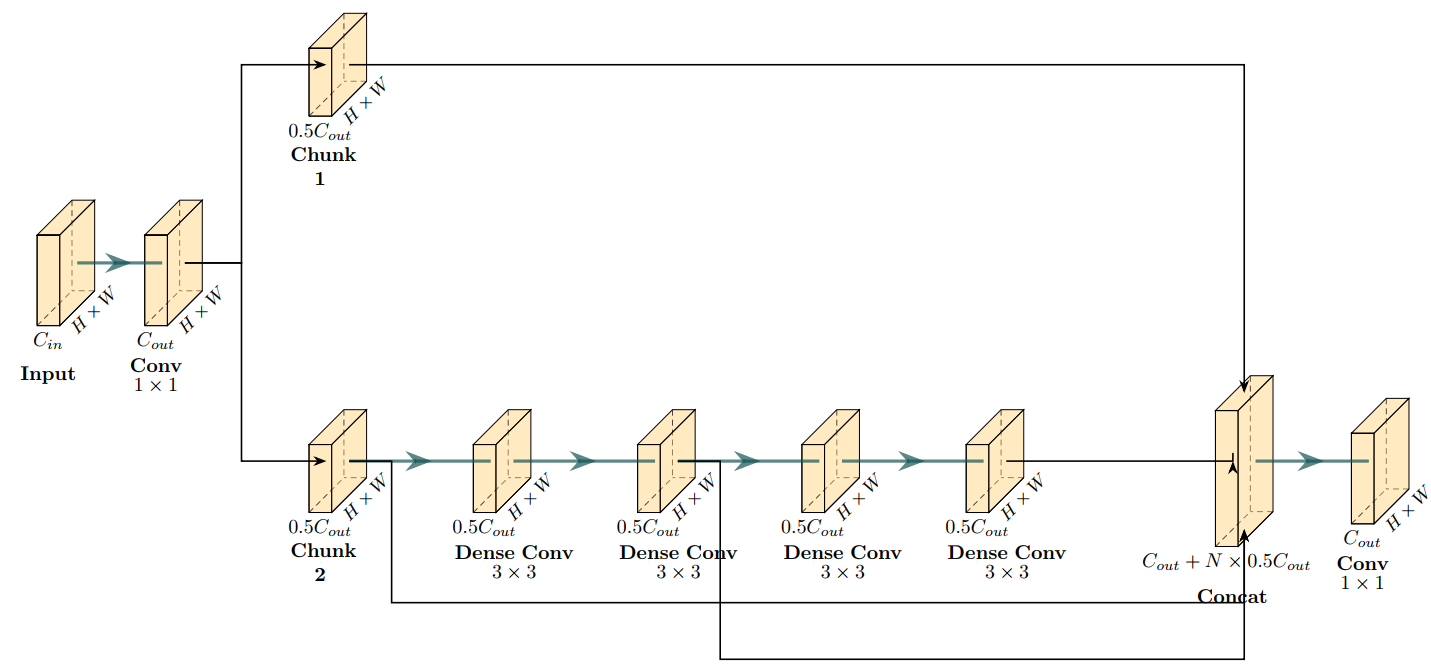
1. YOLOv8n-Efficient for Fast Detection
We replaced the original heavy C2f blocks in the YOLOv8 neck with lightweight C3Ghost blocks.
| Original: Heavy C2f Block | Proposed: Lightweight C3Ghost Block |
|---|---|
 |
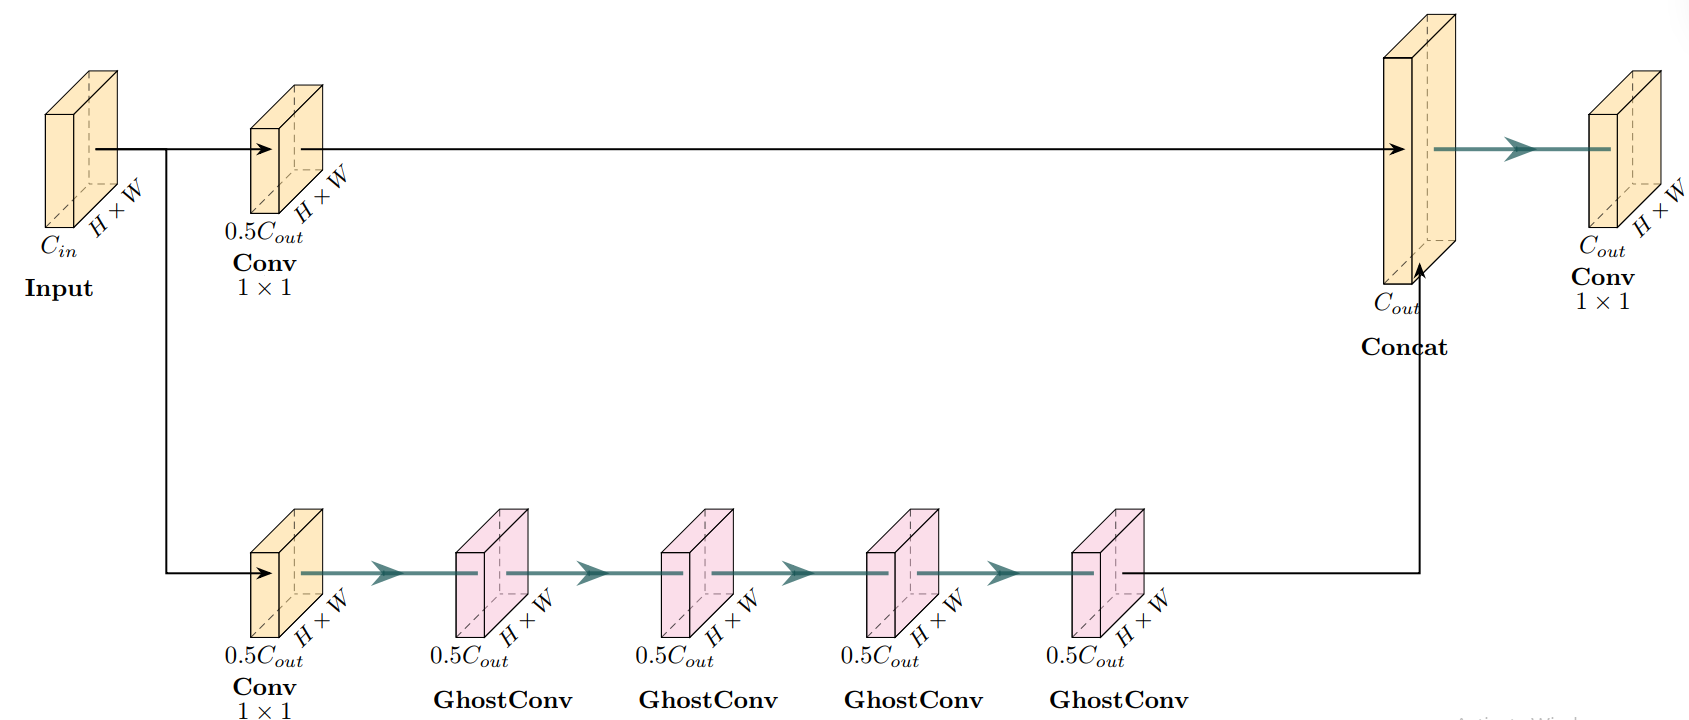 |
Leveraging Ghost modules, this architectural enhancement significantly increases detection speed while maintaining high localization accuracy. By generating more feature maps from cheap operations, it eliminates computational redundancy, enabling highly efficient performance on consumer-grade hardware without compromising precision.
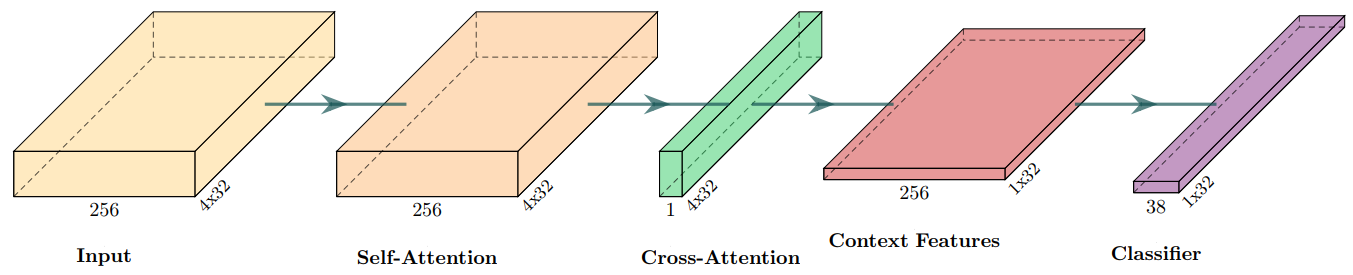
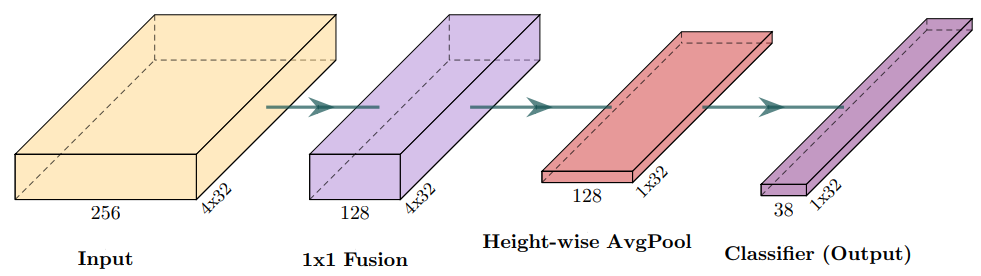
2. SVTR26-Tiny for Fast Recognition
To make the SVTR26 OCR model viable for strict high-speed constraints, we applied a key modification:
- Efficient RCTC Decoder: We entirely discarded the Original heavy attention-based RCTC Decoder. Since license plates have a rigid, horizontally aligned structure, we replaced 2D attention with a simple Height-wise Average Pooling operation. This elegantly compresses the 2D features into a 1D sequence, completely bypassing expensive matrix multiplications.
| Original: Heavy RCTC Decoder | Proposed: Efficient RCTC Decoder |
|---|---|
 |
 |
By integrating these specialized components, LiteALPR delivers robust production-ready performance, processing frames efficiently in high-throughput pipelines.
🛠 Installation
# Standard installation (auto-detects & configures runtime at first run)
pip install litealpr

# Or explicitly specify your target runtime environment:
pip install litealpr[cpu]  # CPU (ONNX) Inference
pip install litealpr[gpu]  # NVIDIA GPU (ONNX) Acceleration
(Note: When using standard pip install litealpr, LiteALPR automatically detects your device hardware and configures the corresponding ONNX Runtime execution engine and Hugging Face pre-trained weights upon initial execution).
⚡ Quick Start
LiteALPR automatically downloads the best pre-trained models from our Hugging Face repository the first time you run it. You don't need to manually configure any paths!
1. End-to-End Recognition (CPU & GPU)
from litealpr import LiteALPR

# Option A: Automatic device selection (GPU if available, else CPU)
model = LiteALPR()

# Option B: Explicitly select target execution device
# model = LiteALPR(device="cpu")     # CPU (ONNX) Inference
# model = LiteALPR(device="cuda:0")  # NVIDIA GPU (ONNX) Acceleration

# Read the license plate (auto-downloads pre-trained weights if not found)
results = model.read("sample.jpg")

for res in results:
    print(f"Plate Text: {res['text']} | Confidence: {res['score']:.4f}")
    print(f"Bounding Box: {res['box']}")
Device Selection: By default, LiteALPR uses
device="cuda:0"if a GPU is available, and seamlessly falls back todevice="cpu"otherwise. When using GPU acceleration with ONNX models, ensurelitealpr[gpu]is installed (pip install litealpr[gpu]).
2. Flexible API: Detect Only
If you only need to locate the license plates without reading the text:
# Disable the recognition model
model = LiteALPR(use_rec=False)
boxes = model.detect("sample.jpg")
print("Detected boxes:", boxes)
3. Flexible API: Recognize Only
If you already have a cropped image of a license plate and just want to read the characters:
import cv2
from litealpr import LiteALPR

# Disable the detection model
model = LiteALPR(use_det=False)

# Pass either image path directly or loaded numpy array
text, score = model.recognize("sample_crop.jpg")
print(f"Text: {text} | Confidence: {score:.4f}")
4. Using Custom Local Weights
LiteALPR seamlessly supports both ONNX Runtime (recommended for ultra-fast deployment) and PyTorch checkpoints (.pt / .pth):
# Option A: Load optimized ONNX models (High-Throughput)
model = LiteALPR(
    det_model_path="/path/to/your/yolov8n_efficient/best.onnx",
    rec_model_path="/path/to/your/svtr26_tiny/best.onnx",
)

# Option B: Load native PyTorch checkpoints (.pt / .pth)
model = LiteALPR(
    det_model_path="/path/to/your/yolov8n_efficient/best.pt",
    rec_model_path="/path/to/your/svtr26_tiny/best.pth",
)
Note: The pipeline automatically detects the file format based on extension (
.onnxvs.pt/.pth) and initializes the corresponding execution backend.
🏋️ Training & Evaluation
LiteALPR provides a complete suite of scripts in the tools/ directory for dataset preparation, training, evaluation, batch inference, and ONNX export.
0. Environment Setup
To use the training and evaluation tools, clone the repository and install the development dependencies:
git clone https://github.com/vn-anhnth/LiteALPR.git
cd LiteALPR

# Choose based on your runtime environment:
pip install -r requirements.lock       # Exact reference environment for reproducibility
pip install -r requirements.txt        # CPU (ONNX) Inference
pip install -r requirements-gpu.txt    # NVIDIA GPU (ONNX) Acceleration
1. Model Weights Preparation
Before training or evaluation, download the official pre-trained models from our Hugging Face repository and place them in the following structure:
LiteALPR/
└── pretrained_models/
    ├── det/
    │   └── yolov8n_efficient/
    │       └── best.pt
    └── rec/
        └── svtr26_tiny/
            └── best.pth
You can download them using wget or curl:
# Download Detection pre-trained weights
wget -O pretrained_models/det/yolov8n_efficient/best.pt https://huggingface.co/anhone3/LiteALPR/resolve/main/yolov8n_efficient/best.pt

# Download Recognition pre-trained weights
wget -O pretrained_models/rec/svtr26_tiny/best.pth https://huggingface.co/anhone3/LiteALPR/resolve/main/svtr26_tiny/best.pth
2. Data Preparation (Create LMDB)
The recognition module requires datasets to be formatted into Lightning Memory-Mapped Databases (LMDB) for fast I/O access during training.
Generate the LMDB using our CLI script:
python tools/create_lmdb_dataset.py \
    --data_dir ./dataset/rec \
    --label_files train_labels.txt val_labels.txt test_labels.txt \
    --output_dir ./dataset/rec/lmdb_data
3. Training (Det & Rec)
Before training, you must configure your dataset paths, batch sizes, and learning parameters:
For Detection (configs/det/yolov8/yolov8n_efficient.yml):
Configure your dataset paths, batch sizes, and training hyperparameters under the Global: section:
Global:
  pretrained_model: "pretrained_models/det/yolov8n_efficient/best.pt"  # or null to train from scratch
  data: "dataset/det/data.yaml"
  epochs: 50
  imgsz: 640
  batch: 256
  device: 0  # GPU ID (e.g. 0), or list for multi-GPU (e.g. [0, 1] or more)
  project: "output/det/yolov8n_efficient"
  workers: 8
For Recognition (configs/rec/svtr26/svtr26_tiny.yml):
Configure your training hyperparameters under Global: and Train: sections:
Global:
  device: gpu
  epoch_num: 150
  pretrained_model: "./pretrained_models/rec/svtr26_tiny/best.pth"  # or null to train from scratch
  output_dir: "./output/rec/svtr26_tiny/train"

Train:
  dataset:
    name: RatioDataSetTVResize
    data_dir_list: ['./dataset/rec/lmdb_data/train']
  sampler:
    first_bs: &bs 256             # Batch size per GPU
  loader:
    batch_size_per_card: *bs
    num_workers: 4

Eval:
  dataset:
    name: RatioDataSetTVResize
    data_dir_list: ['./dataset/rec/lmdb_data/val']
Once configured, start training:
# Train Detection Model (YOLOv8)
# For multi-GPU training, set device to GPU IDs (e.g. [0, 1] or more) in configs/det/yolov8/yolov8n_efficient.yml
python tools/train_det.py -c configs/det/yolov8/yolov8n_efficient.yml

# Train Recognition Model (SVTR26)
# For multi-GPU training, set nproc_per_node to the number of GPUs being used for training
torchrun --nproc_per_node=1 tools/train_rec.py \
    -c configs/rec/svtr26/svtr26_tiny.yml
4. Evaluation (Validation)
Evaluate your trained checkpoints on the validation set:
# Evaluate Detection
python tools/eval_det.py -m output/det/yolov8n_efficient/train/weights/best.pt

# Evaluate Recognition
python tools/eval_rec.py -c configs/rec/svtr26/svtr26_tiny.yml -m output/rec/svtr26_tiny/train/best.pth
5. Batch Inference
Test your checkpoints directly on directories of images (supports --save_log to save predictions):
# Infer Detection
python tools/infer_det.py -m output/det/yolov8n_efficient/train/weights/best.pt -d dataset/det/test/images --save_log

# Infer Recognition
python tools/infer_rec.py -m output/rec/svtr26_tiny/train/best.pth -d dataset/rec/test --save_log
6. Export to ONNX
Export your trained PyTorch models to the ONNX format for deployment in production environments (C++, C#, TensorRT, etc.). You can configure the ONNX operator set version via --opset (default: 12).
# Export Detection (default: imgsz=416, opset=12)
# The ONNX file will automatically be saved alongside the original `.pt` file (e.g., best_416.onnx)
python tools/export_det.py -m output/det/yolov8n_efficient/train/weights/best.pt --imgsz 416 --opset 18
# -> Expected output: output/det/yolov8n_efficient/train/weights/best_416.onnx

# Export Recognition (default: 128x32, opset=12)
# If you need it to accept dynamic width images in production, add the `--dynamic` flag
python tools/export_rec.py -m output/rec/svtr26_tiny/train/best.pth --save_path output/rec/svtr26_tiny/train/best.onnx --opset 18 --dynamic
# -> Expected output: output/rec/svtr26_tiny/train/best.onnx
🤝 Acknowledgements
- OpenOCR: LiteALPR is built upon the robust foundation of OpenOCR.
- YOLOv8 & SVTRv2: This work heavily leverages the architectural innovations from YOLOv8 for high-speed object detection and SVTRv2 for accurate text recognition.
- Read the YOLOv8 Paper
- Read the SVTRv2 Paper
- Datasets: Our evaluation utilizes datasets from Brazil (RodoSol-ALPR), China (CBLPRD-330k), and Vietnam public collections alongside self-collected traffic footage. We sincerely thank the original authors of these datasets for advancing the ALPR research community.
📜 License
This project is open-sourced under the GNU Affero General Public License v3.0 (AGPL-3.0).
📧 Contact
For any questions or issues, please open an issue or contact: anhnth.25ai@ou.edu.vn.
1 maintainer

Metadata
1 maintainer
Release files for litealpr 0.1.7
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| litealpr-0.1.7.tar.gz | 27.5 MB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| litealpr-0.1.7-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 27.6 MB
Release files / litealpr-0.1.7.tar.gz
| Download URL | litealpr-0.1.7.tar.gz |
|---|---|
| Size | 27.5 MB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
a9a06f98d48d608a8fecc7876f6a2fe102987fe9a749f47ac555e6eb46b9d00b
|
|
BLAKE2b-256 checksum How to use checksums |
2e3572e8701a95846b92ad18f1e80c5ff68c5ff33246ab098a3434e7b6072d92
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.8.10
|
Release files / litealpr-0.1.7-py3-none-any.whl
| Download URL | litealpr-0.1.7-py3-none-any.whl |
|---|---|
| Size | 55.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
cc0218a391705f28076b4ea54745e08b9382e50cd4d724c020c683de749b0da6
|
|
BLAKE2b-256 checksum How to use checksums |
dd3c61ce1c677b70b4739cb5c24aa257f239ec331d3ae08762cb38d71bcfbb7b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.1.0 CPython/3.8.10
|














