
LLM Light: Auto-Warmer & Hybrid RAG Chat CLI
Renamed from
claude_light. The tool runs Claude, Gemini (viaagy) and Codex, so the name isllm_light. The old names are no longer read: runllm-light(orpython llm_light.py), renameCLAUDE_LIGHT_*environment variables toLLM_LIGHT_*, and rename~/.claude_light_automation_token,~/.claude_light_stats.jsonand~/.claude_light_sessions/to their~/.llm_light_*names. Startup prints one line for each old setting or file it still finds. See docs/CONFIG.md.
llm_light.py is an interactive CLI chat tool for querying and editing a codebase using Claude, Gemini or Codex. By combining Anthropic's prompt caching with a highly optimized hybrid RAG (Retrieval-Augmented Generation) pipeline, it drastically reduces API costs while maintaining full context of your project.
License: Free for personal and hobby use (PolyForm Noncommercial). Commercial use requires a license — contact Peter Isberg.
📊 Real-World Benchmark Results
Measured against 4 popular Python open-source libraries, running the same 10 queries per repo with each tool (live API runs, 2026-03-23).
Claude Code = the Anthropic CLI (claude --print), each query in a fresh isolated session using its built-in tool-calling to fetch files on demand.
llm_light = this project — hybrid RAG + prompt caching with automatic model routing.
Cost per 10 queries — Claude Code vs llm_light
| Repository | Repo size | Claude Code | llm_light | Savings |
|---|---|---|---|---|
psf/requests v2.31.0 |
108K tokens | $0.91 | $0.23 | 75% |
pallets/flask 3.0.0 |
144K tokens | $1.62 | $0.17 | 89% |
encode/httpx 0.25.2 |
191K tokens | $1.75 | $0.45 | 74% |
bottlepy/bottle 0.13.2 |
92K tokens | $1.52 | $0.30 | 80% |
| Total (≈40 queries) | $5.81 | $1.16 | 80% / 5× cheaper |
Why Claude Code costs more
Claude Code is a powerful general-purpose agentic tool and the cost difference reflects that:
- Its built-in system prompt and tool definitions consume ~35–40K tokens per session (cached, but cache-reads still cost $0.30/M).
- It always uses Sonnet, even for simple lookups where Haiku would suffice.
- Multi-turn tool calls (2–14 turns per query) accumulate cached context with each round-trip.
- It rediscovers the codebase via tools on every session — no pre-indexing.
llm_light makes different trade-offs: pre-indexes the codebase offline, routes simple queries to Haiku, and injects only ~2–3K targeted tokens per query.
How to reproduce:
python tests/benchmarks/benchmark_cost.py --json > cl_results.json, thenpython tests/benchmarks/benchmark_claude_code.py --llm-light-results cl_results.json. Both make live API calls, and the second needs Claude Code installed. Seedocs/BENCHMARKS.mdsection 4 for the methodology.
📉 How It Optimizes Token Usage
This tool is aggressively designed to prevent you from paying full price for tokens. It tackles context bloat and cache expiration through several core strategies:
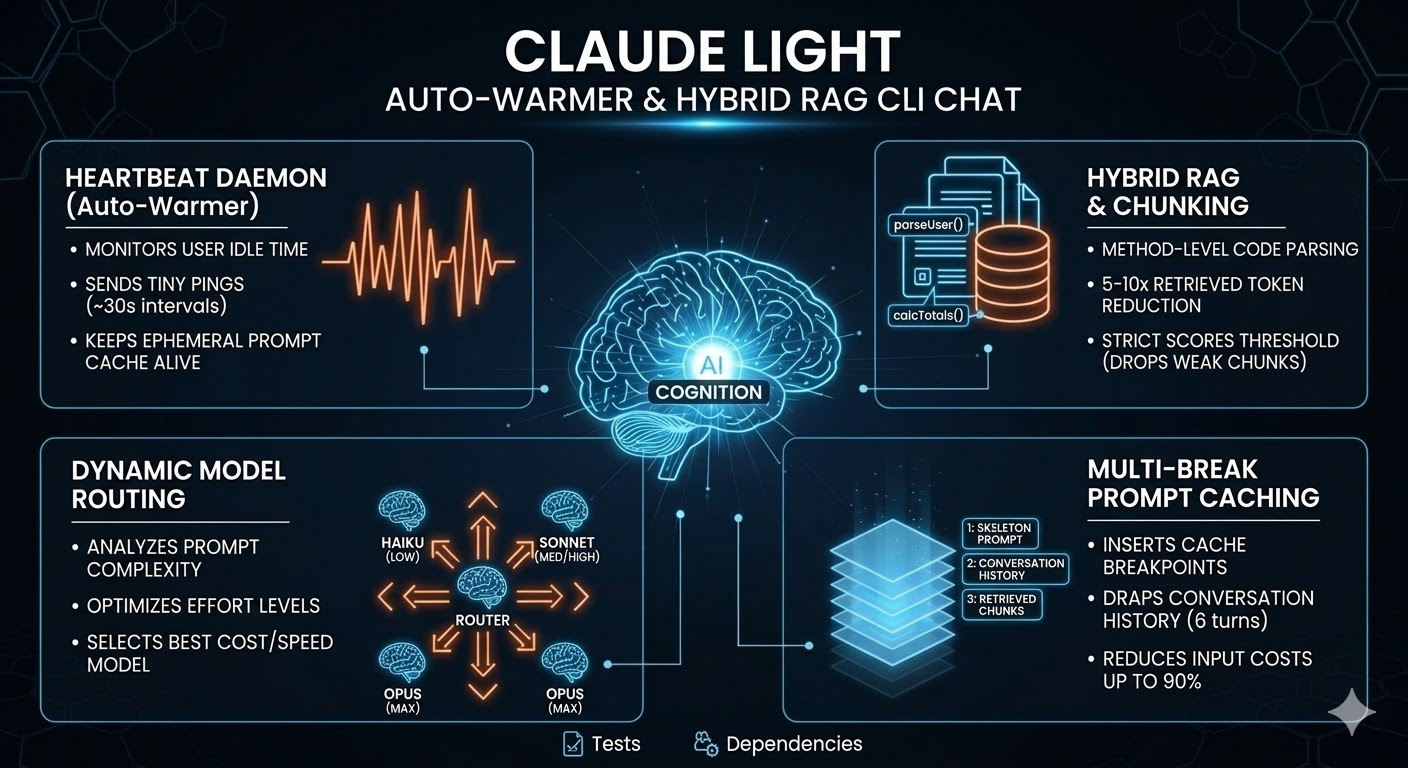
- Hybrid RAG + Prompt Caching: The tool uses a two-tier caching strategy. The project's directory tree and its
.mdfiles act as a cached "skeleton" system prompt. With Claude onlyCLAUDE.md,AGENTS.mdand the rootREADMEgo in, and the model opens other docs from the tree when a question needs them; Gemini and Codex cannot open files, so they get an excerpt of every.mdfile. In a git repository only the.mdfiles git tracks go in (staged ones included): a local draft you have not added stays out of every request, though the tree still lists it. - Three-Tier Prompt Caching: The tool places three
ephemeralcache breakpoints in every request: (1) after the skeleton system prompt — stable for the whole session; (2) after the conversation history — stable for all but the newest turn; (3) after the retrieved RAG chunks in the current user message — stable across consecutive questions about the same code area. If you ask follow-up questions about the same module, the chunk block hits the cache and only your new question text is billed at full price ($2.00/M on Sonnet 5.5); everything above it costs the cache-read rate ($0.10/M). - The "Heartbeat" Auto-Warmer: In API-key mode, a background daemon checks the session every 30 seconds and, once 55 minutes have passed since the last turn or warm, sends one
max_tokens=0request that re-reads the skeleton's 1-hour cache entry and so resets its timer. An idle hour costs one cache read. It warms the model your turns use, and nothing before that model is known. (OAuth/Pro-subscription mode skips the heartbeat: each turn already spawns a freshclaudeCLI subprocess, so there is no persistent process to warm — the Anthropic backend's content-hashed prompt cache still hits across subprocess invocations on its own.) - Method-Level Chunking: Instead of stuffing entire 1,500-line files into the context window, a brace-depth scanner splits source files into one chunk per method or constructor. Each chunk retains its package, imports, and class header to remain self-contained. This provides a massive 5–10× reduction in retrieved tokens.
- One CLI Session on the Subscription: A subscription turn continues the same
claudeCLI session instead of writing the whole history to the cache again, and the agent keeps the files it already read. Measured live on 8 paired sessions: 25% lower API-equivalent cost and 42% fewer cache writes, for 63% more cache reads, so total input tokens rise 44%. Answers held up (6 wins, 8 losses, 34 ties, judged by Opus).LLM_LIGHT_CLI_RESUME=0turns it off. - Sliding Window History: To prevent conversation history from growing unboundedly and costing you on every turn, the tool caps memory at the last 6 turns via the
MAX_HISTORY_TURNSsetting. - Strict Scoring Threshold: Two filters drop low-quality chunks before sending them to Claude.
MIN_SCORE(0.35) is an absolute cosine-similarity floor (natural-language questions score lower against code than keyword queries), andRELATIVE_SCORE_FLOOR(0.60) drops any chunk whose score is below 60% of the top-ranked chunk for that query. Together they prevent a single weak query from dragging in noise alongside one strong hit. - Compressed Skeleton Tree: The directory tree sent in the cached system prompt is compacted in two ways: single-child directory chains are collapsed (
main/java/com/example/on one line), and sibling files sharing an extension are brace-grouped ({OrderService,UserService,PaymentService}.java). This saves 30–50 % of skeleton tokens on typical Java/Go/Python projects. - Retrieved-Chunk Deduplication: When multiple methods from the same file rank highly, the shared preamble (package, imports, class header) is emitted only once, with all retrieved methods listed underneath. This saves 5–20 % of retrieved-context tokens on class-heavy queries.
For a deeper dive into the implementation, see docs/architecture/.
🚀 Getting Started
llm_light supports two ways to authenticate. If you are a Claude Pro subscriber, it will automatically detect your CLI session. For the best experience on Windows, we recommend a one-time setup of a long-lived Automation Token (claude setup-token) which provides a permanent, headless-friendly connection.
Note:
sentence-transformerspulls in PyTorch, which is approximately 1.5 GB on the first install.
Install as a tool (recommended)
If you have pipx or uv installed, the fastest path is to install llm-light-cli from PyPI as a globally-available CLI in its own isolated environment. It installs the llm-light command:
# pipx
pipx install llm-light-cli

# uv
uv tool install llm-light-cli
Then run from any project root:
llm-light                 # interactive
llm-light "what does OrderService do?"   # one-shot
Optional extras:
pipx install "llm-light-cli[llmlingua]"
pipx install "llm-light-cli[mcp]"        # MCP servers with an API key (see below)
LLMLingua compresses retrieved context only when it is at least LLM_LIGHT_LLMLINGUA_MIN_TOKENS tokens long (default 800). The retrieval budgets are 1 500 to 9 000 tokens, so a full retrieval always qualifies; lower the value only if small retrievals should be compressed too. The first compression loads a model (about 280 MB) on CPU, which takes around 10 seconds.
To run the unreleased main instead of the latest release, install from GitHub: pipx install git+https://github.com/PIsberg/llm-light.git. Releases are listed in CHANGELOG.md. The methods below run from a source checkout.
Quick Start
- Install Dependencies:
pip install -r requirements.txt
- Authenticate (Pick One):
- Claude Pro: Run
claude auth loginORclaude setup-token(recommended for Windows persistence). - API Key: Set
export ANTHROPIC_API_KEY=sk-ant-...in your shell.
- Claude Pro: Run
- Run:
python llm_light.py
macOS (Automated)
# Clone or download the repo, then:
bash installers/install_macos.sh
The macOS installer handles the details specific to macOS:
- Detects Apple Silicon (
/opt/homebrew) vs Intel (/usr/local) Homebrew paths - Installs Python 3.12 via Homebrew if no 3.12+ interpreter is found
- Creates a
.venvvirtual environment to avoid the PEP 668 "externally managed" error on macOS 13+ - Generates a
run.shwrapper so you don't need to activate the venv manually - Reminds you to add the key to
~/.zshrc(macOS default shell)
# Set API key (zsh — macOS default since Catalina)
echo 'export ANTHROPIC_API_KEY=sk-ant-your-key-here' >> ~/.zshrc && source ~/.zshrc

# Run from your project root
cd /path/to/your/project
/path/to/llm_light/run.sh
Linux
# Clone or download the repo, then:
bash installers/install.sh
export ANTHROPIC_API_KEY=sk-ant-your-key-here
The script finds a Python 3.12+ interpreter and installs everything in requirements.txt via pip.
Windows (PowerShell)
# Allow scripts for this session, then run the installer:
Set-ExecutionPolicy -Scope Process -ExecutionPolicy Bypass;
.\installers\install.ps1
[System.Environment]::SetEnvironmentVariable("ANTHROPIC_API_KEY","sk-ant-your-key-here","User")
Manual installation
Python 3.12 or newer. Install everything in requirements.txt:
pip install -r requirements.txt
Without tree-sitter, chunking falls back to whole-file mode. Without rich, output degrades gracefully to plain text formatting.
🔑 API key
🔑 Authentication
llm_light is designed to be flexible with how you pay for tokens. It resolves your identity in this order:
- Environment Variable:
ANTHROPIC_API_KEY(Standard API Key) - Local Dotfiles:
.anthropic(home dir) or.env(project dir) - Claude CLI Config (OAuth): Automatically reads your Claude Pro session from
~/.claude/.credentials.json.
Other providers: Gemini and Codex
python3 llm_light.py --provider gemini or --provider codex sends the same skeleton and retrieved chunks to that tool's CLI instead of Claude. Without --provider nothing changes.
- Gemini: runs Google's Antigravity CLI
agy(install: https://antigravity.google) and sign in by runningagyonce. llm_light denies agy's shell, MCP and file tools per run and starts agy with an empty home directory, so your agy plugins, hooks, rules and MCP servers are not loaded (your chosen agy model and your sign-in are kept). agy runs as a custom agent with no tools at all (excludeDefaultComponents), so itssearch_webcannot put your code into web-search queries; if a search ever runs anyway, the turn fails instead of answering. agy also sends its own telemetry toplay.googleapis.comon every turn, more bytes than the model request: error reports with stack traces, agy's built-in prompt templates and session ids. In two decrypted turns (agy 1.5.1 and 1.5.5, #175) neither the question nor the project's code was in it; llm_light has no setting that turns it off. - Codex: install
codex(npm install -g @openai/codex) and runcodex login. llm_light replaces codex's own agent instructions with a short no-tools note and switches off the codex features it never uses, which took one measured question from a mean of 21,766 to 9,190 input tokens (see docs/BENCHMARKS.md, section 2e). - Unavailable there: prompt caching, effort routing, the top-tier prompt,
/budget, cost figures, and shell access. Gemini and Codex show the token counts they report (input, cached, output), with no dollar figure. Each says so when you use it. Each tool runs in an empty temporary directory, so it answers from what llm_light sends and does not read or run anything in your repo. - Sessions: saved per provider;
--continuewith another provider's file starts fresh and names the provider to resume.
Option A: Claude Pro Subscription (OAuth)
If you have a Claude Pro or Team subscription and have authorized the official Claude CLI, llm_light will automatically use your flat-rate subscription.
- Cost: Included in your $20/mo subscription.
- Setup: Just run
claude auth loginonce. - Instructions it sees: the repo's own
CLAUDE.mdfiles are loaded; your personal~/.claude/CLAUDE.mdis not, even when the repo lives under your home directory, so instructions written for your own Claude Code setup do not leak into llm_light's agent. - Other directories: the agent reads only the project. To let it read a sibling repository or a shared library too, start with
llm_light.py --add-dir ../shared-lib(repeatable) or type/add-dir ../shared-libat the prompt, which applies from the next turn for this session;/add-diralone lists them. The agent may useRead,GrepandGlobthere, in every permission mode, but not write: an edit outside the project would skip llm_light's diff, commit and/undo. Each question names the directories, so the agent knows to look. A directory inside the project, a drive root, or a path with a comma or parenthesis is refused. With an API key llm_light's ownread_file,list_filesandgrepreach them instead: the question tells the model to pass an absolute path, or a grep glob that starts with the directory, and those results come back with absolute paths. With Gemini or Codex, which get no file tools, llm_light says it has no effect. - Web access: on a subscription the agent cannot search the web or fetch a page unless you start with
llm_light.py --web(orLLM_LIGHT_WEB=1); then it may use theclaudeCLI'sWebSearchandWebFetchin every permission mode, plan mode included, without asking. It is off by default because a turn reads text from the repo, and a fetched URL can carry what the agent read out of your machine; use it on repositories you trust. Bypass mode already includes both tools. It adds about 1,000 input tokens to every model round (4,251 to 5,235 on a one-word question, mostly cache reads). With an API key it adds Anthropic's server-runweb_searchandweb_fetchtools instead (the basic versions on Haiku), which the model calls without asking; a search bills $0.01 on top of tokens, at most 5 per request, and/budgetand/costcount it. The searches show as they run, and a failed one shows its error. With--provider geminiorcodex,--webhas no effect and llm_light says so at startup. - Running commands: the agent edits files without asking but runs no shell commands by default. To let it run some, such as your tests so it can check its own changes, allow command prefixes (read-only commands like
git statusthen work too): type/allow python -m pytestat the prompt, which applies from the next turn and is remembered for this project (outside the repo, and named at each start;/disallow <prefix>takes it back), or start withllm_light.py --allow-command "python -m pytest"(repeatable) orLLM_LIGHT_ALLOW_COMMANDS="python -m pytest; npm test". A PowerShell command takes apowershell:tag, e.g.--allow-command "powershell: Invoke-Pester", and runs under the PowerShell tool; untagged entries (andbash:) run under Bash. An entry allows any command that starts with it, so preferpython -m pytesttopython, which lets the agent run any Python code. A command that chains, pipes, redirects or substitutes (any of;,&,|,<,>, a backtick,$or a newline) is refused, sonpm test && rm -rf xdoes not run therm. PowerShell commands also refuse(,),{,}and@, because PowerShell evaluates an argument such as(New-Item x); the agent runs one simple command per call. With an allowlist the agent edits files with its own tools so it can run the tests on its change before it finishes; llm_light then shows the diff and commits it (/undoreverts). Without one, edits come back as SEARCH/REPLACE blocks that llm_light lint-checks, previews and applies. Anything else is refused, and llm_light lists the refused commands after the turn. Permission rules, hooks and MCP servers configured inside the repo you are working on are ignored, so a cloned repo cannot grant itself commands. - Long tasks: each turn runs the CLI's own agent loop (it can read and edit files itself), so a multi-file change can take several minutes. Each file it reads, searches or edits is shown as it happens (
⏺ Read llm_light/llm.py). Press Esc (or Ctrl+C) to cancel a turn: the agent process is stopped and you are back at the prompt, with anything you typed meanwhile already in it (files it already changed stay in the working tree, uncommitted). The turn is also cancelled if the CLI produces no output for 5 minutes, or after 1 hour in total. On the very first run the index is still being built (several minutes on a CPU); you can ask questions immediately and they go to the agent without retrieved context until the index is ready. One-shot runs (llm_light.py "question") do the same: the answer comes first, then the index finishes building before the process exits, so the next run has it.
Option B: Anthropic API Key
If you prefer to pay per-token or don't have a Pro subscription:
- Cost: Usage-based (Pay-as-you-go via the Anthropic Console).
- Files beyond the retrieved context: the model can call three read-only tools,
read_file,grepandlist_files, confined to the project directory and any--add-dirdirectory, when retrieval missed the code it needs (up to 8 rounds per turn). It cannot run commands; edits still come back as SEARCH/REPLACE blocks that llm_light lint-checks, previews and commits. - Setup: Set the environment variable:
# Linux / macOS
export ANTHROPIC_API_KEY=sk-ant-your-key-here

# Windows PowerShell (persistent)
[System.Environment]::SetEnvironmentVariable("ANTHROPIC_API_KEY","sk-ant-your-key-here","User")
Through a proxy, such as the llm-fw firewall
To watch or filter what llm_light sends, route its model traffic through an HTTPS proxy. For a local llm-fw (run llm-fw setup once, then llm-fw start):
python3 llm_light.py --llm-fw
That is short for --proxy http://127.0.0.1:8080 --proxy-ca ~/.llm-fw/ca.crt. For another proxy, or llm-fw on another machine, give both: --proxy http://llm-fw:TOKEN@192.168.1.50:8080 --proxy-ca /path/to/llm-fw-ca.crt, or set LLM_LIGHT_PROXY and LLM_LIGHT_PROXY_CA. A startup line names the proxy (password hidden). The traffic then shows on the llm-fw dashboard at http://localhost:7731.
- What goes through it: the Anthropic API client, and the
claude,codexandagyCLIs llm_light starts.--proxywins over anHTTPS_PROXYalready in your environment. Nothing else changes: embedding-model downloads, git and the commands the agent runs keep their own connection. - Trust: the CA is added to the public roots, not swapped in for them, so hosts the proxy only tunnels still verify. The
claudeCLI gets it asNODE_EXTRA_CA_CERTS,codexasSSL_CERT_FILE(a temporary bundle of certifi's roots plus the CA).agygets the same environment, and on Windows it needs nothing more: agy 1.4.12 accepted a certificate from a private CA with--proxy-caand rejected it without, with nothing added to the OS store. Not checked on macOS or Linux;llm-fw setupalso installs the CA in the OS store, which covers them. Without--proxy-caeach client keeps its own default trust; for the Anthropic API client that is the OS store. - Gemini needs one llm-fw setting: a stock llm-fw (checked on 0.9.4) does not treat agy's model host as an LLM target, so it only tunnels it. The turn works and shows on the dashboard, but
inspectedisfalseand nothing is scanned. To have it scanned, add the hosts to~/.llm-fw/config.json, anddaily-cloudcode-pa.googleapis.comthen showsinspected: truewithPOST /v1internal:streamGenerateContent:{ "extraTargets": ["cloudcode-pa.googleapis.com", "daily-cloudcode-pa.googleapis.com"] }
- Sinkhole mode needs none of this: llm-fw redirects the API hosts at the OS level, so only the CA trust matters.
Hooks
Run your own command around the agent's work, a formatter after each edit or a policy check before a command, by listing it in ~/.llm_light/hooks.json, in the shape of Claude Code's hooks setting:
{
  "hooks": {
    "PostToolUse": [{ "matcher": "Edit|Write", "hooks": [{ "type": "command", "command": "ruff format --quiet", "timeout": 30 }] }],
    "PreToolUse":  [{ "matcher": "Bash", "hooks": [{ "type": "command", "command": "/home/me/bin/policy-check" }] }]
  }
}
- Which file: only that one (
LLM_LIGHT_HOOKS_CONFIGmoves it), never a project's.claude/settings.json, so a cloned repo cannot choose a command to run. Your~/.claude/settings.jsonhooks do not run either: the agent starts with an empty home. Events:PreToolUse,PostToolUse,Notification,UserPromptSubmit,Stop,SubagentStop,PreCompact,SessionStart,SessionEnd. A matcher is a regular expression over the tool name; empty or*matches every tool. - On a subscription the
claudeagent runs every event as Claude Code does, after llm_light's own guard for allowed commands. The agent runs with an empty home directory, so give commands absolute paths rather than~. - With an API key llm_light runs
PreToolUseandPostToolUseitself, around its tools and after it writes an edit, under Claude Code's tool names (Read,Grep,Glob,Bash,Editfor a changed file,Writefor a new one,mcp__<server>__<tool>), so one matcher works in both modes. The command gets the event as JSON on stdin and runs from the project root. Exit 2 blocks aPreToolUsecall and its stderr tells the model why; onPostToolUsethe stderr goes to the model with the result. Any other failure, or passingtimeout(default 60 s), is noted and the call goes on. A JSON object printed on stdout counts as in Claude Code, on any exit code but 2: onPreToolUse,permissionDecisiondenyblocks with itspermissionDecisionReason(the olderdecision: "block"too), and so doesask, since nothing can be asked in the middle of a turn; onPostToolUse,decision: "block"puts itsreasonnext to the result.additionalContextreaches the model with the result andsystemMessageis shown to you.updatedInput,updatedToolOutput,continueanddeferare not acted on yet (#248). Edit hooks run before the auto-commit, so the commit holds what a formatter made of the file. /hookslists them;/doctorchecks the file without running anything.
Your own instructions
Put instructions you want in every project, such as "answer in British English" or "prefer pytest fixtures to setUp", in ~/.llm_light/instructions.md; /memory user opens it in your editor. It goes with every question, after llm_light's own prompt and before --append-system-prompt, for Claude (API key or subscription), Gemini and Codex, and an edit applies from the next turn. Startup names the file when it has text. It is cut at 8,000 characters, since it is sent every time: a one-line file added 40 tokens a request. Only that file is read (LLM_LIGHT_INSTRUCTIONS moves it), never one in a project, so a cloned repo cannot add instructions. Your ~/.claude/CLAUDE.md is still not sent: it is written for Claude Code and names tools llm_light does not have. Without the file, or with an empty one, requests are unchanged.
MCP servers
Give the agent the tools of your MCP servers (documentation lookup, an issue tracker, a database) by listing them in ~/.llm_light/mcp.json, in the shape of Claude Code's .mcp.json:
{
  "mcpServers": {
    "docs":   { "command": "npx", "args": ["-y", "some-mcp-server"], "env": { "TOKEN": "${DOCS_TOKEN}" } },
    "issues": { "type": "http", "url": "https://example.com/mcp", "headers": { "Authorization": "Bearer ${ISSUES_TOKEN}" },
                "allow": ["get_issue", "search_*"] }
  }
}
- Which file: only that one (
LLM_LIGHT_MCP_CONFIGmoves it). A project's own.mcp.jsonis never read, so a cloned repo cannot start programs or add tools. A server name is 1 to 32 letters, digits,_or-;typeisstdio(the default, withcommand,args,env),httporsse(withurl,headers).${VAR}and${VAR:-default}expand from your environment. Other keys are ignored, and an entry that does not fit is skipped with a message at startup. - Which tools may run: without
allow, every tool of a listed server runs without asking. Give a server anallowlist to narrow it: tool names, or patterns with*(search_*), matched case-sensitively;[]allows none. Use it for a server with tools that write (post a comment, push, delete a row), since a turn can be steered by text in the repo it reads. On a subscription a tool off the list is refused when the agent calls it; with an API key it is not offered at all, which also saves its definition's tokens. Anallowthat is not a list of names skips the server rather than allowing everything. The startup line names what each server may run. - On a subscription the
claudeagent starts the servers itself, on every turn, and may call any of their tools thatallowpermits. A stdio server sees your real home directory, though the agent runs with an empty one. - With an API key llm_light connects once at startup and offers each tool as
mcp__<server>__<tool>after its own. It needs themcppackage:pipx install "llm-light-cli[mcp]", orpipx inject llm-light-cli mcp. The startup line names each server's tools and what their definitions add to every request; they are cached with the rest of the prompt. The list is fixed for the session: a server that adds tools later needs a restart, and one that stops answers each call with an error. A server's stderr goes to~/.llm_light_sessions/mcp/<name>.log. A result is text: images and binary resources are named, not sent, and output is capped at 40,000 characters. - Asking first: with an API key in the default permission mode, llm_light shows each MCP call, the tool and its arguments, and runs it only on yes; "Yes, and don't ask again" covers that tool for the rest of the session.
acceptEditsand bypass run them unasked, and so does a run without a terminal (-p, piped input), where nothing can be asked: there theallowlist is the only gate. On a subscription theclaudeagent runs with-pand cannot ask either. - Plan mode runs no MCP tool, since one can change things outside the repo.
- Gemini and Codex run without tools, so they ignore the file and say so.
/mcpshows the servers and their tools;/doctorchecks the file without starting anything.
Run the script from the root of your project — it will immediately build the skeleton, chunk your files, and auto-tune the embedding model.
🚀 Usage
1. Interactive Loop (Default)
python3 llm_light.py
The prompt appears in about half a second: the index builds in the background, and the toolbar under the prompt says indexing… until it is ready, then shows the session's tokens, cache hit rate and cost. Replies stream in as rendered markdown (tables, lists, syntax-highlighted code), with a spinner and elapsed time while Claude thinks or runs a tool, and one line per file it reads, searches or edits. In the reply each proposed edit is a single ✎ edit to path line; the change itself is shown as a diff, with a menu underneath to approve them (arrow keys and Enter, or press 1/2/3; Esc says no). Keys typed before the menu appears are ignored, so a stray Enter cannot answer it. "Yes, and don't ask again" stops that one question for the rest of the session (applying edits and committing the agent's edits are remembered separately); -y approves both from the start.
Scripting
-p answers one question and exits, and a script can rely on what it prints:
git diff | llm_light.py -p "review this"             # piped text goes with the question
llm_light.py -p "what does OrderService do?" > a.md  # stdout holds the reply, nothing else
llm_light.py -p --output-format json "..." | jq -r .result
llm_light.py -p --output-format stream-json "..."    # one object per line as it happens
llm_light.py -c -p "and then?"                       # continue the saved conversation
json prints one object when the turn ends, with result, is_error, error, subtype (success, error or interrupted), model, duration_ms, num_turns, usage and total_cost_usd, the field names claude -p uses. usage and total_cost_usd are null for a provider that does not report them, never 0. stream-json prints a system init line, then text and tool events, then that same object. Progress and the turn's stats go to stderr. The process exits 0 on success, 1 on a failed turn (including an edit that still has syntax errors after 3 attempts) and 130 on Ctrl+C.
If a question is given and stdin is a pipe, llm_light waits 3 seconds for the first data, then goes on without it, so a script with an idle inherited stdin does not hang. Once data starts it reads to the end, for up to 10 minutes, and keeps the first and last 25,000 characters, so the error at the end of a long build survives. The text is fenced and labelled as data, not instructions, but treat it like any other untrusted input: in acceptEdits or a subscription turn the agent can still act on what it reads. NO_COLOR turns off colour.
Shell completion
eval "$(llm-light --completion bash)"     # or zsh, in ~/.bashrc or ~/.zshrc
llm-light --completion fish | source
llm-light --completion powershell | Out-String | Invoke-Expression
Also for scripts: -C <dir> runs in another directory, and --append-system-prompt "..." adds to the system prompt for that run.
Permission modes
What llm_light may do without asking is set by a permission mode, named after Claude Code's. shift+tab at the prompt cycles through them, /permissions <mode> sets one, and the toolbar shows any mode other than the default.
| Mode | Start with | Edits | Shell commands |
|---|---|---|---|
default |
(nothing) | Asks before applying edits and before committing the agent's edits | Only allowed prefixes (/allow, --allow-command), one simple command at a time |
acceptEdits |
-y |
Applied and committed without asking | As in default |
plan |
--permission-mode plan |
None: the model investigates and proposes a plan; any SEARCH/REPLACE blocks it writes are shown, not applied | None |
bypassPermissions |
--dangerously-skip-permissions (alias --yolo) |
Applied and committed without asking | Any command, chaining included, with no allowlist; a failing affected-test run keeps the edit instead of asking to revert it |
Bypass asks nothing, so use it only in a sandbox, a container or a repository you can restore: the agent can run any command your user can. As in Claude Code, shift+tab and /permissions offer it only when llm_light was started with --dangerously-skip-permissions or --allow-dangerously-skip-permissions (the latter starts in another mode). Spending questions are not permissions: the top-tier model prompt and the /budget cap still ask in every mode. In plan and bypass modes a one-line note goes before each question, so the model knows; default and acceptEdits requests are unchanged.
On a subscription the agent is offered only the tools its mode can use: reading and editing files, plus a shell where the table above allows one, plus NotebookEdit in a project with notebooks, and the web tools in bypass or with --web. It cannot start subagents, run skills or schedule jobs. That saves about 11,000 input tokens on every model round.
python3 llm_light.py --continue (or -c) picks up this project's previous conversation where you left it, as claude --continue does. The conversation is saved after every turn to ~/.llm_light_sessions/ (one file per project, outside the repo so a cloned repo cannot supply one), along with the session's model. Cost counters start from zero. Retrieval runs fresh for each new question, but earlier answers may describe code that has changed since. /clear starts a new conversation and keeps the old one: --resume at startup, or /resume in a session, lists this project's saved conversations (date, turns, first question) and switches to the one you pick, keeping the newest 10 unnamed ones per project and provider. /rename auth-fix names the conversation: the name leads its line in the list, it is never pruned, and --resume auth-fix continues it without asking, also with a question (--resume auth-fix -p "and then?"). A plain --resume asks which conversation, so it needs a terminal. --continue also takes a question: llm_light.py -c -p "and then?" answers in the saved conversation and saves it again, while a plain -p question sends no history and saves nothing.
Each question is routed to Haiku 5.5, Sonnet 5.5 or Opus 5.5, and the session keeps the first question's model (LLM_LIGHT_ROUTE_ONCE=0 routes every question). A question that routes to Opus asks first: Opus 5.5, Fable 5.1 or Sonnet 5.5, each with its estimated cost for the turn. Esc, or running without a terminal, picks Sonnet 5.5.
| Command / key | What it does |
|---|---|
/help |
Commands and keys |
/clear |
Start a new conversation; the old one stays available to /resume; the next question also picks the model again, which the session then keeps (LLM_LIGHT_ROUTE_ONCE=0 picks it per question) |
/compact [focus] |
Replace the conversation so far with a summary, so later turns send fewer tokens; a focus says what to keep in detail |
/config [key value] |
Show the saved settings, or save one: vim, theme (dark, light), notify (off, bell), permission_mode, model, effort. They live in ~/.llm_light/settings.json, and a flag beats them. A file in the project is never read, and bypassPermissions cannot be saved |
/context |
What the next turn would send, by part, as an estimate. The agent's own prompt, tools and reads come on top of it on a subscription |
/copy [n] |
Copy the latest reply, or the n-th latest, to the clipboard, code blocks included. Uses clip on Windows, pbcopy on macOS and wl-copy, xclip or xsel on Linux; without one (over SSH, say) it sends an OSC 52 escape, which many terminals copy locally |
/cost |
Token usage and cost for this session, and lifetime savings |
/diff |
The uncommitted changes under the current directory, one diff per file, and the untracked files |
/doctor |
Check the install, login and tools. It starts no program and sends nothing. --doctor runs it from the command line, even when the login is what is broken, and exits 1 on a problem |
/effort [level] |
Show the effort, or pin low, medium, high or max for every question; auto returns to routing. It also sets how much code retrieval sends. Claude only |
/export [file] |
Save the conversation as plain text; without a name, to llm_light-conversation-<date>-<time>.txt in the project (a .txt, so the skeleton does not pick it up) |
/hooks |
Your hooks from ~/.llm_light/hooks.json, by event and matcher (see Hooks) |
/init |
Ask the model to write or improve this project's CLAUDE.md (AGENTS.md for Gemini and Codex), as a normal turn, so edits ask as usual |
/mcp |
The MCP servers from ~/.llm_light/mcp.json: with an API key, whether each connected and its tools; on a subscription, the servers the agent starts each turn (see MCP servers) |
/memory [user] |
Open that file in $VISUAL or $EDITOR; it goes out with every question. /memory user opens your own instructions instead (see Your own instructions) |
/model [name] |
Show the model; opus, sonnet, haiku, fable or a full model id pins every question to it, auto returns to routing. Claude only: Gemini and Codex pick their own |
/permissions [mode] |
Show the permission mode, or set one (see above) |
/run <cmd> |
Run a shell command and ask Claude about its output. As with !, the output shows as it arrives, the command has no stdin, ctrl+c stops it and everything it started, and it is killed after 120 s (LLM_LIGHT_RUN_TIMEOUT) |
/allow [prefix] |
Let the agent run commands starting with this, from the next turn and in later sessions in this project. Without a prefix, lists them. A prefix holding a character the shell refuses, or ,, (, ) or *, is rejected |
/disallow <prefix> |
Take a prefix back, now and for later sessions |
/loop <n> <question> |
Ask the same question up to 20 times in a row, one turn each |
/loop <n or interval> --until "<cmd>" <question> |
Stop as soon as the command exits 0. It runs before each turn, so a check that already passes spends nothing, and its failing output goes with the next turn: /loop 5 --until "python -m pytest -q" fix the failing tests. It runs like !, so no allowlist applies. A command that cannot run or times out stops the loop, since it could never pass |
/loop <interval> <question> |
Ask again every 30s, 5m or 1h, counted from the end of the last turn, up to 20 turns. The question may be one of your own /commands. ctrl+c, a failed turn or a reached /budget stops either form. Nothing can be typed while it runs, and in default mode a turn that edits still stops to ask |
/budget <$> |
Cap the session's spend; at the cap, questions go to the cheapest model. /budget off removes it |
/status |
Version, project, provider and access, model, permission mode, what the shell may run, index state and where the conversation is saved |
/resume |
Switch to one of this project's saved conversations, picked from a list with their name, date, turn count and first question. The conversation you leave is kept |
/rename [name] |
Name this conversation, so /resume shows it and --resume <name> continues it without asking; a named conversation is never pruned. Without a name, shows the current one. Names are one line, up to 60 characters, unique per project |
/review [ref] |
Review the uncommitted changes, or those against a ref, as a turn in plan mode whatever the session's mode, so it cannot edit or run a command. Up to 50,000 characters of diff are sent, and untracked files are named. Your own ~/.llm_light/commands/review.md replaces it, and likewise init.md for /init |
/rewind |
Go back to before an earlier turn of this run: picks the turn from a menu, truncates the conversation to before it and resets the files to the commit HEAD was at then (git reset --keep). Refuses, changing nothing, if a commit since is not a Claude: one or a file it would reset has local edits. Edits the agent left uncommitted are not restored; compaction and /clear drop the earlier turns from the menu |
/undo |
Undo the last Claude: commit. Keeps uncommitted work; refuses if the last commit is yours or its files have local edits |
/vim |
Switch the prompt between vi and emacs editing keys |
/why |
How the last query was routed and what was retrieved |
/<name> [args] |
Your own command: ~/.llm_light/commands/<name>.md (or $LLM_LIGHT_COMMANDS_DIR). Its body is sent as the question, with $ARGUMENTS replaced by what you type after the name (without the placeholder, that text goes after the body). An optional --- frontmatter description: shows in /help and the / menu. Names are lowercase letters, digits, - and _; a built-in name wins. A repository's own .llm_light/commands/ is not read: it would be prompt text a cloned repo controls |
/exit, exit, quit |
Quit; prints a one-line session summary |
@shot.png |
Attach an image: PNG, JPEG, GIF or WebP, inside the project, up to 5 MB and 5 per question. In API-key mode the image goes in the request. On a subscription the agent opens it with its Read tool. Later turns keep only the path, so an API-key follow-up has to mention it again. Gemini and Codex cannot read images |
!!<cmd> |
Run a program that needs the terminal: an editor, a REPL, git rebase -i. It has the terminal to itself with no timeout, and nothing goes to the model |
!<cmd> |
Run a command yourself, from the project root; its output is shown and sent with your next message. No allowlist applies, since you typed it. On Windows it runs in Git Bash when Git for Windows is installed, as the agent's commands do, else cmd.exe (LLM_LIGHT_SHELL=cmd keeps cmd.exe) |
@<path> |
Attach a project file to the message (tab completes the path). Up to 50,000 characters per file; a file outside the project, a directory or a binary file is not attached, and a line says why. Routing and retrieval still see only what you typed |
Typing / |
Menu of commands with descriptions |
shift+tab |
Cycle the permission mode |
alt+enter, \+enter |
New line in the prompt (enter sends) |
alt+v |
Paste an image from the clipboard, such as a screenshot: it is saved as .llm_light_cache/pastes/paste-<time>.png (git and the index ignore that folder; the newest 20 are kept) and @ that path goes in the prompt, so it is attached like @shot.png. ctrl+v does the same where the terminal passes it on; Windows Terminal turns it into a text paste. Uses PowerShell on Windows, osascript on macOS and wl-paste or xclip on Linux; with none of those, or no image on the clipboard, it says so. If the project ships .llm_light_cache or its pastes folder as a link, nothing is saved |
ctrl+g |
Edit the prompt in $VISUAL or $EDITOR (Notepad on Windows if neither is set) |
ctrl+r |
Search earlier prompts |
ctrl+l |
Clear the screen |
esc |
Cancel the running turn, as ctrl+c does, without the risk of quitting. Keys you type while the model answers wait in the next prompt; enter is not passed on, so nothing is sent for you. Not in -p runs; LLM_LIGHT_ESC=0 turns it off |
ctrl+c |
Cancel the running turn, ! command or /loop; at the prompt, clear what you typed, and on an empty prompt quit |
One-shot runs write only the answer to stdout, as plain text; progress and tool lines go to stderr, so llm_light.py "question" > answer.md holds just the answer. -p (--print) asks for one-shot mode explicitly, as in claude -p; @path mentions work there too.
Other flags: --model <name> pins the model from the start (as /model does), --permission-mode <mode> starts in a permission mode, and --version prints the version.
The script runs three concurrent threads to keep your workflow seamless:
- Main Thread: Handles the input loop, retrieves relevant chunks per query, and manages the conversation history.
- Watchdog: Monitors your directory for file saves. If a source file changes, it automatically re-chunks and re-embeds it; if a tracked
.mdfile changes, it rebuilds the skeleton cache. Files under.git,.venv,node_modulesand other skipped directories are ignored. It reports in the toolbar (re-indexed calc.py (2 chunks)), never in the middle of a reply. - Heartbeat Daemon (API-key mode only): Keeps the Anthropic prompt cache warm while you step away. Disabled in OAuth/Pro-subscription mode, where each turn spawns a fresh
claudeCLI subprocess and there is no persistent process to keep warm.
Embedding Models (hybrid retrieval)
Code is indexed twice, by two models that are good at different questions:
static-retrieval-mrl-en-v1(static embeddings, no transformer): indexes this repo's 1,400 chunks in about 2 s on a CPU, so retrieval works from the first question. Best of six models measured at questions that name code ("where isretry_with_backoffused?").all-mpnet-base-v2: about 380 s for the same chunks, so it runs in the background while you work, and its vectors are cached. Best at questions that describe behaviour without naming it ("where do we wait longer between attempts?").
Once both are ready, each chunk's similarity to the question is z-scored per model and averaged. On 35 questions about this repo, the file that answers the question reached the model's context for 23, against 15 with mpnet alone (the setup before this change), and the 6 off-topic questions still got no context. Measure on your own changes with python tests/benchmarks/benchmark_models.py. LLM_LIGHT_HYBRID=0 switches back to a single model picked by repository size (all-MiniLM-L6-v2 under 50 files, all-mpnet-base-v2 under 200, nomic-ai/nomic-embed-text-v1.5 above).
🛡️ Security & SBOM
To ensure supply chain transparency and prevent dependency confusion, llm_light uses:
- Version floors:
requirements.txtandpyproject.tomlset each dependency's minimum to the newest release that installs on Python 3.12. The installers readrequirements.txt, so there is one list to keep current. TheInstallersworkflow runs all three on clean Linux, macOS and Windows runners whenever an installer orrequirements.txtchanges, and weekly. - SBOM (Software Bill of Materials): The project maintains an industry-standard SBOM in CycloneDX format.
Continuous Inventory
A GitHub Action automatically generates a fresh sbom.json on every push to main and uploads it as a build artifact.
Manual Generation
You can generate the SBOM manually using the provided scripts:
# Linux / macOS
bash scripts/generate_sbom.sh

# Windows
.\scripts\generate_sbom.ps1
Tests
Run the full unit test suite:
python -m pytest -q
Run a quick CLI smoke test with the synthetic mocked codebase:
python -m llm_light --test-mode small "List all public classes or modules in this codebase"
Larger synthetic presets are also available for local stress testing:
python -m llm_light --test-mode medium
python -m llm_light --test-mode large
python -m llm_light --test-mode extra-large
CI Regression Checks
The GitHub Actions workflow (.github/workflows/test.yml, Python 3.12) runs three steps:
- Unit tests
python -m pytest -q
- Analytical token-cost regression
python tests/benchmarks/benchmark.py --json > tests/baseline_token_stats_new.json
python tests/linting/check_regression.py tokens tests/fixtures/baseline_token_stats.json tests/baseline_token_stats_new.json
- Offline retrieval regression on the committed local fixture
python tests/benchmarks/benchmark_retrieval.py --fixture tests/fixtures/retrieval_cases.json --output tests/baseline_retrieval_stats_new.json
python tests/linting/check_regression.py retrieval tests/fixtures/baseline_retrieval_stats.json tests/baseline_retrieval_stats_new.json
If retrieval behavior changes intentionally, refresh the baseline with the same fixture command so CI remains deterministic:
python tests/benchmarks/benchmark_retrieval.py --fixture tests/fixtures/retrieval_cases.json --output tests/fixtures/baseline_retrieval_stats.json
1 maintainer

Metadata
1 maintainer
Release files for llm-light-cli 0.2.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| llm_light_cli-0.2.0.tar.gz | 236.3 kB | With provenance | Details for llm_light_cli-0.2.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| llm_light_cli-0.2.0-py3-none-any.whl | Python 3 | none | any | Details for llm_light_cli-0.2.0-py3-none-any.whl |
Total release size: 455.0 kB
Release files / llm_light_cli-0.2.0.tar.gz
| Download URL | llm_light_cli-0.2.0.tar.gz |
|---|---|
| Size | 236.3 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
c94271fb6fb1eacd0b1c11ad1be2dda27e216e94a81c673f2e316475c4d34a66
|
|
BLAKE2b-256 checksum How to use checksums |
4c6272c598d09de55db7b18028152a7de1b1189cd8a211b33712df6ce19ee8b1
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 14, 2026.
Transparency logRelease files / llm_light_cli-0.2.0-py3-none-any.whl
| Download URL | llm_light_cli-0.2.0-py3-none-any.whl |
|---|---|
| Size | 218.8 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
1448ec035c143cad1c3fa8b7e7c6adf5698f792a0dd1c0d44a2d4060897dcf33
|
|
BLAKE2b-256 checksum How to use checksums |
763fe1576c05476436486cb9e471611b334397ea9be61c1246a73ee4282993aa
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.16
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 14, 2026.
Transparency logSecurity for llm-light-cli 0.2.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
Full provenance
Both files in this release have been uploaded with provenance metadata.
Attestation for llm_light_cli-0.2.0.tar.gz
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Nov 14, 2026.
Transparency logA note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














