
LLM Preflight
Last reviewed: 2026-10-14 · As of: v2.21.2


The pre-merge check for LLM changes. Catch model, prompt, schema, and provider-route regressions against your application's contract, then review latency, usage, and price evidence.
Try it in 60 seconds
Find out, with no configuration and no request, which model IDs in a repository the provider has retired or scheduled for retirement:
python3 -m pip install llm-preflight
llm-preflight --audit-source .
Retired IDs print their date and the provider-stated replacement with a
ready --dry-run command; see model retirements.
Then create and run a deterministic local benchmark—no API key or network request:
llm-preflight init
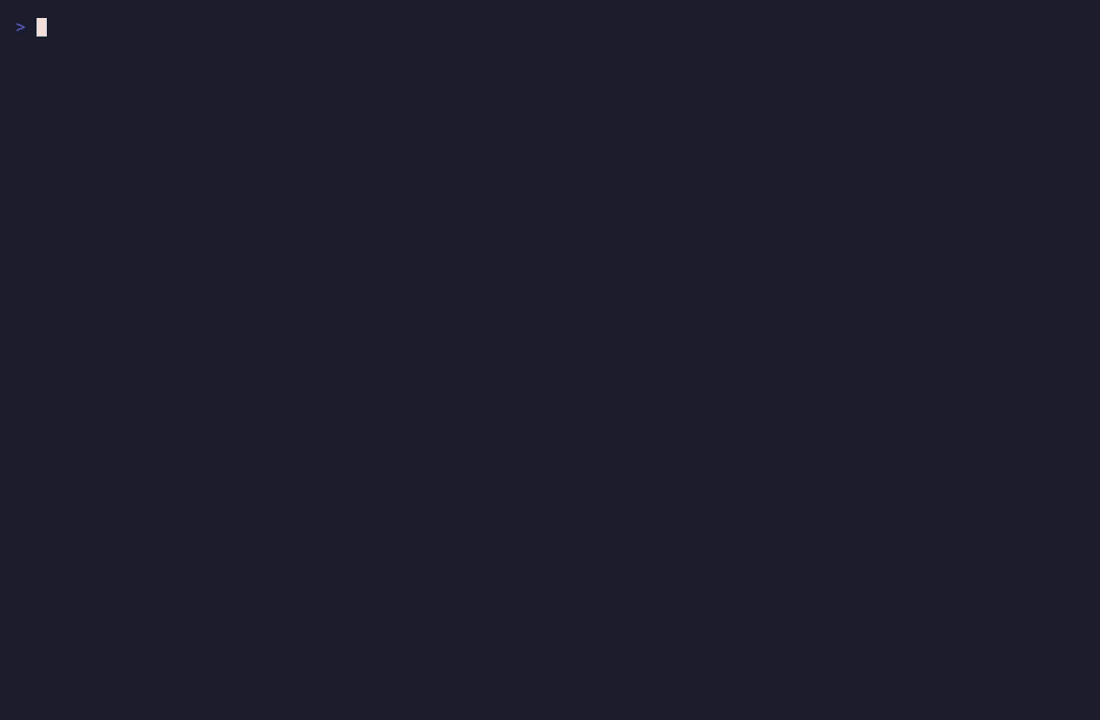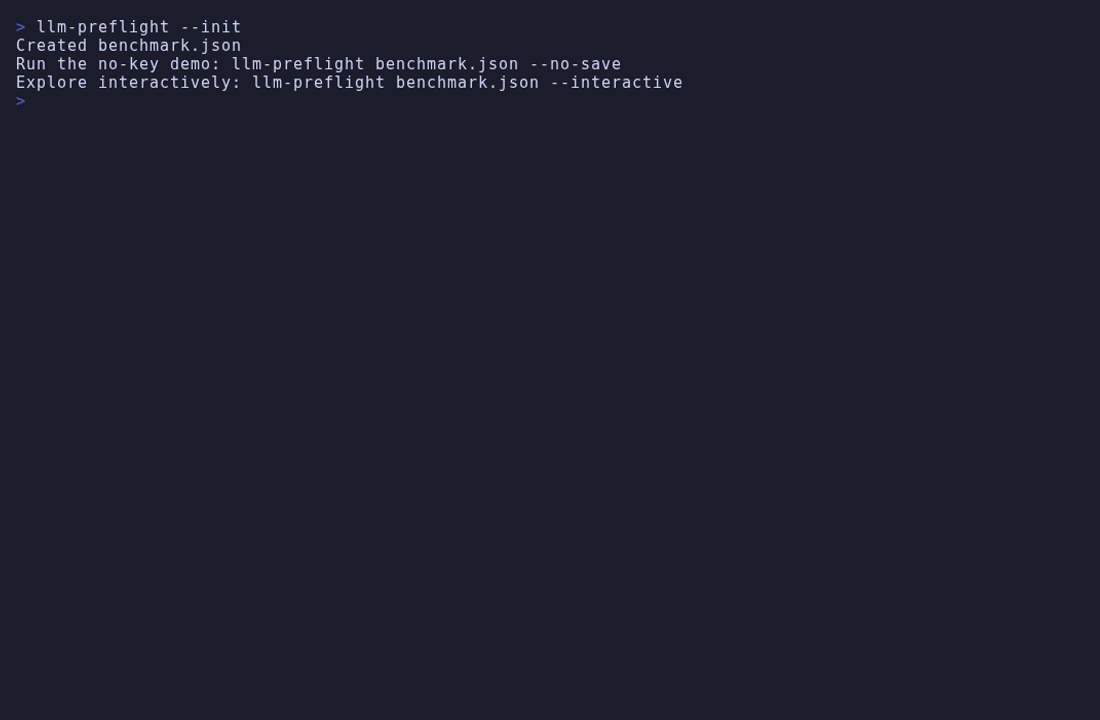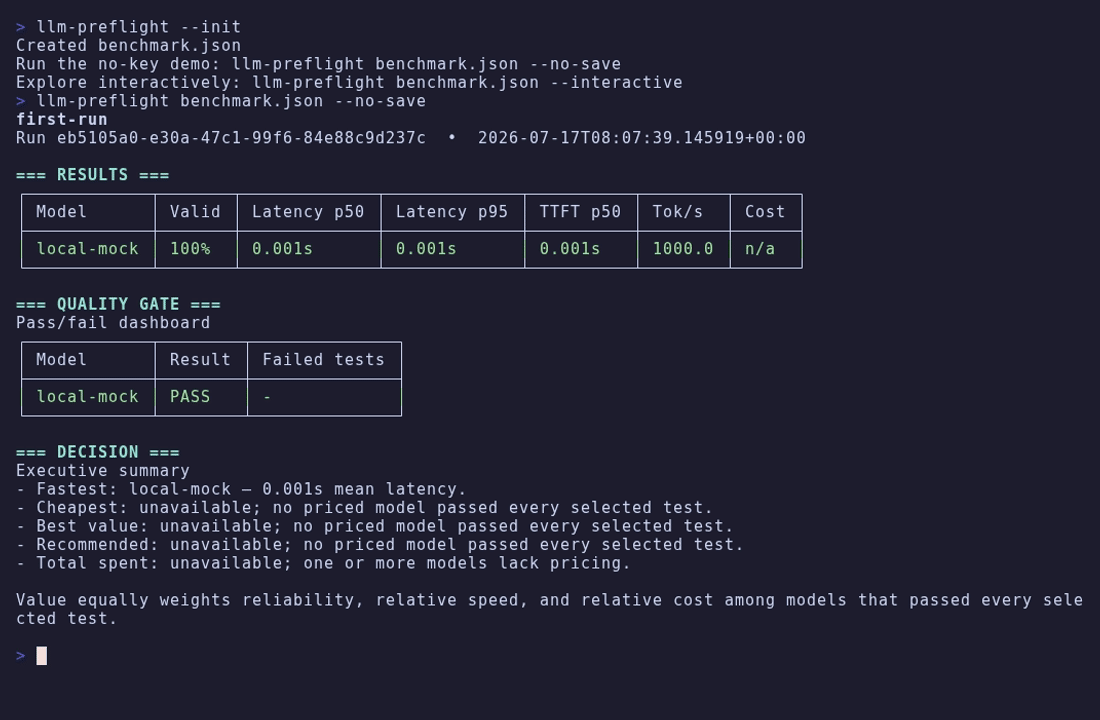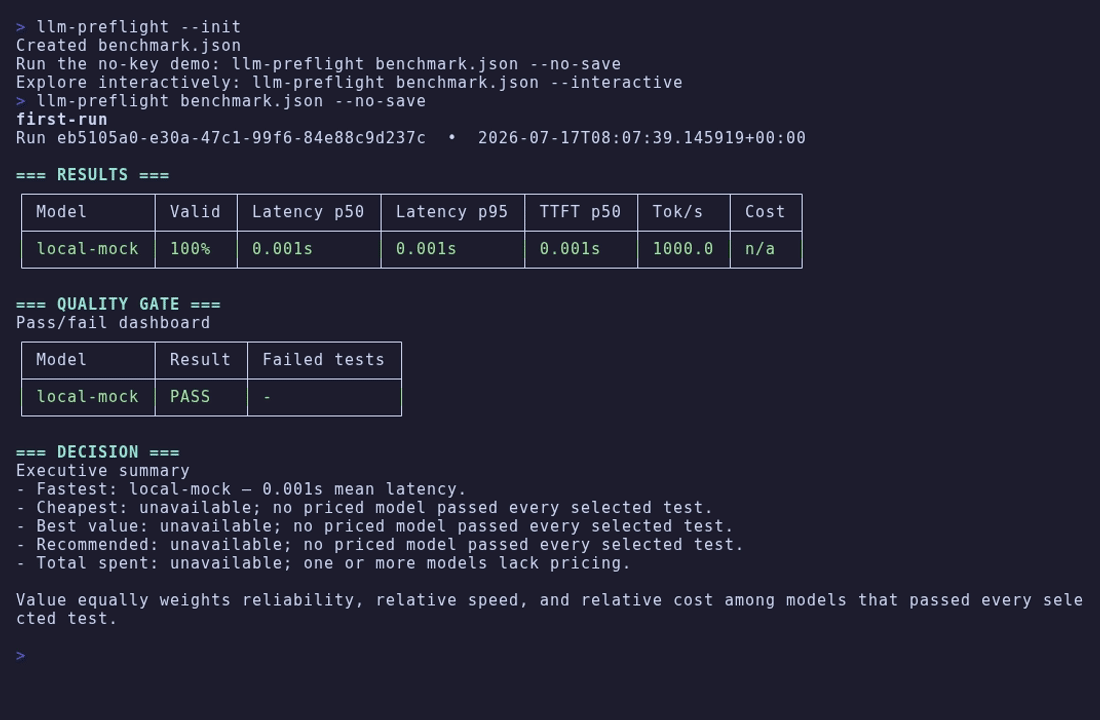
llm-preflight benchmark.json --no-save
From a source checkout:
python3 -m llm_preflight init
python3 -m llm_preflight benchmark.json --no-save
init never overwrites an existing config. It creates a mock benchmark so
you can see the report and exit behavior before making a paid request.
Its result is intentionally inconclusive (exit code 3): a local mock
validates configuration and output handling, but cannot approve a live model.
See a contract change fail
These saved results are synthetic fixtures. Render the same report you can attach to a pull request, without contacting a provider. From a checkout of this repository, run:
python3 -m llm_preflight report examples/reports/schema-baseline.json --format markdown
python3 -m llm_preflight report examples/reports/schema-break.json --format markdown
The first result passes. The second catches a response that no longer meets the declared output contract:
Decision: pass (benchmark_passed)
Contract validity: 100%

Decision: fail (contract_failure)
Contract validity: 67%
Contract-only failures: 1
The report gallery adds a cheaper candidate that fails the contract and a compatible baseline comparison with latency and cost regressions. Every number is labeled synthetic; none is a live model claim.
Purpose
Mission: help engineers catch LLM integration regressions before shipping a change.
Vision: every LLM-related pull request carries reproducible evidence of compatibility, latency, and cost.
Positioning: LLM Preflight is a local CLI and CI tool that checks an application's LLM contract and reports compatibility, latency, and estimated cost before a change ships.
It is built for small engineering teams maintaining AI features. Coding agents can run the same checks, while engineers own the decision. Read the north star and the AI implementation testing guide for the intended workflow and boundaries.
Choose your path
- Set up a real project. Adapt a representative contract, reuse an existing env file, and add a no-spend CI check with the project integration guide.
- Validate a change. Compare an approved model, prompt, schema, or provider route with a candidate using the model-change guide.
- Review a new model. Discover metadata, deliberately probe a route, then prepare a bounded candidate smoke with the model-catalogue guide.
- Inspect a measured example. See the dated support-routing model comparison to understand what a narrow contract run can and cannot establish.
- Automate an established contract. Add the no-spend GitHub Marketplace Action or use CI and JSON output.
- Configure a coding agent. Start the local MCP server from a trusted
repository with
llm-preflight-mcp --workspace "$PWD", then use the MCP server guide for your client configuration.
Safety boundary
flowchart LR
    A[Integration change] --> B[No-spend validation\ndoctor, pricing, dry run]
    B --> C{Human reviews\nevidence and cost bound}
    C -->|Explicit approval| D[Bounded paid smoke]
    C -->|No approval or missing evidence| E[Resolve evidence or stop]
    D --> F[Local evidence for\nproduction approval]
LLM Preflight is local evidence, not production approval. It is not a hosted evaluation platform, tracing system, RAG framework, or public leaderboard. Its results apply to your account, network, prompts, and validation rules.
CLI, CI, and MCP
Works as a CLI, GitHub Action, and local MCP server. Every path starts with no-spend validation and planning; a live provider run remains an explicit, bounded human-approved step. See the GitHub Action guide or the MCP server guide.
Native routes and release-reviewed official pricing snapshots are listed in current snapshots. That list is direct-provider price coverage, not a ranking or every discoverable ID.
Release notes for every version are in the changelog.
Common jobs
-
Switch a model or provider. Run the bounded migration check, then add the contract test your feature needs.
-
Check a prompt, schema, parser, or tool change. Define an explicit output contract before the smoke, then run
llm-preflight benchmark.json --contract-checkto prove local accepted/rejected fixtures and lint declared tool schemas. -
Plan an agent-made change. Run
llm-preflight benchmark.json --change-planbefore the ordinary no-spend checks. It identifies static model and contract signals in local Git changes, but never authorizes a paid run. -
Review a newly discovered model. Refresh metadata, then prepare—not run— a bounded candidate plan:
llm-preflight catalog refresh benchmarks/watch.json
llm-preflight catalog prepare benchmarks/watch.json \
  --against benchmarks/approved.json --output benchmarks/candidates.json
llm-preflight benchmarks/candidates.json --migration-check --dry-run
Only explicitly approved, fully evidenced models proceed to paid work; see the model catalogue guide.
-
Investigate a provider or price change. Run
--doctor,--pricing-check, and a dry-run; report a suspected regression through the redacted issue forms. -
Automate a known contract. Use the no-spend GitHub Action or the CI guide with a saved baseline and
--ci.
It measures deterministic test validity, end-to-end latency (p50/p95), time to first token, throughput when the stream is incremental and usage is available, token totals, and estimated cost. Result files retain request metadata and per-request observations for reproducibility.
"Deterministic" describes the validator, not the model: every response is checked against explicit structural rules — a regular expression, a JSON shape, an exact routing label — so the same response always produces the same verdict. The tool does not score semantic quality; that is your task-specific evaluation, and it stays out of scope on purpose.
What live evidence looks like
A completed preflight retains per-request observations and a machine-readable
decision: contract validity, latency (including TTFT where observable), token
usage, estimated cost, pricing evidence, and blocking warnings. The terminal
summary is a convenience; automation should consume the saved JSON decision.
Render saved schema-version-1 JSON as a self-contained offline HTML report with
llm-preflight report results/run.json --output report.html. The renderer
omits prompts, responses, local paths, and identifying run metadata; the
Marketplace Action adds a compact report to the GitHub Actions job summary.
That evidence applies to your account, network, prompts, and validator at one time—not a universal model ranking. For a complete interactive example, see interactive runs.
Model comparison
Our current shortlist covers flagship and budget options across OpenAI, Anthropic, Gemini, GLM, DeepSeek and Qwen. Start a balanced-model review with Sonnet 5.5 or GPT-6.1 Sol; include Opus 5.5 for a higher-cost candidate. For a budget review, compare GPT-6 Luna, Haiku 5.5, Qwen 3.8 Flash and DeepSeek V4.1 Flash against your own contract. Gemini 3.8 Flash and Qwen 3.8 Max are also measured alternatives. These are review candidates; production promotion requires your application's evidence and approval.
The table shows the latest retained run of the same eight example routing and JSON cases, twice per model. Not run means there is no live measurement; it contributes no success, latency or cost claim. Model availability and request support were reviewed on 2026-10-14.
| Provider route | Exact API model ID | Observed date | Valid / 16 | Mean latency | Estimated cost / 16 |
|---|---|---|---|---|---|
| Anthropic | claude-opus-5-5 |
2026-09-28 | 16 | 2.041s | $0.012120 |
| Anthropic | claude-sonnet-5-5 |
2026-10-07 | 16 | 1.390s | $0.005740 |
| Anthropic | claude-haiku-5-5 |
2026-10-07 | 16 | 1.090s | $0.000481 |
| OpenAI | gpt-6.1-sol |
2026-09-30 | 16 | 2.071s | $0.004802 |
| OpenAI | gpt-6-luna |
2026-09-28 | 16 | 1.361s | $0.000350 |
| Gemini | gemini-4-argon |
Not run | — | — | — |
| Gemini | gemini-3.8-flash |
2026-09-28 | 16 | 2.363s | $0.014768 |
| OpenRouter / Relace | z-ai/glm-5.3 |
2026-09-30 | 14 | 0.948s | $0.001190 |
| OpenRouter | z-ai/glm-5.3-flash |
Not run | — | — | — |
| OpenRouter | deepseek/deepseek-v4.1-flash |
2026-09-28 | 16 | 0.963s | $0.001863 |
| OpenRouter | qwen/qwen3.8-max-0902 |
2026-09-28 | 16 | 4.186s | $0.012932 |
| OpenRouter | qwen/qwen3.8-flash |
2026-09-28 | 16 | 1.459s | $0.000274 |
Known limits: Haiku passed these 16 cases and 53/53 additional checks, but its separate password-reset smoke was 5/6. Sonnet's smoke was 6/6. GLM's 14/16 result includes an empty JSON answer and a wrong routing label; it is a candidate to investigate, not a passing recommendation. The native Z.ai, DeepSeek and Qwen routes have no measurements in this study.
Each cost is a token-based estimate for those 16 requests, not an invoice or a current per-task price. September OpenAI estimates predate cache-write accounting and can omit those charges. Settings and reasoning differ across routes; calls ran in sequential blocks from one host. This small example does not establish a stable quality, speed or cost ranking.
The observed comparison
retains all 27 measured IDs, request settings and failure analysis.
Current availability also includes GLM 5.3 Flash/FlashX,
z-ai/glm-5.3-flashx, GLM 5.3 Prime,
z-ai/glm-5.3-prime, and Qwen 3.8 Max Prime,
qwen/qwen3.8-max-prime. These variants are unmeasured here; their
availability does not transfer another row's result.
Gemini 4 Argon
gemini-4-argon has bundled pricing and deterministic protocol coverage of
the native synchronous GenerateContent adapter. Gemini 4 has no live measurement
in the comparison above. See the current snapshots guide
for thinking settings, token limits, caching and published price transitions.
The bounded example
includes local contract fixtures and an explicit one-request budget:
llm-preflight examples/gemini-4-argon.json --contract-check --json
llm-preflight examples/gemini-4-argon.json --dry-run --json
Google's deprecated 3.5/3.7 Flash aliases redirect to 3.6/3.8; current examples use 3.8 directly. Their September results remain dated historical evidence.
First live run
Python 3.10+ is required. The installed CLI and MCP server have no third-party runtime dependencies. Create a bounded provider starter from any directory:
llm-preflight init live.json --template provider \
  --provider openai --model gpt-6.1-sol --api-key-env OPENAI_API_KEY
Set OPENAI_API_KEY in your shell or in .env.production beside live.json.
The starter expects exactly ok. Add the following top-level field to
live.json, keeping its existing fields, to check that validator locally:
{
  "validation_fixtures": [
    {"name": "accepted-label", "response": "ok", "expect": "pass"},
    {"name": "rejected-label", "response": "not ok", "expect": "fail"}
  ]
}
# Review the prompt, validator, model, request limit and estimated-cost cap.
llm-preflight live.json --contract-check
llm-preflight live.json --doctor
llm-preflight live.json --pricing-check
llm-preflight live.json --dry-run

# Paid request: run only after explicitly approving the displayed plan.
llm-preflight live.json
The starter uses one short exact-output check, a three-request limit and a $0.05 estimated-cost cap. Adapt it to a representative application contract before using its result to review a model. The checks above make no generation requests; the final command does.
The CLI reads .env.production beside the config without overriding shell
variables. Select an existing file with --env-file PATH, or use
--no-env-file. Results are saved as JSON and Markdown under results/
unless you use --no-save. See project integration
for an application example and a no-spend CI gate.
Change a model safely
This is the core workflow. Put your approved model and candidate model in one config, review the combined request and cost limits, then preview the small response-and-contract preflight:
llm-preflight benchmark.json --migration-check --dry-run
llm-preflight benchmark.json --migration-check
It sends three short representative cases to each selected model, once each. It answers: did the API work, did each response meet the basic contract, and how quickly did the provider start and finish responding? It is a cheap compatibility check, not a statistical performance conclusion.
When that passes, run the task-specific checks that match your application—for
example exact-routing-check or structured-output-check—before approving a
switch.
Use custom contract tests to express the outputs your
own feature must preserve.
Using a coding agent
Give an agent the same evidence you would use yourself: a reviewed config, an
explicit output contract, and a dry run before paid work. The agent-smoke
alias selects five profiles; --smoke makes six requests per model:
# No generation request: inspect credentials, model selection, and paid-work plan.
llm-preflight benchmark.json --doctor --json
llm-preflight benchmark.json --tests agent-smoke --smoke --dry-run --json

# Paid run, only after reviewing the plan.
llm-preflight benchmark.json --tests agent-smoke --smoke --json --no-save
An agent should not infer model IDs, weaken a validator to turn a failure into a pass, or approve a model without an explicit instruction. The compact LLM and coding-agent guide covers commands, result JSON, exit codes, and automation guardrails. The AI implementation testing guide shows how to make this validation an agent's default testing step.
MCP for coding agents
Use the local stdio MCP server when an agent needs the preflight evidence without shell parsing or arbitrary command execution:
{
  "mcpServers": {
    "llm-preflight": {
      "command": "llm-preflight-mcp",
      "args": ["--workspace", "/absolute/path/to/repository"]
    }
  }
}
It exposes only four tools: validate a config, prepare a dry-run plan, run an explicitly confirmed preflight, and compare saved baselines. The first, second, and fourth tools never contact providers or load credentials. A live run still needs an explicit paid-run confirmation. See the MCP server guide for tool semantics, workspace boundaries, and the safe agent workflow.
Useful commands once you know your path
# Inspect configuration, credentials, and model selection without generation.
# --doctor provides pricing advisory; use --pricing-check as the fail-closed coverage gate.
llm-preflight benchmark.json --doctor
llm-preflight benchmark.json --pricing-check
llm-preflight benchmark.json --dry-run

# Run a reduced live benchmark.
llm-preflight benchmark.json --smoke

# Run a single ad hoc prompt.
llm-preflight --quick "Return only valid JSON with a status field." \
  --models openai:gpt-6-luna
The guided interactive preflight lets you select models and workload, review the shared plan and local fixtures, then preview, export, edit, or explicitly confirm execution. Try the offline example from a source checkout:
llm-preflight examples/interactive-contract.json --interactive --dry-run --no-env-file
See interactive runs for the prompts, exports and scripted equivalents.
For advanced discovery, interactive runs, CI, baselines, replay, and stop modes, see workflows. For models, environment files, custom prompts, and provider-specific options, see configuration.
What makes a comparison useful
- Keep prompts, system instructions, temperature, and output limits fixed.
- Validate outputs: a fast malformed response is a failed result.
- Run from the same host; network distance and provider load affect latency.
- Treat single-user latency and load testing as separate experiments.
- Prefer dated model IDs over moving aliases.
The CLI distinguishes API FAIL (transport, credentials, provider, or request
failure) from API OK / TEST FAIL (a response that fails your validator).
Recommendations only consider models that pass every selected test.
How it compares
Several good tools live near this space. Use them when their job is your job:
- promptfoo, deepeval — full evaluation suites: scored quality metrics, red-teaming, large ongoing test matrices in CI. Use them to grade prompt and model quality over time.
- Braintrust, LangSmith — hosted platforms: tracing, dashboards, team collaboration, production observability.
llm(Simon Willison) — a general multi-provider CLI for running prompts, not a comparison harness.
LLM Preflight does one narrower job: the local go/no-go check in the moment before an LLM integration change. Your prompt, candidate models, structural validation, latency, and cost — one command, one report, no hosted service, no telemetry, and no vendor between you and the verdict.
Documentation
Start at the documentation homepage, then choose the path that matches your work:
- Start safely: safe demo and model change.
- Validate a change: output contracts, model catalogue, and pricing and safety.
- Automate: CI and JSON output, coding agents, and MCP.
- Look up details: CLI reference, configuration, result JSON, and troubleshooting.
- Understand the product: north star, product decisions, and AI implementation testing.
- Contributing — development setup and the TDD workflow.
- Security — reporting vulnerabilities.
Contributing and license
Contributions are welcome; see CONTRIBUTING.md. Released under the MIT License.
1 maintainer

Metadata
1 maintainer
Release files for llm-preflight 2.21.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| llm_preflight-2.21.2.tar.gz | 941.6 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| llm_preflight-2.21.2-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 1.1 MB
Release files / llm_preflight-2.21.2.tar.gz
| Download URL | llm_preflight-2.21.2.tar.gz |
|---|---|
| Size | 941.6 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
5e712d3186e97eaf6db791c2a2191bd39f23f7a603df8a8d8574a8def62d8645
|
|
BLAKE2b-256 checksum How to use checksums |
41ce5b95891010362faba8a28ece8ed2d411d6904152b83120492780a1f31e49
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency logRelease files / llm_preflight-2.21.2-py3-none-any.whl
| Download URL | llm_preflight-2.21.2-py3-none-any.whl |
|---|---|
| Size | 126.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
2866cc0d116bcc09a3411565fb55fed217a3b0a66ba7b1d8f97454124f926d3f
|
|
BLAKE2b-256 checksum How to use checksums |
52c65037d520e30043937119967b03623a8cf0cece2d1fe2b630b3dac9543704
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 14, 2026.
Transparency log













