
llm-route-audit
Find out whether LLM model routing saves money without hurting quality, on your own traffic.


Model routers send easy prompts to cheap models and hard prompts to strong ones. Whether that works for your workload is usually a guess. llm-route-audit replays a sample of your real requests on cheaper models, grades every answer against the original, and tells you, task by task, where a cheaper model is good enough. You get a report and a routing policy for the gateway you already run.
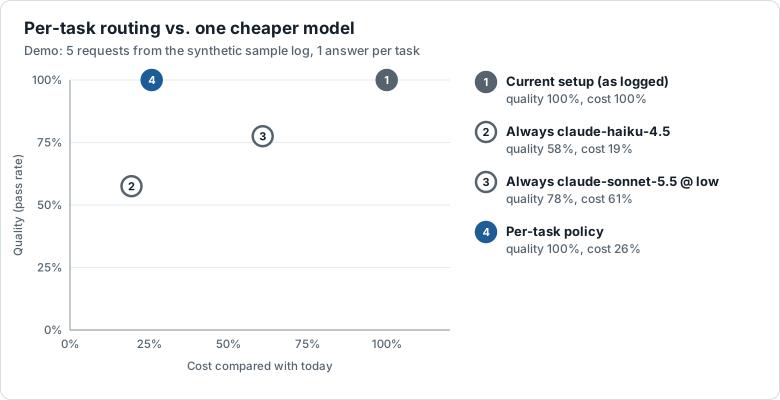
Demo run on 5 requests: using Haiku everywhere cut cost to 19% but only 58% of answers passed. Per-task routing kept every answer passing at 26% of the cost. The sample is far too small to trust, so run it on your own logs.
Try it in one minute
No API key needed. The repository includes the results of a real run.
git clone https://github.com/good2idnan/llm-route-audit.git
cd llm-route-audit
uv sync
uv run routeaudit report examples/sample_logs.jsonl \
  --replay examples/demo/replay.jsonl --grades examples/demo/grades.jsonl --min-samples 1
Requires Python 3.11+ and uv. The command-line tool is called routeaudit.
Why
- Routers often don't beat one good model. In independent benchmarks, most learned routers fail to beat simply using the best single model.
- Cheaper per call isn't cheaper per task. A cheap model that breaks your JSON format or gets the facts wrong costs more than it saves.
- Your workload is not a benchmark. The only evidence that counts is how candidate models do on your own requests.
llm-route-audit is not a router. It measures whether routing pays off, and can tell you not to route.
Features
- Your own data. Replays your logged requests, not public benchmarks.
- Per task type. Recommends a model for each kind of request, since one cheaper model rarely fits all of them.
- Honest grading. Exact checks first (JSON, fields, required text), then an AI judge that reads each pair in both orders, with its consistency reported.
- Model and effort. Tests (model, reasoning effort) pairs, not just models.
- Spending you control. A cost estimate and confirmation before any paid call, plus a hard
--max-spendlimit that can't be exceeded. Answers are cached, so you never pay twice. - Readable output. An offline HTML report, a YAML policy, or a ready-to-use LiteLLM config.
- Local first. Logs, results and reports stay on your machine.
How it works
your logs ─▶ analyze ─▶ replay a sample ─▶ grade answers ─▶ report ─▶ export policy ─▶ monitor
| Command | What it does |
|---|---|
routeaudit import |
Convert LiteLLM, Langfuse or OpenTelemetry logs into routeaudit's log format |
routeaudit validate |
Check a log file |
routeaudit analyze |
Show what your traffic costs today, by task type and model |
routeaudit replay |
Re-run a sample of requests on candidate models (Anthropic, OpenRouter, Ollama) |
routeaudit grade |
Compare every answer with the original: exact checks, then an AI judge |
routeaudit report |
Recommend a model per task type, with cost and quality for each strategy |
routeaudit export |
Write the policy as YAML or as a LiteLLM proxy config |
routeaudit monitor |
After you switch, check that routed traffic still meets the audited quality |
routeaudit check-model |
Test a newly released model on your last audit's sample and see what it would change |
Audit your own traffic
The commands below use the bundled synthetic sample, examples/sample_logs.jsonl. Swap in your own log file.
1. See what you spend today
uv run routeaudit analyze examples/sample_logs.jsonl
By task type (most expensive first)
  Task             Requests  Share  Avg in  Avg out     Cost  Cost share  Per 1K    p50
  review_contract        30    15%     209    1,126  $0.7005         55%  $23.35  24.1s
  summarize_call         40    20%     199      235  $0.2197         17%   $5.49   6.3s
  classify_ticket        45    22%     121       31  $0.0499          4%   $1.11   1.6s
2. Replay a sample on cheaper models
List the candidates in a YAML file (see examples/candidates.yaml), check the cost first, then run:
uv run routeaudit replay examples/sample_logs.jsonl -c examples/candidates.yaml --dry-run
uv run routeaudit replay examples/sample_logs.jsonl -c examples/candidates.yaml --max-spend 1.00
3. Grade the answers
uv run routeaudit grade examples/sample_logs.jsonl --config examples/grading.yaml --max-spend 1.00
Rules are set per task type in examples/grading.yaml. Exact checks run first and cost nothing. Answers that pass them go to the AI judge, which compares each one with the original twice, swapping the order to cancel position bias. Disagreements count as ties. Pick the judge with --judge-model.
4. Get the report
uv run routeaudit report examples/sample_logs.jsonl
For each task type, the report recommends the cheapest option that keeps at least 95% of the original's pass rate, and only once that option has at least 10 graded answers. Until then it keeps your current model and says why. The same report is saved as .routeaudit/report.html. Tune the rules with --target and --min-samples.
5. Export the policy
uv run routeaudit export examples/sample_logs.jsonl --out routing-policy.yaml
uv run routeaudit export examples/sample_logs.jsonl --format litellm --out litellm-config.yaml
The LiteLLM config gives each task type its own model alias, such as route/draft_reply. Your app sends each request to its task's alias, and LiteLLM forwards it to the chosen model with the right effort setting.
6. Keep watching after you switch
Models change and traffic drifts, so a cheaper route that passed the audit can get worse later. Once the policy is live, point monitor at fresh production logs:
uv run routeaudit monitor production-logs.jsonl --policy routing-policy.yaml --config examples/grading.yaml
For each task that switched to a cheaper model, it samples recent requests (--per-task 20) and replays them on the model the route replaced. It then grades the production answer against that reference answer and compares the pass rate with what the audit measured:
| Status | Meaning |
|---|---|
OK |
At or above the audited pass rate, minus a small tolerance (--tolerance 0.05) |
WAIT |
No problem so far, but too few checks to be sure (--min-checks 10) |
WARN |
Below the line, but the sample can't rule out bad luck yet |
ALERT |
95% sure quality dropped. The command exits with code 2, so cron or CI can flag it. |
Monitoring uses the same cost estimate, confirmation, --max-spend and cache as replay.
7. Test a new model in one command
When a new model comes out, test it on the same requests as your last audit:
uv run routeaudit check-model examples/sample_logs.jsonl -m claude-sonnet-5-5 --effort low --config examples/grading.yaml
It replays and grades only the new model, adds its results to your audit files, and shows which tasks it would take over and how projected savings change. To test the "one strong model at lower effort" alternative, check your current model at --effort low.
Providers and spending
Name each candidate (and the judge) after where it runs, and put the key in a .env file:
| Provider | Model name | Key in .env |
|---|---|---|
| Anthropic | claude-haiku-4-5 |
ANTHROPIC_API_KEY |
| OpenRouter | openrouter/anthropic/claude-haiku-4.5 |
OPENROUTER_API_KEY |
| Ollama (local, free) | ollama/llama3.2 |
none |
Effort levels (low to max) go next to the model in the candidates file. OpenRouter prices are looked up automatically, and the real cost of each call is recorded.
Three spending controls work on both replay and grade:
- Confirmation. routeaudit shows the estimate and asks before spending (
--yesskips the question). --budget 1.00refuses to start if the estimate is above $1.00.--max-spend 1.00is a hard limit on actual spend. Each call reserves its worst-case cost first, so even parallel calls can't push the total over. Calls that don't fit are held back and reported.
Logs
Already logging somewhere? Import from the tool you use. Point import at one file or a folder:
| Source | Command | Task type comes from |
|---|---|---|
| LiteLLM logging callbacks (JSON/JSONL) | routeaudit import litellm-logs/ --format litellm |
request tag task:<name> |
Langfuse observations (UI export or /api/public/v2/observations) |
routeaudit import observations.json --format langfuse |
trace tag task:<name>, or --task-from-name |
| OpenTelemetry GenAI spans (OTLP JSON, e.g. the Collector's file exporter) | routeaudit import traces.jsonl --format otel |
span attribute task_type (--task-attribute) |
Only real model calls are imported. Requests that can't be replayed faithfully yet are skipped and counted: failed calls, cache hits, images and tool calls. For OpenTelemetry, turn on GenAI message capture so the spans include the prompts and answers. API keys and other metadata are not copied.
Writing your own logs? Use one JSON object per line:
{"id": "req_0001", "timestamp": "2026-09-28T09:14:03Z", "model": "claude-opus-5-5",
 "task_type": "classify_ticket",
 "messages": [{"role": "system", "content": "..."}, {"role": "user", "content": "..."}],
 "response": "{\"category\": \"billing\", \"priority\": \"high\"}",
 "input_tokens": 180, "output_tokens": 32, "latency_ms": 1610}
| Field | Required | Notes |
|---|---|---|
id, timestamp, model, response |
Yes | id must be unique |
messages or prompt |
Yes | Use either one |
input_tokens, output_tokens |
No | input_tokens counts uncached input only; estimated from text if missing |
cache_read_tokens, cache_write_tokens |
No | For cache-aware pricing |
task_type |
No | Strongly recommended: recommendations are per task type |
latency_ms, outcome, metadata |
No | Unknown fields are ignored |
Prices. A starter table for Claude models is built in. Pass your own with --prices my-prices.yaml (USD per 1M tokens: input, output, cache_read, cache_write). Requests whose model has no price are reported, not silently dropped.
FAQ
When should I not route? When traffic is low, when every request is equally hard, or in long agent sessions where switching models throws away the prompt cache. Also whenever cheaper models fail your checks. "Keep your current model" is a normal result.
How much does an audit cost?
Mostly the replay and judge calls. The demo in this repo (5 requests, 2 candidates, a Sonnet judge) cost $0.11. Costs grow roughly in line with requests × candidates. --dry-run shows the estimate, --max-spend caps it, and local Ollama models are free.
Does my data leave my machine? Only the requests you choose to replay, sent to the providers you configure. Logs, answers, grades and reports stay in your project folder, and the HTML report loads nothing from the internet.
Can I trust an AI judge?
Treat it as one signal. Exact checks come first and settle formats and facts for free. The judge sees each pair in both orders, and the report shows how often its two verdicts agree. Use a strong judge model, and spot-check .routeaudit/grades.jsonl.
How many requests do I need? At least 10 graded answers per task type before anything is recommended, and 30 or more for confident numbers. The report shows a 95% range for every pass rate.
Does it handle agents and tool calls? Not yet. Version 0.1 covers single requests, such as chat, extraction, classification and drafting. Agent turns are skipped on import.
Is this a router? No. It audits routing and produces a policy. Put the policy in the gateway you already use, for example with the LiteLLM export.
Development
uv sync
uv run pytest
uv run ruff check . && uv run ruff format --check .
Issues and pull requests are welcome. See CONTRIBUTING.md.
License
MIT © 2026 Muhammad Idnan
1 maintainer

Metadata
1 maintainer
Release files for llm-route-audit 0.1.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| llm_route_audit-0.1.0.tar.gz | 115.9 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| llm_route_audit-0.1.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 186.8 kB
Release files / llm_route_audit-0.1.0.tar.gz
| Download URL | llm_route_audit-0.1.0.tar.gz |
|---|---|
| Size | 115.9 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
83a3b2282fd239d68418c6b1be24ed73d7a6819be4e2d32ca70ce1db570571d3
|
|
BLAKE2b-256 checksum How to use checksums |
a058d00330407c8fa07832997213d9a7ca0f1d63cde9ba4d32e9f5766c09f47c
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.9.22 {"installer":{"name":"uv","version":"0.9.22","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|
Release files / llm_route_audit-0.1.0-py3-none-any.whl
| Download URL | llm_route_audit-0.1.0-py3-none-any.whl |
|---|---|
| Size | 70.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
af2f63202f980ed69ca1c9060170223163a02afa30da4d2d5a6471cbfc1e19b9
|
|
BLAKE2b-256 checksum How to use checksums |
682d200a38db74dc385feb28a834c9ac124866a9b54ca6b5e0dd49da52b03f0f
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
uv/0.9.22 {"installer":{"name":"uv","version":"0.9.22","subcommand":["publish"]},"python":null,"implementation":{"name":null,"version":null},"distro":null,"system":{"name":null,"release":null},"cpu":null,"openssl_version":null,"setuptools_version":null,"rustc_version":null,"ci":null}
|














