
MacSmart LLM


Memory-intelligent local LLM orchestration for 16GB Apple Silicon Macs.
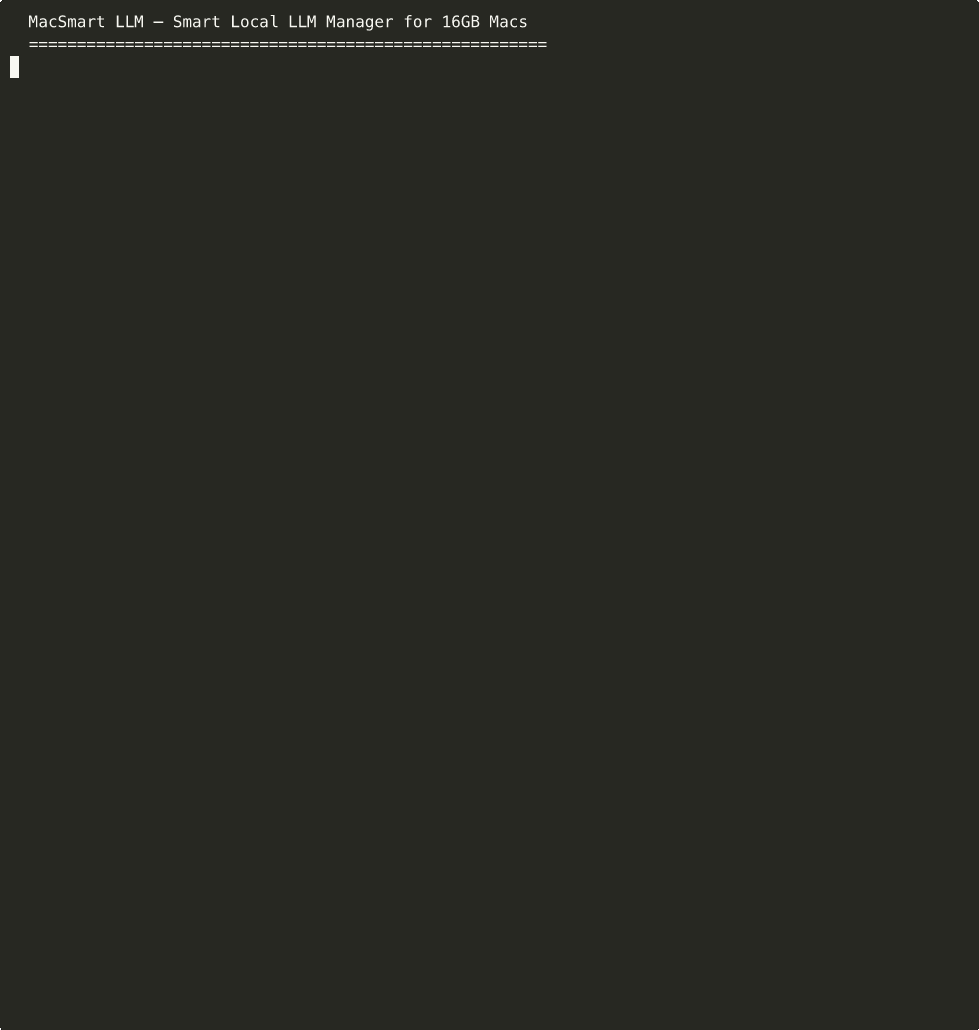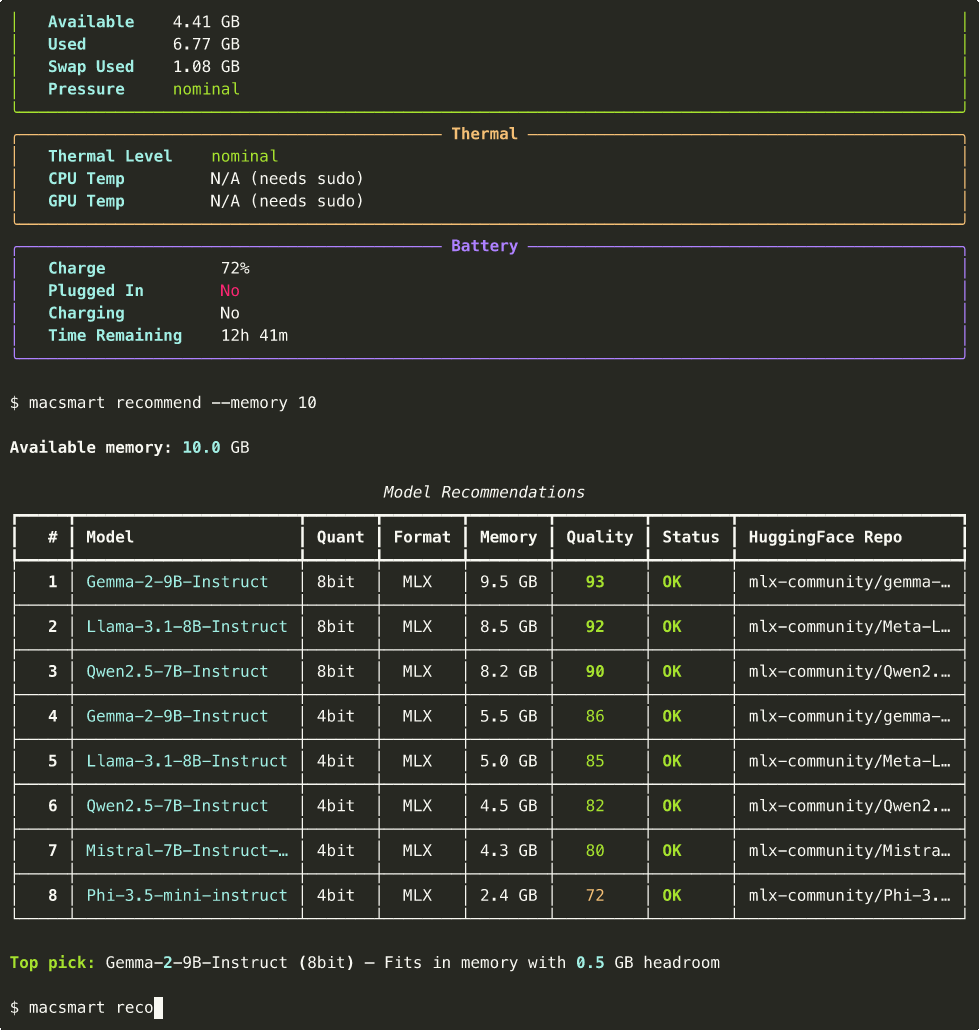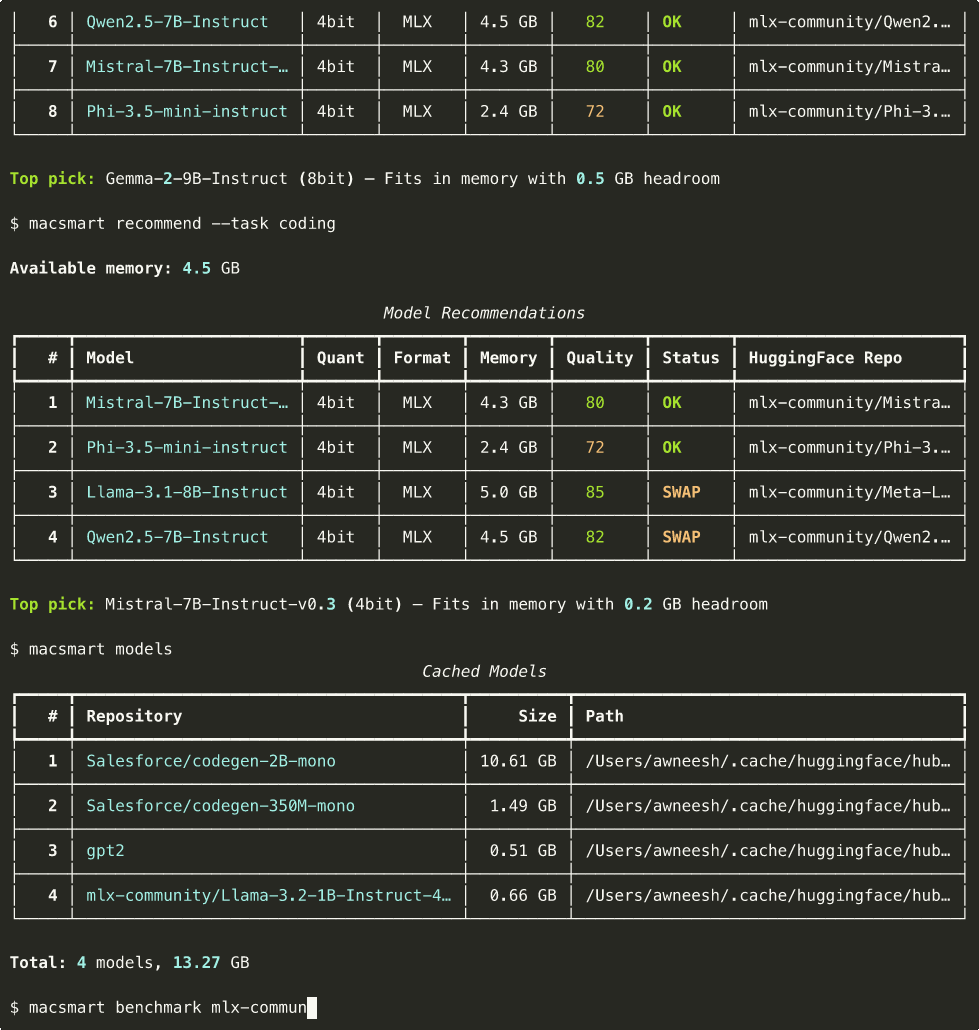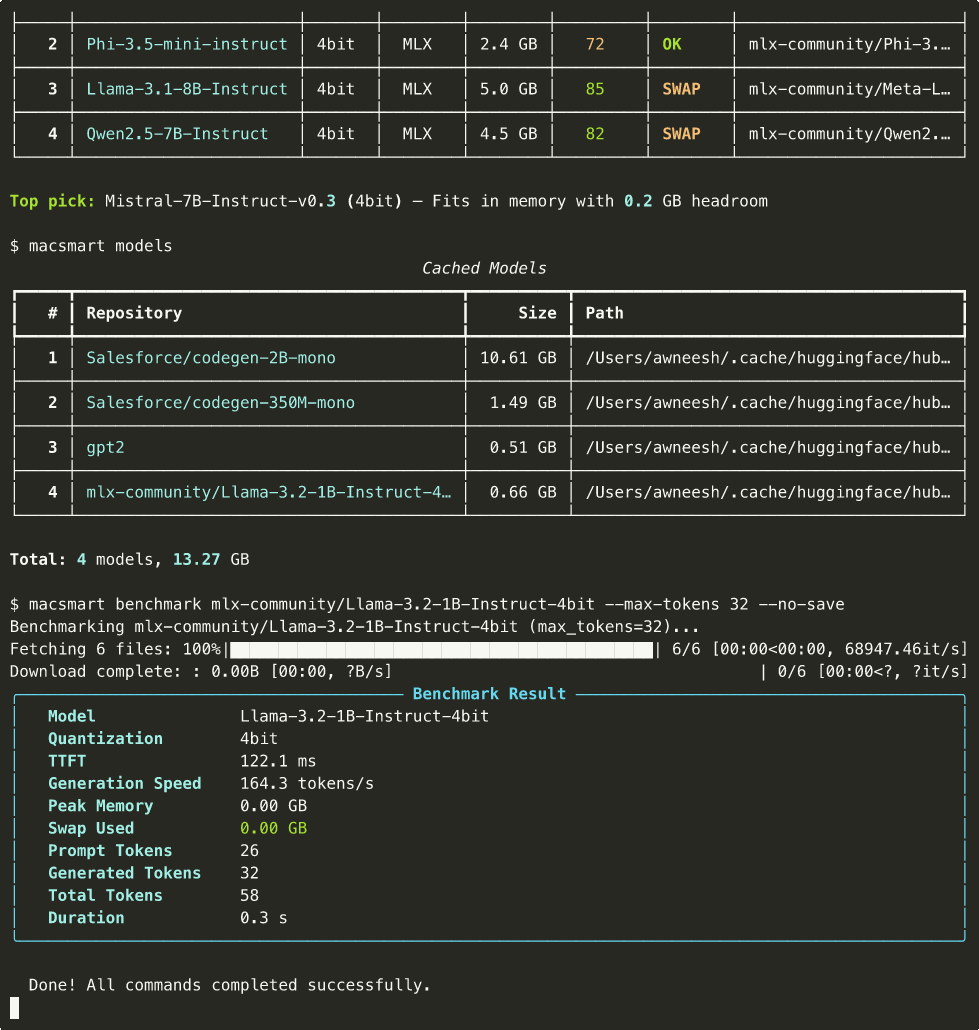
Unlike LM Studio or Ollama which treat all Macs the same, MacSmart actively monitors available memory, thermal state, and battery level to recommend and manage the best model + quantization for your current system state.
Why?
- 16GB is the most common MacBook config but completely ignored by benchmarking research
- Existing tools let users download models that crash or swap-thrash on 16GB
- No tool auto-selects the best model/quantization based on actual available memory
- Apple Silicon Neural Accelerators (via MLX) are untapped on 16GB configs
Features
- System Profiler — Detect chip (M1–M5), GPU cores, memory bandwidth, thermal state, battery
- Model Recommender — Auto-select the best model + quantization for your available memory
- Benchmark Runner — Measure TTFT, tokens/sec, peak memory, swap usage, energy
- Batch & Compare — Run multiple models head-to-head with side-by-side results
- Energy Comparison — Compare energy efficiency across prompt lengths
- Memory Watchdog — Real-time memory pressure monitoring with live Rich UI
- Download Manager — Download, list, and manage models from HuggingFace Hub
- Dashboard — Interactive web UI for exploring benchmark results
Installation
# Install from PyPI
pip install macsmart

# Or install from source (for development)
git clone https://github.com/awneesht/m5-llm-benchmark.git
cd m5-llm-benchmark
pip install -e ".[dev]"
Usage
# Show system profile (chip, memory, thermal, battery)
macsmart profile

# Get model recommendations for your current memory
macsmart recommend

# Recommend for a specific task with custom memory budget
macsmart recommend --task coding --memory 10

# Run inference on a model
macsmart run mlx-community/Qwen2.5-7B-Instruct-4bit --prompt "Hello, world!"

# Download a model
macsmart download mlx-community/Qwen2.5-7B-Instruct-4bit

# List cached models
macsmart models

# Benchmark a model
macsmart benchmark mlx-community/Qwen2.5-7B-Instruct-4bit

# Batch benchmark multiple models
macsmart batch model1 model2 model3

# Compare models side-by-side
macsmart compare model1 model2

# Compare energy efficiency across prompt lengths
macsmart energy-compare model1 model2

# Launch the results dashboard
macsmart dashboard

# Watch memory pressure in real-time
macsmart watch

# Delete a cached model
macsmart delete mlx-community/Qwen2.5-7B-Instruct-4bit

# All commands support --json-output for scripting
macsmart profile --json-output
macsmart recommend --json-output
16GB Memory Budget
| Component | Memory |
|---|---|
| macOS + system | ~3–4 GB |
| Typical user apps | ~1–2 GB |
| Available for LLM | ~10–12 GB |
| Safe model size (no swap) | ~8–9 GB |
| Max model size (some swap OK) | ~12–14 GB |
Requirements
- macOS with Apple Silicon (M1/M2/M3/M4/M5)
- Python 3.11+
- 16GB RAM (optimized for this config, works on others too)
Development
# Install dev dependencies
pip install -e ".[dev]"

# Run tests
pytest

# Run with coverage
pytest --cov=macsmart

# Run a single test file
pytest tests/test_benchmark.py -v
License
MIT
1 maintainer

Metadata
1 maintainer
Release files for macsmart 0.2.2
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| macsmart-0.2.2.tar.gz | 59.7 kB | Without provenance | Details for macsmart-0.2.2.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| macsmart-0.2.2-py3-none-any.whl | Python 3 | none | any | Details for macsmart-0.2.2-py3-none-any.whl |
Total release size: 108.3 kB
Release files / macsmart-0.2.2.tar.gz
| Download URL | macsmart-0.2.2.tar.gz |
|---|---|
| Size | 59.7 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
fa28df466b0dde674ac2ebad1dd3877b21b5a6c65d70de1629583e1060e4189a
|
|
BLAKE2b-256 checksum How to use checksums |
18a1d691b847faa88a42732379aeb114a255dfe61d2f53fbcef51ea51b80ea6d
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.14.3
|
Release files / macsmart-0.2.2-py3-none-any.whl
| Download URL | macsmart-0.2.2-py3-none-any.whl |
|---|---|
| Size | 48.6 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
a63198d0b08be8589a1df5269bee9d6b75d655f31ab2f8c85dbbad4b485ae66e
|
|
BLAKE2b-256 checksum How to use checksums |
16e5e5c8465018a47b052e503aefd4e18e8e8c886d359f46f9c24523b74b5109
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/6.2.0 CPython/3.14.3
|
Security for macsmart 0.2.2
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














