
MaldiDeepKit


A catalogue of sklearn-compatible deep learning classifiers for MALDI-TOF binned spectra
Installation • Features • Quick start • Documentation • Tutorials • MaldiSuite • Contributing • Citing • License
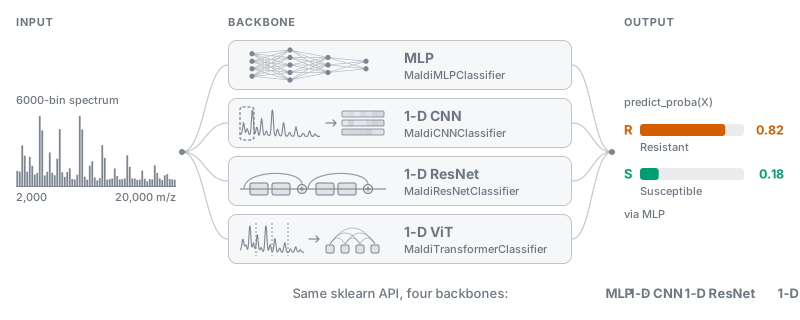
MaldiDeepKit provides four PyTorch backbones (MLP, 1-D CNN, 1-D ResNet, and 1-D Vision Transformer), a dual-branch classifier for a spectrum plus side features, a self-training classifier for partly labelled data, and a self-supervised encoder that pre-trains the backbones on unlabelled spectra. All of them share one scikit-learn estimator API, with defaults set for 6000-bin MALDI-TOF spectra. It is part of the MaldiSuite ecosystem: it can be used on its own, or together with MaldiAMRKit and MaldiBatchKit.
Installation
pip install maldideepkit
maldiamrkit is a core dependency and is installed automatically (MaldiDeepKit duck-types on the MaldiSet data model and reuses maldiamrkit.alignment.Warping for leak-safe spectral warping).
To enable the Laplace-approximation estimator in maldideepkit.uncertainty, install the optional uncertainty extra (pulls in laplace-torch):
pip install "maldideepkit[uncertainty]"
Monte Carlo Dropout and split conformal prediction work without any extra.
The smiles_to_fingerprint helper used in MaldiDualBranchClassifier workflows requires RDKit, available via the rdkit extra:
pip install "maldideepkit[rdkit]"
Install the full MaldiSuite
To install MaldiDeepKit together with MaldiAMRKit and MaldiBatchKit at compatible versions, install the maldisuite meta-package:
pip install maldisuite
Visit the MaldiSuite landing page at https://ettorerocchi.github.io/MaldiSuite/.
Development installation
git clone https://github.com/EttoreRocchi/MaldiDeepKit.git
cd MaldiDeepKit
pip install -e ".[dev]"
pre-commit install
See CONTRIBUTING.md for coding conventions, testing, and PR guidelines.
Features
- Unified scikit-learn API (
BaseEstimator+ClassifierMixin) for every classifier:fit,predict,predict_proba,score,get_params, andset_params, so each one works inPipeline,cross_val_score, andGridSearchCV. - Four PyTorch architectures sharing the same base class and parameters:
MaldiMLPClassifier- MLP with optional sigmoid-gated attention on the first hidden layer.MaldiCNNClassifier- 1-D Conv1D + BatchNorm + ReLU + MaxPool blocks for local pattern learning.MaldiResNetClassifier- 1-D ResNet-18-style residual blocks for a deeper convolutional backbone.MaldiTransformerClassifier- 1-D Vision Transformer with global self-attention, pre-norm, LayerScale, and stochastic depth.
- MALDI-TOF defaults: kernel sizes, depths, patch widths, and warmup / cosine-annealing schedules are tuned for 6000-bin spectra in the 2000-20000 Da range.
- Auto-scaling for non-default layouts: the four architectures and the dual-branch classifier have a
from_spectrum(bin_width, input_dim, **overrides)factory, which setsinput_dimand scales the conv kernels of the CNN and the ResNet to the bin width. See the Spectrum scaling guide. - Training recipes: AdamW when
weight_decay > 0, gradient clipping, linear warmup and cosine annealing, focal loss, label smoothing, mixed precision (AMP), Stochastic Weight Averaging, Sharpness-Aware Minimization, post-hoc threshold tuning, and temperature scaling, all set through classifier parameters. - Leak-safe spectral warping: pass any sklearn-style transformer (such as
maldiamrkit.alignment.Warping) aswarping=; it is fitted on the training split only, then applied to both splits during training and to new spectra atpredicttime, before per-feature standardisation. - MaldiSet integration: pass a
maldiamrkit.MaldiSetdirectly tofit/predict; MaldiDeepKit reads its DataFrame-like.Xattribute. - Persistence:
save()writes a state-dict.ptplus a hyperparameter.json(and a.warper.pklwhen a warper was fitted);load()raises on a class mismatch, andpredicton a wrong number of bins. - Uncertainty quantification: the
maldideepkit.uncertaintysubpackage has three drop-in estimators sharing onepredict_with_uncertaintyinterface:MCDropoutEstimator(Monte Carlo Dropout with epistemic / aleatoric decomposition),LaplaceEstimator(last-layer or full-network Laplace through the optionallaplace-torchdependency), andConformalPredictor(split conformal prediction with the LAC non-conformity score). - Extensible: choose the optimiser, scheduler, loss, and callbacks of every architecture and of the dual-branch classifier; custom backbones and pre-text tasks work wherever a built-in one does (see Choosing the training components).
- Self-supervised pre-training:
MaldiSpectrumEncoderpre-trains any of the four backbones on unlabelled spectra (masked reconstruction, intensity-weighted bin shuffling, both combined, or contrastive views, with an optional semi-supervised auxiliary head); classifiers start their trunk from it withinit_from=and can train only the final layer first withfreeze_trunk_epochs=. See Self-supervised pre-training. - GPU or CPU: with the default
device="auto", every classifier trains on a CUDA GPU when one is available and on CPU otherwise.
Documentation
Full documentation is available at maldideepkit.readthedocs.io.
Quick start
Fit a classifier
Every MaldiDeepKit classifier exposes the standard scikit-learn estimator API. Swapping architectures is a one-line change:
import numpy as np
from maldideepkit import MaldiMLPClassifier

rng = np.random.default_rng(0)
X = rng.standard_normal((200, 6000)).astype("float32")  # 200 binned spectra
y = rng.integers(0, 2, size=200)

clf = MaldiMLPClassifier(random_state=0)
clf.fit(X, y)

proba = clf.predict_proba(X)
preds = clf.predict(X)
acc = clf.score(X, y)

# Inspect attention weights (MLP only)
weights = clf.get_attention_weights(X[:10])  # (10, hidden_dim)
Inside a scikit-learn Pipeline
from sklearn.model_selection import StratifiedKFold, cross_val_score
from sklearn.pipeline import Pipeline
from sklearn.preprocessing import StandardScaler
from maldideepkit import MaldiCNNClassifier

pipe = Pipeline([
    ("scaler", StandardScaler()),
    ("clf", MaldiCNNClassifier(random_state=0)),
])

cv = StratifiedKFold(n_splits=5, shuffle=True, random_state=0)
scores = cross_val_score(pipe, X, y, cv=cv, scoring="accuracy")
print(f"CV accuracy: {scores.mean():.3f} ± {scores.std():.3f}")
MaldiSet integration
A MaldiAMRKit MaldiSet can be passed directly:
from maldiamrkit import MaldiSet
from maldideepkit import MaldiCNNClassifier

ds = MaldiSet.from_directory(
    "spectra/", "metadata.csv",
    aggregate_by={"antibiotics": "Ciprofloxacin"},
    n_jobs=-1,
)
clf = MaldiCNNClassifier(random_state=0).fit(ds, ds.y.squeeze())
preds = clf.predict(ds)
Auto-scaling for custom layouts
When the spectrum layout deviates from the reference 6000-bin / 3 Da default, from_spectrum rescales the conv kernels:
from maldideepkit import MaldiCNNClassifier, MaldiTransformerClassifier

# Reference layout (kernel_size=7, patch_size=4)
cnn = MaldiCNNClassifier.from_spectrum(bin_width=3, input_dim=6000)

# Wider bins -> smaller kernel
cnn_coarse = MaldiCNNClassifier.from_spectrum(bin_width=6, input_dim=3000)

# Transformer is scale-agnostic; only input_dim is recorded
tr = MaldiTransformerClassifier.from_spectrum(bin_width=1, input_dim=18000)
See the Spectrum scaling guide for how each parameter is scaled.
Save and load
clf.save("my_model")
# -> my_model.pt, my_model.json, my_model.warper.pkl (if warping was used)
restored = MaldiCNNClassifier.load("my_model")
For more examples covering training recipes, calibration, and attention inspection, see the Quickstart guide and, for ensembles, the API reference.
Algorithms
| Classifier | Backbone | Typical use case |
|---|---|---|
MaldiMLPClassifier |
MLP + optional sigmoid-gated attention | Fast baseline with inspectable attention gates |
MaldiCNNClassifier |
1-D Conv1D + BatchNorm + ReLU + MaxPool blocks | Local pattern learning from binned spectra |
MaldiResNetClassifier |
1-D ResNet-18-style residual blocks | Deeper convolutional backbone |
MaldiTransformerClassifier |
1-D Vision Transformer (LayerScale, stochastic depth) | Long-range peak combinations through global self-attention |
MaldiDualBranchClassifier |
Spectrum branch + per-row side-feature branch + fused head | Multi-modal: condition on an antibiotic fingerprint, instrument ID, patient feature, ... |
All five inherit from BaseSpectralClassifier (or its dual-input subclass BaseDualSpectralClassifier) and share the same parameters for optimisation, device placement, early stopping, calibration, and persistence.
Semi-supervised wrapper
| Class | Purpose |
|---|---|
MaldiSelfTrainingClassifier |
Iterative pseudo-labelling on a labelled seed plus an unlabelled pool (rows marked -1 by default). Wraps any classifier (defaults to MaldiMLPClassifier); follows the sklearn.semi_supervised.SelfTrainingClassifier API. |
Self-supervised encoder
| Class | Purpose |
|---|---|
MaldiSpectrumEncoder |
Self-supervised pre-training of a backbone on unlabelled (or partially labelled) spectra; scikit-learn transformer returning (n_samples, feature_dim_) embeddings, with save / load. Its checkpoint initialises a classifier through init_from= (see Self-supervised pre-training). |
Shared training parameters
| Feature | Parameter | Notes |
|---|---|---|
| Decoupled weight decay | weight_decay |
Switches Adam to AdamW when > 0. Default 0 (MLP/CNN), 1e-4 (ResNet), 0.05 (Transformer). |
| Gradient clipping | grad_clip_norm |
clip_grad_norm_ before every step. Default on (1.0) for the deep models. |
| Warmup + cosine annealing | warmup_epochs |
Epochs of linear warmup before the cosine schedule (scheduler="cosine", the default). Default 5 (deep models), 0 (MLP/CNN). |
| Stochastic depth (Transformer) | drop_path_rate |
Linearly ramped across blocks. Default 0.1. |
| LayerScale (Transformer) | layerscale_init |
Per-channel residual scaling initialised near zero (crucial on small cohorts). |
| Focal loss | loss="focal" + focal_gamma |
For imbalanced binary problems. |
| Label smoothing | label_smoothing |
Passed to both cross-entropy and focal paths. |
| Mixed precision | use_amp + amp_dtype |
Autocast on a GPU; amp_dtype is "float16" (default, with a GradScaler), "bfloat16", or "auto" (bfloat16 when the GPU supports it). |
| Stochastic Weight Averaging | swa_start_epoch |
AveragedModel replaces best-val at end of fit. |
| Threshold tuning | tune_threshold |
Binary only; sweeps balanced-accuracy / F1 / Youden on val. |
| Temperature scaling | calibrate_temperature |
One-parameter LBFGS calibration on val logits. |
| Sharpness-Aware Minimization | use_sam + sam_rho |
Two-pass training, ~2× compute. |
| Spectral warping | warping |
Any Warping-like scikit-learn transformer; fitted on train only, applied before standardisation. |
| Per-sample weighting | sample_weight (fit) |
sklearn-style weighted-mean loss; composes with class_weight and flows into early stopping, threshold tuning, and temperature scaling. |
| Warm-start / resume | warm_start (fit) |
Reuse the existing fitted module as the training start point (continual, federated, or fine-tuning). |
| Self-supervised initialisation | init_from |
Encoder checkpoint path or fitted MaldiSpectrumEncoder; copies the trunk and inherits the encoder's fitted preprocessing. |
| Linear probing then fine-tuning | freeze_trunk_epochs |
Train only the final layer for the first N epochs, then unfreeze the trunk (LP-FT). Default 0. |
| Compiled training | torch_compile |
Train through torch.compile (default False); the fitted module, checkpoints, init_from, and inference stay uncompiled. Pays off on long GPU runs. |
Utilities
maldideepkit.utils exposes:
find_lr(clf, X, y)- learning-rate finder.tune_threshold/fit_temperature- post-hoc calibrators usable standalone.FocalLoss,SAMOptimizer- loss / optimiser building blocks for custom training loops. Composablenn.Moduleprimitives (DropPath,PatchEmbed1D, the full backbones) live undermaldideepkit.blocks.SpectralEnsemble(classifiers)- averages thepredict_probaof several classifiers (fitted members, or instances and names thatfittrains); a scikit-learn estimator withsave/load.
Self-supervised pre-training
MaldiSpectrumEncoder (from maldideepkit or maldideepkit.pretraining) pre-trains any of the four backbones on unlabelled spectra with a self-supervised pre-text task: pretext="mae" (masked-bin reconstruction, the default), "shuffle" (detect bins swapped between spectra, sampled proportionally to intensity), "shuffle+mae", or "contrastive" (NT-Xent on two augmented views). With aux_lambda > 0 an auxiliary head is also trained on the labelled rows of a partial y (classification or regression; unlabelled rows marked -1 or NaN). A classifier then starts its trunk (every layer except the final one) from the encoder with init_from= and is fine-tuned on the labelled data:
import numpy as np
from sklearn.base import clone
from maldideepkit import MaldiCNNClassifier, MaldiSpectrumEncoder

rng = np.random.default_rng(0)
X_pool = np.abs(rng.standard_normal((2000, 6000))).astype("float32")  # unlabeled spectra
X = np.abs(rng.standard_normal((200, 6000))).astype("float32")        # labeled spectra
y = rng.integers(0, 2, size=200)

# 1. Pre-train the backbone of the classifier you will fine-tune: the
#    template fixes both the architecture and the preprocessing.
template = MaldiCNNClassifier(random_state=0)
encoder = MaldiSpectrumEncoder(backbone=template, pretext="mae", random_state=0)
encoder.fit(X_pool)                 # no labels needed
encoder.save("cnn_encoder")         # -> cnn_encoder.pt, cnn_encoder.json
Z = encoder.transform(X)            # (200, encoder.feature_dim_) embeddings

# 2. Fine-tune: trunk from the encoder, fresh final layer, encoder preprocessing.
clf = clone(template).set_params(init_from="cnn_encoder").fit(X, y)

# 3. LP-FT: only the final layer for 10 epochs, then the whole network.
lpft = clone(template).set_params(init_from="cnn_encoder", freeze_trunk_epochs=10)
lpft.fit(X, y)
print(lpft.trunk_unfroze_, lpft.best_epoch_phase_)  # unfreeze reached? phase of the kept weights
- Preprocessing comes from the template: the encoder fits the template's
standardize,input_transform, andwarpingon the pool, and a classifier withinit_fromreuses that fitted state (a mismatch raisesValueError). - Linear probing first:
freeze_trunk_epochs=ktrains only the final layer forkepochs, then the whole network (LP-FT);trunk_unfroze_andbest_epoch_phase_report what happened. - Clone-safe: give
init_froma checkpoint path inGridSearchCV,cross_val_score, orMaldiSelfTrainingClassifier; a fitted encoder instance is shared by reference across clones. - Dual-branch:
MaldiDualBranchClassifiertakesinit_fromandfreeze_trunk_epochsfor its spectral branch. - Pre-text tasks:
pretext=takes a name or aPretextinstance (MAEPretext,ShufflePretext,ShuffleMAEPretext,ContrastivePretext, or your own subclass);register_pretextadds a name, and a task withuses_target = Truereceives theygiven tofit. - Contrastive views:
augment=SpectrumAugment(...)replaces the default views ofpretext="contrastive". - GPU throughput:
data_device="auto"keeps the pool on the GPU when it fits, andtorch_compile=Truecompiles the model forfit. - Custom backbones: a
BaseSpectralClassifiersubclass works wherever a built-in one does, andregister_backbonegives it a name.
See the Pre-training API reference for the details of each point, a custom pre-text example, the auxiliary head, and the checkpoint format.
Choosing the training components
The four architectures and the dual-branch classifier take these parameters, and MaldiSpectrumEncoder takes all of them except loss (its loss is the pre-text task); with self-training, set them on its base estimator. The defaults are Adam (AdamW when weight_decay > 0), the warmup plus cosine schedule, and cross-entropy.
| Parameter | Accepts |
|---|---|
optimizer |
A torch.optim name ("sgd"), a class, or a factory such as functools.partial(torch.optim.SGD, momentum=0.9). |
scheduler |
"cosine", "constant", or a class or factory called with the optimiser; stepped once per epoch after the warmup. |
loss |
"cross_entropy", "focal", or an nn.Module or function returning one value per row or a scalar. |
callbacks |
Callback objects with the hooks on_train_start, on_epoch_start, on_step_end, on_epoch_end, and on_train_end. |
from functools import partial

import torch
from maldideepkit import Callback, MaldiCNNClassifier


class ValLoss(Callback):
    def __init__(self):
        self.values = []

    def on_epoch_end(self, model, epoch, logs):
        self.values.append(logs["val_loss"])


clf = MaldiCNNClassifier(
    optimizer=partial(torch.optim.SGD, momentum=0.9),
    scheduler=partial(torch.optim.lr_scheduler.StepLR, step_size=10, gamma=0.5),
    loss=torch.nn.CrossEntropyLoss(reduction="none"),
    callbacks=[ValLoss()],
).fit(X_train, y_train)
Z = clf.get_embeddings(X_test)  # (n_samples, feature_dim), as encoder.transform
save stores a class, a function, or a functools.partial by import path; any other object is rebuilt at load from its class and the attributes named after its constructor arguments. A lambda, or a function or class defined inside a function, cannot be saved: clear it first, for example with set_params(optimizer=None). A class defined in a script or notebook is stored under __main__, so define it again before loading (or keep it in an importable module).
With the default trusted=False, load imports no new module: every class named by the checkpoint must come from MaldiDeepKit or from a module you have already imported. On top of that, an object given as optimizer, scheduler, loss or callbacks must be a torch module, optimiser or scheduler, or a Callback, and a function must be defined in MaldiDeepKit or in torch.nn.functional (a few functions exposed there, such as F.gelu, are defined elsewhere). Anything else needs load(path, trusted=True). init_from=<path> always uses the default: for a trusted checkpoint, pass MaldiSpectrumEncoder.load(path, trusted=True). A .warper.pkl is a pickle, read whatever trusted is: load checkpoints with a warper only from trusted sources.
get_embeddings, sample_weight, and save / load work the same way across the architectures, the dual-branch classifier, and self-training, and from_spectrum across the architectures and the dual-branch classifier (a custom BaseSpectralClassifier subclass inherits them).
Tutorials
For more detailed examples, see the notebooks:
- Quick start - Fit a
MaldiMLPClassifierand explore the sklearn-compatible API. - Model comparison - Train all four classifiers on the same dataset and compare AUROC.
- Attention interpretation - Visualise the sigmoid-gated attention learned by
MaldiMLPClassifier. - Cross-validation with augmentation - Cross-validate a CNN with on-the-fly
SpectrumAugmentaugmentation, scored by AUROC on stratified folds. - Uncertainty quantification - MC Dropout, split conformal prediction, and Laplace approximation on a fitted classifier; selective prediction curves.
- Self-supervised pre-training - Pre-train an encoder on unlabelled spectra, fine-tune from it at a few label fractions, and extend it with custom pre-text tasks, backbones, and training components.
MaldiSuite ecosystem
MaldiDeepKit is one of the three packages of the MaldiSuite ecosystem:
- MaldiAMRKit - preprocessing, alignment, peak detection, differential analysis, and classical-ML evaluation for MALDI-TOF AMR workflows.
- MaldiBatchKit - batch-effect correction and harmonisation for multi-centre / multi-instrument MALDI-TOF spectra.
- MaldiDeepKit (this package) - sklearn-compatible deep learning classifiers.
The three packages share the MaldiSet data model. Each can be used on its own, or combined with the others. Install the full suite with pip install maldisuite. Landing page: MaldiSuite.
Requirements
MaldiDeepKit needs Python 3.10 or newer and PyTorch 2.3 or newer (full list in requirements.txt). Every model trains on a CUDA GPU when one is available and on CPU otherwise.
Contributing
Pull requests, bug reports, and feature ideas are welcome. See the Contributing Guide for how to get started.
Citing
MaldiDeepKit is part of MaldiSuite, which is described in an Application Note currently under review at Bioinformatics. The full citation will be added here once the article is published.
See the full publications list for more papers using the MaldiSuite.
License
This project is licensed under the MIT License. See the LICENSE file for details.
Acknowledgements
The architectures and training recipes bundled in MaldiDeepKit are 1-D adaptations of well-established networks. In particular:
ResNet - He K, Zhang X, Ren S, Sun J (2016). Deep Residual Learning for Image Recognition. CVPR. doi:10.1109/CVPR.2016.90
Vision Transformer - Dosovitskiy A, Beyer L, Kolesnikov A, et al. (2021). An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale. ICLR. arXiv:2010.11929
LayerScale - Touvron H, Cord M, Sablayrolles A, et al. (2021). Going deeper with Image Transformers. ICCV. arXiv:2103.17239
Stochastic Depth - Huang G, Sun Y, Liu Z, Sedra D, Weinberger K (2016). Deep Networks with Stochastic Depth. ECCV. arXiv:1603.09382
Temperature Scaling - Guo C, Pleiss G, Sun Y, Weinberger KQ (2017). On Calibration of Modern Neural Networks. ICML. arXiv:1706.04599
Sharpness-Aware Minimization - Foret P, Kleiner A, Mobahi H, Neyshabur B (2021). Sharpness-Aware Minimization for Efficiently Improving Generalization. ICLR. arXiv:2010.01412
1 maintainer

Metadata
1 maintainer
Release files for MaldiDeepKit 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | Provenance | Actions |
|---|---|---|---|---|
| maldideepkit-0.4.0.tar.gz | 257.8 kB | Without provenance | Details for maldideepkit-0.4.0.tar.gz |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Actions Reset |
|---|---|---|---|---|
| maldideepkit-0.4.0-py3-none-any.whl | Python 3 | none | any | Details for maldideepkit-0.4.0-py3-none-any.whl |
Total release size: 439.7 kB
Release files / maldideepkit-0.4.0.tar.gz
| Download URL | maldideepkit-0.4.0.tar.gz |
|---|---|
| Size | 257.8 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
faa3034691db39d0bf7e7cf84c7acc1d7681a25ec6452b98d7482bf520e6f256
|
|
BLAKE2b-256 checksum How to use checksums |
20842b11673c37ef2eaea3ca41bad6a67a675623e29a9dbe72969451435522cd
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.12
|
Release files / maldideepkit-0.4.0-py3-none-any.whl
| Download URL | maldideepkit-0.4.0-py3-none-any.whl |
|---|---|
| Size | 181.9 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
3db6a2a2cec2398a71a30a55229ca92f62f5908a1225d9476ca97da6b8b57b2d
|
|
BLAKE2b-256 checksum How to use checksums |
49529439fda7a3319f9a6a9a533e388078c64e159929e589752c7c6c84ad8a4b
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
No |
| Uploaded via |
twine/7.0.0 CPython/3.10.12
|
Security for MaldiDeepKit 0.4.0
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
No provenance found
None of the files in this release were uploaded with provenance metadata.
A note on package security
PyPI is a repository for distributing packages, not a service for auditing them. While third-party security researchers and our staff do their best to detect and remove malicious packages, PyPI cannot guarantee the quality, security or suitability of any given package.
To learn more about protecting yourself from malicious actors, visit our package security documentation.














