
Markov-K-means
K-means that stops once the only work left is a handful of boundary points changing cluster, then finishes the run with Markov chains: the path of each center tells where it is heading, and each undecided point's label history tells how it splits between clusters.
pip install markov-kmeans
from markov_kmeans import MarkovKMeans

mk = MarkovKMeans(n_clusters=50, random_state=0).fit(X)
mk.labels_                    # hard labels
mk.cluster_centers_           # centers
mk.unstable_indices_          # points still undecided when the run stopped
mk.membership_                # sparse (n, k): one-hot for settled points, a distribution for undecided ones
mk.pseudo_centers_            # where each center was heading (long-run mean of its path)
mk.stop_reason_, mk.regime_   # why it stopped; "drift" or "oscillation"
English
How it works
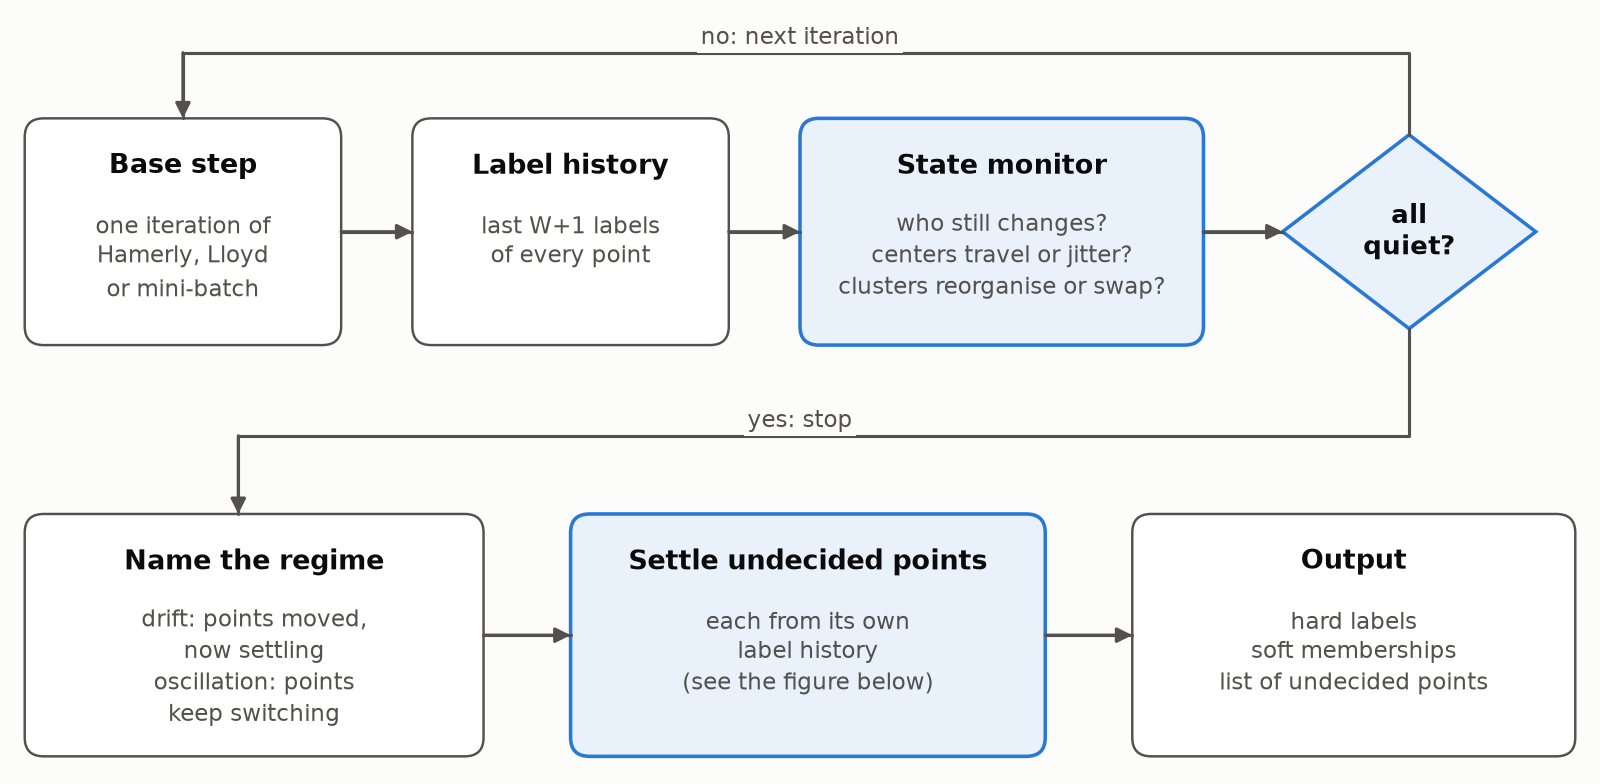
The base algorithm runs as usual while the recent labels of every point and the recent positions of the centers are kept. After each iteration a monitor asks three questions about the whole run, cheapest first. Once all three answers are quiet, the run stops.
| check | question | quiet when |
|---|---|---|
| Movement | Who still changes cluster? | almost no point changes, the changes are dying out, or the same points keep switching in steady numbers |
| Representatives | Are the centers travelling, or jittering in place? | the centers barely move, or only jitter around fixed positions |
| Partitions | Are the clusters reorganising, or only swapping members? | cluster sizes are steady, and few members move or they move both ways |
At the stop, two kinds of Markov chains finish the run.
1. The centers' chains give pseudo representatives. Each center's recent path is read as a chain that keeps stepping the same way. Its long-run position is where a converging center is heading, or the middle of a center that only jitters. Every point is then assigned to its nearest pseudo representative. This moves, right away, the points that are about to cross a boundary but have not moved yet, which no label history can see. The new labels are kept only if they fit the data at least as well as the old ones.
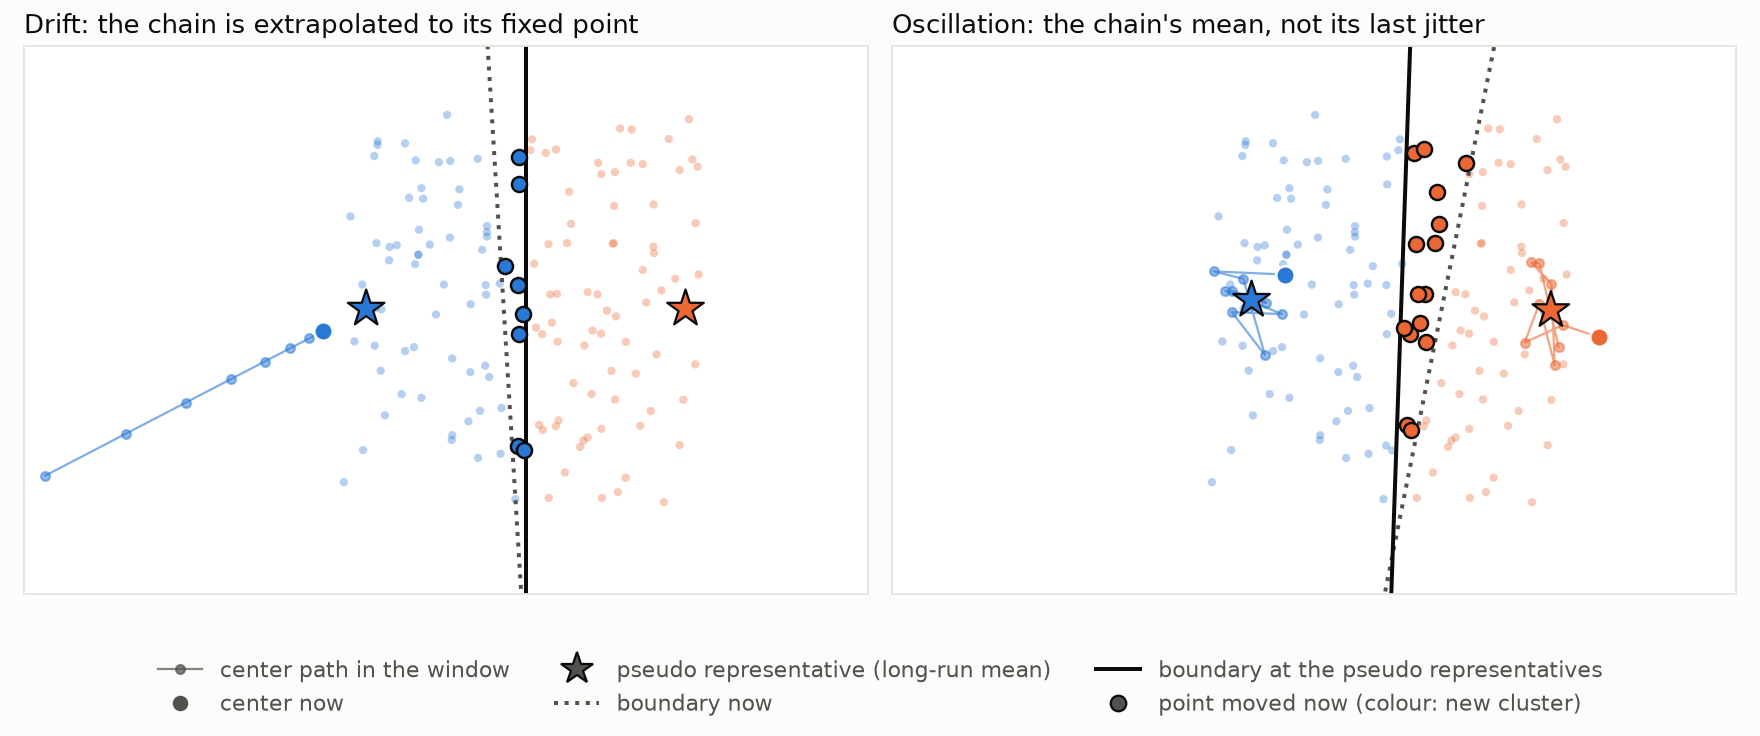
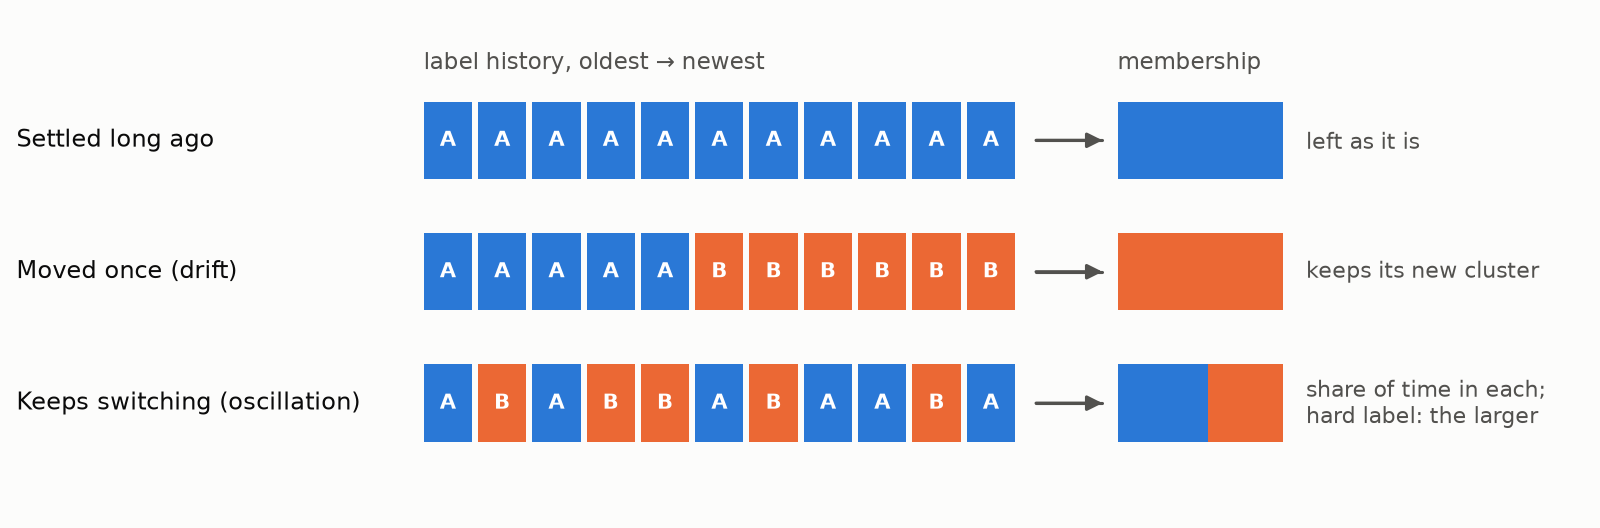
2. The labels' chains settle the undecided points. The undecided points are those that changed cluster in the window, plus those the pseudo representatives just moved. Each gets a membership from its own label history:
| undecided point | membership |
|---|---|
| moved once and stayed (drift) | its cluster |
| keeps switching (oscillation) | its share of time in each cluster |
| just moved by the pseudo representatives | mostly its new cluster, some of the old one; the later its boundary would have crossed it, the more of the old |
When the monitor diagnoses an oscillation, every point that changed in the window gets its share of time. Hard labels come from the pseudo representatives; if their labels were not kept, from the larger share.
Where the time of a run goes
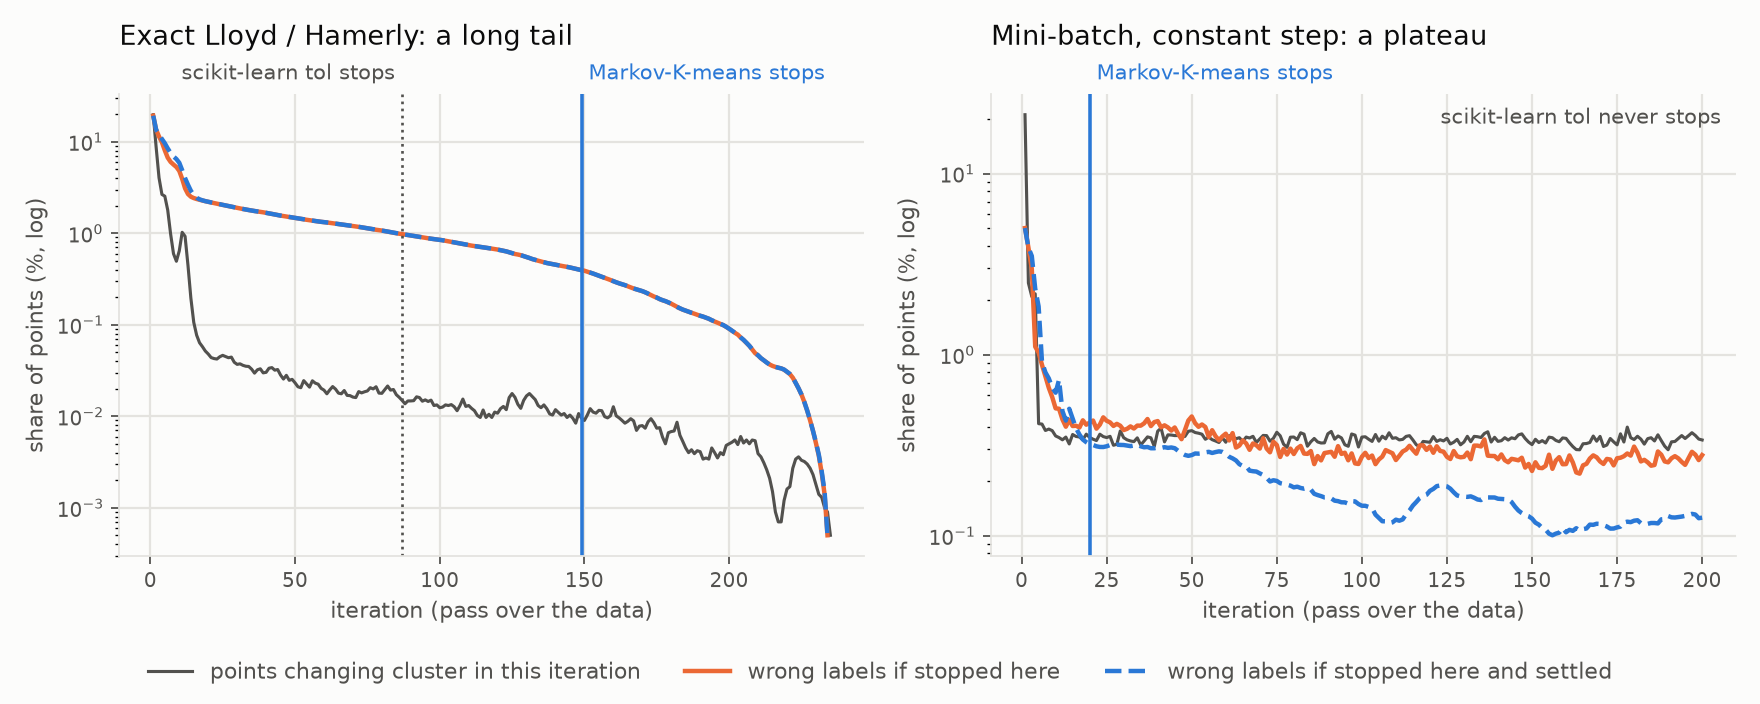
Exact Lloyd (left). After the early iterations only a tiny share of points still change cluster, yet the run goes on for many more passes over the data. That tail is what Markov-K-means cuts. Most labels that are still wrong at a stop belong to points that have not started to move, so their label histories say nothing: settling from the histories alone (green) gives the same labels as stopping and keeping them. The pseudo representatives (blue) see where the centers are heading and move part of those points in advance, so the blue line runs below the others at every stop.
Constant step (right). After a quick drop, the number of changing points stops falling. The run sits on a plateau, and the share of wrong labels barely moves however long it runs. Once on the plateau, settling the switching points from their history leaves fewer wrong labels than keeping the current ones, and the gap widens as the run goes on. Averaging the jittering centers adds a little more. The automatic rule stops as soon as the plateau is reached. A later fixed stop (t0) with settlement buys a lower error for more time.
Time versus error, compared with other stopping rules
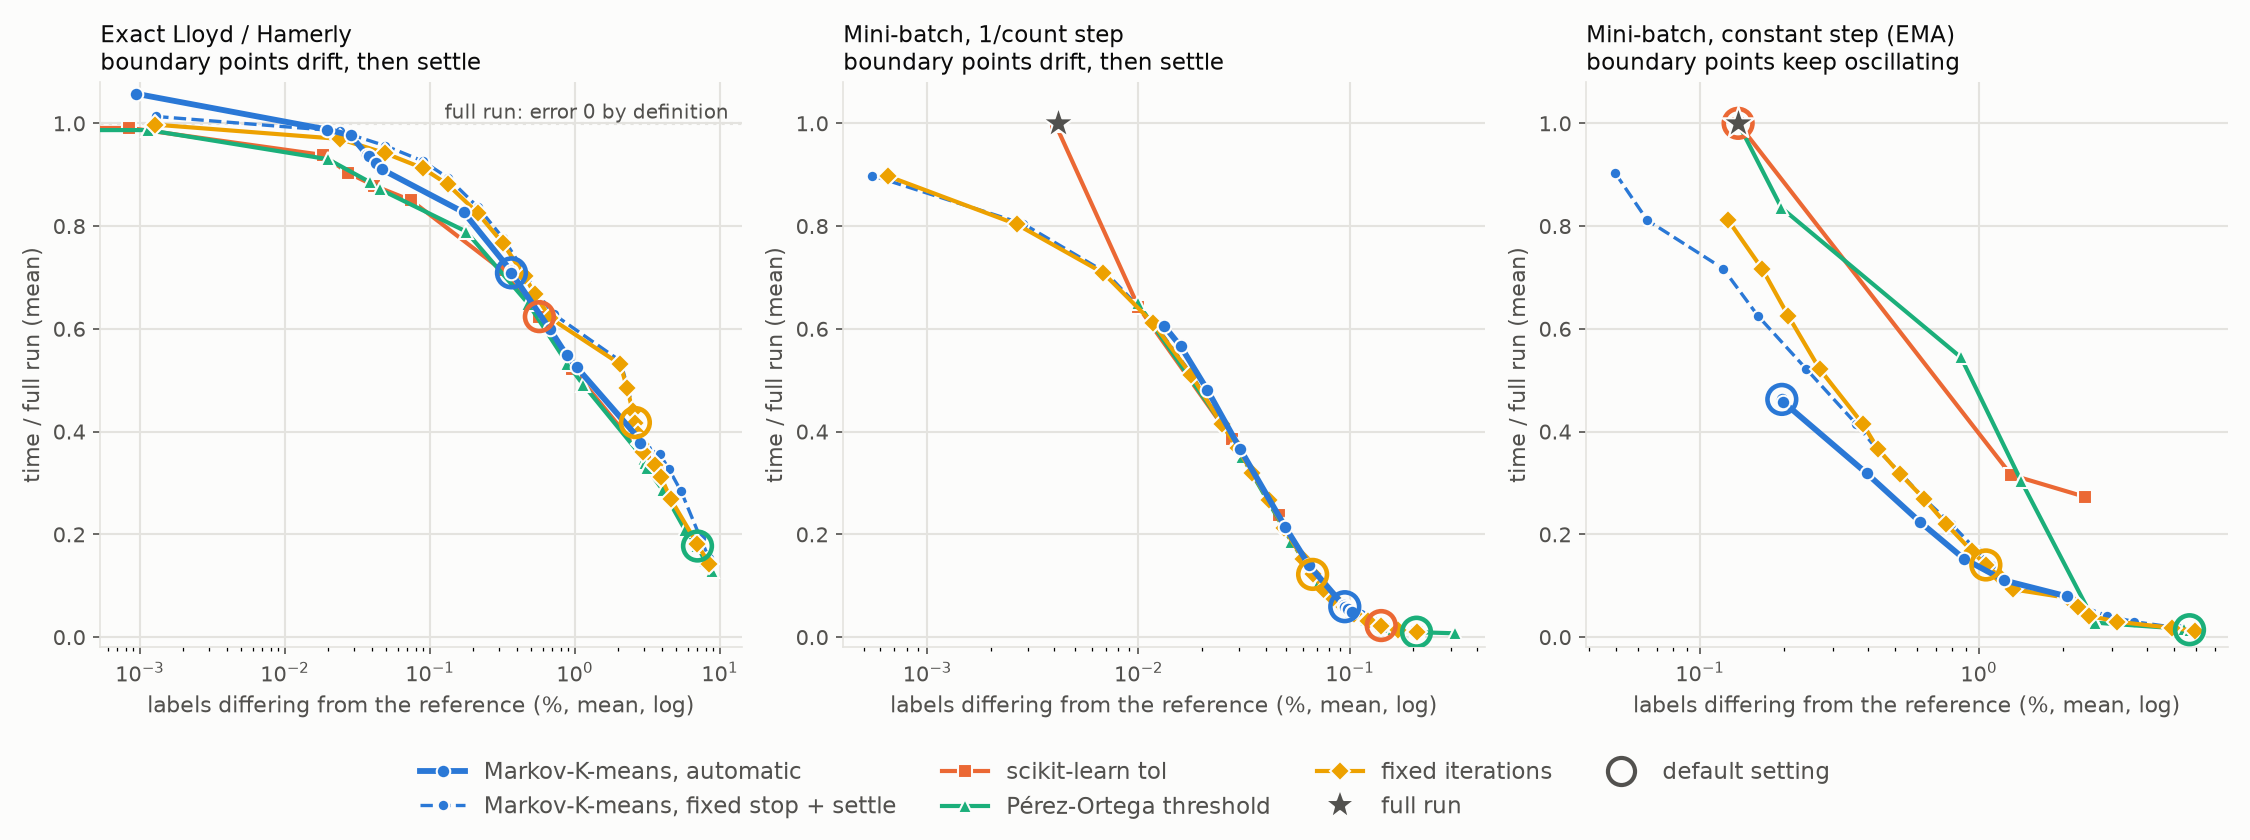
Each line is one stopping rule with its own setting swept. Every setting is applied unchanged to all datasets of a panel, as a user would choose it without knowing the outcome. A point gives the average error (labels that differ from the reference partition) and the average time relative to running to the end. Lower and further left is better. Circles mark the default settings.
| constant step / EMA | 1/count mini-batch | exact Lloyd / Hamerly | |
|---|---|---|---|
| Markov-K-means, automatic | fastest at every error level it reaches | fastest for precise answers; slower for rough ones, because it first watches a full window | on the shared curve, slightly behind a tuned threshold |
| Markov-K-means, fixed stop | the only rule that goes below the full run's error | goes below the full run's error | slightly above the shared curve |
scikit-learn tol |
never stops at its default | on the shared curve | on the shared curve; slightly ahead when tuned |
| Pérez-Ortega threshold | stops too early or too late | on the shared curve | on the shared curve; slightly ahead when tuned |
| fixed iterations | stops at an arbitrary moment of the oscillation | on the shared curve | on the shared curve |
| where the defaults land | Markov-K-means: low error; scikit-learn: runs to the end; Pérez-Ortega: fast but rough | all at low error and little time | Markov-K-means and scikit-learn: low error; Pérez-Ortega and fixed iterations: fast but rough |
In short, each unit of error costs Markov-K-means the least time when training oscillates, and with 1/count mini-batch when a precise answer is needed. On exact Lloyd it costs slightly more than a threshold tuned for the data. The pseudo representatives lower the error at each stop on exact Lloyd too, but there the error jumps between stops are larger than the gain, so the curve barely moves.
On real satellite images
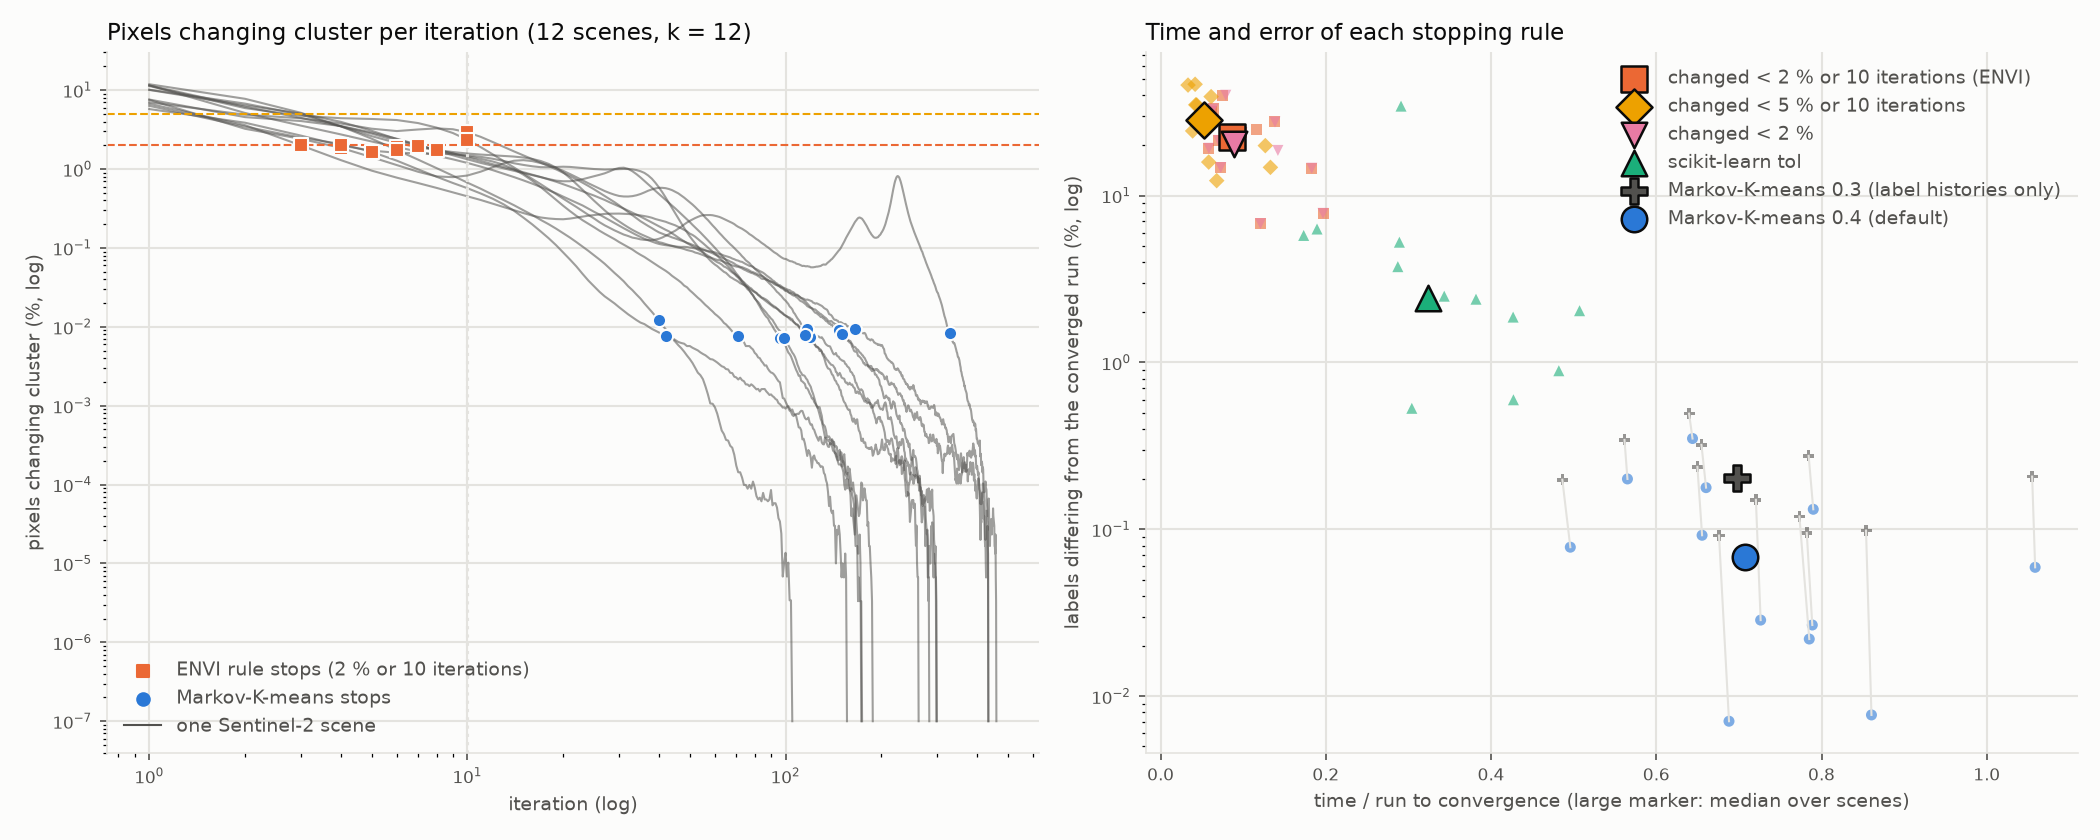
Twelve Sentinel-2 scenes from very different landscapes, each with about thirty million pixels, were clustered with exact K-means until no pixel changed. Every stopping rule was judged on the same run.
| stopping rule | where it stops | how far from the converged map |
|---|---|---|
| remote-sensing default: fewer than 2 % of pixels changed, or 10 iterations | very early | a large share of pixels labelled differently, though the aggregate fit is close |
| scikit-learn tolerance | about a third of the way | usually close, but far off when clusters reorganise late |
| Markov-K-means, label histories only (0.3) | later, at a point that differs from scene to scene | close to the converged map in every scene |
| Markov-K-means (0.4) | the same stop | closer still in every scene: about two thirds of the remaining difference is gone, for almost no extra time |
The tail is real on satellite images, and the right number of iterations varies so much between scenes that no fixed setting reaches the converged map everywhere. Markov-K-means is the only rule that gets there in every scene without tuning. Almost every pixel still wrong at its stop had not started to move, which is exactly what the pseudo representatives are for: nearly all the pixels they move end where the converged run puts them. The time saved is moderate, because late iterations on low-dimensional imagery are already cheap. The undecided list and soft memberships carry little information here: the scenes settle by drift, and a simple distance ratio flags mixed pixels better.
Where it applies
| base algorithm | boundary points | what Markov-K-means adds |
|---|---|---|
exact Lloyd: "hamerly" (default), "lloyd" |
drift, then settle | cuts the tail without a tuned threshold; lists the undecided points |
1/count mini-batch, as in scikit-learn's MiniBatchKMeans: "minibatch" |
drift, then settle | the same |
constant-step mini-batch, the same update as an EMA codebook: "minibatch" with learning_rate="constant" |
keep oscillating | knows when to stop; labels better than the run's last state; memberships that mean share of time |
any other iterative hard assignment: assign_from_history |
either | settles each point from the recorded history |
Other iterative hard assignments include online or streaming k-means, VQ codebook training, and k-medoids or k-modes style reassignment. Record the labels at each step and pass them in:
from markov_kmeans import assign_from_history

r = assign_from_history(history)        # history: (n_steps, n_points), oldest first
r.labels, r.dense(n_clusters), r.uncertainty
When to use it
| situation | what you get |
|---|---|
| Large data with a long convergence tail | The tail is cut without tuning. The result differs from the converged one only on a few boundary points. |
| Constant-step, EMA or online training | A stopping point that no other rule finds. Labels better than the run's last state, and memberships that reflect time spent in each cluster. |
| Large imagery, such as satellite scenes, when you need the converged map without tuning per scene | It stops close to the converged map in every scene, where fixed thresholds stop too early on some scenes and needlessly late on others. |
| Mini-batch or oscillating training where you need to know which points are uncertain | A list of undecided points with soft memberships, ready for review, a more expensive model, or a downstream step that accepts soft assignments. After exact Lloyd the list is short and mostly correct, so it says little. |
| One setting must serve many datasets | Defaults that stay near the best trade-off whether the run drifts or oscillates. |
When not to use it
| situation | what goes wrong | use instead |
|---|---|---|
| Small or easy data | Monitoring and the observation window are pure overhead; the run is slightly slower than plain K-means. | plain K-means |
| Exact Lloyd with a threshold already tuned for this kind of data | The tuned threshold is slightly cheaper for the same error. | the tuned threshold |
| Only aggregate quality matters: colour palettes, inertia, compression quality, a rough land-cover map | The aggregate settles long before individual points do, but the rule waits for the points. | fit on a sample, or a short fixed run |
| Codebooks that jitter strongly, such as EMA VQ codebooks in image tokenizers | The rule rightly never intervenes, so monitoring costs time and saves nothing. | plain training; distance-based soft tokens |
| You need the exact converged partition | It stops early by design. | run to convergence |
| A rough answer from 1/count mini-batch | Waiting for the observation window costs more than it saves. | a short fixed number of epochs |
Reading the soft membership
regime_ |
a fractional membership means | use it as |
|---|---|---|
"drift" |
the point is still undecided and will end in one cluster | a flag for points likely to be wrong |
"oscillation" |
the point really alternates, and the fractions match its long-run share of time | a soft assignment |
Limits
- Most of the error left after a drift comes from points that look settled at the stop but would move later. The pseudo representatives catch those on the path of a moving center; points the centers would reach only much later remain. A smaller
unstable_tolstops later and leaves fewer of them. - The extrapolation of a center is capped (
rho_max). A cap set higher overshoots on exact Lloyd, so a center still far from its final position is extrapolated only part of the way. - New points get the nearest center from
predict, since they have no history.
Main parameters
| parameter | default | meaning |
|---|---|---|
n_clusters |
8 | number of clusters |
algorithm |
"hamerly" |
"hamerly", "lloyd", "minibatch" |
learning_rate, eta, batch_size |
"count", 2e-4, 4096 |
mini-batch step: "count" (1/count) or "constant" (fixed eta) |
stop_rule |
"auto" |
"auto" judges the state; "unstable" looks only at the share of changing points |
assign_rule |
"auto" |
"auto" (by regime), "markov", "frequency", "keep" |
t0 |
None |
stop at this iteration instead, then settle |
representatives |
"markov" |
"markov" finishes from the pseudo representatives; "current" settles against the current centers only (the 0.3 behaviour) |
unstable_tol |
1e-3 | lower stops later and leaves fewer undecided points |
window |
10 | iterations of label history kept per point |
min_iter, max_iter |
10, 300 | iteration bounds |
center_update |
"auto" |
final centers: "hard", "soft" (membership-weighted), "pseudo" (the pseudo representatives), "none" |
The monitor's other thresholds are documented in the docstring; the evaluation used their defaults. assign_rule="markov" settles every undecided point by the long-run law of its label Markov chain. Diagnostics include n_iter_, stop_reason_, regime_, decision_trace_, unstable_fraction_, n_dist_, fit_seconds_, labels_at_stop_, and for the pseudo representatives pseudo_centers_, center_rho_, pseudo_accepted_ and predicted_moves_. MarkovKMeans is a scikit-learn estimator: it passes scikit-learn's check_estimator and works with clone, Pipeline, GridSearchCV and set_output.
Further reading
- Evaluation report: methods, every number behind the figures, colour quantization and VQ codebook studies
- Prior work
- Quick start
- Citing: CITATION.cff, or "Cite this repository" on the GitHub page
한국어
작동 방식
기반 알고리즘은 평소처럼 돌고, 모든 점의 최근 라벨과 대표점의 최근 위치가 기록된다. 매 반복 뒤 감시기가 실행 전체에 대해 세 가지를 묻는다. 싼 질문부터 묻고, 셋 다 잠잠해지면 멈춘다.
| 검사 | 질문 | 잠잠하다고 보는 때 |
|---|---|---|
| 움직임 | 아직 군집을 바꾸는 점은? | 바뀌는 점이 거의 없거나, 변화가 잦아들고 있거나, 같은 점들이 일정한 수로 계속 오갈 때 |
| 대표점 | 대표점이 이동 중인가, 제자리에서 흔들리기만 하는가? | 대표점이 거의 움직이지 않거나, 고정된 위치 주변에서 흔들리기만 할 때 |
| 분할 | 군집이 재편되는 중인가, 구성원을 주고받기만 하는가? | 군집 크기가 일정하고, 움직이는 구성원이 적거나 양방향으로 오갈 때 |
멈추면 두 종류의 Markov 연쇄가 실행을 마무리한다.
1. 대표점의 연쇄가 의사 대표점(pseudo representative)을 준다. 대표점마다 최근 경로를 같은 방식으로 계속 걸어가는 연쇄로 읽는다. 그 장기 위치는 수렴 중인 대표점이 향하는 곳이고, 흔들리기만 하는 대표점이면 흔들림의 한가운데다. 모든 점을 가장 가까운 의사 대표점에 다시 배정한다. 경계를 곧 넘을 참이지만 아직 움직이지 않은 점, 즉 어떤 라벨 이력도 볼 수 없는 점을 지금 옮겨 준다. 새 라벨은 데이터에 대한 적합도가 이전보다 나쁘지 않을 때만 채택한다.
2. 라벨의 연쇄가 미결정 점을 정리한다. 미결정 점은 관찰 창 안에서 군집을 바꾼 점에, 의사 대표점이 방금 옮긴 점을 더한 것이다. 각 점은 자기 라벨 이력에서 소속도를 받는다.
| 미결정 점 | 소속도 |
|---|---|
| 한 번 옮겨 가 자리 잡은 점 (표류) | 그 군집 |
| 계속 오가는 점 (진동) | 군집별로 머문 시간의 비율 |
| 의사 대표점이 방금 옮긴 점 | 대부분 새 군집, 일부는 옛 군집. 경계가 늦게 지나갈 점일수록 옛 군집 몫이 크다 |
감시기가 진동으로 판정하면, 관찰 창 안에서 바뀐 모든 점이 머문 시간의 비율을 받는다. hard 라벨은 의사 대표점에서 오고, 의사 대표점의 라벨을 채택하지 않았으면 더 큰 비율 쪽이다.
실행 시간은 어디에 쓰이는가
exact Lloyd (왼쪽). 초반 반복이 지나면 군집을 바꾸는 점은 아주 적은데, 실행은 그 뒤로도 데이터를 여러 번 더 훑는다. Markov-K-means가 끊는 것이 이 꼬리다. 멈춘 시점에 아직 틀린 라벨은 대부분 움직이기 시작하지도 않은 점의 것이라, 라벨 이력은 아무것도 말해 주지 않는다. 이력만으로 정리하면(초록) 멈춘 시점의 라벨을 그대로 두는 것과 같다. 의사 대표점(파랑)은 대표점이 향하는 곳을 보고 그런 점의 일부를 미리 옮기므로, 어느 정지 시점에서든 파란 선이 다른 선보다 아래에 있다.
고정 학습률 (오른쪽). 초반에 빠르게 줄어든 뒤로는 바뀌는 점의 수가 더 줄지 않는다. 실행은 평탄 구간에 머물고, 틀린 라벨의 비율은 아무리 오래 돌려도 거의 그대로다. 평탄 구간에서는 오가는 점을 이력으로 정리하면 현재 라벨을 그대로 둘 때보다 틀린 라벨이 적고, 그 차이는 실행이 길어질수록 벌어진다. 흔들리는 대표점을 평균하면 조금 더 줄어든다. 자동 규칙은 평탄 구간에 들어서자마자 멈춘다. 더 늦은 고정 시점(t0)에서 멈추고 정리하면 시간을 더 쓰는 대신 오차가 더 낮아진다.
다른 정지 규칙과 비교한 시간–오차 교환
선 하나는 정지 규칙 하나다. 각 규칙의 설정값을 바꿔 가며 돌렸고, 설정 하나는 한 패널의 모든 데이터에 그대로 적용했다. 결과를 모르는 사용자가 설정을 고르는 상황을 그대로 재현한 것이다. 점의 위치는 평균 오차(기준 분할과 라벨이 다른 점의 비율)와 평균 시간(끝까지 돌린 시간 대비)이다. 아래·왼쪽일수록 좋다. 동그라미는 각 규칙의 기본 설정이다.
| 고정 학습률 / EMA | 1/count mini-batch | exact Lloyd / Hamerly | |
|---|---|---|---|
| Markov-K-means 자동 규칙 | 닿는 모든 오차 수준에서 가장 빠름 | 정밀한 답에서 가장 빠름. 먼저 관찰 창 동안 지켜봐야 해서 대략적인 답에서는 느림 | 공통 곡선 위, 조정된 임계값보다 조금 뒤 |
| Markov-K-means 고정 정지 | 끝까지 돌린 결과보다 낮은 오차에 닿는 유일한 규칙 | 끝까지 돌린 결과보다 낮은 오차에 닿음 | 공통 곡선보다 조금 위 |
scikit-learn tol |
기본값에서 끝내 멈추지 못함 | 공통 곡선 위 | 공통 곡선 위, 조정하면 조금 앞섬 |
| Pérez-Ortega 임계값 | 너무 이르거나 너무 늦게 멈춤 | 공통 곡선 위 | 공통 곡선 위, 조정하면 조금 앞섬 |
| 고정 반복 수 | 진동 중 아무 순간에나 멈춤 | 공통 곡선 위 | 공통 곡선 위 |
| 기본값의 위치 | Markov-K-means: 낮은 오차. scikit-learn: 끝까지 돎. Pérez-Ortega: 빠르지만 거침 | 모두 낮은 오차, 적은 시간 | Markov-K-means와 scikit-learn: 낮은 오차. Pérez-Ortega와 고정 반복: 빠르지만 거침 |
정리하면, 오차 한 단위를 줄이는 데 드는 시간은 진동하는 학습에서, 그리고 1/count mini-batch에서 정밀한 답이 필요할 때 Markov-K-means가 가장 적다. exact Lloyd에서는 데이터에 맞춰 조정한 임계값보다 조금 더 든다. 의사 대표점은 exact Lloyd에서도 정지 시점마다 오차를 줄이지만, 정지 시점 사이의 오차 차이가 그보다 커서 곡선은 거의 그대로다.
실제 위성영상에서
지형이 전혀 다른 Sentinel-2 장면 12개(장면마다 화소 약 3천만 개)를 라벨이 하나도 바뀌지 않을 때까지 exact K-means로 군집하고, 같은 실행 위에서 정지 규칙들을 판정했다.
| 정지 규칙 | 멈추는 곳 | 수렴한 지도와의 차이 |
|---|---|---|
| 원격탐사 기본값: 라벨이 바뀐 화소 2% 미만 또는 10회 | 매우 이른 시점 | 다른 라벨을 받은 화소가 많다. 전체 적합도는 비슷하다 |
| scikit-learn tol | 대략 3분의 1 지점 | 대개 가깝지만, 군집이 늦게 재편되는 장면에서는 크게 틀린다 |
| Markov-K-means, 라벨 이력 정리만 (0.3) | 더 늦게, 장면마다 다른 시점 | 모든 장면에서 수렴한 지도에 가깝다 |
| Markov-K-means (0.4) | 같은 시점 | 모든 장면에서 더 가깝다. 남은 차이의 약 3분의 2가 사라지고, 추가 시간은 거의 없다 |
위성영상에도 꼬리가 분명히 있고, 알맞은 반복 수가 장면마다 크게 달라서 고정된 설정 하나로는 모든 장면에서 수렴 결과에 닿지 못한다. 조정 없이 모든 장면에서 그곳에 닿는 규칙은 Markov-K-means뿐이다. 멈춘 시점에 아직 틀린 화소는 거의 모두 움직이기 시작하지도 않은 화소였고, 의사 대표점이 바로 그런 화소를 위한 것이다. 의사 대표점이 옮긴 화소는 거의 모두 수렴한 실행이 두는 곳으로 갔다. 저차원 영상에서는 늦은 반복이 원래 싸서 절약되는 시간은 크지 않다. 미결정 목록과 soft 소속도는 여기서 정보가 거의 없다. 장면들이 표류 후 정착하는 체제여서, 혼합 화소는 단순한 거리 비가 더 잘 가려낸다.
적용 가능한 알고리즘
| 기반 알고리즘 | 경계 점의 거동 | Markov-K-means가 더하는 것 |
|---|---|---|
exact Lloyd: "hamerly"(기본), "lloyd" |
표류 후 정착 | 임계값 조정 없이 꼬리를 끊고, 미결정 점 목록을 준다 |
scikit-learn MiniBatchKMeans와 같은 1/count mini-batch: "minibatch" |
표류 후 정착 | 위와 같다 |
EMA 코드북과 같은 고정 보폭 mini-batch: "minibatch", learning_rate="constant" |
계속 진동 | 언제 멈출지 알고, 마지막 상태보다 나은 라벨과 머문 시간 비율로서의 소속도를 준다 |
그 밖의 반복형 hard 배정: assign_from_history |
둘 다 | 기록된 이력으로 각 점을 정리한다 |
그 밖의 반복형 hard 배정에는 온라인·스트리밍 k-means, VQ 코드북 학습, k-medoids·k-modes식 재배정이 있다. 매 단계의 라벨을 기록해 넘기면 된다.
from markov_kmeans import assign_from_history

r = assign_from_history(history)        # history: (단계 수, 점 수), 오래된 단계부터
r.labels, r.dense(n_clusters), r.uncertainty
이럴 때 쓰면 좋다
| 상황 | 얻는 것 |
|---|---|
| 수렴 꼬리가 긴 대용량 데이터 | 조정 없이 꼬리가 끊긴다. 결과는 수렴한 결과와 경계의 소수 점에서만 다르다. |
| 고정 학습률, EMA, 온라인 학습 | 다른 규칙이 찾지 못하는 정지 시점을 얻는다. 라벨은 마지막 상태보다 정확하고, 소속도는 군집별로 머문 시간을 나타낸다. |
| 위성영상 같은 대용량 영상에서 장면마다 조정하지 않고 수렴한 지도가 필요할 때 | 모든 장면에서 수렴한 지도 가까이에서 멈춘다. 고정 임계값은 어떤 장면에서는 너무 일찍, 어떤 장면에서는 쓸데없이 늦게 멈춘다. |
| mini-batch나 진동하는 학습에서 어떤 점이 불확실한지 알아야 할 때 | soft 소속도가 붙은 미결정 점 목록을 얻는다. 사람 검토, 더 비싼 모델, soft 배정을 받는 후속 단계로 바로 넘길 수 있다. exact Lloyd 뒤에는 목록이 짧고 대부분 맞는 점이라 정보가 적다. |
| 설정 하나로 여러 데이터를 처리해야 할 때 | 표류든 진동이든 최적 교환선 가까이에 놓이는 기본값을 쓸 수 있다. |
이럴 때는 오히려 독이 된다
| 상황 | 무엇이 문제인가 | 대신 쓸 것 |
|---|---|---|
| 작거나 쉬운 데이터 | 감시와 관찰 창이 순수한 추가 비용이 되어, 그냥 K-means보다 약간 느리다. | 그냥 K-means |
| 같은 종류의 데이터에 맞춰 임계값을 이미 조정해 둔 exact Lloyd | 같은 오차를 조정된 임계값이 조금 더 싸게 얻는다. | 조정된 임계값 |
| 색 팔레트, inertia, 압축 화질, 대략적인 토지피복 지도처럼 전체 품질만 중요할 때 | 집계 지표는 점들보다 훨씬 먼저 안정되는데, 규칙은 점 하나하나를 기다린다. | 표본 학습, 짧은 고정 반복 |
| 이미지 토크나이저의 EMA VQ 코드북처럼 크게 흔들리는 코드북 | 규칙이 개입하지 않는 것이 옳으므로, 감시 비용만 들고 절감은 없다. | 일반 학습, 거리 기반 soft 토큰 |
| 정확히 수렴한 분할이 필요할 때 | 설계상 일찍 멈춘다. | 끝까지 수렴 |
| 1/count mini-batch로 대략적인 답만 필요할 때 | 관찰 창을 기다리는 비용이 아끼는 시간보다 크다. | 짧은 고정 epoch |
soft 소속도 읽는 법
regime_ |
분수형 소속도의 뜻 | 쓰는 법 |
|---|---|---|
"drift" |
아직 미결정이고, 결국 한 군집에 정착한다 | 틀릴 가능성이 큰 점의 표시 |
"oscillation" |
실제로 오가며, 비율이 장기적으로 머무는 시간과 맞는다 | soft 배정 |
한계
- 표류 뒤 남는 오차는 대부분 멈출 때 자리 잡은 듯 보였다가 나중에 옮겨 갈 점에서 나온다. 의사 대표점은 움직이는 대표점의 경로 위에 있는 점을 잡지만, 대표점이 한참 뒤에야 닿을 점은 남는다.
unstable_tol을 낮추면 더 늦게 멈추는 대신 이런 점이 줄어든다. - 대표점의 외삽에는 상한(
rho_max)이 있다. 상한을 높이면 exact Lloyd에서 지나치게 외삽하므로, 최종 위치에서 아직 먼 대표점은 일부만 외삽된다. - 새 점은 이력이 없으므로
predict가 가장 가까운 대표점을 준다.
주요 매개변수
| 매개변수 | 기본값 | 의미 |
|---|---|---|
n_clusters |
8 | 군집 수 |
algorithm |
"hamerly" |
"hamerly", "lloyd", "minibatch" |
learning_rate, eta, batch_size |
"count", 2e-4, 4096 |
mini-batch 보폭: "count"(1/count) 또는 "constant"(고정 eta) |
stop_rule |
"auto" |
"auto"는 상태를 판정하고, "unstable"은 바뀌는 점의 비율만 본다 |
assign_rule |
"auto" |
"auto"(체제별), "markov", "frequency", "keep" |
t0 |
None |
이 반복에서 멈춘 뒤 정리한다 |
representatives |
"markov" |
"markov"는 의사 대표점으로 마무리하고, "current"는 현재 대표점 기준으로 이력 정리만 한다(0.3 동작) |
unstable_tol |
1e-3 | 낮출수록 늦게 멈추고 미결정 점이 줄어든다 |
window |
10 | 점마다 보관하는 라벨 이력의 반복 수 |
min_iter, max_iter |
10, 300 | 반복 수 범위 |
center_update |
"auto" |
최종 대표점: "hard", "soft"(소속도 가중), "pseudo"(의사 대표점), "none" |
감시기의 나머지 임계값은 docstring에 정리되어 있고, 평가는 모두 기본값으로 했다. assign_rule="markov"는 모든 미결정 점을 라벨 Markov 연쇄의 장기 분포로 정리한다. 진단 속성으로 n_iter_, stop_reason_, regime_, decision_trace_, unstable_fraction_, n_dist_, fit_seconds_, labels_at_stop_, 의사 대표점 관련 pseudo_centers_, center_rho_, pseudo_accepted_, predicted_moves_가 있다. MarkovKMeans는 scikit-learn 추정기다. scikit-learn의 check_estimator를 통과하고 clone, Pipeline, GridSearchCV, set_output과 함께 쓸 수 있다.
더 보기
- 평가 보고서: 방법, 그림 뒤의 모든 수치, 색 양자화·VQ 코드북 실험
- 선행연구
- 빠른 시작 예제
- 인용: CITATION.cff 또는 GitHub 페이지의 "Cite this repository"
Apache-2.0
1 maintainer

Metadata
1 maintainer
Release files for markov-kmeans 0.4.0
For a detailed explanation of source distributions (sdists) and built distributions (wheels), please see the package formats documentation.
Source distribution (sdist)
| File | Size | Uploaded | |
|---|---|---|---|
| markov_kmeans-0.4.0.tar.gz | 47.1 kB | Details |
Built distribution (wheel)
| File | Interpreter | ABI | Platform | Reset |
|---|---|---|---|---|
| markov_kmeans-0.4.0-py3-none-any.whl | Python 3 | none | any | Details |
Total release size: 85.6 kB
Release files / markov_kmeans-0.4.0.tar.gz
| Download URL | markov_kmeans-0.4.0.tar.gz |
|---|---|
| Size | 47.1 kB |
| Tags | Source |
|
SHA-256 checksum How to use checksums |
23c1661fd91c1142608b6ac2c2d96cc9e71ec9ce6ba5430c5cb58e828788a66d
|
|
BLAKE2b-256 checksum How to use checksums |
182bcaf7e8eac65acb5c3ed92c942b8e860d2cb4bd9d8c7172eec00a642eb0fa
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.


PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 12, 2026.
Transparency logRelease files / markov_kmeans-0.4.0-py3-none-any.whl
| Download URL | markov_kmeans-0.4.0-py3-none-any.whl |
|---|---|
| Size | 38.5 kB |
| Tags | Python 3 |
|
SHA-256 checksum How to use checksums |
0d703bfbf80c443af8078f5b9a9af5271a3f6d9fdbd5faf227d35b880e9e2c1f
|
|
BLAKE2b-256 checksum How to use checksums |
67caa68a1f7aa3dc108dcaa8b88cff3aa1751dc699900de64ada62fca3b3c74e
|
| Upload date | |
|
Uploaded using Trusted Publishing? What is trusted publishing? |
Yes |
| Uploaded via |
twine/7.0.0 CPython/3.13.14
|
Provenance
Provenance describes where a file came from. On PyPI, provenance is shared via attestations, which provide a verifiable record of the build or publishing details. View details, limitations and caveats.
PyPI Publish Attestation
PyPI verified that this artifact, at this checksum, originated from the publisher listed below.
Signed by GitHub Actions, verified by PyPI on Oct 12, 2026.
Transparency log













